
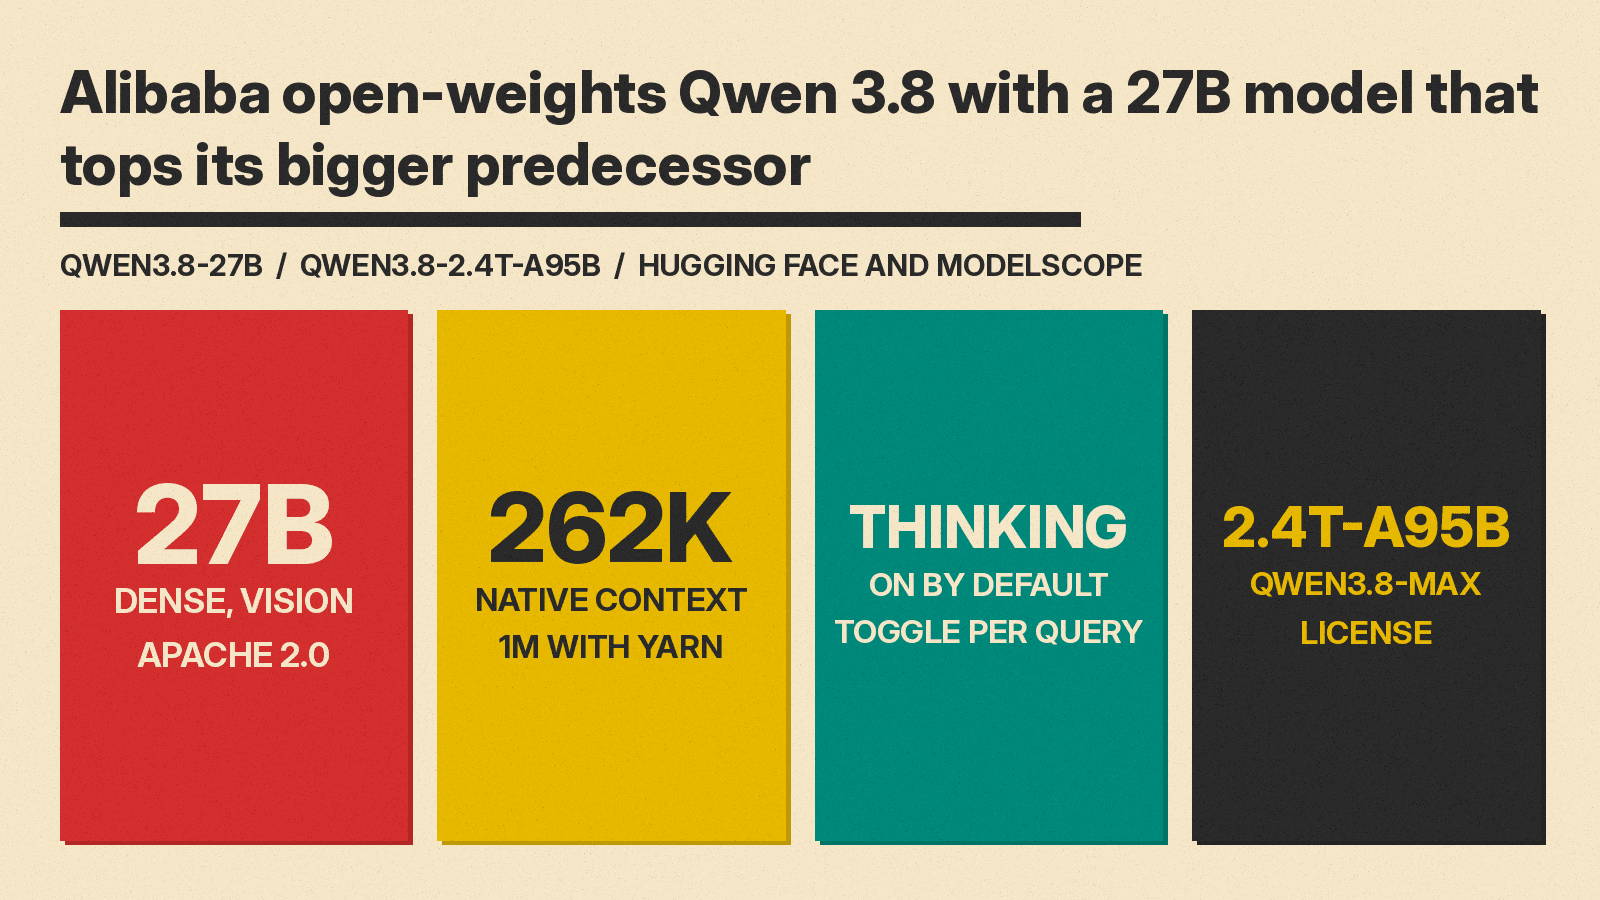
Alibaba's Qwen team announced the open weights for Qwen3.8 on August 14. The Qwen3.8-27B model card lists the Apache 2.0 license, and Hugging Face shows its weight files uploaded on August 13 (UTC). The move puts a capable new open model directly into the hands of researchers and companies that want to fine-tune and self-host it.
The centerpiece is Qwen3.8-27B, a 27 billion parameter multimodal dense model. Qwen says it outperforms the larger Qwen3.7-Plus on coding and office tasks. The team also highlights stronger agent behavior, with the model planning more independently and completing multi-step tasks more reliably.
Qwen3.8-27B handles up to 262,000 tokens of context natively and can stretch to one million using the YaRN method. It reads images and video, including diagrams, documents, and multi-hour recordings, and ships with a flexible thinking mode that is on by default but can be toggled per query.
Qwen also published weights for Qwen3.8-2.4T-A95B, a much larger model built to the Max tier. Hugging Face shows that repository created on August 8 and its weight files uploaded on August 9 (both UTC), and its model card lists the Qwen3.8-Max License, not Apache 2.0. Both are available on Hugging Face and ModelScope, and a hosted version with one million tokens of context is expected soon on Qwen Cloud, Alibaba's AI service.
The open release follows Alibaba's Aug 3 launch of the Qwen 3.8-Max flagship, whose early benchmarks drew scrutiny. By open-weighting the 3.8 family, with the 27B model under Apache 2.0 and the 2.4T model under the Qwen3.8-Max License, Alibaba gives the broader AI community a transparent, modifiable baseline rather than a closed API. Our Qwen3.8 explainer covers the full family, from Max and the open 2.4T weights to the Flash models and the Qwen 4 preview.
Update (Oct 19, 2026)
We have folded the details from our Aug 17 report on the 27B release into this post. Each one is checked against the Qwen3.8-27B model card or Simon Willison's hands-on test.
Native vision. The model card lists the 27B as a causal language model with a vision encoder and calls it "a native vision-language model that understands images and videos," from STEM diagrams and documents to hour-scale videos. The card's examples pass images and video directly through the Chat Completions API.
Reasoning control. The card says Qwen3.8 has official support for reasoning_effort, with three levels: xhigh, the default, "for complex tasks demanding thorough analysis"; medium, "balancing accuracy and speed"; and low, "efficient reasoning optimizing for speed and cost." A preserve_thinking setting, on by default, keeps reasoning from earlier messages in context. The card also notes that in multi-turn agent tasks, lower effort "does not always reduce overall task completion time," because it can lead to more failures and retries.
Local sizing. Simon Willison ran the 17GB Q4_K_M quantized build in LM Studio on a 128GB M5 Max MacBook Pro and on an NVIDIA DGX Spark, and got around 15 to 30 tokens per second. LM Studio's default 8,192-token context was too small for the model's reasoning, so he loaded it with the full 262,144 tokens. Our review of the 27B's default reasoning setting covers his tests in more detail.
Update (Oct 28, 2026): an X post shared a run-time recipe that pushes one neuron in Qwen3.8-27B to make it act like a villain. Our Qwen evil neuron explainer covers what the recipe does and what it does not show.
Sources
The Decoder, "Alibaba's Qwen team releases Qwen 3.8 models with open weights under the Apache 2.0 license" (Aug 14, 2026): https://the-decoder.com/alibabas-qwen-team-releases-qwen-3-8-models-with-open-weights-under-the-apache-2-0-license/
Qwen via X: https://x.com/Alibaba_Qwen/status/2088280182356611304
Hugging Face, Qwen3.8 collection: https://huggingface.co/collections/Qwen/qwen38
Hugging Face, Qwen3.8-27B model card (Apache 2.0): https://huggingface.co/Qwen/Qwen3.8-27B
Hugging Face, Qwen3.8-27B commit history: https://huggingface.co/Qwen/Qwen3.8-27B/commits/main
Hugging Face, Qwen3.8-2.4T-A95B model card (Qwen3.8-Max License): https://huggingface.co/Qwen/Qwen3.8-2.4T-A95B
Hugging Face, Qwen3.8-2.4T-A95B commit history: https://huggingface.co/Qwen/Qwen3.8-2.4T-A95B/commits/main
Techmeme aggregation: https://www.techmeme.com/260814/p16#a260814p16
Simon Willison, "Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things" (Aug 16, 2026): https://simonwillison.net/2026/Aug/16/qwen-38-27b/
