Emergent Outlier Features in Large Language Models: Why Hidden Dimension Spikes Arise at Scale and How They Reshape Quantization
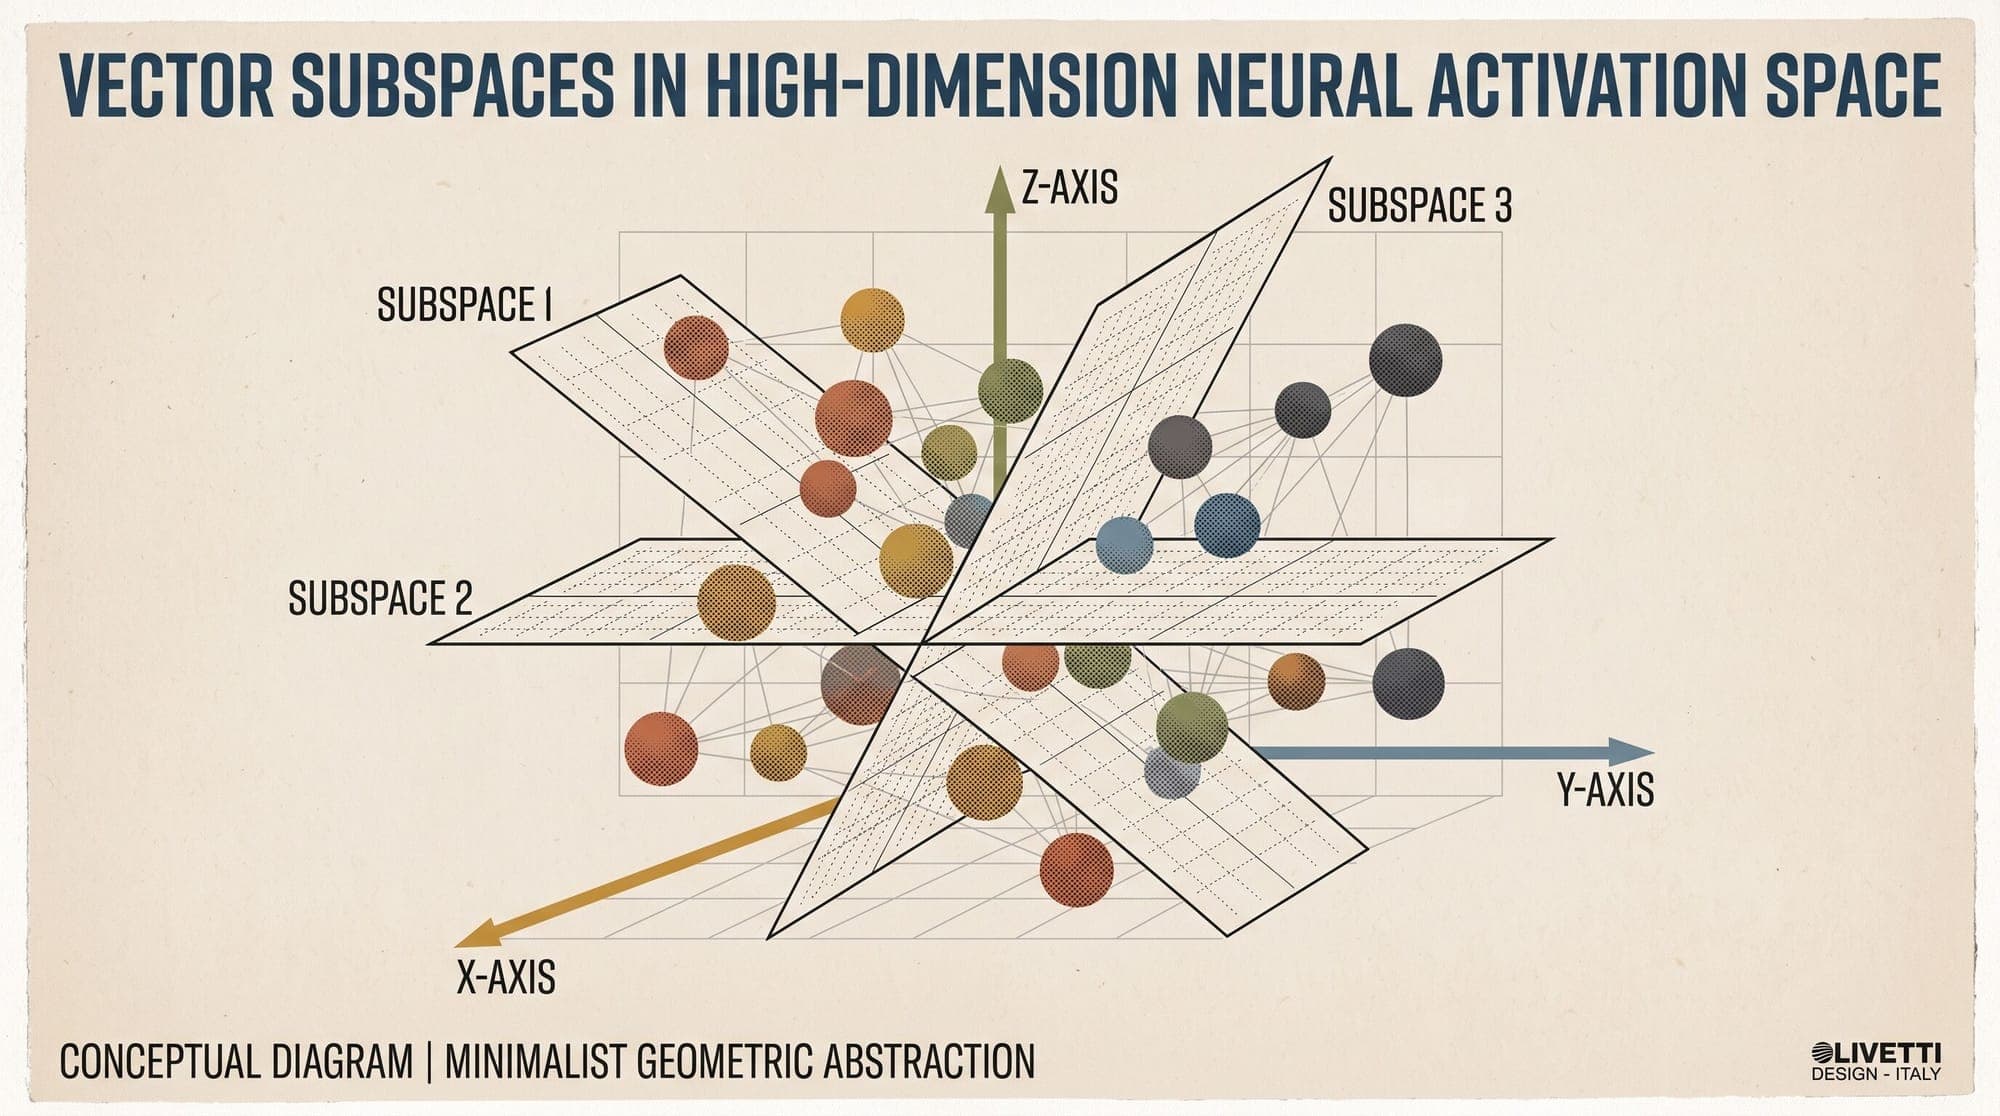
Emergent Outlier Features in Large Language Models: Why Hidden Dimension Spikes Arise at Scale and How They Reshape Quantization When language models scale past approximately 6.7 billion parameters, their internal representations undergo a sharp qualitative phase transition. In smaller models (125M to 2.7B parameters), hidden state activations remain relatively compact, bounded within predictable normal distributions across all embedding dimensions. However, as demonstrated by Dettmers et al. (