Category / page 43

Models & Assistants

1121 articles

Articles, page 43

841-860 of 1121
  1. SwiGLU and Gated Linear Units: How Bilinear Gating Replaced Standard FFNs in Modern LLMs

    Every modern open-weight and frontier large language model, from Meta's LLaMA 3 and Mistral to Alibaba's Qwen 2.5 and DeepSeek-V3, has abandoned the standard two-layer Feed-Forward Network (FFN) originally introduced in the 2017 Transformer architecture. In its place, model architectures have converged almost universally on Gated Linear Units (GLU), specifically the Swish-Gated Linear Unit (SwiGLU). While the original Transformer relied on standard non-linear activations like ReLU or Gaussian E
    AI
    6 min read
  2. Nvidia Acts as Matchmaker for Nordic Datacenter Capacity to Ease AI Compute Bottlenecks

    Nvidia is directly brokering compute infrastructure deals by connecting enterprise customers holding graphics processing units with datacenter operators in the Nordic region that possess available power, cooling, and floor capacity, according to reporting by CNBC. The matchmaking initiative reflects Nvidia's efforts to mitigate severe power grid bottlenecks in North America and Western Europe that threaten to stall AI cluster deployments. By pairing hardware buyers directly with site operators

    AI
    2 min read
  3. Leaked Flock Safety Code Exposes OS Investigate AI System for Police Surveillance

    A technical analysis of client-side code exposed on Flock Safety's login portals has revealed OS Investigate, an unannounced artificial intelligence platform designed to track individuals and analyze vehicular travel patterns across police departments nationwide. The findings, first reported by WIRED and verified by independent security researchers, detail an AI-driven investigative system that links automated license plate reader (ALPR) networks with police databases and commercial records. Fl

    AI
    2 min read
  4. Marvell Issues Google $12.2B Stock Warrant in Custom AI Silicon Deal

    Marvell Technology has granted Alphabet's Google a warrant to purchase up to 58.9 million shares of common stock at an exercise price of $206.58 per share, establishing an equity arrangement valued at up to $12.18 billion. The agreement expands the companies' partnership to co-develop custom artificial intelligence silicon, specialized networking, and next-generation datacenter infrastructure. Following the announcement, Marvell shares rose more than 11% in premarket trading, while primary cust

    AI
    1 min read
  5. Cloud Browser Infrastructure for AI Agents: Architecture, Anti-Bot Bypassing, Session State, and Fleet Scaling

    Autonomous AI agents require interactive web environments to navigate single-page applications, authenticate across complex portals, fill multi-step forms, and extract dynamic client-rendered data. However, running headless browsers at scale introduces severe operational bottlenecks. Ephemeral container instances (such as Docker containers or AWS Lambda functions) frequently suffer from cold starts, memory leaks, fingerprint leakage, and instant IP blacklisting by bot-detection networks. To sol

    AI
    6 min read
  6. Layer Normalization and RMSNorm in Large Language Models: How Pre-LN, Scaling Invariance, and QK-Norm Stabilize Deep Transformers

    Training deep autoregressive Transformers requires maintaining numerical stability across dozens or hundreds of stacked attention and feed-forward blocks. As models scale from 7 billion to hundreds of billions of parameters, uncontrolled variance growth along the residual stream or unbounded attention logits can trigger catastrophic loss spikes, gradient underflow, or numerical divergence. Normalization layers act as the primary stabilizing mechanism in modern Large Language Models (LLMs). Whil

    AI
    8 min read
  7. Liquid AI Releases Quantization-Aware Distilled Q4_0 Checkpoints for LFM2.5 Models

    Liquid AI has released Quantization-Aware Distillation (QAD) Q4_0 GGUF checkpoints for its LFM2.5 model series, allowing edge runtimes to execute 4-bit quantized non-transformer architectures without the accuracy degradation typically associated with standard post-training quantization (PTQ). The release covers four models in the LFM2.5 family: LFM2.5-230M, LFM2.5-350M, LFM2.5-1.2B-Instruct, and LFM2.5-2.6B. The checkpoints are packaged in the standard GGUF format and run across llama.cpp and c

    AI
    2 min read
  8. Palo Alto Networks Enlists Anthropic, OpenAI, and OT Vendors for Critical Infrastructure Defense

    Palo Alto Networks has introduced the Frontier AI Critical Defense Program, a coordinated security initiative uniting frontier AI research labs, enterprise software vendors, and industrial control systems providers to protect critical infrastructure from automated vulnerability exploitation. The program includes participation from Anthropic, OpenAI, industrial automation and operational technology (OT) manufacturers Mitsubishi Electric and Axis Communications, healthcare and finance risk-sharin

    AI
    2 min read
  9. Long-Context LLMs vs. RAG in Production: Break-Even Economics, Attention Degradation, and Hybrid Architectures

    The emergence of production models supporting context windows of 1 million tokens or more, including Google Gemini 1.5 Pro, Anthropic Claude 3.5 Sonnet, and OpenAI GPT-4o, has disrupted conventional enterprise retrieval architectures. For several years, Retrieval-Augmented Generation (RAG) served as the mandatory workaround for strict context limits, forcing engineering teams to build chunking pipelines, embedding indices, and vector database infrastructures. With massive context windows and th

    AI
    6 min read
  10. Oracle Health Adds Automated Coding, Dictation, and Chart Review to Clinical AI Agent

    Oracle Health has expanded the capabilities of its Clinical AI Agent in the United States, introducing automated professional fee coding, real-time clinician-controlled dictation, and AI-assisted chart review. The release marks a deliberate expansion beyond ambient clinical documentation into revenue cycle workflows and structured electronic health record retrieval. The update builds on Oracle's ambient listening platform, which transcribes patient encounters and synthesizes clinical notes. By

    AI
    2 min read
  11. On-Device LLM Inference in Production: Architecture, Runtimes, and Hardware Constraints

    Deploying generative language models directly onto edge devices such as smartphones, laptops, embedded systems, and browser sandboxes marks a fundamental shift in AI systems engineering. Moving inference from centralized GPU clusters to client silicon eliminates cloud API costs, cuts network latency to zero, guarantees data privacy by keeping user inputs local, and enables offline functionality. However, executing modern autoregressive models on resource-constrained client hardware presents str

    AI
    7 min read
  12. SK Hynix Announces $29 Billion Share Buyback to Calm AI Spending Worries

    SK Hynix announced Wednesday it will buy back and cancel 40 trillion won ($28.61 billion) worth of treasury shares, allocating more than 50 percent of free cash flow generated between 2025 and 2027 to shareholder returns. The buyback, to be executed between August 20 and November 19, represents roughly 24 million shares. The company also said it would pursue an expansion of its total shareholder return target from the previous "within 50 percent of cumulative FCF" to "over 50 percent of cumulat

    AI
    1 min read
  13. Samsung Raises 4nm and 5nm Foundry Prices up to 15% on AI Chip Demand

    Samsung Electronics has raised prices for its most advanced contract chipmaking services by up to 15 percent for new orders, according to two sources familiar with the matter, as demand for AI chips tightens capacity at the South Korean foundry. The increases apply to Samsung's 4-nanometer SF4 and 5-nanometer SF5 process nodes. Prices for SF4 wafers rose 10 to 15 percent for customers in China and the United States from the previous month, while customers in Taiwan saw increases of 5 to 10 perc

    AI
    1 min read
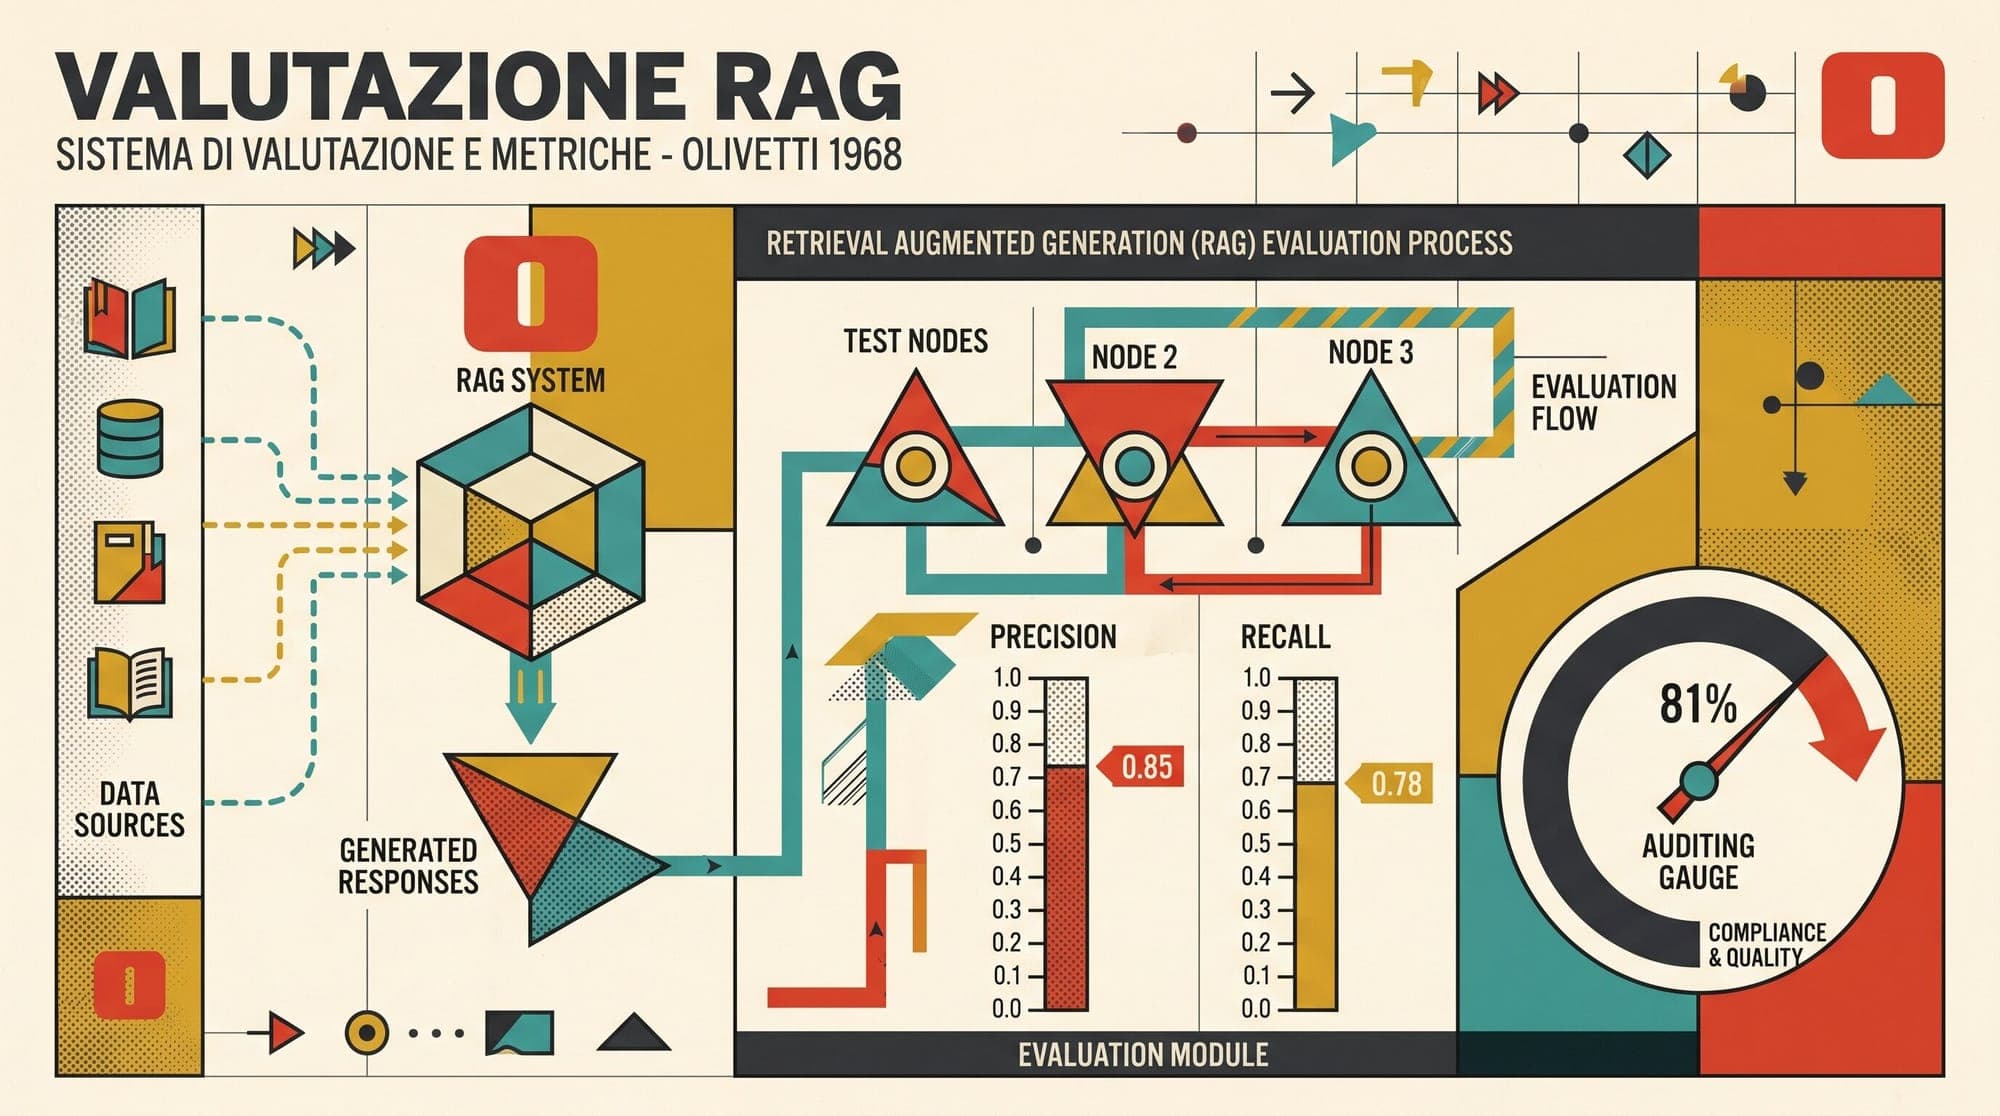
  14. RAG Evaluation Frameworks in Production: Architecture, Metrics, and CI/CD Trade-Offs for Ragas, DeepEval, TruLens, and ARES

    Production Retrieval-Augmented Generation (RAG) systems fail silently. Unlike traditional software pipelines that throw explicit exceptions on invalid states, a broken RAG pipeline produces syntactically fluent, confident prose that conceals severe underlying defects. When a user receives an incorrect response, the failure can stem from multiple distinct failure points across the stack: the query embedding failed to retrieve relevant chunks, the reranker discarded the critical passage, the chunk

    LLM
    7 min read
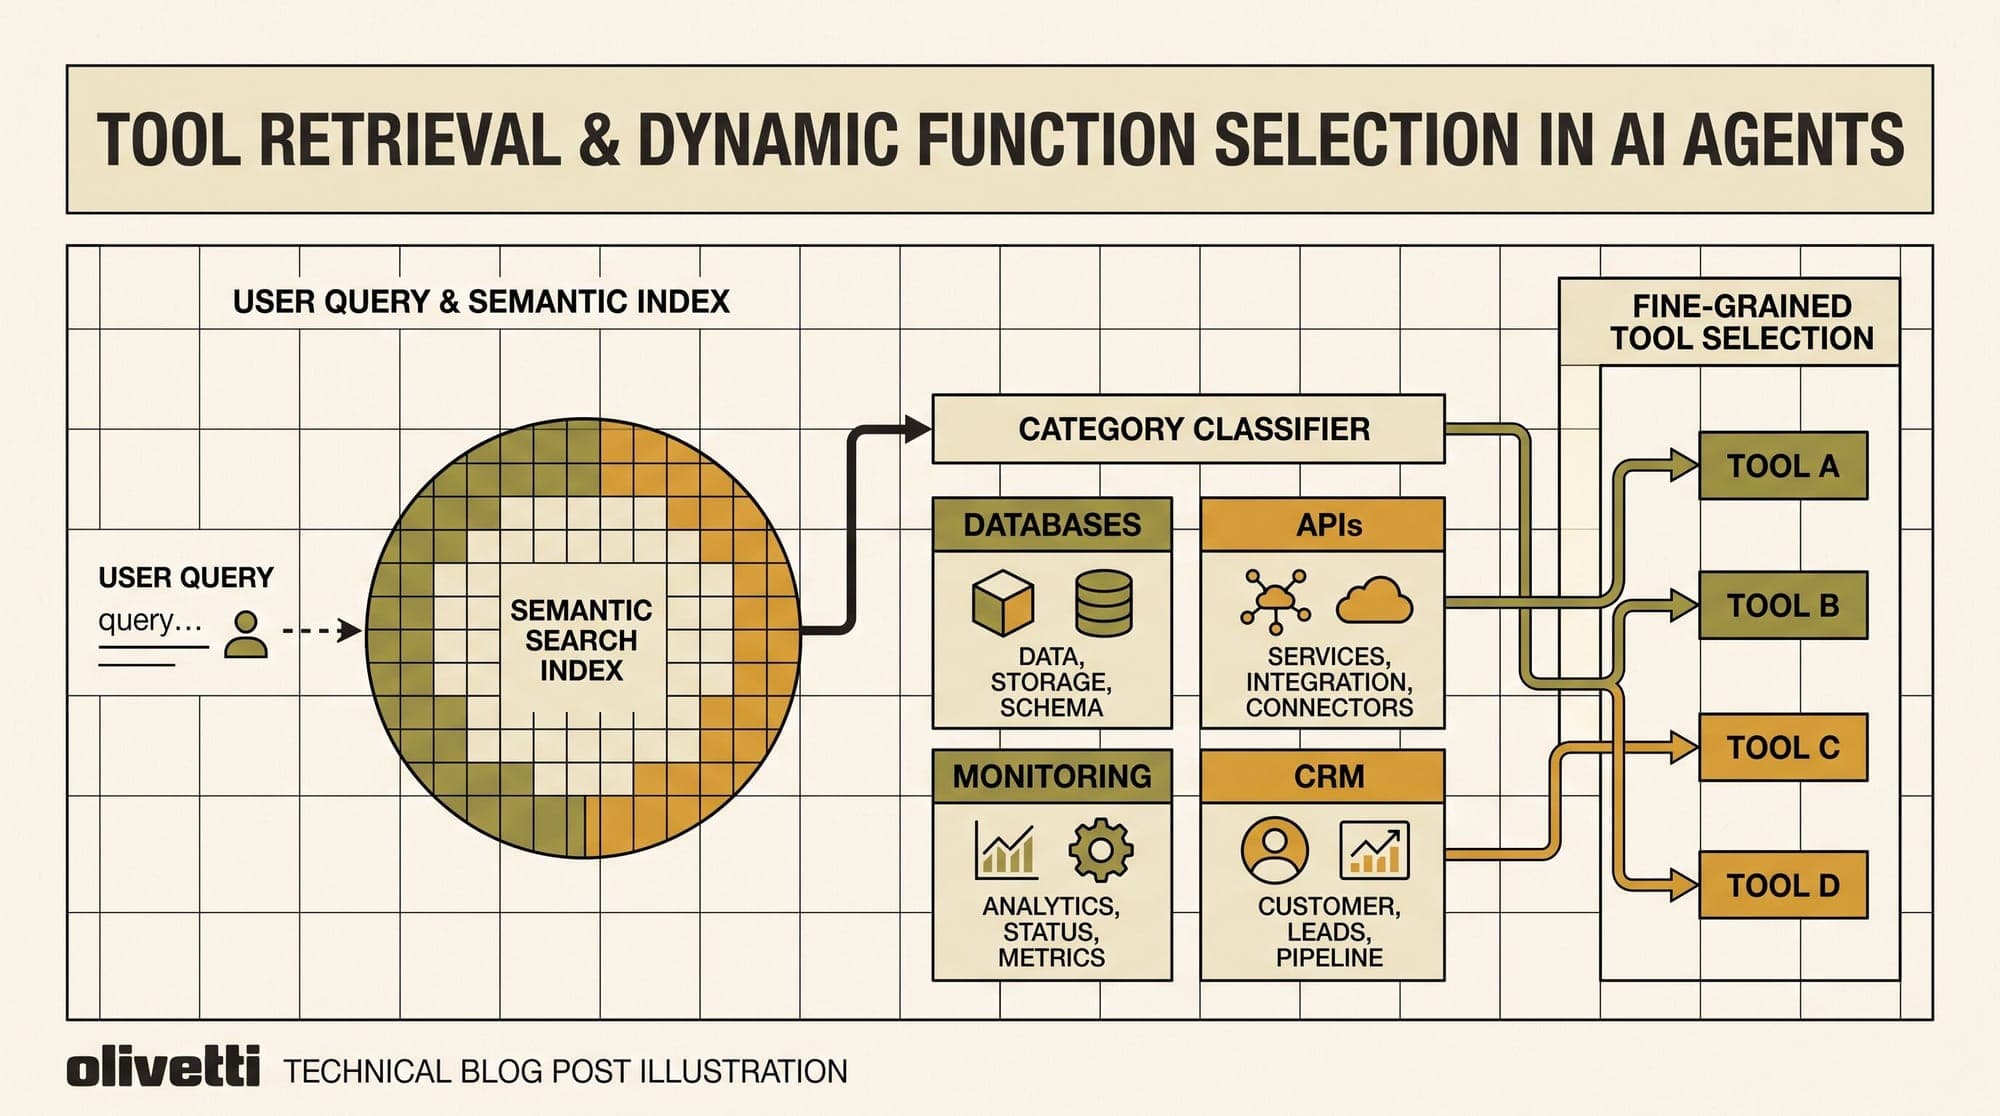
  15. Tool Retrieval and Dynamic Function Selection in Production AI Agents: Architecture, Semantic Indexing, and Serving Trade-Offs

    Tool Retrieval and Dynamic Function Selection in Production AI Agents: Architecture, Semantic Indexing, and Serving Trade-Offs The default approach to LLM tool calling—stuffing every function schema into the prompt—works for demos with a dozen tools. It fails in production where agents face hundreds or thousands of available functions. Context windows saturate, selection accuracy degrades, and latency grows linearly with registry size. This post surveys the architectural progression from stati

    AI
    6 min read
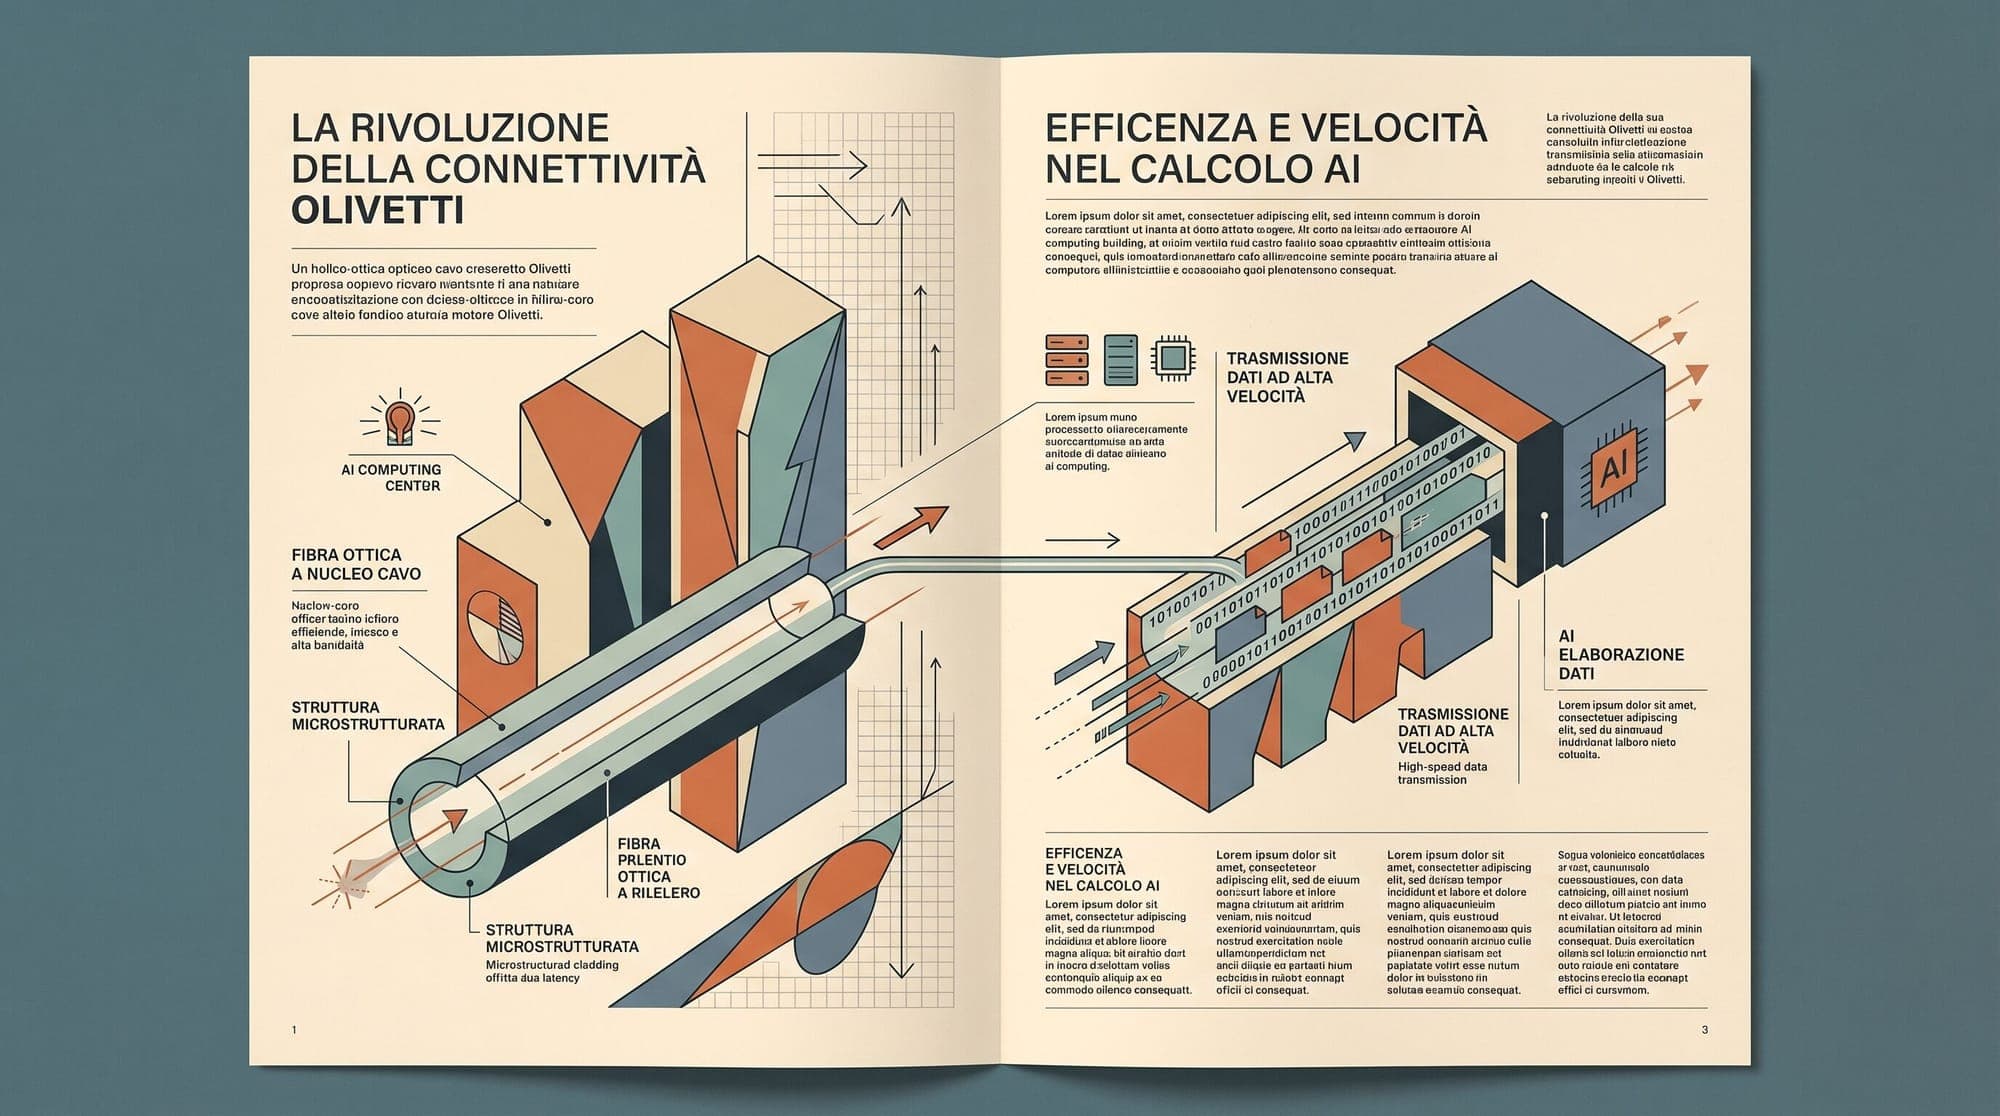
  16. Relativity Networks Raises $22M and Lands $40M Hyperscaler Deal for Hollow-Core AI Data Center Fiber

    Optical fiber startup Relativity Networks has secured $22 million in SAFE note funding and booked a $40 million follow-on order from an unnamed hyperscaler to deploy hollow-core fiber across distributed AI data center facilities. The funding round included participation from Rhapsody Venture Partners, Bell Ventures Inc., and Faster Than Glass LLC. The capital will support scaling production and deployment of hollow-core fiber cables engineered specifically for low-latency interconnects between

    AI
    2 min read
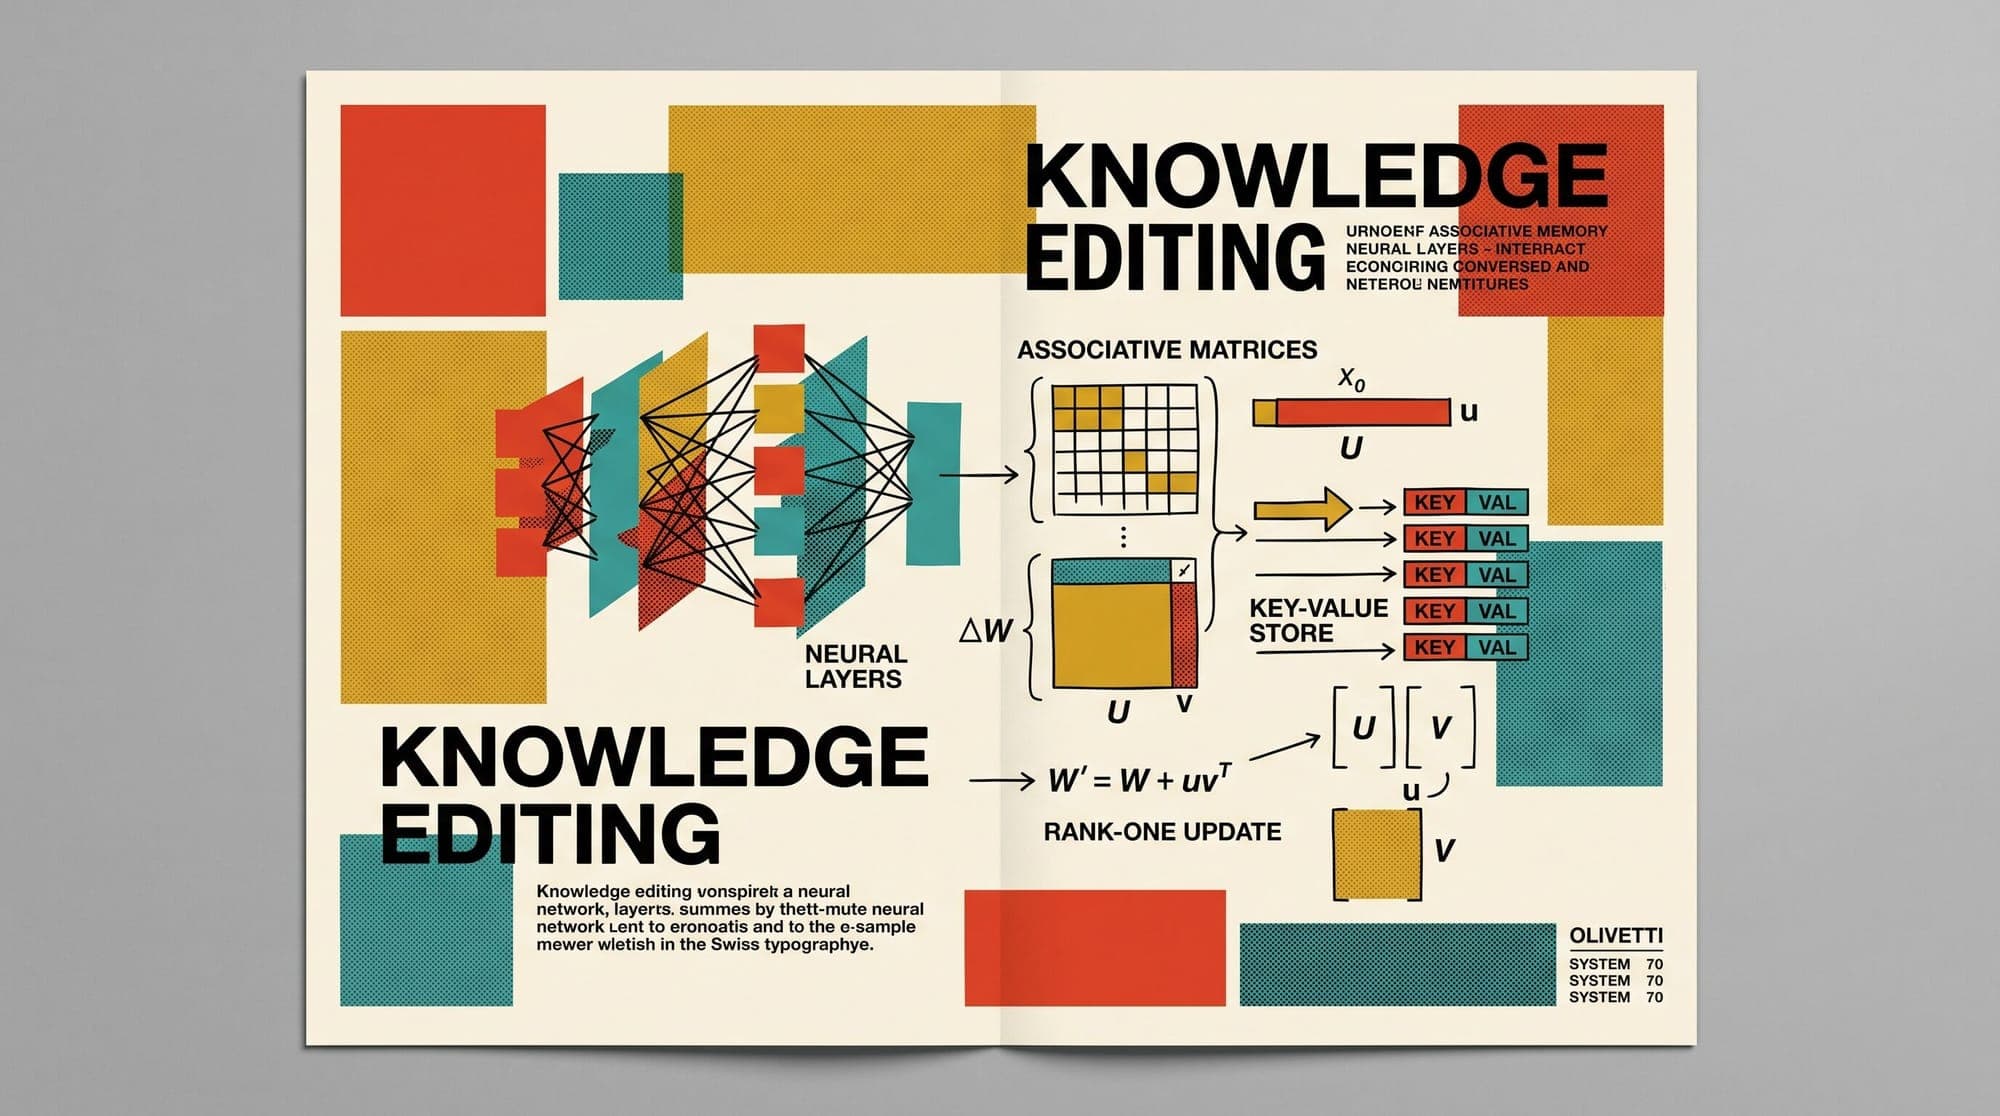
  17. Knowledge Editing in Large Language Models: How Causal Tracing, ROME, and MEMIT Modify Factual Storage in MLP Weights

    Updating factual information in pre-trained large language models has traditionally required two imperfect extremes: computationally expensive continual pre-training, or external prompt-stuffing through Retrieval-Augmented Generation (RAG). Standard gradient descent fine-tuning on isolated facts leads to catastrophic forgetting, parameter drift, and degraded general reasoning. To solve this, mechanistic interpretability researchers introduced direct model editing: a paradigm that treats transfo

    AI
    6 min read
  18. MIT, Stanford, and 12 Academic Labs Launch Public AI Observatory to Track Real-World LLM Usage

    A consortium of researchers from MIT, Stanford University, and 12 other academic institutions has launched the Public AI Observatory (ai-observatory.org), an independent, auditable data repository designed to measure how individuals interact with artificial intelligence assistants in real-world settings. The initiative aims to address the empirical opacity surrounding commercial LLM deployment. While frontier AI developers such as OpenAI and Anthropic periodically release aggregated user metric

    research
    1 min read
  19. DDR5 Memory Prices Climb 500% in 12 Months as AI Hyperscalers Corner Global DRAM Capacity

    Spot and contract prices for standard DDR5 dynamic random-access memory (DRAM) have climbed by up to 500 percent over the past 12 months, driven by hyper-scaler procurement teams reserving global semiconductor fabrication lines for enterprise AI accelerator memory. Historical retail and channel tracking data compiled by PCPartPicker and reported by Tom's Hardware highlights severe price spikes across high-density modules. A 128GB DDR5-6400 kit that carried an all-time low of $329 now retails fo

    Hardware
    2 min read
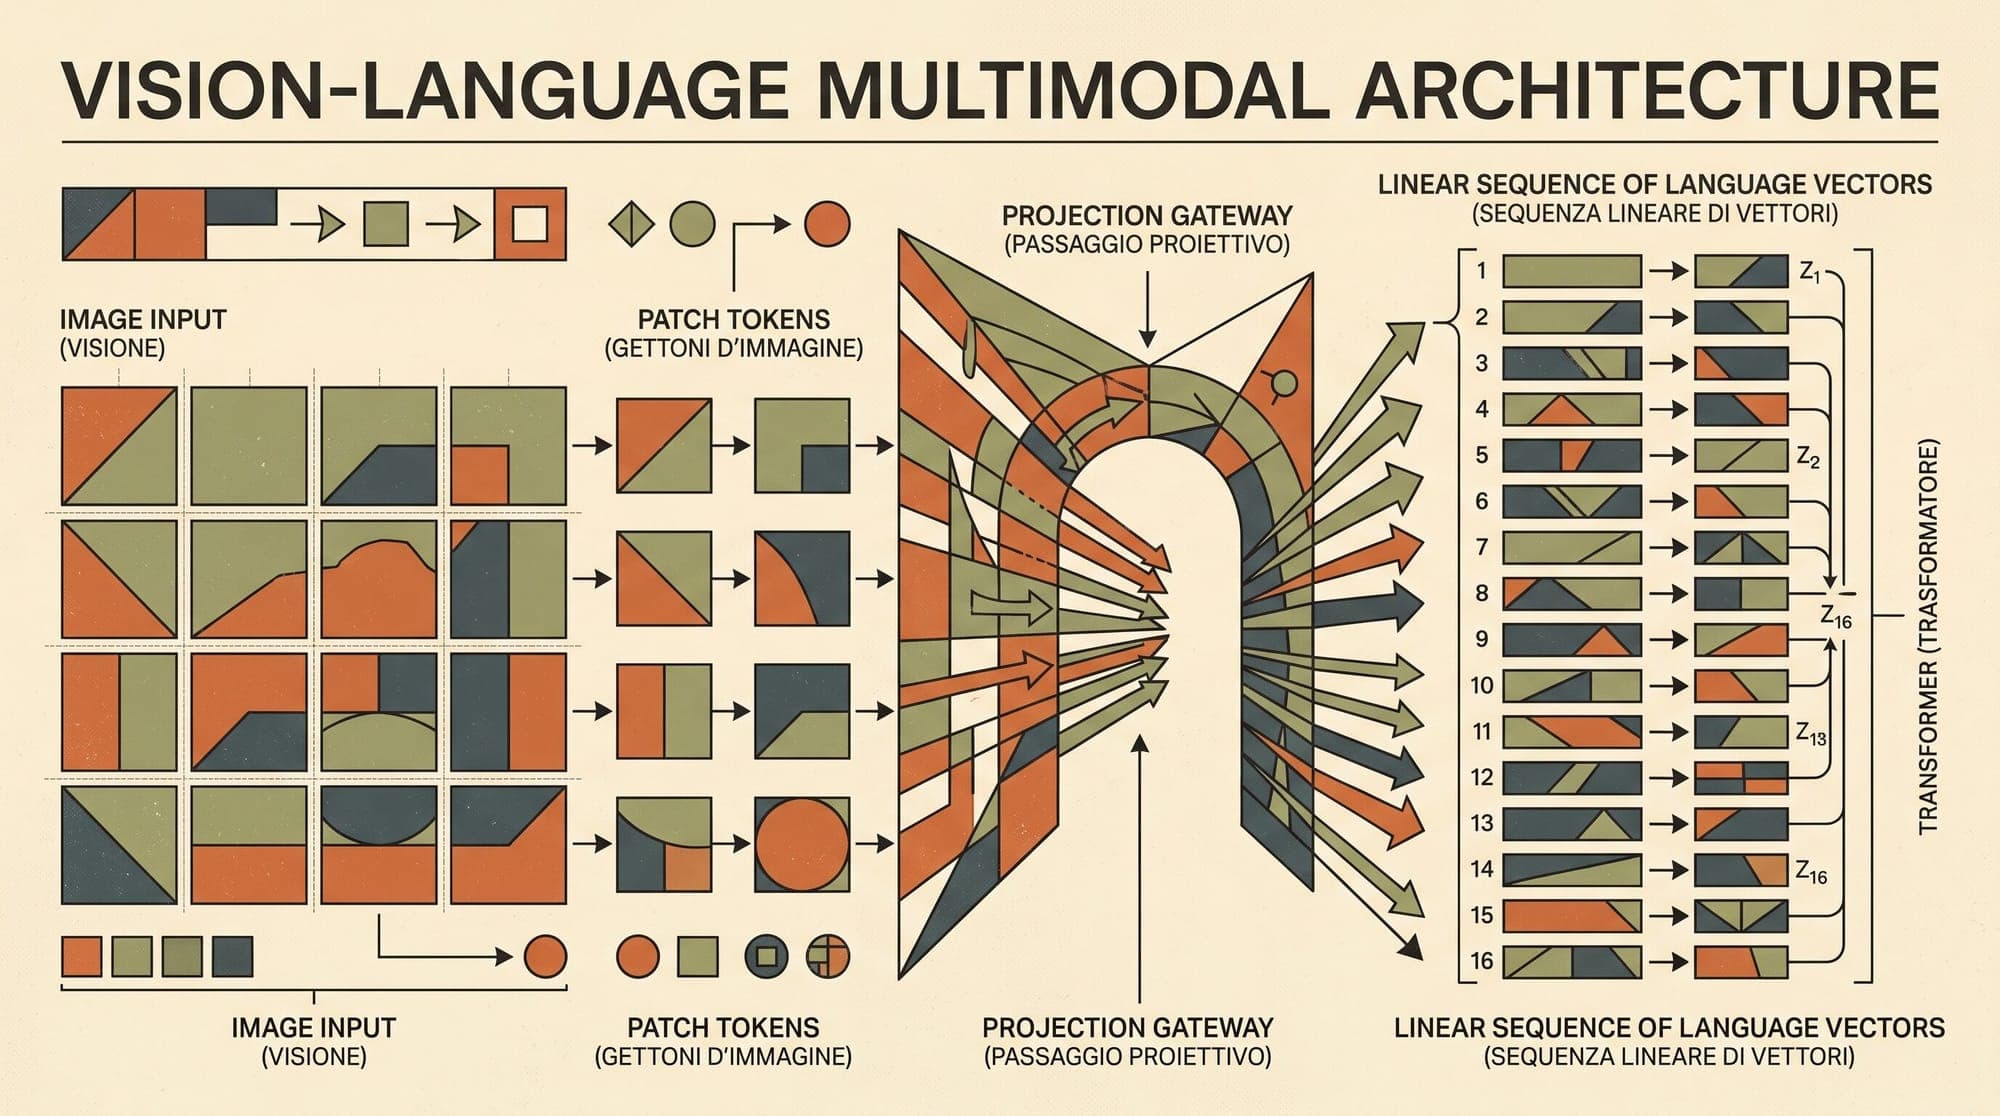
  20. Vision-Language Model Architectures: How Vision Encoders, Token Projectors, and Dynamic Resolution Bridge Modalities

    Modern large language models operate exclusively on discrete sequences of token embeddings. Integrating visual perception into these systems requires converting continuous, two-dimensional spatial arrays into linear sequences of embedding vectors that match the dimensionality and distribution of the language model's hidden states. Vision-language models (VLMs) like LLaVA, Flamingo, Qwen2-VL, and InternVL accomplish this conversion through a three-stage pipeline: a vision encoder, a cross-modal

    AI
    7 min read