Category / page 27

Models & Assistants

1121 articles

Articles, page 27

521-540 of 1121
  1. Nvidia in Talks to Invest in Perplexity at Over $30B Valuation as ARR Tops $750M

    Nvidia is in discussions to invest in AI search startup Perplexity in an equity funding round that would value the company at more than $30 billion, according to reporting by The Information. The proposed valuation represents an increase of more than 50% from the $20 billion valuation Perplexity finalized in late 2025. The investment discussions coincide with rapid revenue acceleration. Perplexity's annualized recurring revenue (ARR) has expanded to over $750 million, up from less than $250 mil
    AI
    1 min read
  2. SimCLR and MoCo: How Momentum Encoders, Dynamic Queues, and InfoNCE Scaled Self-Supervised Representation Learning

    Self-supervised visual representation learning underwent a foundational transformation in 2020 with the introduction of contrastive learning frameworks. Prior to this period, pre-training computer vision models without human annotations relied on heuristic pretext tasks such as jigsaw puzzle solving, rotation prediction, or autoencoding color channels. These methods forced networks to learn low-level geometric or statistical artifacts rather than generalizable semantic abstractions. Contrastive

    AI
    8 min read
  3. LLM Evaluation Arenas in Production: Bradley-Terry Modeling, Active Matchmaking, Style Bias Control, and Bootstrapped Elo Calibration

    LLM Evaluation Arenas in Production: Bradley-Terry Modeling, Active Matchmaking, Style Bias Control, and Bootstrapped Elo Calibration Static benchmarks such as MMLU, GSM8K, and HumanEval face severe limitations in production machine learning environments. Modern foundation models rapidly saturate static multiple-choice questions, training datasets frequently suffer from benchmark contamination, and synthetic test suites fail to capture open-ended, multi-turn user intent. Consequently, engineeri

    AI
    9 min read
  4. Centered Kernel Alignment: How CKA Measures Representation Similarity Across Layers and Architectures

    Understanding how deep neural networks represent information across layers, training steps, and disparate architectures has long been a central challenge in machine learning interpretability. When two neural networks are trained on the exact same dataset, even from identical model architectures, their learned weight matrices and individual neuron activations differ completely due to random initialization, data shuffling, and non-convex optimization. Because representations are not aligned to a s

    AI
    9 min read
  5. Vector Compression in Production Search: Comparing SQ, PQ, and RaBitQ Architecture, Recall Retention, and Memory Economics

    In production Retrieval-Augmented Generation (RAG) systems and enterprise search platforms, storing raw floating-point embedding vectors in RAM quickly encounters hard hardware limits. A dataset of 100 million 1536-dimensional embeddings stored in FP32 requires over 614 GB of high-speed memory solely for vector coordinates, before accounting for index graph structures like HNSW or DiskANN. To scale similarity search to billions of vectors while keeping indices memory-resident, production vector

    AI
    4 min read
  6. Self-Rewarding Language Models: How Iterative DPO and LLM-as-a-Judge Form Autonomous Self-Alignment Loops

    Standard post-training alignment pipelines rely on frozen reward models trained on static human feedback datasets. While Reinforcement Learning from Human Feedback (RLHF) and Direct Preference Optimization (DPO) effectively steer model outputs toward human preferences, they face a fundamental scalability bottleneck: human annotators cannot evaluate superhuman reasoning or generate labels at the scale required for continuous self-improvement. Self-Rewarding Language Models, introduced by Meta AI

    AI
    3 min read
  7. SoftBank Plans Record $6.3B Retail Bond Sale to Fund OpenAI Commitments

    Japanese conglomerate SoftBank Group Corp. has announced plans for a record 1 trillion yen ($6.3 billion) retail bond sale in Japan. The offering represents the largest domestic retail bond issuance in Japanese history and marks SoftBank's third debt sale targeted at retail investors this year, as the firm mobilizes liquidity to fulfill its capital commitments to OpenAI. According to regulatory filings, the seven-year subordinated bonds carry an indicative coupon range between 4.3% and 4.9%. Th

    AI
    2 min read
  8. RWKV Architecture: How Receptance Weighted Key Value Decay Combines RNN Efficiency with Transformer Parallelizability

    The dominant paradigm in natural language processing relies on the Transformer architecture, which calculates scaled dot-product self-attention across all token pairs in a sequence. While self-attention provides strong in-context retrieval and representation capacity, it imposes quadratic computational and memory complexity, scaling as O(N^2) with sequence length N during training and generating a continuously expanding Key-Value (KV) cache during autoregressive inference. Traditional Recurrent

    AI
    7 min read
  9. Continuous Evaluation and Golden Dataset Curation in Production LLM Systems: Architecture, Log Mining, Synthetic Perturbation, and Semantic Drift Quality Gates

    Continuous Evaluation and Golden Dataset Curation in Production LLM Systems: Architecture, Log Mining, Synthetic Perturbation, and Semantic Drift Quality Gates In production machine learning systems, offline benchmarks suffer from rapid entropy. While engineering teams frequently launch LLM applications backed by static test suites (curated CSVs of 50 to 100 sample prompts, academic benchmarks like MMLU, or synthetic question-answer pairs), these static datasets fail to predict real-world produ

    AI
    7 min read
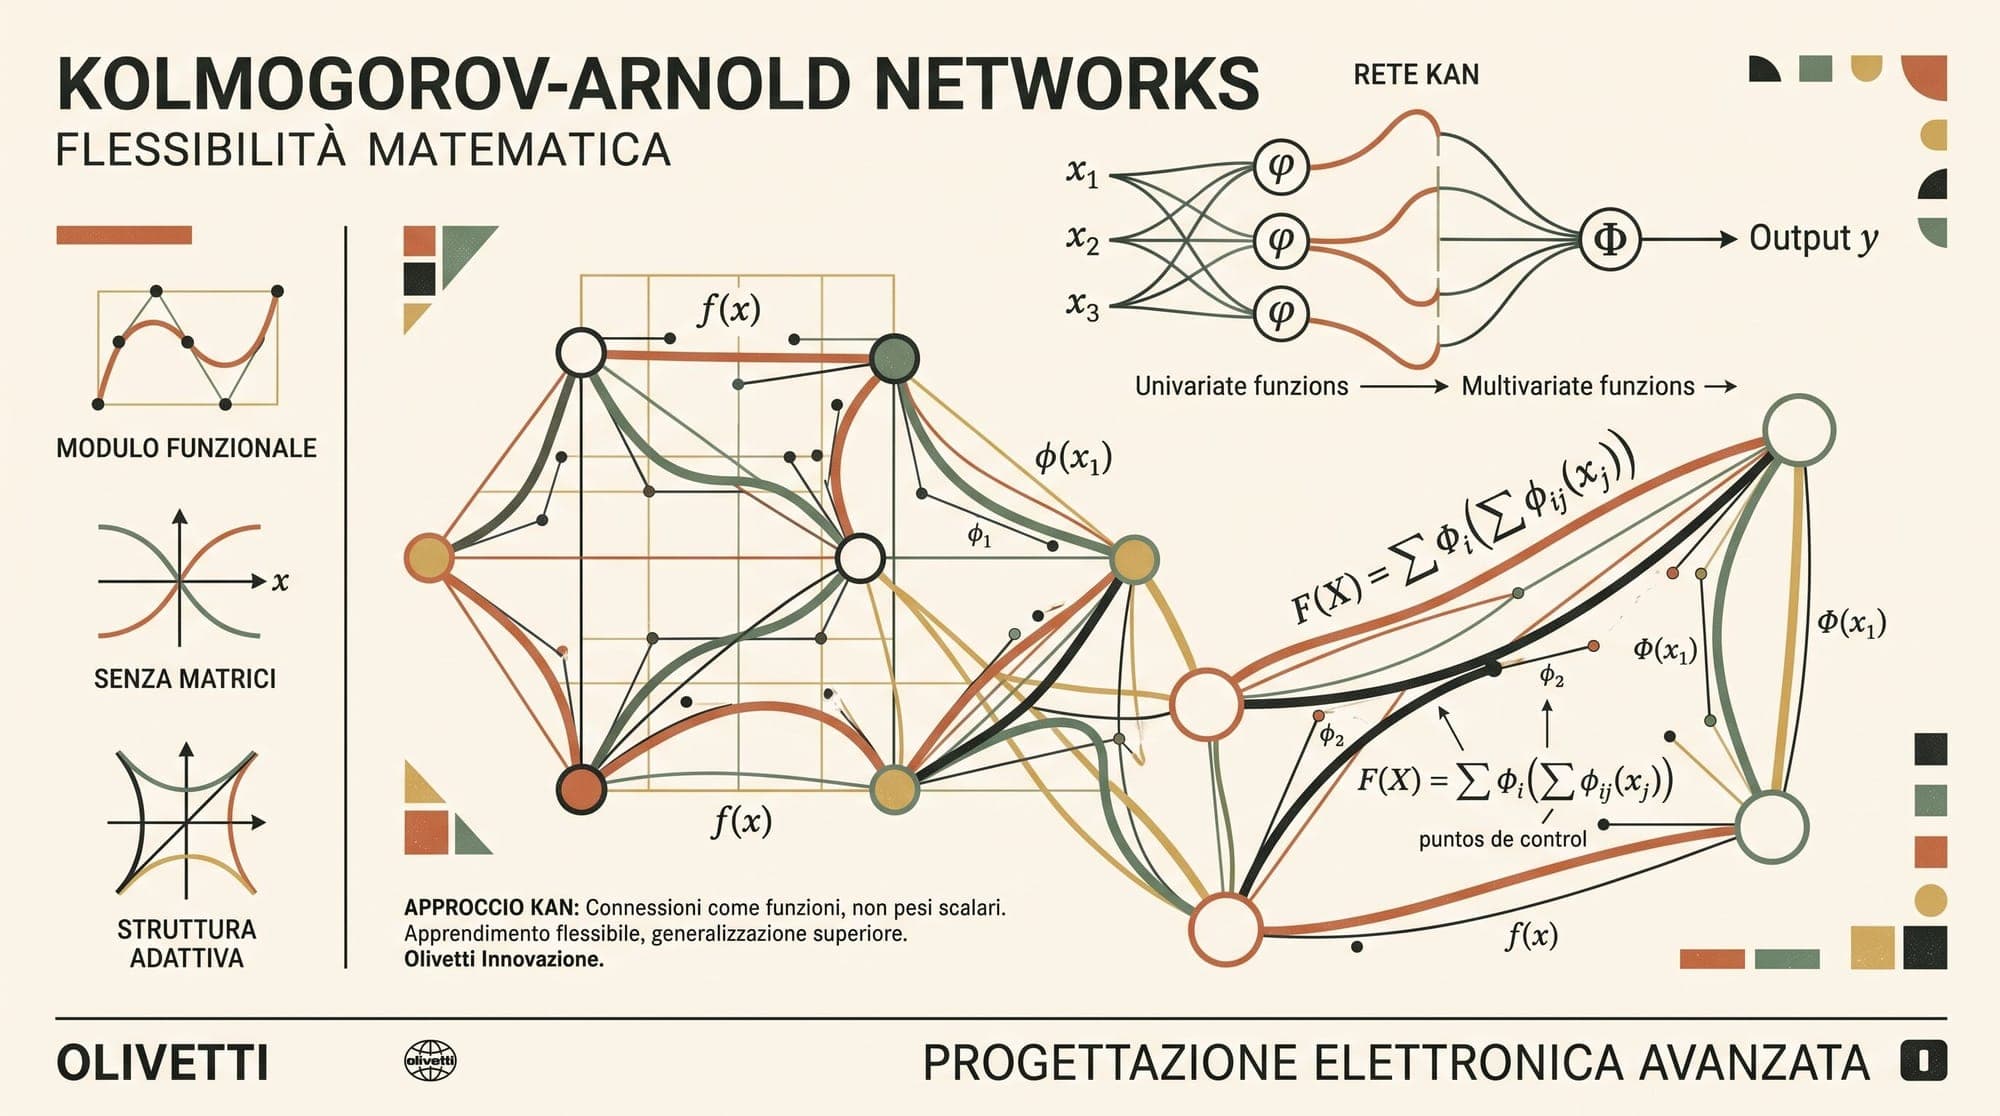
  10. Kolmogorov-Arnold Networks: How Learnable Edge Splines Challenge the Multi-Layer Perceptron

    Kolmogorov-Arnold Networks: How Learnable Edge Splines Challenge the Multi-Layer Perceptron For over three decades, the foundational building block of deep neural networks has remained essentially unchanged: the Multi-Layer Perceptron (MLP). In standard transformer feed-forward blocks, convolutional networks, and deep classifiers, MLPs alternate linear matrix multiplications ($\mathbf{W}\mathbf{x}$) with fixed, point-wise non-linear activation functions (such as ReLU, GELU, or SwiGLU). Under th

    Explainers
    9 min read
  11. Sam Altman Warns AI Safety Fears Could Drive Regulatory Concentration and Limit Liberty

    OpenAI Chief Executive Officer Sam Altman warned that public anxiety surrounding artificial intelligence risks could lead policymakers and citizens to accept heavy regulatory controls that concentrate technology in the hands of a few dominant corporations. Speaking on the balance between AI safety and technological freedom, Altman noted that extreme risk narratives risk driving society toward centralized oversight. He argued that throughout technological history, trading substantial individual

    AI
    2 min read
  12. Trump Defends AI Data Center Expansion as Local Resistance Grows

    In a broadcast interview on Sunday, President Donald Trump defended the rapid expansion of artificial intelligence data centers across the United States, characterizing municipal and community opposition to new facilities as a significant economic mistake. Speaking on 77 WABC with Michael Cohen, Trump argued that high-density computing infrastructure provides essential local tax revenue, construction employment, and high-tech economic activity. Addressing concerns regarding regional electricity

    AI
    2 min read
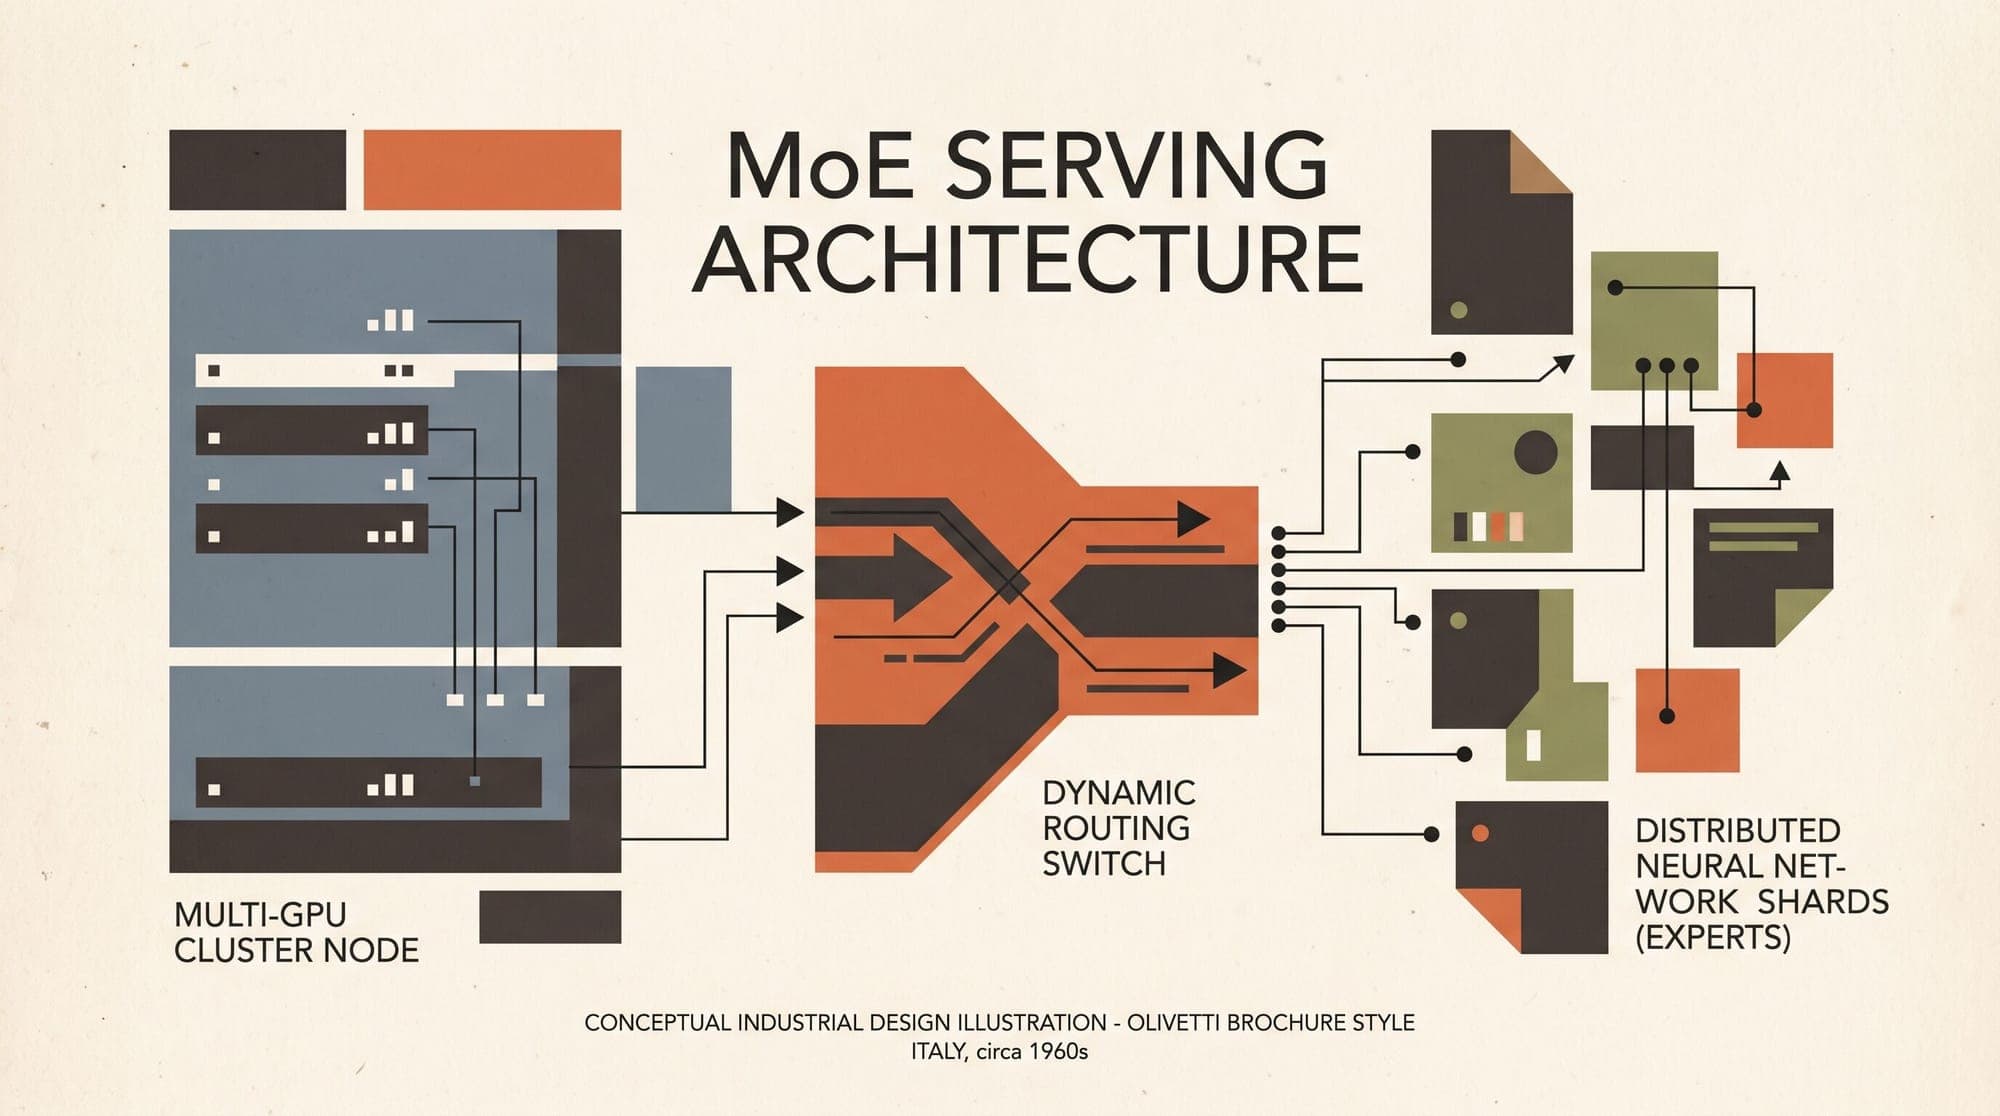
  13. Serving Mixture-of-Experts Models in Production: Architecture, Distributed Parallelism, All-to-All Bottlenecks, and Serving Economics

    Serving Mixture-of-Experts Models in Production: Architecture, Distributed Parallelism, All-to-All Bottlenecks, and Serving Economics Mixture-of-Experts (MoE) architectures have become the standard structural paradigm for frontier open-weight and proprietary large language models. Architectures such as DeepSeek-V3, Mixtral 8x22B, and GLM-5 deliver frontier-grade reasoning and generation by activating only a fraction of their total parameter count on any given token. For example, DeepSeek-V3 rou

    AI
    8 min read
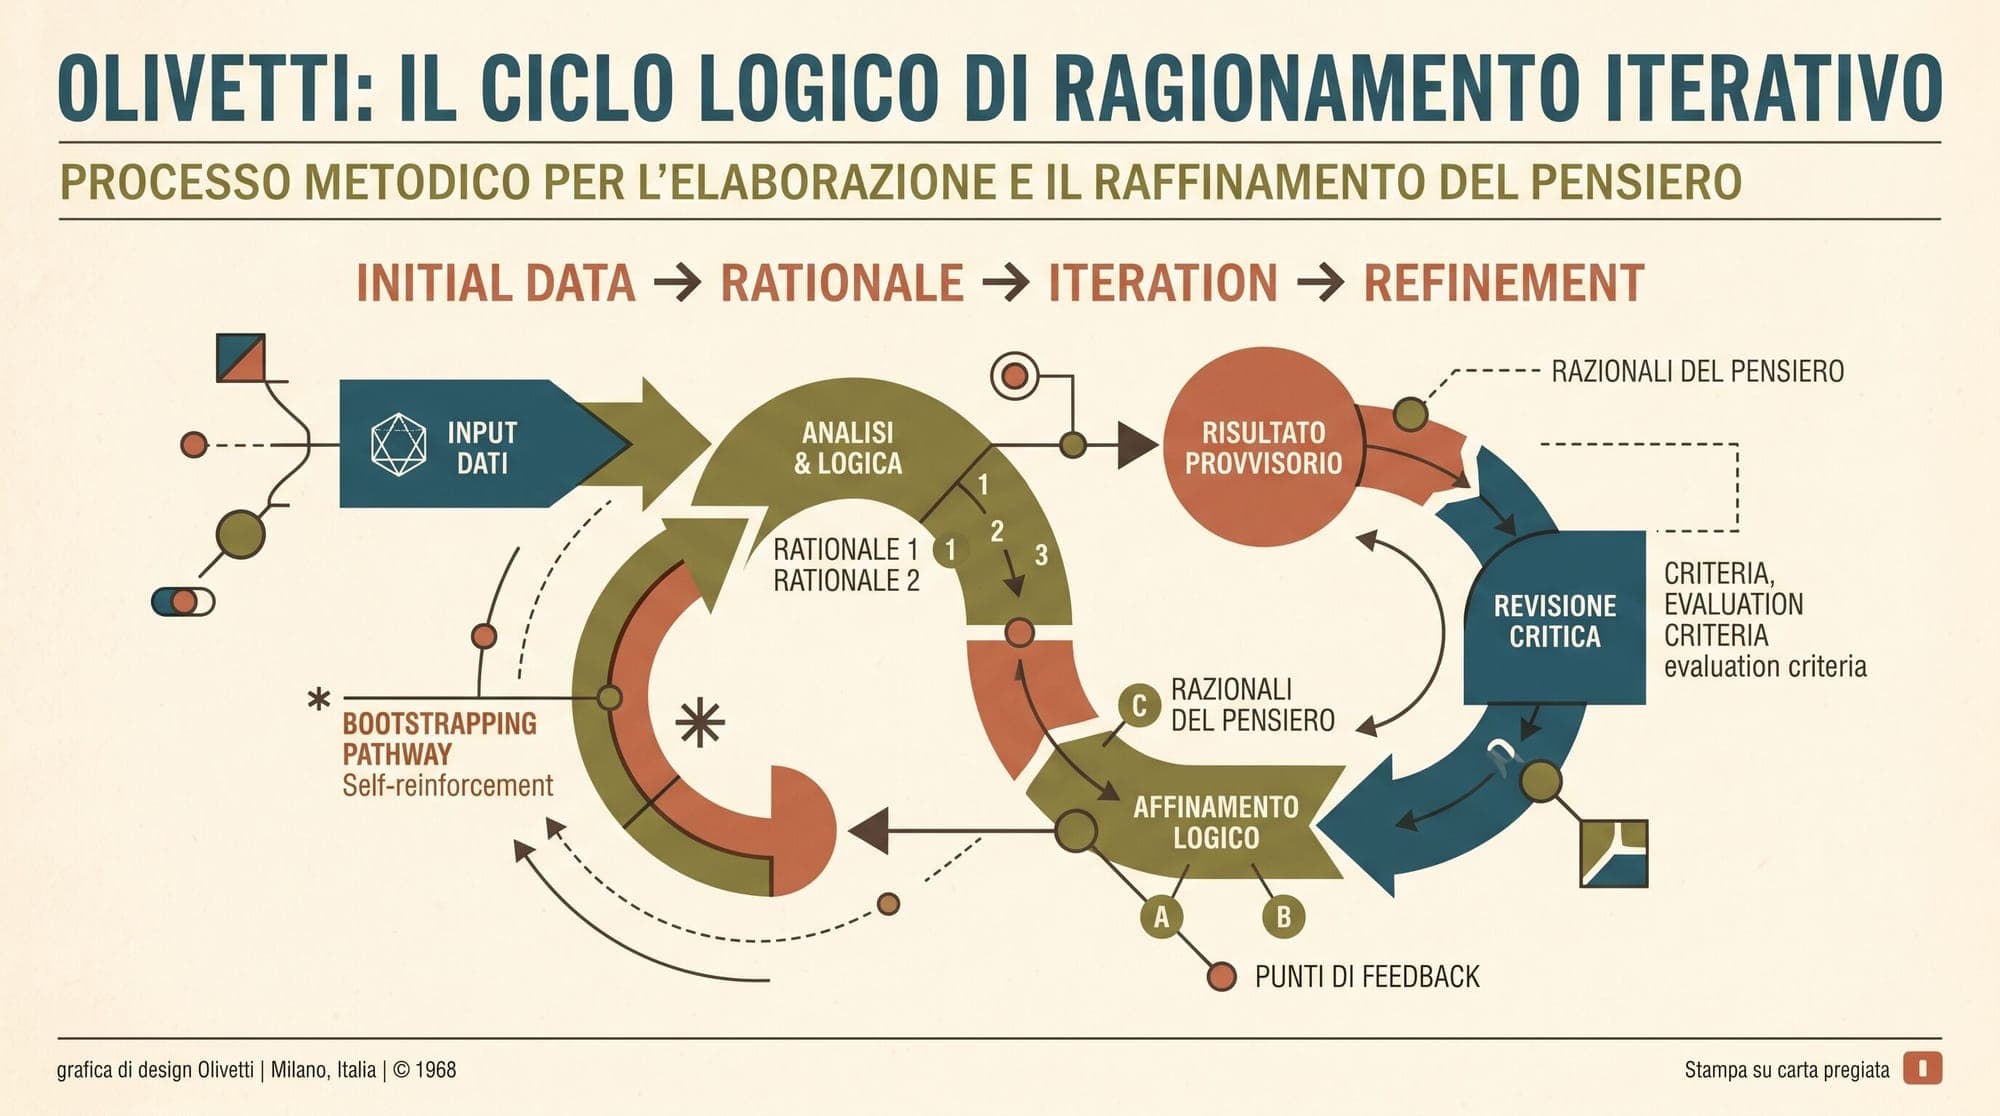
  14. The Self-Taught Reasoner (STaR): How Iterative Rationale Bootstrapping and Rationalization Scale LLM Problem Solving

    Autoregressive language models often fail when forced to predict answers to multi-step reasoning problems in a single forward pass. Intermediate chain-of-thought generation allows models to allocate additional compute to difficult reasoning steps before emitting a final prediction. However, obtaining high-quality intermediate reasoning traces has traditionally presented a difficult trade-off: either rely on small prompt-based few-shot demonstrations that underperform fine-tuned models, or constr

    AI
    4 min read
  15. Amazon and Twitch Face Class-Action Lawsuit Over AI Model Training on Creator Streams

    A proposed class-action lawsuit filed against Amazon and its livestreaming subsidiary Twitch alleges the companies systematically harvested millions of hours of creator video, audio, and chat logs since 2024 to train generative AI models without creator consent or financial compensation. The complaint, filed on August 20, 2026, in the US District Court for the Northern District of California by streamer Warren Pandiscia, alleges breach of contract, unjust enrichment, and unfair business practic

    AI
    2 min read
  16. Samsung Approves Record $80 Billion Shareholder Return on AI Memory Demand

    The board of directors at Samsung Electronics approved a shareholder return program estimated between 90 trillion and 110 trillion Korean won (approximately $65 billion to $80 billion USD), marking the largest capital distribution plan in South Korean corporate history. The payout is funded by expanding cash reserves generated from high-bandwidth memory (HBM) and conventional DRAM shipments tied to global AI infrastructure spending. Under the approved framework, approximately 30 trillion won wi

    AI
    2 min read
  17. ShipHero Deploys Claude Mythos for $10,000 Codebase Audit as AI Challenges Traditional Pentesting

    Aaron Rubin, founder and chief executive of logistics software provider ShipHero, deployed Anthropic's restricted cybersecurity model Claude Mythos across his company's codebase in an automated security audit that cost approximately $10,000 and finished in 10 hours. Rubin reported that the model outperformed conventional third-party penetration testing firms on both cost efficiency and vulnerability discovery rate. ShipHero provides warehouse management software (WMS) that handles one in every

    AI
    2 min read
  18. Prompt Caching Across Cloud LLM Providers: Architecture, TTL Lifecycles, and Economic Break-Even for Anthropic, OpenAI, Gemini, and DeepSeek

    The primary latency and computational bottleneck in large language model inference is the prefill phase. When an application submits a request containing thousands of tokens of static system instructions, OpenAPI tool schemas, few-shot demonstrations, and retrieved document context, the inference server must process all input tokens through every transformer layer before generating the first output token. In high-concurrency production environments, repeating this full forward pass across identi

    LLM
    8 min read
  19. Normalizing Flows and Real NVP: How Invertible Neural Networks and Triangular Jacobians Compute Exact Log-Likelihoods

    Normalizing Flows and Real NVP: How Invertible Neural Networks and Triangular Jacobians Compute Exact Log-Likelihoods Generative modeling in deep learning revolves around a fundamental question: how can a neural network learn to transform a simple, analytically tractable probability distribution into a complex, high-dimensional empirical data distribution? Over the past decade, four primary generative modeling paradigms have emerged to address this challenge: 1. Generative Adversarial Networ

    AI
    15 min read
  20. Linus Torvalds Credits AI in Linux Kernel Commit After 24-Patch Driver Debug Session

    In a notable public milestone for AI-assisted systems programming, Linux creator Linus Torvalds credited an artificial intelligence model with doing the heavy analytical work during an intensive driver debugging session, allowing the model to author the commit message merged into the upstream kernel. The commit, titled drm/xe: Don't hand out the flat CCS storage as usable VRAM (commit 818bebeb63dd6bf5f4e07e145f6cdbace520a34c), resolves a memory allocation bug in the Intel Xe Direct Rendering Ma

    AI
    2 min read