Grouped-Query Attention: How Head Sharing Slashed KV Cache Memory and Scaled LLM Serving
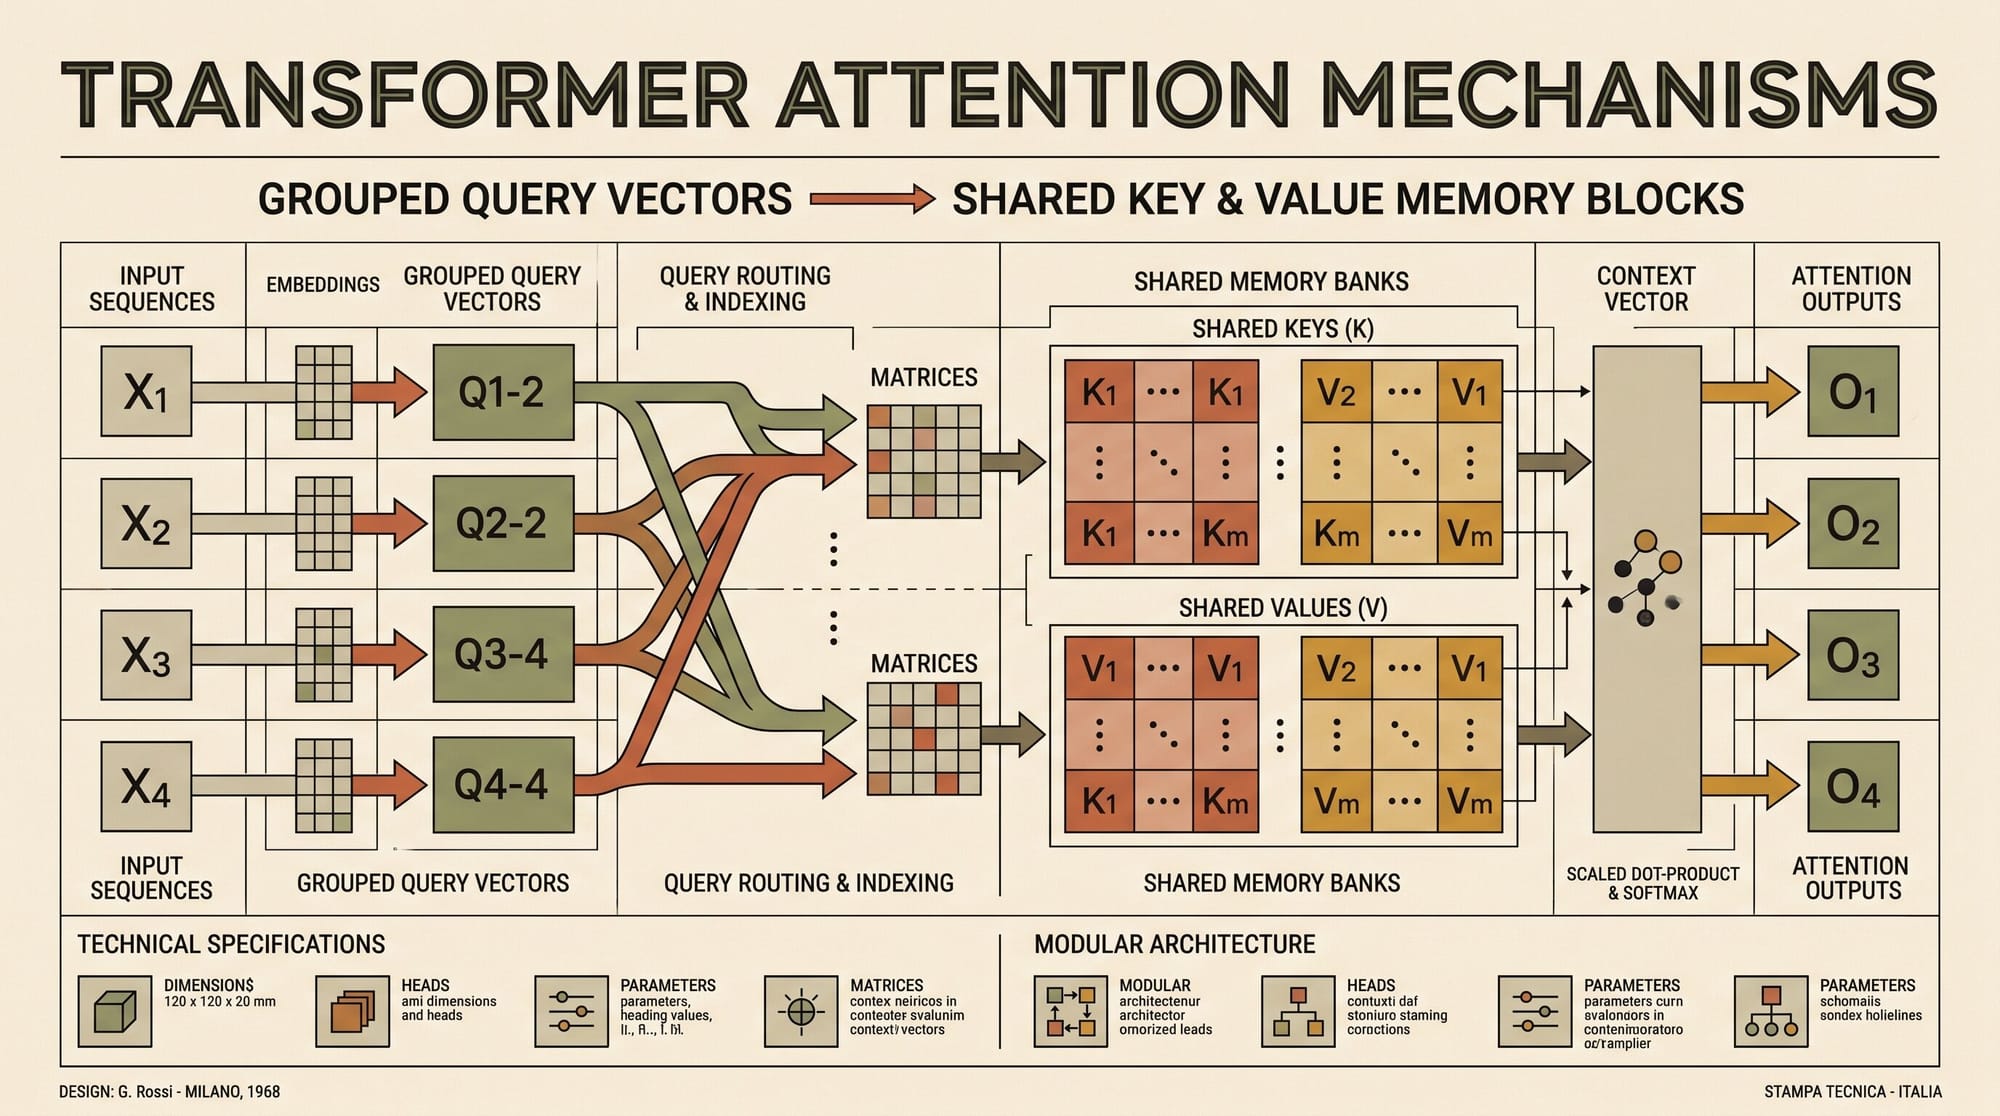
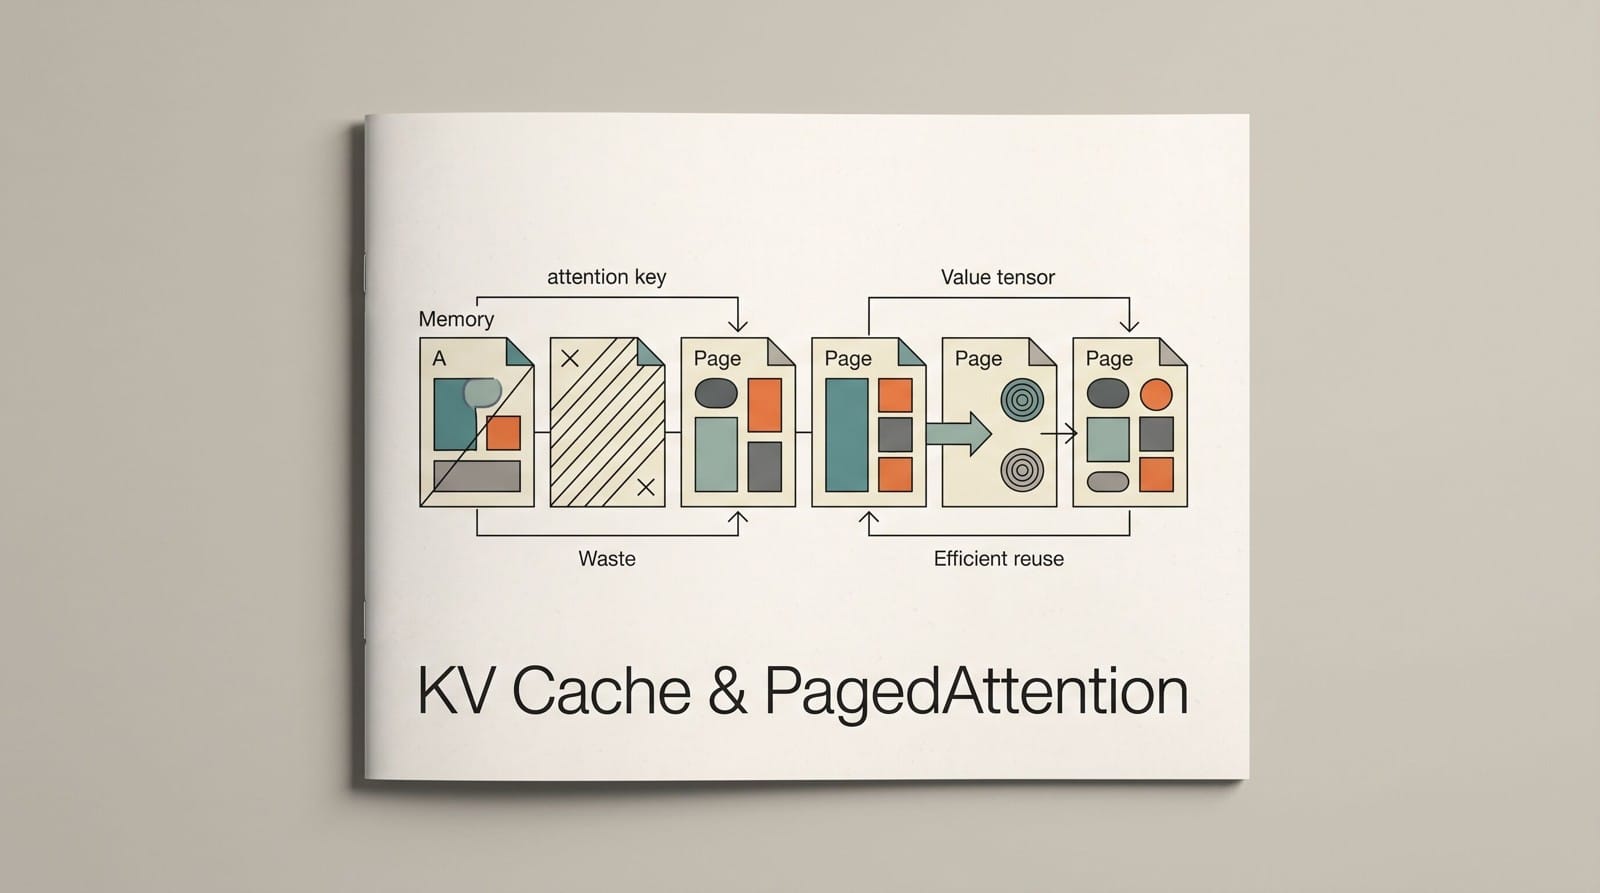
Serving large language models at scale presents a fundamental hardware bottleneck: autoregressive decoding is bound by memory bandwidth rather than compute. While the initial prompt processing phase (prefill) operates as compute-bound matrix multiplications, token-by-token generation requires loading billions of cached attention states from GPU High-Bandwidth Memory (HBM) to on-chip SRAM for every single generated token. Multi-Head Attention (MHA), introduced in the foundational Vaswani et al.