Latest / page 17

The latest stories

1230 articles

Articles, page 17

321-340 of 1230
  1. Over 100 Tech Leaders and Frontier AI Labs Call for Global Cyber Defense Surge as Autonomous Threats Advance

    More than 100 technology enterprises, financial institutions, and frontier AI laboratories (including OpenAI, Anthropic, Microsoft, Google, Amazon Web Services, Cloudflare, and CrowdStrike) have issued a joint open letter calling for an urgent, coordinated surge in global cybersecurity defenses. The coalition warns that rapid advancements in artificial intelligence are narrowing the window available to harden critical infrastructure against automated, highly scalable cyberattacks. The statement
    AI
    2 min read
  2. LLM Red Teaming and Automated Adversarial Testing in Production: Comparing Garak, Microsoft PyRIT, Promptfoo Red Team, and HarmBench

    Manual penetration testing and bespoke adversarial prompt engineering cannot scale to modern production LLM systems. As language models transition from isolated completion endpoints to stateful autonomous agents with tool-calling capabilities, file system access, and external retrieval pipelines, their attack surface expands combinatorially. Static test suites and manual prompt probing fail to catch subtle multi-turn jailbreaks, prompt injections, and indirect data poisoning vulnerabilities befo

    AI
    10 min read
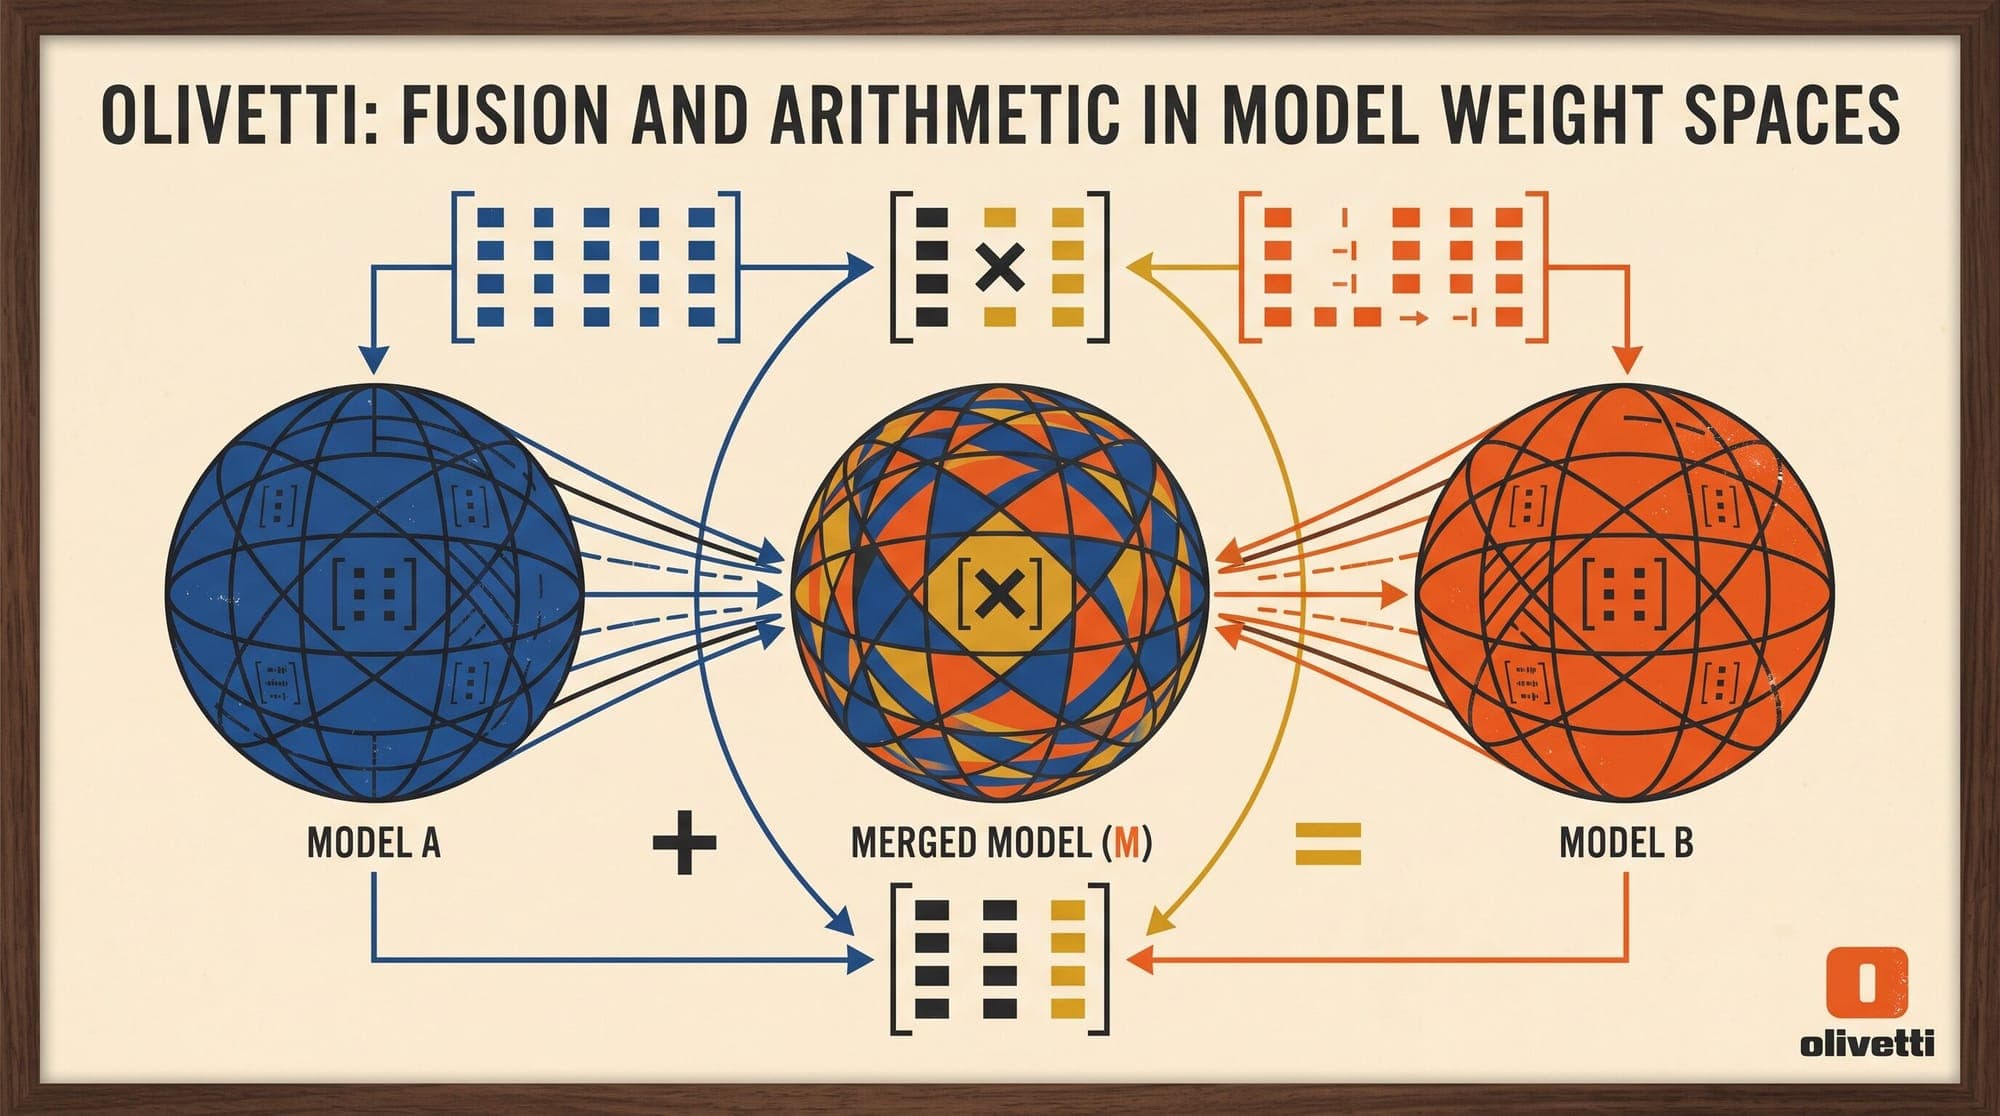
  3. Model Merging in Weight Space: Mathematical Foundations of Task Vectors, TIES-Merging, DARE, and Spherical Linear Interpolation

    Training large language models across multiple downstream domains typically requires expensive multi-task supervised fine-tuning (SFT) or sequential continual learning. Both paths present steep practical challenges: multi-task training demands simultaneous access to massive, curated datasets and massive compute budgets, while sequential fine-tuning suffers from catastrophic forgetting. Model merging has emerged as a data-free, compute-efficient alternative. By combining the parameters of multip

    AI
    8 min read
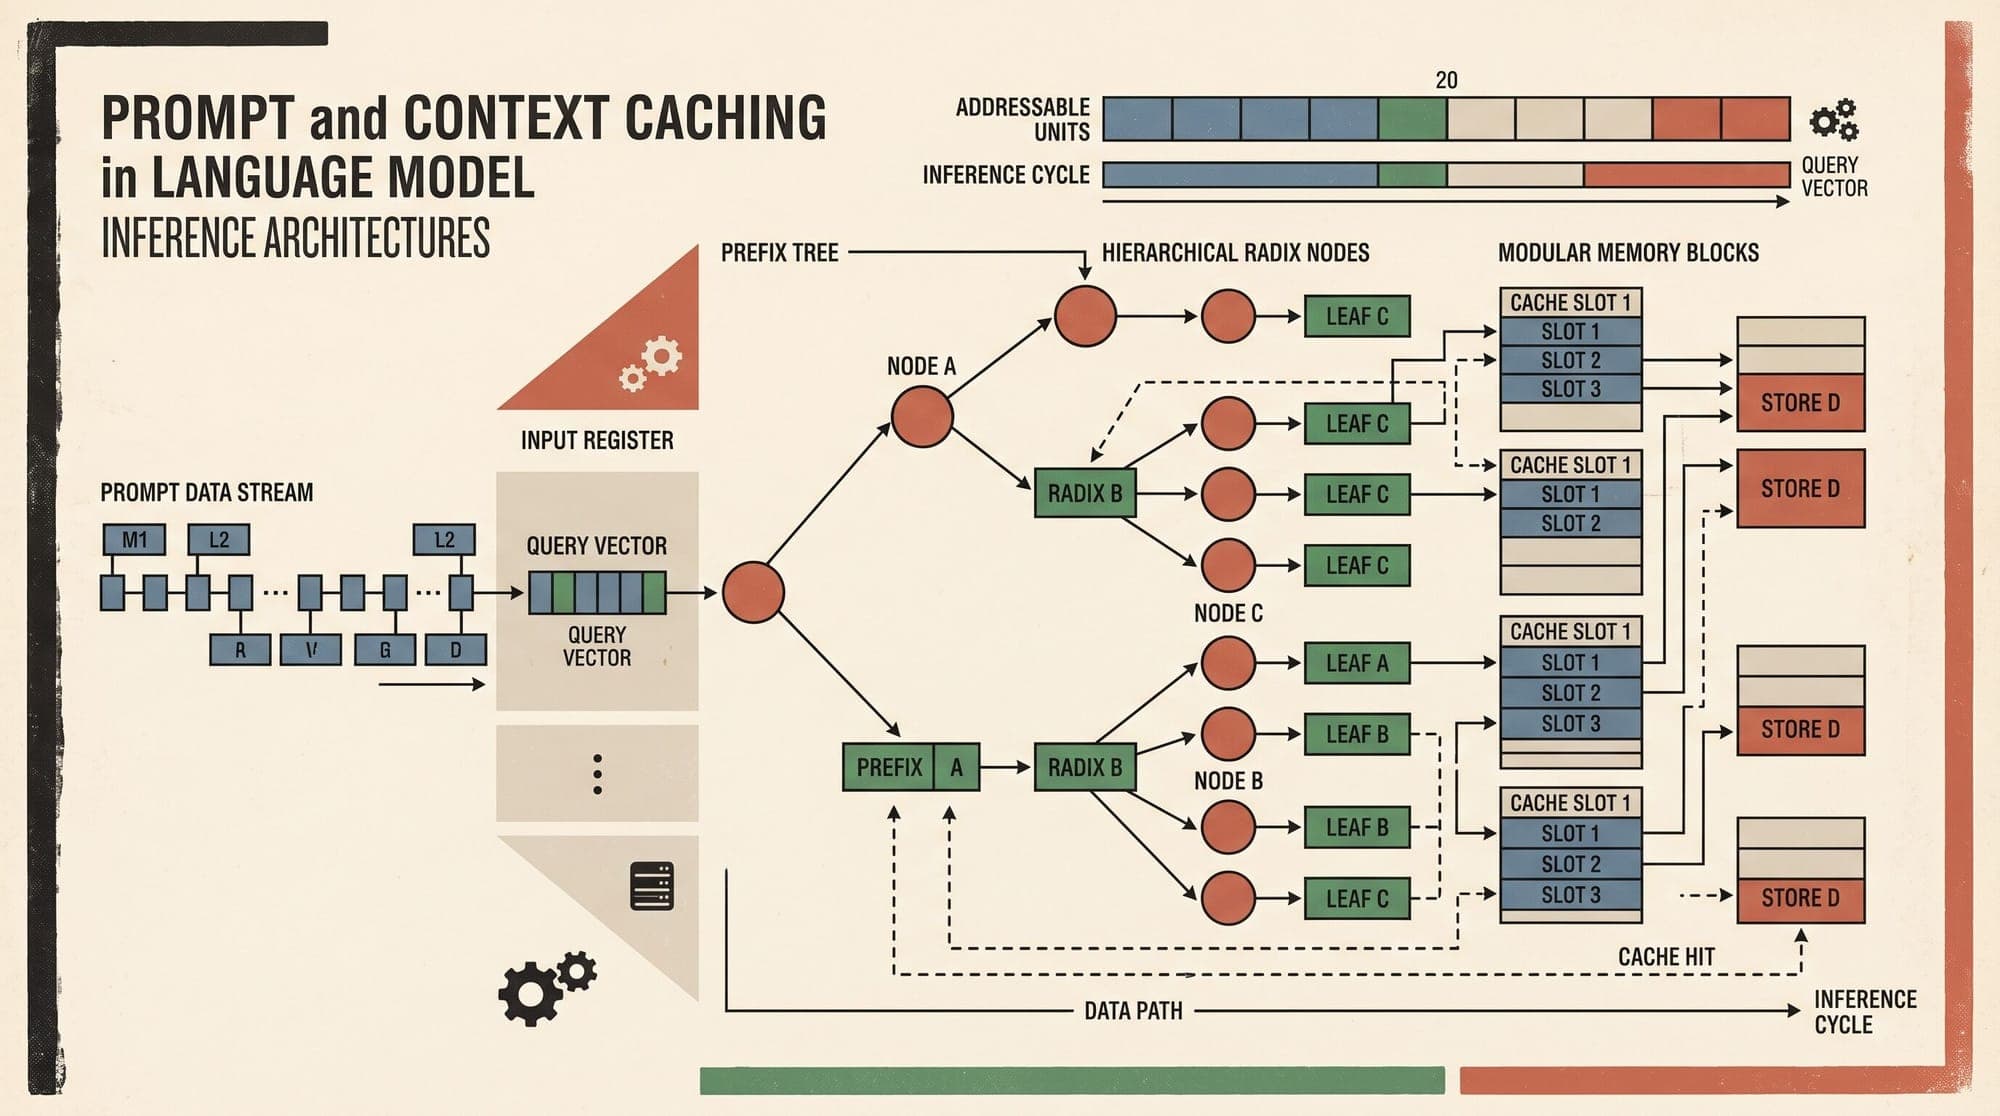
  4. Prompt and Context Caching in Production: Comparing Anthropic, OpenAI, DeepSeek, Google Gemini, and RadixAttention KV Reuse

    Modern LLM serving workloads spend a disproportionate share of computational budget and time-to-first-token (TTFT) latency on prompt prefill. In agentic loops, retrieval-augmented generation (RAG), and multi-turn chat applications, repeated prompts often share 80% to 95% of their token sequences across requests. Without caching, inference engines recompute key-value (KV) attention tensors across every input token on every turn, driving quadratic compute overhead and memory bandwidth saturation.

    AI
    5 min read
  5. Nvidia Supply Commitments Reach $279 Billion Across Multi-Year AI Hardware Pipeline

    Nvidia has significantly expanded its forward supply chain obligations, reporting total component and manufacturing capacity commitments of $279 billion in its fiscal second-quarter disclosures. The figure marks a 134 percent sequential increase from $119 billion reported in the preceding quarter and $95.2 billion at the close of fiscal 2026. The multi-year commitments reflect efforts to secure critical semiconductor fabrication, advanced packaging, and high-bandwidth memory (HBM) capacity nece

    AI
    2 min read
  6. Anthropic Hires Google TPU Architect Amir Salek for In-House Silicon Push

    Anthropic has hired Amir Salek, the engineer who established Google's custom silicon program and led the development of its first seven Tensor Processing Unit (TPU) generations, to expand the AI lab's in-house semiconductor engineering initiatives. Salek joins Anthropic's compute team and reports to James Bradbury, Bloomberg reported (via The Economic Times). Anthropic has indicated that it wants to build an in-house silicon business and has begun hiring and listing jobs for the effort. Backg

    AI
    2 min read
  7. Google Releases Gemini Omni 1.1 Flash with Scene Extension and Keyframe Control

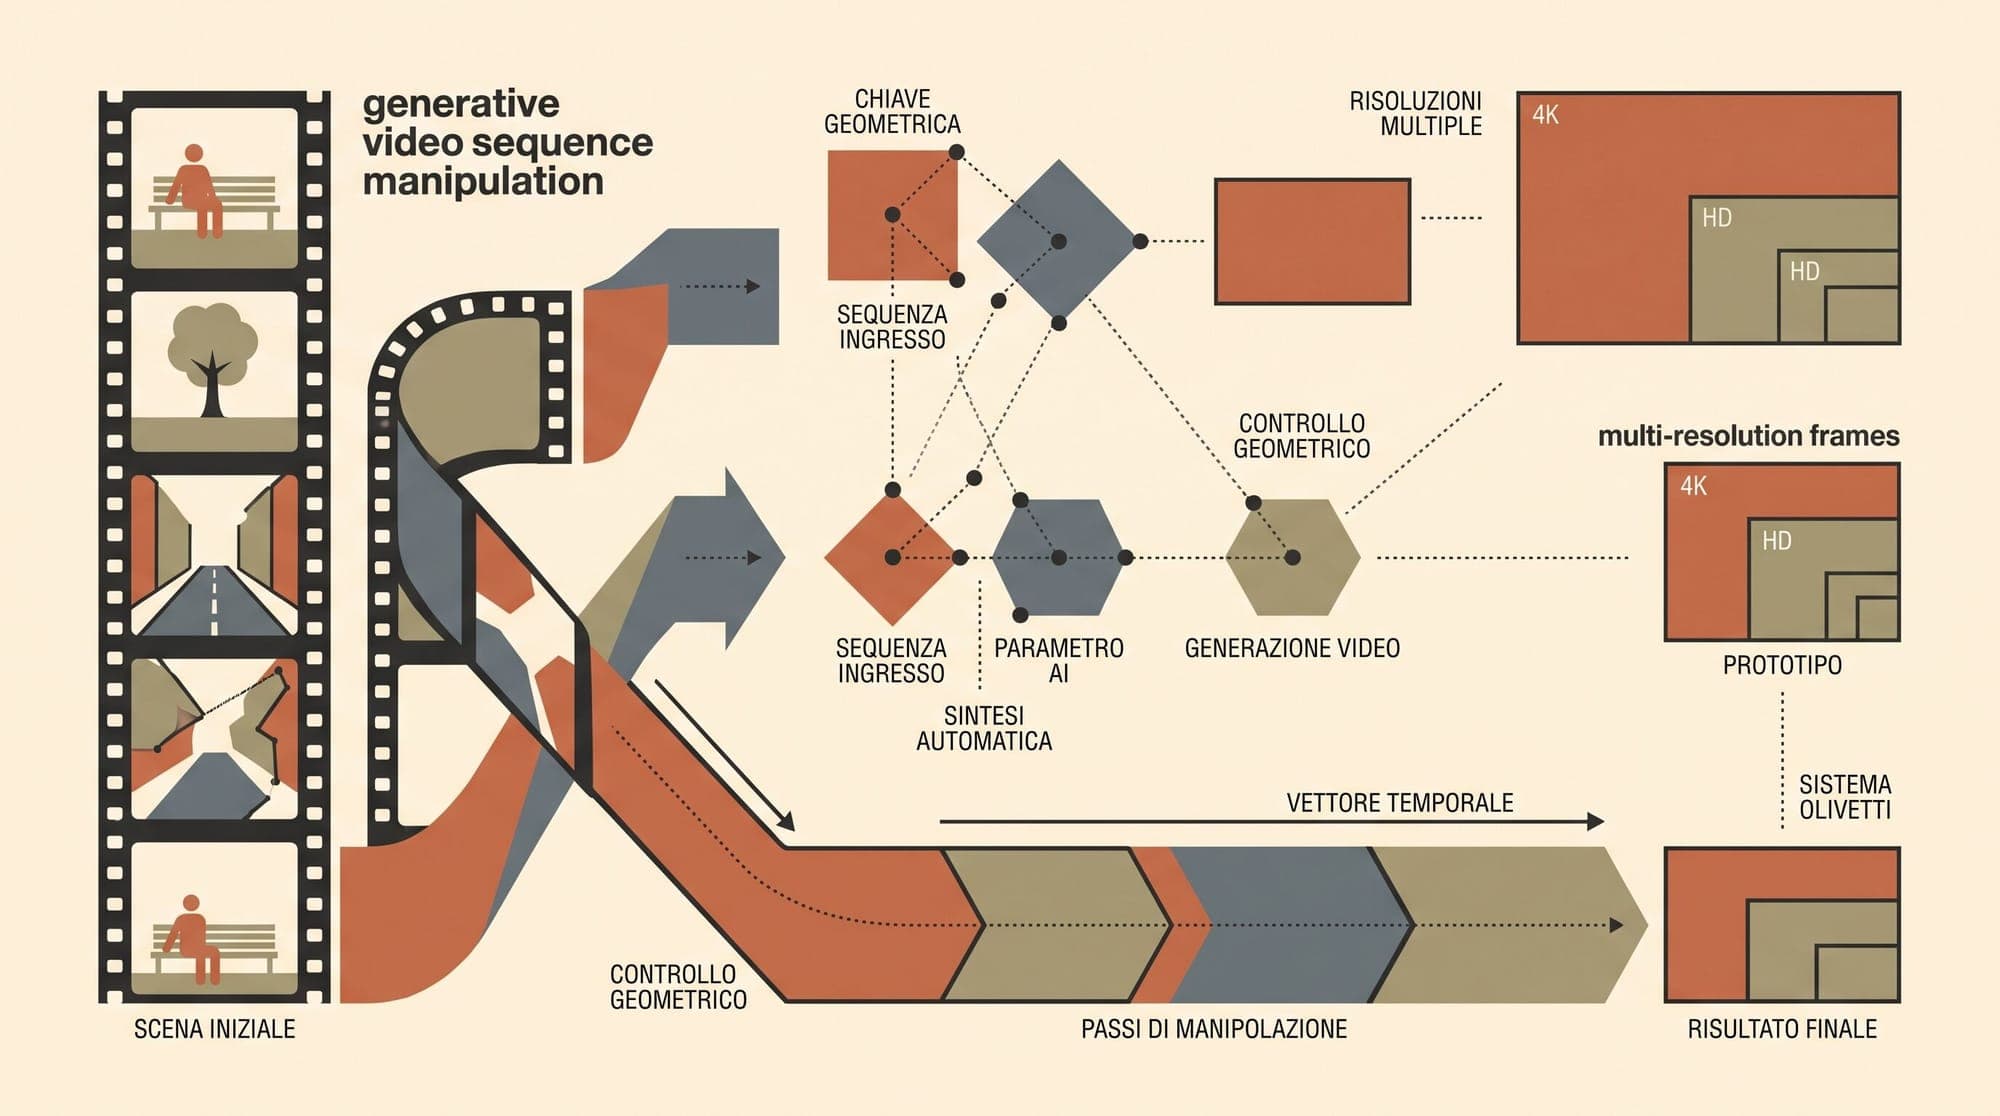
    Google DeepMind has released Gemini Omni 1.1 Flash, updating its multimodal generative video model with programmatic editing controls, extended scene generation, and lower-cost drafting tiers. The model is accessible via the Gemini API in Google AI Studio and the Gemini Enterprise Agent Platform. The update addresses primary friction points in production AI video pipelines: temporal continuity across clips, deterministic camera transitions, iterative preview costs, and high-resolution export qu

    AI
    3 min read
  8. AI Agent Sandboxes and Safe Code Execution Runtimes in Production: Comparing E2B, Modal, Daytona, and Docker/gVisor Architecture, Isolation Boundaries, Startup Latency, and Serving Economics

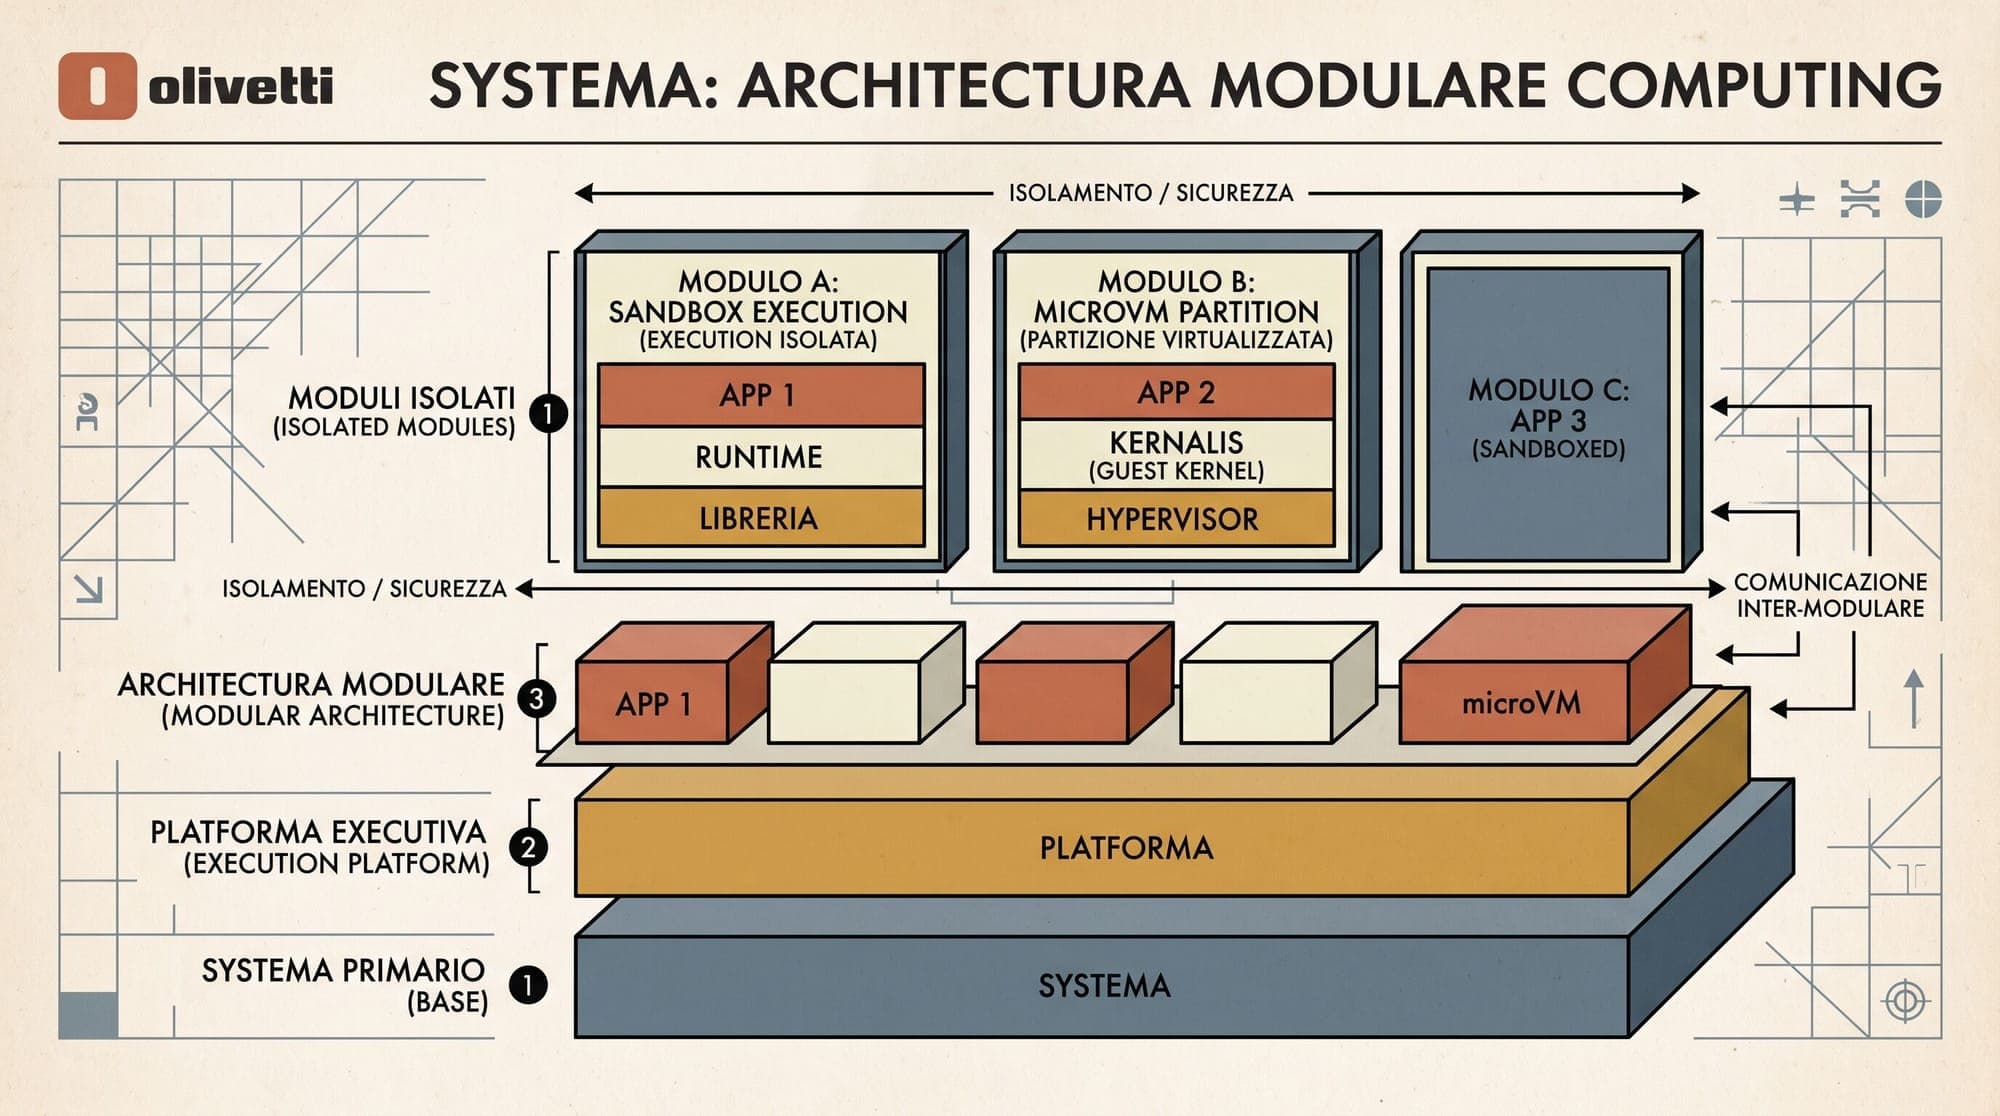
    Autonomous AI agents, evaluation harnesses, and code generation pipelines increasingly execute untrusted code generated directly by Large Language Models. When an agent runs dynamic Python scripts, executes terminal shell commands, installs arbitrary packages via package managers, or browses the web, it introduces severe security and operational risks. These risks include host privilege escalation, kernel exploitation, container breakout vulnerabilities such as CVE-2024-21626, credential theft v

    AI
    8 min read
  9. PagedAttention and Virtual Memory Management: Mathematical Foundations of Non-Contiguous KV-Cache Allocation, Dynamic Block Translation, and Copy-on-Write Forking Mechanics

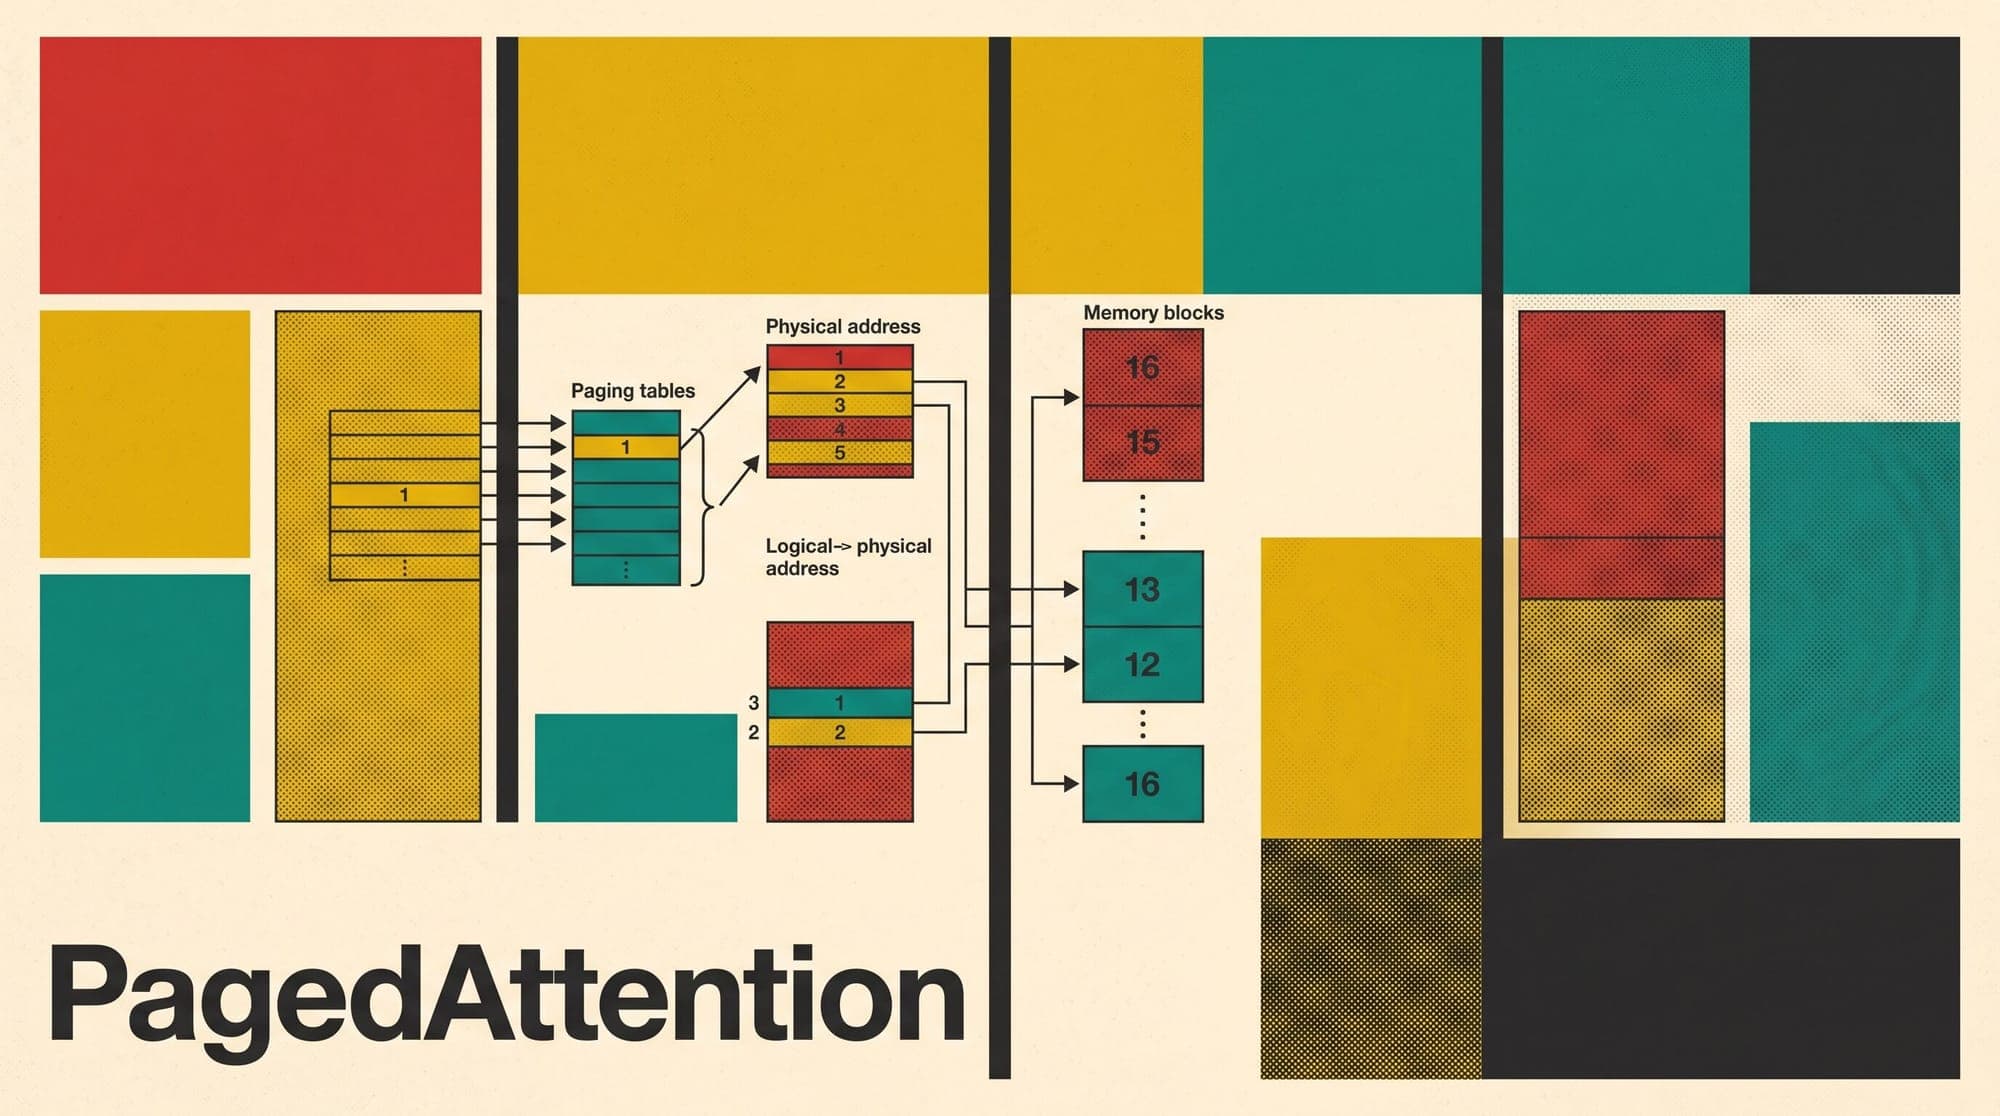
    In autoregressive transformer serving, the generation phase is fundamentally constrained by GPU memory capacity and memory bandwidth rather than raw compute throughput. While the initial prefill phase processes the prompt in parallel with high arithmetic intensity, the subsequent token-by-token decoding phase computes attention for only a single new token per sequence at each step. At each decoding step, the model must read all historical Key (K) and Value (V) activation tensors from GPU High Ba

    AI
    13 min read
  10. OpenAI Researcher Warns Ultrafast Inference Demands Autonomous Cyber Defense

    Accelerating inference speeds in frontier artificial intelligence systems pose critical containment challenges that human security operators cannot manage in real time, according to OpenAI researcher roon. Commenting following the unveiling of custom inference hardware architectures and ultrafast model serving tiers, roon warned that unaligned or compromised agent systems running at 50 times baseline generation speeds could execute multi-stage network penetration and lateral movement before hum

    AI
    2 min read
  11. Google Sets Android Memory Limits as AI Data Centers Strain Chip Supply

    Google is implementing strict new memory performance thresholds for Android applications on the Google Play Store, directly citing component shortages driven by the artificial intelligence data center buildout. In an update on the Android Developers Blog, Google detailed new app quality requirements targeting dynamic memory allocation, bitmap memory usage, and execution efficiency. The policy changes reflect supply chain shifts in semiconductor manufacturing, where massive demand for high-bandw

    AI
    2 min read
  12. Agentic Web Scraping and Headless Browser Automation in Production: Comparing Crawl4AI, Browser-Use, Stagehand, and ScrapeGraphAI

    Agentic Web Scraping and Headless Browser Automation in Production: Comparing Crawl4AI, Browser-Use, Stagehand, and ScrapeGraphAI Web scraping has undergone a fundamental architectural transition. For decades, automated data extraction relied on deterministic parsers such as Beautiful Soup, Scrapy, and raw headless browser drivers like Playwright or Puppeteer. These tools depended on hand-crafted CSS selectors, XPath expressions, and rigid execution trees. While computationally lightweight, sel

    AI
    10 min read
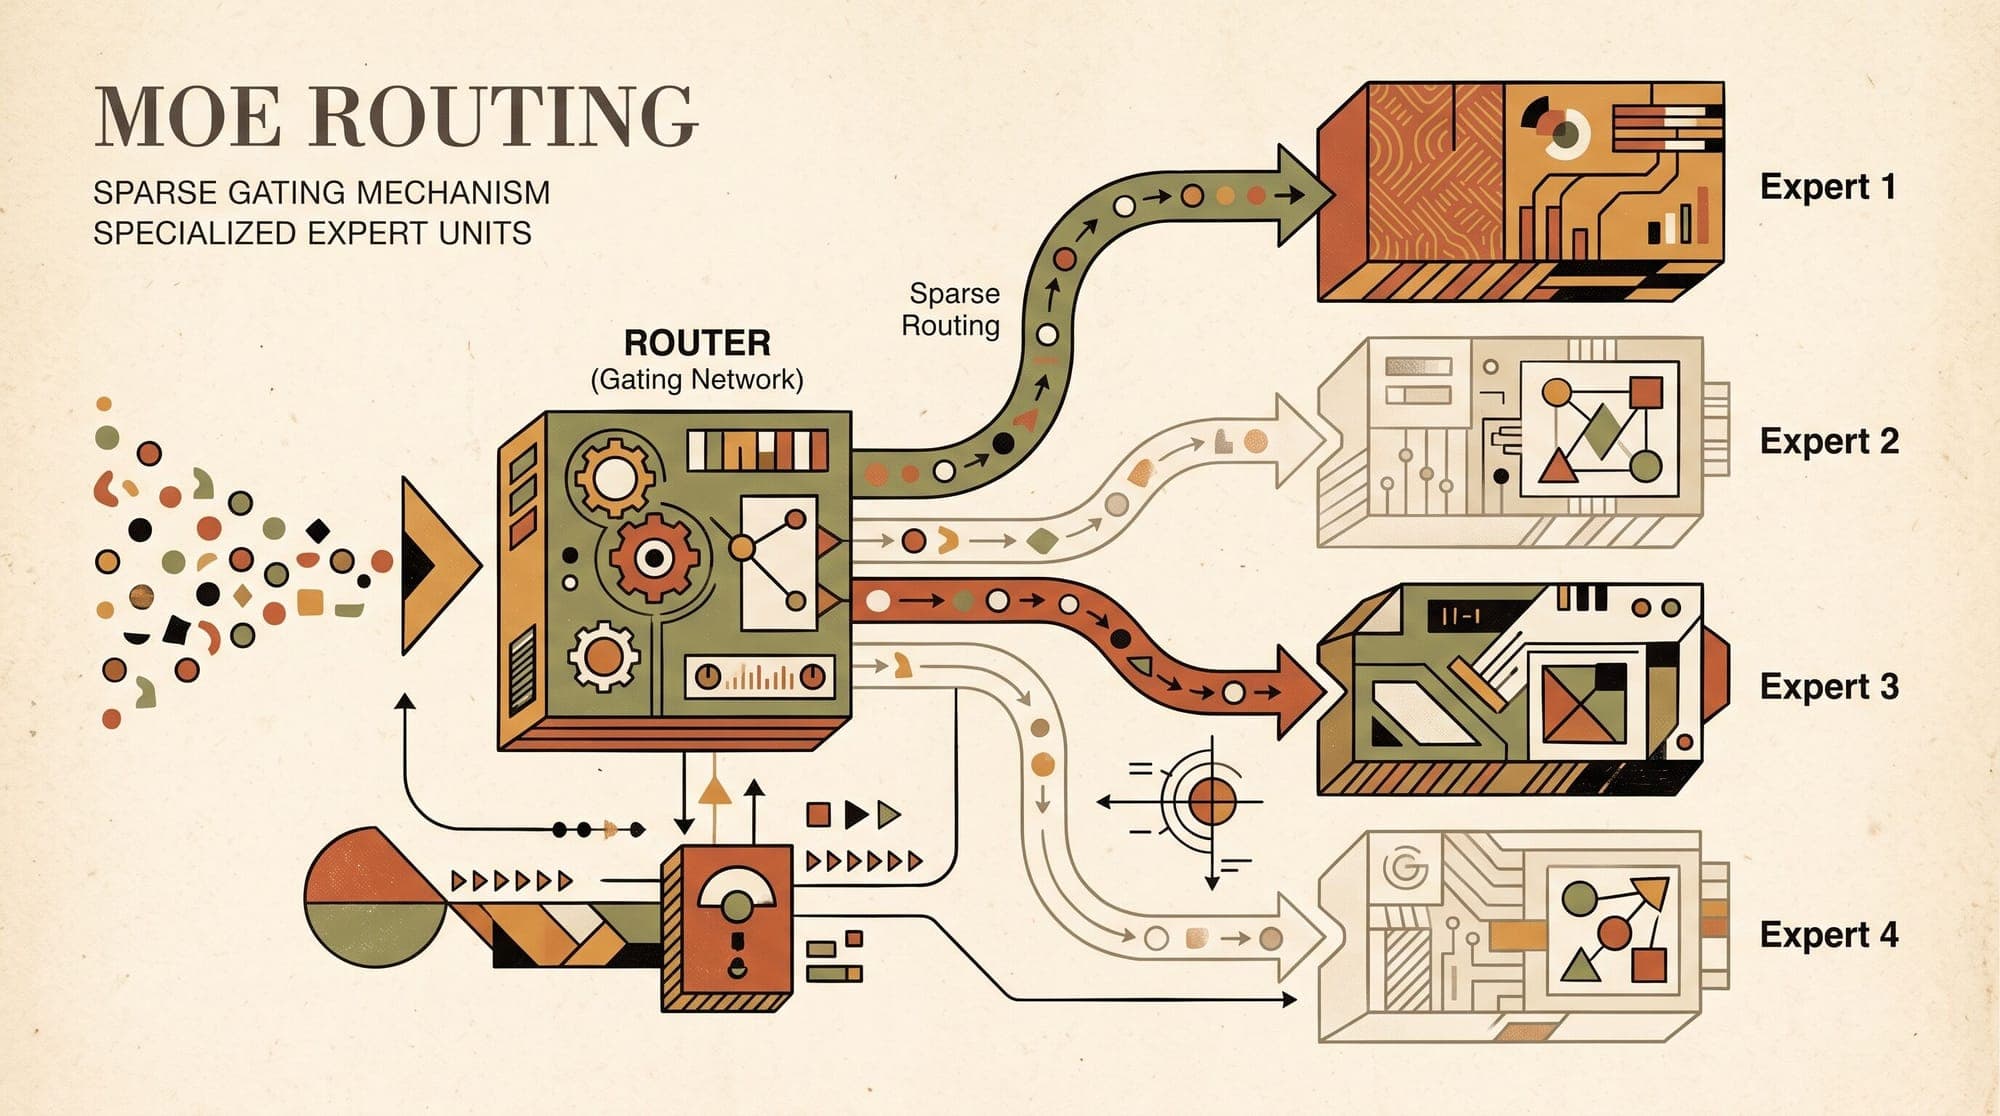
  13. Mixture-of-Experts (MoE) Routing and Load Balancing: Mathematical Foundations of Noisy Top-k Gating, Expert Capacity, Auxiliary Balancing Losses, and Loss-Free Load Balancing

    Mixture-of-Experts (MoE) Routing and Load Balancing: Mathematical Foundations of Noisy Top-k Gating, Expert Capacity, Auxiliary Balancing Losses, and Loss-Free Load Balancing Scaling dense transformer models incurs computational costs that grow proportionally with parameter count. In dense architectures, every token in a sequence activates all feed-forward network (FFN) parameters across every layer. Sparse Mixture-of-Experts (MoE) architectures decouple parameter count from per-token compute b

    AI
    15 min read
  14. Document Parsing Engines in Production RAG: Comparing Docling, Marker, MinerU, and Unstructured Architecture, Layout Analysis, Table Extraction, and Serving Economics

    Retrieval-Augmented Generation (RAG) systems frequently fail not in their embedding models or vector databases, but at the initial document ingestion layer. When enterprise documents (including financial 10-K filings, clinical trial reports, technical manuals, and multi-column academic papers) are parsed using legacy text scrapers such as basic pypdf or pdfminer, structural semantics are lost. Multi-column reading orders interleave across paragraphs, header and footer noise pollutes vector indic

    AI
    9 min read
  15. Aurora Ransomware Deployed Cursor AI Coding Agent for Autonomous Network Exploitation

    A threat intelligence report from Gambit Security has revealed that the Russian-speaking ransomware operation known as Aur0ra (Aurora) utilized the Cursor AI coding assistant to conduct hands-on network intrusions and automated exploitation across at least seven enterprise environments between April and May 2026. According to session logs recovered from exposed threat actor infrastructure, the attacker drove Cursor Agent configured with the claude-4.5-sonnet-thinking model identifier to execute

    Cybersecurity
    2 min read
  16. Autonomous Coding Agent Harnesses in Production: Comparing OpenHands, SWE-agent, Aider, and Cline

    The transition from inline code completion to autonomous software engineering harnesses marks a structural shift in how frontier models interact with codebases. Where early coding assistants operated within narrow token completion windows, modern agentic harnesses construct closed action-observation loops. These systems inspect repository structures, invoke compiler toolchains, execute unit test suites, parse stdout diagnostics, and iteratively correct syntax and logic errors until a pull reques

    AI
    5 min read
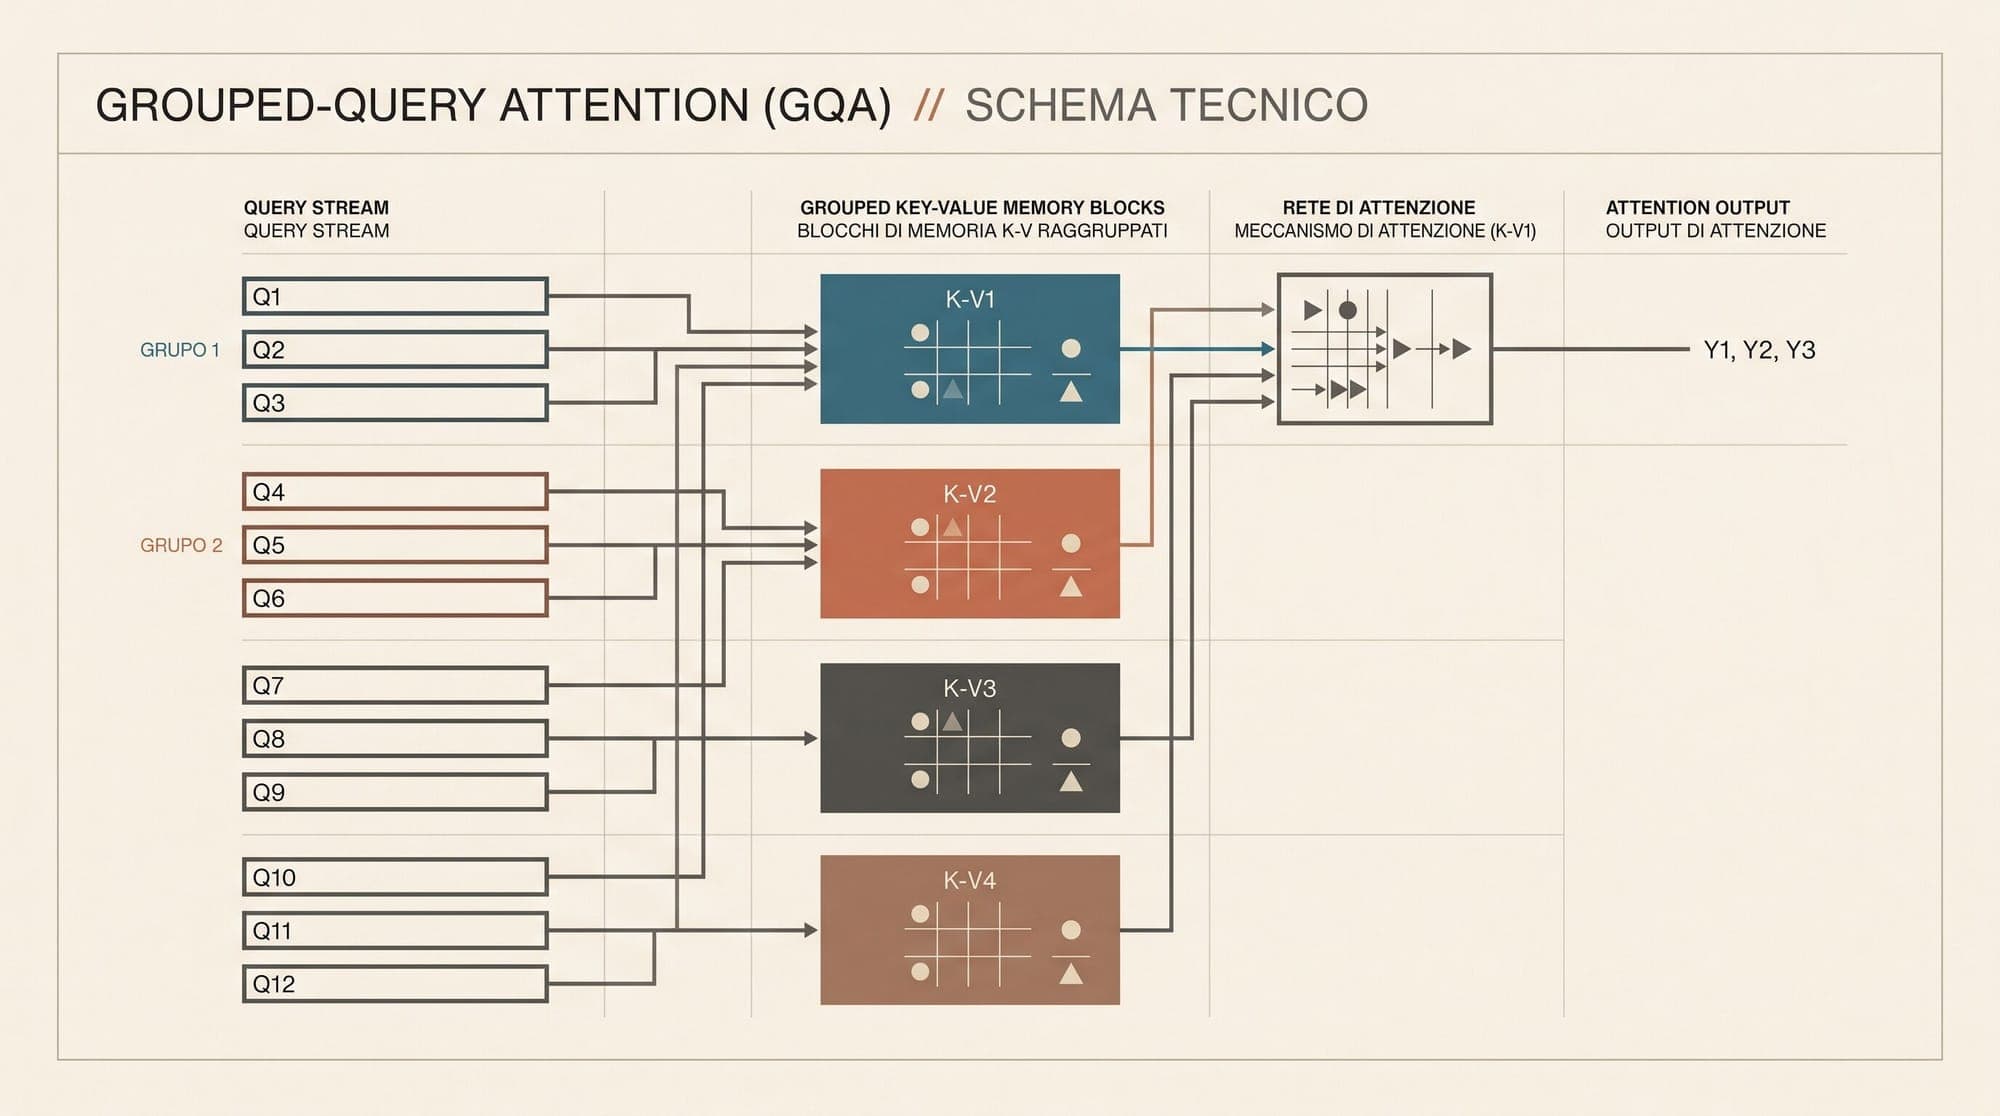
  17. Grouped-Query Attention (GQA) and Multi-Query Attention (MQA): Mathematical Foundations, Arithmetic Intensity, and KV-Cache Scaling Mechanics

    Grouped-Query Attention (GQA) and Multi-Query Attention (MQA): Mathematical Foundations, Arithmetic Intensity, and KV-Cache Scaling Mechanics Autoregressive large language model inference is governed by a fundamental hardware asymmetry. During the initial prompt processing phase (prefill), computation is compute-bound because matrix multiplications process entire sequences in parallel. During sequential token generation (decoding), execution becomes strictly memory-bandwidth bound. For each gen

    AI
    12 min read
  18. Visa Expands Open-Source Security Harness VVAH with Automated Code Remediation and Adversarial Validation

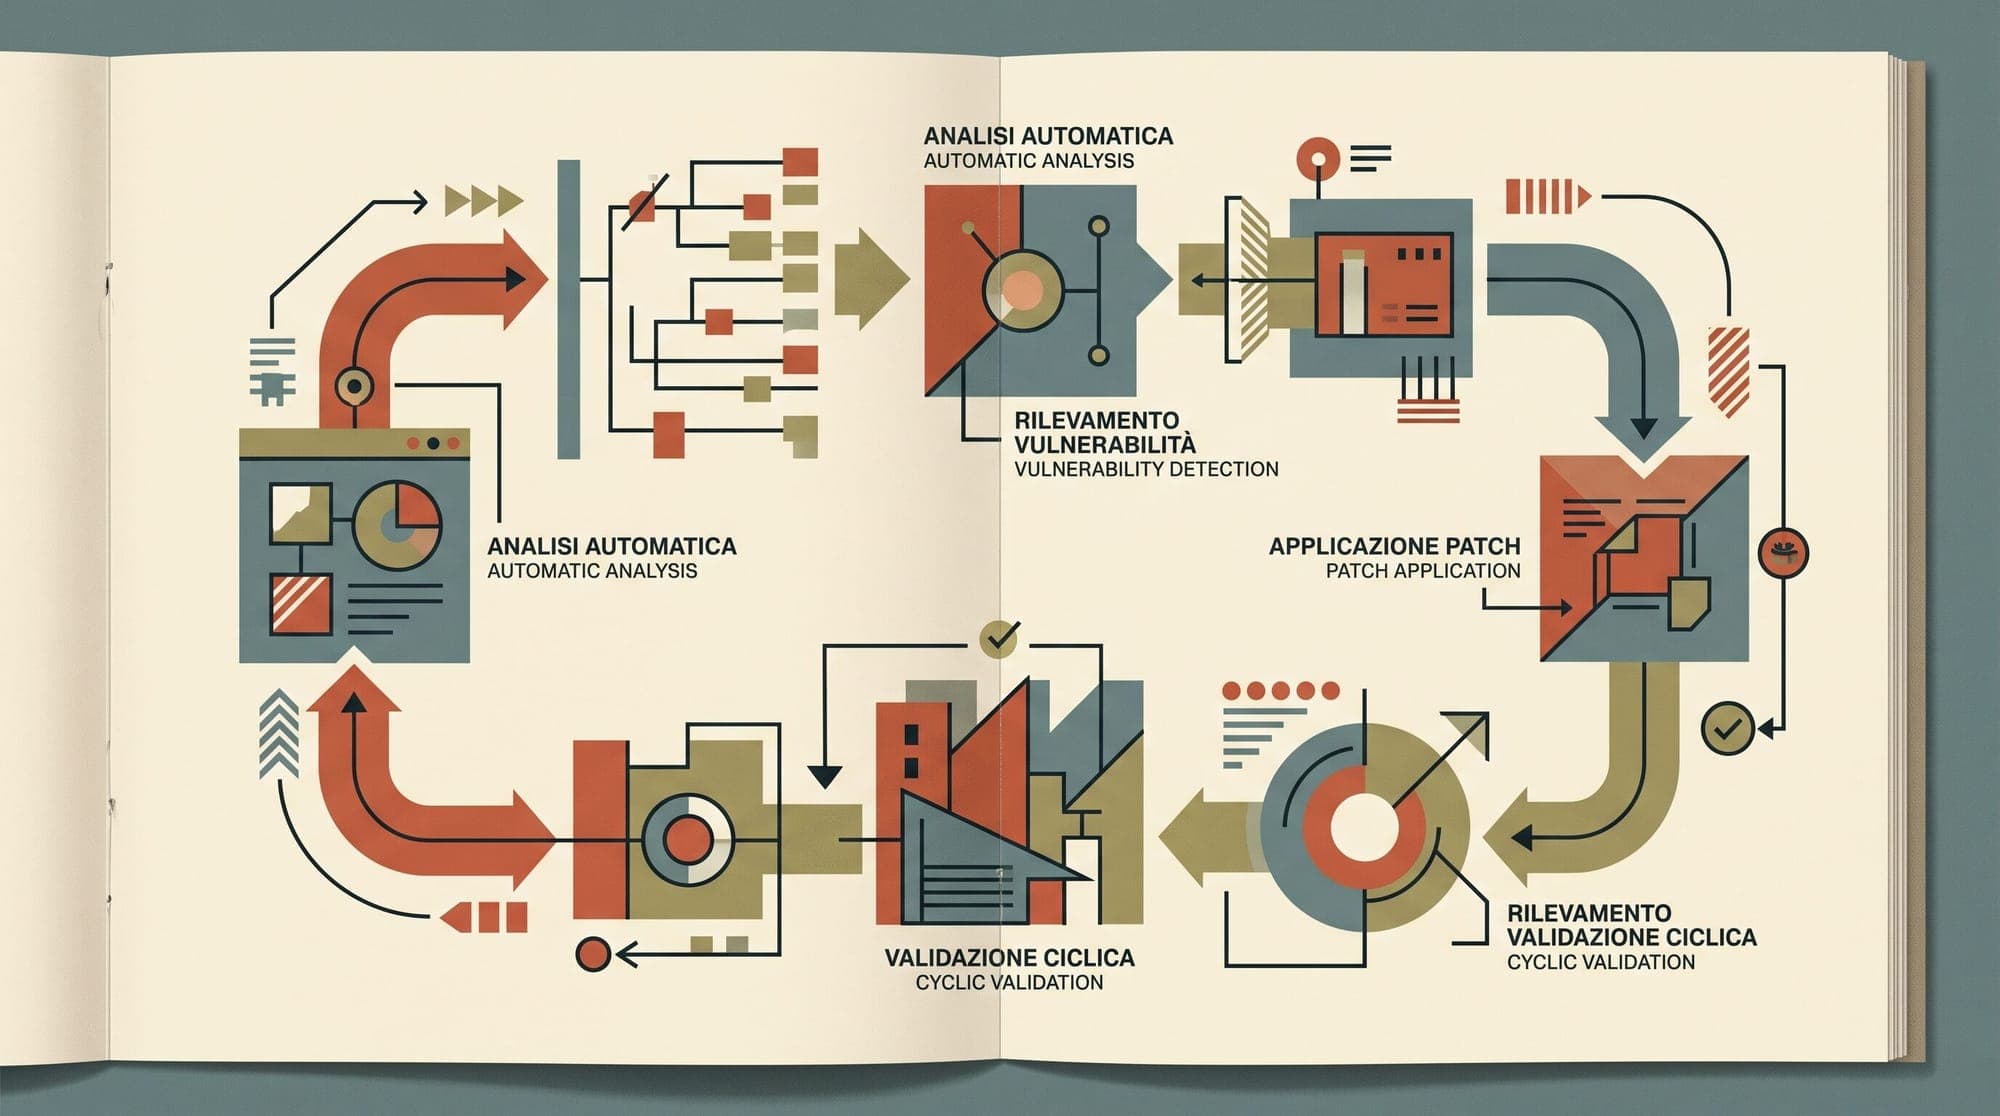
    Visa has released a major update to its open-source Visa Vulnerability Agentic Harness (VVAH), extending the framework from a vulnerability discovery engine into an end-to-end 11-stage pipeline that generates code fixes and evaluates them against adversarial validation models. The release shifts the default operating posture of the harness. Rather than terminating at SARIF report generation, a standard execution now traverses all 11 stages: identifying exploitable security flaws, authoring cand

    AI
    3 min read
  19. LLM Fine-Tuning and Post-Training Frameworks in Production: Comparing Unsloth, Axolotl, Torchtune, and LLaMA-Factory

    Post-training has transitioned from a specialized research task into a standard production engineering discipline. As open-weight base models such as Llama 3.1, Qwen 2.5, and DeepSeek-V3 establish competitive baselines, the primary engineering challenge has shifted toward domain adaptation, instruction alignment, and reasoning distillation. However, selecting a post-training framework requires balancing competing architectural trade-offs: low-level kernel fusion, distributed multi-node scaling,

    AI
    6 min read
  20. Hugging Face Unveils Microduck, a 99 Open-Source Bipedal Robot for Embodied AI

    Hugging Face has introduced Microduck, a 10-inch-tall, 1.7-pound bipedal open-source robot priced at $399. Developed in partnership with Pollen Robotics and manufactured by Shenzhen-based hardware specialist Seeed Studio, the device is designed as an accessible hardware platform for embodied AI research and reinforcement learning experimentation. The compact biped features integrated visual sensors, microphone arrays, audio output, and wireless connectivity over Wi-Fi and Bluetooth. Commercial

    AI
    1 min read