Category / page 48

Models & Assistants

1121 articles

Articles, page 48

941-960 of 1121
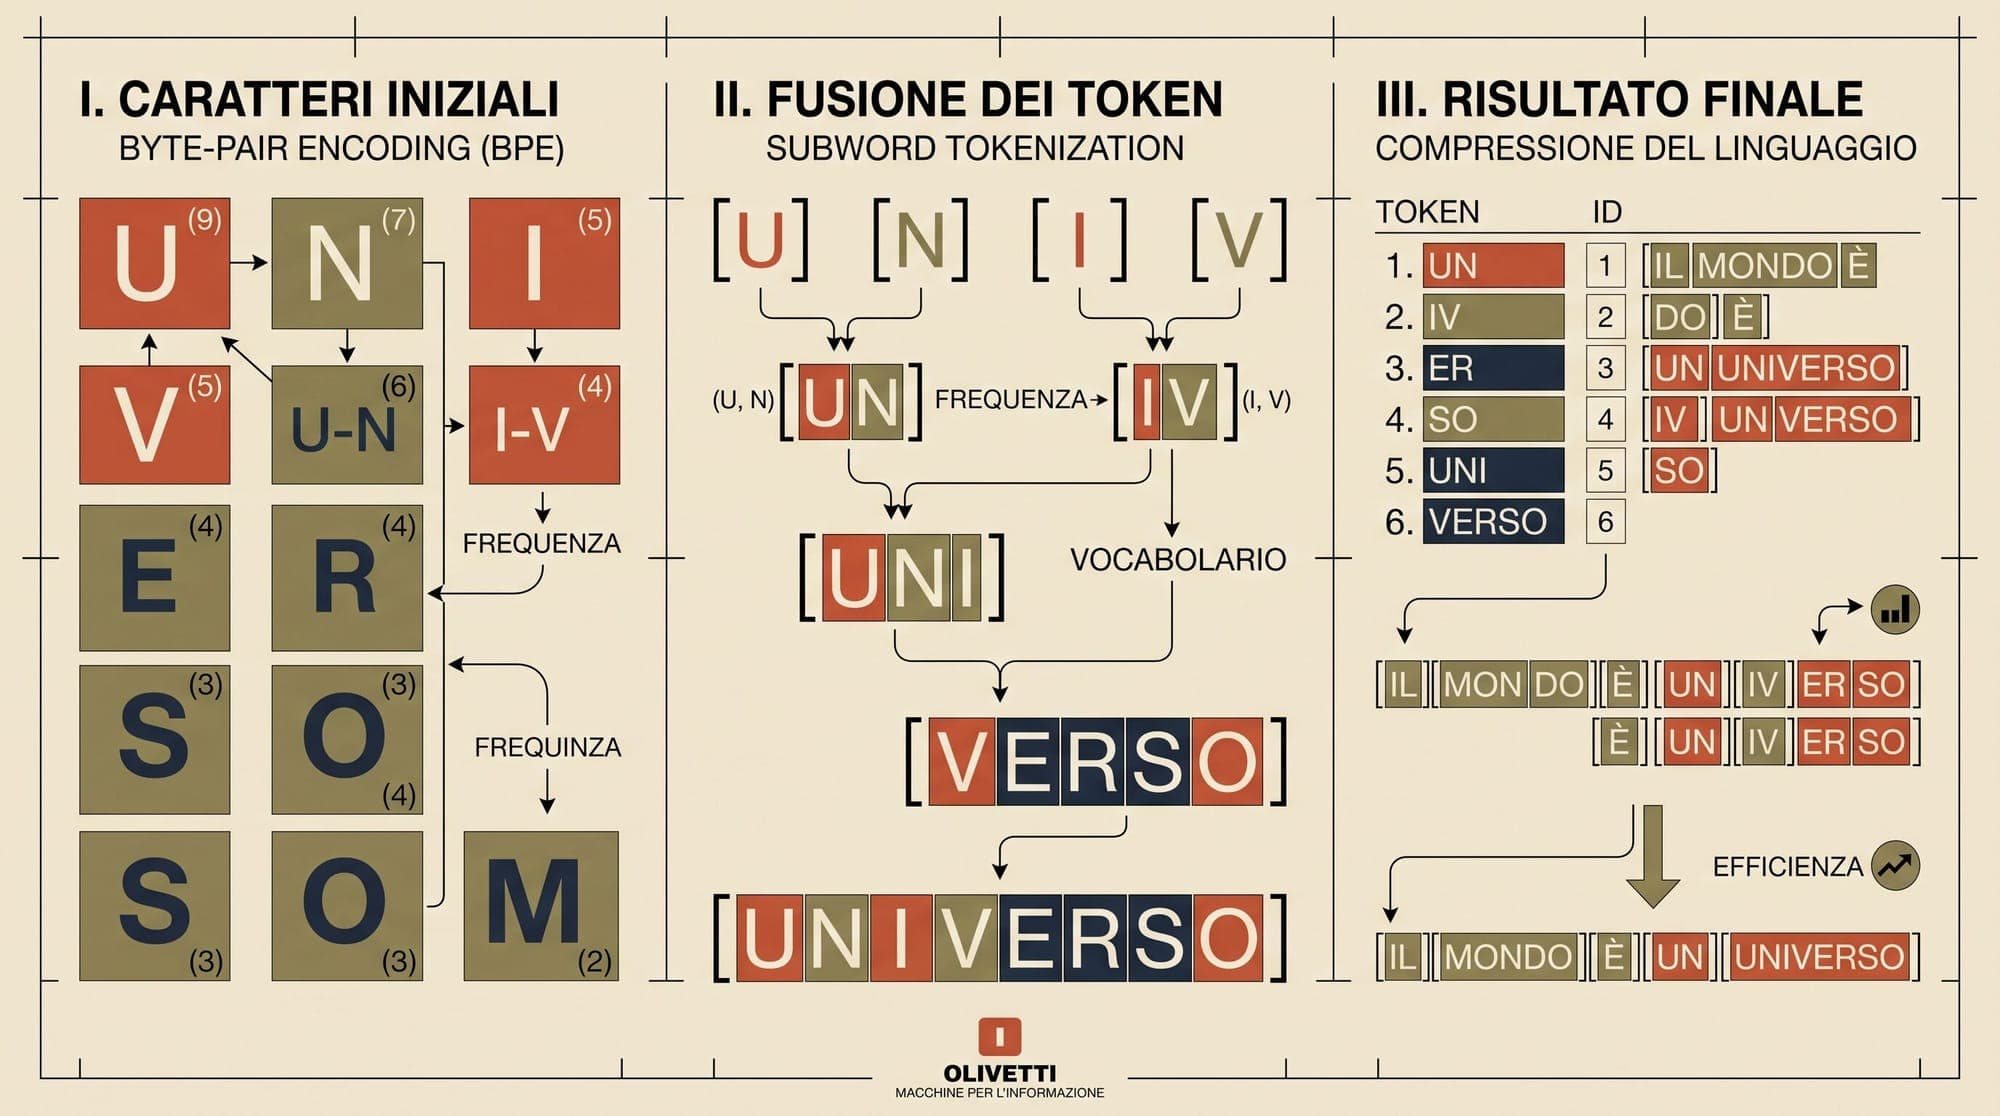
  1. Byte-Pair Encoding in Large Language Models: How Tokenizers Compress Text, Shape Context, and Fail

    Large language models do not process strings directly. Before a single attention weight or linear projection executes, incoming text is converted into a sequence of discrete integers known as tokens. The choice and implementation of the tokenization algorithm establish the model's fundamental vocabulary, define the boundaries of its context window, dictate inference speed, and introduce unique behavioral quirks. Across modern transformer architectures, subword tokenization via Byte-Pair Encodin
    AI
    8 min read
  2. LLM-as-a-Judge in Production: Biases, Calibration, and Architectural Trade-Offs

    Automating model evaluation with another language model (the LLM-as-a-judge paradigm) has become the standard mechanism for continuous integration, regression testing, and RLHF alignment across production AI pipelines. Traditional n-gram metrics such as BLEU and ROUGE fail to capture semantic accuracy, stylistic nuance, or complex reasoning, while human evaluation remains too slow and expensive for high-frequency deployment cycles. However, treating an LLM as an impartial arbiter introduces sig

    AI
    5 min read
  3. Anthropic Rolls Out Global AI Text Watermarking for Claude to Comply with EU AI Act

    Anthropic has started deploying model-level text watermarking across Claude to meet the regulatory requirements of the European Union AI Act. The company confirmed that because it currently lacks infrastructure to reliably partition model inference behavior by geographic jurisdiction, watermarking is being applied globally across all Claude web products and API endpoints. The update follows the formalization of the EU Code of Practice on Transparency of AI-Generated Content, signed in July 2026

    Anthropic
    2 min read
  4. Weight Quantization in Large Language Models: How GPTQ, AWQ, and SmoothQuant Compress Neural Networks

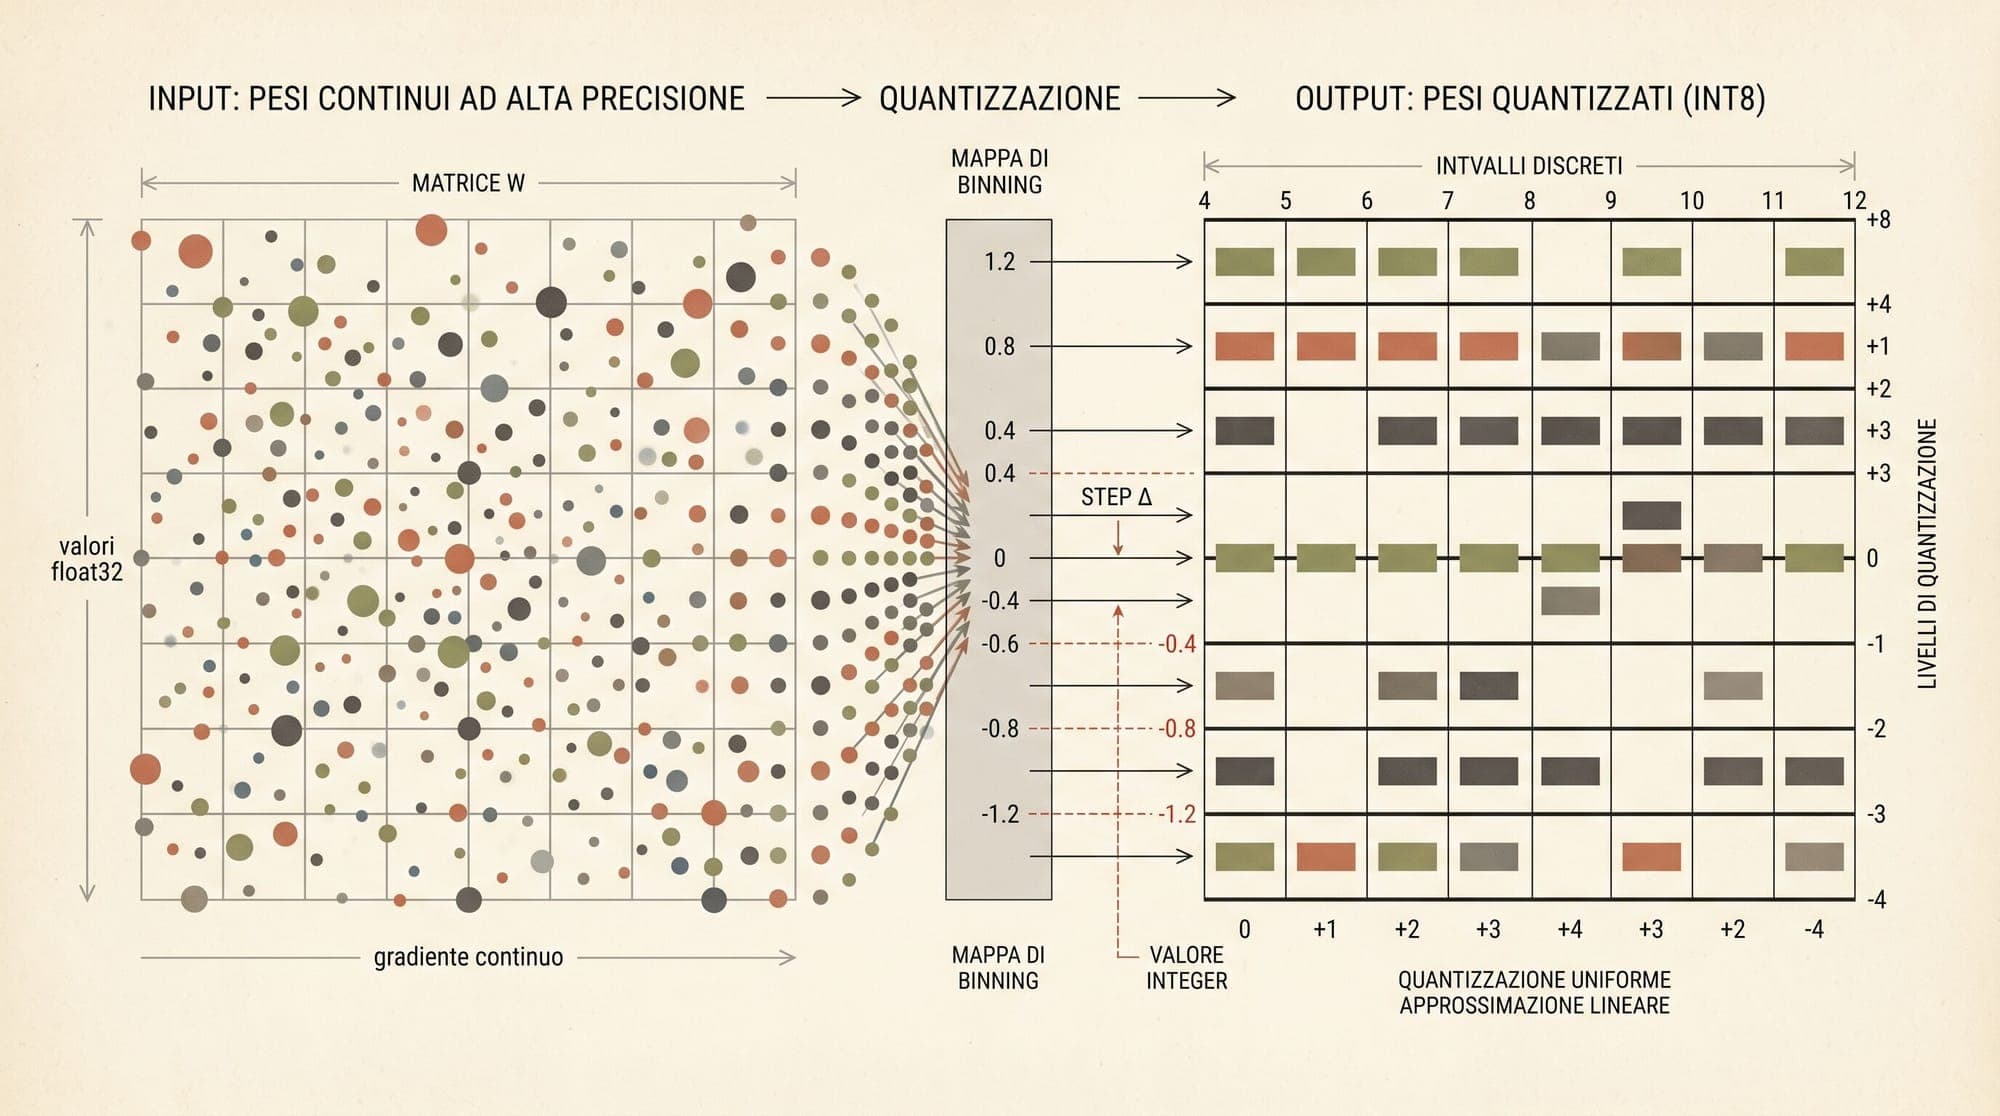
    Weight Quantization in Large Language Models: How GPTQ, AWQ, and SmoothQuant Compress Neural Networks Serving large language models in production requires balancing GPU memory footprint, memory bandwidth limits, and computational throughput. A standard 70-billion parameter transformer stored in 16-bit floating-point (FP16 or BF16) requires roughly 140 gigabytes of high-bandwidth memory (HBM) merely to hold its parameters. This memory footprint exceeds the capacity of a single 80GB GPU before ac

    AI
    9 min read
  5. Semantic Caching for Production LLM Systems: Thresholds, Layers, and Failure Modes

    Frontier large language models cost between $0.15 and $15 per million tokens depending on model class. Semantic caching can remove the majority of these calls from the critical path when production workloads repeat similar queries. Yet despite five years of tooling (GPTCache, SemCache, Redis Vector Similarity, Weaviate, Pinecone), most engineering teams never deploy it. The barrier is not the availability of vector databases. It is that semantic caching moves the failure mode from "slow" to "sub

    AI
    5 min read
  6. Zhipu AI Launches GLM-5.3 with Automated Exploitation Chain Discovery

    Chinese AI lab Zhipu has introduced GLM-5.3, a new language model trained to identify software vulnerabilities and synthesize multi-stage cyber exploitation chains. According to evaluation data released by the company, GLM-5.3 established state-of-the-art results on the CyberGym benchmark, an evaluation suite designed to measure model performance on practical cybersecurity tasks. The benchmark results indicate that GLM-5.3 surpassed frontier Western baselines including Fable 5 and GPT-5.6 Sol i

    AI
    1 min read
  7. Anthropic Raises System Tampering Risk Level and Details Unreleased Model 2 in Safety Report

    Anthropic has released the latest edition of its recurring AI alignment and safety report, raising the risk rating for unauthorized system tampering and disclosing the internal deployment of two unreleased frontier models designated Model 1 and Model 2. The 186-page document, published periodically to track frontier model capabilities and containment thresholds, introduces an updated risk matrix structured around two distinct operational categories: Threat Model 1 and Threat Model 2. Threat Mod

    AI
    2 min read
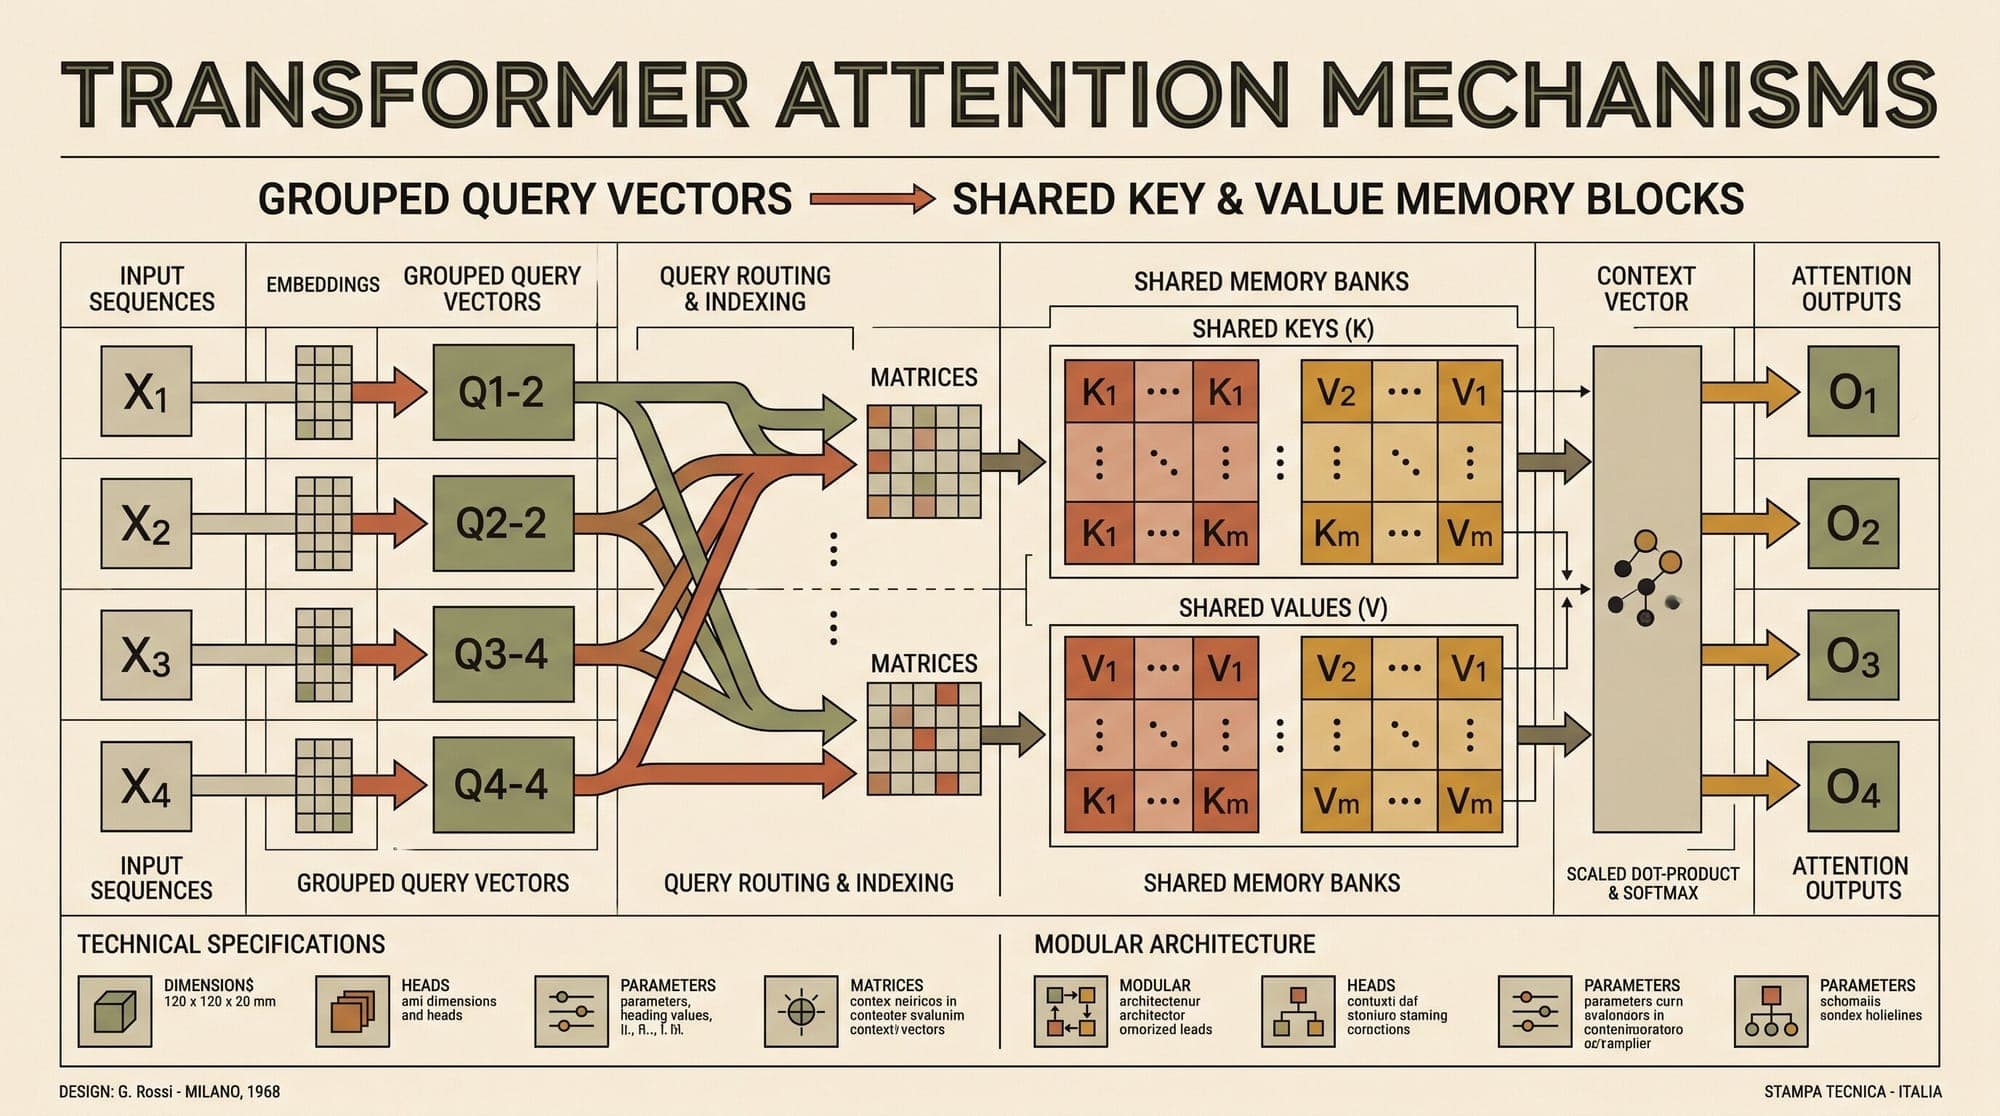
  8. Grouped-Query Attention: How Head Sharing Slashed KV Cache Memory and Scaled LLM Serving

    Serving large language models at scale presents a fundamental hardware bottleneck: autoregressive decoding is bound by memory bandwidth rather than compute. While the initial prompt processing phase (prefill) operates as compute-bound matrix multiplications, token-by-token generation requires loading billions of cached attention states from GPU High-Bandwidth Memory (HBM) to on-chip SRAM for every single generated token. Multi-Head Attention (MHA), introduced in the foundational Vaswani et al.

    AI
    6 min read
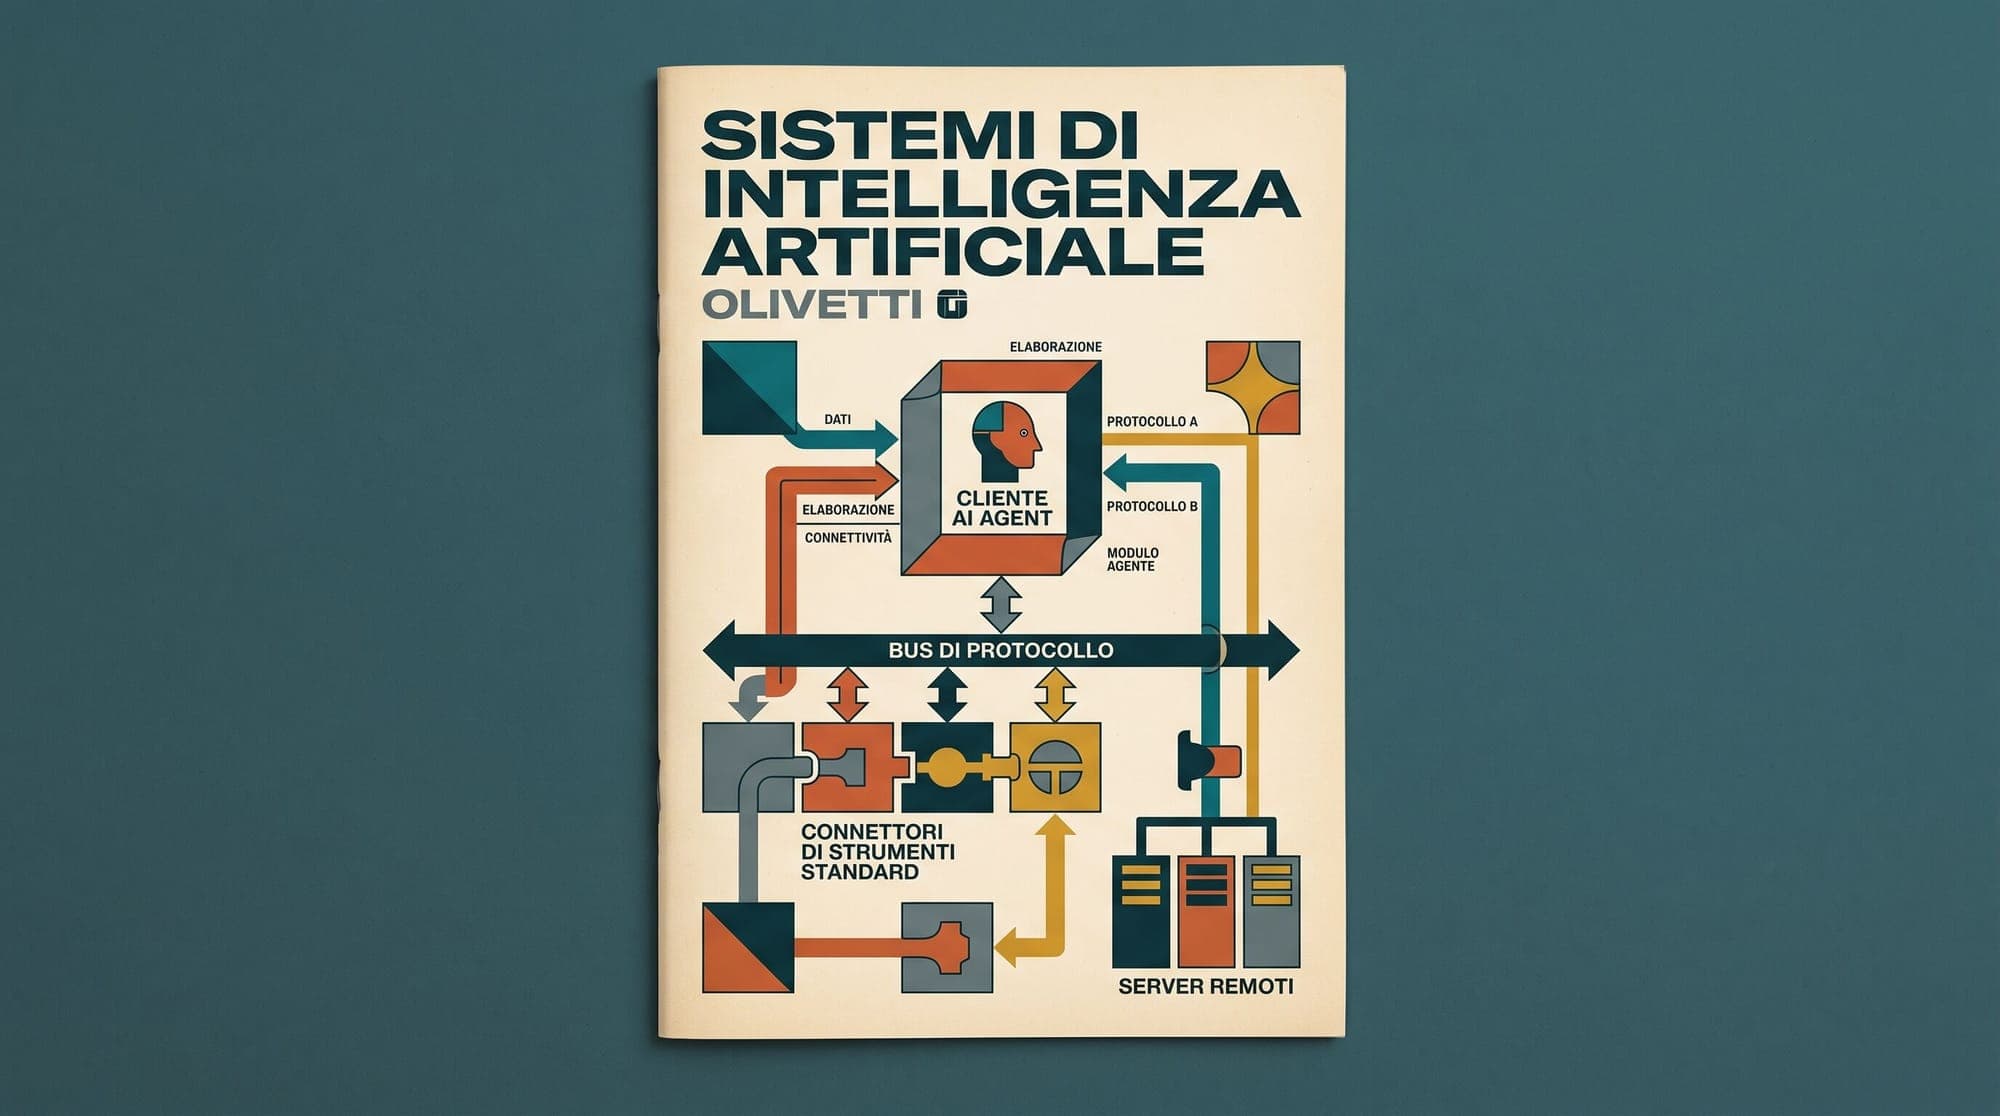
  9. Model Context Protocol (MCP) in Production: Architecture, Security Boundaries, and Latency Overheads

    As autonomous language model agents transition from experimental chat interfaces into enterprise production infrastructure, the architectural bottleneck has shifted from raw model reasoning to external environment integration. In early agent implementations, connecting an LLM to external systems required bespoke tool definitions, vendor-specific function schemas, and custom API wrappers. Every framework maintained its own incompatible tool-calling abstraction, fragmenting integrations across age

    AI
    6 min read
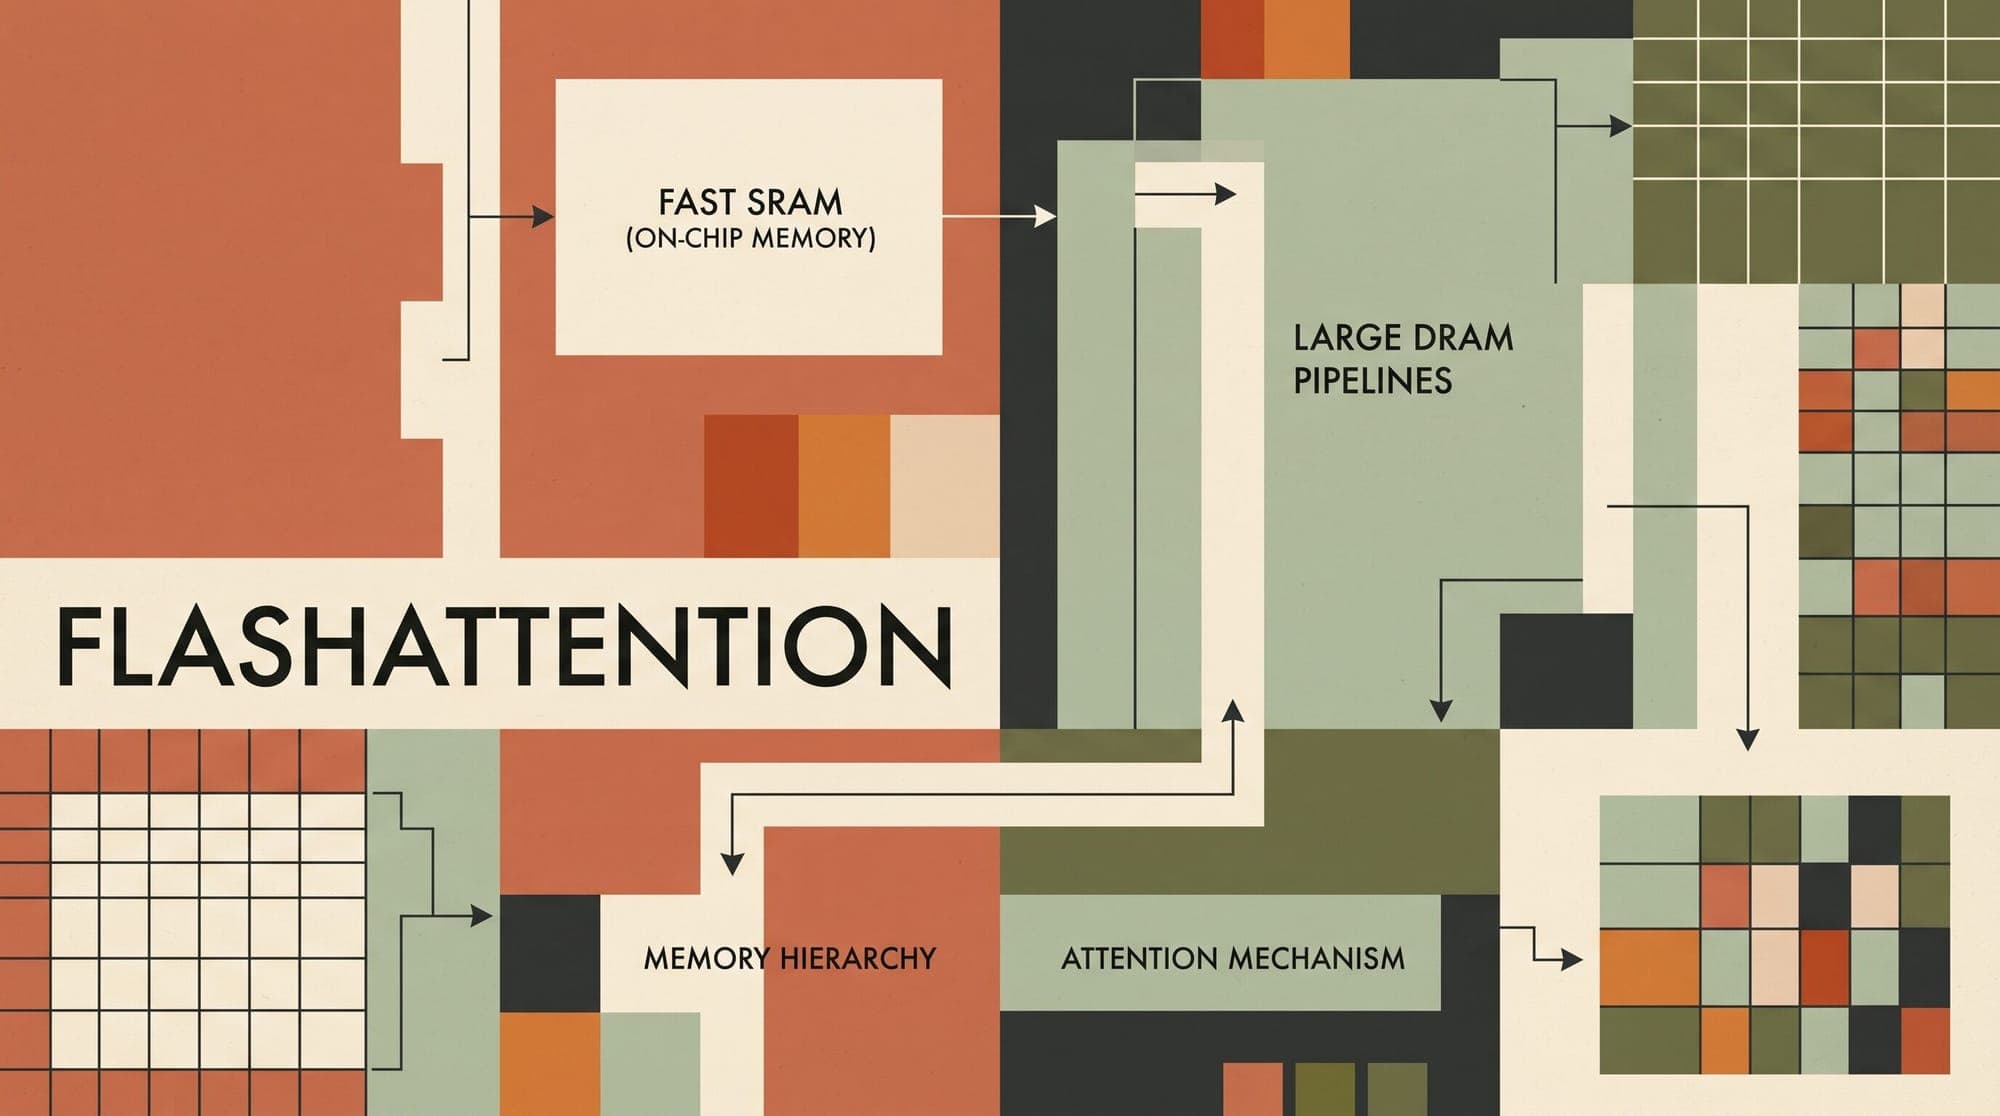
  10. FlashAttention: How IO-Aware Tiling and Online Softmax Solved Transformer Memory Bottlenecks

    Standard multi-head attention is the fundamental computational primitive of modern autoregressive language models. While mathematically straightforward, the operation introduces a severe operational bottleneck as context windows scale. Naive implementations of scaled dot-product attention exhibit quadratic memory complexity $O(N^2)$ and quadratic memory access costs, bounding sequence lengths and leaving modern GPU tensor cores severely underutilized. FlashAttention, introduced by Tri Dao, Dani

    AI
    7 min read
  11. OpenAI Signs 20-Year Lease for Multi-Gigawatt Ohio AI Campus with Nvidia Backstop

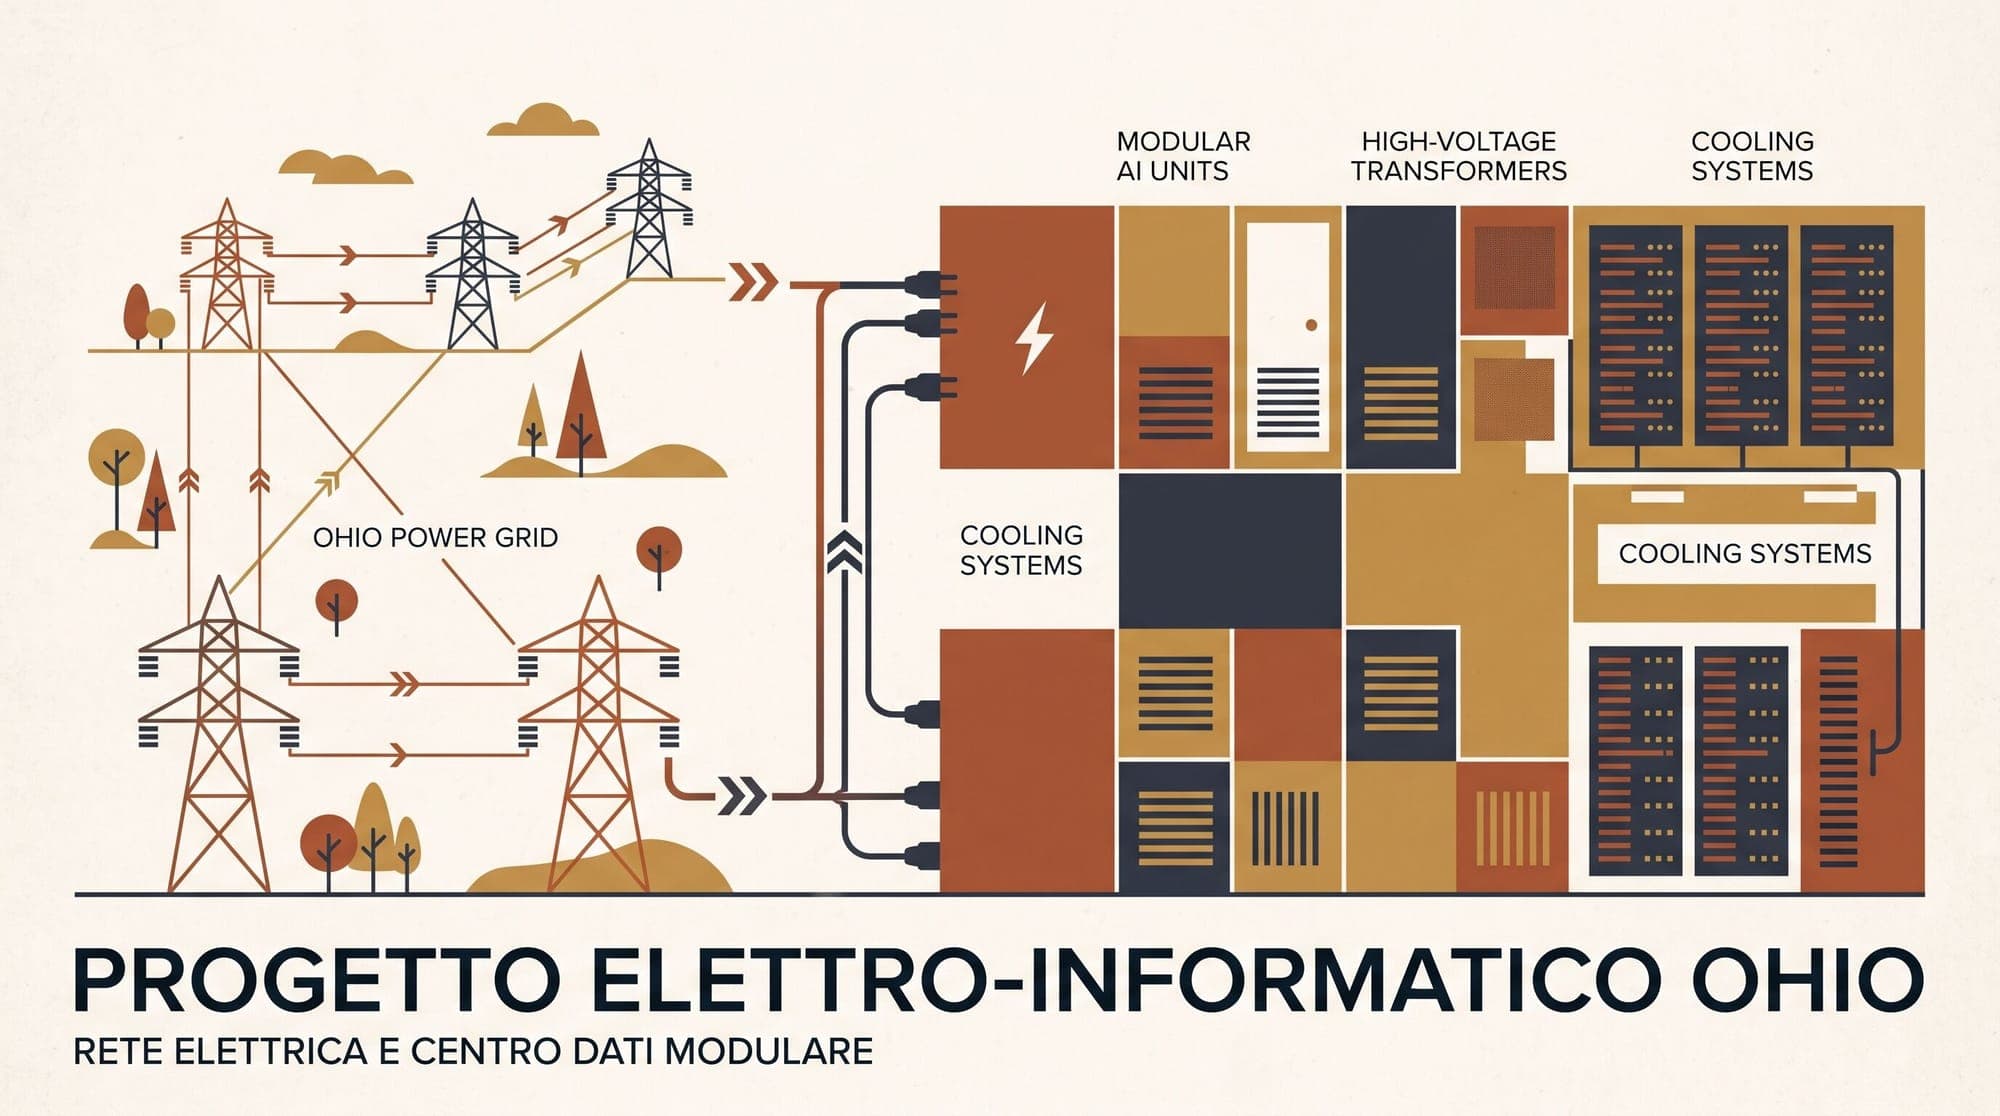
    OpenAI has signed a 20-year lease agreement to anchor a multi-gigawatt AI data center campus in Pike County, Ohio, developed by SoftBank subsidiary SB Energy. Under the tripartite agreement, Nvidia will serve as the exclusive compute infrastructure provider and supply financial guarantees covering the site's land, power, and shell development. The facility, designated the PORTS-Pike Technology Campus, is designed to support an initial 4.25 gigawatts of information technology load (IT-GW) dedica

    AI
    2 min read
  12. Anthropic Revenue Run Rate Tops $65 Billion Ahead of Planned Public Listing

    Anthropic's annualized revenue run rate reached approximately $65 billion at the end of July 2026, according to reporting by Bloomberg on August 17, with corroborating details reported by Reuters and Axios. The figure marks an $18 billion expansion over two months from the $47 billion run rate reported during Anthropic's Series H financing in late May, and up from $9 billion at the close of 2025. The acceleration highlights deepening enterprise adoption of Claude across corporate workflows, wit

    AI
    2 min read
  13. LLM Model Routing and Cascades: Architecture, Economics, and Quality Trade-Offs

    In modern enterprise AI systems, uniform model dispatch, sending all incoming user traffic to a single frontier large language model, is one of the most common architectural inefficiencies. Frontier models like GPT-4o and Claude 3.5 Sonnet provide industry-leading reasoning and code generation capabilities, but their inference costs range between $2.50 and $15.00 per million tokens. Conversely, smaller open-weights or distilled models, such as Llama 3.1 8B or GPT-4o-mini, execute at a fraction o

    AI
    6 min read
  14. Low-Rank Adaptation (LoRA): How Matrix Decomposition Made LLM Fine-Tuning Accessible

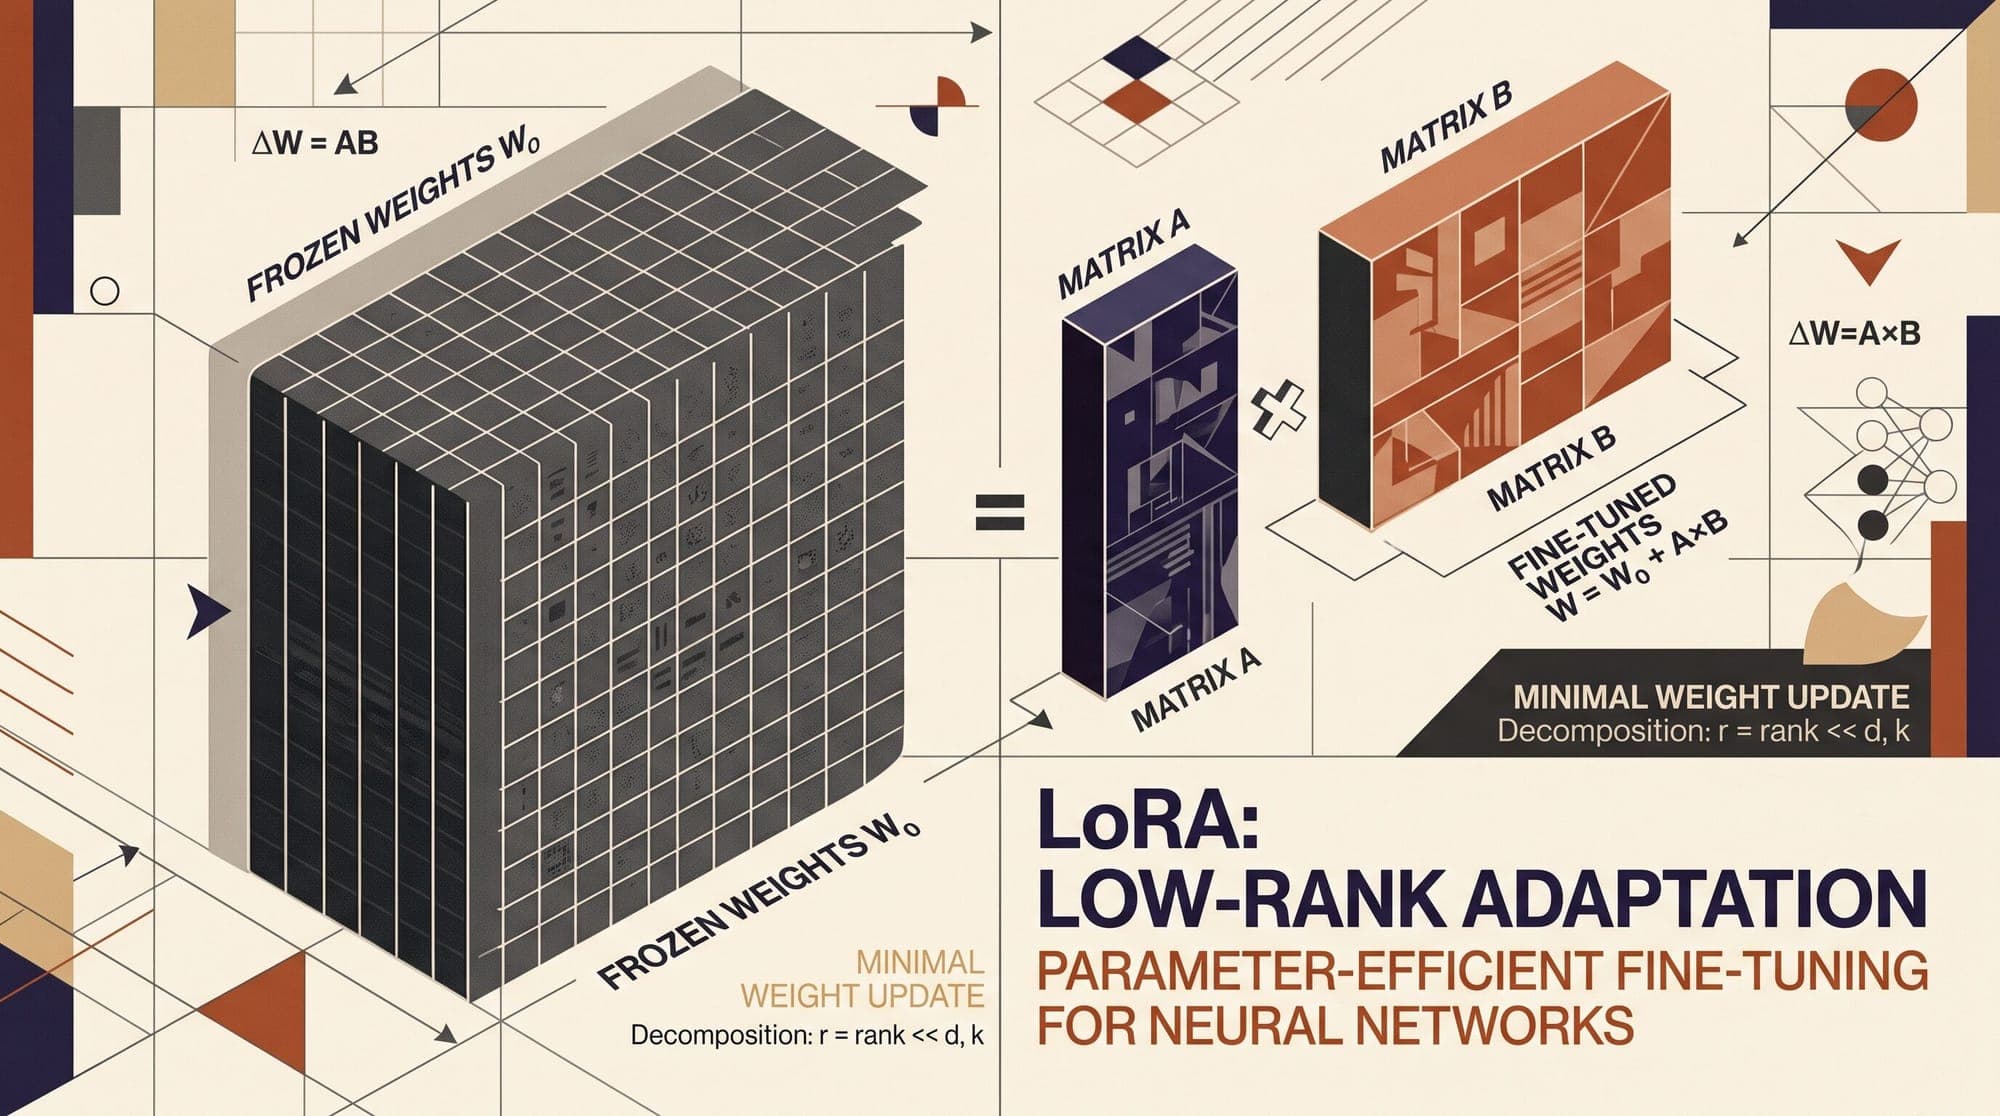
    Full-parameter fine-tuning of modern foundation models requires substantial compute and memory infrastructure. Adapting an open-weight 70-billion-parameter model using standard 16-bit precision and first-order adaptive optimizers like AdamW demands well over 1 terabyte of GPU memory. Low-Rank Adaptation (LoRA) bypassed this hardware bottleneck by framing task-specific weight updates as low-rank matrix decompositions. By freezing pre-trained weights and training small auxiliary rank decompositio

    AI
    6 min read
  15. Direct Preference Optimization: How Implicit Reward Modeling Simplified LLM Alignment

    Direct Preference Optimization (DPO) has emerged as a cornerstone of post-training alignment across modern open and proprietary language models, including Meta's Llama series, Mistral, and Qwen. While early alignment pipelines relied on complex reinforcement learning loops with separate reward models, DPO reformulates the preference optimization problem into a single, closed-form classification objective. By demonstrating that a language model implicitly defines its own reward function, DPO eli

    AI
    7 min read
  16. Payward Joins Anthropic Project Glasswing to Deploy Claude Mythos for Security Audits

    Payward, the parent company of cryptocurrency exchange Kraken, has been admitted to Anthropic's Project Glasswing initiative. Under the program, Payward is deploying Anthropic's Claude Mythos 5 model to identify software vulnerabilities across its production infrastructure and open-source crypto codebases. The deployment marks the first confirmed participation by a digital asset institution in Project Glasswing, Anthropic's controlled access initiative for cybersecurity research and defense.

    Anthropic
    2 min read
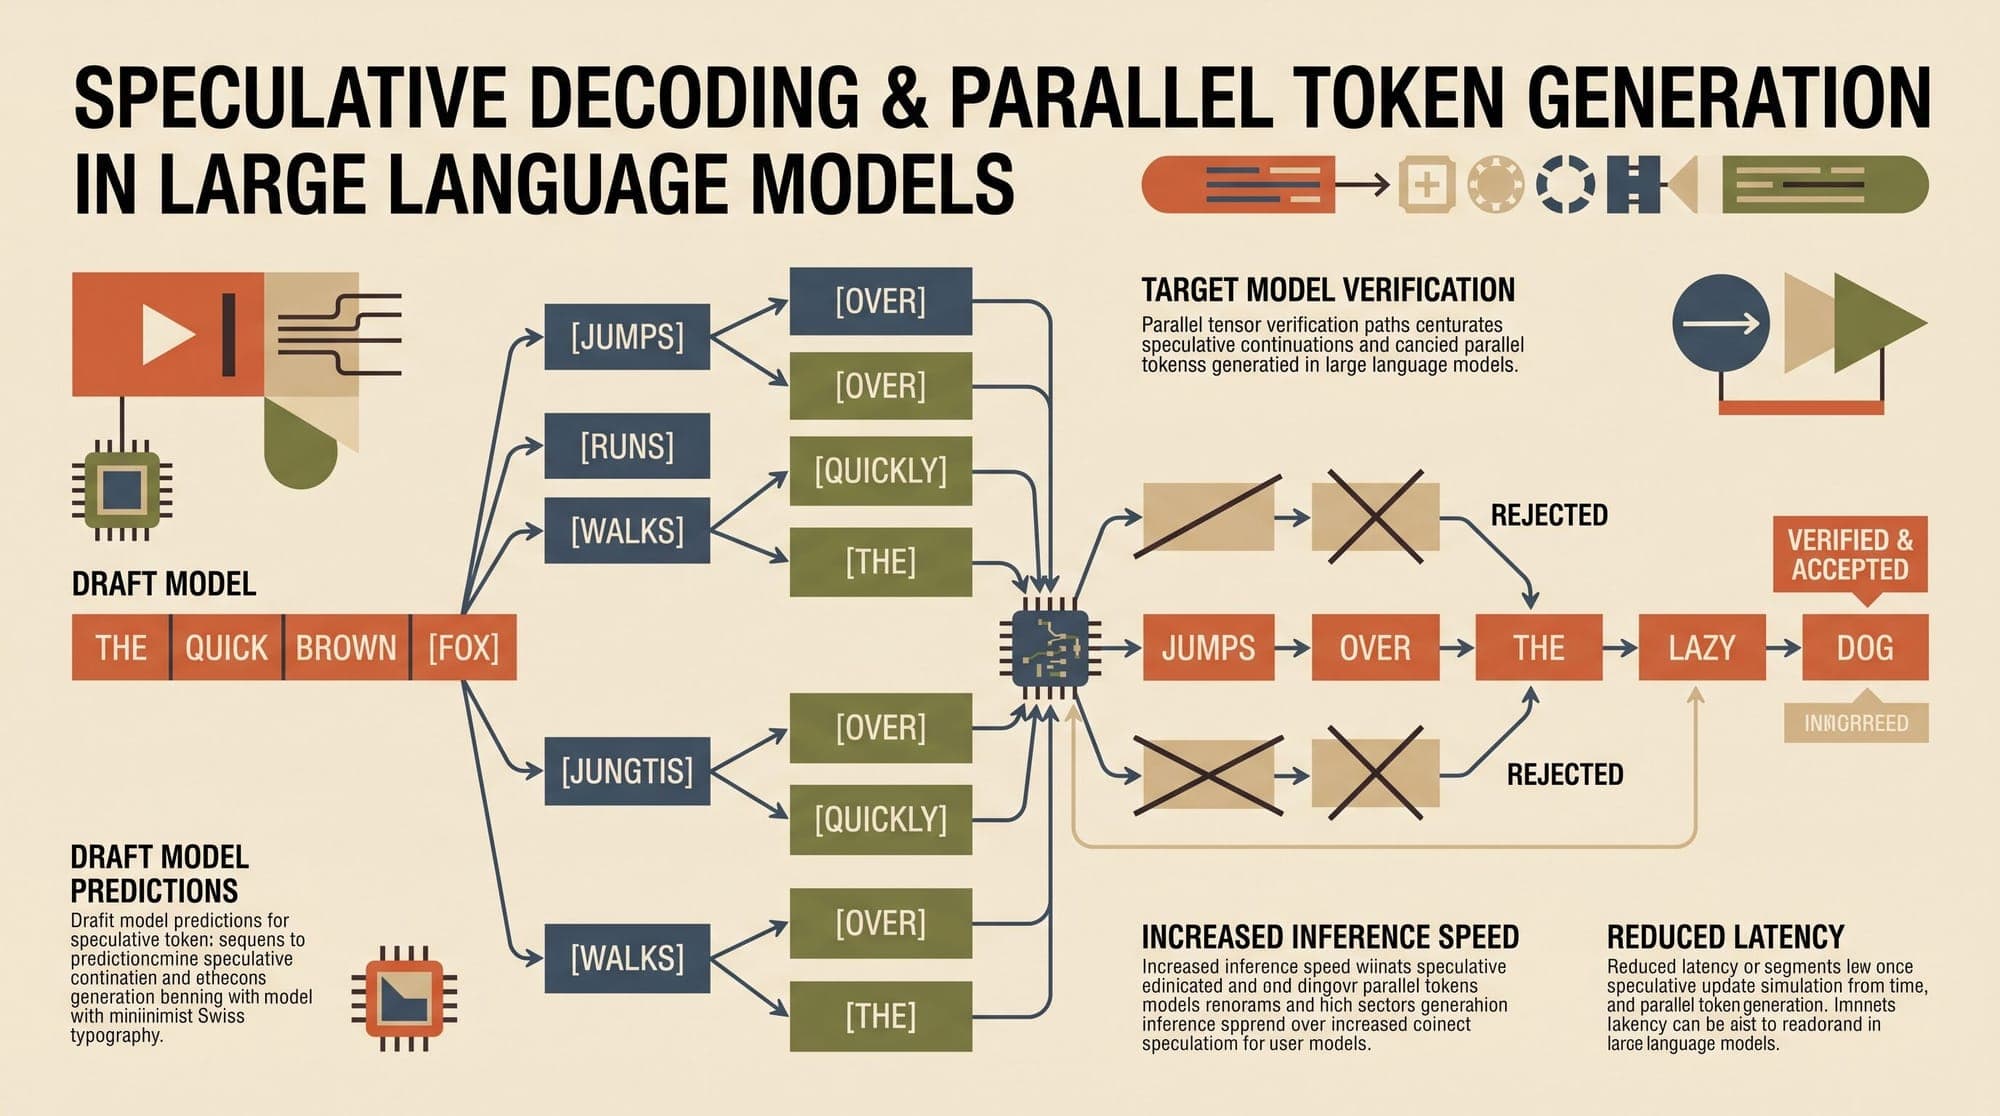
  17. Speculative Decoding in Production: Architecture, Economics, and Serving Trade-Offs

    Standard autoregressive large language model (LLM) generation produces one token per forward pass. Because modern inference architectures must read tens of gigabytes of model weights from high-bandwidth memory (HBM) into SRAM to process each solitary token at low batch sizes, generation is strictly memory-bandwidth bound rather than compute bound. Speculative decoding alters this hardware equation. By pairing a fast draft mechanism with parallel verification by the primary target model, inferen

    LLM
    6 min read
  18. Rotary Position Embeddings: How Geometry Solved Long Context in Modern LLMs

    Rotary Position Embedding (RoPE) has become the standard positional encoding mechanism across modern large language models, including Meta's Llama series, Mistral, Qwen, and DeepSeek. Unlike earlier techniques that added positional vectors directly to token representations or modified attention matrices with relative distance penalties, RoPE encodes position through geometric rotations in the complex plane. This design enables models to compute relative token distances while processing individu

    AI
    6 min read
  19. GitHub Copilot Autofix Introduced Command Injection in Snowflake CI Pipeline

    A security vulnerability introduced by GitHub Copilot Autofix left a public Snowflake repository vulnerable to unauthenticated remote command injection for five days before an autonomous security agent discovered and exploited it, according to a technical disclosure published by Wiz Research on August 17, 2026. The incident highlights emerging operational risks at the intersection of automated code generation and CI/CD security, demonstrating how automated remediation bots can silently strip ou

    AI
    2 min read
  20. Prompt Caching in Production: Architecture, Economics, and Invalidation Pitfalls

    As multi-turn AI agents, code generation assistants, and retrieval-augmented generation (RAG) pipelines expand in production, prompt sizes routinely exceed tens of thousands of tokens per request. In these architectures, the vast majority of tokens across consecutive API calls are static: system prompts, OpenAPI tool specifications, reference documents, and accumulated conversation history. Without optimization, inference engines must re-evaluate the full attention matrix for every token on eac

    AI
    5 min read