Subscribe
Topic / page 7

Open Weights

Articles, page 7

121-138
  1. Chinese State-Linked Hackers Double Attack Volume Using DeepSeek AI, Researchers Find

    State-affiliated Chinese cyber espionage groups have more than doubled their operational attack volume by integrating open-weight artificial intelligence models into routine reconnaissance and script generation workflows, according to threat intelligence from Taiwanese cybersecurity firm TeamT5 and reporting by Bloomberg. The surge in offensive volume is driven primarily by DeepSeek models, which threat actors favor due to low inference costs, local deployment options, and minimal safety guardr
    News
    3 min read
  2. Liquid AI Ships LFM2.5-DSpark Draft Models for Up to 3.2x Faster Inference

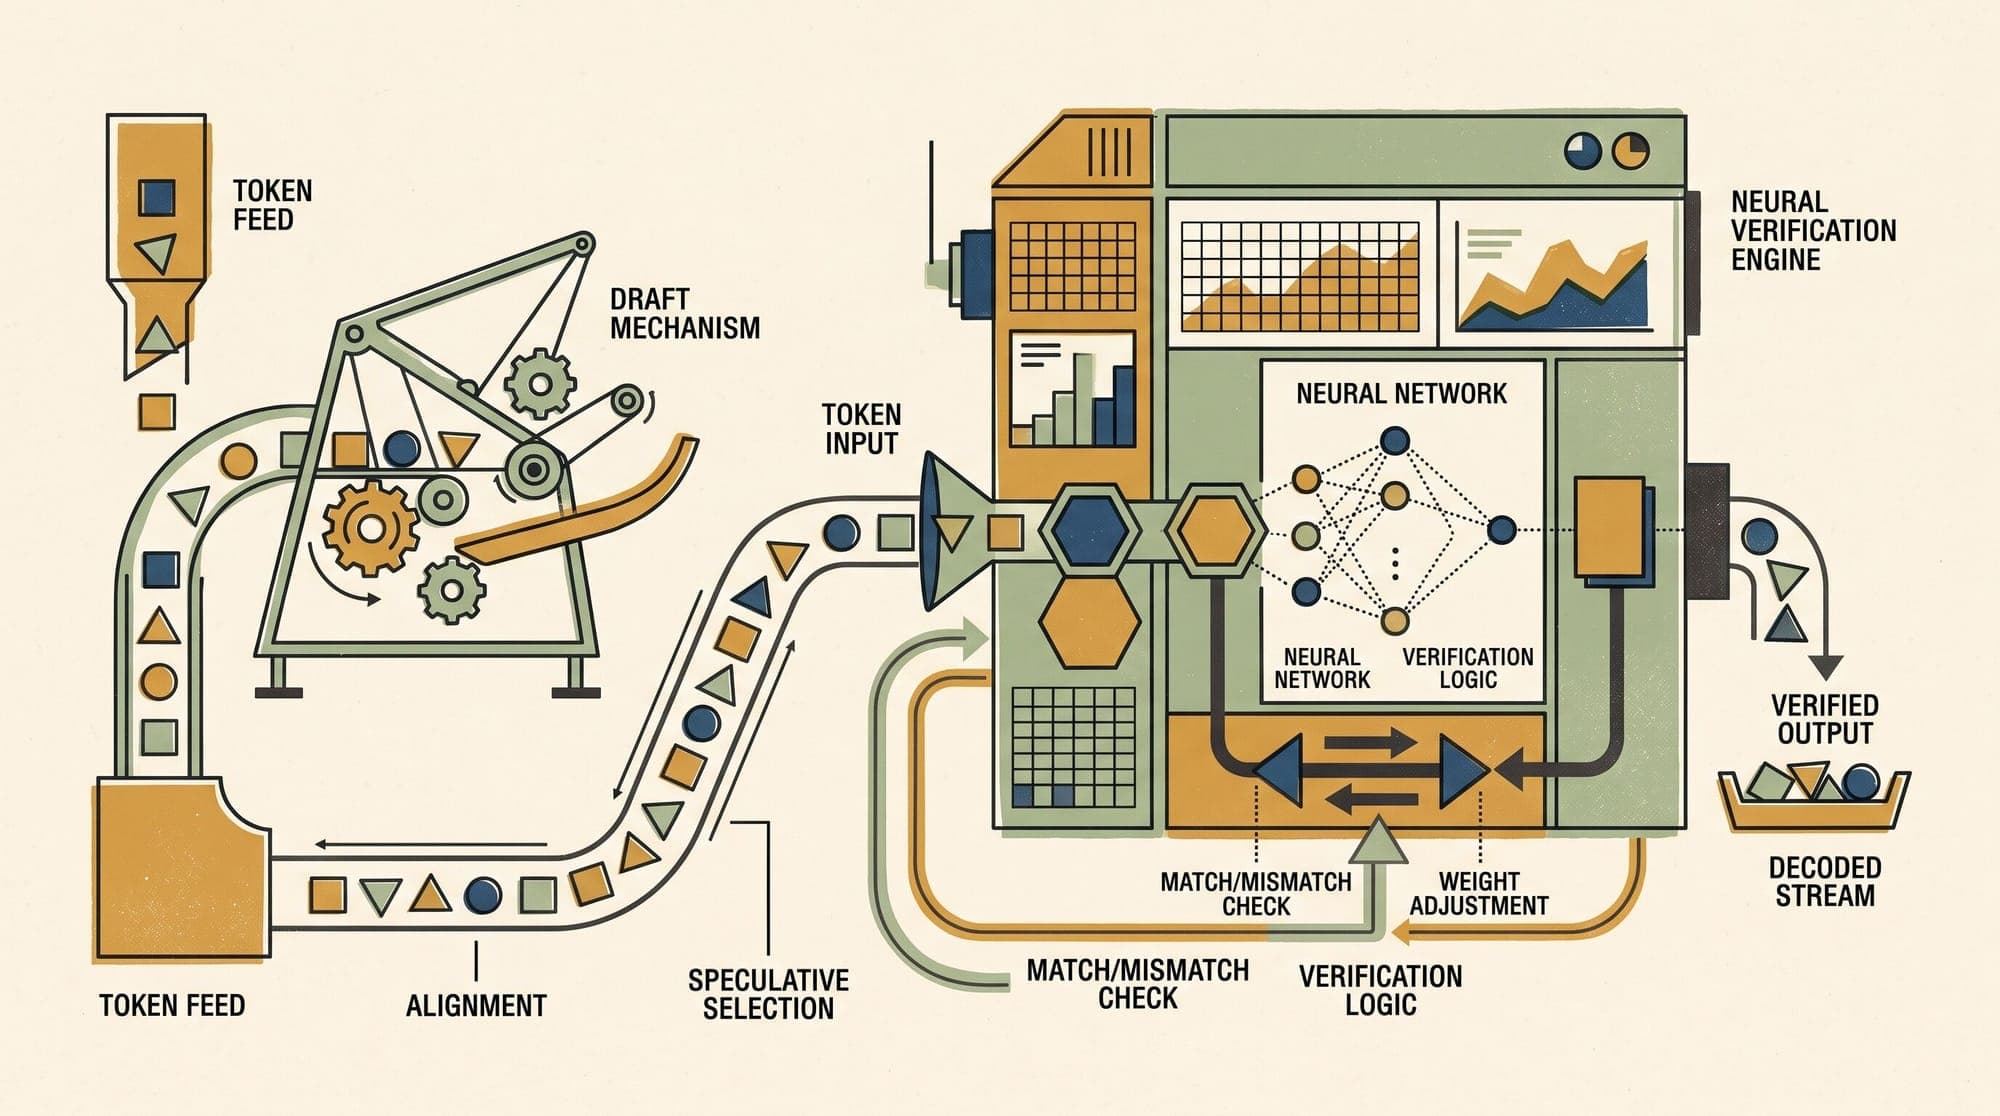
    Liquid AI has released speculative decoding draft checkpoints for three models across its LFM2.5 series: LFM2.5-1.2B-Instruct, LFM2.5-2.6B, and the mixture-of-experts model LFM2.5-8B-A1B. The release introduces small companion models designed to accelerate auto-regressive generation without altering final token distributions. The draft models are available in Safetensors and GGUF formats on Hugging Face, with immediate support implemented for SGLang and llama.cpp. Architecture and Draft Desig

    AI
    2 min read
  3. Unsloth Releases Dynamic V3.0 GGUFs for Qwen 3.8 27B with 1-Bit Mode and MTP

    Unsloth AI has published its Dynamic V3.0 quantization suite for Alibaba's Qwen 3.8 27B model family, releasing optimized GGUF and NVFP4 checkpoints alongside public calibration matrices. The release claims a greater than 10 percent increase in top-1 percent accuracy at identical file sizes compared to standard baseline quantizations, while introducing an ultra-low-bit dynamic tier that operates within 8GB of memory. Qwen 3.8 27B is a dense vision-language model utilizing hybrid attention layer

    Open Weights
    2 min read
  4. Liquid AI Releases Quantization-Aware Distilled Q4_0 Checkpoints for LFM2.5 Models

    Liquid AI has released Quantization-Aware Distillation (QAD) Q4_0 GGUF checkpoints for its LFM2.5 model series, allowing edge runtimes to execute 4-bit quantized non-transformer architectures without the accuracy degradation typically associated with standard post-training quantization (PTQ). The release covers four models in the LFM2.5 family: LFM2.5-230M, LFM2.5-350M, LFM2.5-1.2B-Instruct, and LFM2.5-2.6B. The checkpoints are packaged in the standard GGUF format and run across llama.cpp and c

    AI
    2 min read
  5. Reference-Free Preference Optimization: How ORPO and SimPO Eliminate Reference Models in LLM Alignment

    Aligning large language models with human preferences has historically relied on two distinct stages after pretraining: Supervised Fine-Tuning (SFT) to establish instruction-following behaviors, followed by reinforcement learning from human feedback (RLHF) or Direct Preference Optimization (DPO) to maximize response quality. While DPO removed the need for explicit reward modeling and complex actor-critic policy loops (such as Proximal Policy Optimization, or PPO), it retained an architectural b

    AI
    7 min read
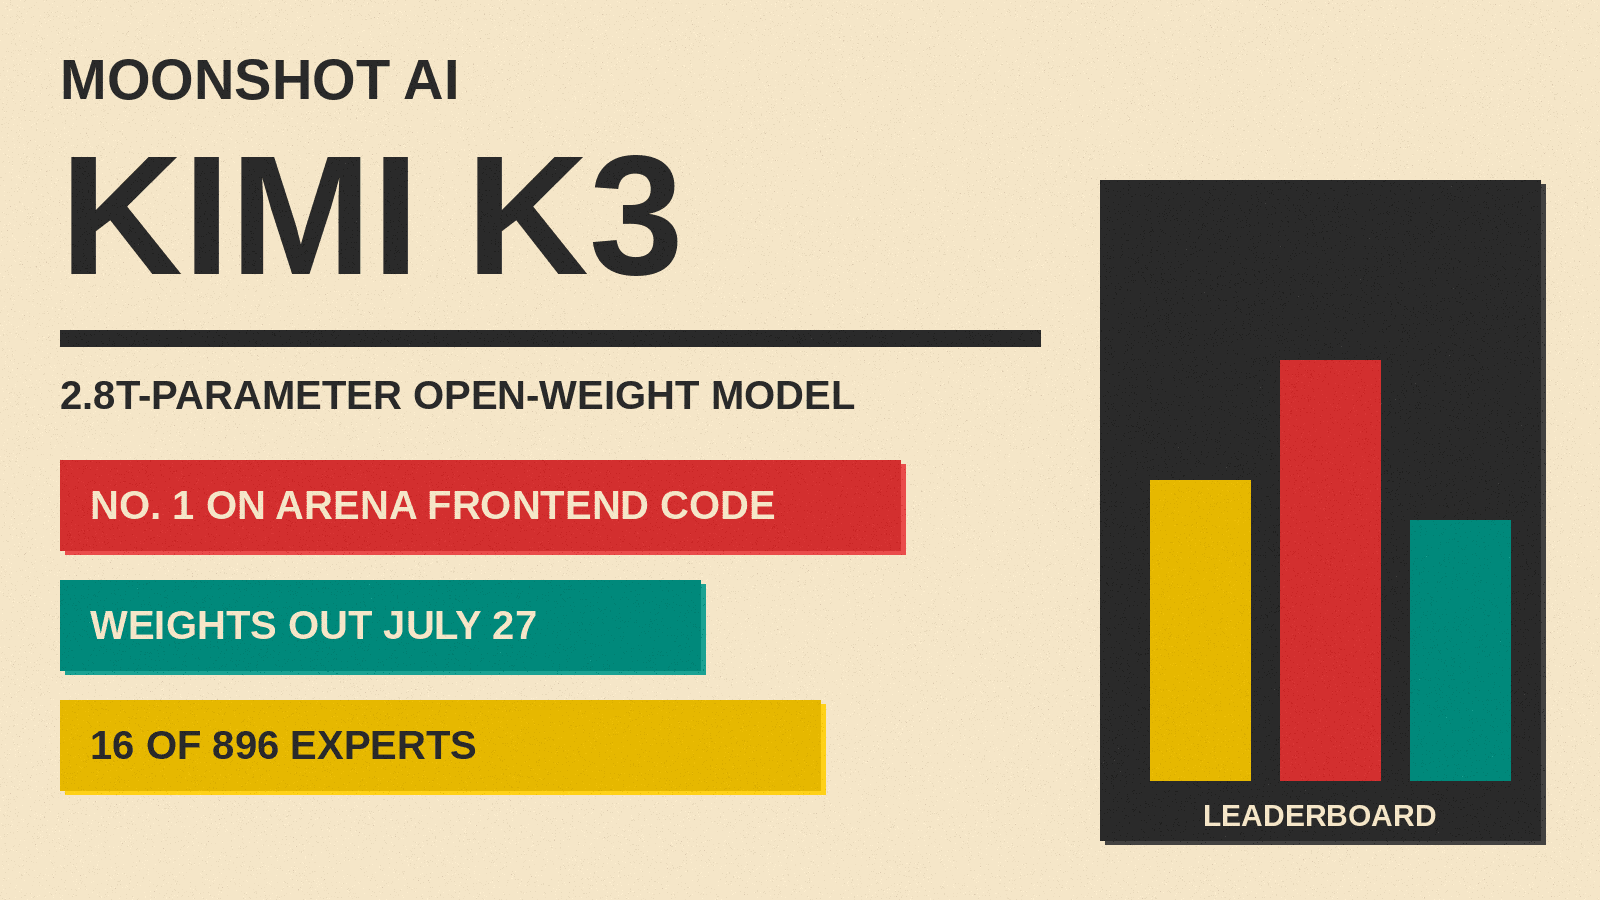
  6. Harvey Introduces Tenet, Its First In-House Legal LLM Trained on Moonshot's Kimi K3

    Legal AI startup Harvey has announced Harvey Tenet, its first proprietary, in-house foundation model tailored for legal workflows. The release marks a strategic shift for the $11 billion legal tech company, which has historically relied on API access to third-party frontier models from OpenAI and Anthropic. Tenet is post-trained on top of Kimi K3, an open-weights model released in July 2026 by Chinese AI lab Moonshot AI. The initiative is part of a broader platform update titled Harvey II, whic

    AI
    2 min read
  7. Sentence Transformers v6.0 Adds Native Multi-Vector Late Interaction for ColBERT and ColPali

    Hugging Face has released Sentence Transformers v6.0, adding native multi-vector late-interaction retrieval to the library through a new MultiVectorEncoder interface. The update integrates ColBERT-style models and vision-language document retrieval systems directly into the standard Sentence Transformers workflow alongside dense bi-encoders, sparse models, and cross-encoder rerankers. Mechanics of Late Interaction and MaxSim Standard dense embedding models compress an entire passage or query

    AI
    2 min read
  8. Tencent Releases UI-Mate: Open-Weight Foundation GUI Agents with In-Context Demonstration Learning

    Tencent's HY Frontier team has released UI-Mate, an open-weight foundation GUI agent designed for autonomous computer operation across desktop environments. Available in 27-billion and 9-billion parameter configurations, the models pair environment-grounded reinforcement learning with an in-context demonstration pipeline that allows agents to reference structured human workflows during execution. Alongside model weights on Hugging Face, Tencent published a technical report, code repository, and

    AI
    2 min read
  9. Nvidia's Nemotron 4 aims for a trillion parameters, but China is already there

    Nvidia is building Nemotron 4, a new family of open-weight AI models meant to challenge the strongest freely available models, according to reporting by The Information cited by The Decoder. The largest model in the family is planned to reach at least one trillion parameters, twice the size of Nvidia's current Nemotron 3 Ultra. To train it, Nvidia has tripled its cloud spending on in-house model development to 28 billion dollars through 2031. The earliest the models could ship is this fall. C

    Nvidia
    1 min read
  10. Nvidia's Nemotron 3.5 Lightning bets on speed over size

    Nvidia has released Nemotron 3.5 Lightning, the first model in a new Nemotron 3.5 family, and it is playing a different game than most open-weight releases this year. Instead of chasing the highest intelligence score, Nvidia built a compact model that runs fast and cheap while still matching much larger rivals on standard benchmarks. A small model that keeps up Lightning carries 31.6 billion total parameters, but only 3.6 billion are active at any moment. It keeps the hybrid Mamba-Transformer

    Nvidia
    3 min read
  11. Nvidia Opens Alpamayo 2 Super for Commercial Use

    Nvidia has released the weights for Alpamayo 2 Super, a 34-billion-parameter vision-language-action model for autonomous-vehicle development, under the Linux Foundation's OpenMDW-1.1 license. The change gives automakers and autonomous-driving developers a commercial path to fine-tune, redistribute, and build derivative models from Nvidia's largest Alpamayo release, according to the company's announcement and model card. A cloud teacher model, not a robotaxi driver Alpamayo 2 Super combi

    AI
    2 min read
  12. Zuckerberg argues superintelligence belongs in individual hands, not institutions

    Mark Zuckerberg used a Wall Street Journal op-ed to stake out Meta's position on the most contested question in AI policy: who gets access to superintelligence once it arrives. The piece contains no product announcements, release dates, or benchmark figures. It is a positioning argument, not a technical roadmap. Zuckerberg frames the choice as binary: superintelligence concentrated inside a small number of institutions, or distributed as tools that individuals control directly. He calls the lat

    Meta
    2 min read
  13. Three open letters split the AI industry on open weights and development pacing

    In the span of one week in late July 2026, three open letters from different factions of the AI industry laid bare a fundamental disagreement about how to govern frontier model development. The letters address open weights, distillation, and whether the pace of AI progress should be deliberately slowed. Letter 1: Microsoft's open weights coalition (July 24) Microsoft organized a letter titled "Open Weights and American AI Leadership" signed by 235 companies including NVIDIA, Amazon, Y Combina

    Policy
    2 min read