FlashDecoding: How Sequence Partitioning Solved the Memory Bandwidth Bottleneck in LLM Generation
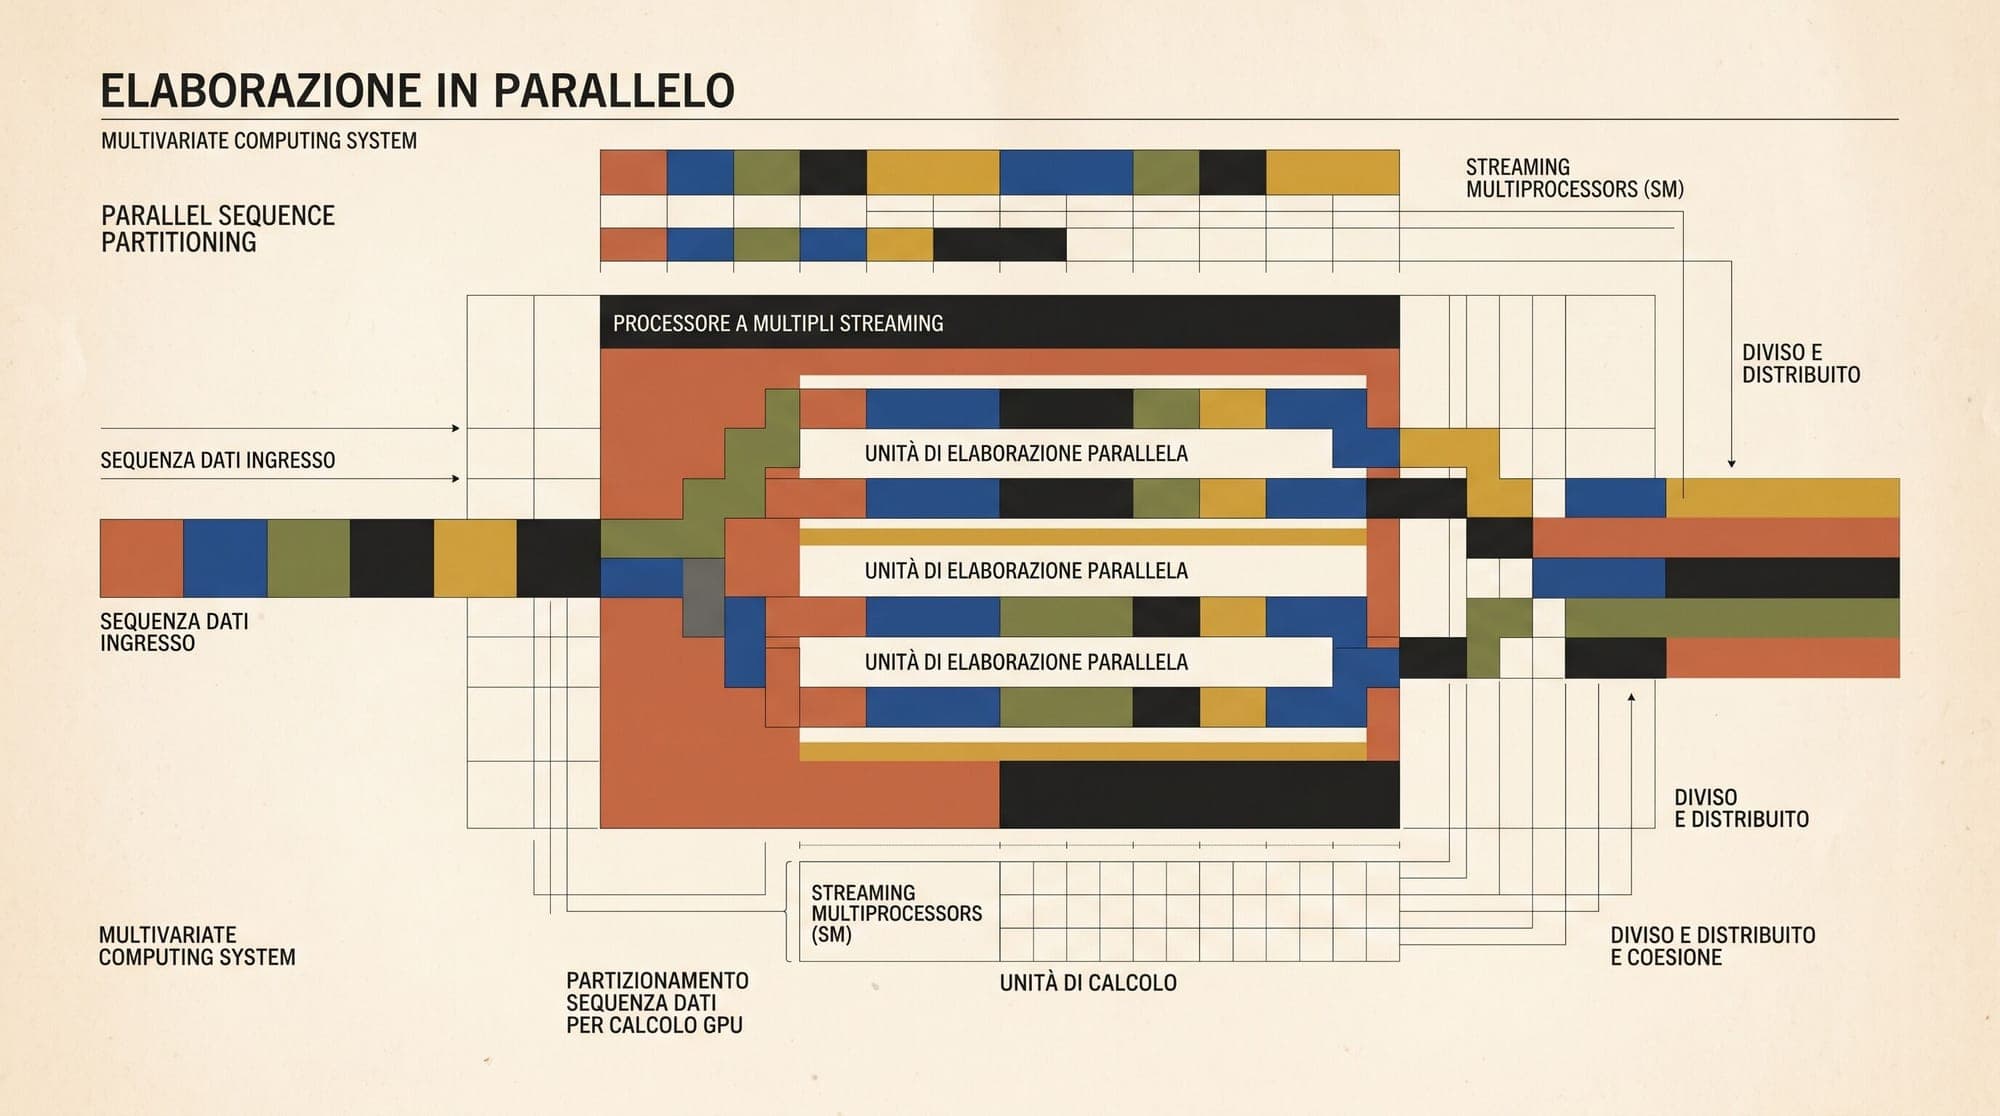
FlashDecoding: How Sequence Partitioning Solved the Memory Bandwidth Bottleneck in LLM Generation In large language model serving, execution divides into two distinct operational regimes: prompt prefill and autoregressive token generation (decoding). While FlashAttention transformed prefill throughput by eliminating High Bandwidth Memory (HBM) round-trips for intermediate attention matrices, standard FlashAttention algorithms encounter a severe hardware utilization bottleneck during decoding.