
The open-source LLM serving engine SGLang has released version 0.5.18, introducing an overlapped startup engine that significantly reduces cold-start latency for large language models, alongside communication kernel optimizations and expanded architecture support.
Comprising 710 pull requests from 212 contributors, the release addresses operational overheads in LLM infrastructure where autoscaling, rolling cluster deployments, and worker node recovery frequently pay steep restart penalties.
Overlapping Checkpoint Staging and CUDA Graph Capture
In traditional LLM serving runtimes, initialization executes sequentially: the engine first loads model weights from disk or network storage into host and device memory, runs kernel autotuning, and then captures CUDA graphs across multiple batch bucket sizes to minimize runtime kernel launch overhead.
SGLang v0.5.18 introduces an overlapped startup mode, enabled via the --startup-weight-load-mode overlap flag. The mechanism stages model checkpoint pages from storage concurrently with the initialization and capture of CUDA execution graphs.
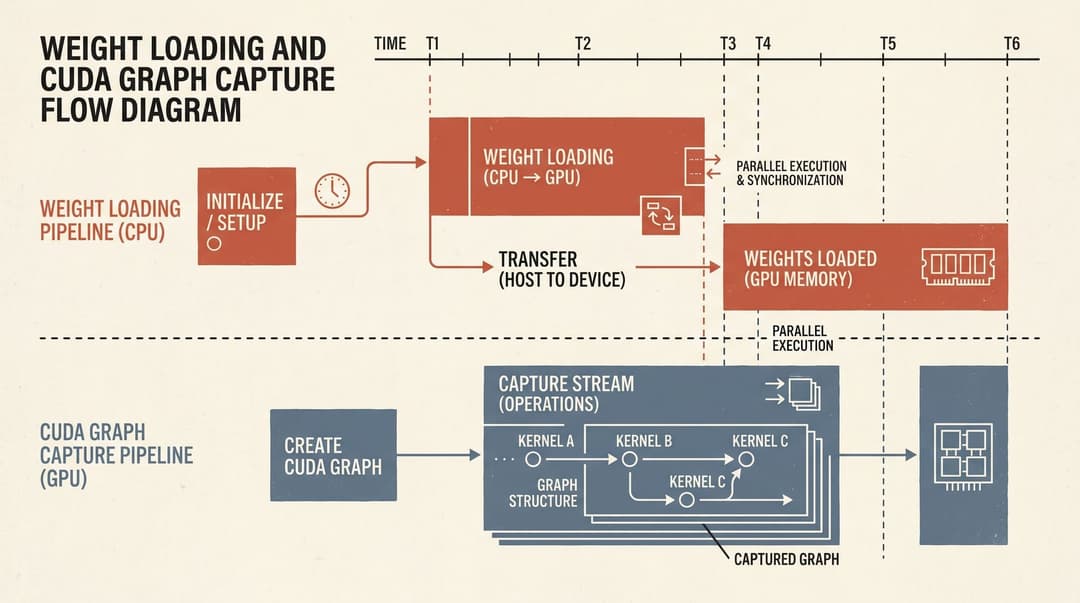
According to benchmark data published in the release notes, initializing a Qwen3-32B checkpoint on an NVIDIA H100 system drops from 84.8 seconds under standard serial loading to 35.6 seconds with overlapped staging, representing a 2.38x speedup. The approach also outperforms standard serial prefetching pipelines by 8.6% to 11.7%.
All-to-All Communication for Tensor-Parallel LMHead
The release restructures the final language model head (LMHead) computation across tensor-parallel ranks. Previously, computing logits over large vocabularies across partitioned ranks required an allgather collective followed by a scatter operation.
Version 0.5.18 refactors this path into a single all-to-all communication pattern for pure data-parallel attention layouts. On NVIDIA B200 accelerators running DeepSeek-V4-Pro decode workloads, execution time in the LMHead drops from 320 microseconds to 169 microseconds, reducing time per output token (TPOT) from 36.97 ms to 35.67 ms.
Additionally, the runtime integrates FlashInfer's Multi-Node NVLink (MNNVL) workspace for non-fused allreduce sites, avoiding fallback to standard NCCL collectives. When serving DeepSeek-V4-Flash under tensor parallelism 4 (TP4) on Blackwell GPUs, decode throughput improves by up to 6.9% at low batch sizes.
Unified Kernel Caching and Architectural Additions
SGLang v0.5.18 unifies caching infrastructure across compilation layers. Previously, runtime artifacts from Triton, FlashInfer, PyTorch Inductor, DeepGEMM, and CUDA driver JIT compilers were distributed across separate system paths. All compiled artifacts are now centralized under SGLANG_CACHE_DIR.
The release expands architecture coverage across autoregressive and diffusion models, adding native serving engines for:
- Muse Glimmer: Multimodal autoregressive vision-language model.
- Intern-S2-Mobius: Autoregressive foundation architecture.
- Diffusion Video & Image Frameworks: SANA-Video, LingBot-Video-MoE, LTX-2.5, Cosmos3 Edge and Distilled, and LongCat-Image.
- Recipe Additions: Validated serving recipes for Qwen 3.8, Ling-3.0, Nemotron 3.5 Lightning, Dots3-Note, and DeepSeek-V4-Pro-0813.
Core framework dependencies have been updated to PyTorch 2.13.0 with Triton 3.7.1, FlashInfer 0.6.17, CuTeDSL 4.6.2, and sgl-kernel 0.4.6.post1.
AMD GPUs: NVFP4 Checkpoints and Kimi K3 Tuning
A large part of the release targets AMD hardware. With --quantization quark_mxfp4, SGLang can now load NVFP4 checkpoints made with NVIDIA ModelOpt or AMD Quark on AMD GPUs. It dequantizes the weights and requantizes them to MXFP4 at load time, without holding a full-precision copy in memory. The release notes report 97.5% to 100.2% GSM8K accuracy recovery against the NVFP4 reference across MiniMax-M2.7, GLM-5.1, Kimi-K2.6, Qwen3.5-397B, and DeepSeek-R1.
Kimi K3 also gets a set of MI355X optimizations. A grouped-head MLA verify kernel replaces a path that re-read the shared latent once per head. At concurrency 2 to 32, the notes list 1.37x to 1.77x higher throughput and 1.45x to 2.42x better inter-token latency. The AITER MLA prefill kernel now accepts K3's 12-head shape, cutting time to first token by up to 14.9%. A decode geometry tuned for gfx950 adds 46% to 73% inter-token latency improvement at 68k input tokens and is opt-in via SGLANG_MLA_DECODE_TUNE=1. GSM8K accuracy holds at 0.951 to 0.957.
Speculative Decoding Updates
The speculative decoding section adds log-probability output for both DFlash and DSpark drafters, which matters for evaluation and reinforcement learning pipelines that need token-level scores. It also fixes a silent KV cache corruption bug in DeepSeek-V4 when more than four draft tokens were used, a crash when combining speculative decoding with DP attention, and DFlash draft KV pool sizing.
Breaking Changes and Upgrade Notes
Operators should check a few items before upgrading:
- First launch recompiles. Because all kernel caches move under
SGLANG_CACHE_DIR, the first start after upgrading rebuilds them once. Teams that pre-warm or volume-mount caches should copy or symlink the old directories; DeepGEMM and FlashInfer are the costly ones. Setting an existing variable such asTRITON_CACHE_DIRkeeps that cache where it is. - torchao is gone. The
--torchao-configoption is removed. It had raised an ImportError for every value since the torchao pin moved to 0.17.0. - DeepEP ships as wheels. DeepEP now installs from released
sgl-deep-epwheels instead of building from source. - Remote media limits. Image, video, and audio URLs are capped at 64 MiB by default, with redirect validation and optional hostname allowlists.
- New defaults. MoE deferred finalize and unified-cache out-of-window SWA slot freeing are on by default for the paths named in the notes; each has an environment variable to turn it off.
The notes also list known issues. Two kernel fusions, one for Kimi K3 and one for GLM-5.2 on AMD, were landed and reverted and are not in this release. The overlapped startup mode itself is opt-in, so existing deployments keep the old serial loading until they add --startup-weight-load-mode overlap.
