
A small network of 3D art sites says a crawler carrying a Roblox email address copied 145.5 GB of its users' models in October, and the post describing it reached the Hacker News front page on Tuesday. The reaction split three ways: anger about licenses and robots.txt, doubt that the files were ever meant for a model that makes things for kids, and a loud group asking why anyone is surprised that public files got downloaded.
Roblox had not answered the sites' two emails when the post went up, according to Open3DLab. Roblox has not publicly confirmed or denied that it ran the crawler, and a user agent string is something anyone can type. Everything below about the crawler is the operator's account.
What Open3DLab says happened
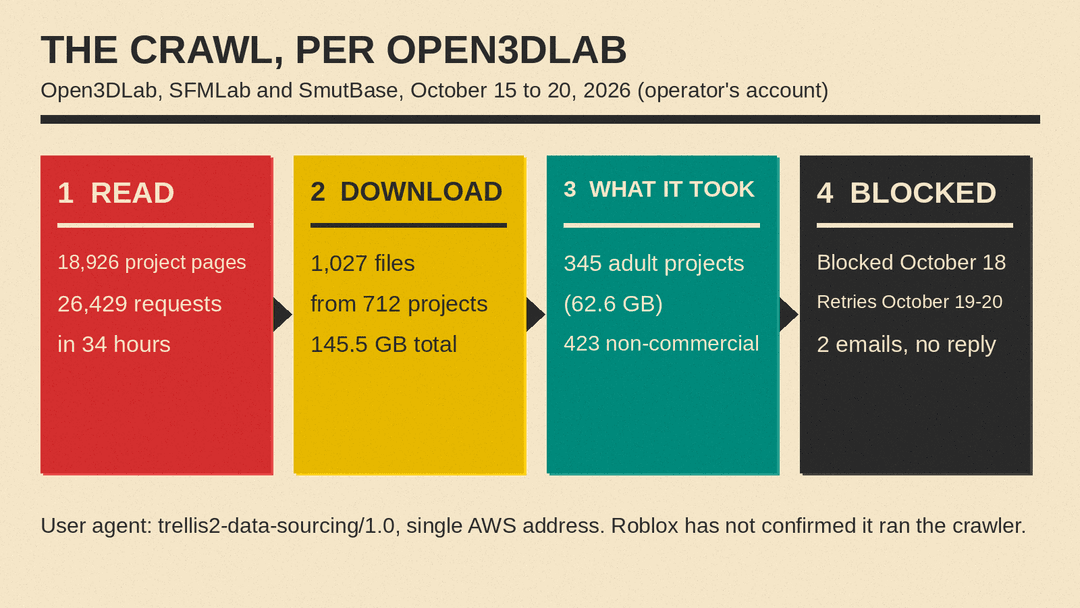
Open3DLab, SFMLab and SmutBase are run by the same operator, who posts as Salaryman. In the October 26 post, the operator says that on October 15 and 16 a crawler with the user agent trellis2-data-sourcing/1.0 (3D foundation model research; [redacted]@roblox.com) read the main pages of 18,926 projects in 26,429 requests over 34 hours, all from a single Amazon Web Services address.
It then downloaded complete copies of 1,027 files from 712 projects, 145.5 GB in all. The operator gives these counts:
- 364 of the files (54.8 GB) came from 224 projects on SmutBase, which hosts only adult content.
- Counting adult-marked SFMLab projects, 345 of the 712 projects (62.6 GB) were adult content.
- 423 of the 712 projects carry non-commercial-only licenses.
- The crawler fetched robots.txt and did not follow it, and the sites' terms of service forbid scraping.
The sites blocked the crawler on October 18. The operator says it came back on October 19 and 20, kept trying through the blocks, and ran in a pattern that matched office hours in Central European time, with a pause around lunch. The sites say they kept the full log export for an outside audit.
The post's guess at the purpose is labeled as a guess. Roblox has been building a 3D foundation model since at least 2025, starting with a system it calls Cube, and the operator says the email address belongs to one of the more than 40 authors of the Cube paper. The "trellis2" label may point to TRELLIS.2, an open 3D generation model Microsoft released in late 2025, or may just be a codename. "We can't prove it, and we don't know whether any of our creators' files ended up in a model," the post says.
Tom's Hardware and Startup Fortune picked up the story. Startup Fortune noted it had found no independent reporting and no statement from Roblox.
Hacker News: licenses, not download size
The Hacker News thread had 342 points and 205 comments as of about 7:20 a.m. PT on October 27. Some early replies said 145 GB is small and the files were public. Several commenters pushed back by pointing at the licenses.
User whizzter opened one model at random and found a Creative Commons non-commercial, no-derivatives license. "This is a huge part of why AI upsets people, we can't have nice things such as communities where people are sharing 3d models without it being feeding ground for commercial companies that has little intention to ever honor any licences or compensate authors," they wrote.
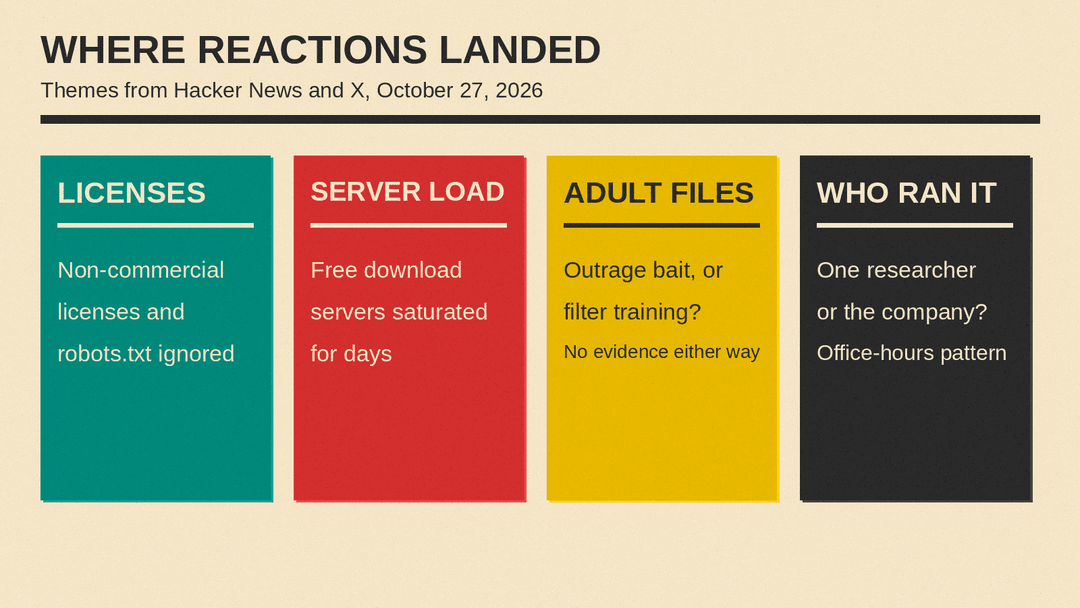
Others focused on the cost to a hobby site. "We used to call this a Denial of Service attack but now it's apparently just a cost of doing business, even for people who just want to run a non-commercial hobby site," wrote tarsierscripter. The operator's post says the scrape saturated the free download servers for a couple of days.
User 233mhz linked a LinkedIn court win over scrapers and asked: "Megacorps can enforce their TOS through the law but small companies cannot?"
The other side argued from the law and from the open web. "In Germany we have decisions from the highest courts that deemed websracping perfectly legal (it was in the context of a competitor scraping airline ticket fares)," wrote littlecranky67, who said sites that do not want scraping need paywalls.
The adult content argument
The post's focus on adult files drew pushback. "I'm sympatic to open3dlab but I think the focus on adult-content is just trying to spark outcry for cheap," wrote KolmogorovComp.
A few commenters offered a different reason a company might want such files. "I assume they need the adult content in order to detect adult content generated by their users," wrote philipwhiuk. User kortex said a filter model was plausible, then added: "Or they are just being irresponsible. point is, we dont know."
User RIMR called the framing performative. "No, that does not mean they are going to give adult content to children," they wrote.
Others saw the opposite risk. "Given that roblox is almost entirely children, and given the amount of hot water they're in you'd think they'd stay the hell away from adult content," wrote ChrisRR. The operator's post itself says it has "no evidence that any of it reached a model or a product."
One researcher or the company?
The lunch-break pattern became its own thread. One commenter, happyopossum, argued that the timing looked like one person's laptop, possibly not for company use. "If it was not for business purposes, why do it on your work machine, during working hours, with your work email address in the User-agent?" replied Liquid_Fire.
User hmokiguess quoted the single-address detail from the post and said it sounded like "some R&D dude running solo." The operator's post takes the other view and says a data-collection run like this "is a company's decision, and the responsibility for it is Roblox's."
On defenses, itintheory wrote that bot protection services cost money, and "In the case of publicly hosted freely accessible data it can be hard to justify."
On X: mostly summaries, a few takes
On X, most posts were summaries of the blog. The Tom's Hardware account wrote that Open3DLab "has publicly claimed that a web crawler, attributed to Roblox, downloaded 145.5GB of its data." A post by @murtuza_merc had about 6,500 views and 101 likes as of 7:28 a.m. PT, and ended: "Roblox has not commented."
A few added opinions. "Ask who approved the export, not just what the model learned," wrote @harmszaj5. @hunterarrowx called it "the oldest trade there is: take first, apologize if the ones taken from can afford a lawyer." And @NabilChiheb reduced it to one line: "it fetched the robots.txt, then ignored it."
Why it matters
This dispute is about 3D assets, which the operator argues public datasets have relatively little of: complete, textured characters, many of them rigged, in the formats artists work in. The same post says Meta's crawler made about 380,000 requests to the sites in the month before, though the operator calls the Roblox crawler the first it spotted that pulled users' uploaded files.
The open questions are the ones the operator listed for Roblox: whether it ran the crawler, what the data was for, whether any of it went into a model, and whether it will delete the files. Until Roblox answers, the identification rests on a user agent and the operator's logs. We will update this post if Roblox responds.
Sources
- Open3DLab: Roblox downloaded 145 GB of models from our sites (including adult content) without asking
- Tom's Hardware: Open3DLab accuses Roblox of downloading 145GB of 3D assets
- Startup Fortune: A crawler labelled Roblox downloaded 145 GB of 3D models
- Hacker News discussion
- X post by @tomshardware
- X post by @murtuza_merc
- X post by @harmszaj5
- X post by @hunterarrowx
- X post by @NabilChiheb
