Latest / page 15

The latest stories

1230 articles

Articles, page 15

281-300 of 1230
  1. USD.AI Secures $100M Stablecoin Debt Facility from Bullish to Fund GPU-Backed Infrastructure Loans

    Digital asset exchange operator Bullish has committed a $100 million stablecoin-denominated debt facility to USD.AI, an on-chain lending protocol that issues non-recourse debt collateralized by data center GPU hardware. The financing establishes an institutional credit channel connecting liquid stablecoin capital with the expanding compute infrastructure requirements of modern AI training and inference providers. Developed by Permian Labs, USD.AI structures asset-backed credit facilities specif
    Hardware
    2 min read
  2. Mixture-of-Depths (MoD): Mathematical Foundations, Dynamic Token-Level Compute Routing, Top-k Capacity Budgeting, and FLOP-Optimal Transformer Architectures

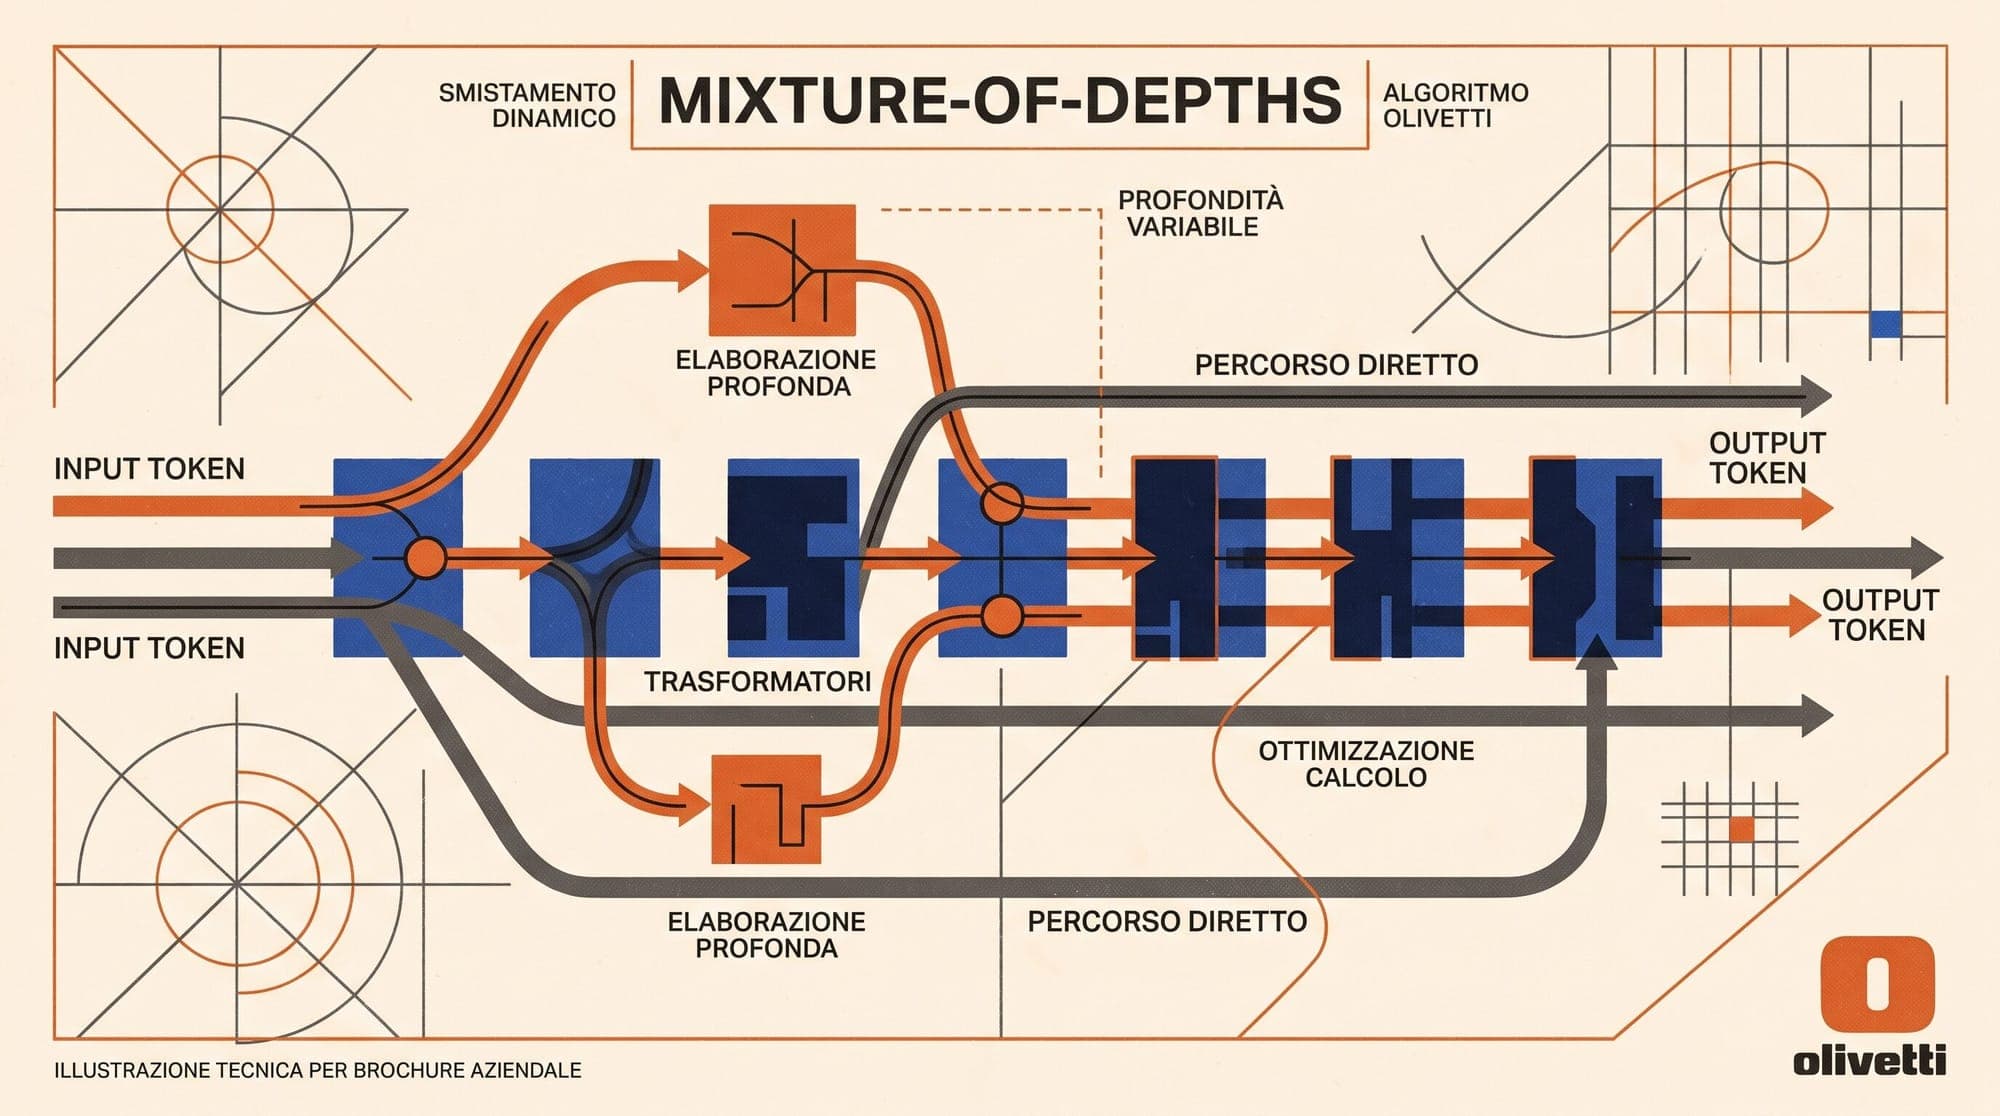
    Standard autoregressive Transformers allocate an identical compute budget to every token in a sequence. Regardless of whether a token represents a trivial punctuation mark, a common grammatical function word, or a complex semantic reasoning step, the model applies the exact same sequence of multi-head self-attention and multilayer perceptron (MLP) operations across all $L$ layers. In Mixture-of-Depths: Dynamically allocating compute in transformer-based language models, researchers at Google De

    AI
    6 min read
  3. South Korea Launches AI for All Initiative Treating Frontier Models as Public Utilities

    South Korea's Ministry of Science and ICT (MSIT) has launched the "AI for All" initiative, a government-sponsored project aimed at deploying nationwide, free-tier access to artificial intelligence chatbots and public administrative agents. The initiative structures generative AI capabilities and agent workflows as public utilities, establishing a subsidized access model for South Korean citizens. Consortia and Public Bidding Six major commercial consortia submitted bids to operate the public

    AI
    2 min read
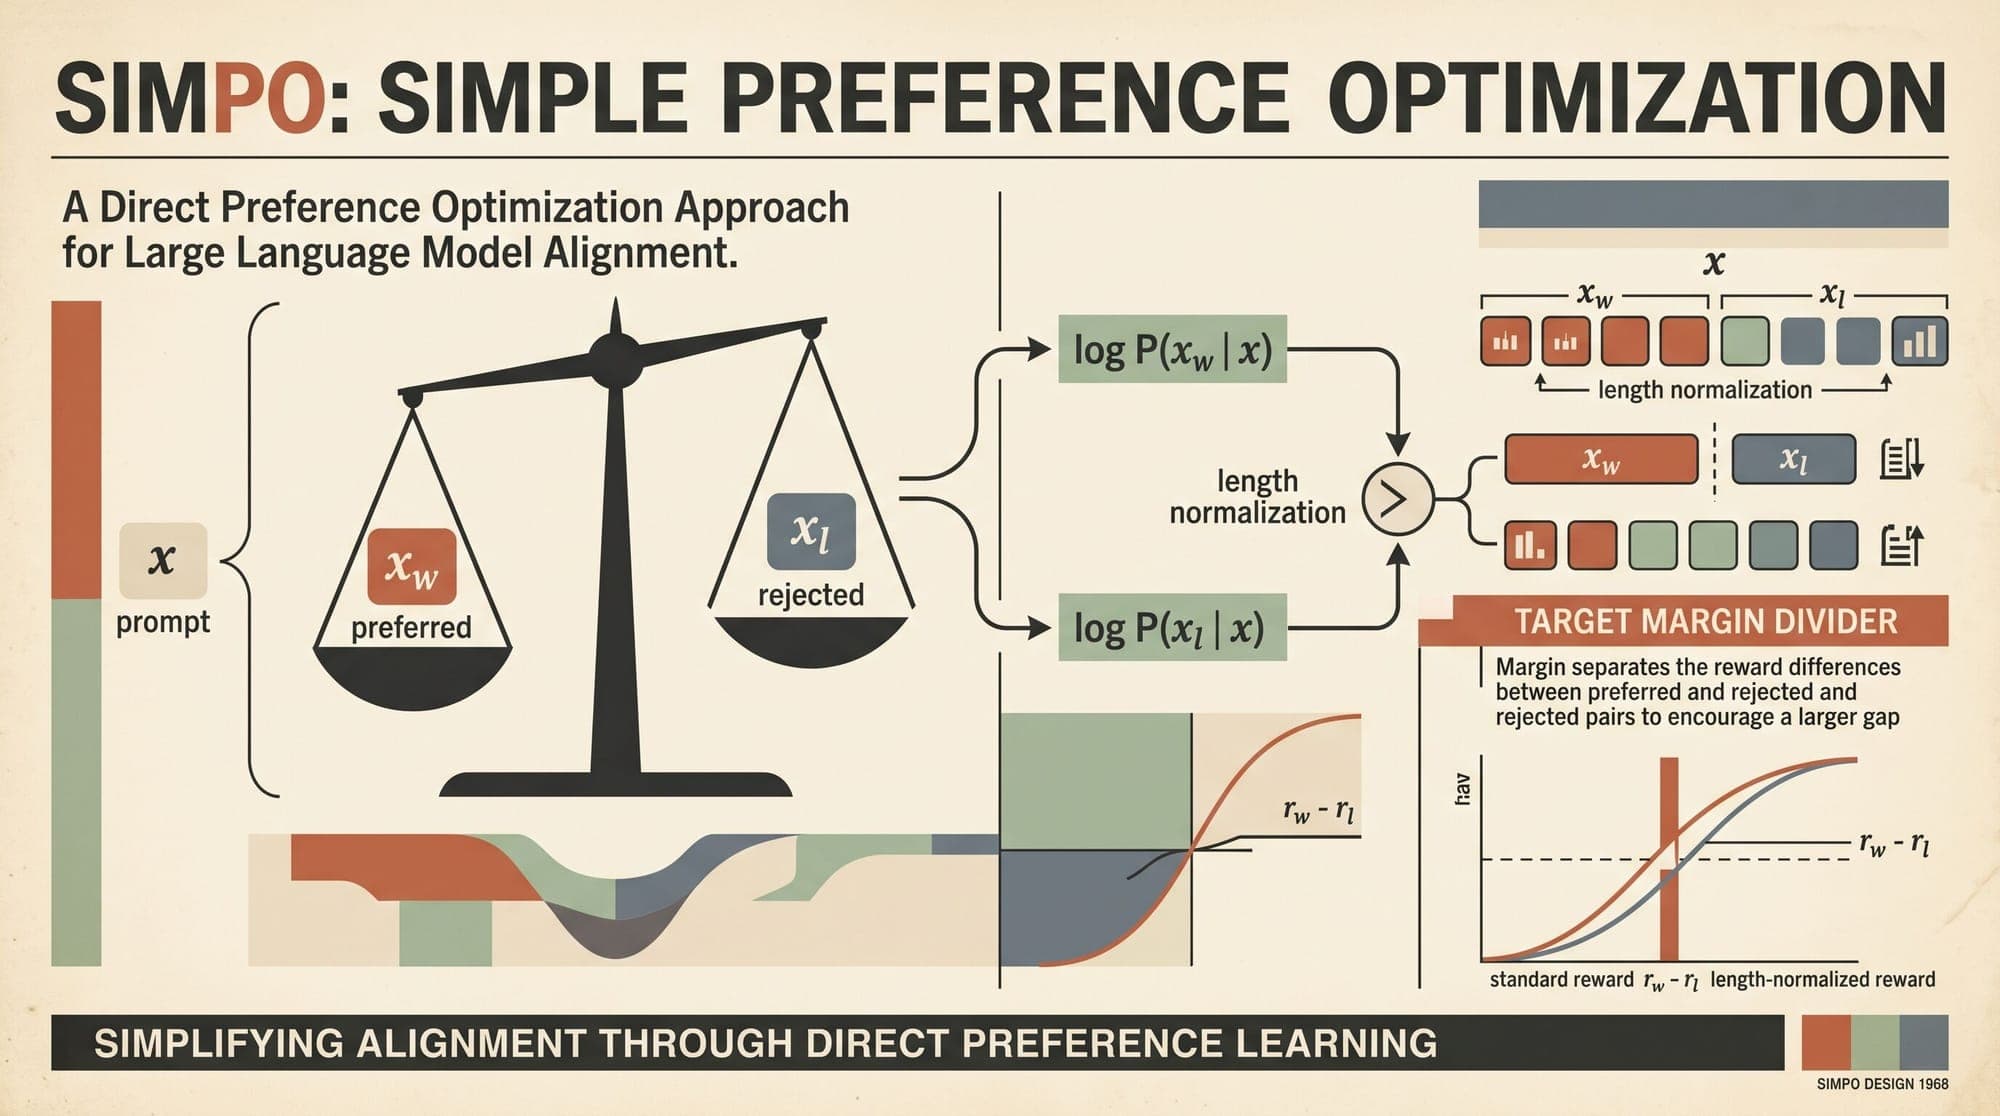
  4. Simple Preference Optimization (SimPO): Mathematical Foundations, Reference-Free Implicit Reward, Length Normalization, and Target Margin Dynamics

    Simple Preference Optimization (SimPO): Mathematical Foundations, Reference-Free Implicit Reward, Length Normalization, and Target Margin Dynamics Post-training preference alignment has become the definitive step in transforming raw pretrained large language models into instruction-following assistants. While Reinforcement Learning from Human Feedback (RLHF) via Proximal Policy Optimization (PPO) established the initial standard, its requirement to maintain actor, critic, reference, and reward

    AI
    11 min read
  5. OpenAI Partners with Thai Government to Launch Accelerator for Healthcare and Education Startups

    OpenAI has partnered with Thailand's Ministry of Higher Education, Science, Research and Innovation (MHESI) to launch an eight-week accelerator program supporting ten Thai startups building AI products in healthcare, wellness, and education. The initiative, announced in Bangkok, represents OpenAI's first public-private partnership focused on startup acceleration with the Thai government. Participating organizations include Thailand's National Innovation Agency (NIA), Mahidol University, and Tec

    OpenAI
    2 min read
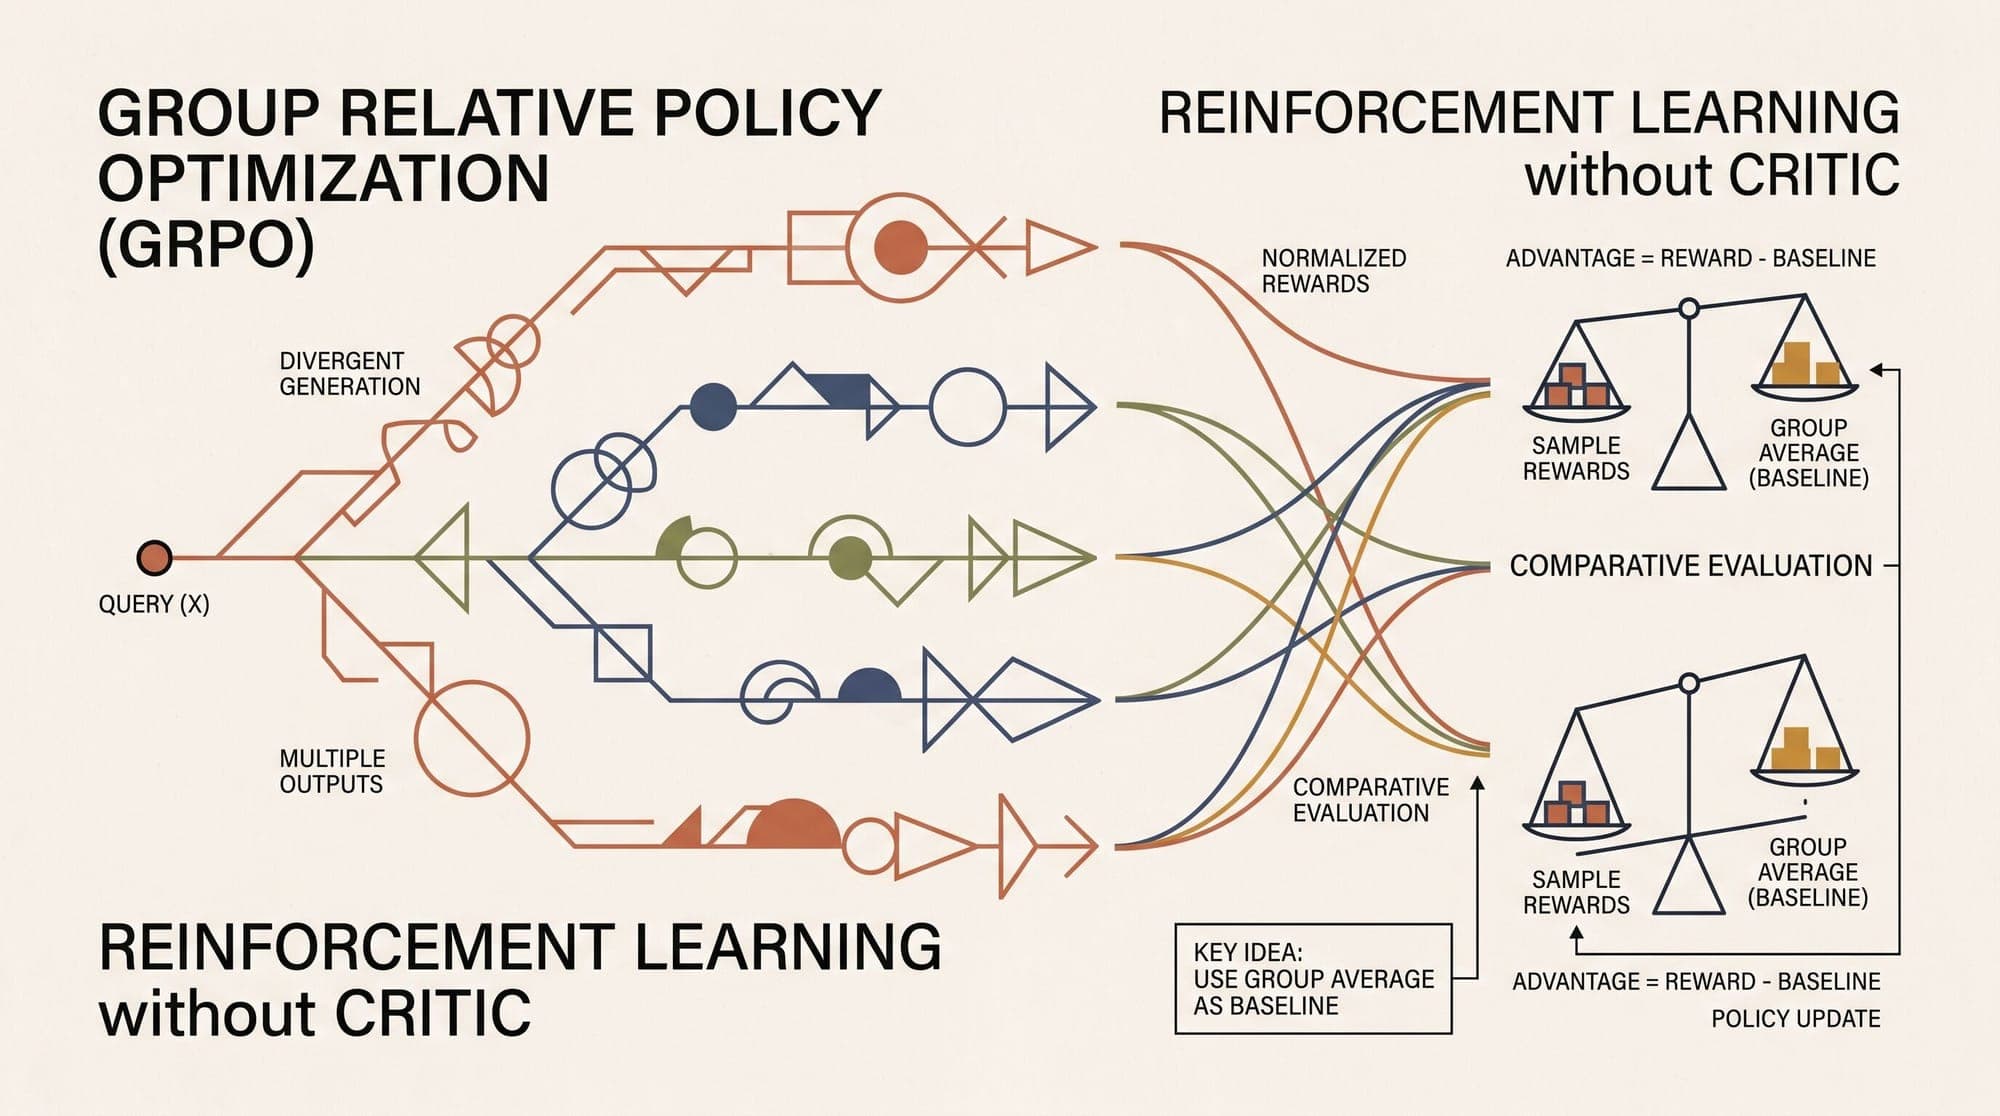
  6. Group Relative Policy Optimization (GRPO): Mathematical Foundations, Critic-Free Advantage Estimation, Group Reward Normalization, and Reinforcement Learning with Verifiable Rewards

    Reinforcement learning from human and verifiable feedback has become the central paradigm for unlocking complex reasoning, mathematical problem solving, and autonomous code synthesis in frontier large language models. While early post-training pipelines relied heavily on Proximal Policy Optimization (PPO) or offline preference algorithms like Direct Preference Optimization (DPO), both methodologies present structural bottlenecks when scaling to long-horizon reasoning. PPO requires maintaining a

    AI
    11 min read
  7. OpenAI Tests Persistent Mode in Codex for Long-Running Autonomous AI Agents

    OpenAI is testing an execution profile termed "Persistent Mode" within its Codex agent codebase, designed to enable continuous, self-directed task execution without standard step-count timeouts or per-turn pauses. Code commits surfaced in the public repository of the Codex command-line interface indicate that the agent can proactively generate follow-up tasks, maintain state across development sessions, and continue working autonomously until explicitly halted by the user. Architecture and Re

    OpenAI
    1 min read
  8. Federal Judge Overturns Pentagon Supply Chain Risk Blacklisting of Anthropic

    A federal judge has ruled that the Trump administration broke the law when it designated Anthropic a supply chain risk, finding that the government unlawfully targeted the company for refusing to comply with Defense Department demands, The Guardian reported. U.S. District Judge Rita Lin issued a 59-page decision overturning Defense Secretary Pete Hegseth's designation and barring the federal agencies named in the lawsuit from enforcing President Trump's order to stop using Anthropic's tools. Th

    Anthropic
    2 min read
  9. Anthropic Opens 10,000 Claude Seats and Expands Grants for Academic Scientists

    Anthropic has introduced a dedicated scientific research initiative providing 10,000 subsidized Claude Team subscription seats and expanding API grant funding for academic and non-profit institutions. The program broadens the company's research support beyond initial biology use cases into mathematics, physics, engineering, and computer science. Under the new plan, accredited academic institutions and non-profit research organizations can register research groups under principal investigator ad

    AI
    2 min read
  10. Tencent Open-Sources Hy4-Preview: 770B MoE Architecture with 1M Context

    Tencent has released the open-weights preview of its next-generation foundation model, Hy4-preview, under the Apache 2.0 license. The release scales the organization's Mixture-of-Experts (MoE) line to 770 billion total parameters, activating 49 billion parameters per token across a native 1-million-token context window. Weights have been published across Hugging Face, ModelScope, GitCode, and GitHub, alongside managed API availability on Tencent Cloud TokenHub and OpenRouter. Architectural Sp

    AI
    2 min read
  11. Open-Source Embedding Models and Serving Frameworks in Production: Comparing BGE-M3, NV-Embed-v2, GTE-Qwen2, and ModernBERT-Embed Architecture, Matryoshka Projections, Context Scaling, and Serving Economics

    Open-Source Embedding Models and Serving Frameworks in Production: Comparing BGE-M3, NV-Embed-v2, GTE-Qwen2, and ModernBERT-Embed Architecture, Matryoshka Projections, Context Scaling, and Serving Economics (TEI vs. Triton vs. vLLM) Text embeddings form the indexing and retrieval foundation for production Retrieval-Augmented Generation (RAG), semantic search, and agentic memory systems. While early production architectures relied almost exclusively on closed commercial APIs (such as OpenAI's te

    AI
    8 min read
  12. Contrastive Preference Optimization (CPO): Mathematical Foundations, Direct Likelihood Regularization, Out-of-Distribution Error Bounds, and Non-Degenerate Policy Alignment

    Supervised fine-tuning (SFT) and preference alignment represent the standard two-stage training paradigm for post-training large language models. While SFT establishes foundational task adherence by minimizing cross-entropy loss against target references, it suffers from two structural limitations: it cannot surpass the quality ceiling of its training demonstrations, and it lacks an explicit mechanism to penalize near-correct outputs that contain subtle hallucinations or omissions. Direct Prefe

    AI
    11 min read
  13. Post-Training Quantization Toolkits in Production: Comparing AutoAWQ, AutoGPTQ, bitsandbytes, and llm-compressor Architecture, Calibration Profiling, Kernel Execution, and Serving Economics

    Large language model deployment in high-concurrency production environments is governed primarily by memory bandwidth and hardware economics. In standard autoregressive decoding, memory traffic dominates computation: for every token generated, every parameter of the model must be loaded from GPU High Bandwidth Memory (HBM) into SRAM and tensor cores. Serving a 70-billion parameter model in 16-bit precision requires at least 140 GB of VRAM solely for model weights, necessitating multi-GPU tensor

    LLM
    9 min read
  14. Multi-Token Prediction (MTP): Mathematical Foundations, Sequential Latent Stacking, Auxiliary Loss Schedules, and Speculative Inference Acceleration

    Multi-Token Prediction (MTP): Mathematical Foundations, Sequential Latent Stacking, Auxiliary Loss Schedules, and Speculative Inference Acceleration Autoregressive language models have traditionally been trained under a single-token objective: predicting the immediate next token $x_{t+1}$ given the causal context $x_{1:t}$. While this next-token prediction (NTP) paradigm scales predictably with parameter count and dataset volume, it suffers from severe structural limitations. NTP optimizes excl

    AI
    13 min read
  15. Activation Checkpointing and Selective Rematerialization: Mathematical Foundations, Sub-Linear Memory Scaling, Recomputation Trade-Offs, and Megatron-LM Attention Partitioning

    Activation Checkpointing and Selective Rematerialization: Mathematical Foundations, Sub-Linear Memory Scaling, Recomputation Trade-Offs, and Megatron-LM Attention Partitioning Training modern large language models requires orchestrating hundreds of billions of parameters across distributed GPU clusters. While parameter counts and optimizer states are fixed for a given model architecture, the activation memory generated during forward passes scales directly with sequence length, batch size, and

    AI
    10 min read
  16. Local LLM Inference Frameworks in Production: Comparing llama.cpp, Ollama, Apple MLX, and Exo Distributed Clusters

    The deployment landscape for large language models is bifurcating. While datacenter workloads rely on high-throughput continuous batching engines such as vLLM and TensorRT-LLM, local and edge deployments operate under fundamentally different physical constraints. On developer workstations, embedded hardware, and private office clusters, inference is rarely bound by compute saturation across thousands of concurrent requests. Instead, it is constrained by memory bandwidth, local VRAM capacity, hos

    AI
    6 min read
  17. Salesforce and Anthropic Launch Claudeforce with 37 Prebuilt Enterprise CRM Skills in Claude

    Salesforce and Anthropic have expanded their strategic partnership with the release of Claudeforce, an integration layer designed to connect Anthropic's Claude models directly with Salesforce enterprise data, workflow engines, and governance frameworks. The initiative introduces native CRM capabilities inside Claude while embedding Anthropic reasoning models across Salesforce's Agentforce platform and Slack workspace ecosystem. Salesforce in Claude Plugin and AIforce Harness The primary clie

    AI
    2 min read
  18. Anthropic Previews Model Hardware Standard for AI Agent Control of Physical and Lab Equipment

    Anthropic has introduced the Model Hardware Standard (MHS), an open interface specification intended to let AI agents control physical machinery and scientific instrumentation. Released in a research preview on August 27, 2026, the standard extends the design principles of the Model Context Protocol (MCP) to physical actuators, automated laboratory equipment, and industrial hardware. Connecting autonomous software agents to physical hardware has historically required custom integration code for

    AI
    3 min read
  19. Chinchilla Scaling Laws: Mathematical Foundations of Compute-Optimal Pre-Training, IsoFLOP Loss Profiles, Parametric Power Laws, and Data-Compute Allocation

    Chinchilla Scaling Laws: Mathematical Foundations of Compute-Optimal Pre-Training, IsoFLOP Loss Profiles, Parametric Power Laws, and Data-Compute Allocation When allocating a fixed computational budget to train an autoregressive Transformer, engineers face a fundamental trade-off: should FLOPs be spent increasing the model parameter count ($N$), or should they be spent streaming a larger volume of training tokens ($D$)? For several years, frontier AI development followed the empirical scaling

    AI
    14 min read