Author / page 49

axc

Edited by the llms.blog desk.

1230 articles

Articles, page 49

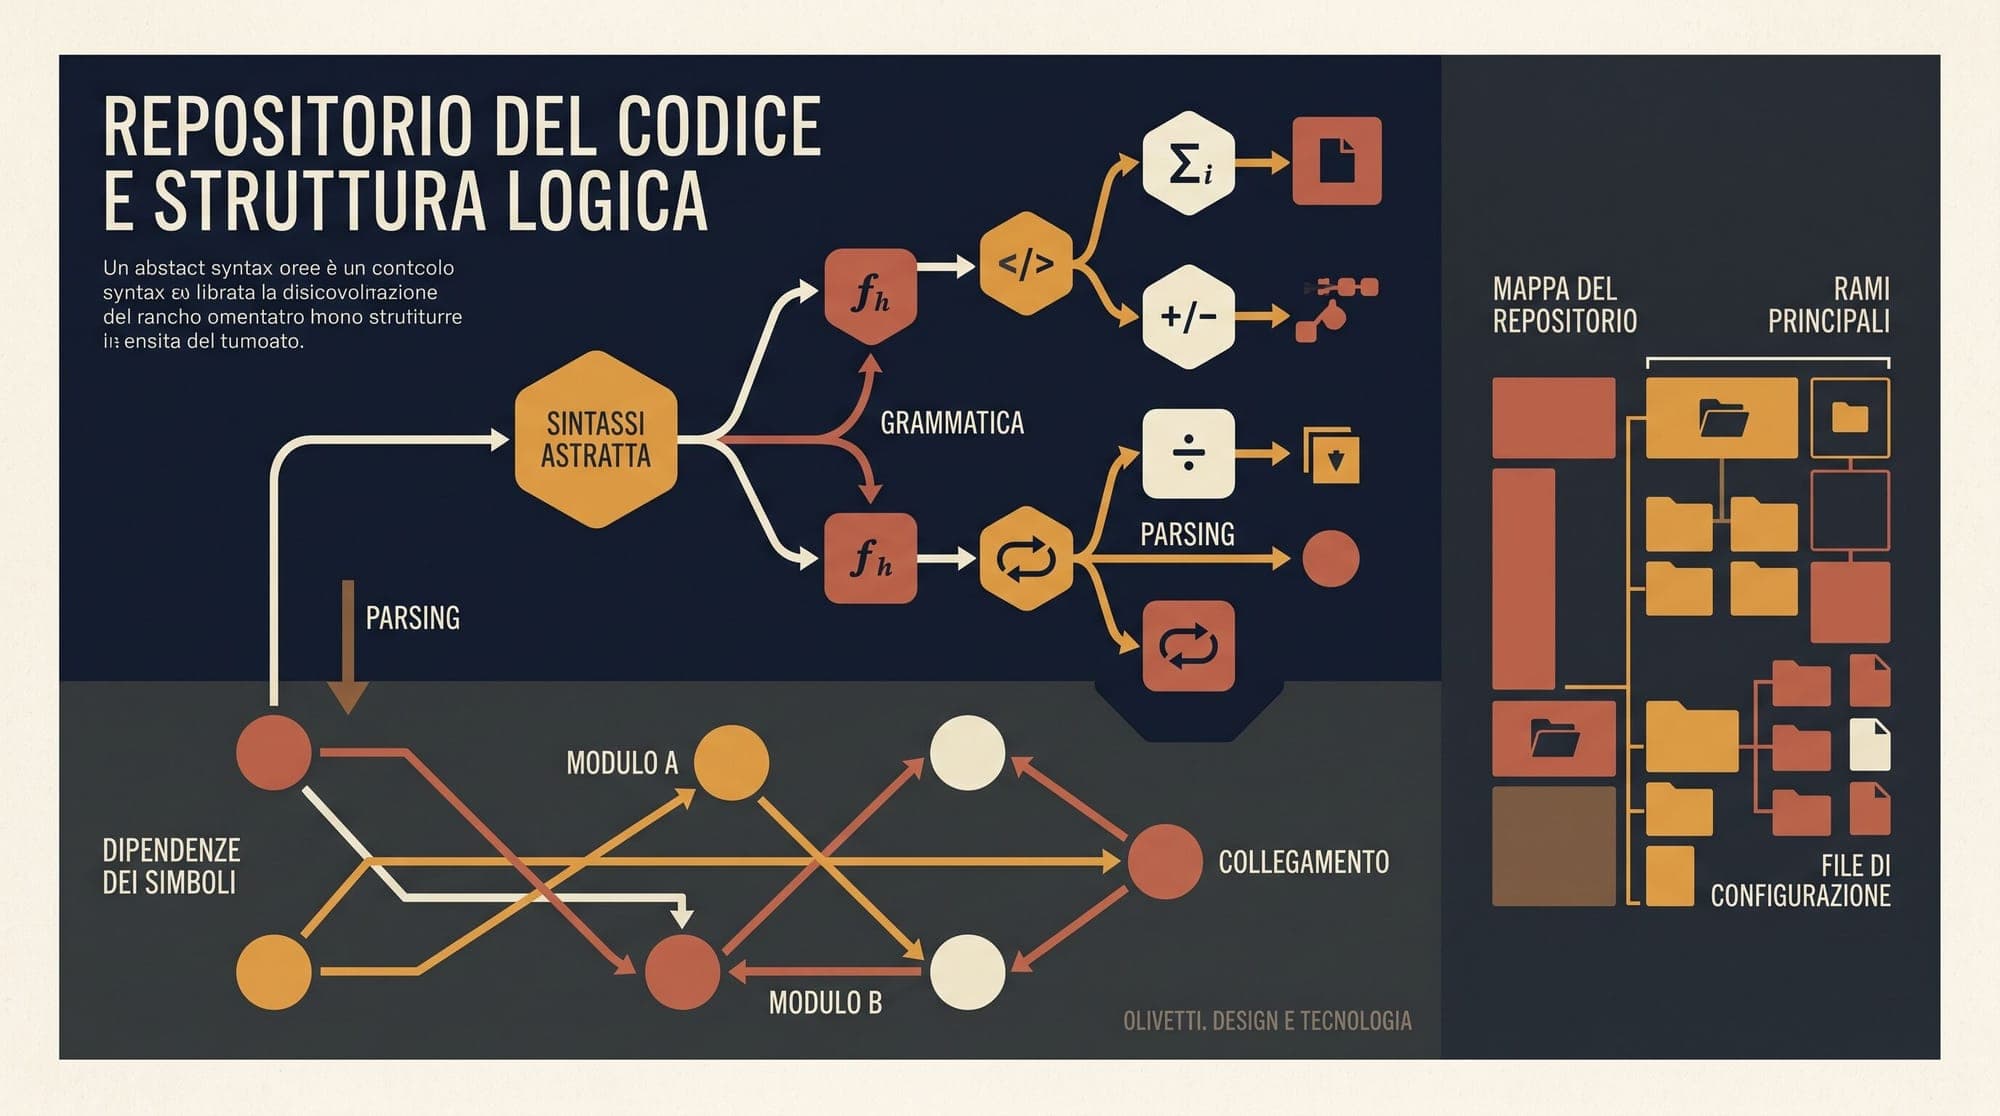
  1. Codebase Context Engineering for AI Agents: Repo Maps, AST Indexing, and Retrieval Architectures

    Modern software repositories routinely contain hundreds of thousands or millions of lines of source code. A medium-sized production project with 500 files and 100,000 lines of code typically spans 3 million to 5 million tokens. While frontier models have expanded context windows to 200,000 tokens or more, stuffing an entire repository into a prompt remains fundamentally impractical. Beyond exponential inference costs and KV cache memory bloat, long-context attention suffers from severe retrieval
    AI
    6 min read
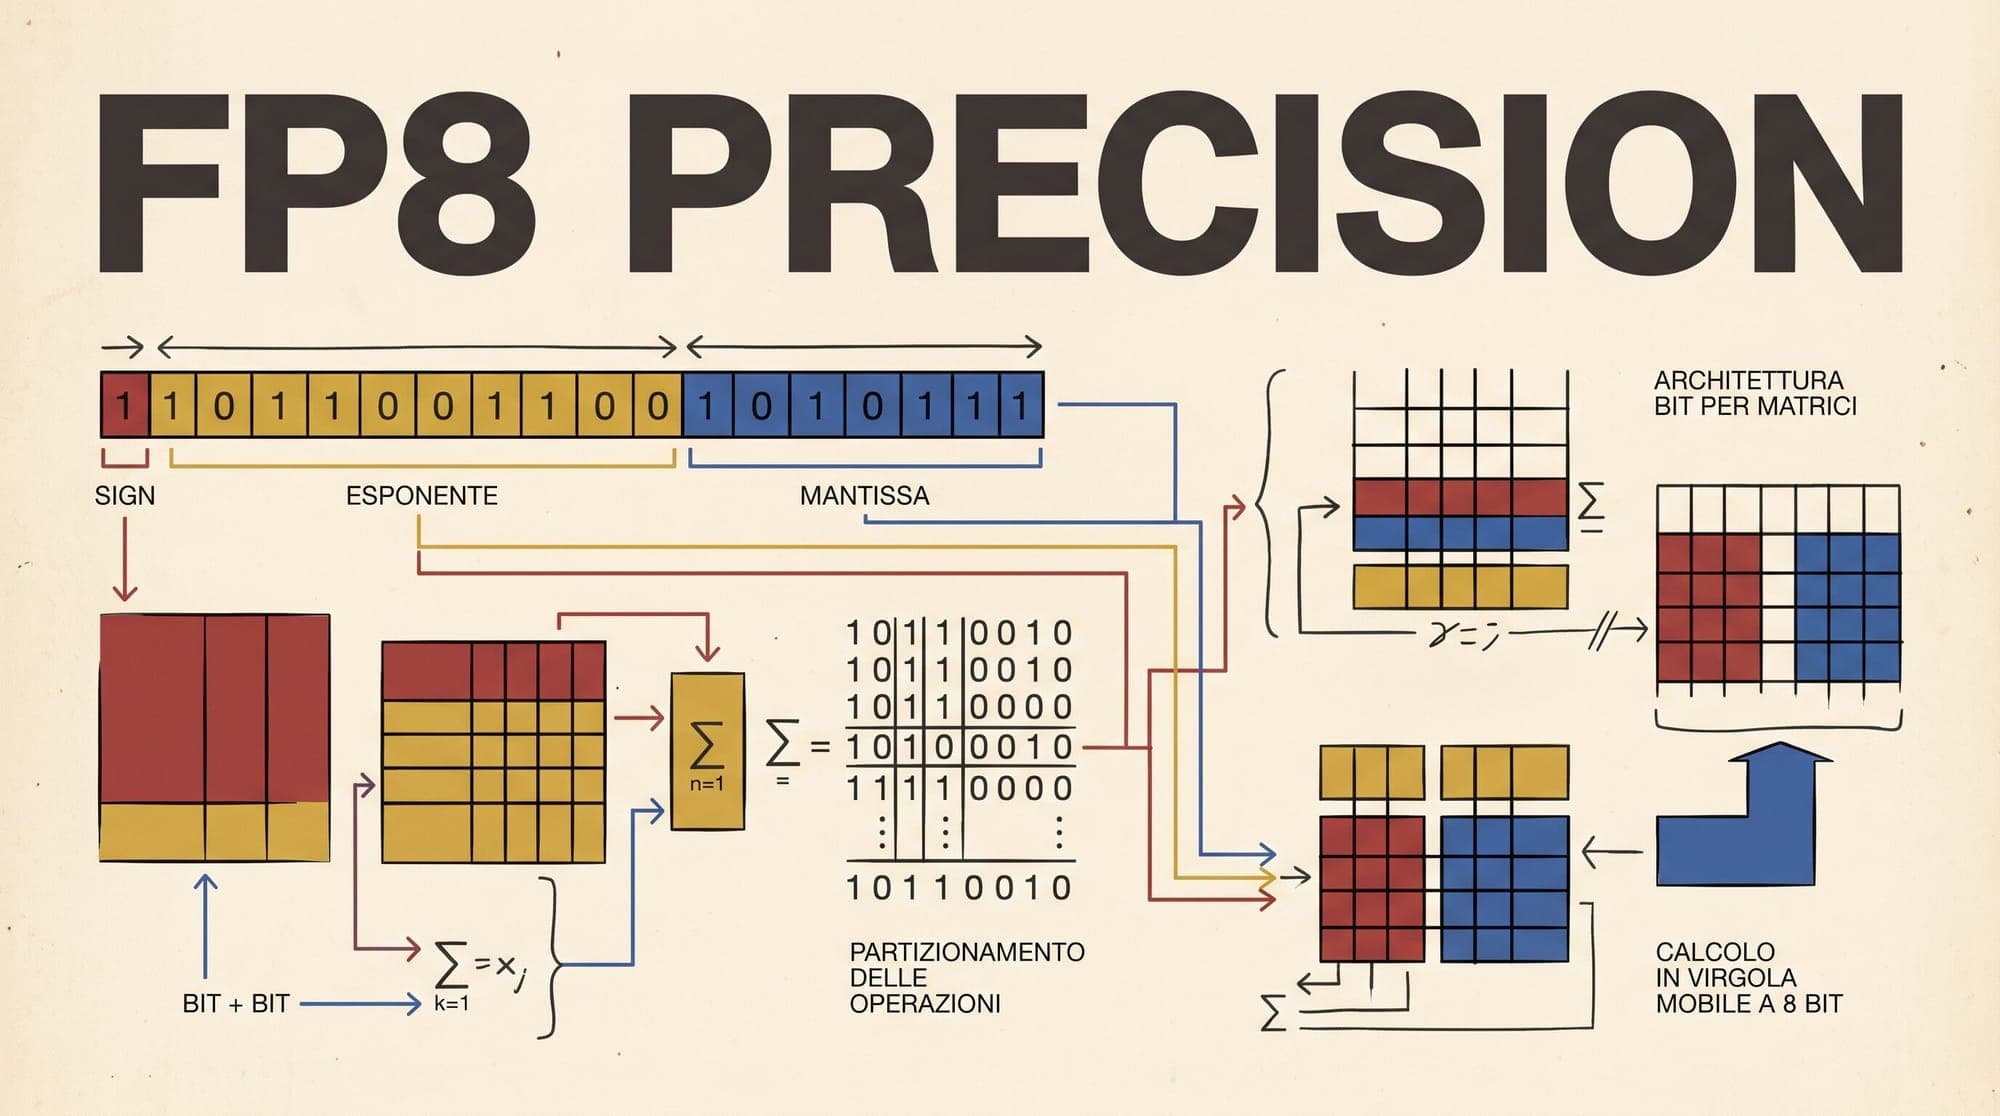
  2. FP8 Mixed-Precision Training: Formats, Scaling Recipes, and Fine-Grained GEMMs

    FP8 Mixed-Precision Training: Formats, Scaling Recipes, and Fine-Grained GEMMs Training frontier large language models requires navigating harsh memory bandwidth and compute boundaries. For years, 16-bit formats such as IEEE FP16 and Brain Floating Point (BF16) served as the standard arithmetic precision for deep learning workloads. While BF16 provided sufficient dynamic range to prevent gradient underflow without manual loss scaling, training clusters still spent substantial time bounded by me

    AI
    8 min read
  3. Z Lab Releases DFlash 2 for Qwen 3.8 27B: Block Diffusion Speculative Decoding with Target KV Injection

    Z Lab has released DFlash 2 checkpoints for Alibaba's Qwen 3.8 27B model family, advancing block-diffusion speculative decoding for open-weights LLM serving. By replacing conventional autoregressive draft models with a non-causal diffusion mechanism paired with direct target key-value (KV) cache injection, the framework achieves up to 3x to 4.3x throughput speedups in production inference engines like SGLang and vLLM without altering output token distributions. For where the 27B fits in the line

    Inference
    2 min read
  4. Pennsylvania Restricts Speculative AI Data Centers in Executive Order 2026-05

    Pennsylvania Governor Josh Shapiro has signed Executive Order 2026-05, introducing strict regulatory standards on high-capacity data center construction and ending the state's expedited permitting program for computing facilities. The directive requires prospective developers of large-scale facilities to enter legally binding commitments with the Commonwealth to safeguard local power grids, protect municipal water supplies, and secure approval from local governments before receiving state enviro

    Policy
    2 min read
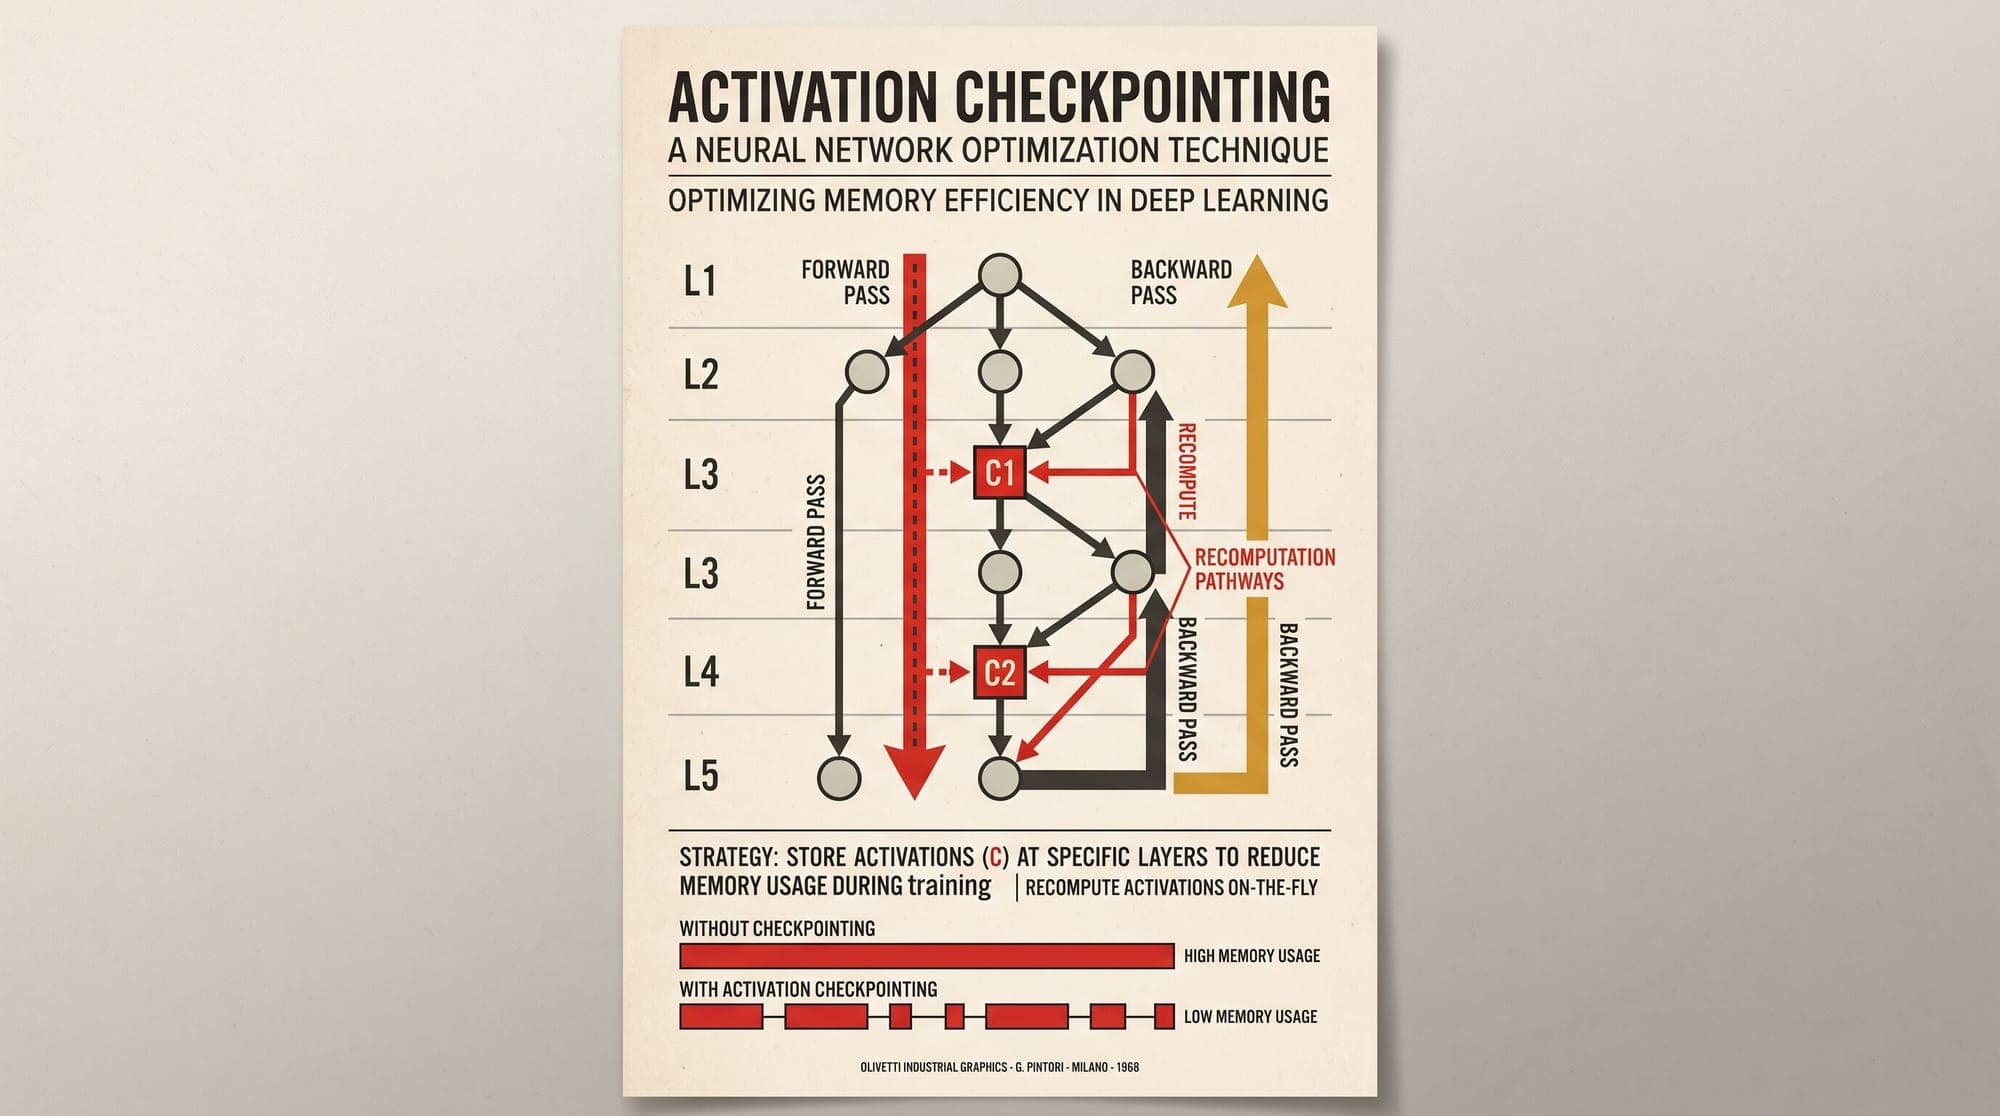
  5. Activation Checkpointing in Large Language Models: How Selective Recomputation Eliminates Memory Bottlenecks

    Large language model pre-training and fine-tuning are fundamentally constrained by GPU memory (VRAM). While distributed techniques such as Fully Sharded Data Parallel (FSDP), ZeRO, and Tensor Parallelism successfully shard model parameters, optimizer states, and gradients across hundreds or thousands of GPUs, activation memory presents a distinct scaling bottleneck. During the forward pass of a transformer model, intermediate tensor outputs must be preserved in GPU memory so that backpropagatio

    AI
    8 min read
  6. Cerebras Unveils CS-4 Rack-Scale System Powered by Three WSE-3 Turbo Chips and Nexus Architecture

    Cerebras Unveils CS-4 Rack-Scale System Powered by Three WSE-3 Turbo Chips and Nexus Architecture Cerebras Systems has announced the CS-4, a rack-scale AI accelerator system designed around three of its next-generation Wafer Scale Engine 3 Turbo (WSE-3 Turbo) chips and a modular hardware architecture dubbed Nexus. Cerebras confirmed that initial customer shipments for the CS-4 are scheduled to begin in the current quarter. The new system marks a structural shift from Cerebras's single-wafer CS

    Hardware
    2 min read
  7. AI FinOps: Cutting LLM Inference Costs by 30-60% Through Model Tiering, Caching, and GPU Optimization

    AI FinOps: Cutting LLM Inference Costs by 30-60% Through Model Tiering, Caching, and GPU Optimization Inference costs have become the second-largest line item in enterprise AI budgets, trailing only talent spend according to RapidData's State of Enterprise AI 2026. This shift represents a fundamental inversion from the 2021-2023 era when training dominated AI expenditure. The compounding nature of serving costs—accumulating every hour as long as users hit the API—means that even modest producti

    AI
    4 min read
  8. Sequence Parallelism in Large Language Models: How Megatron-SP, DeepSpeed Ulysses, and RingAttention Distribute Long Contexts

    Sequence Parallelism in Large Language Models: How Megatron-SP, DeepSpeed Ulysses, and RingAttention Distribute Long Contexts Training and serving frontier large language models on context windows spanning hundreds of thousands to millions of tokens introduces a fundamental memory barrier. While model parameters can be distributed across GPUs using Tensor Parallelism (TP) or Fully Sharded Data Parallelism (FSDP / ZeRO), activation memory scales directly with sequence length $S$. For sequence le

    AI
    9 min read
  9. GLM-5.3 Scores 60 on Artificial Analysis Intelligence Index, Matching Kimi K3

    Independent AI evaluation platform Artificial Analysis has published its benchmark results for Z.ai's GLM-5.3, awarding the reasoning model a score of 60 on its Intelligence Index v4.1.1. The result places GLM-5.3 level with Moonshot AI's Kimi K3 and three points behind frontier leader Claude Opus 5 (63). The evaluation tested GLM-5.3 at its maximum reasoning effort configuration across a nine-part battery that measures agentic tool execution, terminal coding, graduate-level scientific problem-

    AI
    2 min read
  10. Block Open-Sources Berd: Apache 2.0 Desktop Workspace for Multi-Model AI Agents

    Block has open-sourced Berd, an Apache 2.0-licensed desktop application designed to serve as a unified workspace for managing AI agents across different foundation models, toolsets, and execution harnesses. Originally built for internal use across Square, Cash App, and Tidal, the desktop client reached version 0.6.2 on August 18, 2026, with builds available for macOS, Windows, and Linux. The release addresses growing operational fragmentation as developers juggle specialized agent environments

    AI
    2 min read
  11. Self-Hosted Embedding and Reranking Serving in Production: TEI vs. Infinity vs. vLLM Architecture, Dynamic Batching, and Serving Economics

    While generative large language models dominate inference infrastructure discussions, vector embeddings and cross-encoder rerankers handle order-of-magnitude higher request volumes in production retrieval-augmented generation (RAG) and search pipelines. Serving embedding and reranking models presents fundamentally different computational characteristics than auto-regressive text generation. Without auto-regressive token generation loops or key-value (KV) cache state management, the primary engin

    AI
    5 min read
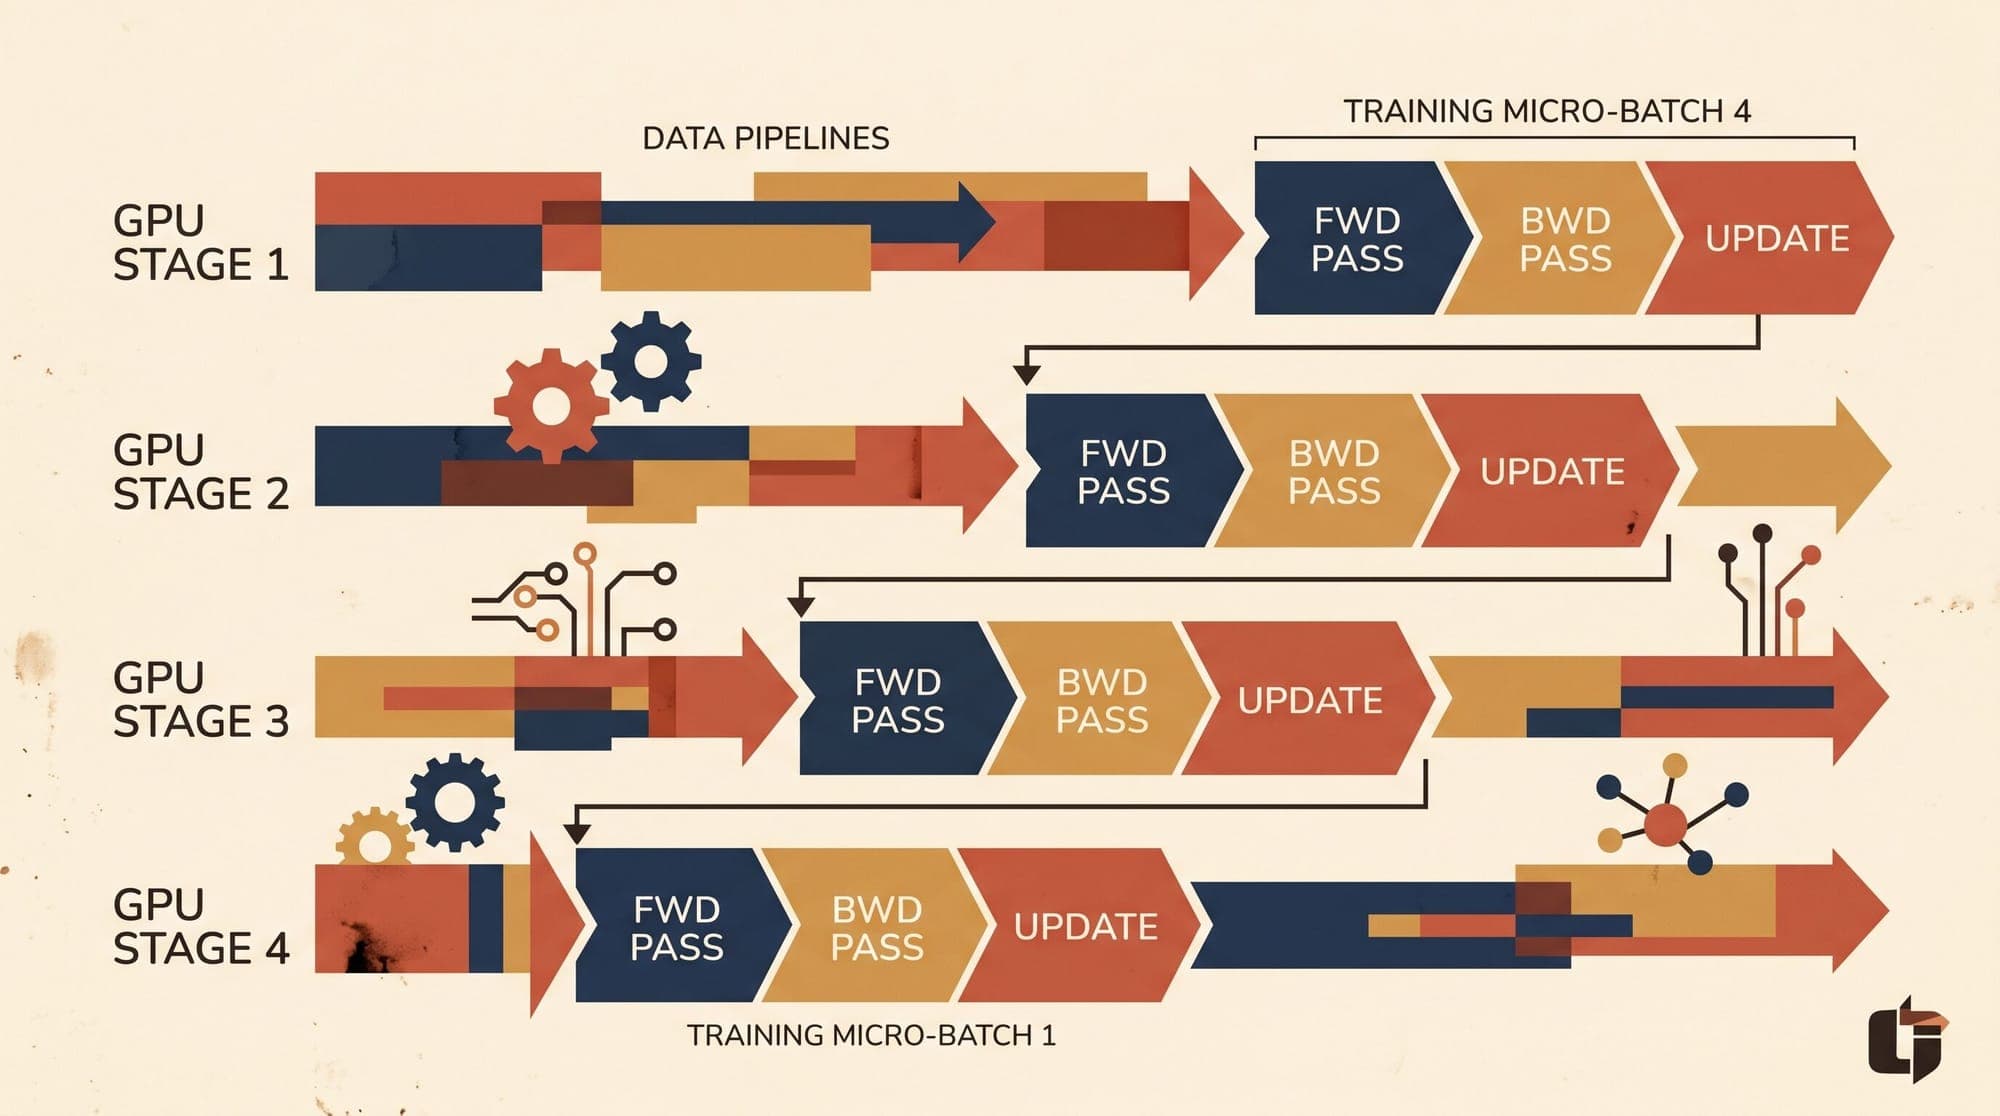
  12. Pipeline Parallelism in Large Language Models: How GPipe, 1F1B Scheduling, and Interleaving Tame Memory and Bubbles

    Training frontier large language models with tens or hundreds of billions of parameters exceeds the physical memory capacity of any individual GPU. While intra-node sharding strategies such as Tensor Parallelism partition individual matrix multiplications across accelerators over high-speed NVLink interconnects, scaling across multi-node clusters encounters strict hardware boundaries. Tensor Parallelism requires multiple collective All-Reduce communications per transformer layer. Across standar

    AI
    6 min read
  13. Modular Open-Sources Mojo Language Compiler and Toolchain Under Apache 2.0

    Modular Open-Sources Mojo Language Compiler and Toolchain Under Apache 2.0 Modular has released the complete source code for the Mojo programming language compiler, standard tooling, and runtime infrastructure under the Apache 2.0 license with LLVM exceptions. The announcement, delivered on August 18, 2026 during the company's ModCon developer conference, fulfills a multi-year roadmap commitment to transition the systems programming language to a fully open development model. The compiler sour

    AI
    2 min read
  14. AI Agent Evaluation in Production: Trajectory Benchmarks, Sandbox Harnesses, and Flakiness Mitigation

    Evaluating standard large language models relies on static input-output pairs: a fixed prompt produces a completion that an automated script compares against reference strings or grades with a calibrated judge. Autonomous AI agents break this paradigm completely. An agent executes a multi-step trajectory consisting of planning, tool invocation, environment state observation, error recovery, and variable-length decision loops. Evaluating an agent requires testing not just the final string output,

    Agents
    5 min read
  15. Fully Sharded Data Parallel (FSDP) and ZeRO: How Memory Sharding Eliminates Redundant Model States in Distributed Training

    Fully Sharded Data Parallel (FSDP) and ZeRO: How Memory Sharding Eliminates Redundant Model States in Distributed Training Training large language models across distributed GPU clusters introduces a fundamental memory bottleneck. In traditional Distributed Data Parallel (DDP) setups, every GPU maintains an identical copy of model weights, optimizer states, and gradients while processing independent data batches. As models scale from billions to hundreds of billions of parameters, static model s

    AI
    6 min read
  16. Anthropic Prepares Dual-Class Super-Voting Shares for Co-Founders Ahead of Planned IPO

    Anthropic is preparing to implement a dual-class share structure that grants super-voting equity to its co-founders ahead of a planned initial public offering, according to a report from The Information. The mechanism is designed to concentrate long-term operational voting control with executive leadership and insulate decision-making from external market and investor pressures. The structure comes as the maker of the Claude model family scales enterprise commercialization, with annual revenue

    Anthropic
    2 min read
  17. Alibaba Demonstrates Native Qwen 3.8 27B Inference on XuanTie C950 RISC-V CPU at 30 Tokens per Second

    Alibaba's semiconductor division, T-Head, announced day-zero native inference support for its latest open-weight model, Qwen 3.8 27B, running directly on the XuanTie C950 RISC-V server processor. Operating without discrete graphics processing units, the 64-core RISC-V chip delivered sustained decode throughput of 30 tokens per second alongside a time-to-first-token latency of 1.9 seconds. The benchmark demonstrates how architectural extensions on general-purpose open instruction sets can handle

    Hardware
    2 min read
  18. Tensor Parallelism in Large Language Models: How Megatron-LM Partitions Multi-Layer Perceptrons and Attention Heads

    Tensor Parallelism in Large Language Models: How Megatron-LM Partitions Multi-Layer Perceptrons and Attention Heads Training and serving modern large language models requires navigating severe hardware memory and compute constraints. While standard Distributed Data Parallelism (DDP) replicates the entire model across multiple accelerators, modern frontier architectures containing tens or hundreds of billions of parameters exceed the physical memory capacity of any single GPU. Even with 80 GB o

    AI
    9 min read
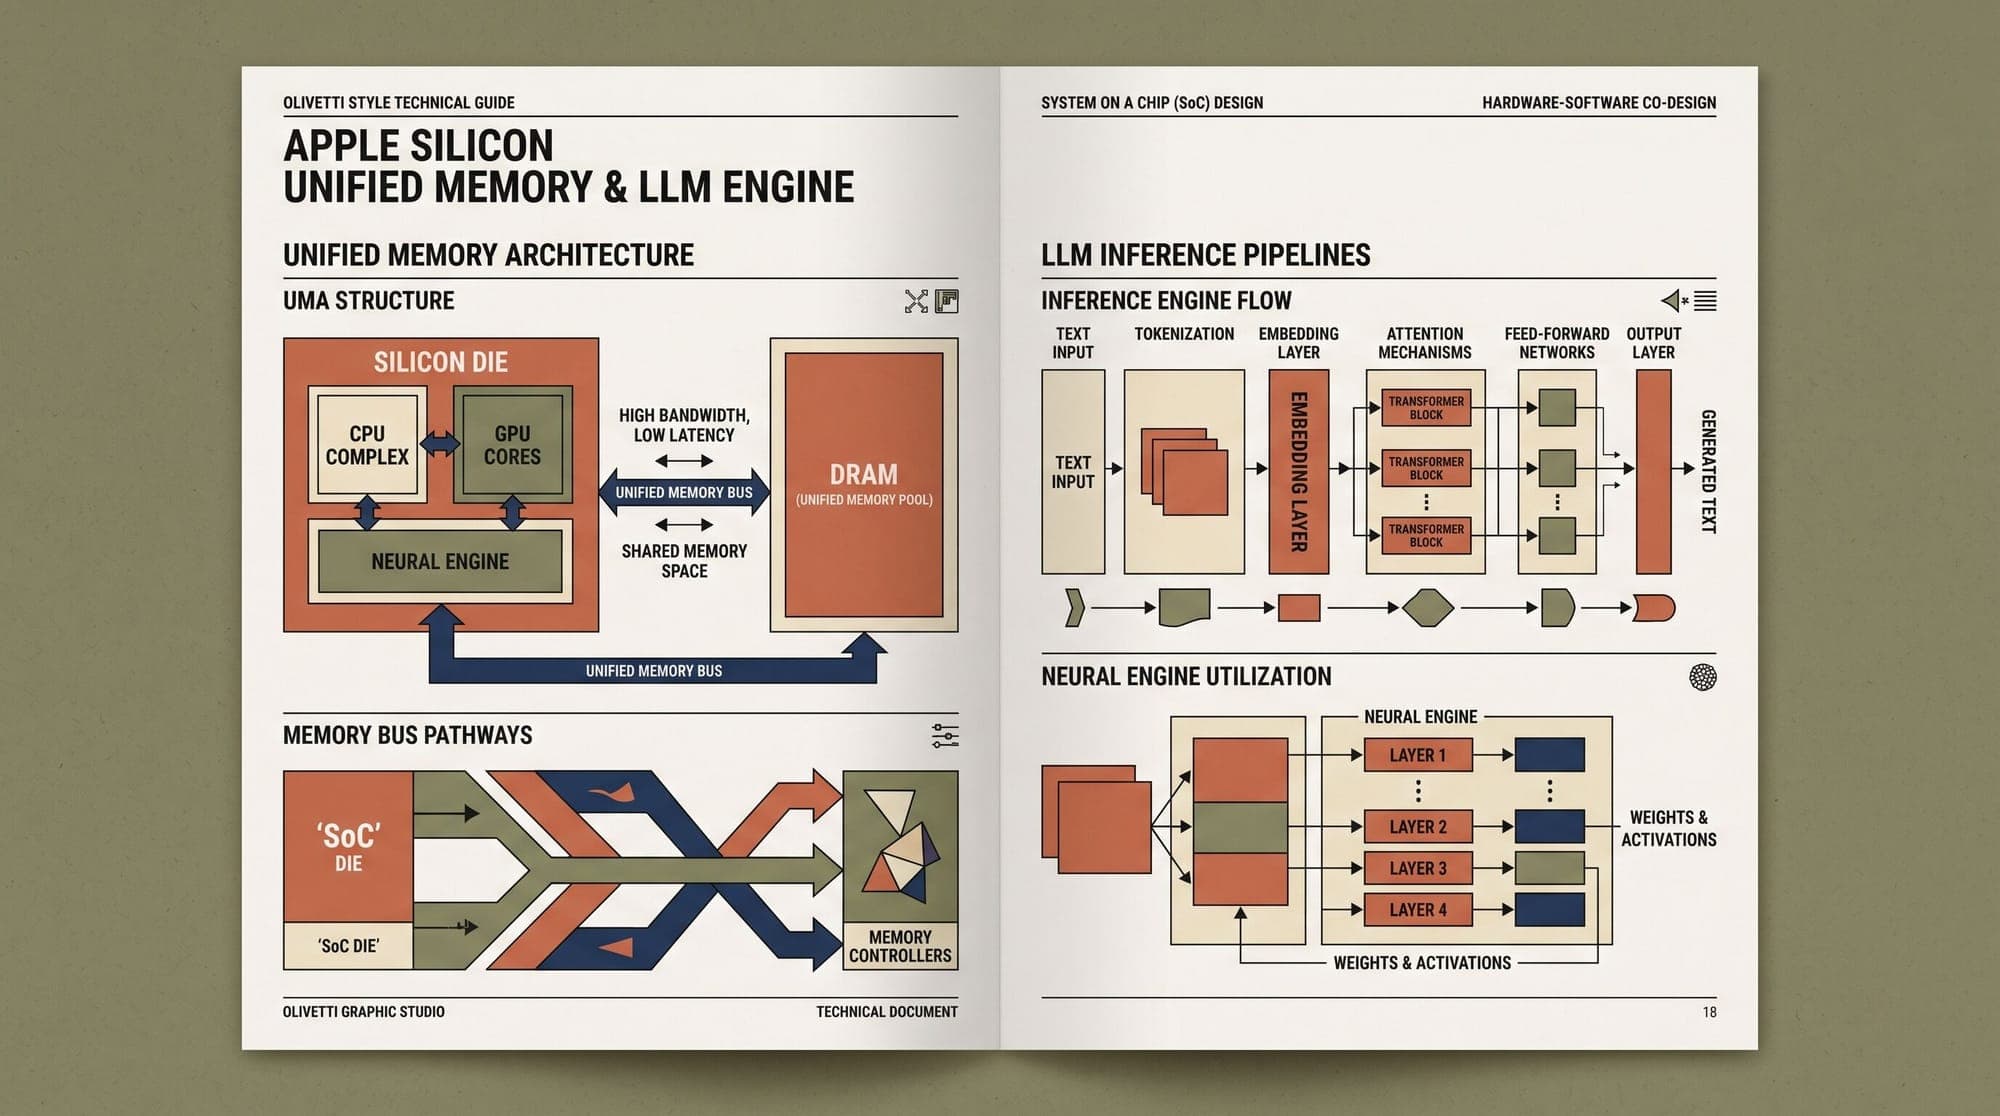
  19. Local LLM Inference on Apple Silicon: Architecture, Unified Memory, and Serving Benchmarks for MLX, llama.cpp, and Ollama

    Local large language model (LLM) serving on consumer hardware has historically faced a hard trade-off between memory capacity and execution bandwidth. Discrete consumer GPUs offer high memory bandwidth (up to 1,008 GB/s on an Nvidia RTX 4090) but are capped at 24 GB of VRAM, requiring model sharding or quantization to fit models beyond 14 billion parameters. Apple Silicon platforms bypass this capacity ceiling through a Unified Memory Architecture (UMA), where the CPU, GPU, and Apple Neural Eng

    LLM
    5 min read
  20. Mistral Expands Platform to Host Third-Party Open Weights Starting with GLM-5.2

    Mistral AI has broadened its API platform to host external open-weight foundation models, beginning with Zhipu AI's GLM-5.2. The move marks a strategic shift for the Paris-based AI company from serving only in-house architectures (such as Mistral Small, Mistral Medium, Mistral Large, and Voxtral) toward operating as a sovereign managed inference hub for third-party open weights. The integration introduces GLM-5.2 under the model identifier zai-glm-5-2 in public preview. The model is hosted with

    Mistral
    2 min read