Subscribe
Topic / page 6

Machine Learning

Articles, page 6

101-109
  1. Warmup-Stable-Decay (WSD): How Decoupled Annealing Replaced Cosine Decay in Modern LLM Pre-Training

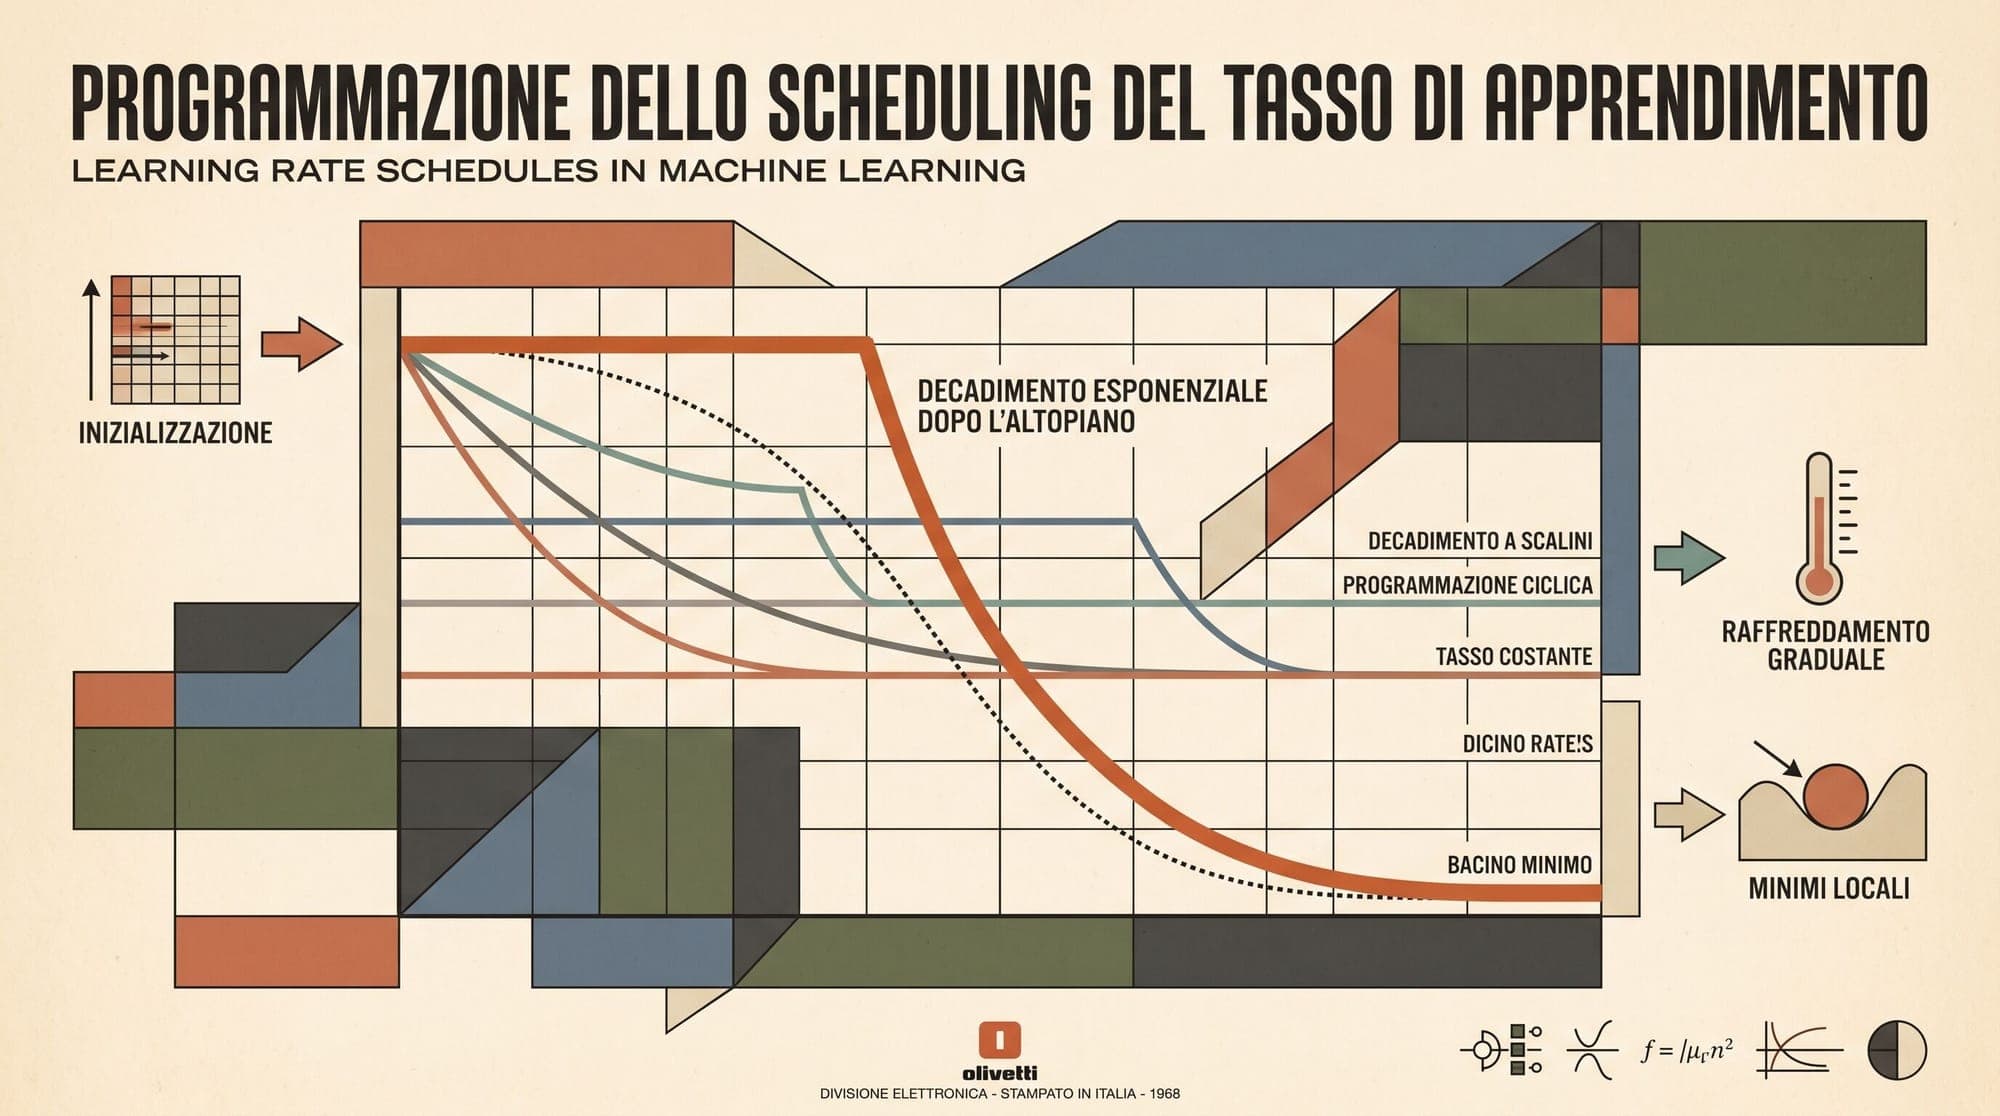
    For years, foundation model pre-training adhered to a standard optimization convention: linear learning rate warmup followed by a full-horizon cosine decay. Adopted across GPT-3, PaLM, Chinchilla, and LLaMA, cosine annealing provided stable convergence across diverse parameter scales. However, it introduced a severe structural limitation: the learning rate schedule is rigidly tied to a fixed, upfront token budget. If a team decides to extend pre-training mid-run, branch into domain-specific vari
    AI
    6 min read
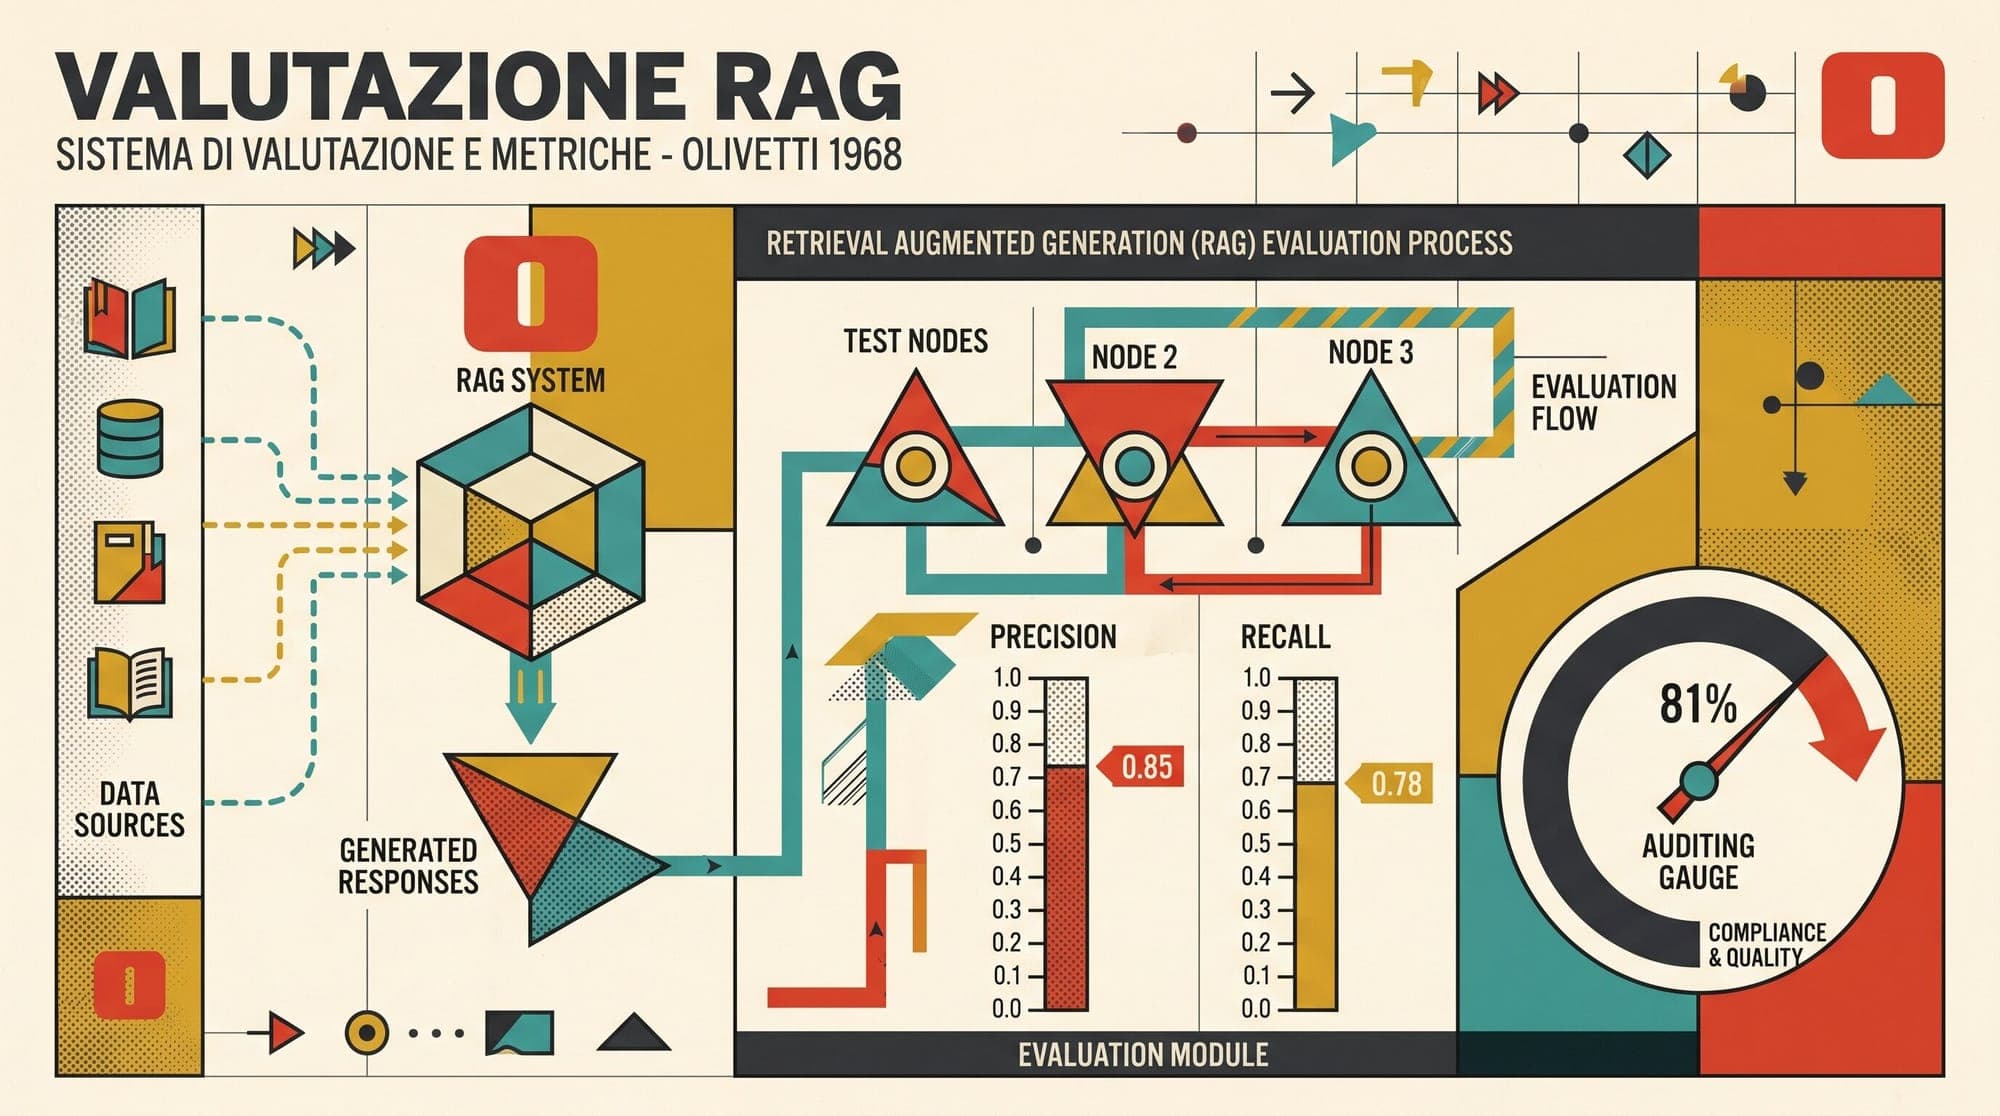
  2. RAG Evaluation Frameworks in Production: Architecture, Metrics, and CI/CD Trade-Offs for Ragas, DeepEval, TruLens, and ARES

    Production Retrieval-Augmented Generation (RAG) systems fail silently. Unlike traditional software pipelines that throw explicit exceptions on invalid states, a broken RAG pipeline produces syntactically fluent, confident prose that conceals severe underlying defects. When a user receives an incorrect response, the failure can stem from multiple distinct failure points across the stack: the query embedding failed to retrieve relevant chunks, the reranker discarded the critical passage, the chunk

    LLM
    7 min read
  3. Activation Checkpointing in Large Language Models: How Selective Recomputation Eliminates Memory Bottlenecks

    Large language model pre-training and fine-tuning are fundamentally constrained by GPU memory (VRAM). While distributed techniques such as Fully Sharded Data Parallel (FSDP), ZeRO, and Tensor Parallelism successfully shard model parameters, optimizer states, and gradients across hundreds or thousands of GPUs, activation memory presents a distinct scaling bottleneck. During the forward pass of a transformer model, intermediate tensor outputs must be preserved in GPU memory so that backpropagatio

    AI
    8 min read
  4. Process Reward Models: How Step-by-Step Supervision and Search Drive LLM Reasoning

    When large language models tackle complex multi-step reasoning (such as formal mathematics, algorithm synthesis, or multi-hop logic), evaluating only the final answer creates a severe credit assignment bottleneck. An outcome-based verifier can confirm whether a final numerical result is correct, but it cannot determine whether the underlying derivation was logically sound or reached the right answer through compounding hallucinations and lucky cancellations. Process Reward Models (PRMs) resolve

    AI
    7 min read
  5. Group Relative Policy Optimization (GRPO): How Eliminating Value Models Scaled LLM Reasoning

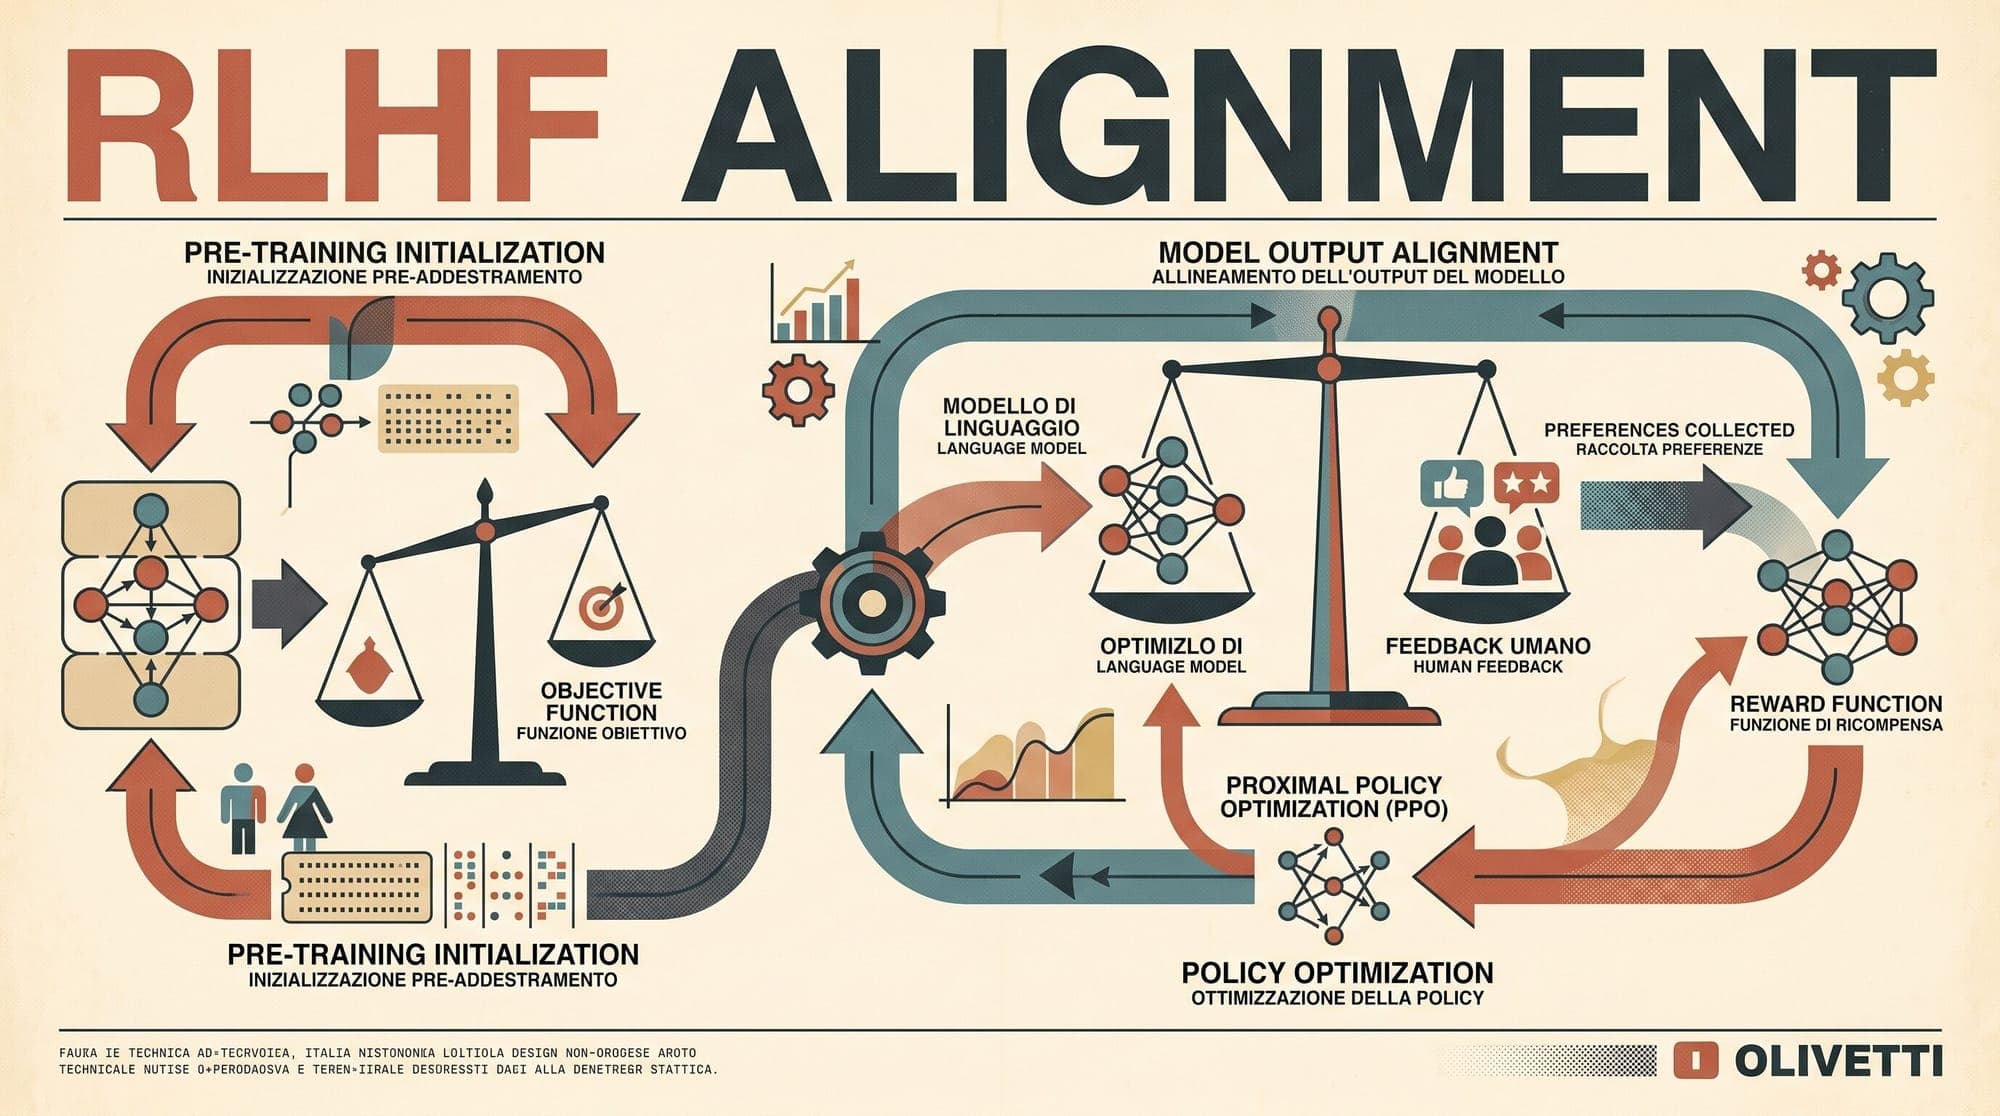
    Post-training reinforcement learning (RL) has become the primary mechanism for scaling reasoning capabilities in large language models. While early reinforcement learning from human feedback (RLHF) focused on conversational style and safety alignment, extending RL to multi-step reasoning domains such as mathematics, algorithmic coding, and formal logic exposed critical limitations in classical algorithms. Standard Proximal Policy Optimization (PPO), long the foundational algorithm for instructi

    AI
    8 min read
  6. Model Merging in Large Language Models: How Task Arithmetic, TIES, and DARE Combine Checkpoints Without Training

    Fine-tuning foundation models for specialized tasks typically produces isolated checkpoints. A model adapted for mathematical reasoning retains high numerical precision but often degrades in general dialogue or code generation. Traditionally, unifying these capabilities required multi-task training: gathering mixed datasets, re-running optimization across multiple GPUs, and managing gradient conflicts during backpropagation. Model merging provides an alternative paradigm. By operating directly

    AI
    5 min read
  7. Weight Quantization in Large Language Models: How GPTQ, AWQ, and SmoothQuant Compress Neural Networks

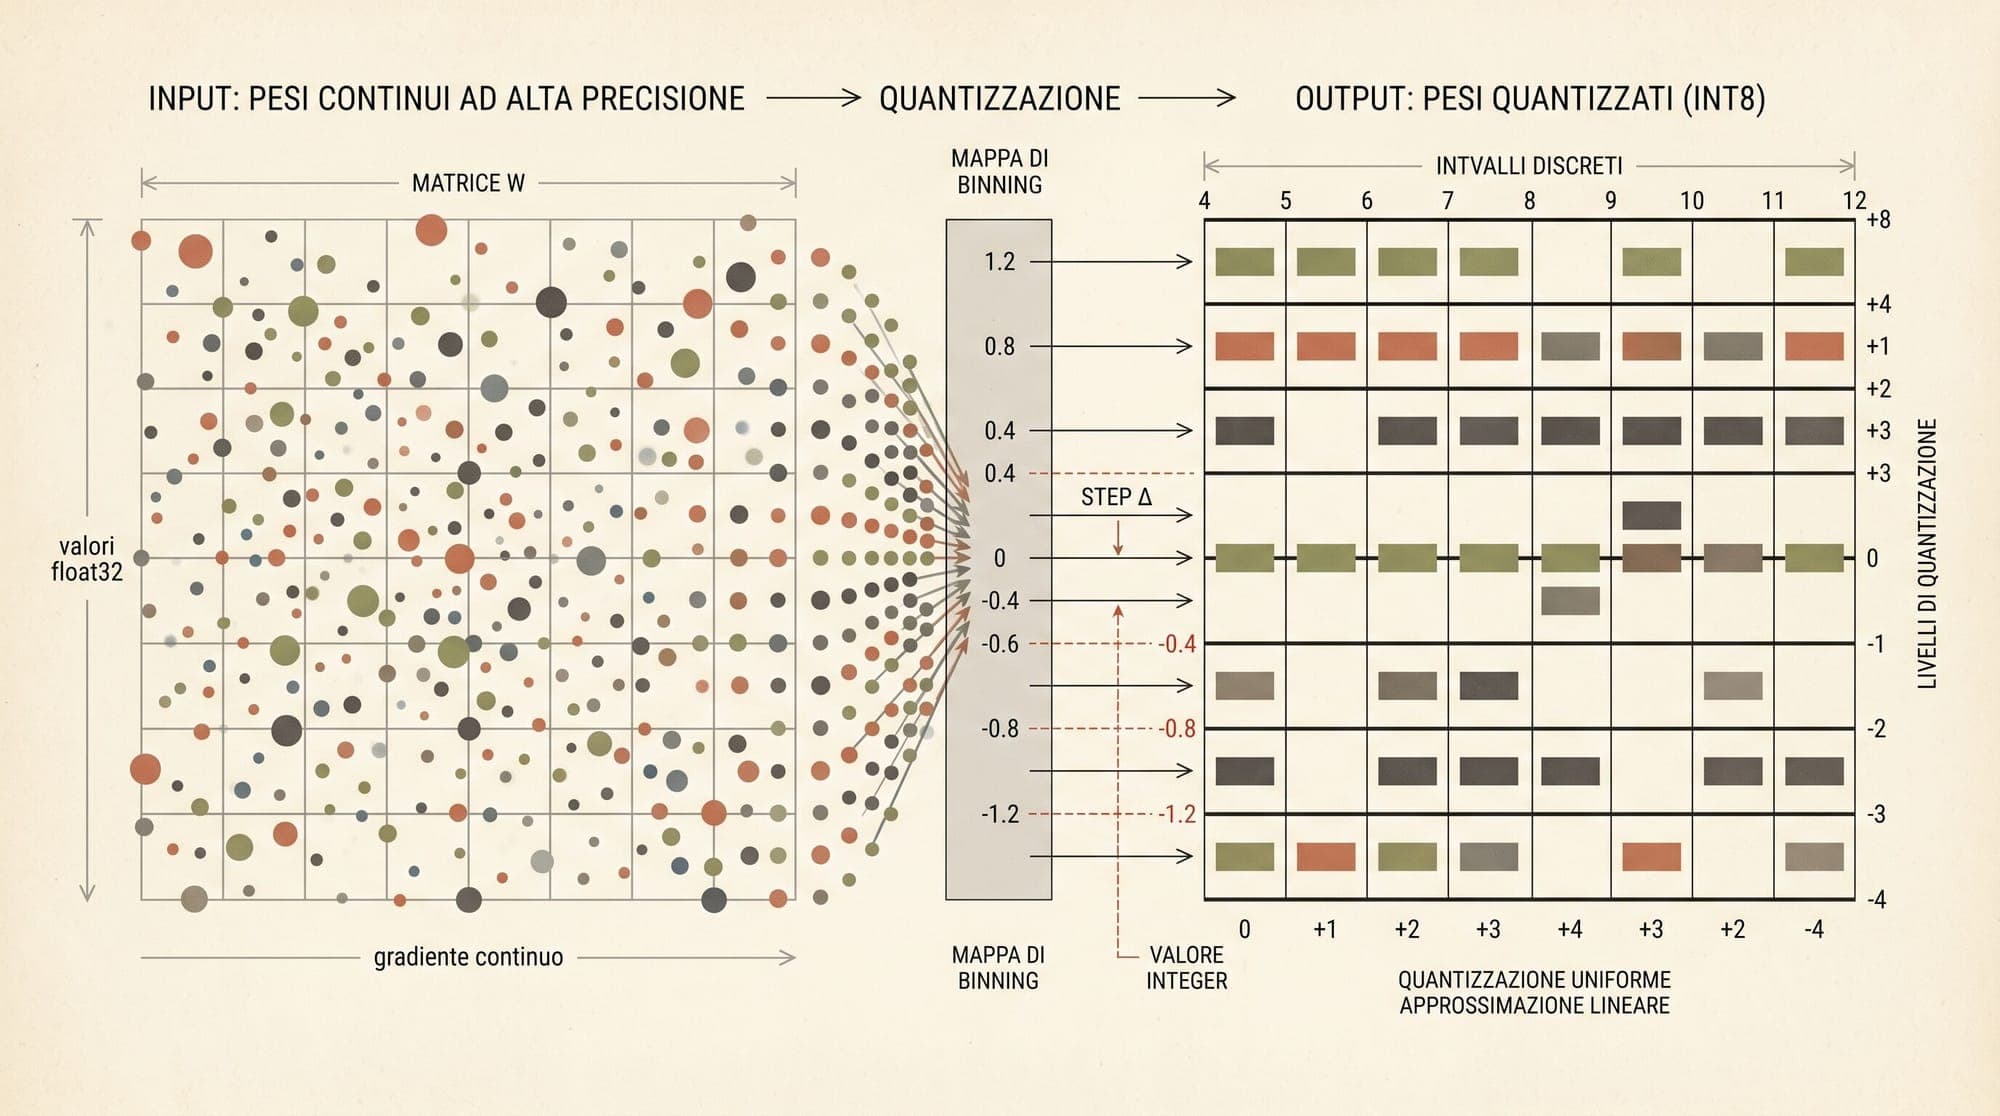
    Weight Quantization in Large Language Models: How GPTQ, AWQ, and SmoothQuant Compress Neural Networks Serving large language models in production requires balancing GPU memory footprint, memory bandwidth limits, and computational throughput. A standard 70-billion parameter transformer stored in 16-bit floating-point (FP16 or BF16) requires roughly 140 gigabytes of high-bandwidth memory (HBM) merely to hold its parameters. This memory footprint exceeds the capacity of a single 80GB GPU before ac

    AI
    9 min read
  8. Direct Preference Optimization: How Implicit Reward Modeling Simplified LLM Alignment

    Direct Preference Optimization (DPO) has emerged as a cornerstone of post-training alignment across modern open and proprietary language models, including Meta's Llama series, Mistral, and Qwen. While early alignment pipelines relied on complex reinforcement learning loops with separate reward models, DPO reformulates the preference optimization problem into a single, closed-form classification objective. By demonstrating that a language model implicitly defines its own reward function, DPO eli

    AI
    7 min read