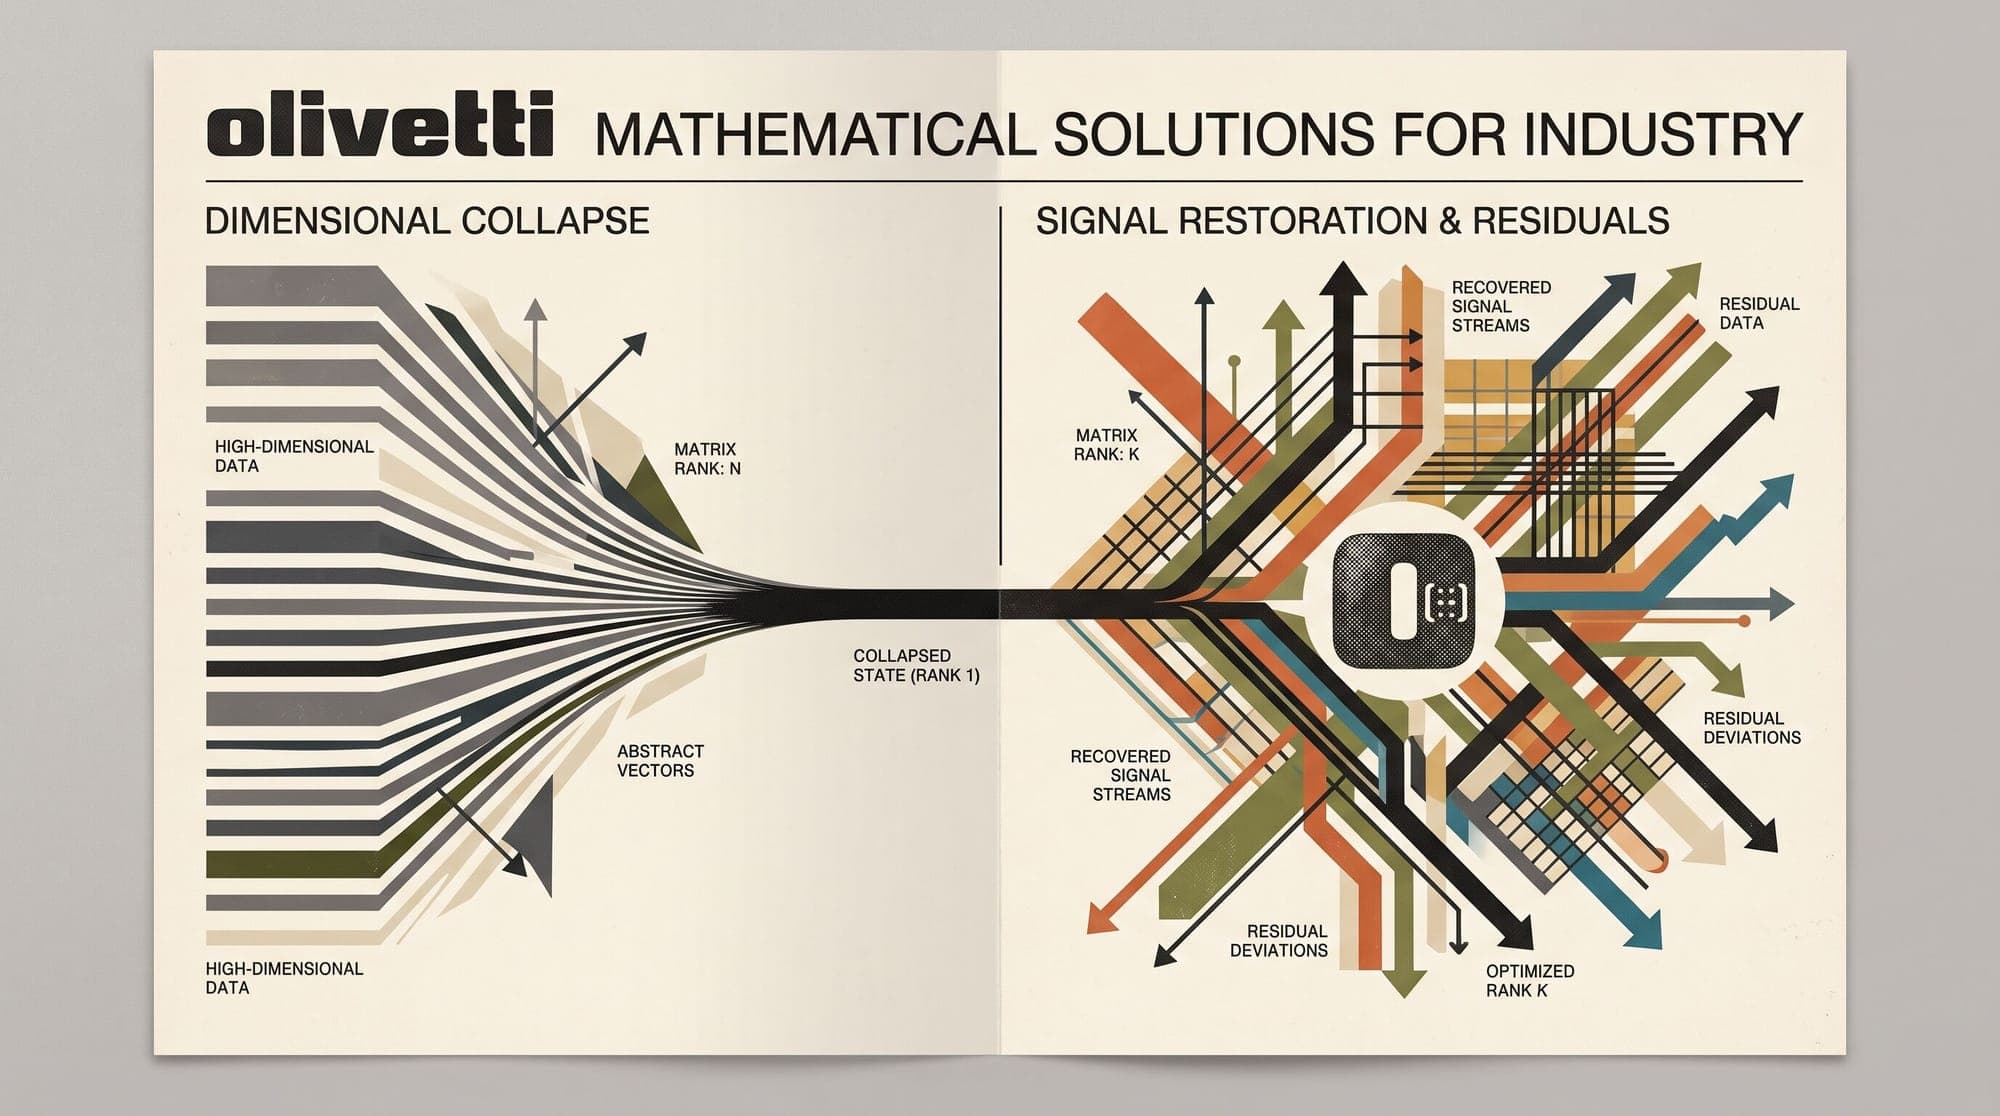
Rank Collapse in Transformer Architectures: Why Pure Attention Decays Doubly Exponentially and How Residuals Restore Expressivity
Rank Collapse in Transformer Architectures: Why Pure Attention Decays Doubly Exponentially and How Residuals Restore Expressivity The foundational premise of the Transformer architecture is that self-attention acts as a dynamic routing engine, computing pairwise affinities across sequence positions to contextualize representations. However, theoretical analysis reveals an underlying instability: stripped of its auxiliary components, a pure self-attention network rapidly destroys its own express