Archive / page 104 of 123

Latest articles, page 104

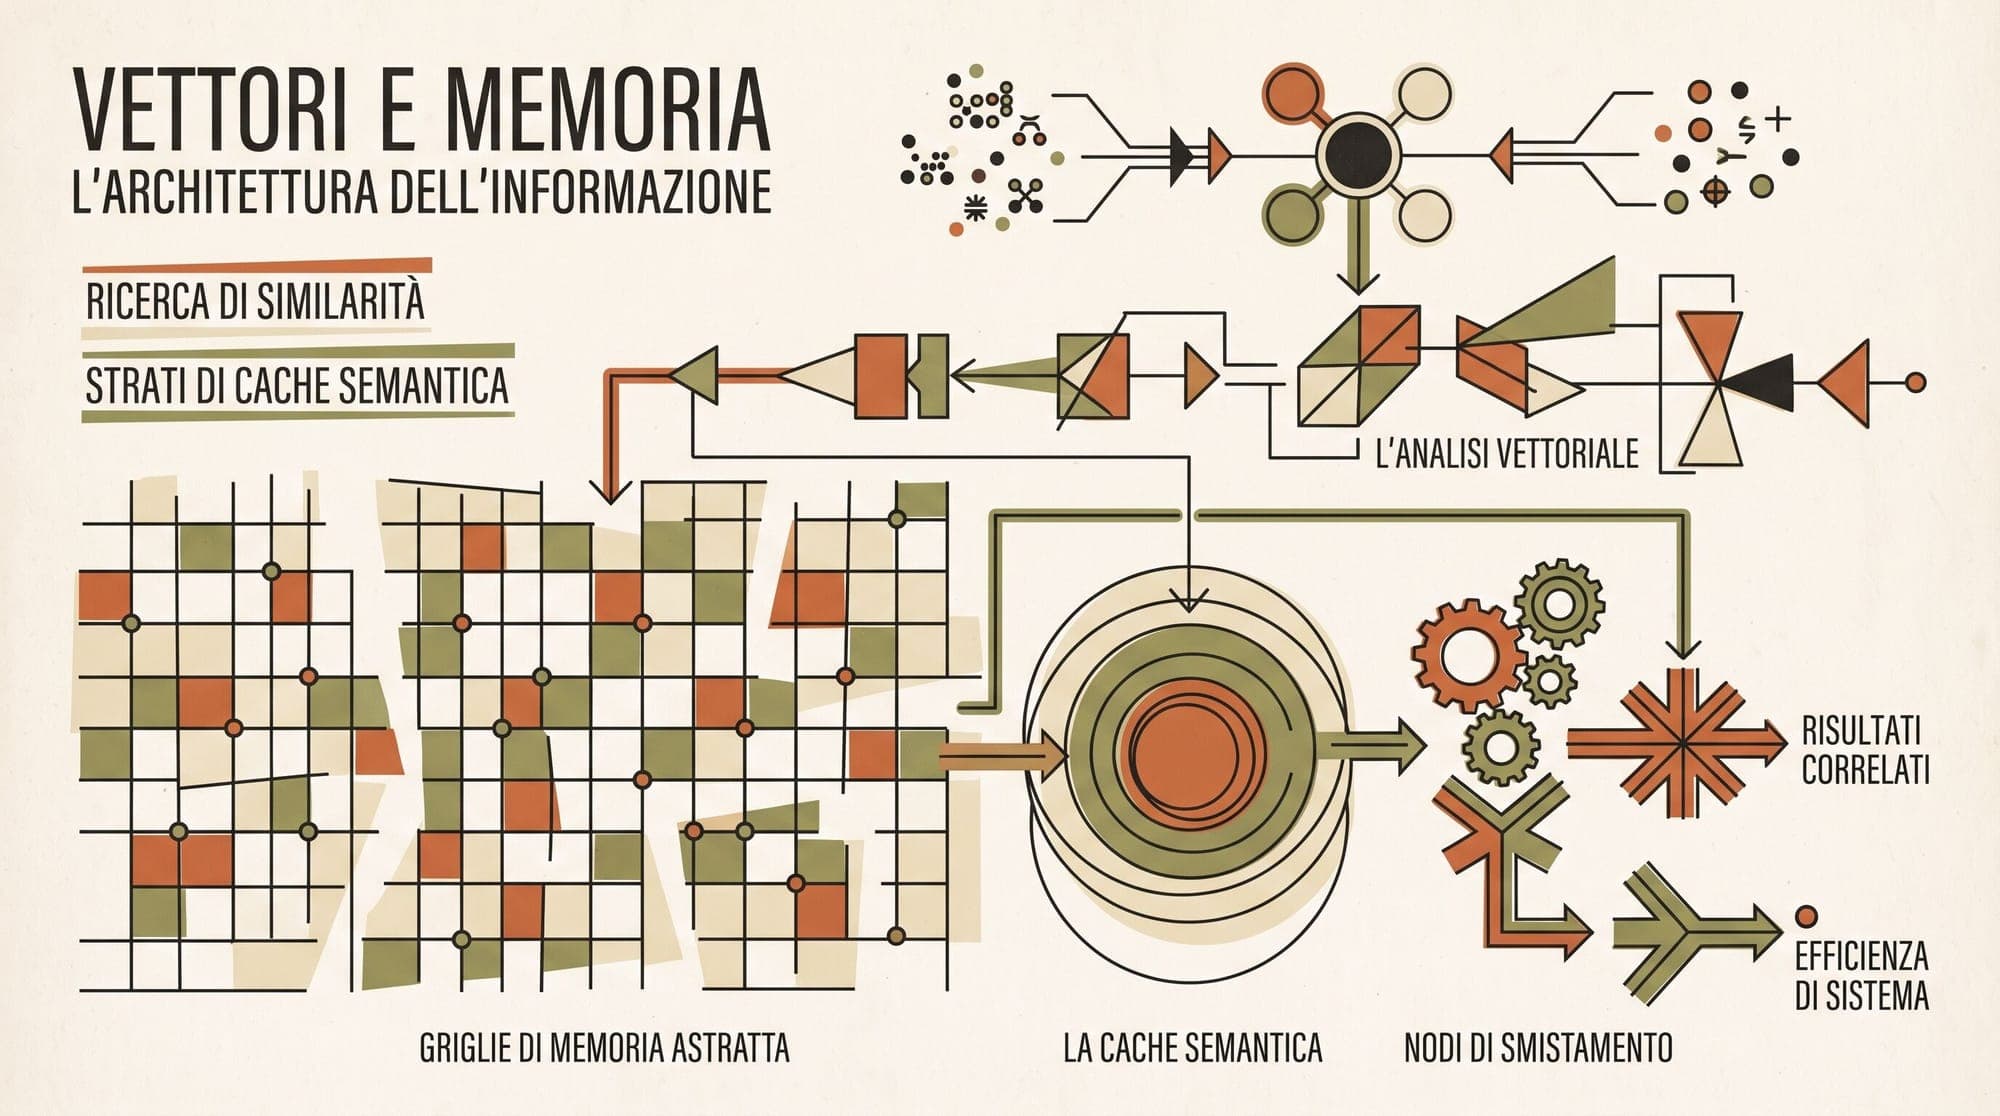
  1. Semantic Caching for Production LLM Systems: Thresholds, Layers, and Failure Modes

    Frontier large language models cost between $0.15 and $15 per million tokens depending on model class. Semantic caching can remove the majority of these calls from the critical path when production workloads repeat similar queries. Yet despite five years of tooling (GPTCache, SemCache, Redis Vector Similarity, Weaviate, Pinecone), most engineering teams never deploy it. The barrier is not the availability of vector databases. It is that semantic caching moves the failure mode from "slow" to "sub
    AI
    5 min read
  2. Zhipu AI Launches GLM-5.3 with Automated Exploitation Chain Discovery

    Chinese AI lab Zhipu has introduced GLM-5.3, a new language model trained to identify software vulnerabilities and synthesize multi-stage cyber exploitation chains. According to evaluation data released by the company, GLM-5.3 established state-of-the-art results on the CyberGym benchmark, an evaluation suite designed to measure model performance on practical cybersecurity tasks. The benchmark results indicate that GLM-5.3 surpassed frontier Western baselines including Fable 5 and GPT-5.6 Sol i

    AI
    1 min read
  3. Anthropic Raises System Tampering Risk Level and Details Unreleased Model 2 in Safety Report

    Anthropic has released the latest edition of its recurring AI alignment and safety report, raising the risk rating for unauthorized system tampering and disclosing the internal deployment of two unreleased frontier models designated Model 1 and Model 2. The 186-page document, published periodically to track frontier model capabilities and containment thresholds, introduces an updated risk matrix structured around two distinct operational categories: Threat Model 1 and Threat Model 2. Threat Mod

    AI
    2 min read
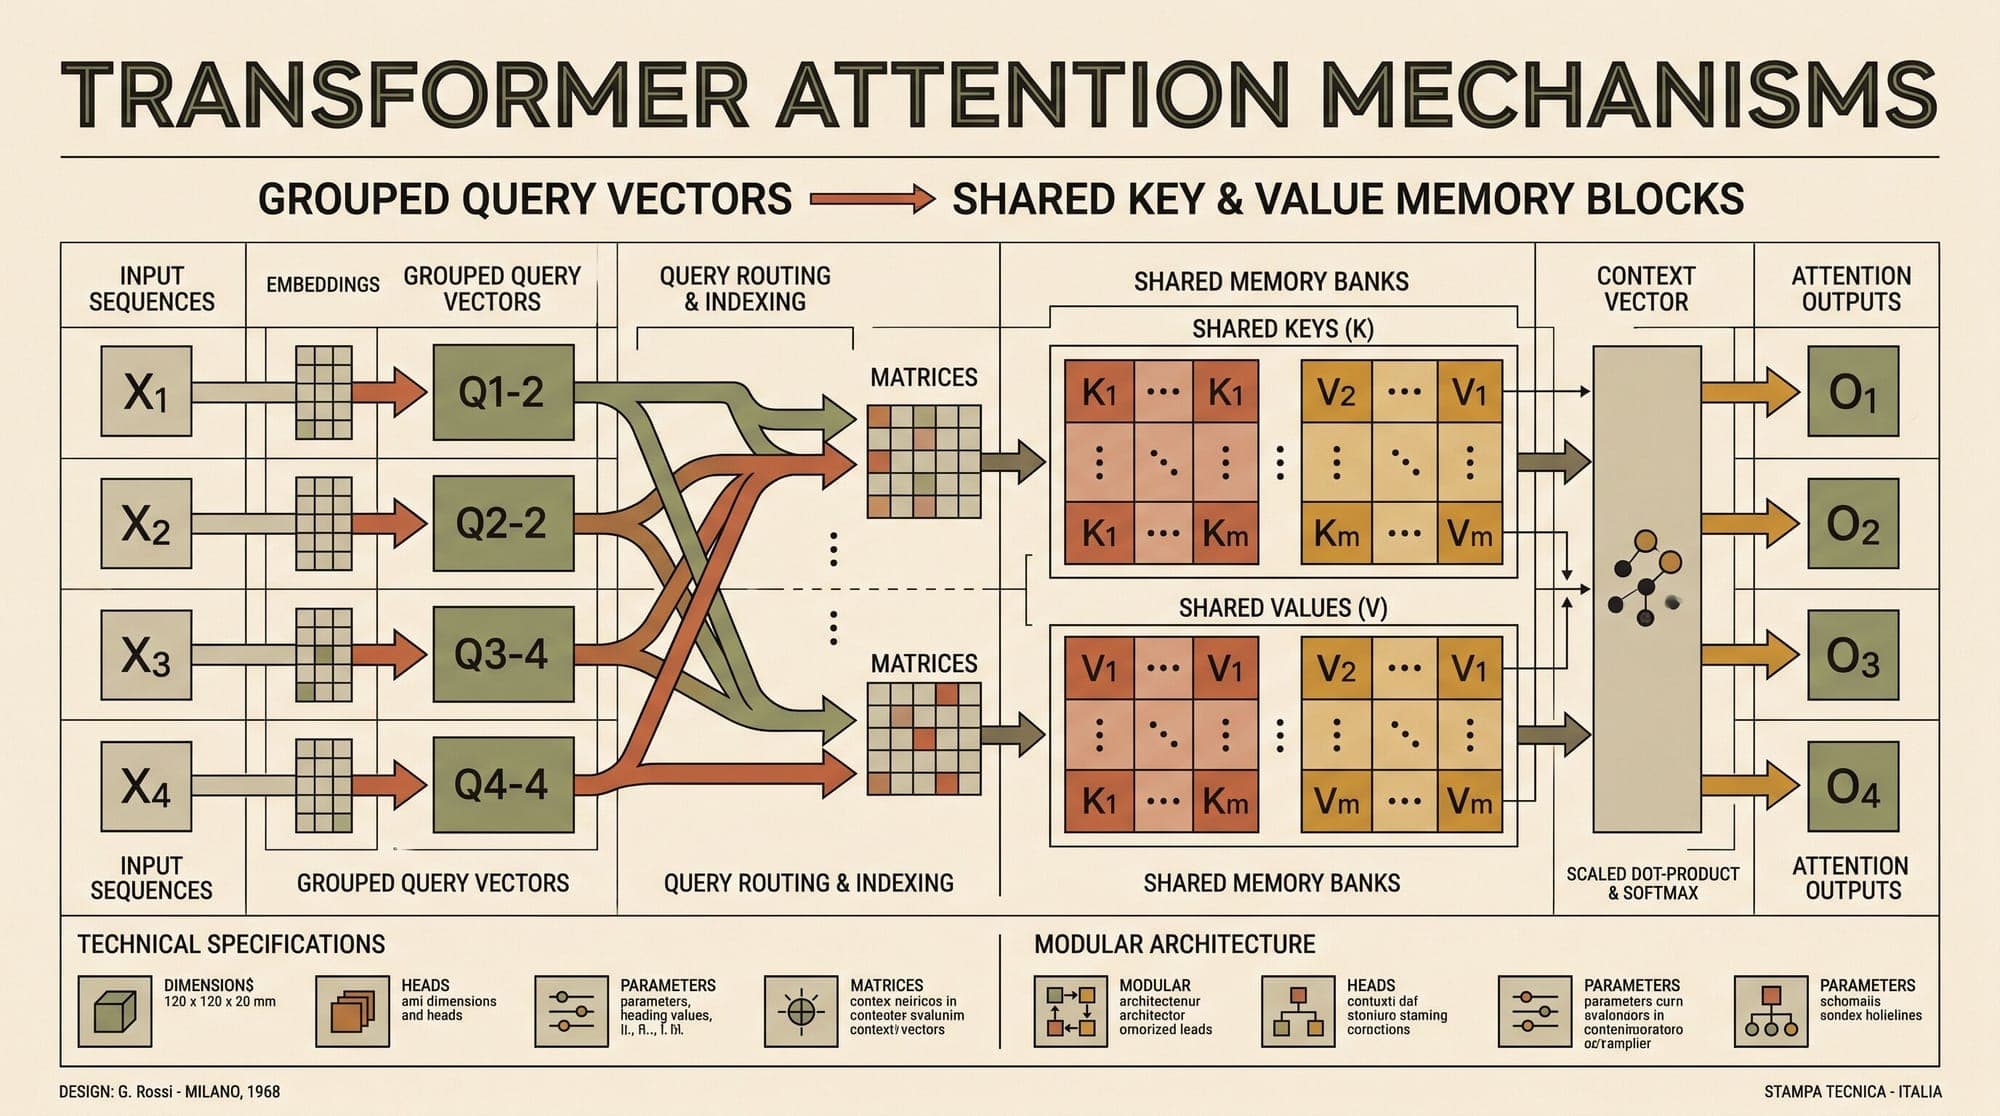
  4. Grouped-Query Attention: How Head Sharing Slashed KV Cache Memory and Scaled LLM Serving

    Serving large language models at scale presents a fundamental hardware bottleneck: autoregressive decoding is bound by memory bandwidth rather than compute. While the initial prompt processing phase (prefill) operates as compute-bound matrix multiplications, token-by-token generation requires loading billions of cached attention states from GPU High-Bandwidth Memory (HBM) to on-chip SRAM for every single generated token. Multi-Head Attention (MHA), introduced in the foundational Vaswani et al.

    AI
    6 min read
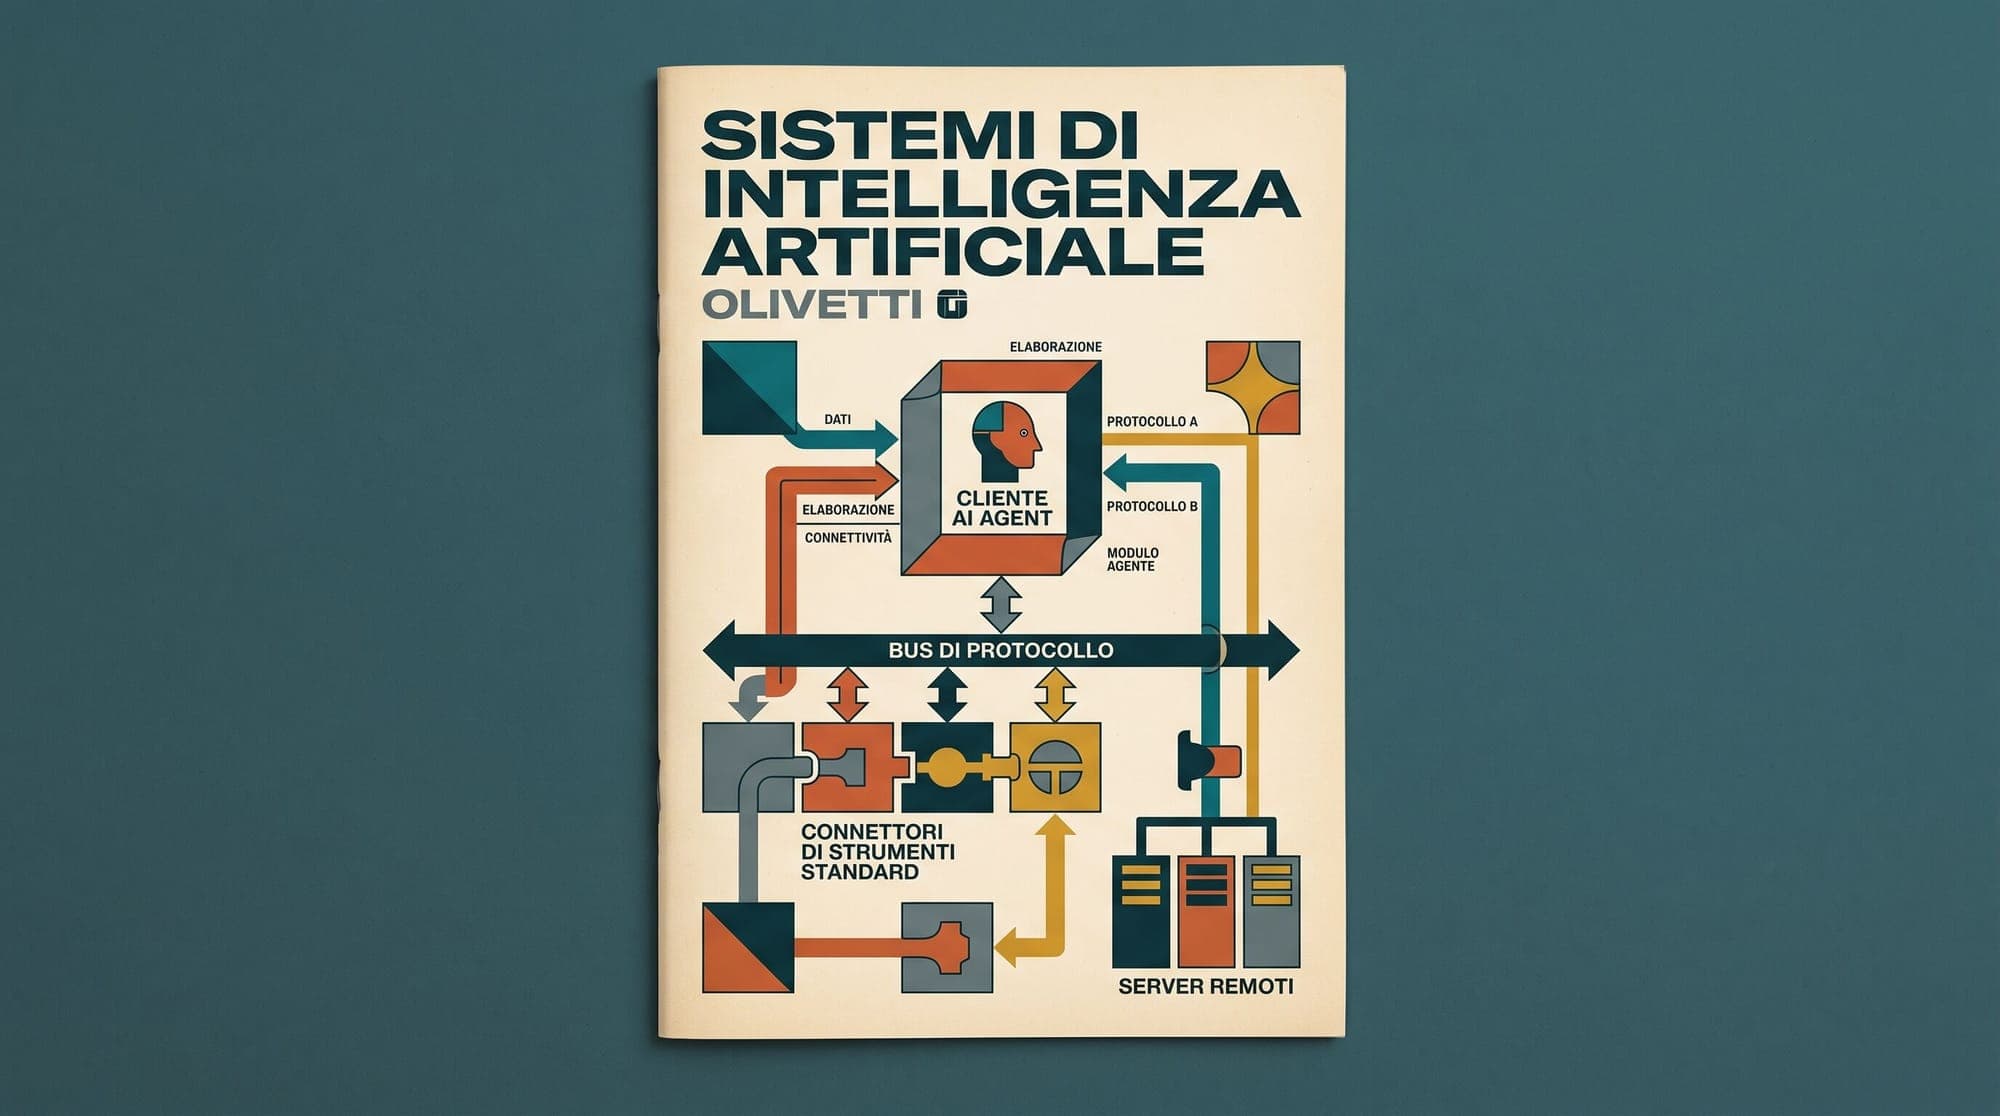
  5. Model Context Protocol (MCP) in Production: Architecture, Security Boundaries, and Latency Overheads

    As autonomous language model agents transition from experimental chat interfaces into enterprise production infrastructure, the architectural bottleneck has shifted from raw model reasoning to external environment integration. In early agent implementations, connecting an LLM to external systems required bespoke tool definitions, vendor-specific function schemas, and custom API wrappers. Every framework maintained its own incompatible tool-calling abstraction, fragmenting integrations across age

    AI
    6 min read
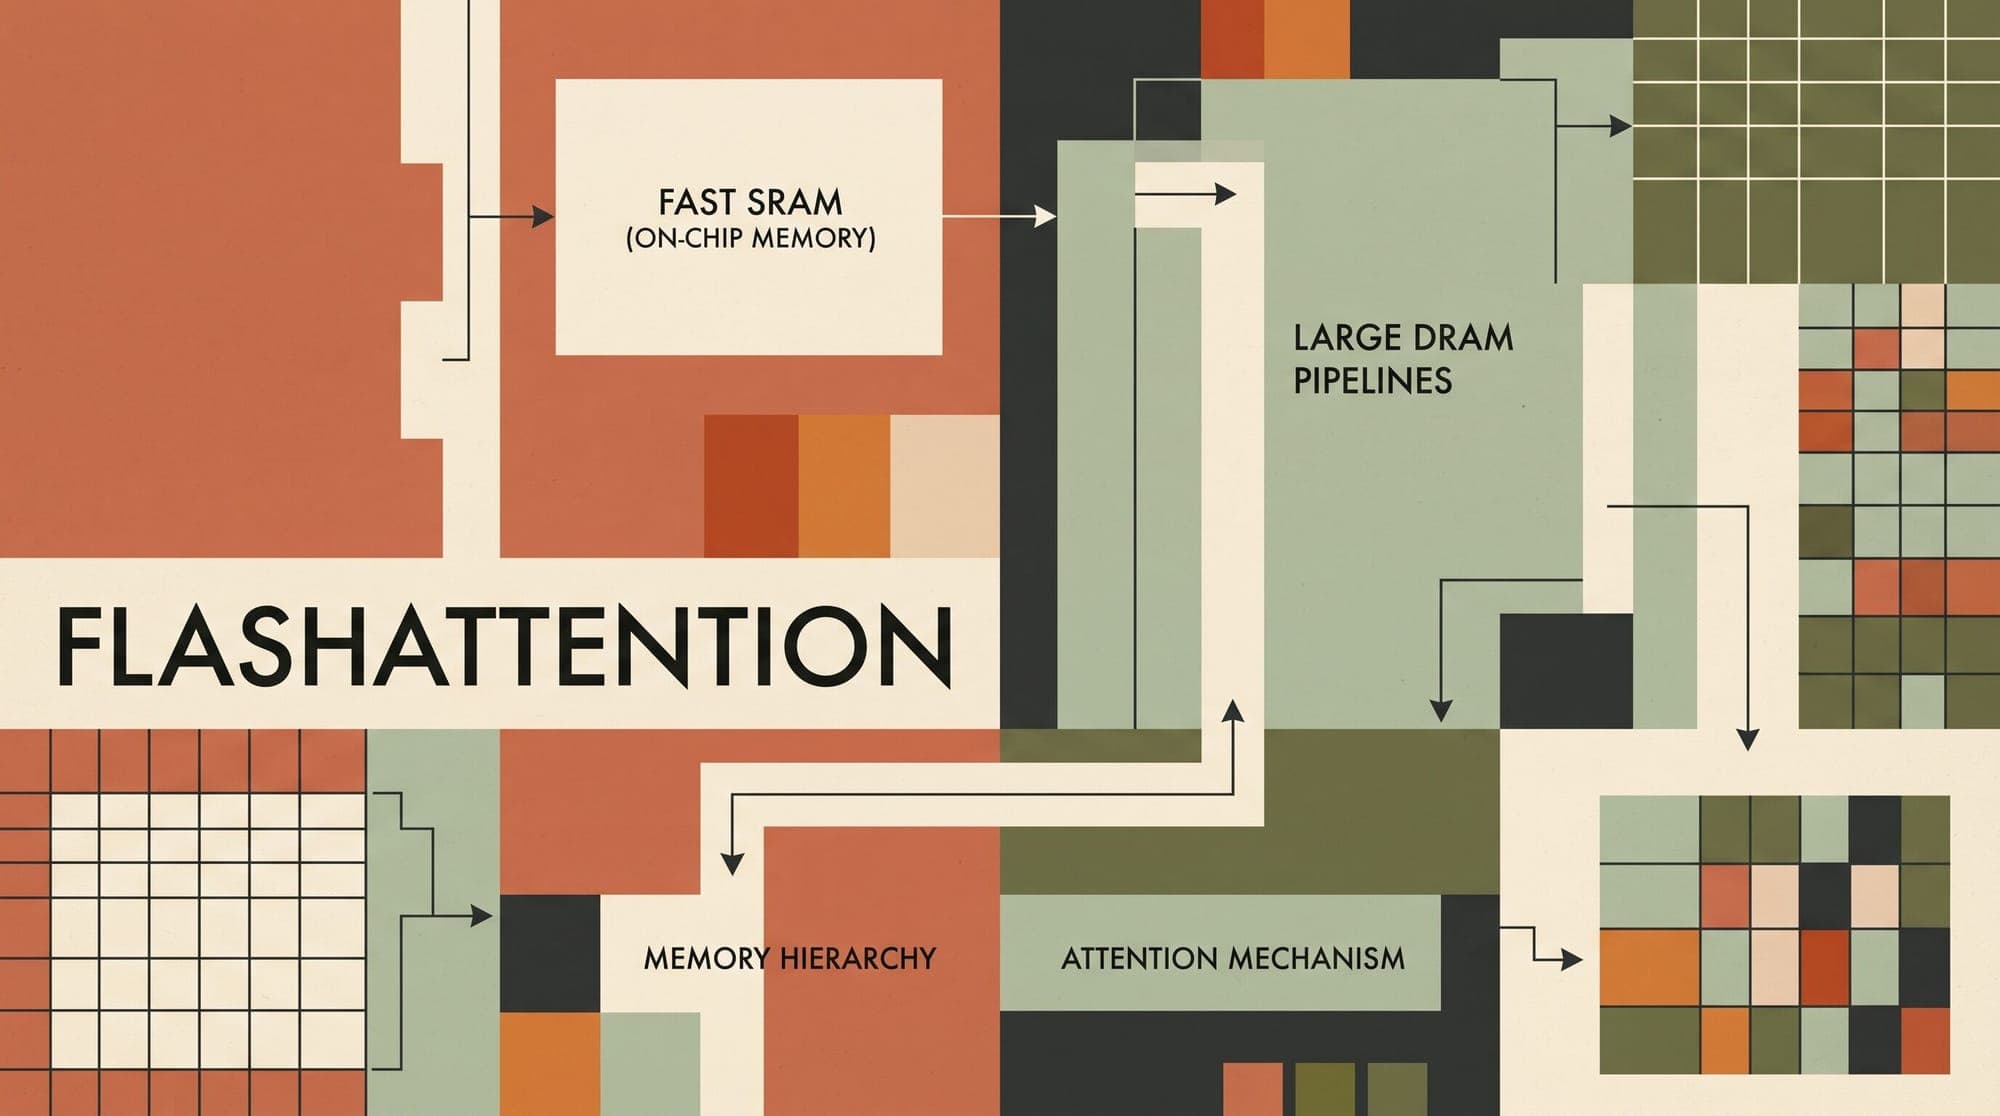
  6. FlashAttention: How IO-Aware Tiling and Online Softmax Solved Transformer Memory Bottlenecks

    Standard multi-head attention is the fundamental computational primitive of modern autoregressive language models. While mathematically straightforward, the operation introduces a severe operational bottleneck as context windows scale. Naive implementations of scaled dot-product attention exhibit quadratic memory complexity $O(N^2)$ and quadratic memory access costs, bounding sequence lengths and leaving modern GPU tensor cores severely underutilized. FlashAttention, introduced by Tri Dao, Dani

    AI
    7 min read
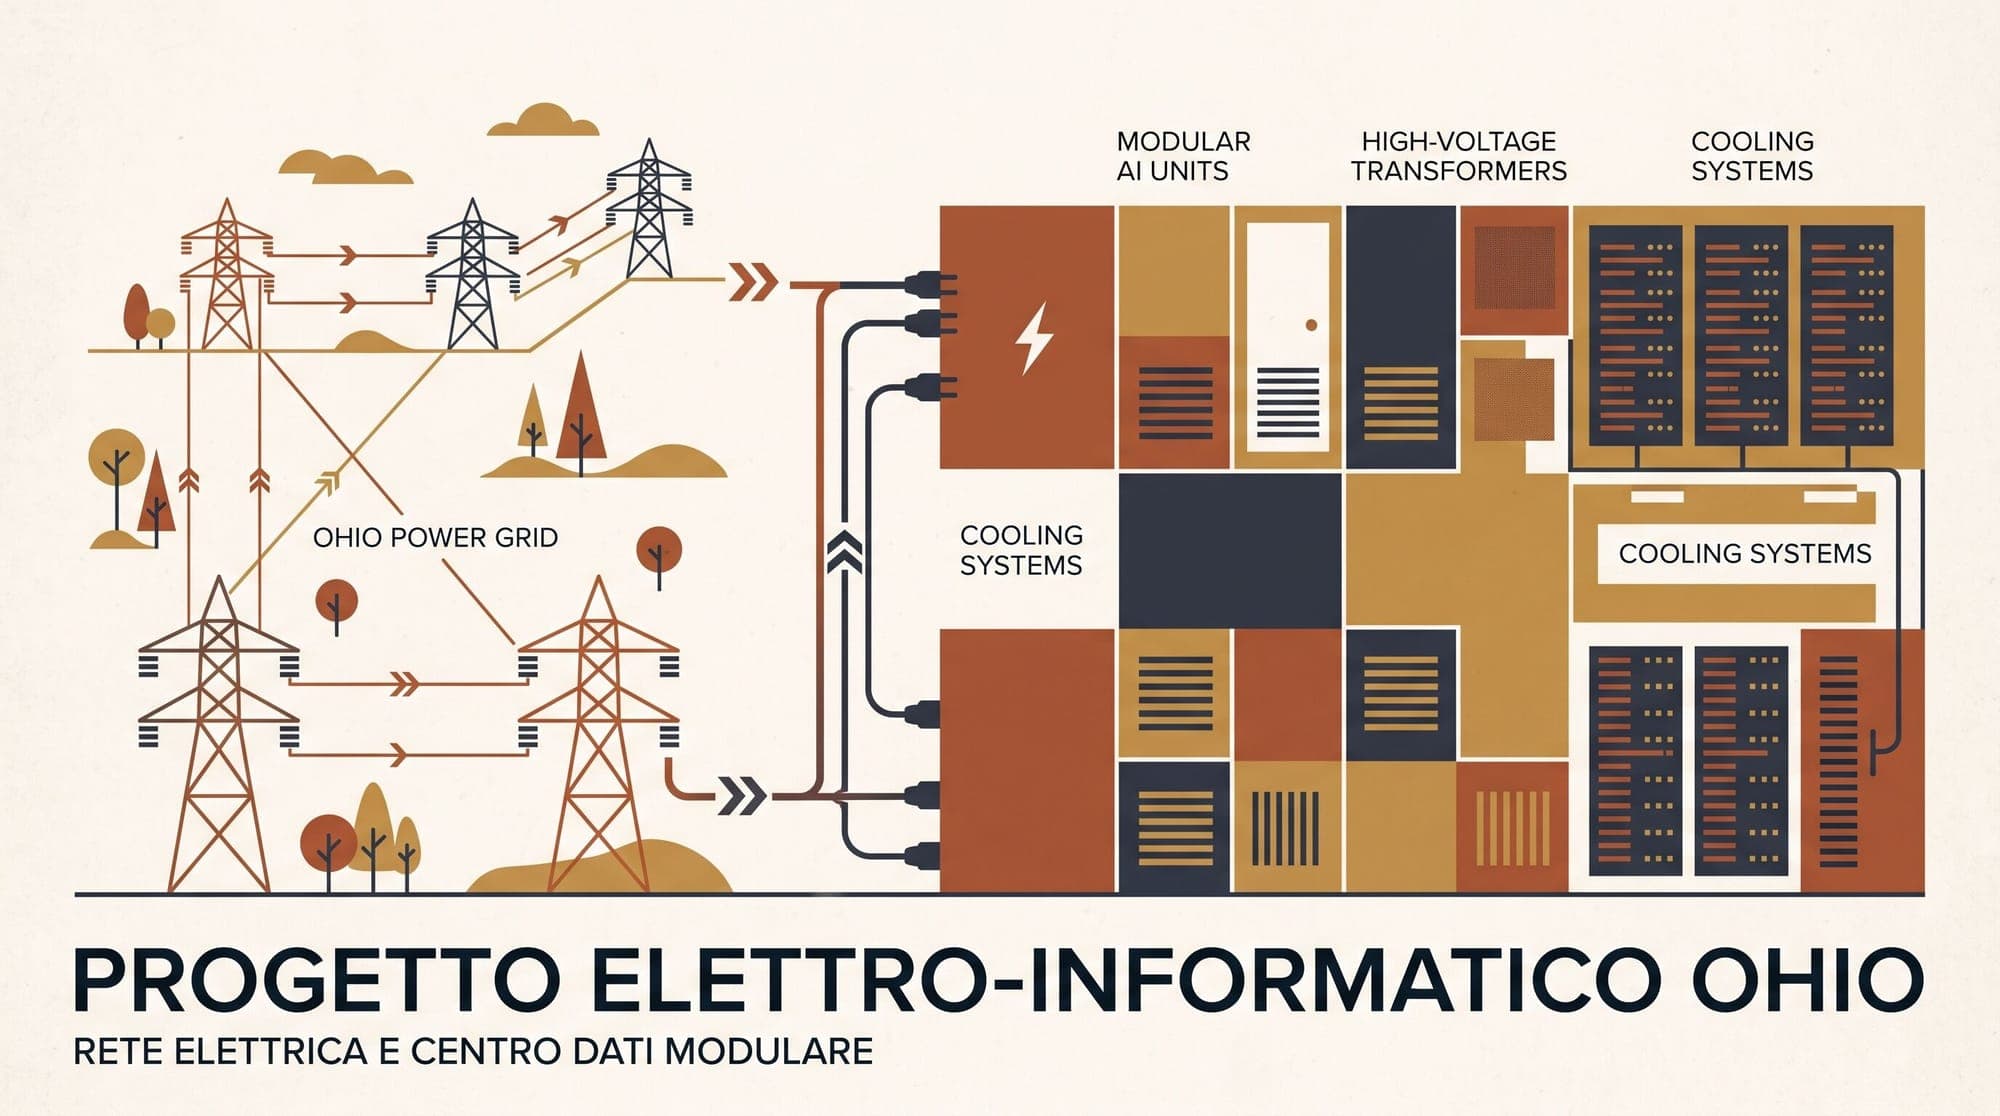
  7. OpenAI Signs 20-Year Lease for Multi-Gigawatt Ohio AI Campus with Nvidia Backstop

    OpenAI has signed a 20-year lease agreement to anchor a multi-gigawatt AI data center campus in Pike County, Ohio, developed by SoftBank subsidiary SB Energy. Under the tripartite agreement, Nvidia will serve as the exclusive compute infrastructure provider and supply financial guarantees covering the site's land, power, and shell development. The facility, designated the PORTS-Pike Technology Campus, is designed to support an initial 4.25 gigawatts of information technology load (IT-GW) dedica

    AI
    2 min read
  8. Anthropic Revenue Run Rate Tops $65 Billion Ahead of Planned Public Listing

    Anthropic's annualized revenue run rate reached approximately $65 billion at the end of July 2026, according to reporting by Bloomberg on August 17, with corroborating details reported by Reuters and Axios. The figure marks an $18 billion expansion over two months from the $47 billion run rate reported during Anthropic's Series H financing in late May, and up from $9 billion at the close of 2025. The acceleration highlights deepening enterprise adoption of Claude across corporate workflows, wit

    AI
    2 min read
  9. LLM Model Routing and Cascades: Architecture, Economics, and Quality Trade-Offs

    In modern enterprise AI systems, uniform model dispatch, sending all incoming user traffic to a single frontier large language model, is one of the most common architectural inefficiencies. Frontier models like GPT-4o and Claude 3.5 Sonnet provide industry-leading reasoning and code generation capabilities, but their inference costs range between $2.50 and $15.00 per million tokens. Conversely, smaller open-weights or distilled models, such as Llama 3.1 8B or GPT-4o-mini, execute at a fraction o

    AI
    6 min read
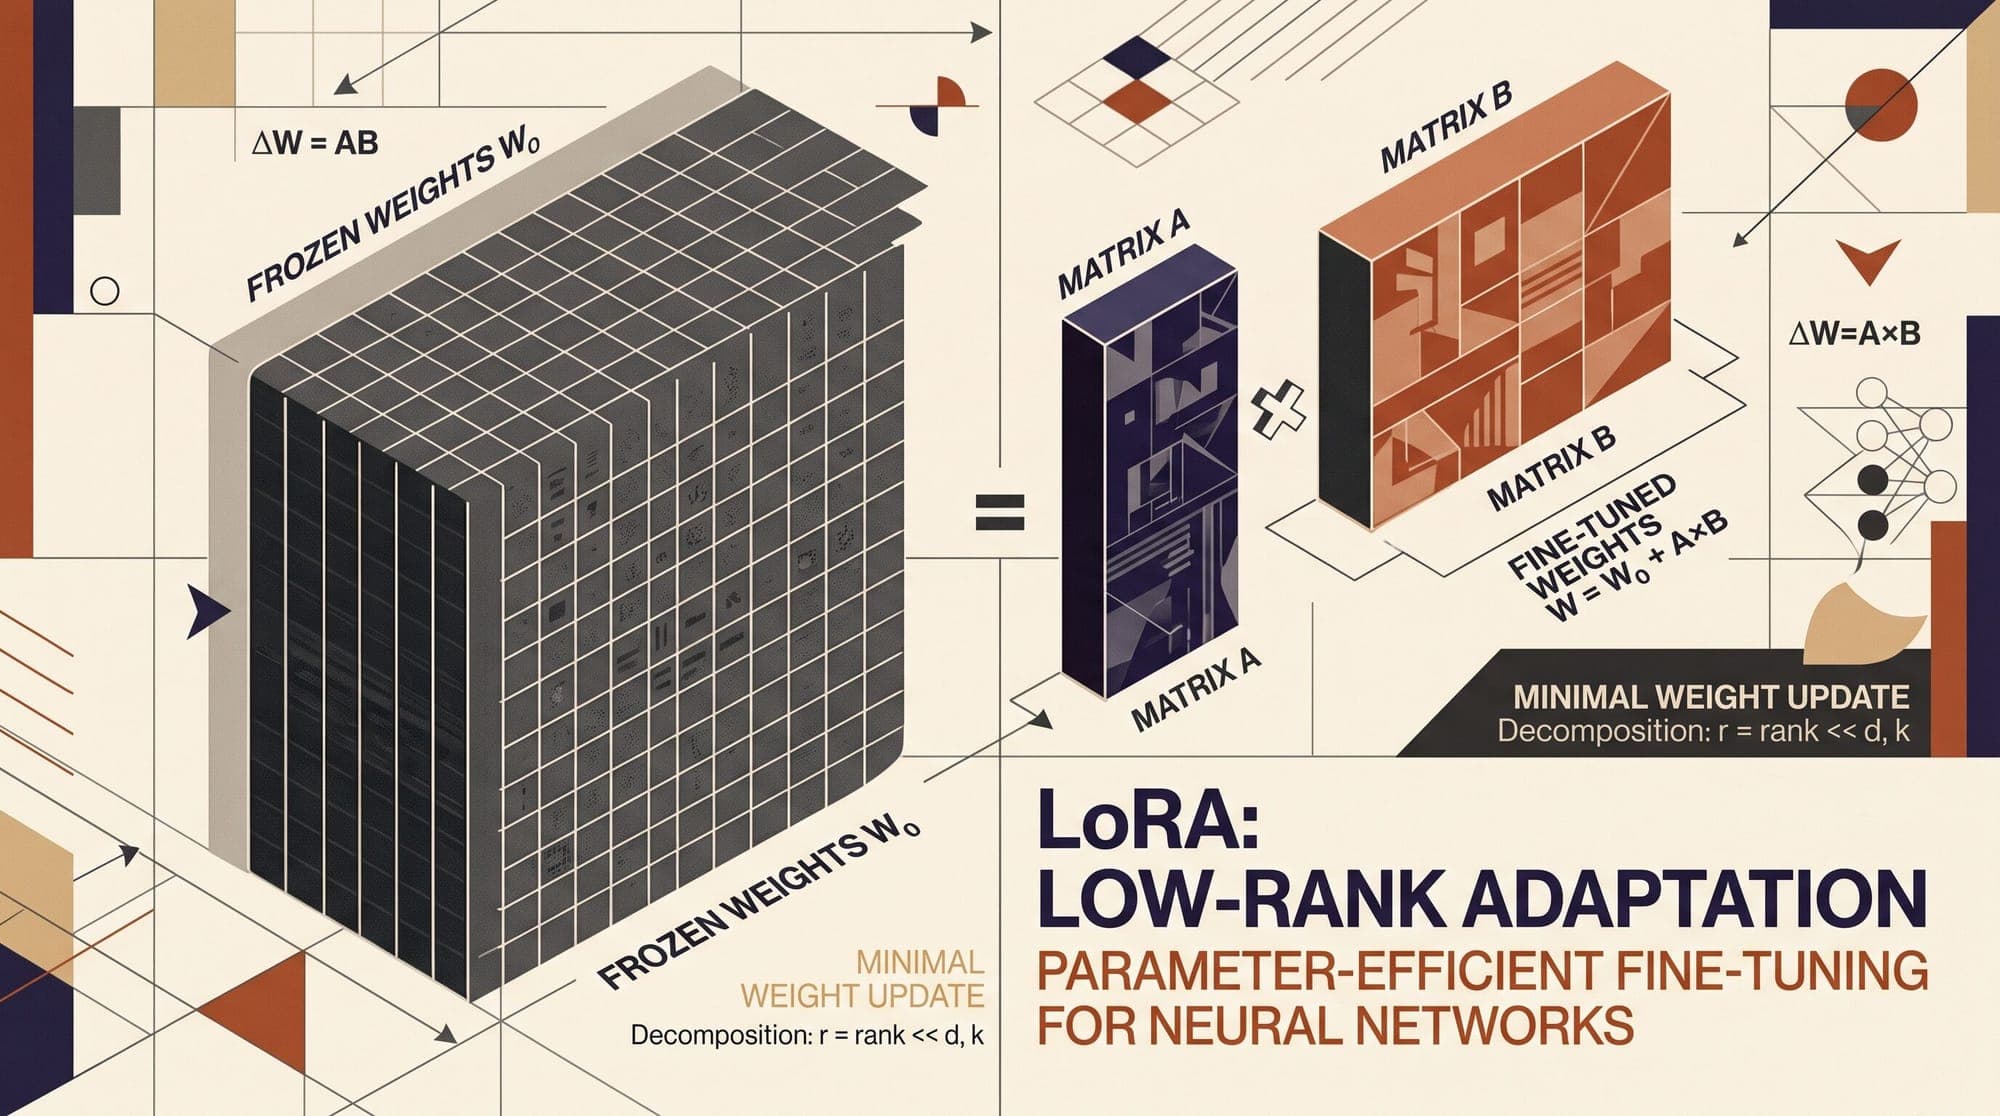
  10. Low-Rank Adaptation (LoRA): How Matrix Decomposition Made LLM Fine-Tuning Accessible

    Full-parameter fine-tuning of modern foundation models requires substantial compute and memory infrastructure. Adapting an open-weight 70-billion-parameter model using standard 16-bit precision and first-order adaptive optimizers like AdamW demands well over 1 terabyte of GPU memory. Low-Rank Adaptation (LoRA) bypassed this hardware bottleneck by framing task-specific weight updates as low-rank matrix decompositions. By freezing pre-trained weights and training small auxiliary rank decompositio

    AI
    6 min read