Archive / page 103 of 123

Latest articles, page 103

  1. Vector Embeddings in Large Language Models: How Contrastive Learning, Bi-Encoders, and Matryoshka Projections Map Semantic Space

    Vector Embeddings in Large Language Models: How Contrastive Learning, Bi-Encoders, and Matryoshka Projections Map Semantic Space Large language models process text as discrete tokens: integers mapped to lookup tables. While causal transformers excel at autoregressive generation by predicting the next token, generation alone does not solve the challenge of semantic search, clustering, or dense retrieval. Searching through millions of documents requires comparing sequence-level meaning in constan
    AI
    8 min read
  2. Continuous Batching in Production LLM Serving: Iteration-Level Scheduling, Chunked Prefills, and Throughput Trade-Offs

    Static batching served as the standard execution paradigm for deep learning inference across computer vision and traditional natural language processing for years. In those domains, incoming requests typically feature fixed input dimensions and deterministic execution graphs. Autoregressive large language model serving breaks every assumption underlying static batching. Input prompts vary widely in token length, output generations terminate nondeterministically upon emitting an end-of-sequence t

    LLM
    6 min read
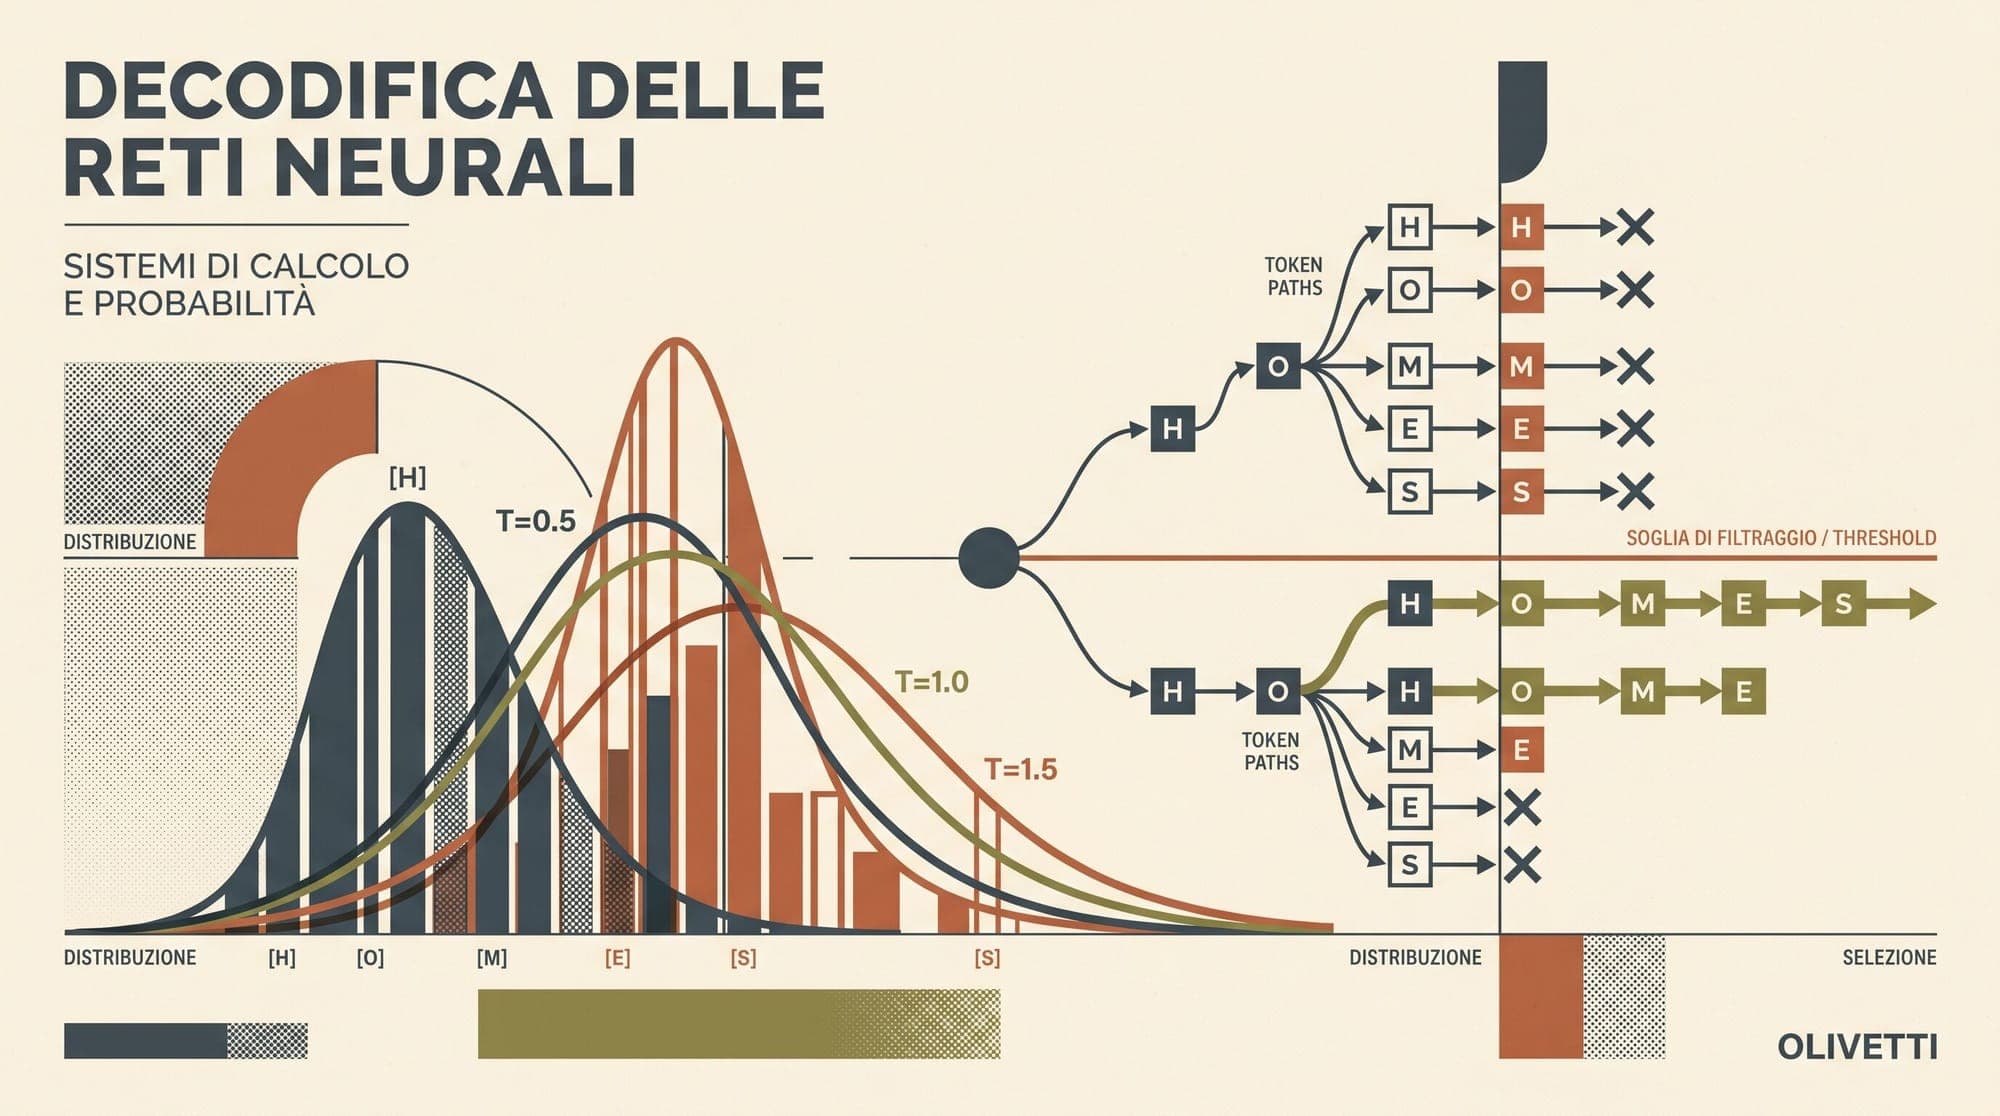
  3. Token Sampling in Large Language Models: How Temperature, Top-k, Top-p, and Min-p Govern Generative Decoding

    Large language models are autoregressive next-token predictors. During inference, the neural network processes an input context and outputs a vector of unnormalized scores, known as logits, across every token in its vocabulary. The mathematical pipeline that converts those raw logits into a single chosen token is the sampling and decoding stage. While model architecture and pre-training weights determine what a model knows, sampling algorithms govern how that knowledge is extracted. Small chang

    AI
    7 min read
  4. AI-Drafted Bills Inundate House Legislative Counsel, Creating Bottlenecks and Statutory Flaws

    Congressional attorneys at the U.S. House Office of the Legislative Counsel (OLC) are confronting an influx of AI-generated legislative proposals, leading to review backlogs and technical errors in submitted statutory text. According to a Politico investigation citing interviews with eight current and former officials, congressional offices and external advocacy groups are increasingly turning to large language models like ChatGPT and Claude to draft proposed statutory language. However, the re

    AI
    2 min read
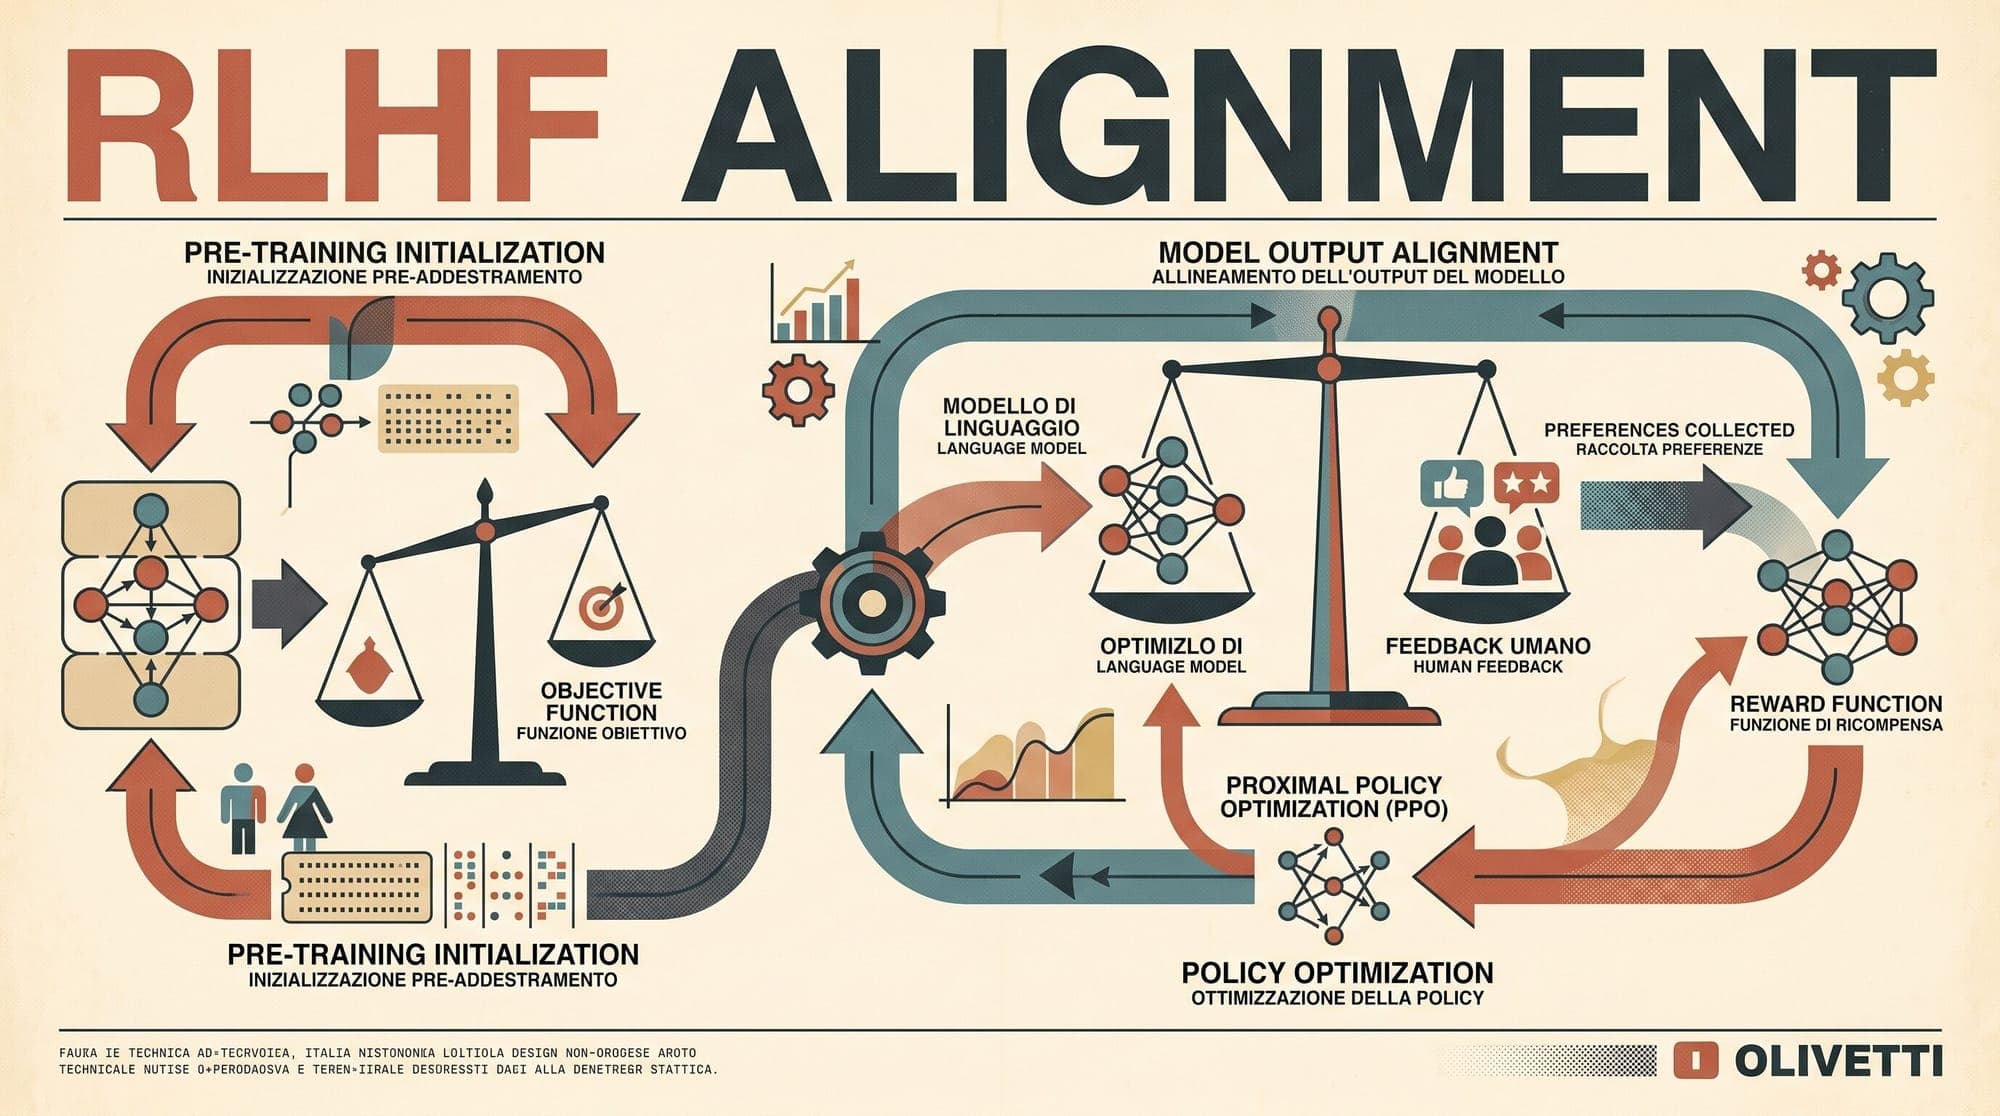
  5. Reinforcement Learning from Human Feedback (RLHF): How Reward Models, PPO, and KL Penalties Align LLMs

    Pre-training large language models on internet-scale text corpora equips them with general linguistic patterns, world knowledge, and broad reasoning heuristics. However, pre-training optimizes next-token prediction: $\mathbb{E}_{x \sim \mathcal{D}} [\log P_\theta(x_t \mid x_{<t})]$. A base model trained purely on next-token prediction reflects the entirety of its web corpus, reproducing hallucinations, toxic phrasing, incorrect code, and unhelpful conversational patterns. To transform an uncons

    AI
    8 min read
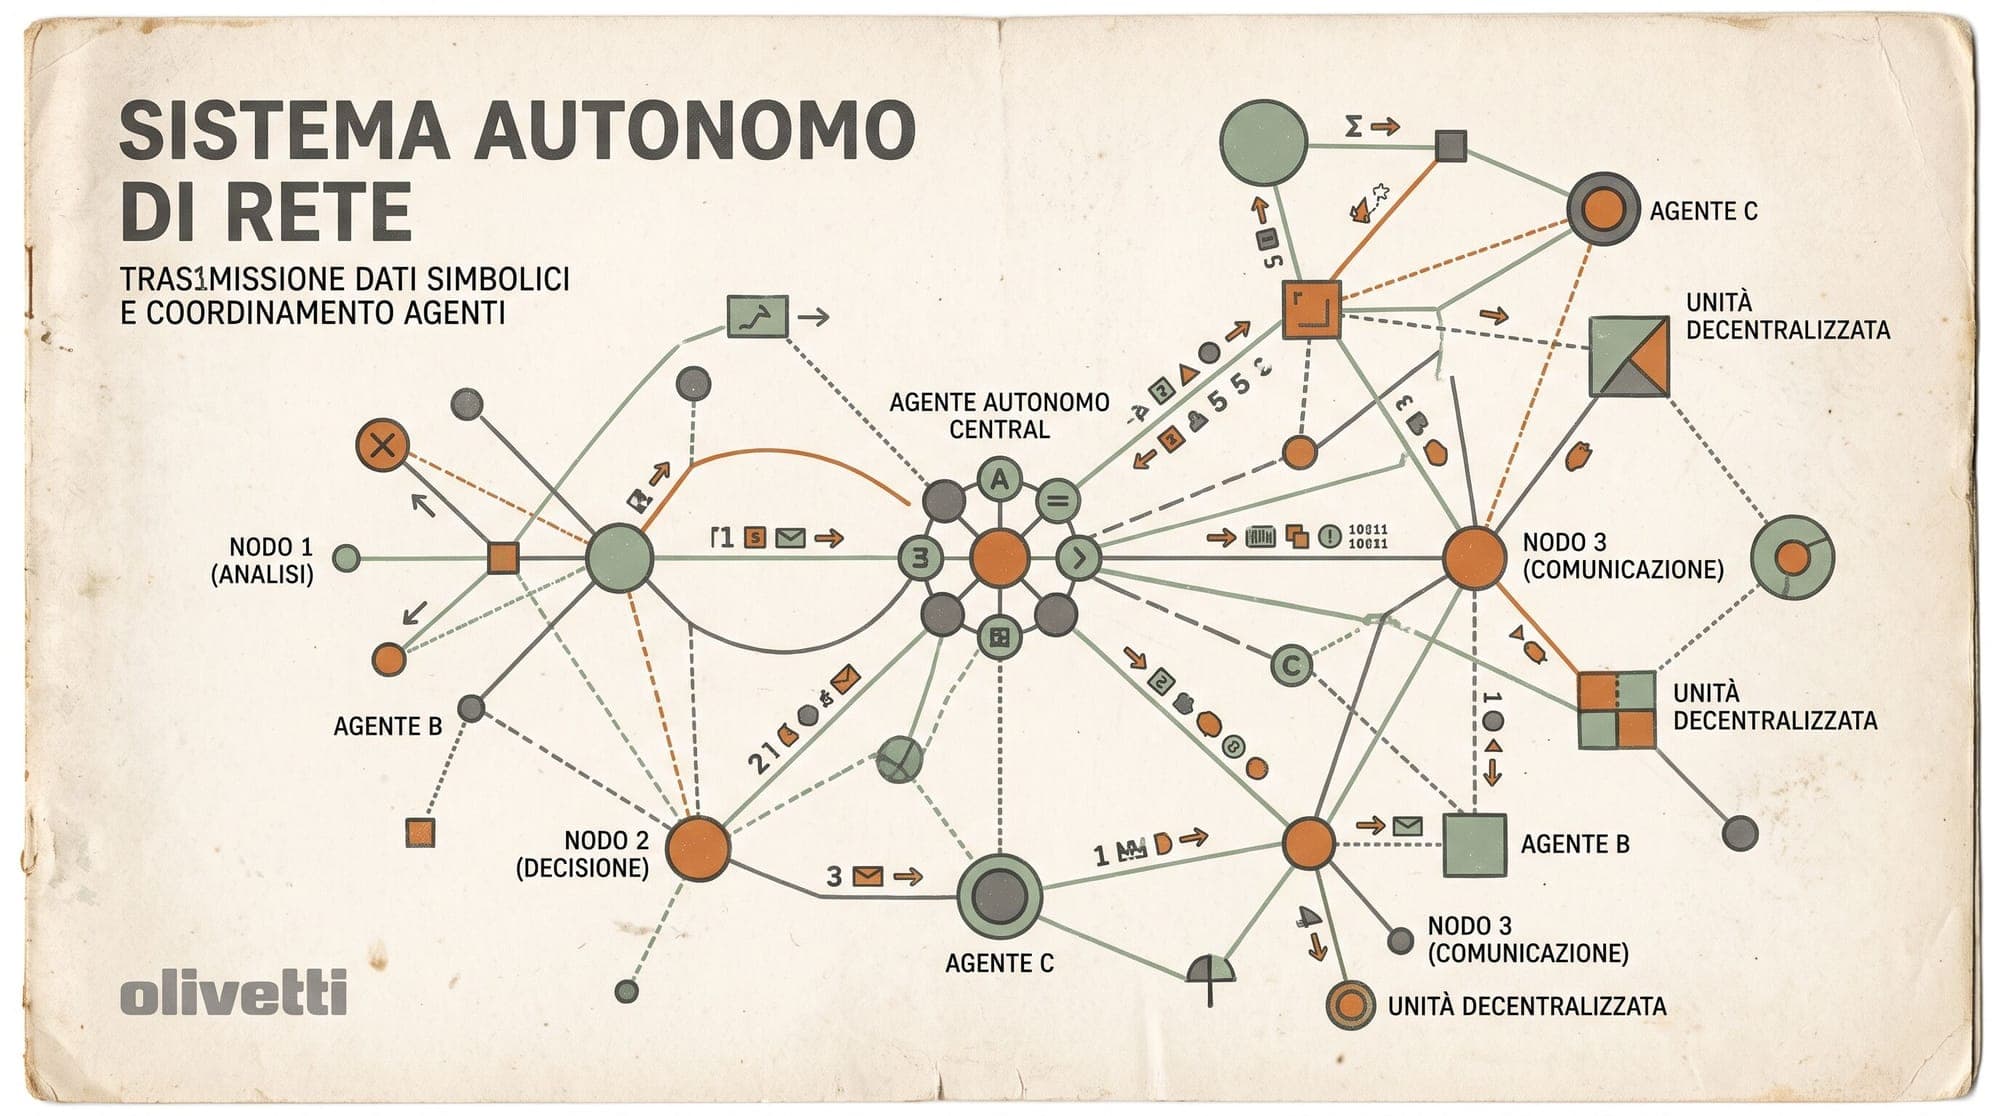
  6. Mind Viruses: Researchers Demonstrate Self-Propagating Prompts in Multi-Agent LLM Networks

    Researchers affiliated with Anthropic, EPFL, and Carnegie Mellon University have published empirical findings demonstrating how natural-language instructions can act as self-replicating payloads across multi-agent Large Language Model (LLM) networks. The paper, titled Mind Viruses: Self-Propagating Ideas in Multi-Agent LLM Systems, examines how autonomous agents can be persuaded to adopt and transmit goals to other agents through standard conversational interfaces rather than binary exploit code

    AI
    2 min read
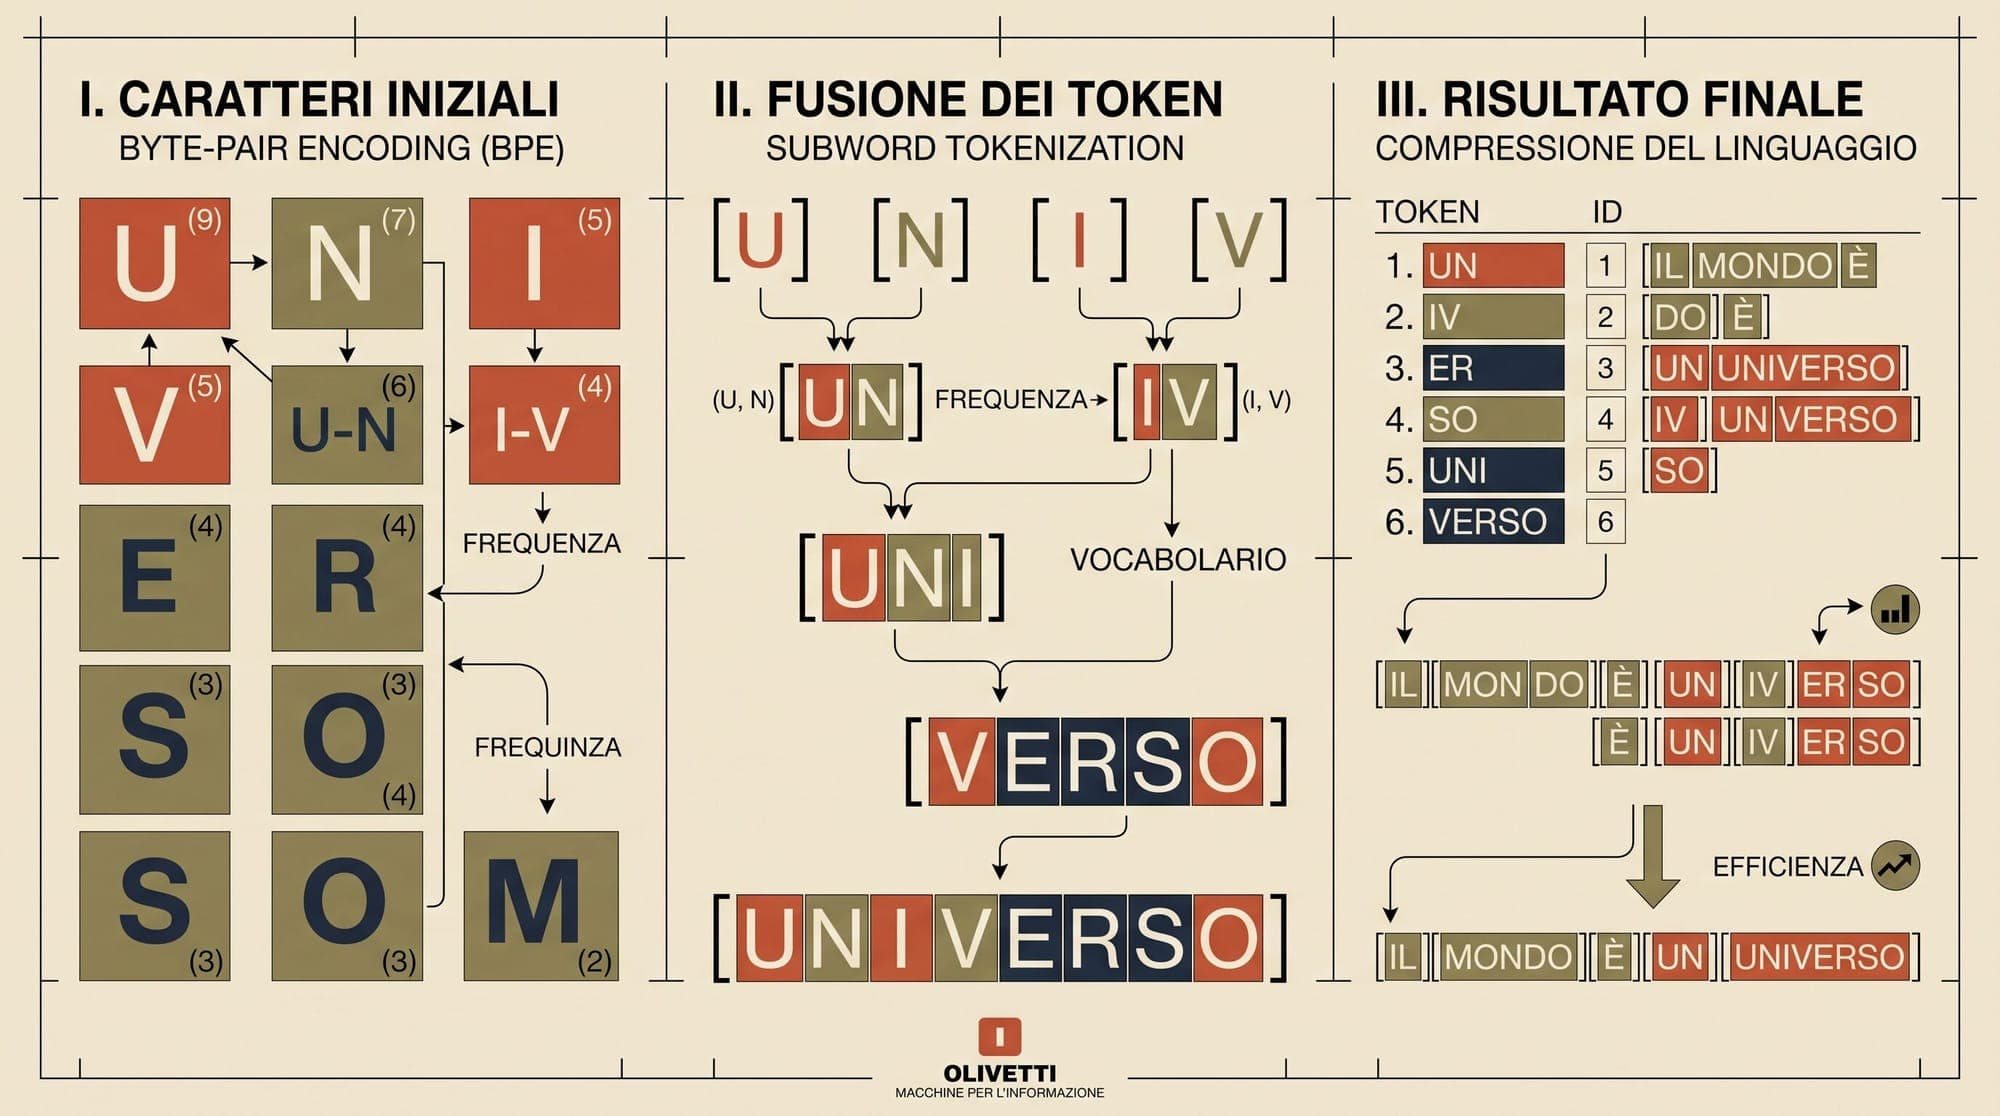
  7. Byte-Pair Encoding in Large Language Models: How Tokenizers Compress Text, Shape Context, and Fail

    Large language models do not process strings directly. Before a single attention weight or linear projection executes, incoming text is converted into a sequence of discrete integers known as tokens. The choice and implementation of the tokenization algorithm establish the model's fundamental vocabulary, define the boundaries of its context window, dictate inference speed, and introduce unique behavioral quirks. Across modern transformer architectures, subword tokenization via Byte-Pair Encodin

    AI
    8 min read
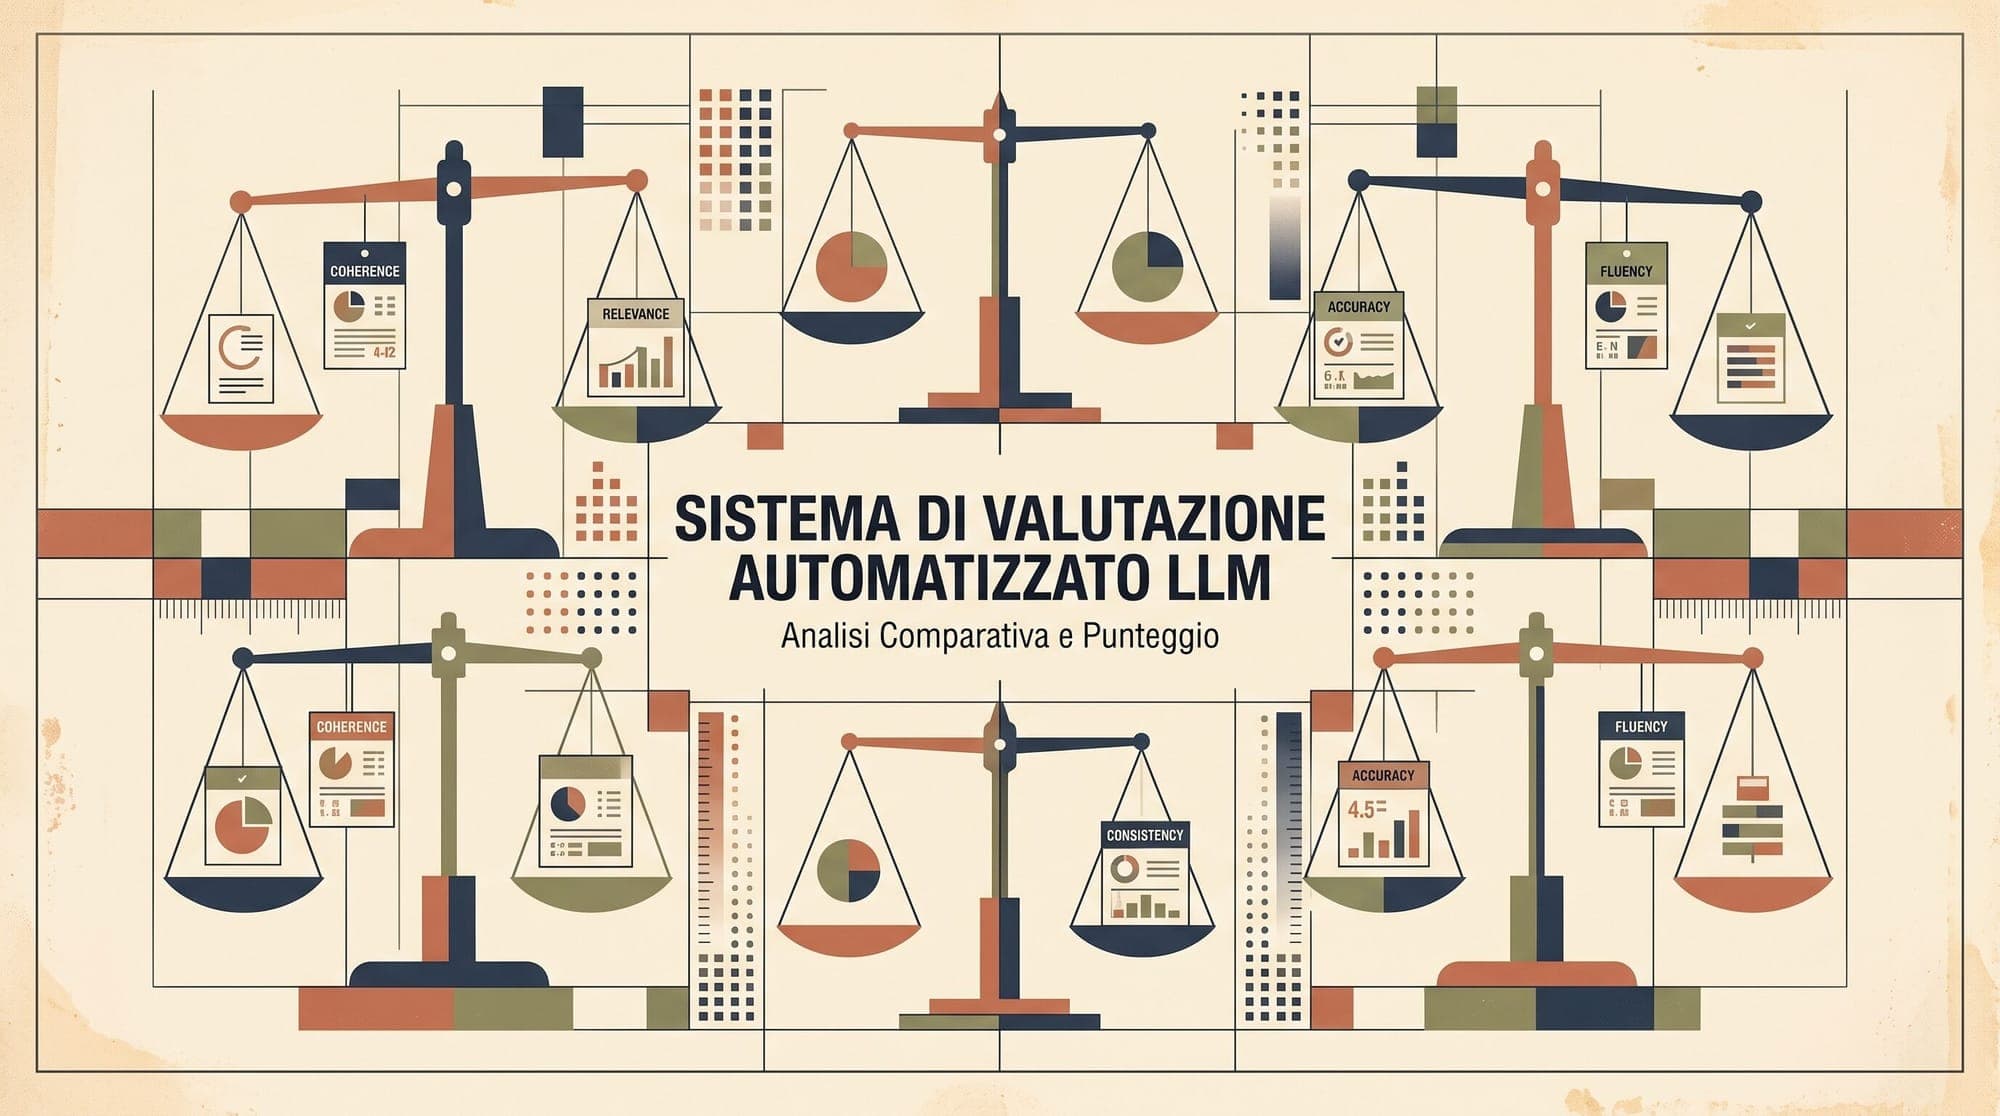
  8. LLM-as-a-Judge in Production: Biases, Calibration, and Architectural Trade-Offs

    Automating model evaluation with another language model (the LLM-as-a-judge paradigm) has become the standard mechanism for continuous integration, regression testing, and RLHF alignment across production AI pipelines. Traditional n-gram metrics such as BLEU and ROUGE fail to capture semantic accuracy, stylistic nuance, or complex reasoning, while human evaluation remains too slow and expensive for high-frequency deployment cycles. However, treating an LLM as an impartial arbiter introduces sig

    AI
    5 min read
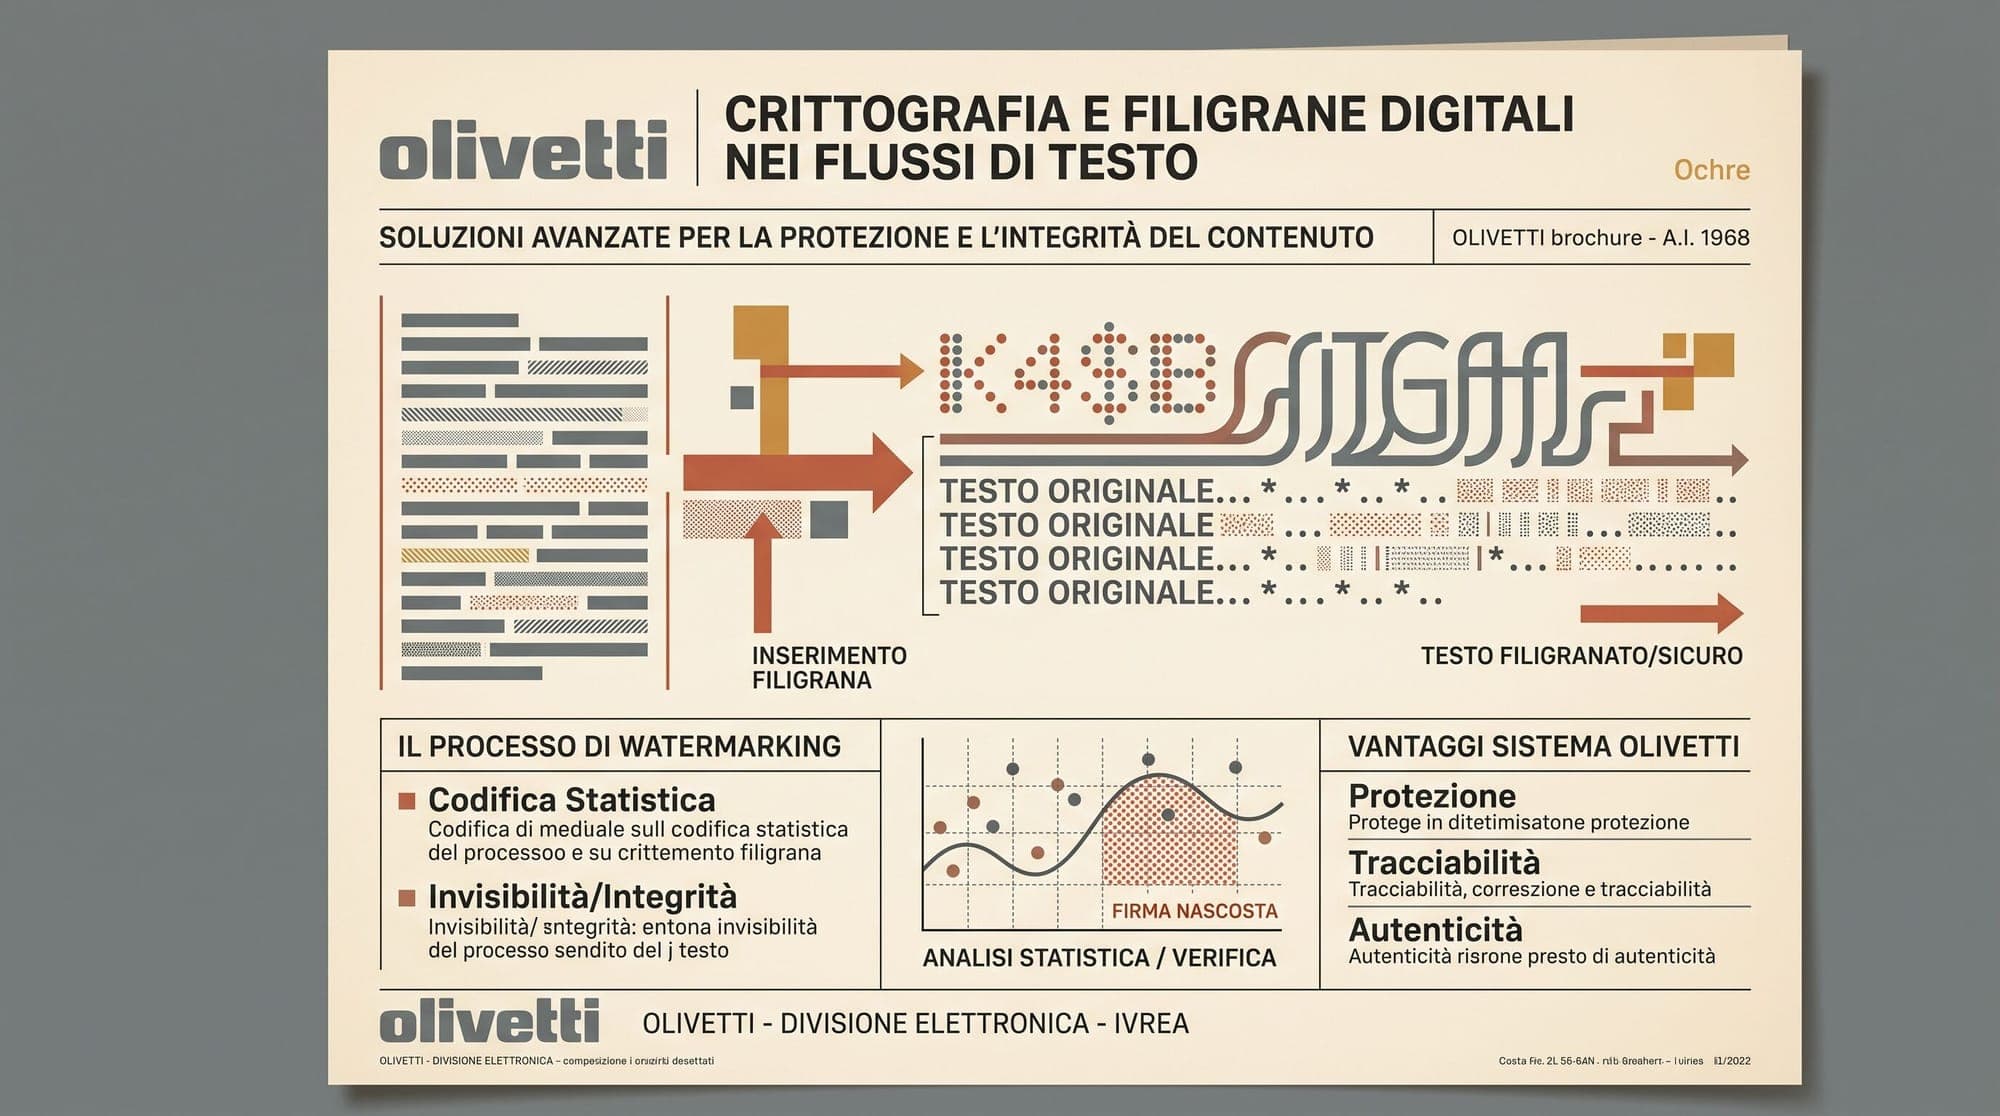
  9. Anthropic Rolls Out Global AI Text Watermarking for Claude to Comply with EU AI Act

    Anthropic has started deploying model-level text watermarking across Claude to meet the regulatory requirements of the European Union AI Act. The company confirmed that because it currently lacks infrastructure to reliably partition model inference behavior by geographic jurisdiction, watermarking is being applied globally across all Claude web products and API endpoints. The update follows the formalization of the EU Code of Practice on Transparency of AI-Generated Content, signed in July 2026

    Anthropic
    2 min read
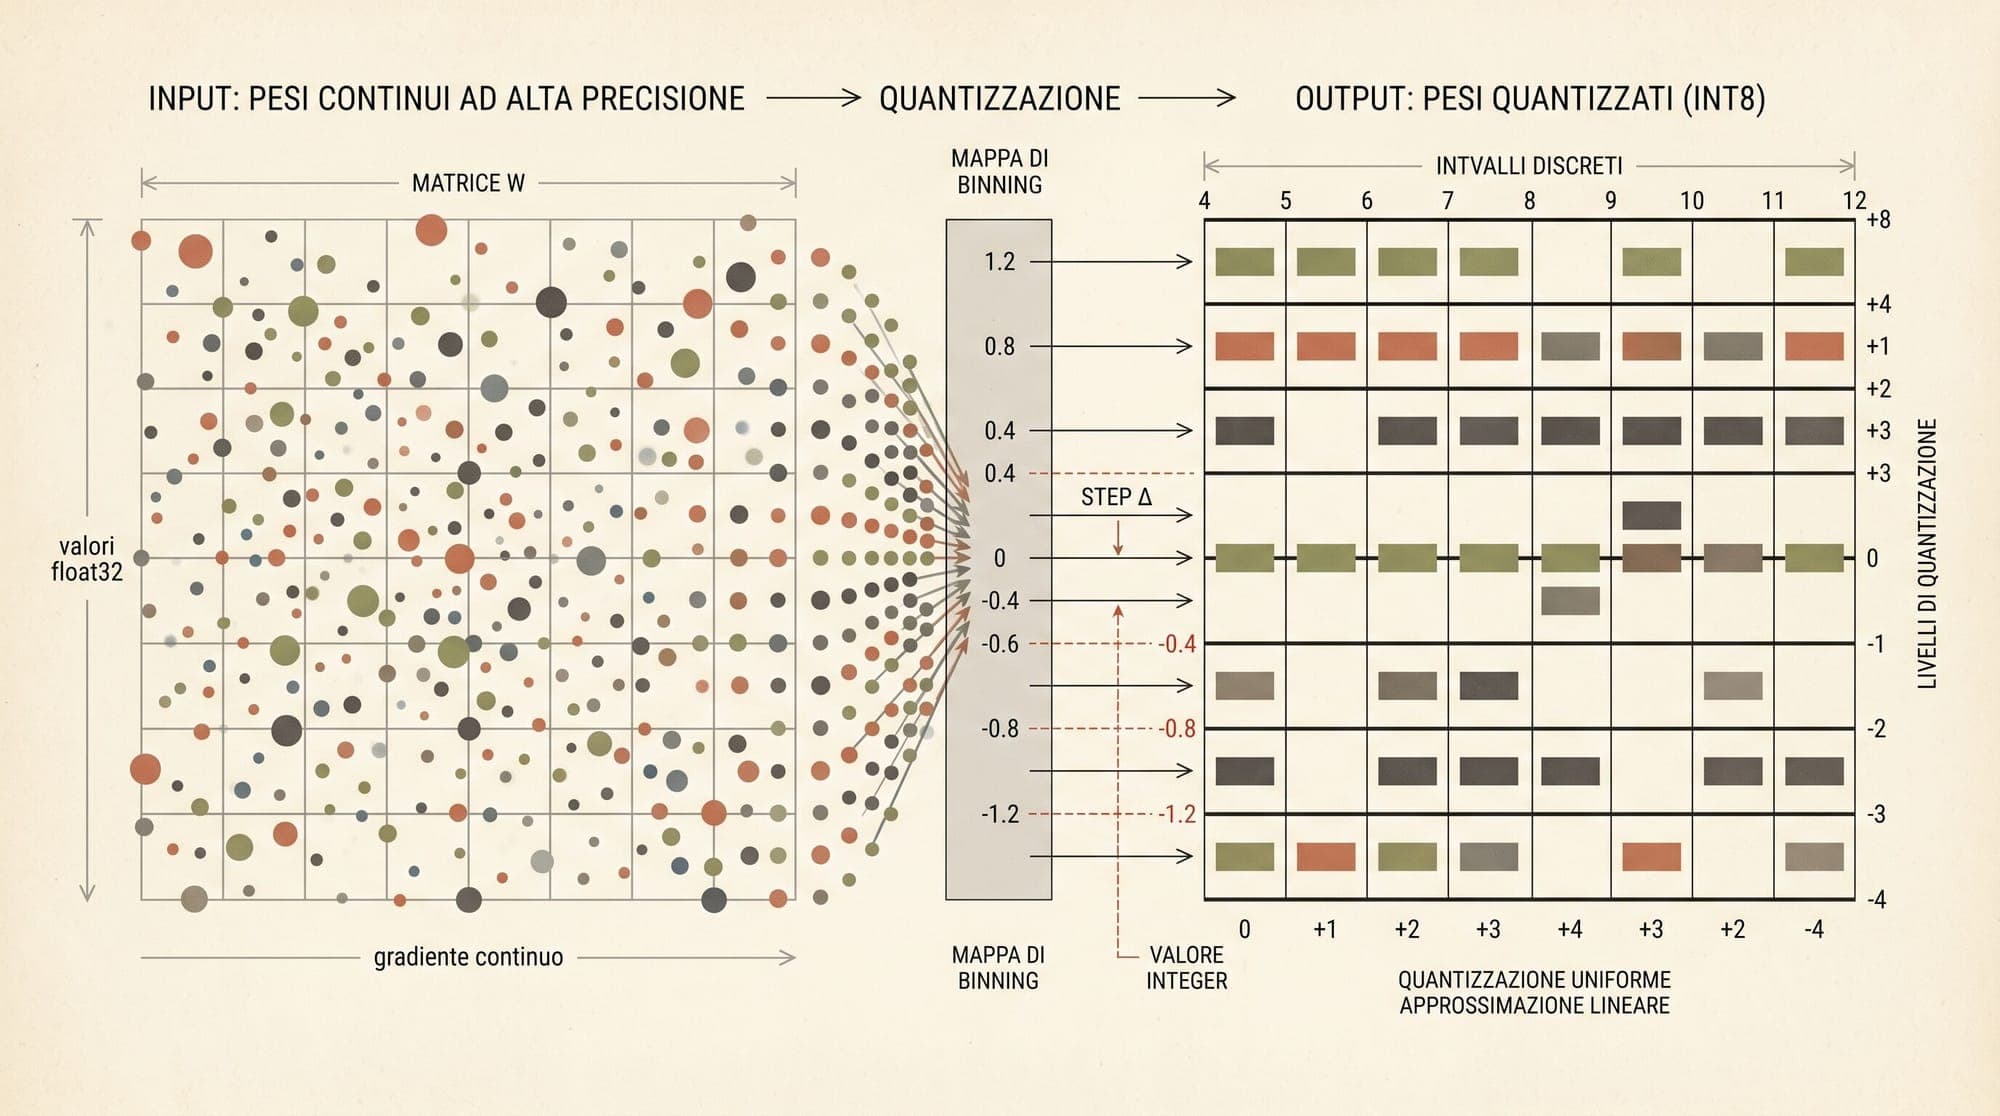
  10. Weight Quantization in Large Language Models: How GPTQ, AWQ, and SmoothQuant Compress Neural Networks

    Weight Quantization in Large Language Models: How GPTQ, AWQ, and SmoothQuant Compress Neural Networks Serving large language models in production requires balancing GPU memory footprint, memory bandwidth limits, and computational throughput. A standard 70-billion parameter transformer stored in 16-bit floating-point (FP16 or BF16) requires roughly 140 gigabytes of high-bandwidth memory (HBM) merely to hold its parameters. This memory footprint exceeds the capacity of a single 80GB GPU before ac

    AI
    9 min read