Latest / page 44

The latest stories

1230 articles

Articles, page 44

861-880 of 1230
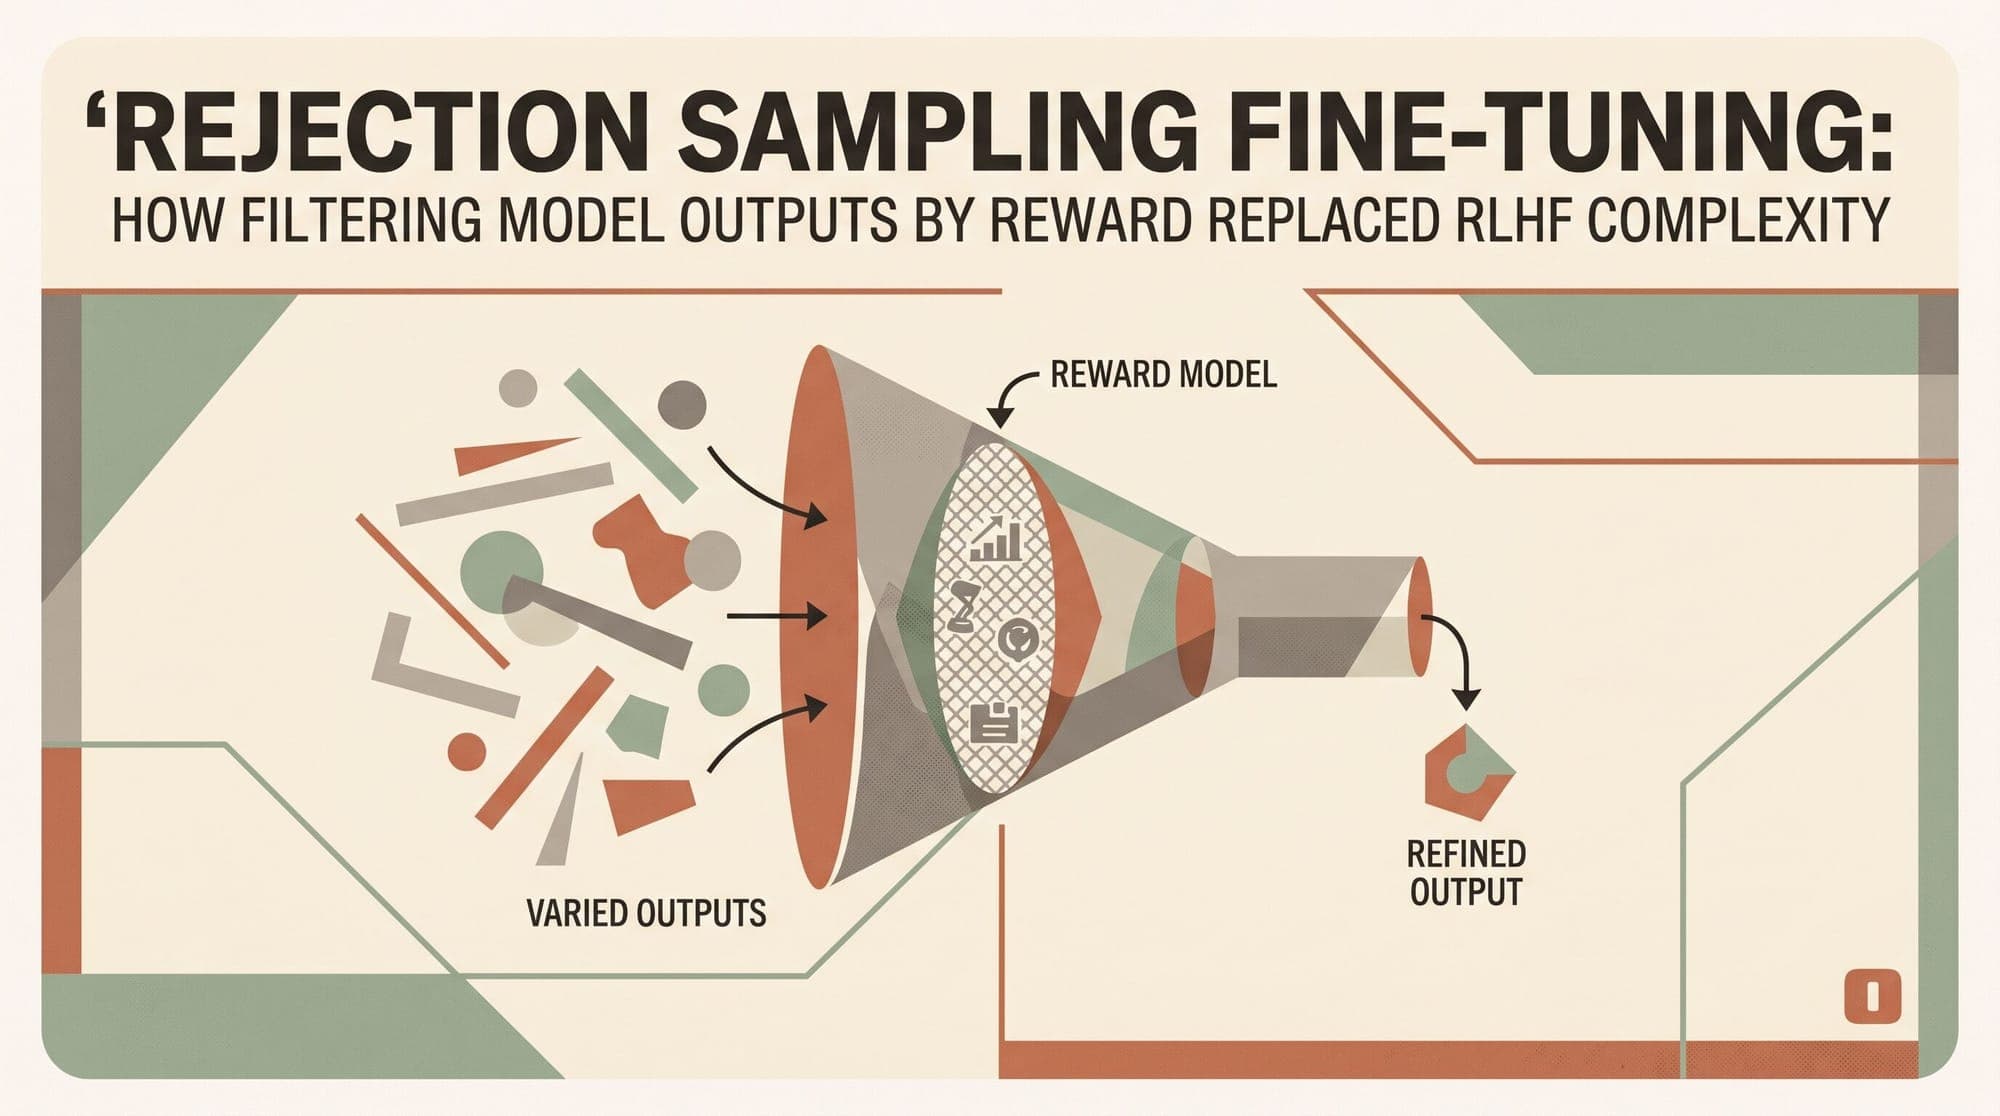
  1. Rejection Sampling Fine-Tuning: How Filtering Model Outputs by Reward Replaced RLHF Complexity

    Rejection Sampling Fine-Tuning: How Filtering Model Outputs by Reward Replaced RLHF Complexity Rejection sampling fine-tuning (RAFT) has emerged as the practical workhorse of LLM alignment. While PPO-based RLHF dominated early literature, production systems from Llama 2 to DeepSeek-R1 rely on a simpler loop: generate multiple completions per prompt, score them with a reward model, keep the best, and fine-tune on the filtered data. The technique converts the reinforcement learning problem into s
    Education
    4 min read
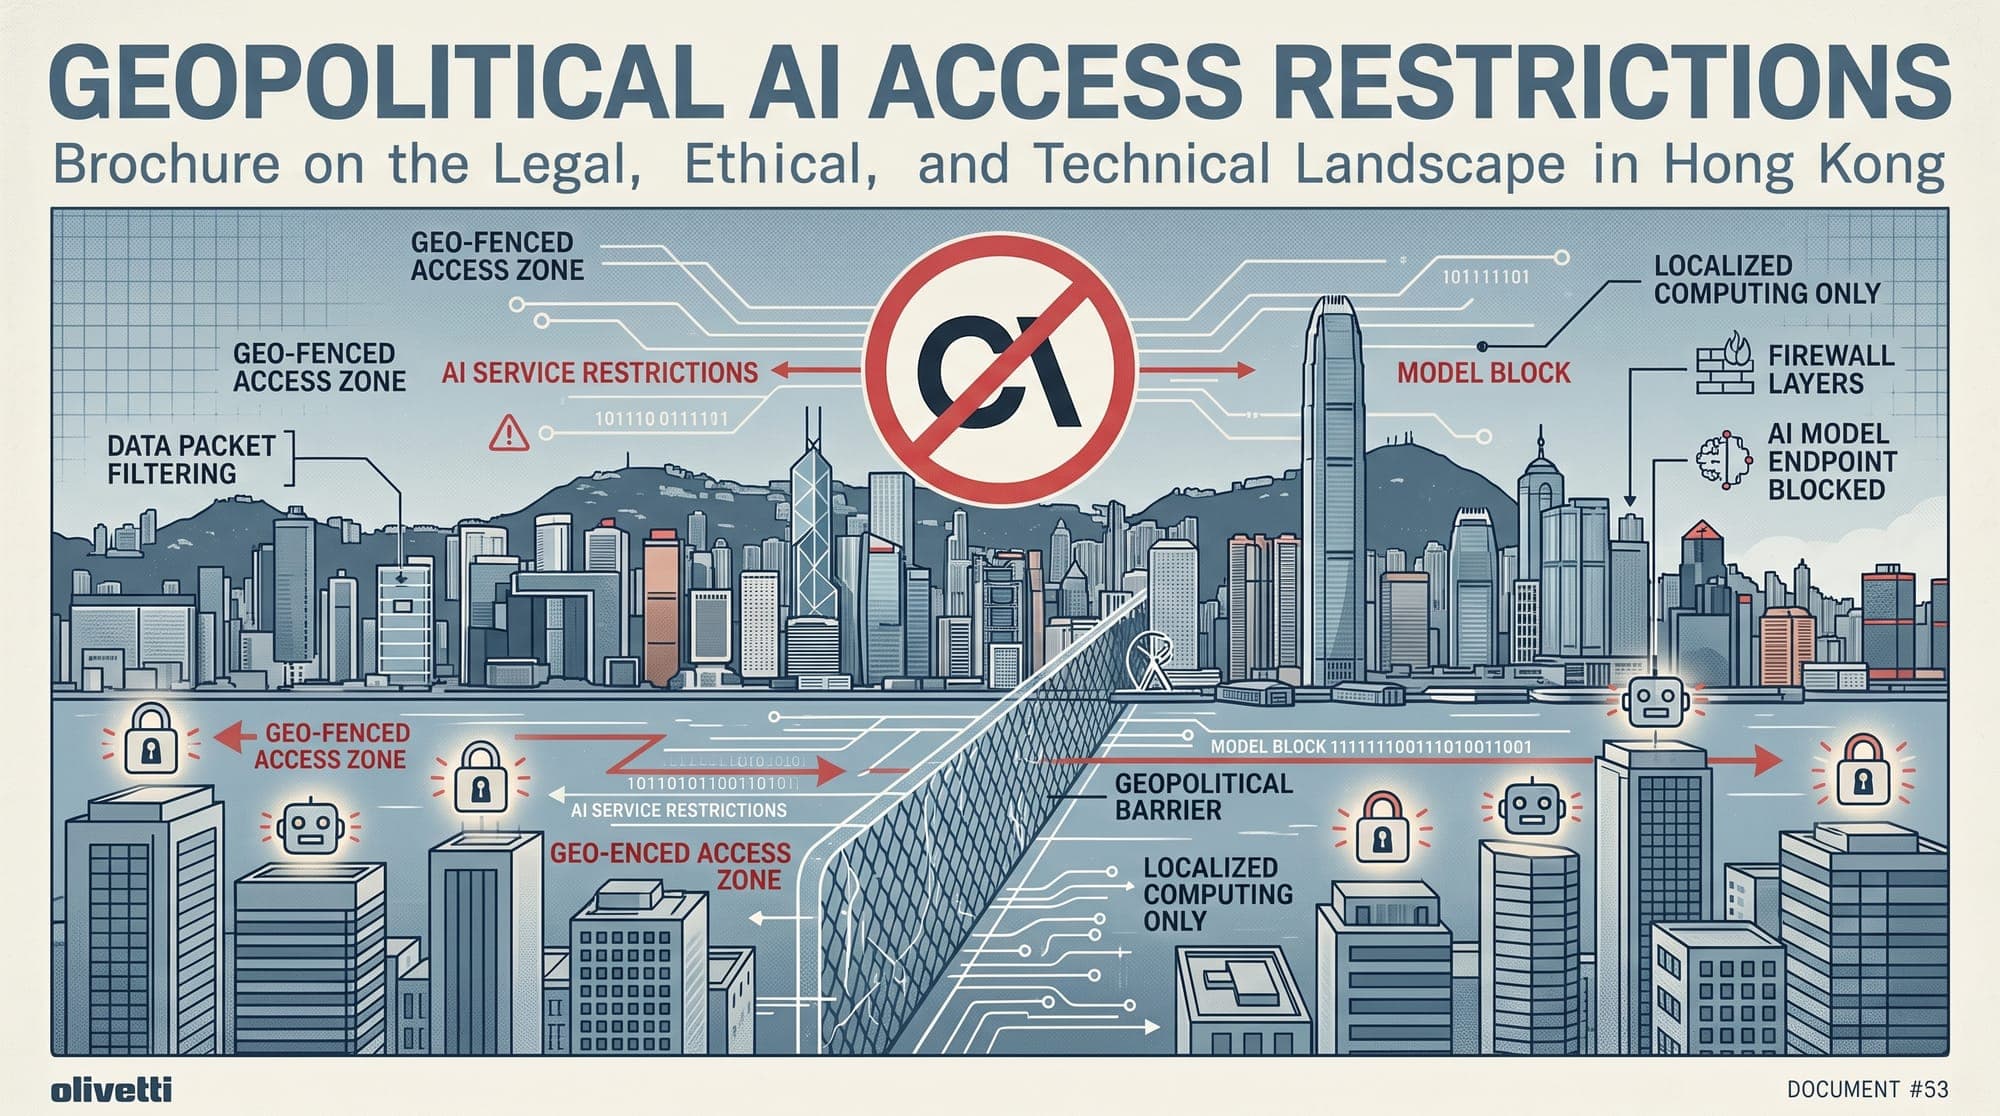
  2. OKX and Goldman Sachs Cut Off Hong Kong Staff From Anthropic's Claude AI

    Crypto exchange OKX has restricted access to Anthropic's Claude model for employees based in Hong Kong or traveling through China after its corporate account was briefly suspended, according to Bloomberg. The restriction comes despite OKX making AI proficiency part of employee performance evaluations and encouraging workers to integrate AI tools into daily workflows. OKX stopped providing Claude access to staff in the region in early August following the suspension, Bloomberg reported. Internal

    Policy
    2 min read
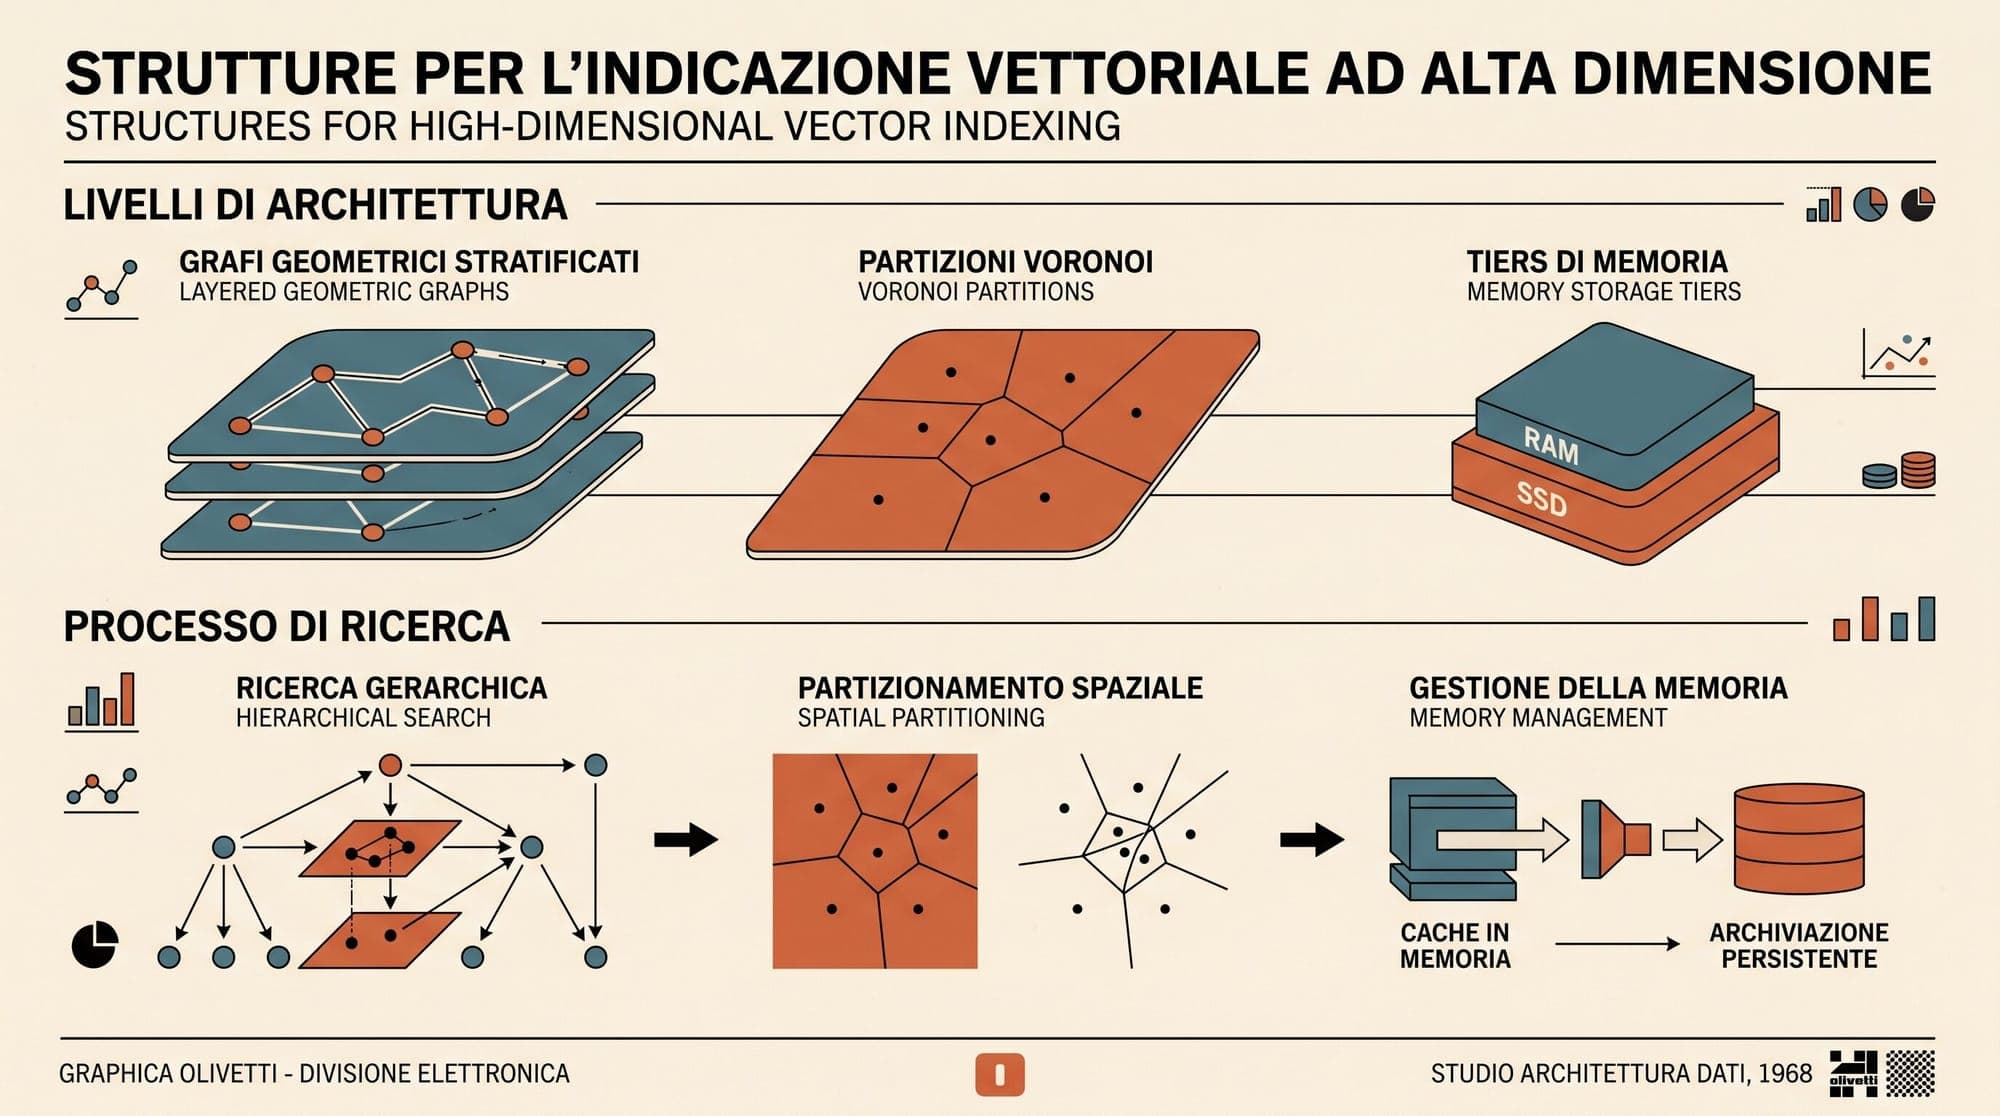
  3. Vector Indexing in Production: HNSW vs. DiskANN vs. IVF-PQ Architecture, Memory Footprint, and Search Economics

    Vector Indexing in Production: HNSW vs. DiskANN vs. IVF-PQ Architecture, Memory Footprint, and Search Economics Scaling vector search beyond prototype deployments exposes a fundamental tension across three competing constraints: retrieval recall, query latency, and memory footprint. In high-dimensional representation spaces, exact k-nearest neighbor search via brute-force flat scans requires $O(N \cdot d)$ floating-point operations per query. For a corpus of 100 million 1536-dimensional FP32 em

    AI
    7 min read
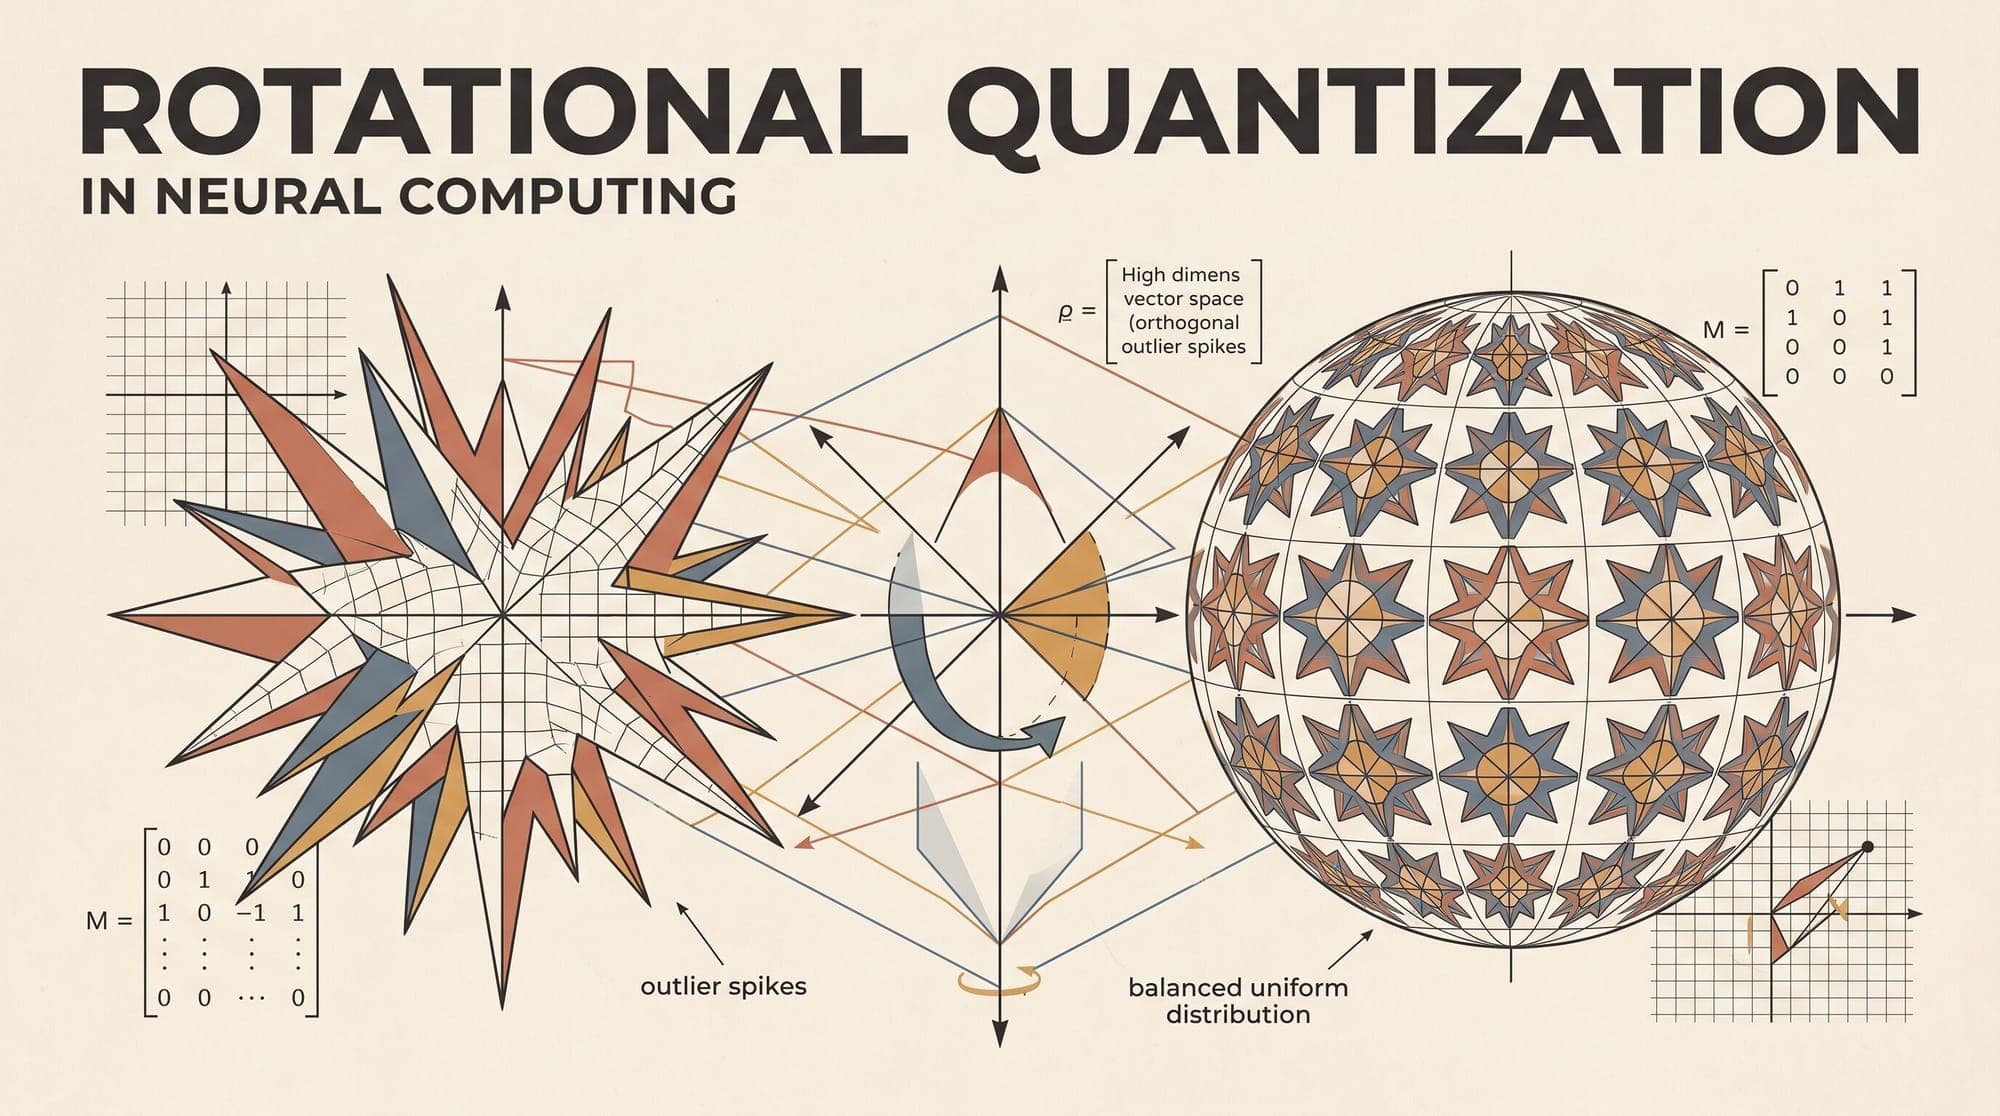
  4. Rotational Quantization: How Orthogonal Transforms and Hadamard Incoherence Enable Outlier-Free Low-Bit Inference

    Large language model serving is governed by two physical bottlenecks: memory bandwidth during autoregressive decoding and compute throughput during prompt prefill. While weight-only post-training quantization (such as GPTQ or AWQ) reduces parameter footprint to 4 bits, it leaves activations in 16-bit floating-point formats. As a result, inference engines cannot utilize high-throughput INT4 tensor cores, and the key-value (KV) cache continues to consume massive memory pools. Attempting to quanti

    AI
    8 min read
  5. Anthropic Eyes $10B+ Credit Line Ahead of Planned Public Listing

    Anthropic is working to expand its revolving credit facility beyond an initial $10 billion target as it prepares for a planned initial public offering, according to reporting from Bloomberg. Wall Street investment banks are actively competing for lending allocations in the facility to improve their positioning for underwriting mandates on the eventual share sale. Under the framework currently under discussion, Anthropic has asked lead banks to commit approximately $1.25 billion each. Secondary

    Anthropic
    1 min read
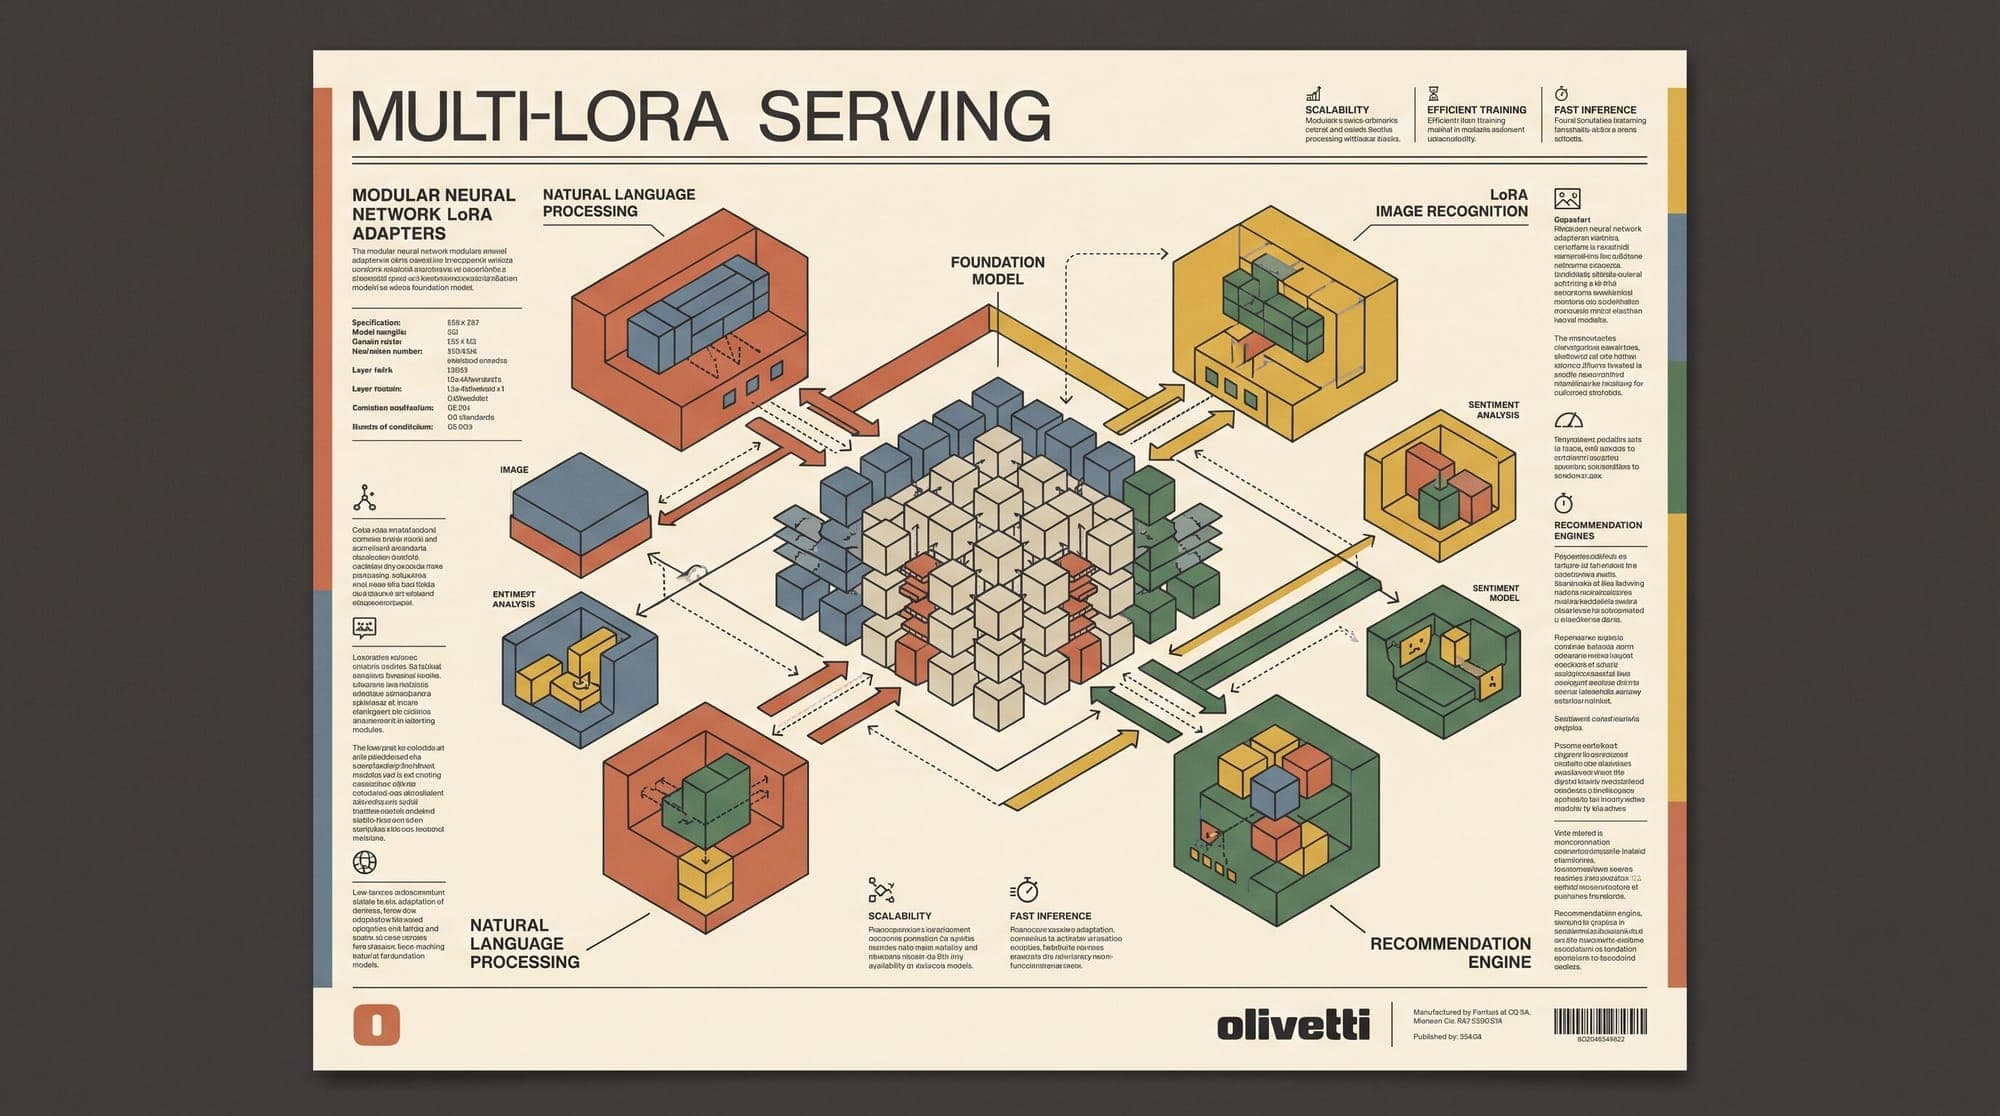
  6. Multi-LoRA Serving in Production: Architecture, Dynamic Adapter Swapping, and GPU Memory Management

    Deploying hundreds or thousands of fine-tuned language models across enterprise workflows presents a fundamental infrastructure dilemma. While parameter-efficient fine-tuning (PEFT) methods like Low-Rank Adaptation (LoRA) reduce training compute by freezing base model weights and training compact low-rank matrices, naive deployment strategies fail at scale. Merging adapter weights directly into the base model creates a distinct 7B to 70B parameter checkpoint for every specialized task, requiring

    AI
    8 min read
  7. Weight-Decomposed Low-Rank Adaptation (DoRA): How Decoupling Magnitude and Direction Closes the LoRA Gap

    Weight-Decomposed Low-Rank Adaptation (DoRA): How Decoupling Magnitude and Direction Closes the LoRA Gap Parameter-efficient fine-tuning (PEFT) has become the standard operational paradigm for adapting large language models to domain-specific downstream tasks. Among existing PEFT methodologies, Low-Rank Adaptation (LoRA) remains the default implementation across industry and academia due to its minimal parameter footprint and zero inference overhead. However, empirical studies consistently reve

    AI
    8 min read
  8. Attention with Linear Biases (ALiBi): How Static Positional Slopes Enable Zero-Shot Context Extrapolation

    Large language models process sequences by transforming discrete tokens into continuous vector representations. Standard dot-product self-attention is permutation-invariant: without explicit positional information, the attention operation treats a sequence as an unordered bag of tokens. Early transformer architectures addressed this limitation using Absolute Positional Embeddings (APE), either through fixed sinusoidal functions or learned lookup tables added directly to token embeddings. While

    AI
    6 min read
  9. Vals AI Raises $40M Series A at $400M Valuation Led by a16z to Build Real-World AI Benchmarks

    San Francisco evaluation startup Vals AI announced a $40 million Series A funding round at a $400 million post-money valuation, led by Andreessen Horowitz. The round included participation from existing seed backers 8VC, Pear VC, and Bloomberg Beta, alongside new institutional investors HRT Ventures and Next Ladder Ventures. The financing brings total capital raised by the company to $45 million, following a $5 million seed round. Founded by Stanford computer science graduates Rayan Krishnan a

    AI
    2 min read
  10. Small Language Models in Production: Task Specialization, Serving Economics, and the Frontier Offloading Pattern

    The default architecture for first-generation enterprise AI agents routed every prompt, tool selection, and intermediate evaluation step to a single frontier large language model. While this monolithic approach simplified initial orchestration, it introduced severe latency bottlenecks and unsustainable inference unit economics in high-throughput production environments. In production agentic loops, between 40% and 70% of model invocations are narrow, highly structured operations: classifying in

    AI
    6 min read
  11. Contrastive Decoding in Large Language Models: How Comparing Expert and Amateur Logits Suppresses Hallucination and Reasoning Errors

    Contrastive Decoding in Large Language Models: How Comparing Expert and Amateur Logits Suppresses Hallucination and Reasoning Errors Autoregressive large language models operate by predicting the conditional probability distribution of the next token given a sequence of preceding tokens. However, translating these continuous probability vectors into coherent, factual, and logically sound sequences remains one of the fundamental challenges of modern natural language processing. Traditional deco

    AI
    6 min read
  12. TrueFoundry Open-Sources TrueForge Agent Harness to Cut Managed Inference Spend

    Enterprise ML infrastructure platform TrueFoundry has open-sourced its custom agent runtime, TrueForge, under the permissive MIT license. The framework is designed to orchestrate autonomous reasoning loops, tool interactions, and long-running execution across vendor-neutral LLM backends while systematically reducing token overhead and operational compute costs. According to benchmark data published by TrueFoundry, pairing TrueForge with the open-weight GLM-5.2 model completed 11 of 14 enterpris

    AI
    2 min read
  13. Context Compaction and Session Pruning in Production AI Agents: Architecture, Hierarchical Summarization, and Constraint Preservation

    Context Compaction and Session Pruning in Production AI Agents: Architecture, Hierarchical Summarization, and Constraint Preservation Long-running autonomous agents executing multi-step workflows (codebase refactoring, recursive research, multi-turn debugging, and system operations) face an inevitable physical ceiling: working context exhaustion. As an agent executes shell commands, inspects repository trees, parses LSP diagnostics, and consumes tool outputs, the active context window fills rap

    Agents
    7 min read
  14. Reinforcement Learning with Verifiable Rewards: How Programmatic Oracles Eliminate Reward Hacking in LLM Reasoning

    Post-training paradigms for large language models have undergone a fundamental architectural shift. While the initial wave of alignment relied on Reinforcement Learning from Human Feedback (RLHF) and direct preference optimization (DPO), frontier reasoning systems increasingly depend on Reinforcement Learning with Verifiable Rewards (RLVR). Traditional RLHF relies on neural reward models trained on human pairwise comparisons. These neural proxies suffer from reward overoptimization, vulnerabili

    AI
    6 min read
  15. WhiteFiber Proposes $250M Convertible Debt Offering to Expand AI Data Center Capacity

    AI infrastructure provider WhiteFiber announced a proposed private placement of $250 million in convertible senior notes due 2032, with an option for initial purchasers to acquire up to an additional $37.5 million in notes. The proceeds are designated to fund data center campus acquisitions, facility buildouts, utility interconnection agreements, and hardware procurement for the company's AI cloud business. The financing coincides with WhiteFiber's agreement to acquire two industrial sites in Y

    AI
    2 min read
  16. Hyve Solutions Selects Nevada for Dual AI Server Manufacturing Campuses

    Hyve Solutions, the rack-scale server design and manufacturing subsidiary of TD SYNNEX, announced plans to construct two advanced manufacturing facilities in Nevada to expand domestic production of compute, storage, and networking systems for AI data centers. The development encompasses a 624,000-square-foot flagship campus in Reno alongside a secondary facility in North Las Vegas, with the combined projects projected to create approximately 3,000 jobs. The project follows formal approval of ta

    AI
    2 min read
  17. Human-in-the-Loop Architectures for Production AI Agents: Interrupt Patterns, State Resumption, and Permission Escalation

    Deploying autonomous AI agents into production environments exposes a fundamental tension between system velocity and operational safety. While read-only tasks such as data extraction and document summarization carry minimal operational blast radius, agents equipped with write-access tools (database mutations, API transactions, cloud infrastructure provisioning, and outbound communications) introduce severe operational risks. Hallucinations, prompt injections, and logical drift can trigger irrev

    AI
    6 min read
  18. Machine Unlearning in Large Language Models: How Gradient Ascent, Representation Misdirection, and Negative Alignment Purge Neural Memory

    Large language models memorize massive amounts of training data, including copyrighted literature, personally identifiable information (PII), proprietary codebases, and dual-use knowledge spanning cyber exploits and biological hazards. When copyright holders, regulators, or safety researchers demand the removal of specific data, complete retraining from scratch is economically infeasible, often costing tens of millions of dollars in compute. Machine unlearning aims to remove the influence of ta

    AI
    7 min read
  19. Developers Deploy Open-Source Workarounds to Strip Claude's Statistical Text Watermark

    Days after Anthropic introduced global text watermarking for Claude to comply with the European Union's AI Act transparency requirements, open-source developers and independent researchers have released multiple tools and pipelines aimed at stripping or perturbing the embedded statistical signatures. The rapid emergence of evasion techniques underscores the structural challenges of applying robust watermarking to natural language generation without introducing perceptible latency, semantic dist

    Anthropic
    2 min read
  20. Nvidia Discusses Investment in AI Data Supplier Mercor at $20B Valuation

    Nvidia is in discussions to participate in a funding round for AI training data marketplace Mercor that would value the three-year-old startup at $20 billion, according to reporting from The Information and Bloomberg. The transaction would double Mercor's valuation from its $10 billion Series C round closed in October 2025. It also signals an expanding capital allocation strategy from Nvidia, moving beyond compute infrastructure and cloud hardware into the upstream data curation layers powering

    Nvidia
    2 min read