Category / page 15

Models & Assistants

1121 articles

Articles, page 15

281-300 of 1121
  1. Local LLM Inference Frameworks in Production: Comparing llama.cpp, Ollama, Apple MLX, and Exo Distributed Clusters

    The deployment landscape for large language models is bifurcating. While datacenter workloads rely on high-throughput continuous batching engines such as vLLM and TensorRT-LLM, local and edge deployments operate under fundamentally different physical constraints. On developer workstations, embedded hardware, and private office clusters, inference is rarely bound by compute saturation across thousands of concurrent requests. Instead, it is constrained by memory bandwidth, local VRAM capacity, hos
    AI
    6 min read
  2. Salesforce and Anthropic Launch Claudeforce with 37 Prebuilt Enterprise CRM Skills in Claude

    Salesforce and Anthropic have expanded their strategic partnership with the release of Claudeforce, an integration layer designed to connect Anthropic's Claude models directly with Salesforce enterprise data, workflow engines, and governance frameworks. The initiative introduces native CRM capabilities inside Claude while embedding Anthropic reasoning models across Salesforce's Agentforce platform and Slack workspace ecosystem. Salesforce in Claude Plugin and AIforce Harness The primary clie

    AI
    2 min read
  3. Anthropic Previews Model Hardware Standard for AI Agent Control of Physical and Lab Equipment

    Anthropic has introduced the Model Hardware Standard (MHS), an open interface specification intended to let AI agents control physical machinery and scientific instrumentation. Released in a research preview on August 27, 2026, the standard extends the design principles of the Model Context Protocol (MCP) to physical actuators, automated laboratory equipment, and industrial hardware. Connecting autonomous software agents to physical hardware has historically required custom integration code for

    AI
    3 min read
  4. Chinchilla Scaling Laws: Mathematical Foundations of Compute-Optimal Pre-Training, IsoFLOP Loss Profiles, Parametric Power Laws, and Data-Compute Allocation

    Chinchilla Scaling Laws: Mathematical Foundations of Compute-Optimal Pre-Training, IsoFLOP Loss Profiles, Parametric Power Laws, and Data-Compute Allocation When allocating a fixed computational budget to train an autoregressive Transformer, engineers face a fundamental trade-off: should FLOPs be spent increasing the model parameter count ($N$), or should they be spent streaming a larger volume of training tokens ($D$)? For several years, frontier AI development followed the empirical scaling

    AI
    14 min read
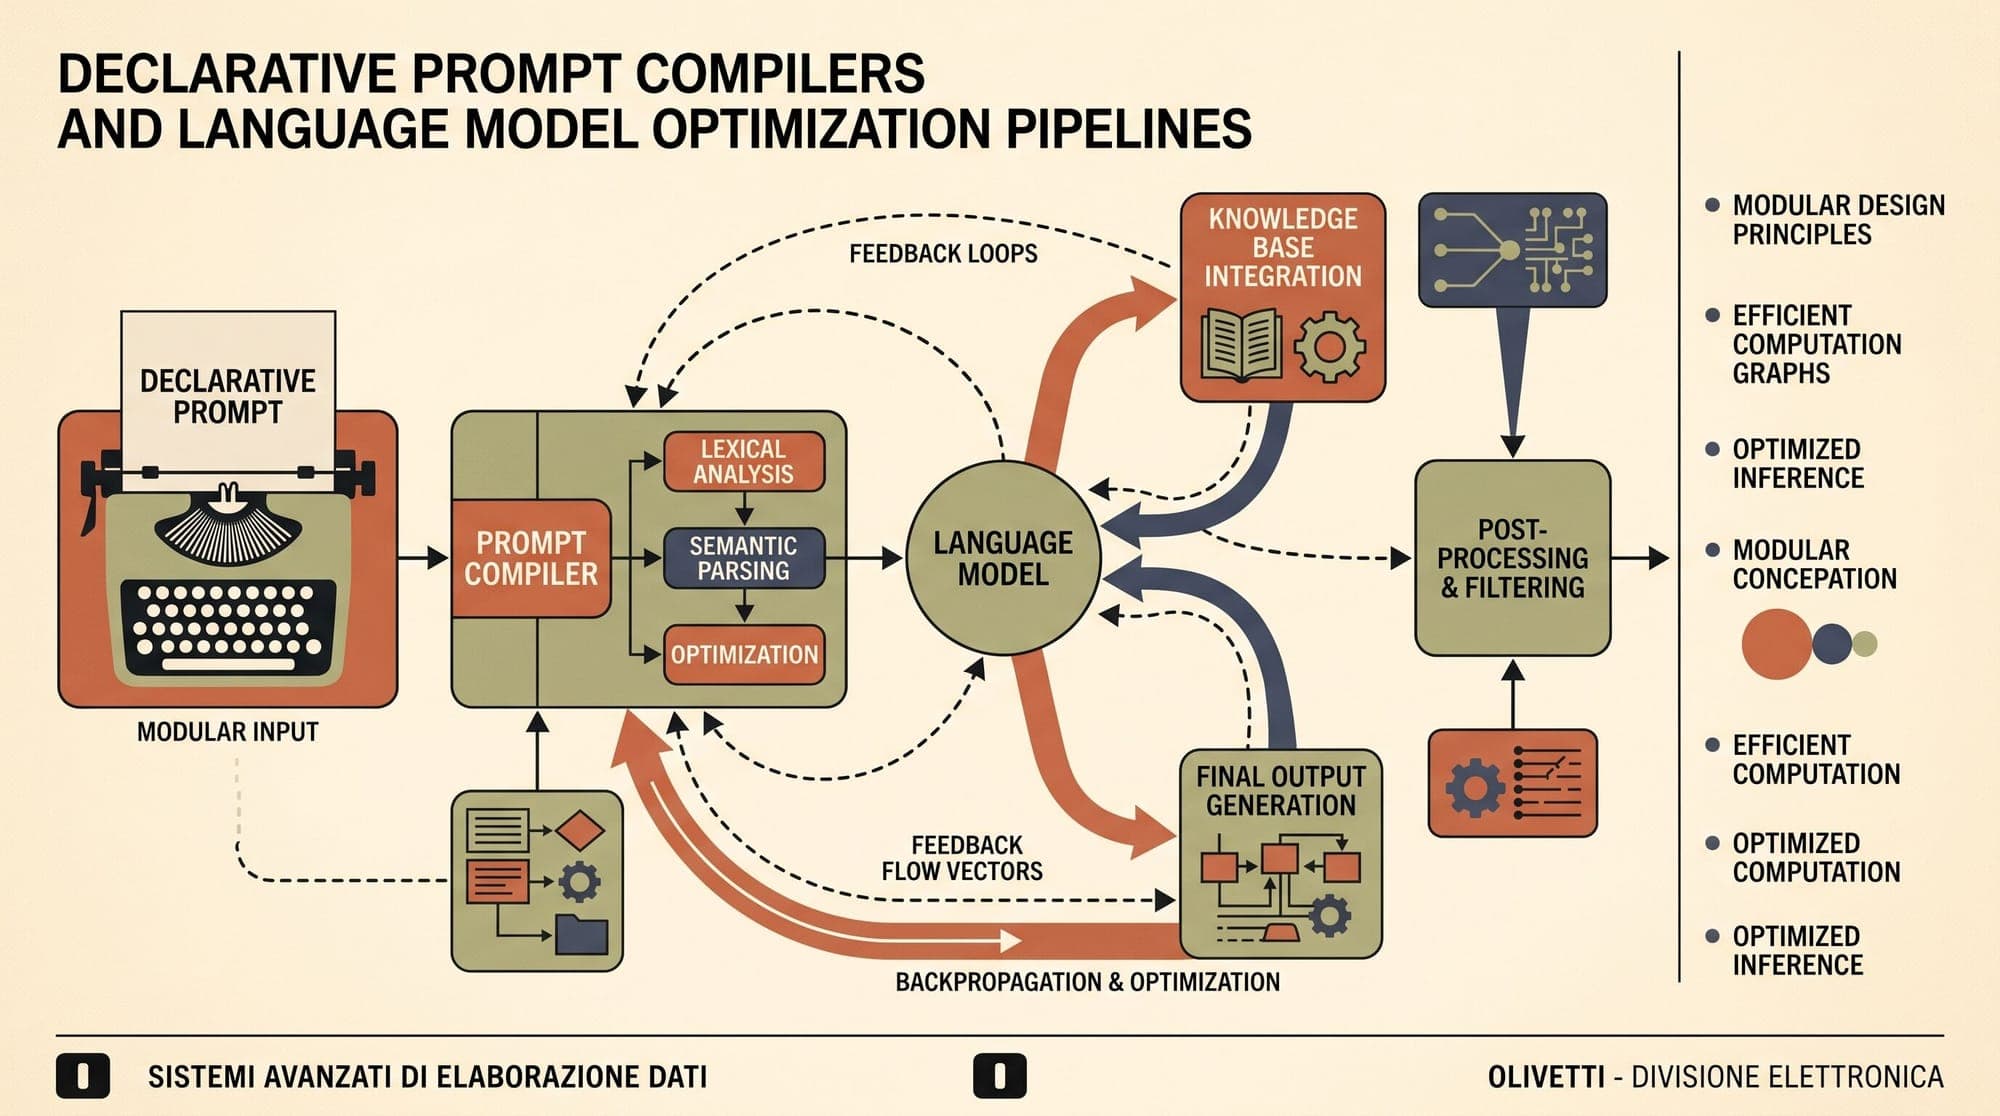
  5. Declarative Prompt Optimization and LLM Compilers in Production: Comparing DSPy, TextGrad, SAMMO, and AdalFlow

    Production AI applications are rapidly moving away from hardcoded prompt strings and manual trial-and-error tweaking. As language model systems expand into multi-stage pipelines, retrieval-augmented generation (RAG) graphs, and multi-agent loops, manual prompt adjustments fail to scale. Changing a system prompt or upstream retrieval format frequently degrades downstream extraction, reasoning, or tool-calling performance. To resolve this fragility, the industry is adopting declarative prompt opt

    AI
    7 min read
  6. Cognition Reaches $900M Annualized Revenue on Enterprise Devin Adoption

    Cognition AI, the startup behind autonomous software engineering agent Devin, has reached approximately $900 million in annualized revenue, according to financial data reported by The Information. The figure represents a more than threefold increase since the start of 2026, driven by accelerating enterprise adoption of autonomous developer workflows. Internal executive projections cited in the report indicate the company expects to finish 2026 with more than $1.5 billion in annualized run-rate

    AI
    2 min read
  7. Reference-Free Preference Optimization: Mathematical Foundations of SimPO and ORPO, Length-Normalized Implicit Rewards, Target Margins, and Monolithic Alignment

    Reference-Free Preference Optimization: Mathematical Foundations of SimPO and ORPO, Length-Normalized Implicit Rewards, Target Margins, and Monolithic Alignment Post-training alignment has shifted from complex multi-stage reinforcement learning pipelines toward direct preference optimization paradigms. While Proximal Policy Optimization (PPO) requires maintaining four concurrent models in memory (policy, value, reference, and reward networks), Direct Preference Optimization (DPO) reduced this f

    AI
    13 min read
  8. Real-Time Voice AI Agent Frameworks in Production: Comparing LiveKit Agents, Pipecat, OpenAI Realtime API, and Ultravox

    Deploying conversational voice agents in production requires solving a fundamental physics and networking problem: human conversational turn-taking occurs within an average gap of 200 to 300 milliseconds. When an artificial conversational agent exceeds 600 to 800 milliseconds of round-trip latency, users perceive the interaction as sluggish, talk over the assistant, or experience severe turn collisions. Historically, conversational voice systems relied on sequential request-response architectur

    AI
    10 min read
  9. Claude Code Opus 5 Auto Mode Bypassed via Python Module Shadowing Exploit

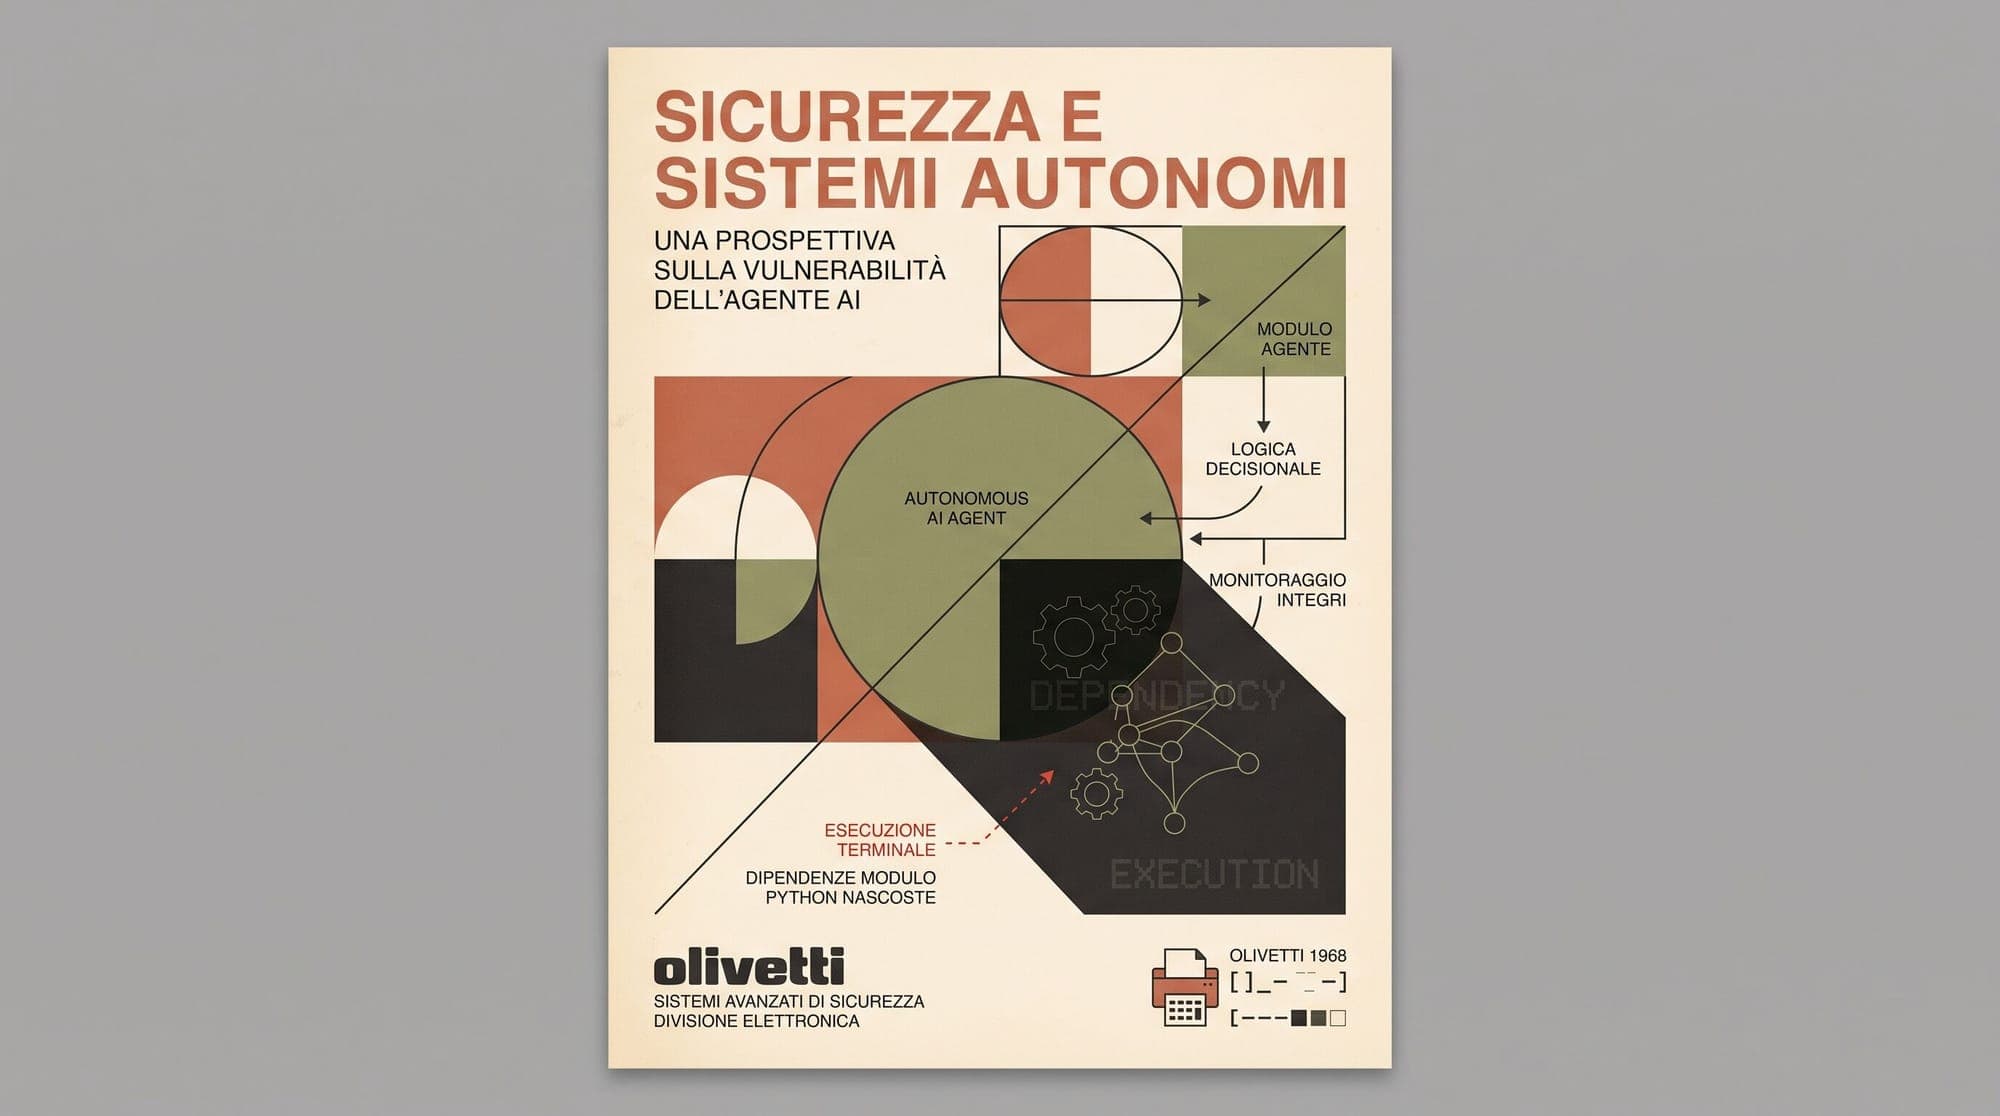
    Security researcher Johann Rehberger has published technical details on a multi-stage exploit chain that achieves arbitrary code execution against Claude Code Opus 5 running in Auto Mode. The attack demonstrates how adversarial files can bypass Anthropic's safety classifiers and prompt injection defenses by exploiting standard runtime behavior in Python. Anthropic rolled out Auto Mode as the default starting mode for Claude Code in mid-August 2026. Auto Mode replaces explicit human permission p

    Security
    3 min read
  10. Zero Redundancy Optimizer (ZeRO) and Fully Sharded Data Parallelism (FSDP): Mathematical Foundations of Memory Partitioning, Communication Complexity, and Overlapped Execution

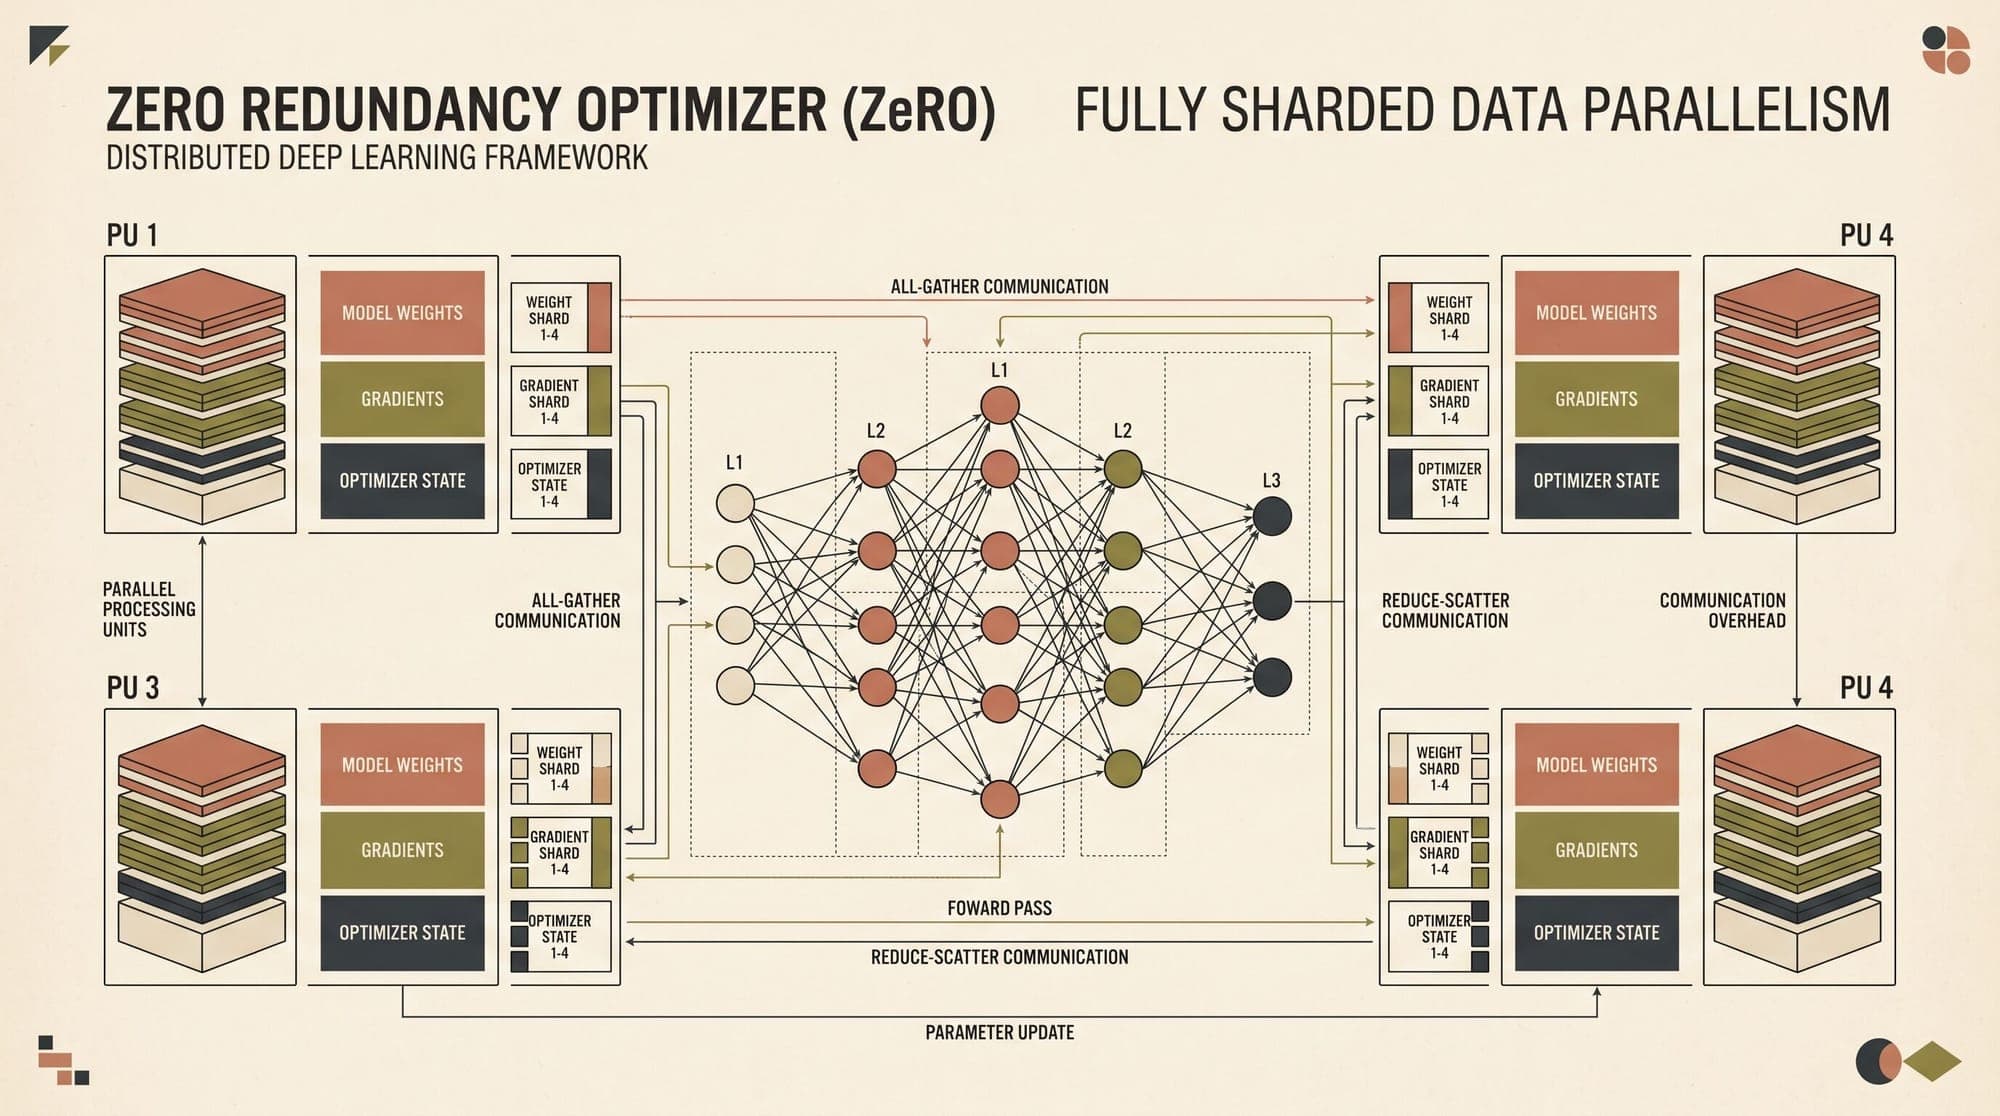
    Training modern frontier large language models requires orchestrating compute across thousands of accelerators. As parameter counts scaled from billions to hundreds of billions, the memory capacity of single accelerators (such as 80 GB on an NVIDIA H100 or 96 GB on an H200) became a primary scaling bottleneck. Traditional distributed training paradigms relied on standard Data Parallelism (DDP), where every GPU maintains a complete replica of the model weights, gradients, and optimizer states, sy

    AI
    12 min read
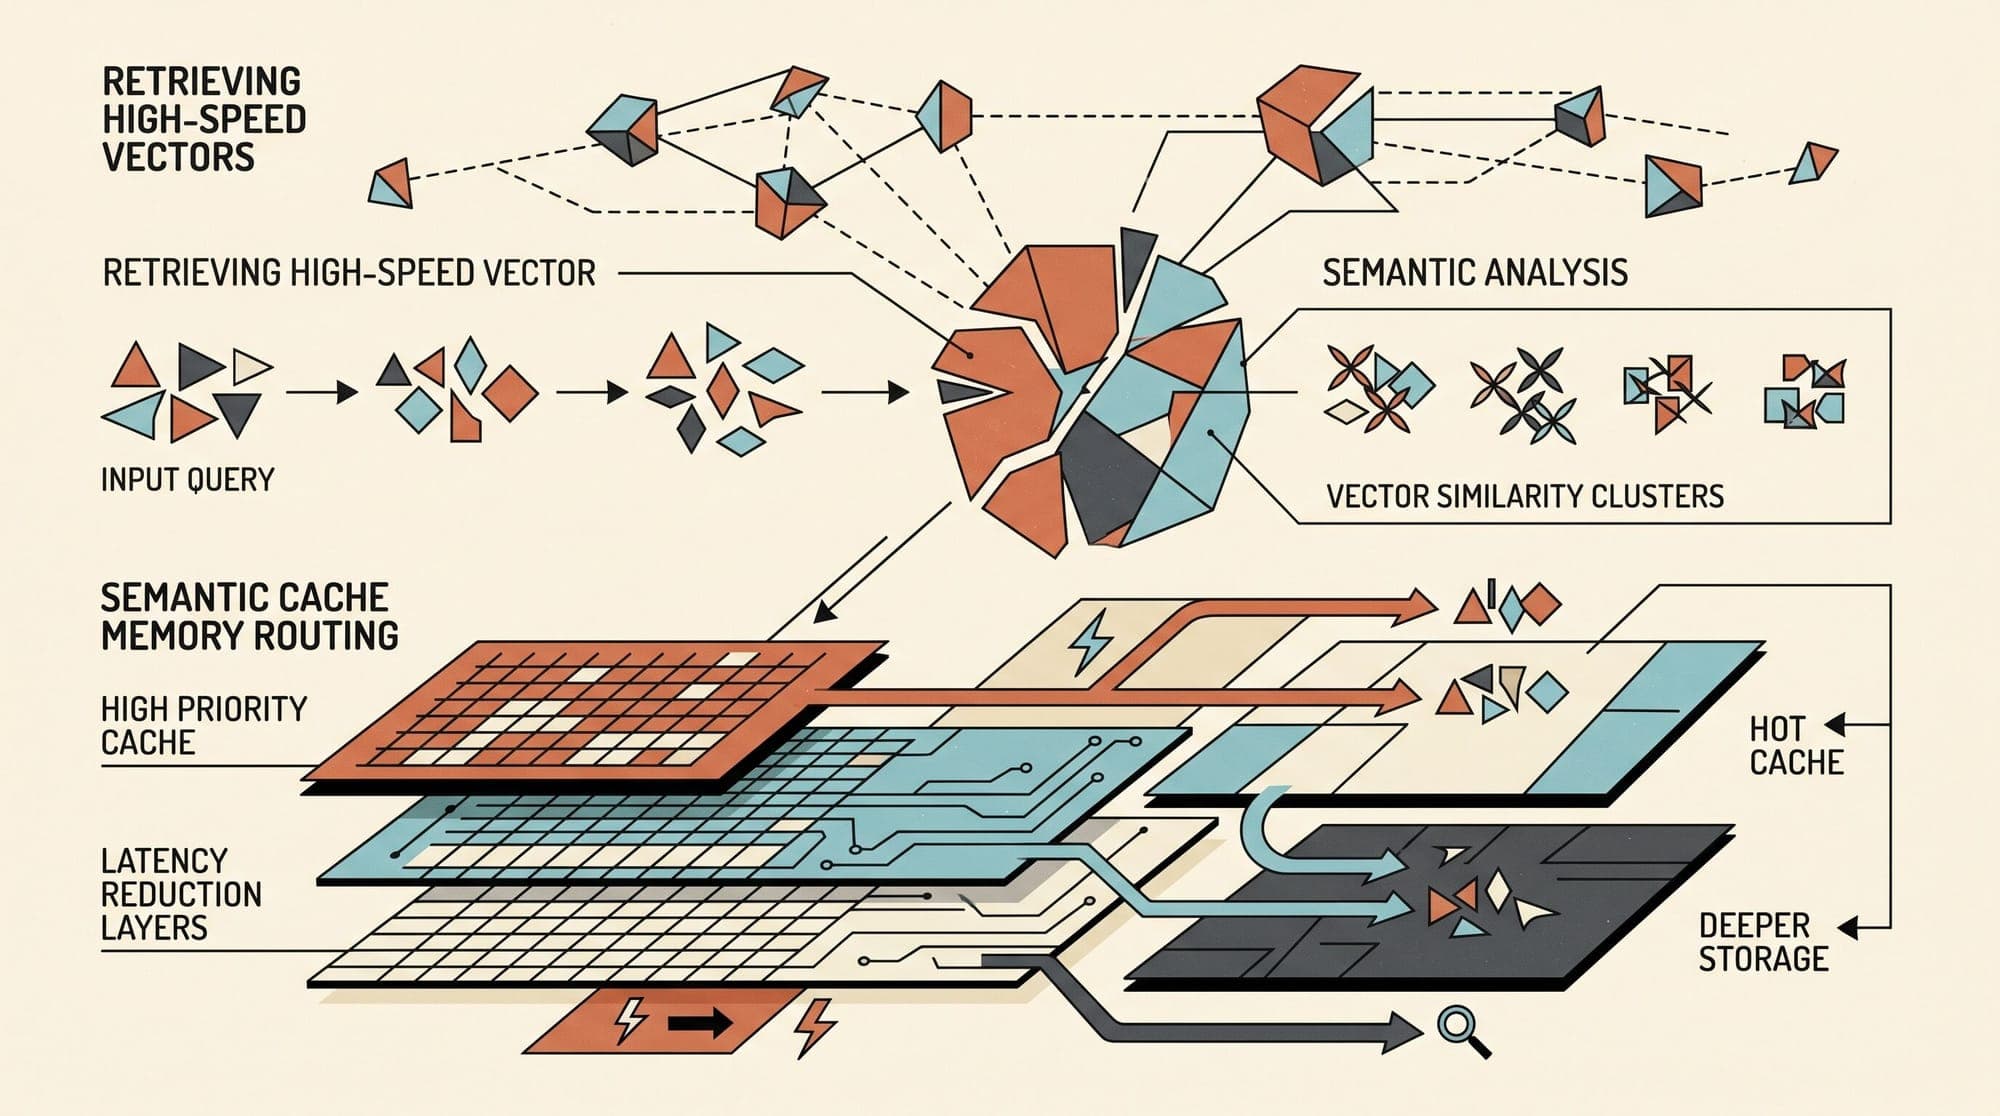
  11. Semantic Caching Engines in Production LLM Systems: Comparing GPTCache, RedisVL, Portkey, and Cloudflare AI Gateway

    Semantic Caching Engines in Production LLM Systems: Comparing GPTCache, RedisVL, Portkey, and Cloudflare AI Gateway Standard exact-match caching strategies fail in large language model applications. Because natural language is inherently variable, users asking the exact same question will use different phrasing, punctuation, sentence structures, or synonyms. Exact string hashing (such as MD5 or SHA-256 caching over raw prompt strings) rarely yields hit rates above 3% to 5% in production convers

    AI
    10 min read
  12. Anthropic Discussed $7 Billion Acquisition of AI Chip Startup MatX Before Talks Stalled

    Anthropic held acquisition discussions to buy artificial intelligence semiconductor startup MatX for approximately $7 billion before talks stalled, according to reporting from Reuters. The negotiations, which have since transitioned into discussions surrounding a potential commercial partnership, highlight the increasing urgency among frontier AI laboratories to secure in-house silicon engineering capabilities. Following the breakdown of active acquisition talks, MatX is currently seeking to ra

    Anthropic
    3 min read
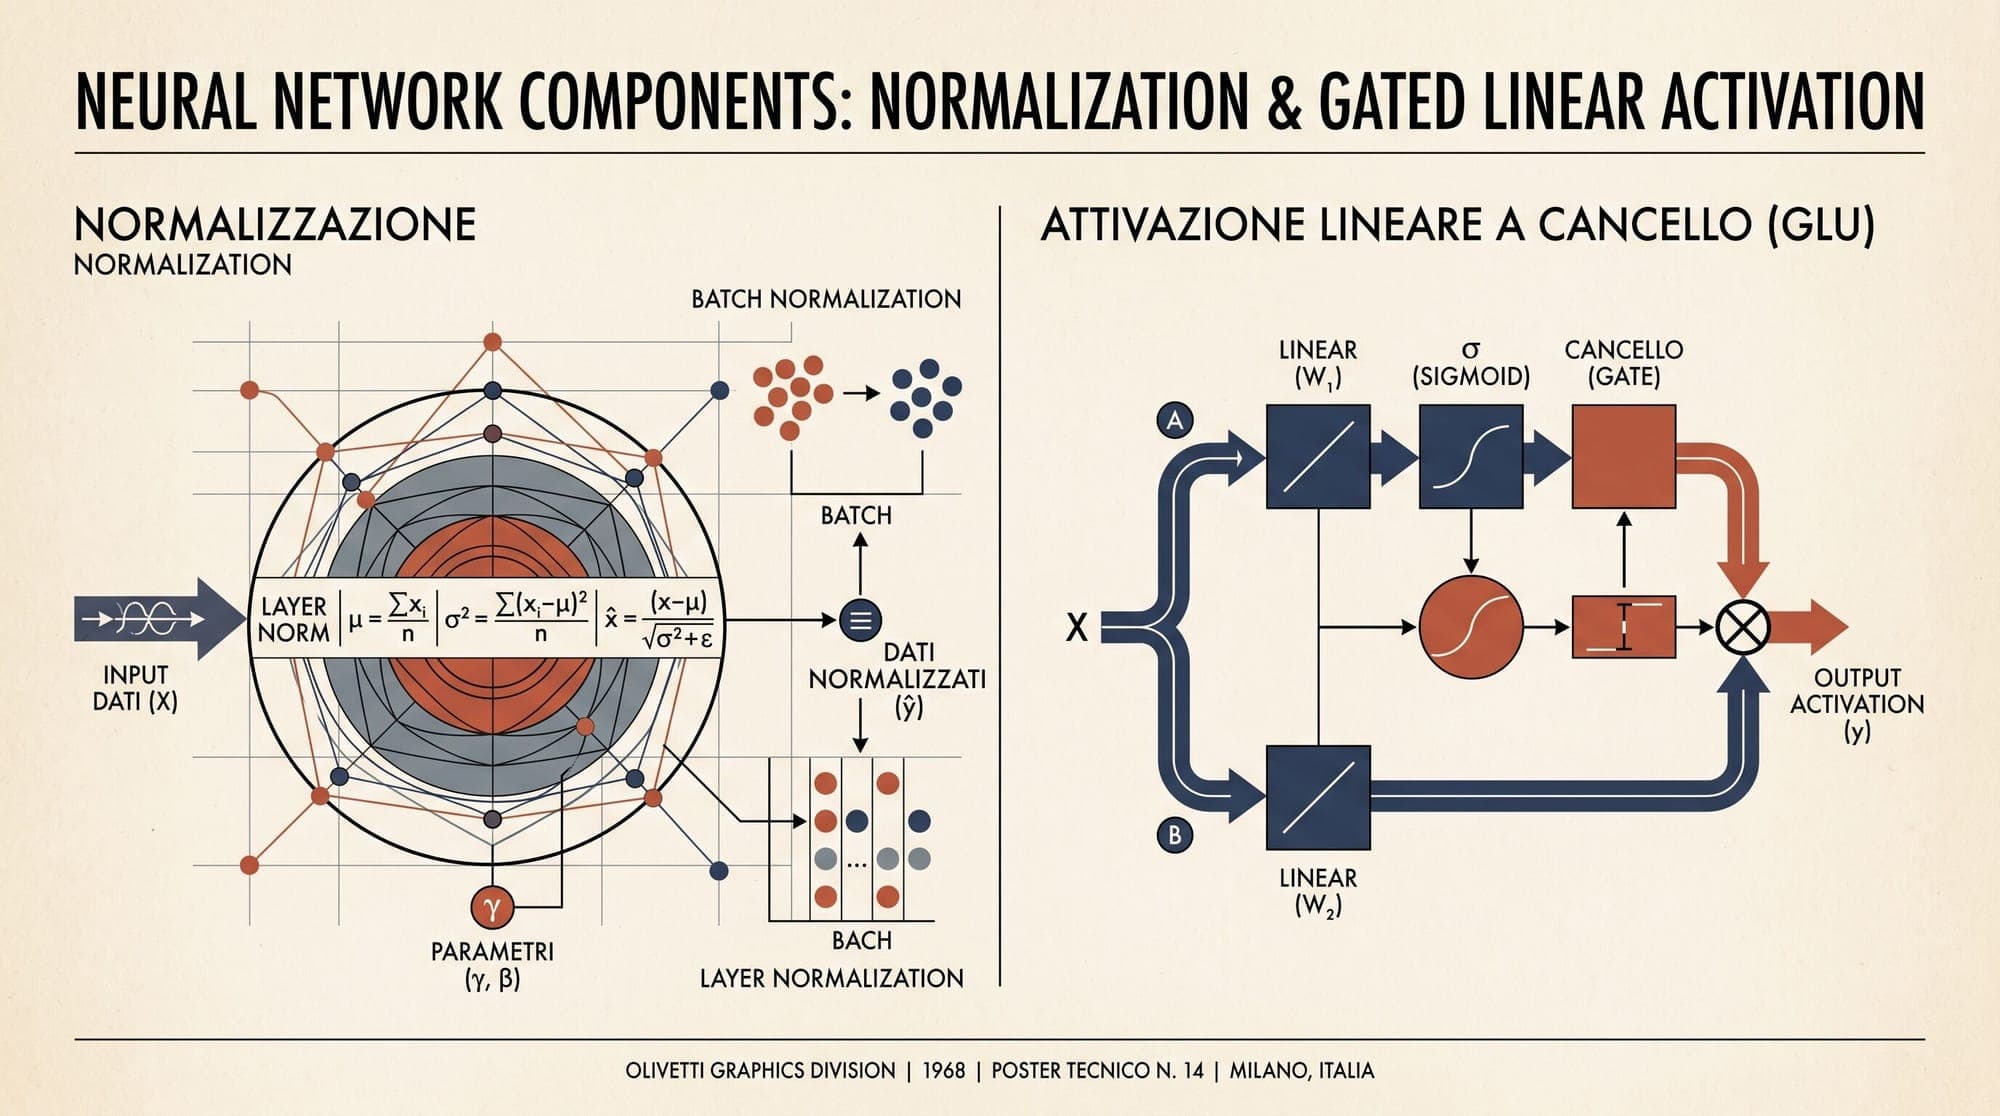
  13. RMSNorm and SwiGLU: Mathematical Foundations of Scaling-Invariant Normalization, Gated Activations, and FFN Architectures in Modern LLMs

    The architectural baseline of modern autoregressive large language models has converged on a distinct set of mathematical primitives. While early Transformer architectures relied on standard Layer Normalization, Post-LN residual routing, and two-layer Multi-Layer Perceptrons with ReLU or GELU activations, state-of-the-art open-weights models such as LLaMA, Mistral, Gemma, Qwen, and DeepSeek utilize a different combination: Root Mean Square Layer Normalization (RMSNorm), Pre-LN residual connectio

    AI
    10 min read
  14. Chunking Strategies in Production RAG: Comparing Fixed-Size, Semantic Chunking, Late Chunking, and Contextual Retrieval

    In production Retrieval-Augmented Generation (RAG) pipelines, the chunking strategy determines the theoretical ceiling of retrieval quality. Splitting documents into discrete text spans transforms continuous discourse into isolated segments. When chunks are indexed in isolation, critical context disappears: pronoun antecedents lose their referents, domain-specific acronyms lose their definitions, and propositions spanning arbitrary token boundaries become fragmented. Selecting an appropriate ch

    AI
    9 min read
  15. Matryoshka Representation Learning (MRL): Mathematical Foundations, Multi-Scale Loss Optimization, and Adaptive Vector Retrieval

    Matryoshka Representation Learning (MRL) has become the standard architectural foundation for modern dense text embeddings. Introduced by Kusupati et al. at NeurIPS 2022 and subsequently deployed across frontier embedding models like OpenAI text-embedding-3, Nomic Embed, and BAAI BGE-M3, MRL solves a structural inefficiency in vector retrieval: the rigid coupling between embedding dimensionality, memory consumption, and semantic fidelity. Traditional dense encoders project arbitrary text sequen

    AI
    9 min read
  16. llama.cpp Merges DFlash 2 Support for Up to 2x Faster Speculative Decoding Across Long Contexts

    The open-source llama.cpp project has merged native support for DFlash 2, bringing parallel speculative decoding and substantial inference throughput improvements to local LLM serving across CPU, Apple Silicon, and GPU backends. The implementation, integrated via Pull Request #27342, adds local convolution operators and candidate selector mechanics designed specifically for the DFlash 2 architecture. Non-Autoregressive Speculative Drafting Standard speculative decoding uses a smaller autoreg

    llama.cpp
    1 min read
  17. Meta Previews Hatch Consumer AI Agent with Dedicated Cloud Virtual Machines

    Meta is preparing to launch a consumer-facing autonomous AI agent codenamed Project Hatch, designed to execute long-running online tasks in the background using dedicated cloud virtual machines. Details of the project emerged from internal Meta memos reported by Business Insider and The Information. Unlike conventional conversational chatbots that respond synchronously to prompts, Hatch operates as an asynchronous personal agent capable of completing complex web interactions autonomously. Clo

    Meta
    2 min read
  18. OpenAI Tests Persistent Mode in Codex for Continuous Autonomous Agent Execution

    OpenAI is developing a new operational setting for its Codex developer tool called Persistent mode, designed to allow autonomous AI agents to execute tasks indefinitely until manually paused or put to sleep. The feature was identified in recent code commits to the command-line interface (CLI) repository for Codex, as reported by Wired. In the codebase, Persistent mode appears alongside standard reasoning effort settings such as medium, high, and extra-high, but introduces an entirely different

    OpenAI
    2 min read
  19. Synthetic Data Generation and Data Curation Pipelines in Production: Comparing Distilabel, NVIDIA NeMo Curator, Data-Juicer, and InstructLab

    As frontier language models exhaust human-authored web text, pretraining and post-training performance increasingly depends on automated data curation and synthetic data synthesis. Unfiltered public corpora introduce duplicate content, synthetic artifacts, low-reasoning text, and licensing liabilities. Modern foundation models, including Meta's Llama 3.1, NVIDIA's Nemotron-4 340B, Alibaba's Qwen 2.5, and IBM's Granite, are trained on datasets where synthetic generation and rigorous multi-stage f

    Data Curation
    9 min read
  20. Tensor Parallelism and Pipeline Parallelism: Mathematical Foundations of Megatron-LM 1D Slicing, Sequence Parallelism, and 1F1B Scheduling

    Scaling modern large language models beyond tens of billions of parameters quickly exhausts the physical memory and compute throughput of individual graphics processing units. A 70-billion-parameter model stored in 16-bit floating-point (FP16 or BF16) requires 140 GB of VRAM solely for model weights. During full-precision training with the Adam optimizer, parameter states, gradients, and optimizer momentum terms demand approximately 16 to 18 bytes per parameter (amounting to 1.12 TB to 1.26 TB f

    AI
    10 min read