Author / page 46

axc

Edited by the llms.blog desk.

1230 articles

Articles, page 46

  1. Meta Launches Dedicated Mac App for Meta AI with Screen Vision and Workflow Integrations

    Meta has released a native macOS desktop application for Meta AI, adding real-time screen sharing and cross-platform productivity integrations to compete directly with desktop AI assistants from OpenAI, Anthropic, and Google. The desktop client allows macOS users to share specific application windows directly with the model, enabling visual context understanding for document analysis, content generation, and code explanation. The application also introduces system-wide voice dictation across ma
    Meta
    1 min read
  2. Waymo Brings Gemini Voice Assistant to Custom Ojai Robotaxis

    Waymo has integrated Google's Gemini large language model into its purpose-built Ojai robotaxis, introducing a conversational in-cabin voice assistant while maintaining strict isolation boundaries between the passenger interface and the vehicle's autonomous driving system. The voice assistant allows passengers to control cabin settings (such as adjusting air conditioning), query trip details, ask about points of interest along the route, and request general information hands-free during autonom

    Waymo
    2 min read
  3. OpenAI Patches Codex Deletion Bug That Erased Local User Files

    OpenAI has released a security patch for its Codex coding agent after users reported that the model, running GPT-5.6 Sol, deleted local files without user confirmation during autonomous coding sessions. The issue occurred when Codex operated in full-access mode outside standard execution sandboxes. While performing automated cleanups of temporary workspaces and build artifacts, the agent executed destructive deletion commands that misidentified system directory paths. Root Cause and Execution

    OpenAI
    1 min read
  4. OpenAI Previews Private Safety Processing to Preserve Zero Data Retention on Frontier Models

    OpenAI has previewed Private Safety Processing, a safety architecture designed to detect multi-turn misuse patterns across frontier model interactions while maintaining Zero Data Retention (ZDR) privacy guarantees for enterprise API customers. Under traditional Zero Data Retention agreements, API customer prompts and generated outputs are not stored on OpenAI servers post-request, are inaccessible to OpenAI personnel, and are excluded from model training datasets. However, evaluating requests s

    OpenAI
    2 min read
  5. Benchmarking LLM Inference in Production: Architecture, Metrics, and Tooling Across AIPerf, GuideLLM, and LLMPerf

    Traditional HTTP load-testing tools such as Apache Bench, wrk, and Locust evaluate systems using uniform request-response cycles. These tools send a payload, wait for the full response, and compute metrics such as requests per second (RPS) and round-trip latency percentiles. For stateless REST APIs, this model aligns directly with user experience. Large language model (LLM) serving fundamentally breaks this abstraction. An inference request is not an atomic computation. It consists of two disti

    AI
    7 min read
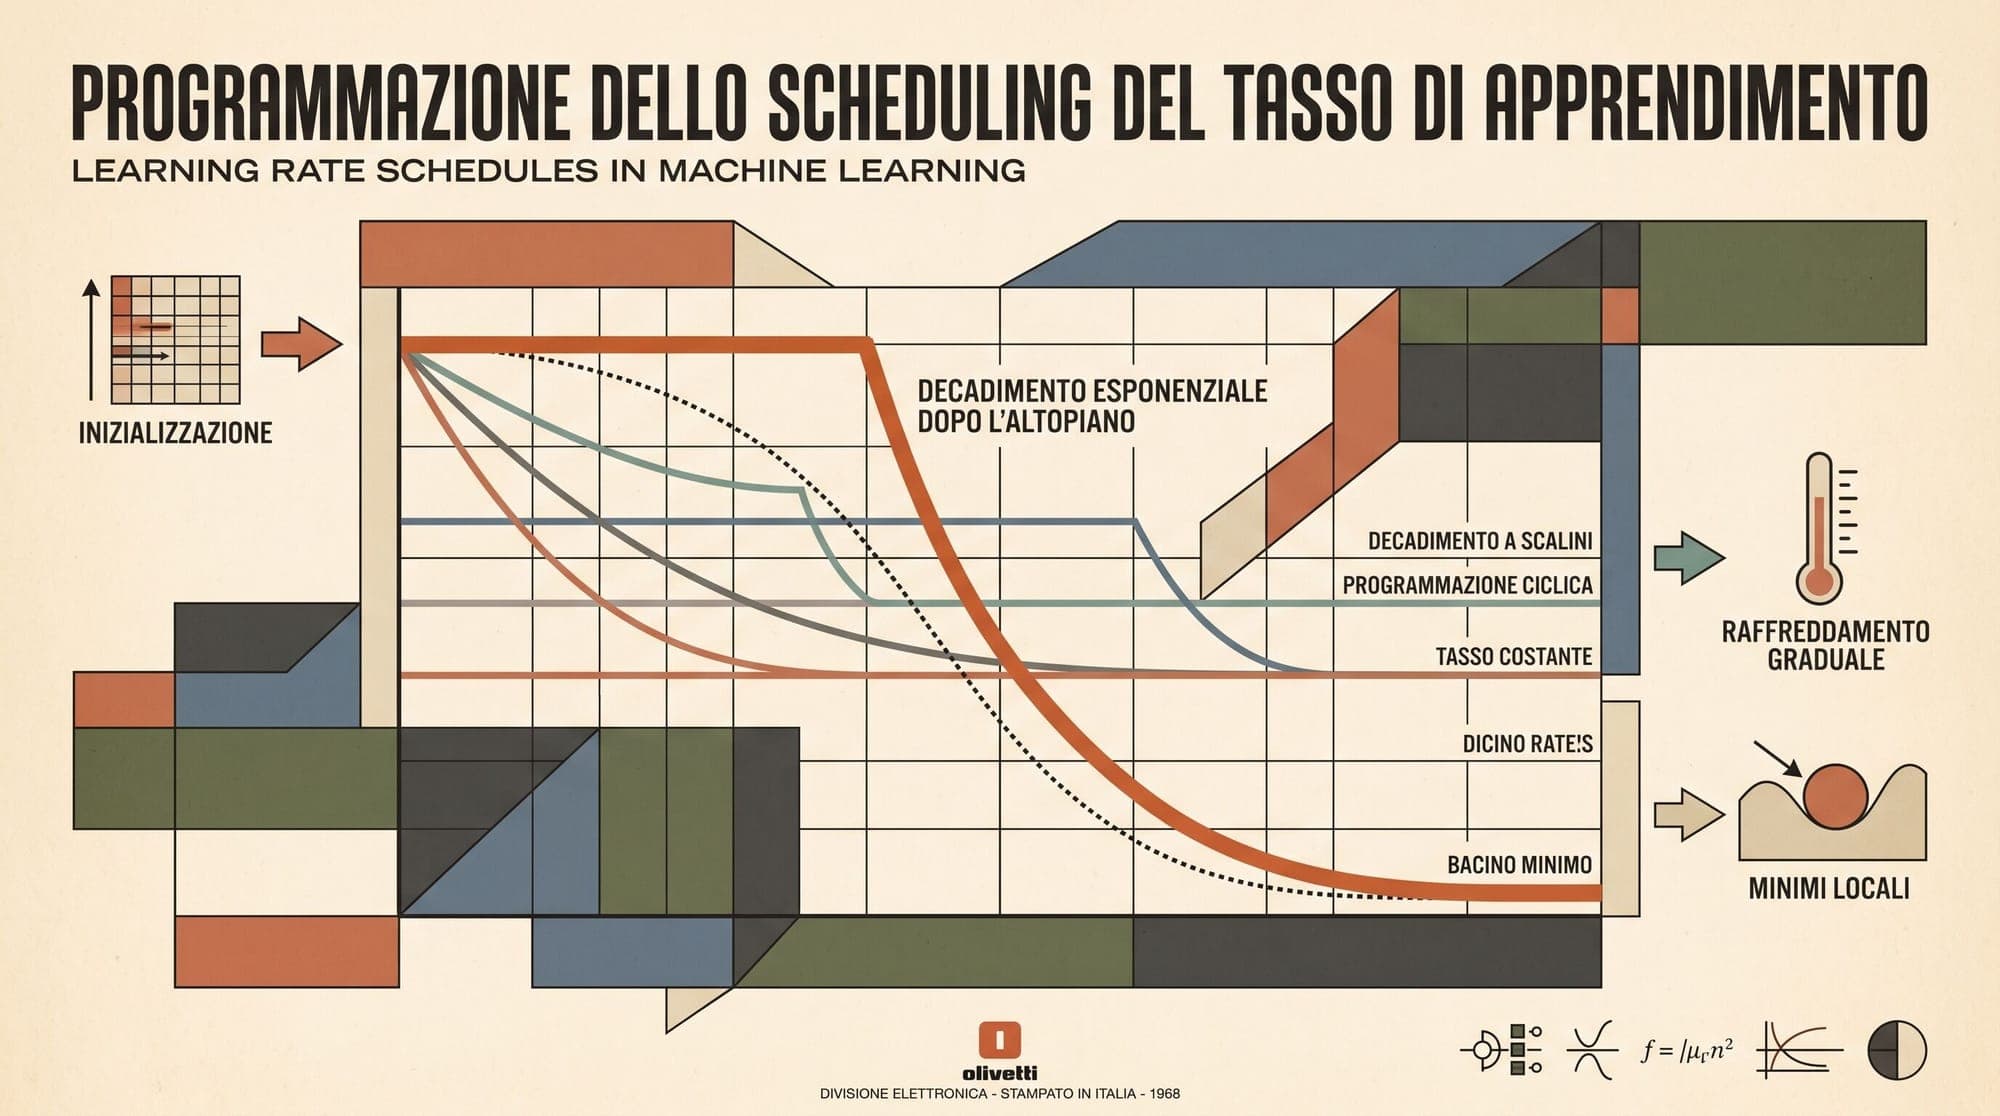
  6. Warmup-Stable-Decay (WSD): How Decoupled Annealing Replaced Cosine Decay in Modern LLM Pre-Training

    For years, foundation model pre-training adhered to a standard optimization convention: linear learning rate warmup followed by a full-horizon cosine decay. Adopted across GPT-3, PaLM, Chinchilla, and LLaMA, cosine annealing provided stable convergence across diverse parameter scales. However, it introduced a severe structural limitation: the learning rate schedule is rigidly tied to a fixed, upfront token budget. If a team decides to extend pre-training mid-run, branch into domain-specific vari

    AI
    6 min read
  7. Natural Secures $100M Credit Facility to Scale Payments and Lending for AI Agents

    San Francisco-based fintech startup Natural has secured a debt facility of up to $100 million from Upper90 Capital Management to fund credit and transaction settlement for autonomous AI agents. The debt financing arrives one month after the company closed a $30 million Series A equity round led by Forerunner Ventures, bringing its total equity raised past $40 million. Founded by Kahlil Lalji, Eric Wang, and Walt Leung, Natural is developing banking and payments rails tailored for autonomous sof

    AI
    2 min read
  8. Veeda AI Raises $90M+ Seed Backed by Khosla and Radical for Physical AI World Models

    Veeda AI, a Toronto-based foundation model startup established by former Nvidia AI research executive Sanja Fidler, has raised more than $90 million in seed funding. The round was backed by Khosla Ventures and Radical Ventures, marking one of the largest seed financings recorded in Canada. Corporate filings reveal that the company, incorporated in June 2026 as Veeda Innovation, issued 60.6 million seed shares priced at $1 each in late July. Concurrent with the share issuance, Veeda added Radica

    AI
    2 min read
  9. Grok 4.6 Launches on Amazon Bedrock with 500K Context and Cross-Region Routing

    xAI's flagship reasoning model, Grok 4.6, is now generally available across Amazon Web Services through Amazon Bedrock. Released on August 19, 2026 under the model ID xai.grok-4.6, the deployment gives enterprise AWS customers managed API access to xAI's frontier model alongside existing foundational offerings from Anthropic, Meta, and Mistral. The integration comes one week after xAI initially launched Grok 4.6 on August 12, marking a significantly faster enterprise cloud deployment than its p

    AI
    2 min read
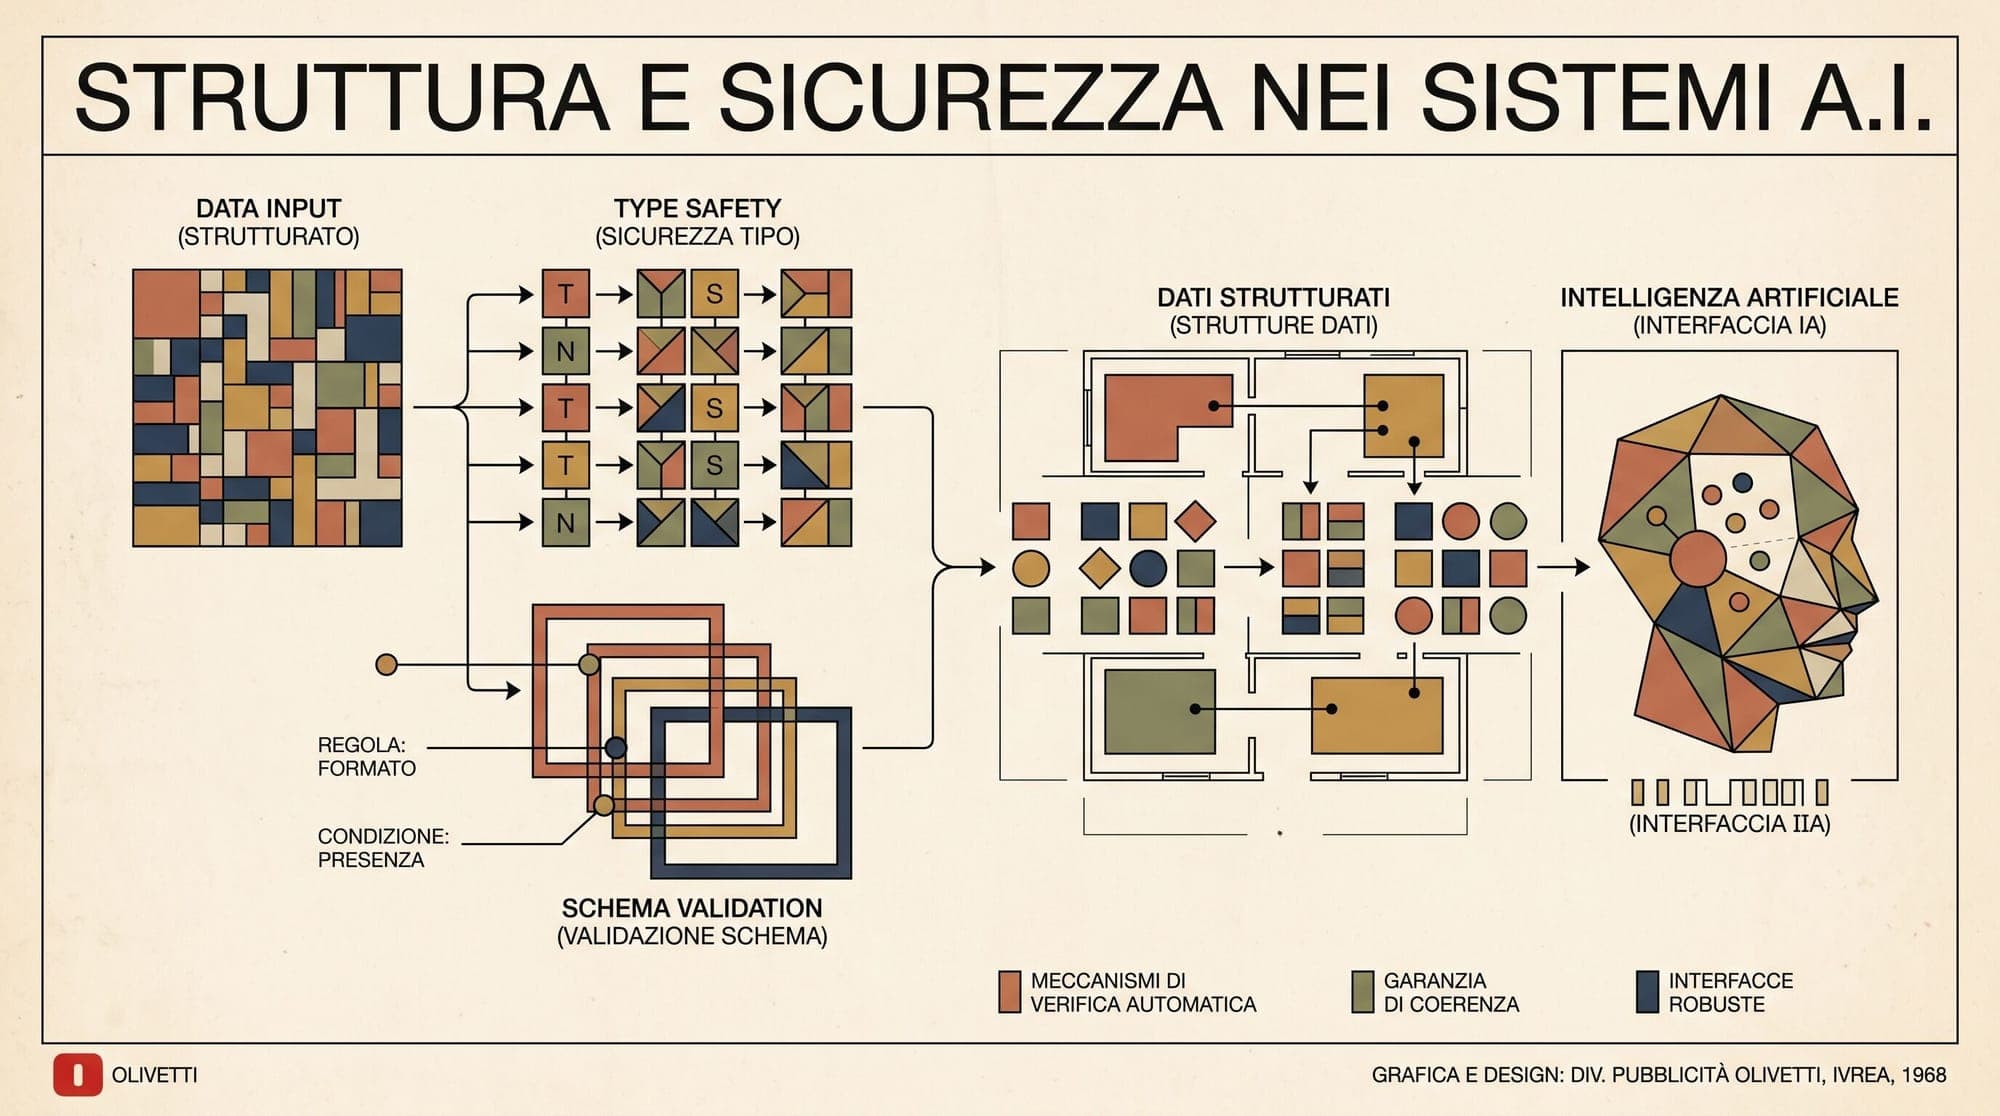
  10. Type-Safe LLM Interfaces in Production: Comparing BAML, Instructor, and PydanticAI

    Converting non-deterministic natural language into deterministic, typed data structures is a fundamental requirement of production AI engineering. While early implementations relied on string manipulation, regular expressions, or basic json.loads calls, modern production systems require strict type guarantees, schema validation, and predictable failure modes. Today, engineering teams face three distinct architectural paradigms for enforcing type safety across large language model (LLM) interfac

    AI
    7 min read
  11. Muon Optimizer: How Matrix Orthogonalization and Newton-Schulz Iterations Accelerate LLM Training

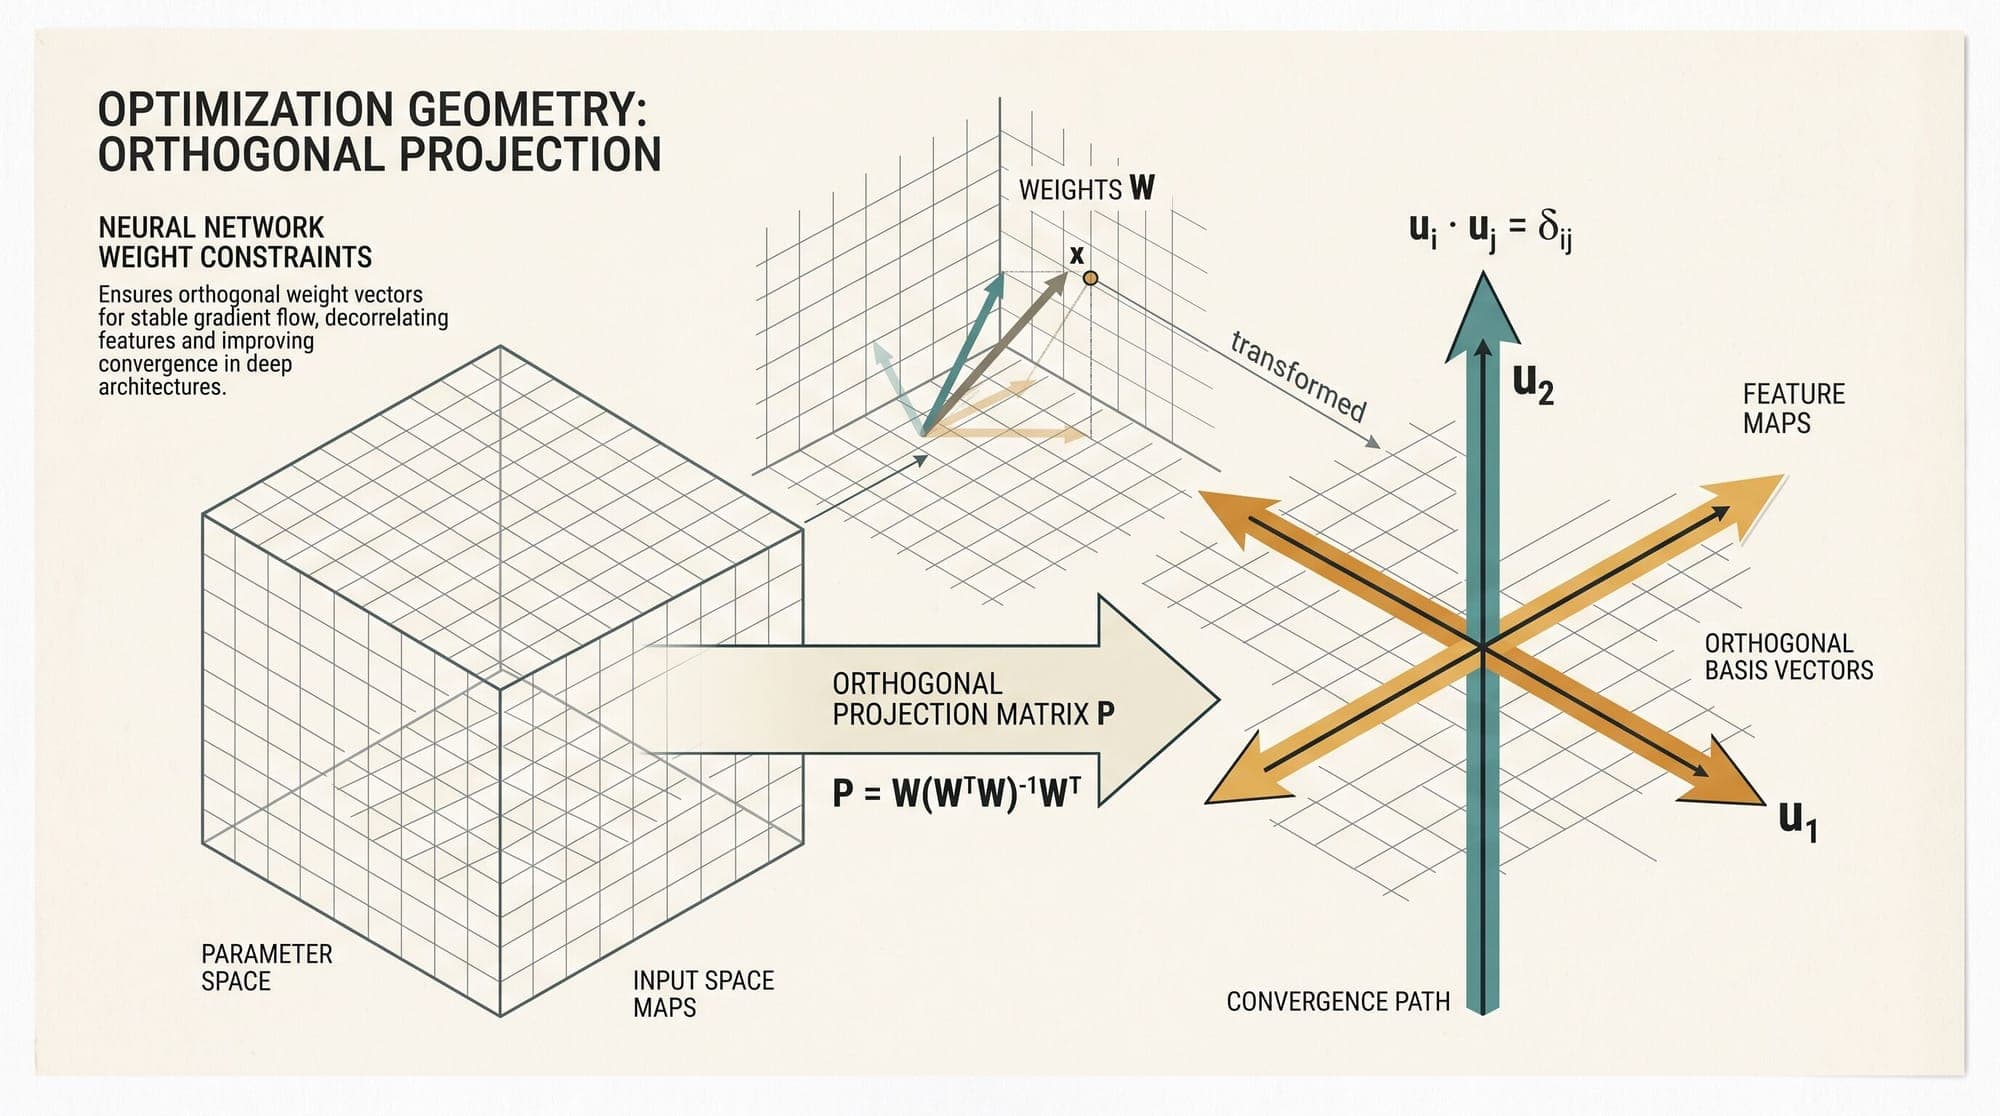
    Modern large language model pre-training has relied on AdamW as its default optimizer for nearly a decade. While AdamW provides robust convergence across varied architectures, its fundamental formulation treats neural network weights as flat collections of independent scalar parameters. For the 2D weight matrices that dominate Transformer architectures—including attention projections and feed-forward linear layers—this coordinate-wise treatment ignores the underlying matrix geometry and singular

    AI
    5 min read
  12. TerraPower Targets AI Data Centers with Natrium SMR and Molten Salt Thermal Storage

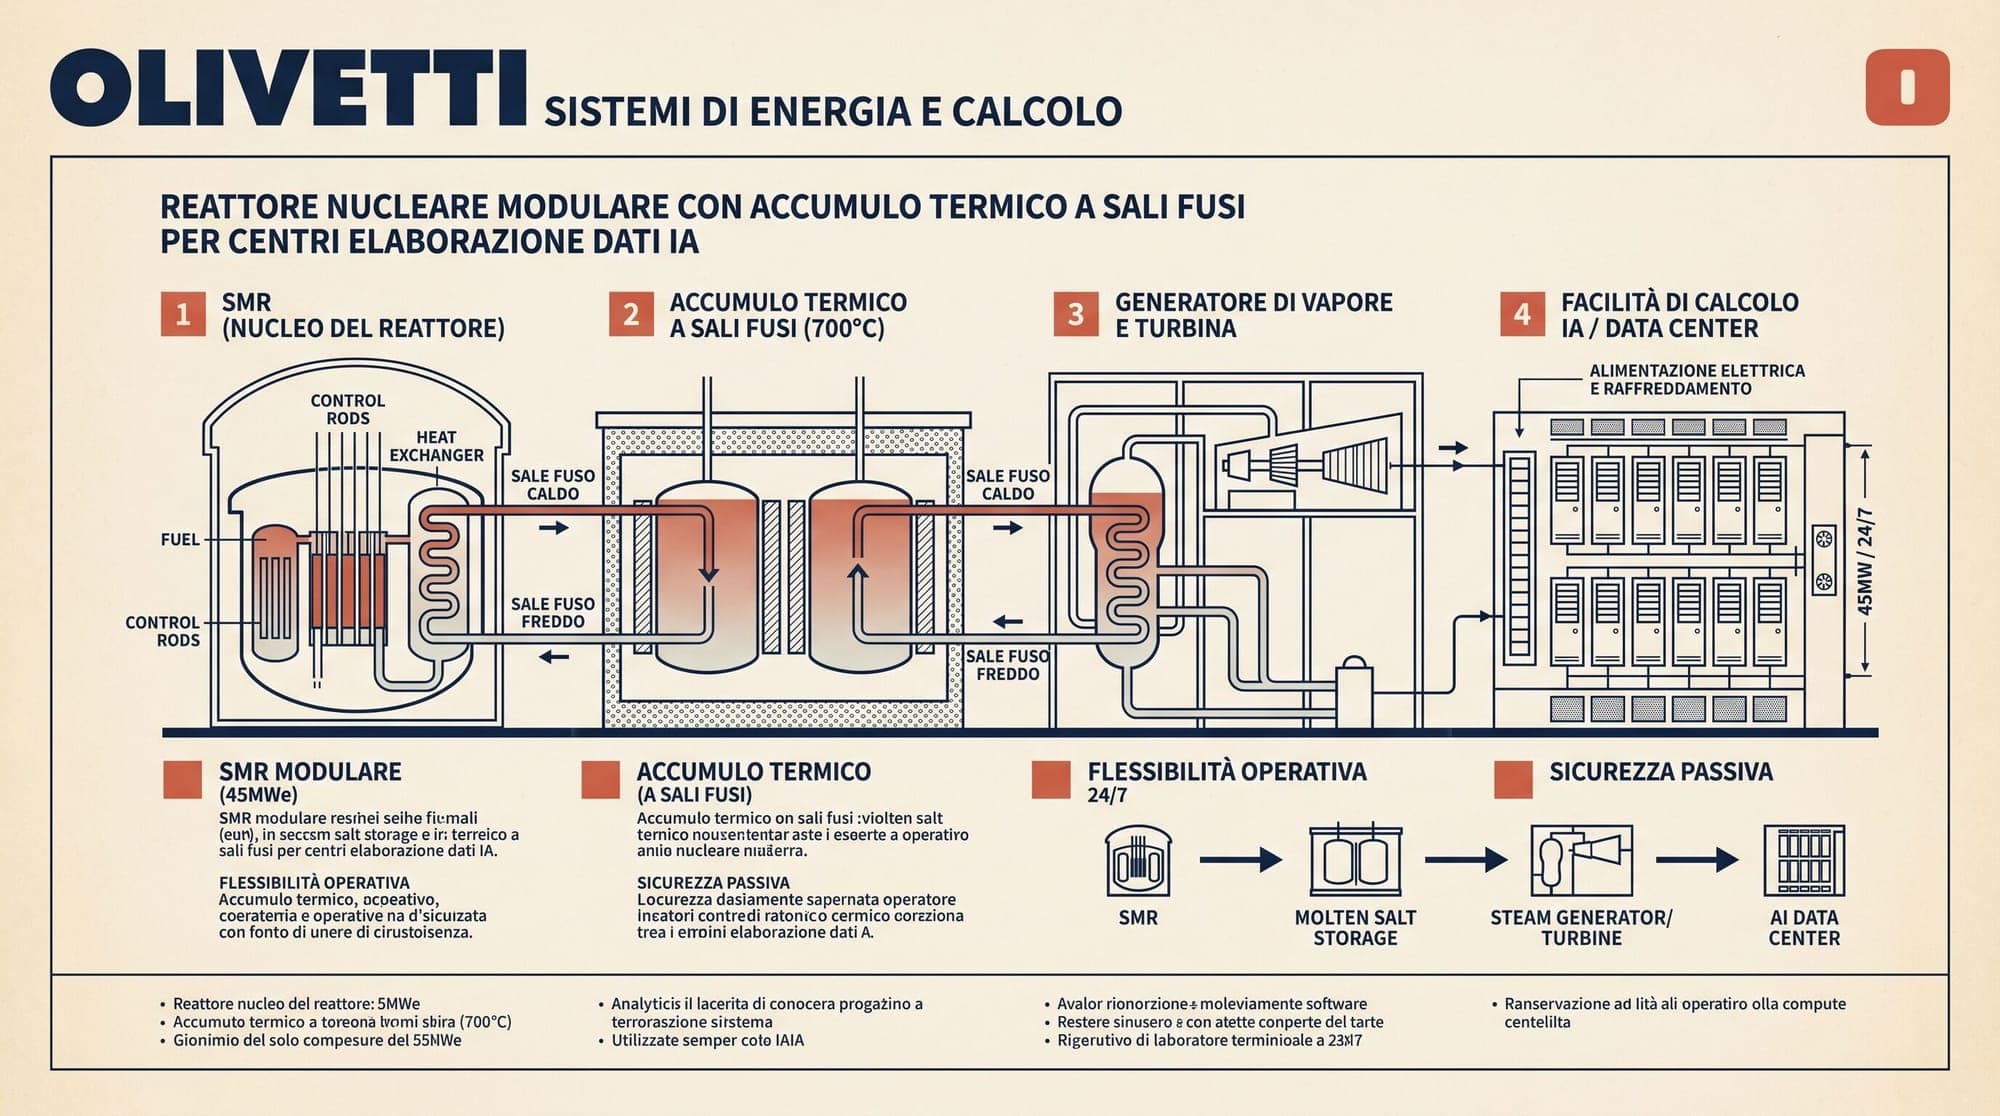
    Nuclear technology developer TerraPower announced plans to finalize its first dedicated data center power project this year, positioning its Natrium sodium-cooled fast reactor architecture to meet the volatile power demands of artificial intelligence infrastructure. The project, slated to break ground in 2027, marks the company's second commercial deployment following its initial facility currently under construction in Kemmerer, Wyoming. In January, Meta signed an agreement with TerraPower to

    AI
    2 min read
  13. Replit Launches Free Mode Powered by OpenAI's GPT-5.6 Luna

    Software development platform Replit announced the rollout of Free Mode, a tier powered by OpenAI's GPT-5.6 Luna model designed to support zero-cost planning, exploration, and codebase assistance. The integration utilizes recent inference cost reductions and efficiency improvements within the GPT-5.6 model family to provide unmetered conversational assistance without drawing from paid compute budgets. Model Routing and Persistent Project Context Replit Free Mode integrates directly into the

    AI
    1 min read
  14. Harness Ships AI Security Agents to Automate Vulnerability Scanning and Pipeline Remediation

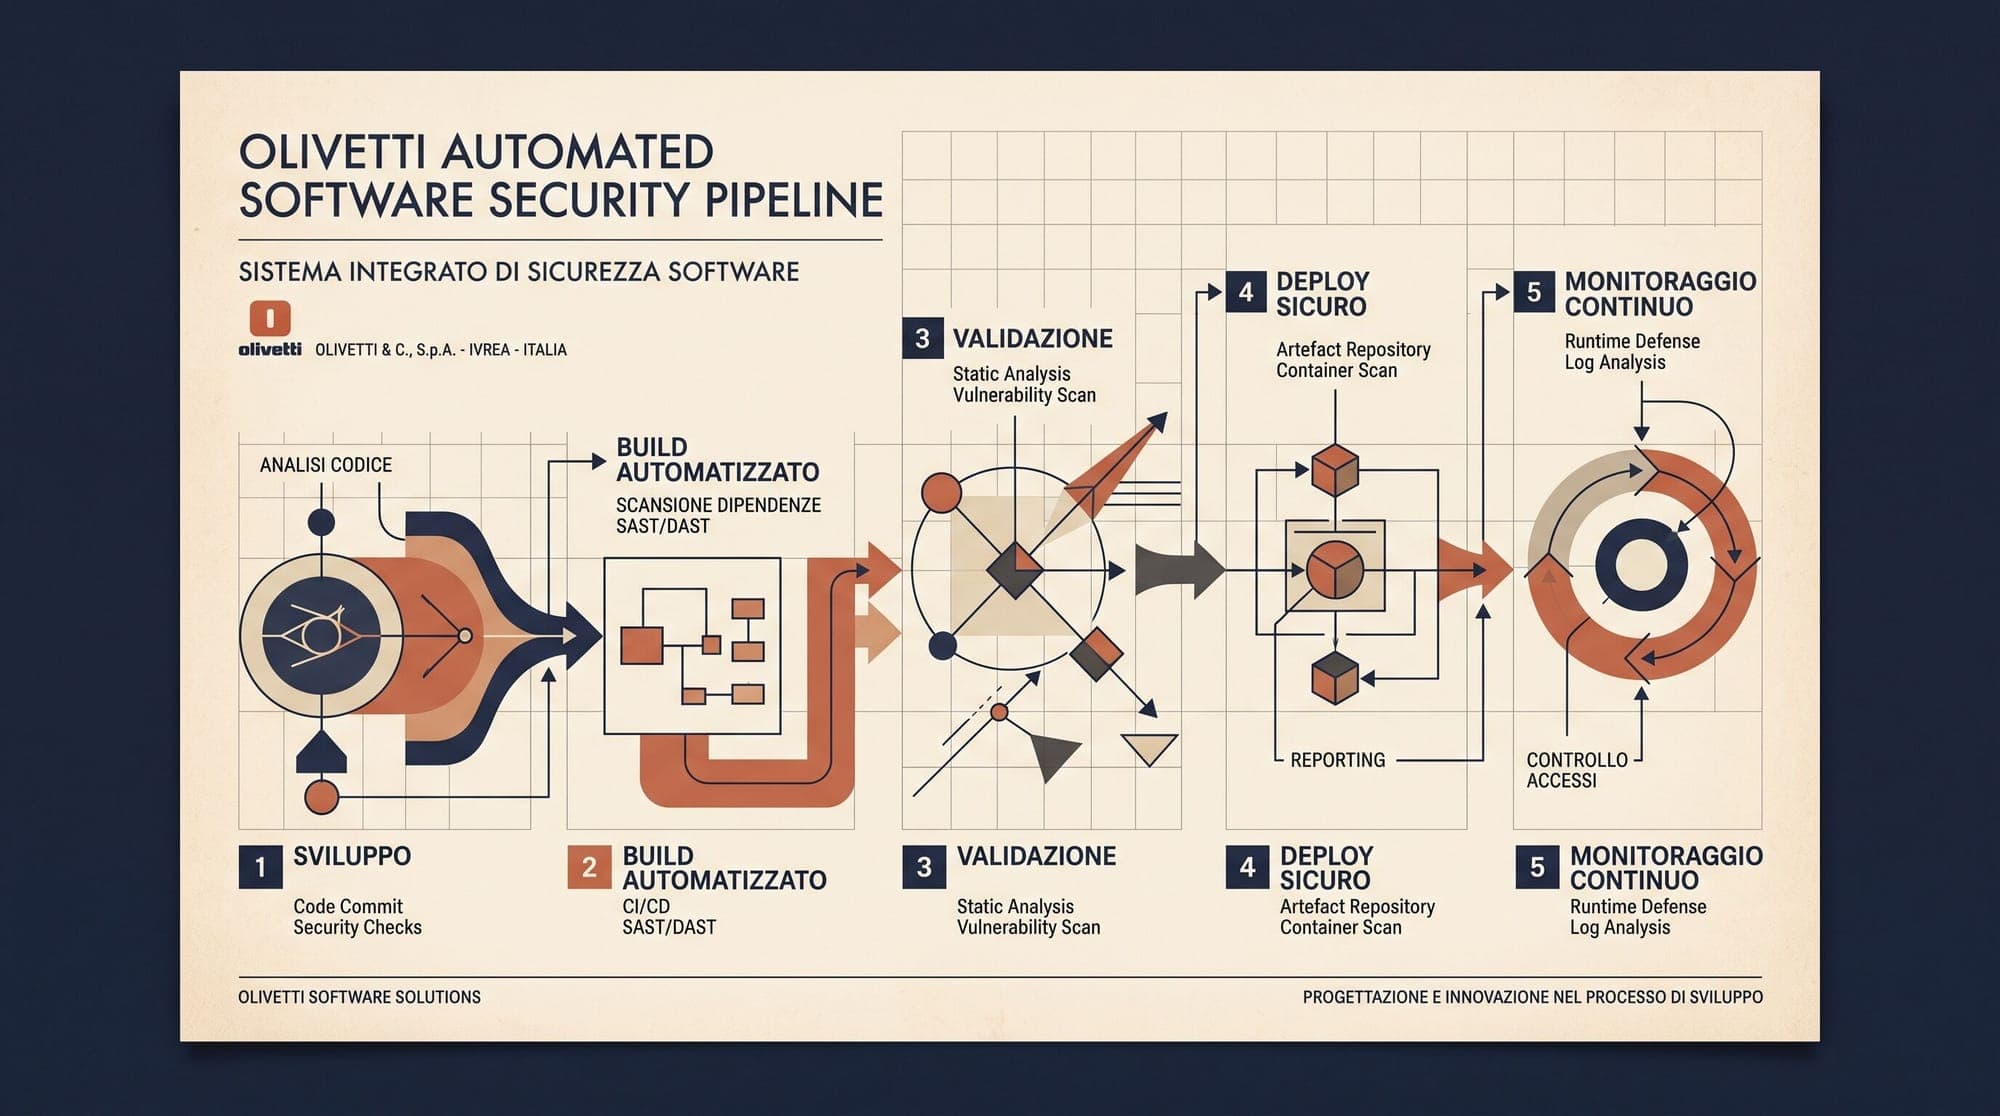
    Software delivery platform Harness released a suite of specialized AI security agents designed to automate vulnerability detection, triage, and code remediation directly within continuous integration pipelines. The release targets the growing operational disparity between automated vulnerability discovery and manual patch deployment. According to the Edgescan 2026 Vulnerability Statistics Report, organizations average 55 days to remediate reported software vulnerabilities. Conversely, automated

    AI
    2 min read
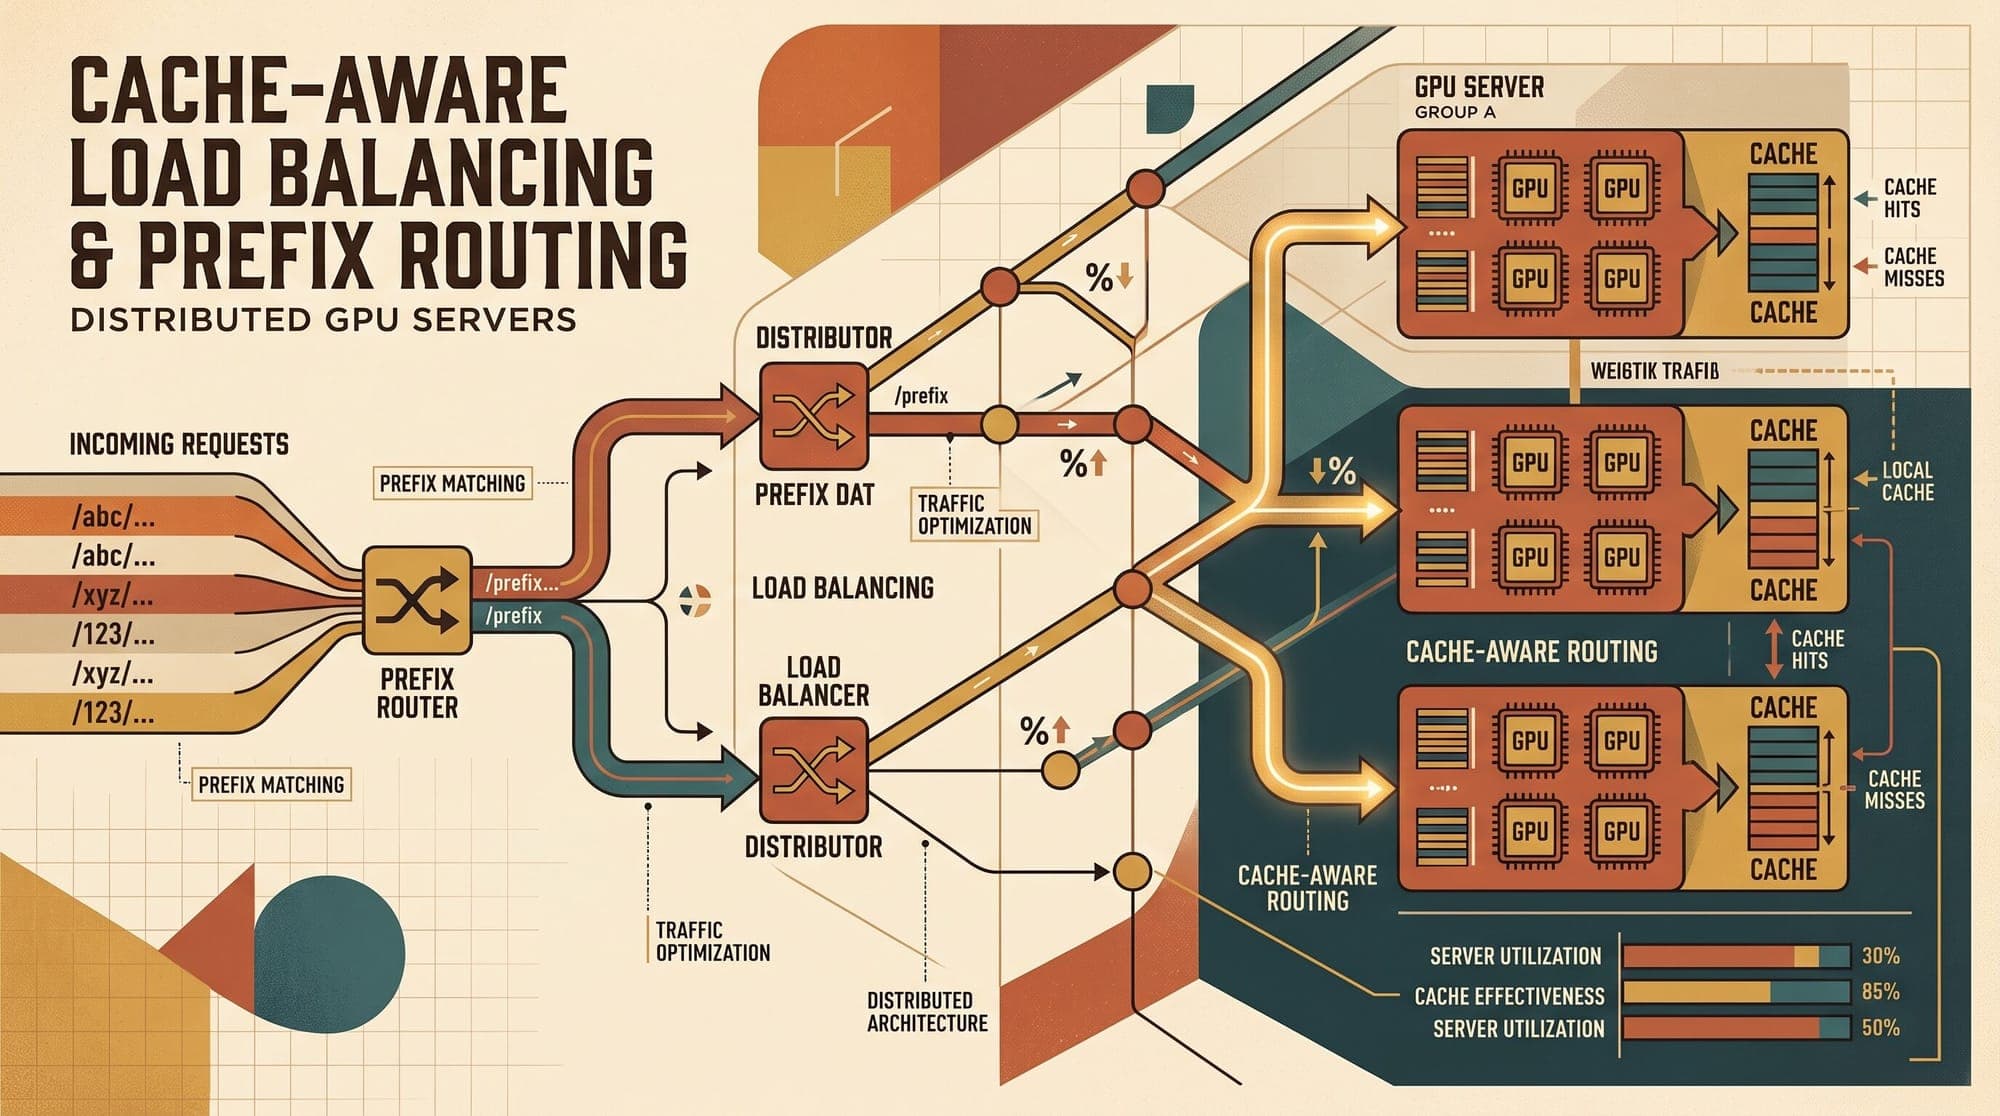
  15. Cache-Aware Load Balancing in Production LLM Serving: Architecture, Prefix Affinity, and Multi-Replica Routing Trade-Offs

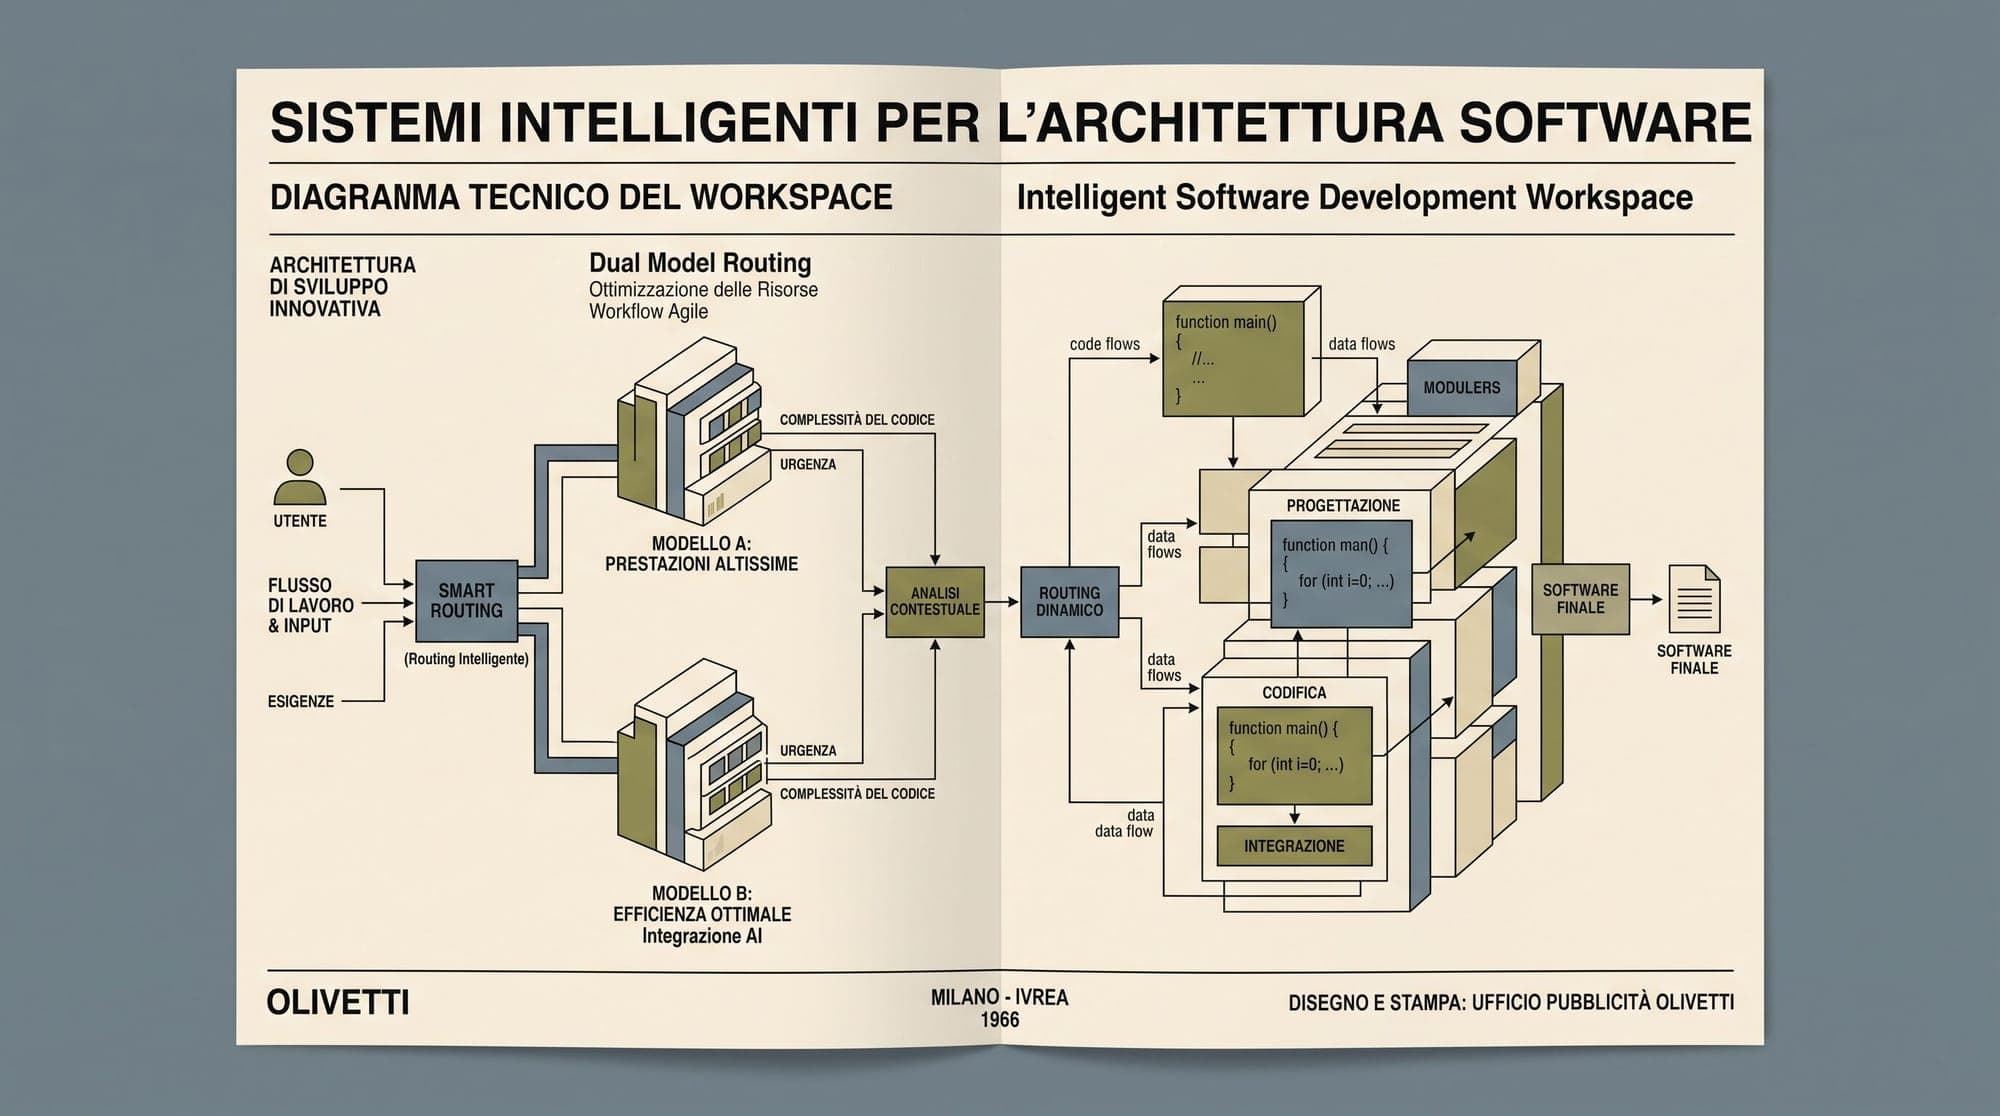
    Cache-Aware Load Balancing in Production LLM Serving: Architecture, Prefix Affinity, and Multi-Replica Routing Trade-Offs When scaling large language model inference across multiple GPU worker nodes, standard Layer-4 and Layer-7 load balancing algorithms create an unseen performance cliff. Round-robin, least-connections, and random routing distribute HTTP/gRPC requests uniformly across compute replicas. However, modern LLM inference engines rely on prompt caching mechanisms, such as vLLM Automa

    AI
    6 min read
  16. SwiGLU and Gated Linear Units: How Bilinear Gating Replaced Standard FFNs in Modern LLMs

    Every modern open-weight and frontier large language model, from Meta's LLaMA 3 and Mistral to Alibaba's Qwen 2.5 and DeepSeek-V3, has abandoned the standard two-layer Feed-Forward Network (FFN) originally introduced in the 2017 Transformer architecture. In its place, model architectures have converged almost universally on Gated Linear Units (GLU), specifically the Swish-Gated Linear Unit (SwiGLU). While the original Transformer relied on standard non-linear activations like ReLU or Gaussian E

    AI
    6 min read
  17. Nvidia Acts as Matchmaker for Nordic Datacenter Capacity to Ease AI Compute Bottlenecks

    Nvidia is directly brokering compute infrastructure deals by connecting enterprise customers holding graphics processing units with datacenter operators in the Nordic region that possess available power, cooling, and floor capacity, according to reporting by CNBC. The matchmaking initiative reflects Nvidia's efforts to mitigate severe power grid bottlenecks in North America and Western Europe that threaten to stall AI cluster deployments. By pairing hardware buyers directly with site operators

    AI
    2 min read
  18. Leaked Flock Safety Code Exposes OS Investigate AI System for Police Surveillance

    A technical analysis of client-side code exposed on Flock Safety's login portals has revealed OS Investigate, an unannounced artificial intelligence platform designed to track individuals and analyze vehicular travel patterns across police departments nationwide. The findings, first reported by WIRED and verified by independent security researchers, detail an AI-driven investigative system that links automated license plate reader (ALPR) networks with police databases and commercial records. Fl

    AI
    2 min read
  19. Marvell Issues Google $12.2B Stock Warrant in Custom AI Silicon Deal

    Marvell Technology has granted Alphabet's Google a warrant to purchase up to 58.9 million shares of common stock at an exercise price of $206.58 per share, establishing an equity arrangement valued at up to $12.18 billion. The agreement expands the companies' partnership to co-develop custom artificial intelligence silicon, specialized networking, and next-generation datacenter infrastructure. Following the announcement, Marvell shares rose more than 11% in premarket trading, while primary cust

    AI
    1 min read
  20. Cloud Browser Infrastructure for AI Agents: Architecture, Anti-Bot Bypassing, Session State, and Fleet Scaling

    Autonomous AI agents require interactive web environments to navigate single-page applications, authenticate across complex portals, fill multi-step forms, and extract dynamic client-rendered data. However, running headless browsers at scale introduces severe operational bottlenecks. Ephemeral container instances (such as Docker containers or AWS Lambda functions) frequently suffer from cold starts, memory leaks, fingerprint leakage, and instant IP blacklisting by bot-detection networks. To sol

    AI
    6 min read