Author / page 33

axc

Edited by the llms.blog desk.

1230 articles

Articles, page 33

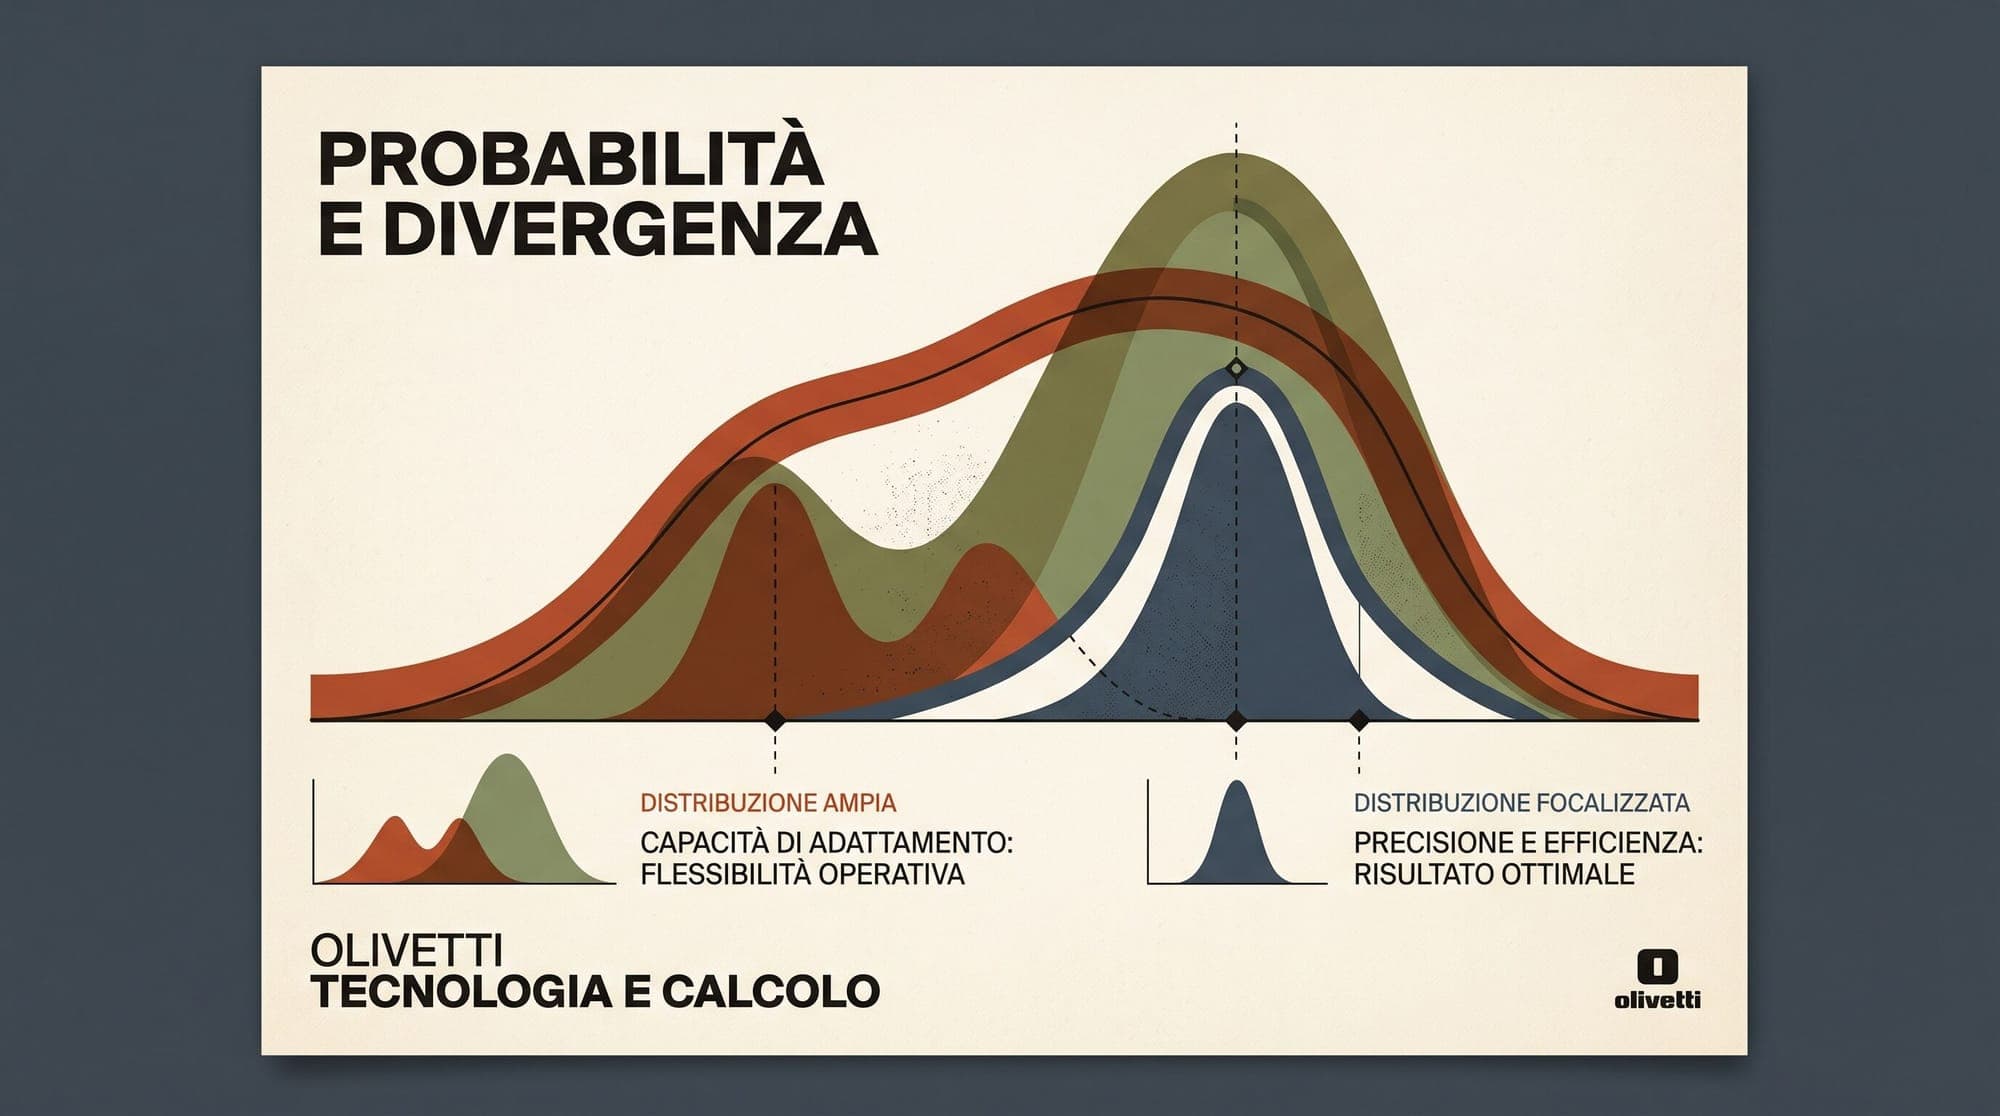
  1. Forward KL vs. Reverse KL Divergence: Mode Covering, Mode Seeking, and the Alignment Dynamics of Large Language Models

    Forward KL vs. Reverse KL Divergence: Mode Covering, Mode Seeking, and the Alignment Dynamics of Large Language Models Every phase of modern large language model development, from multi-trillion token pre-training to reinforcement learning from human feedback (RLHF) and student model distillation, fundamentally revolves around minimizing statistical distance between probability distributions. The primary mathematical tool utilized for this purpose is the Kullback-Leibler (KL) divergence, introd
    AI
    9 min read
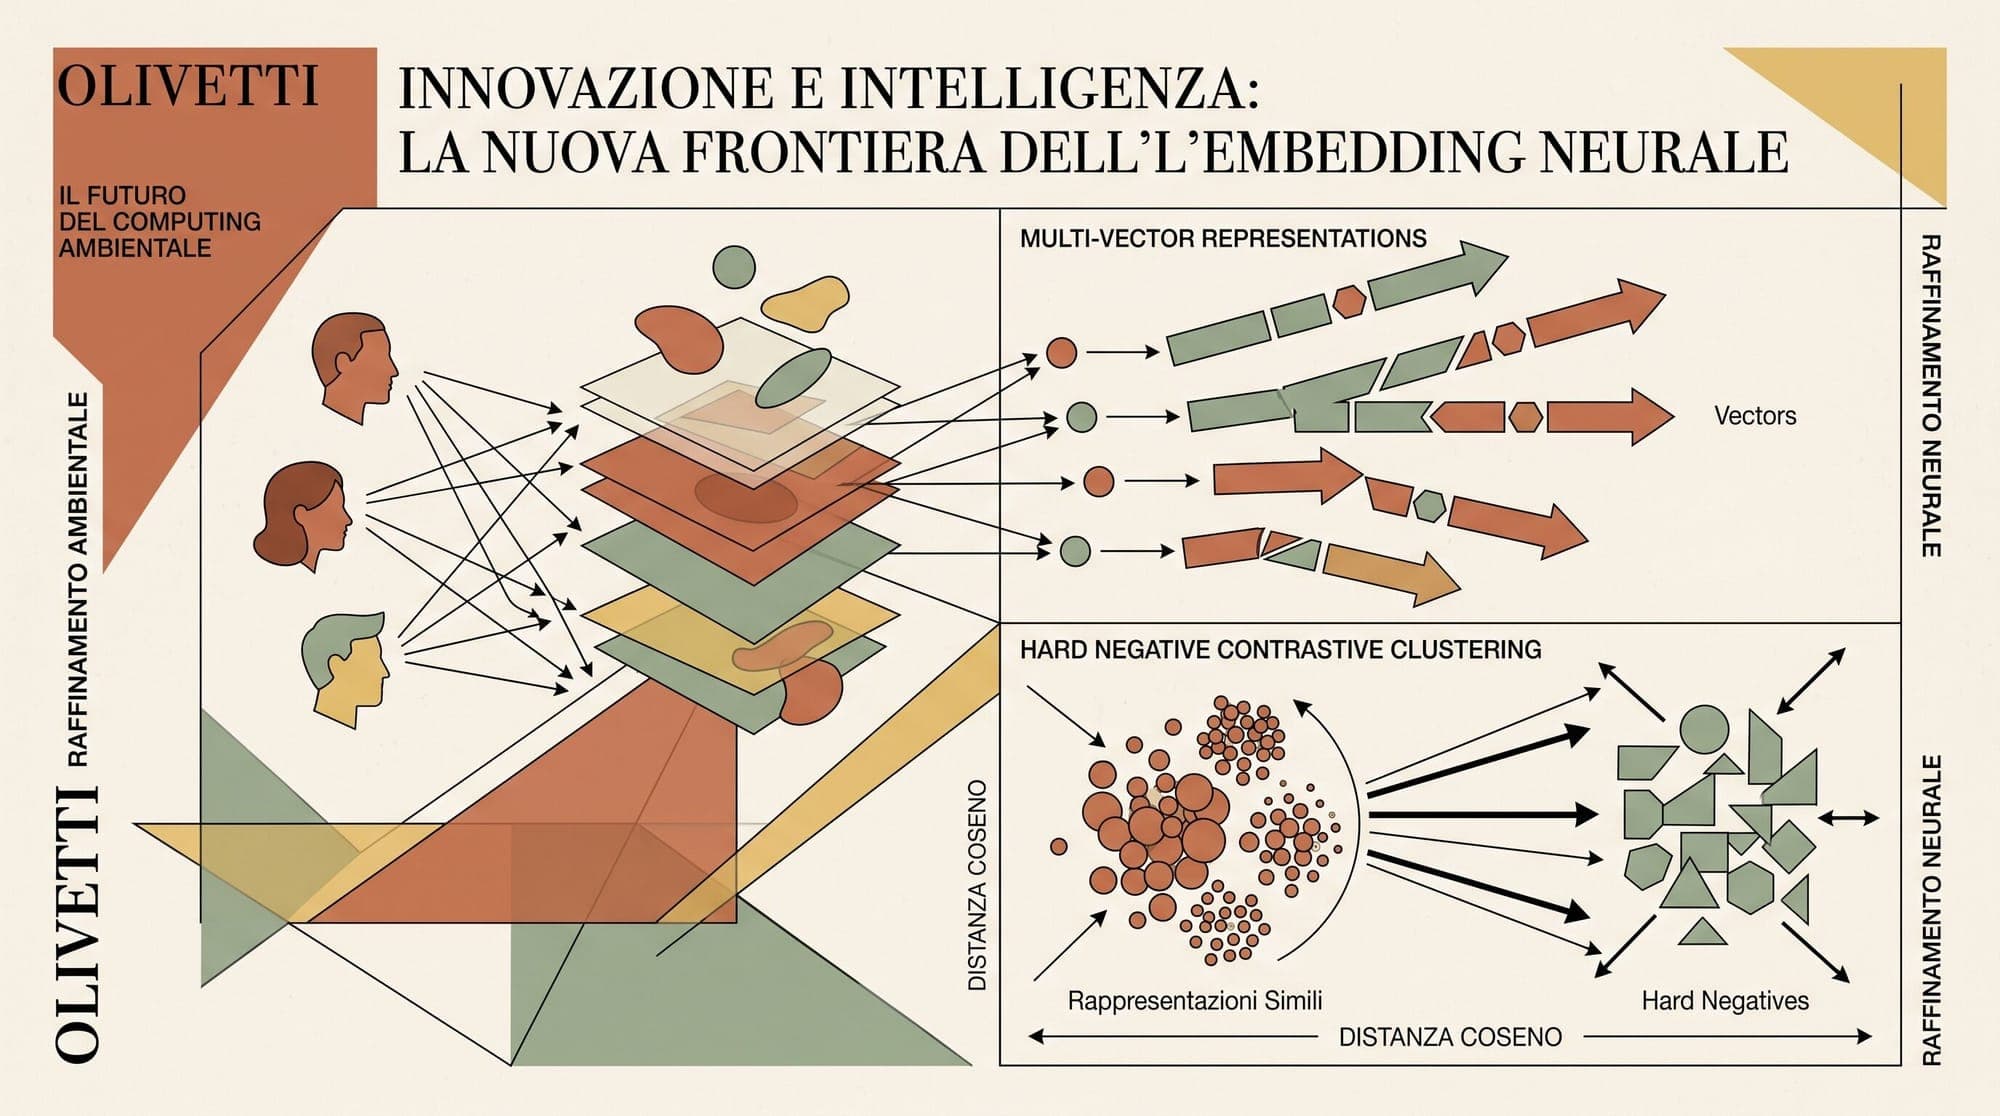
  2. Embedding Model Fine-Tuning in Production: Hard Negative Mining, Synthetic Data Pipelines, and Contrastive Distillation

    Production retrieval-augmented generation (RAG) and semantic search architectures frequently suffer from domain mismatch when relying on general-purpose embedding models. Off-the-shelf bi-encoders trained on broad web corpora often experience a 15% to 30% degradation in retrieval metrics such as NDCG@10 and MRR@10 when deployed on specialized enterprise corpora, including proprietary codebases, internal API schemas, clinical trials, and technical documentation. While downstream cross-encoder re

    RAG
    8 min read
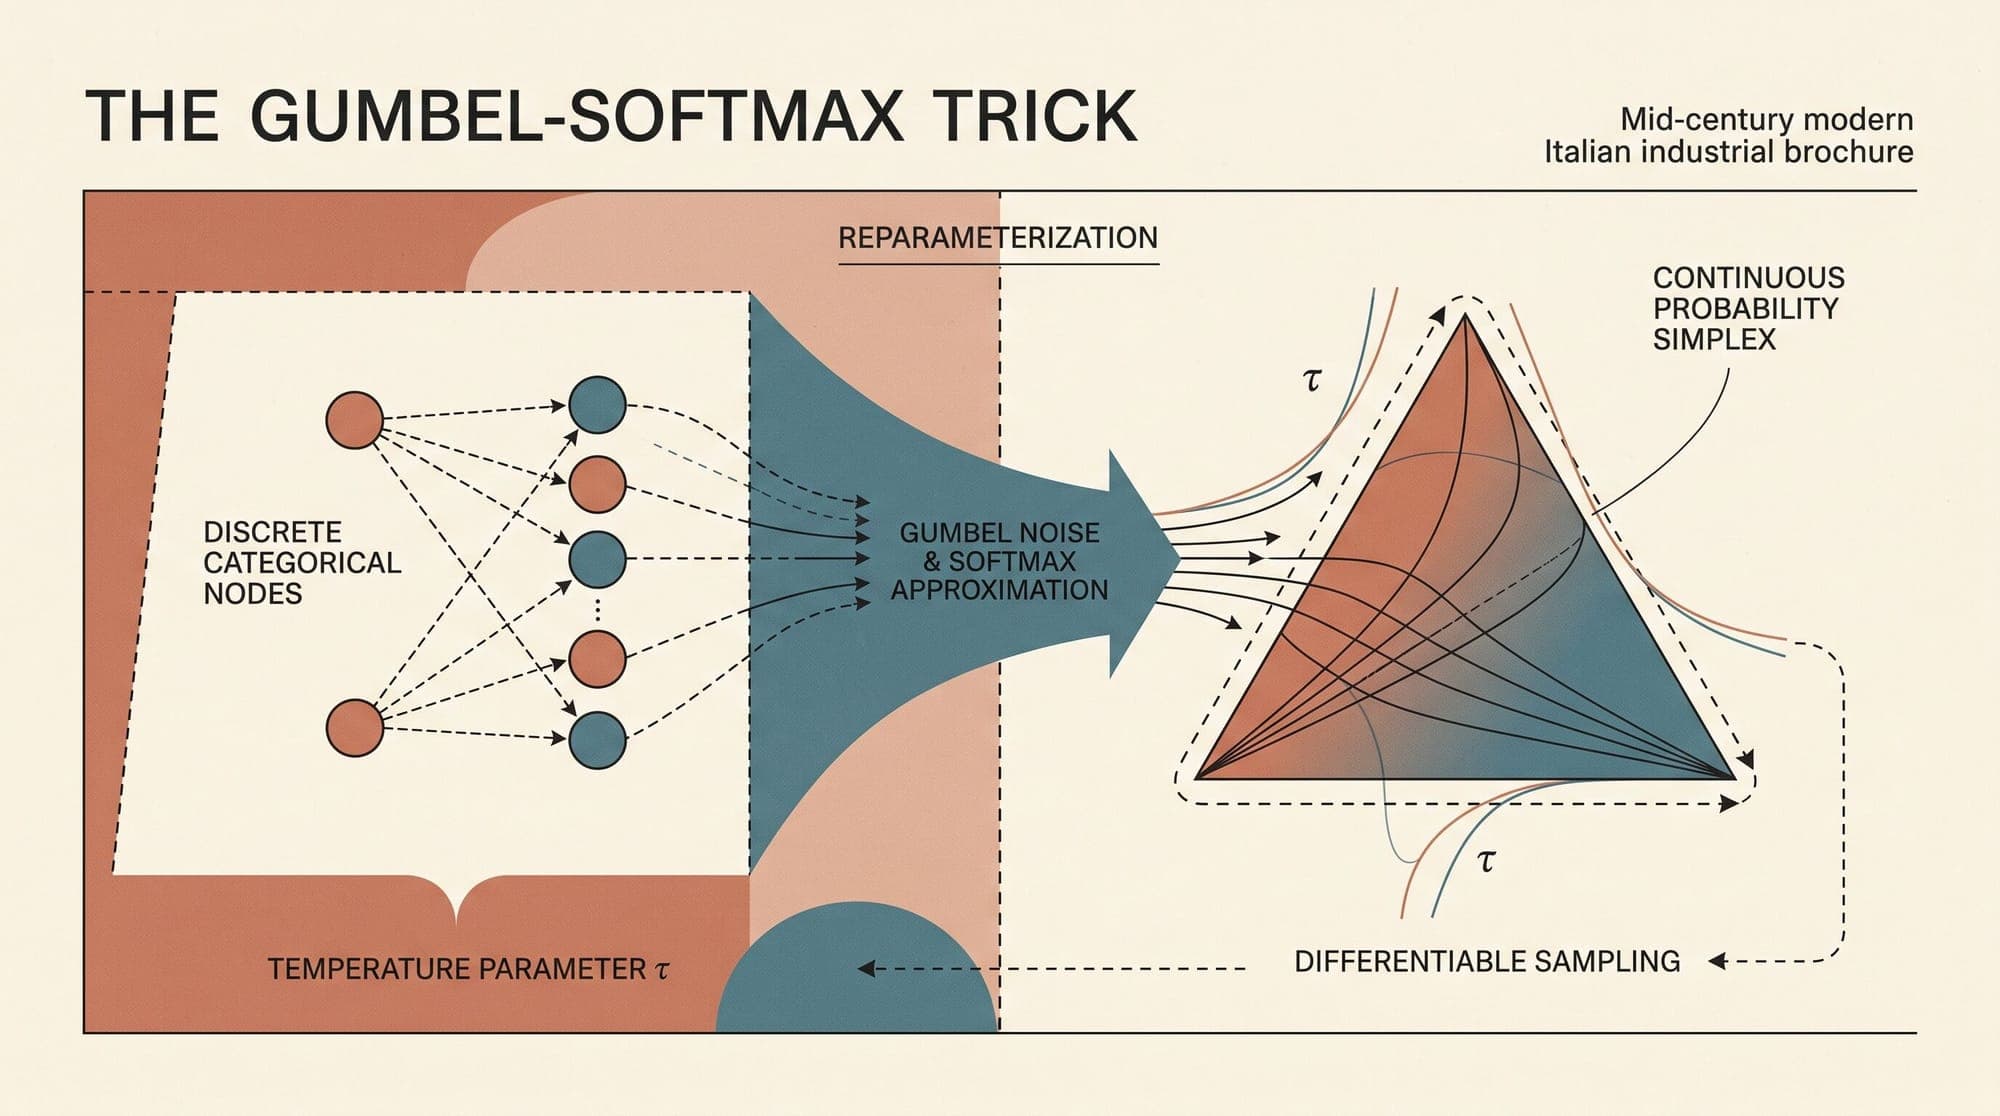
  3. The Gumbel-Softmax Trick: How Continuous Relaxations Enable Differentiable Discrete Sampling

    The Gumbel-Softmax Trick: How Continuous Relaxations Enable Differentiable Discrete Sampling In modern deep learning, end-to-end training depends on reverse-mode automatic differentiation. When an architecture operates on continuous tensors, computing gradients via the chain rule is straightforward. However, many foundational artificial intelligence problems involve discrete choices: selecting tokens from a fixed vocabulary, routing tokens to expert networks in a Mixture-of-Experts (MoE) archit

    Education
    11 min read
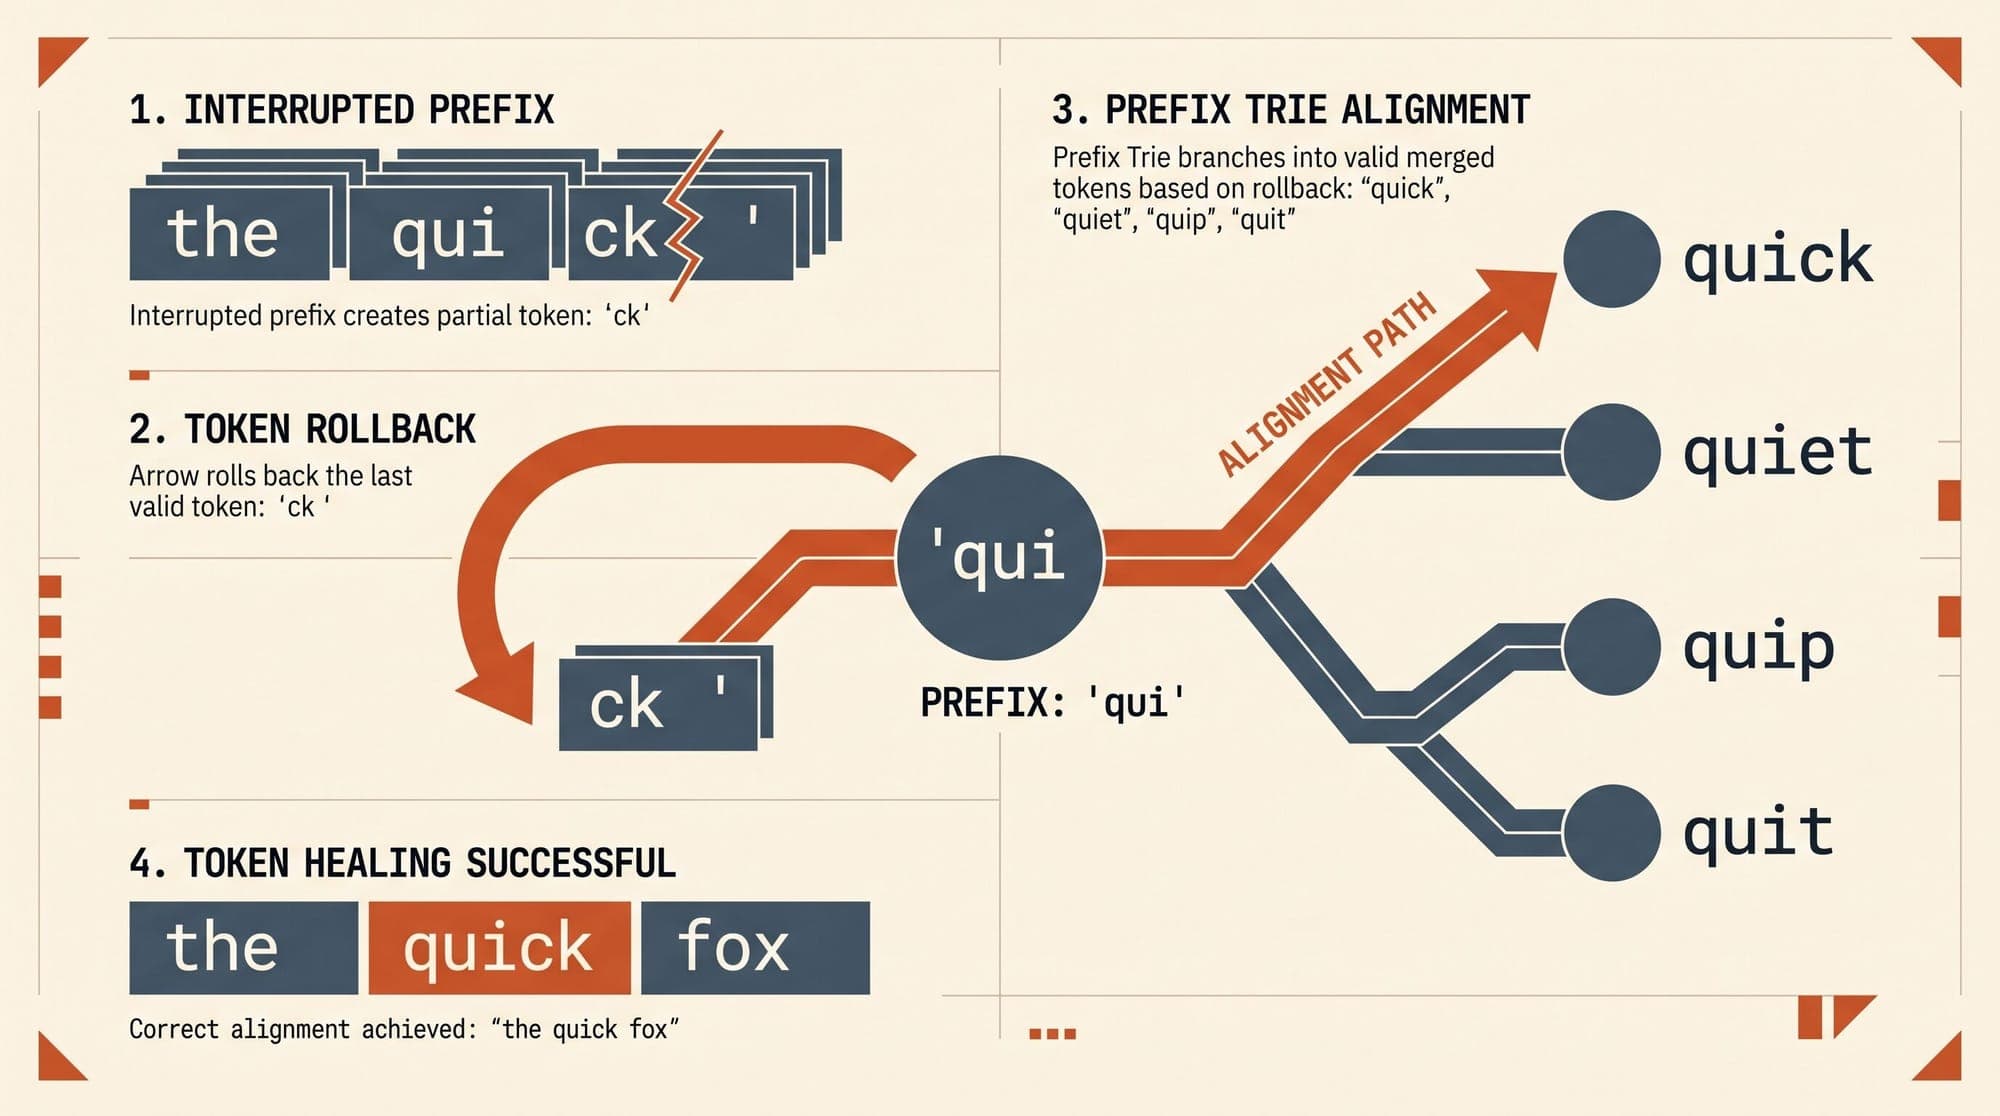
  4. Token Healing and Partial Token Alignment in Production LLM Serving: Architecture, Prefix Trie Rollback, and Serving Trade-Offs

    Modern large language models operate on discrete subword tokens generated by greedy compression algorithms like Byte-Pair Encoding (BPE), WordPiece, or Unigram. While subword tokenization enables high compression rates and fixed vocabulary sizes, it introduces a structural defect at the interface between raw user text and autoregressive inference: the partial token problem, commonly known as the prompt boundary problem. When a user prompt terminates mid-token or at a punctuation boundary that c

    LLM
    7 min read
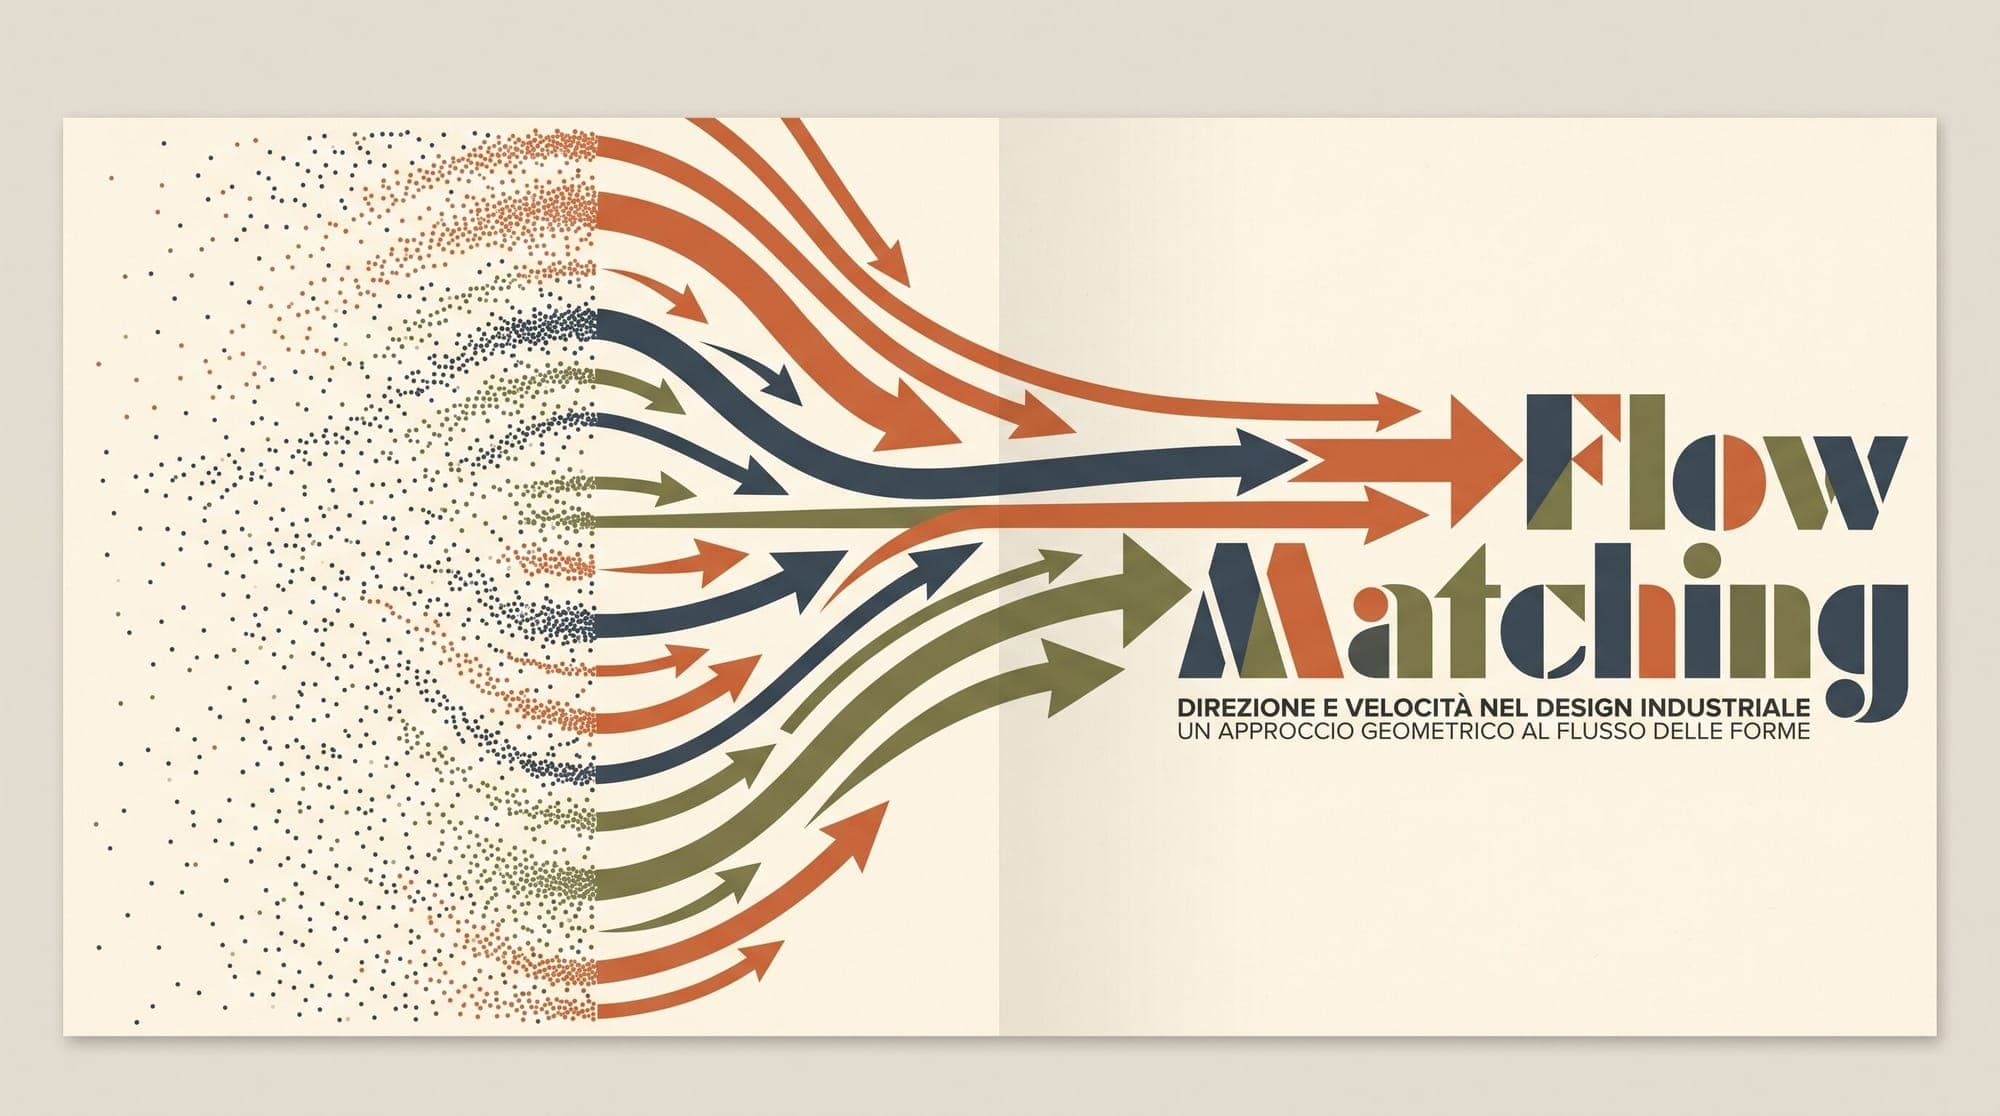
  5. Flow Matching for Generative Modeling: How Continuous Normalizing Flows and Optimal Transport Paths Replace Diffusion SDEs

    Generative modeling underwent a structural shift with the introduction of Flow Matching (FM), formulated independently by Lipman et al. (2022), Albergo and Vanden-Eijnden (2022), and Liu et al. (2022). While Denoising Diffusion Probabilistic Models (DDPM) and score-based Stochastic Differential Equations (SDEs) established state-of-the-art sample quality across vision and audio domains, their sampling dynamics rely on curved stochastic trajectories that require extensive numerical integration st

    AI
    8 min read
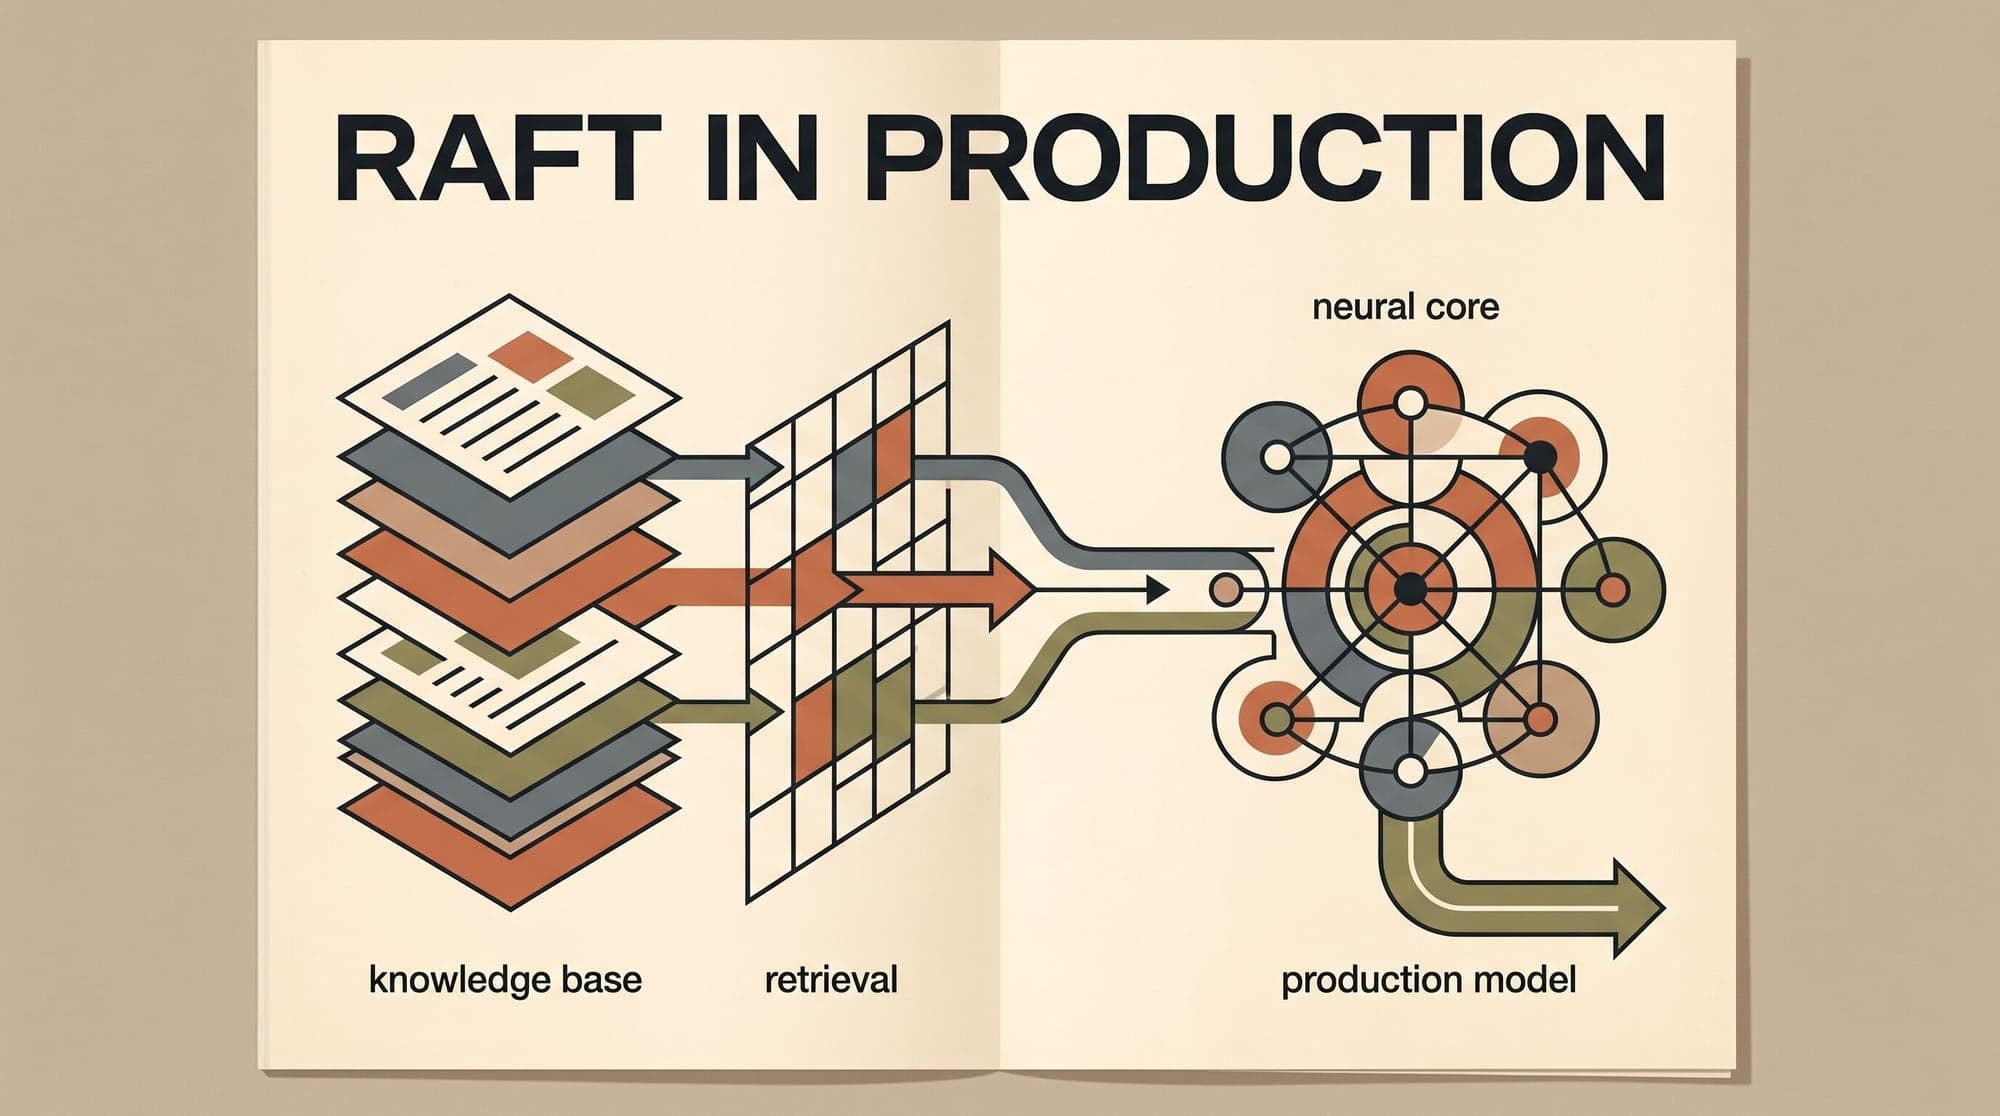
  6. Retrieval-Augmented Fine-Tuning (RAFT) in Production: Architecture, Synthetic Distractor Pipelines, and Evaluation

    Standard approaches to enterprise domain adaptation typically force a choice between two paradigms: Supervised Fine-Tuning (SFT) or Retrieval-Augmented Generation (RAG). SFT bakes domain knowledge directly into model weights, functioning like a closed-book exam. When facts change or precise source attribution is required, SFT models often hallucinate or fail to incorporate updated context. Conversely, standard RAG operates like an open-book exam without prior preparation. The base model reads re

    AI
    5 min read
  7. The Information Bottleneck in Deep Learning: How Mutual Information Compression Shapes Generalization and Neural Representations

    The Information Bottleneck in Deep Learning: How Mutual Information Compression Shapes Generalization and Neural Representations Classical statistical learning theory struggles to explain why overparameterized deep neural networks generalize well to unseen test data. Traditional complexity measures such as Vapnik-Chervonenkis (VC) dimension and Rademacher complexity scale with the raw count of tunable weights, predicting severe overfitting when parameter counts exceed dataset sample sizes. Yet

    AI
    10 min read
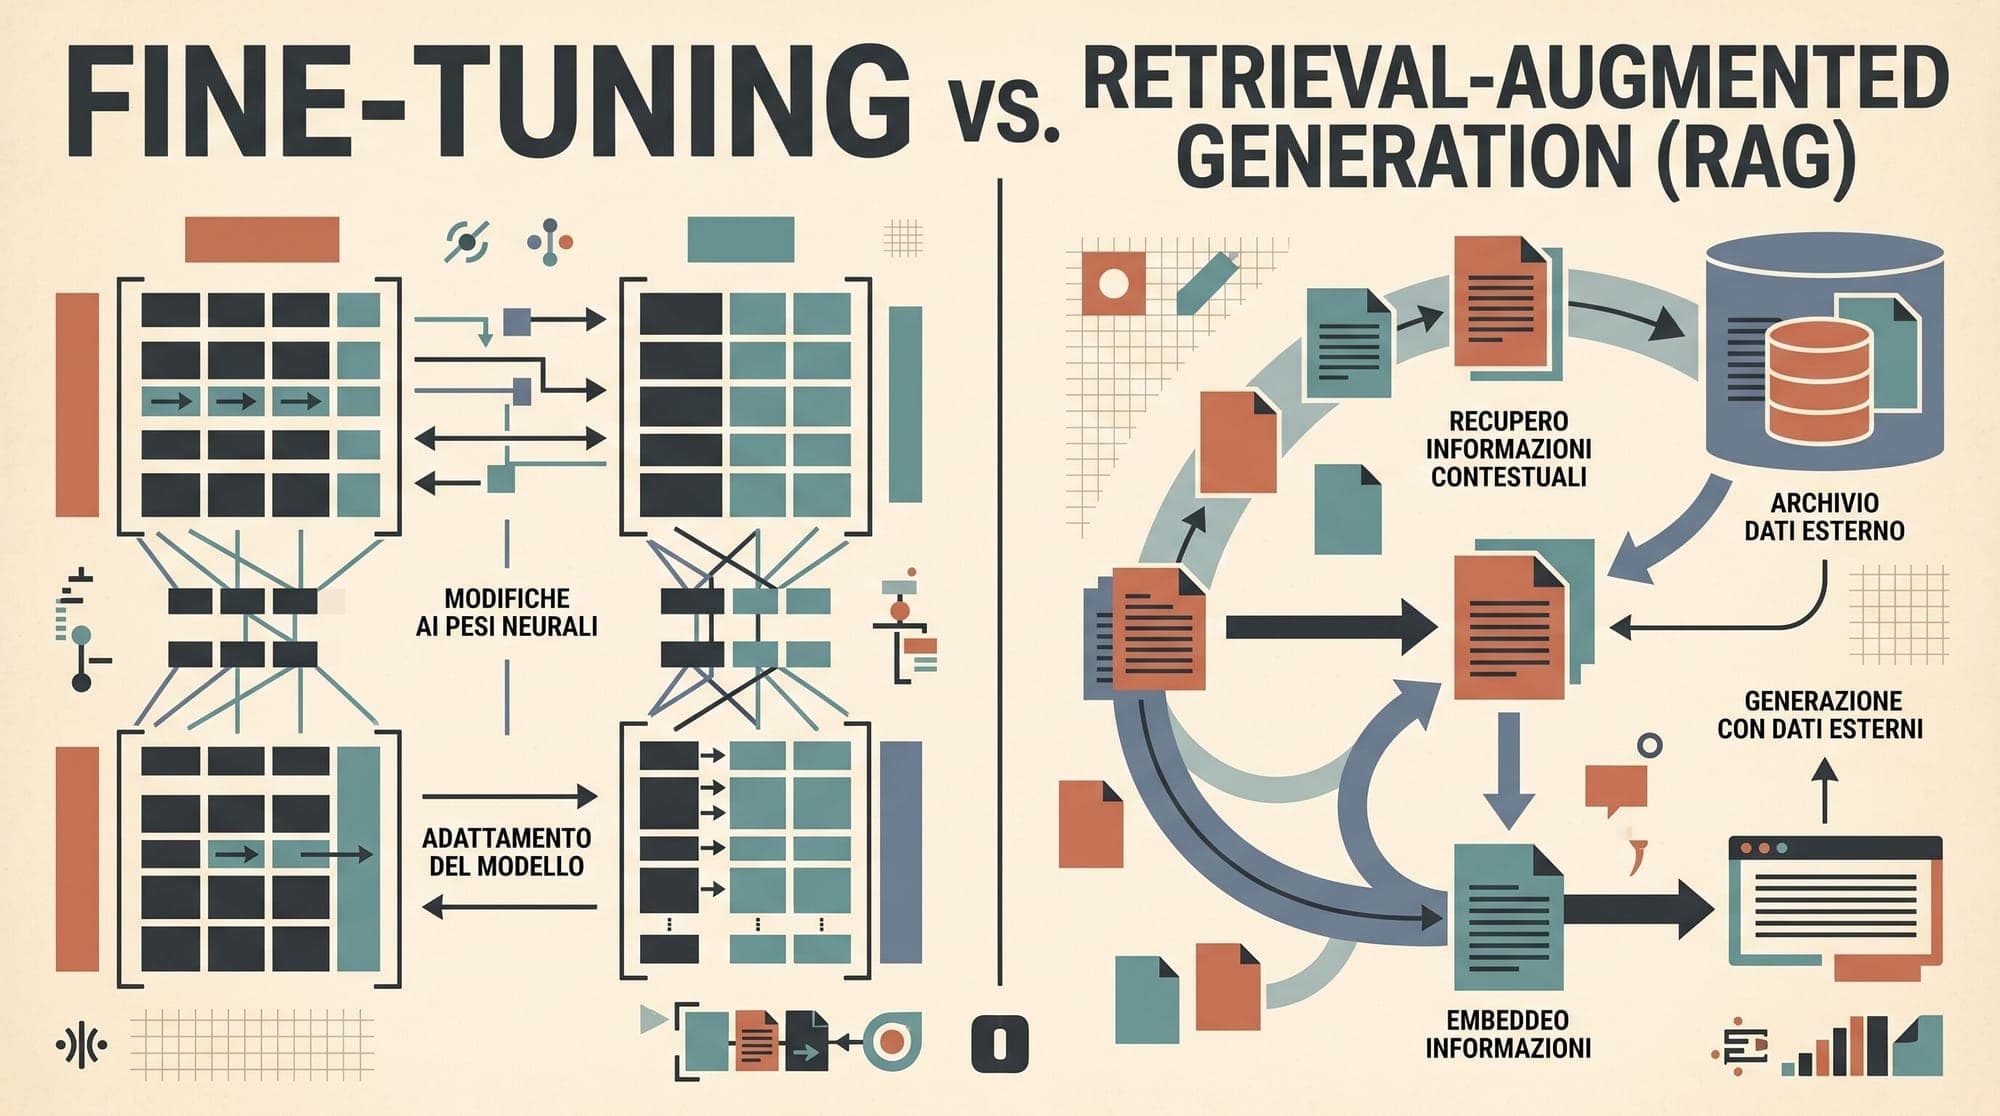
  8. Fine-Tuning vs. RAG in Production: Knowledge Injection, Task Adaptation, Latency Economics, and Hybrid Architecture Trade-Offs

    Fine-Tuning vs. RAG in Production: Knowledge Injection, Task Adaptation, Latency Economics, and Hybrid Architecture Trade-Offs When adapting large language models to domain-specific enterprise workloads, engineering teams face a fundamental architectural choice: modify the model's parametric weights via fine-tuning, or supply dynamic context at inference time via Retrieval-Augmented Generation (RAG). While early discussions often framed this decision as a binary trade-off, empirical evaluation

    AI
    6 min read
  9. Score-Based Generative Modeling via Stochastic Differential Equations: How Continuous SDEs and Score Matching Unify Diffusion Models

    Diffusion and score-based models represent one of the foundational paradigms of modern generative artificial intelligence, underpinning systems across image synthesis, video generation, audio modeling, and continuous multimodal representations. For years, generative diffusion was approached from two distinct perspectives: discrete-step denoising diffusion probabilistic models (DDPM) pioneered by Sohl-Dickstein et al. and Ho et al., and score matching with Langevin dynamics (SMLD / NCSN) introduc

    AI
    8 min read
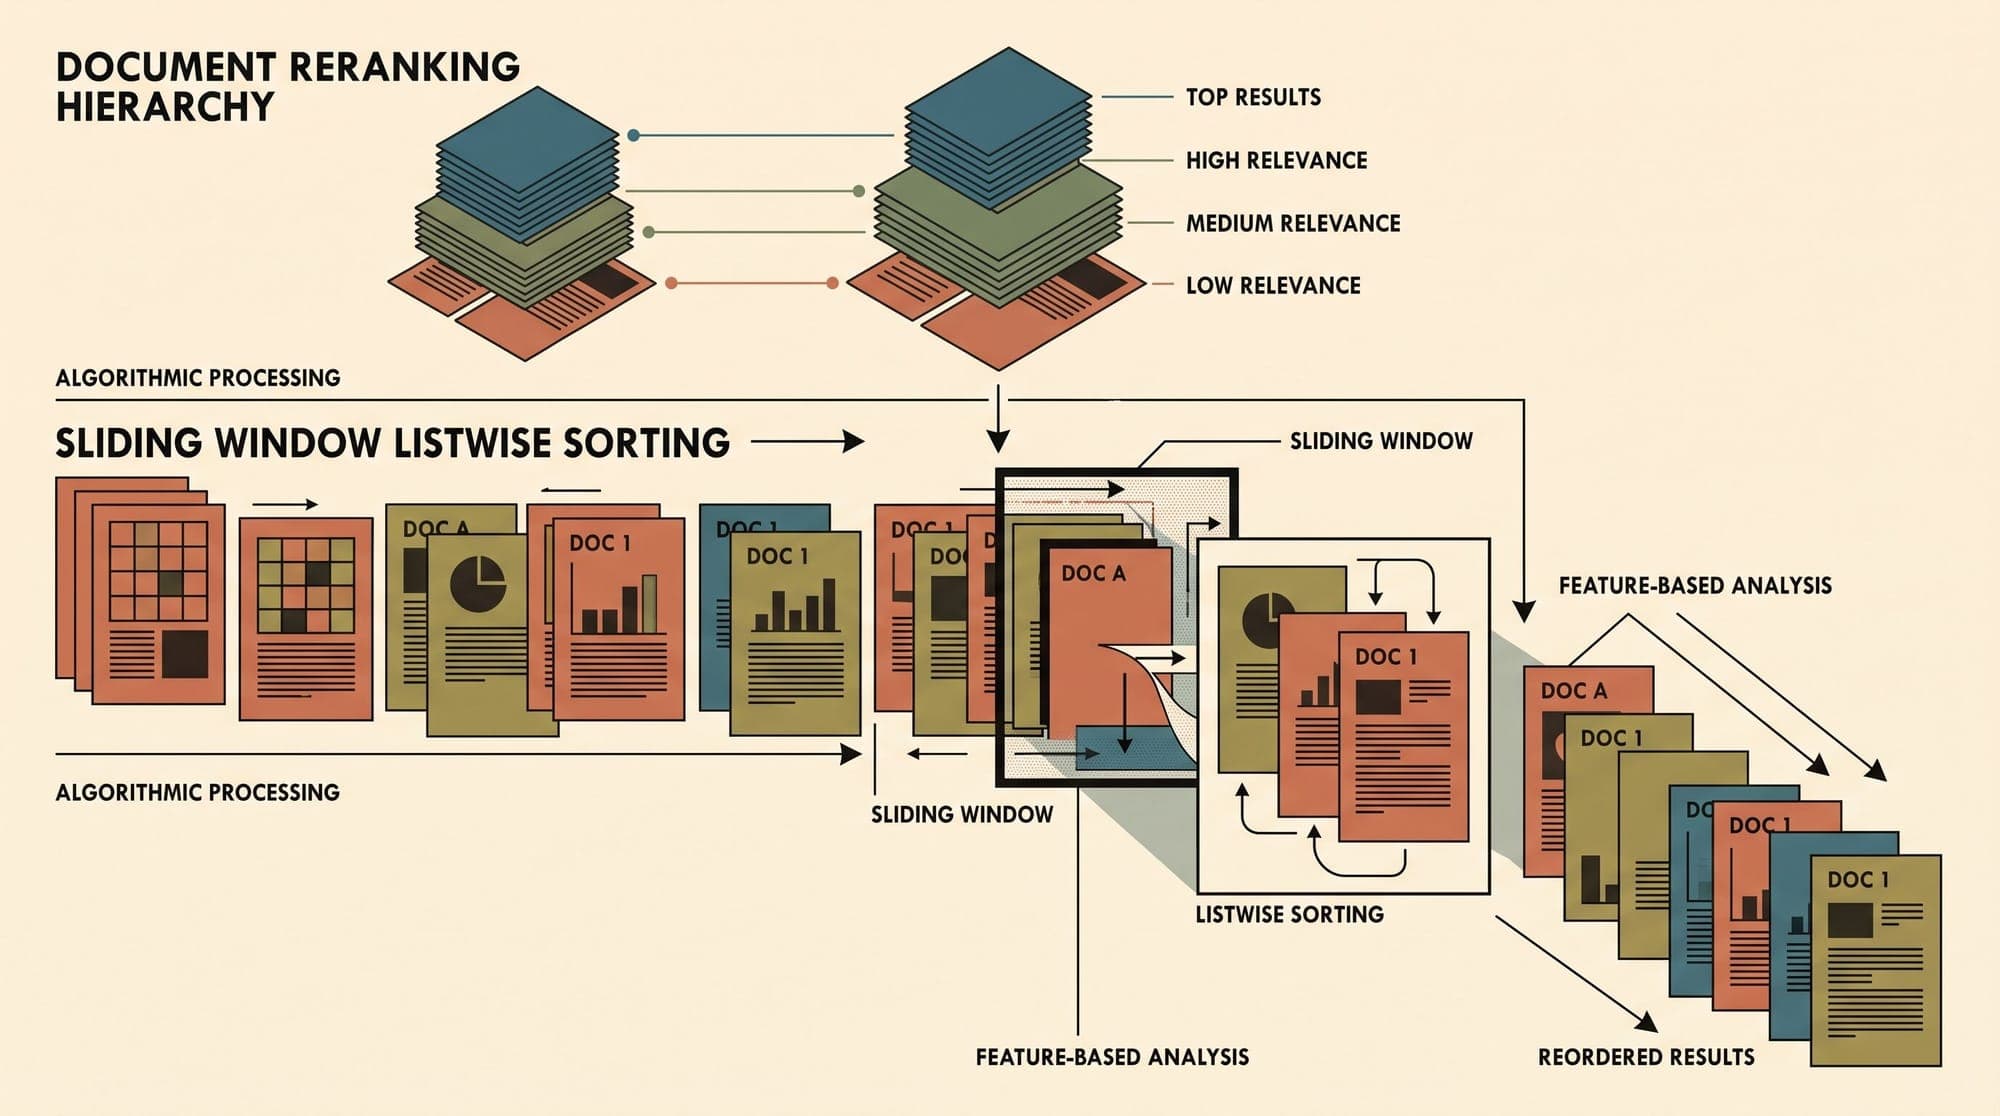
  10. Listwise Reranking in Production: Comparing Pointwise, Pairwise, and Listwise LLM Architectures, Sliding-Window Permutations, and Serving Economics

    Information retrieval systems in production Retrieval-Augmented Generation (RAG) and enterprise search have transitioned through multiple reranking paradigms. While first-stage retrieval (dense vector embeddings and sparse lexical BM25/SPLADE) retrieves candidate sets of 50 to 200 documents in under 20 milliseconds, the precision of downstream generation depends heavily on the reranking stage. Traditional neural rerankers evaluate candidates through pointwise scoring or pairwise classification.

    Information Retrieval
    5 min read
  11. The Lottery Ticket Hypothesis in Large Language Models: How Sparse Subnetworks and Iterative Magnitude Pruning Retain Transformer Capacity

    The Lottery Ticket Hypothesis in Large Language Models: How Sparse Subnetworks and Iterative Magnitude Pruning Retain Transformer Capacity Modern large language models operate under extreme overparameterization. Frontier architectures allocate tens or hundreds of billions of parameters to achieve low perplexity and robust generalization across reasoning, code generation, and factual retrieval. Yet empirical pruning consistently demonstrates that post-training models can lose 30% to 50% of their

    AI
    8 min read
  12. Enterprises Curb AI Agent Autonomy Amid 40% Project Cancellation Projections

    Enterprises deploying agentic artificial intelligence are shifting architectures away from open-ended autonomy toward bounded, verifiable execution as projects encounter governance, security, and financial bottlenecks in production environments. Data from industry research firms highlights a widening divergence between model capability and operational control. According to projections from Gartner, more than 40% of current agentic AI initiatives are projected to be canceled by the end of 2027.

    AI
    2 min read
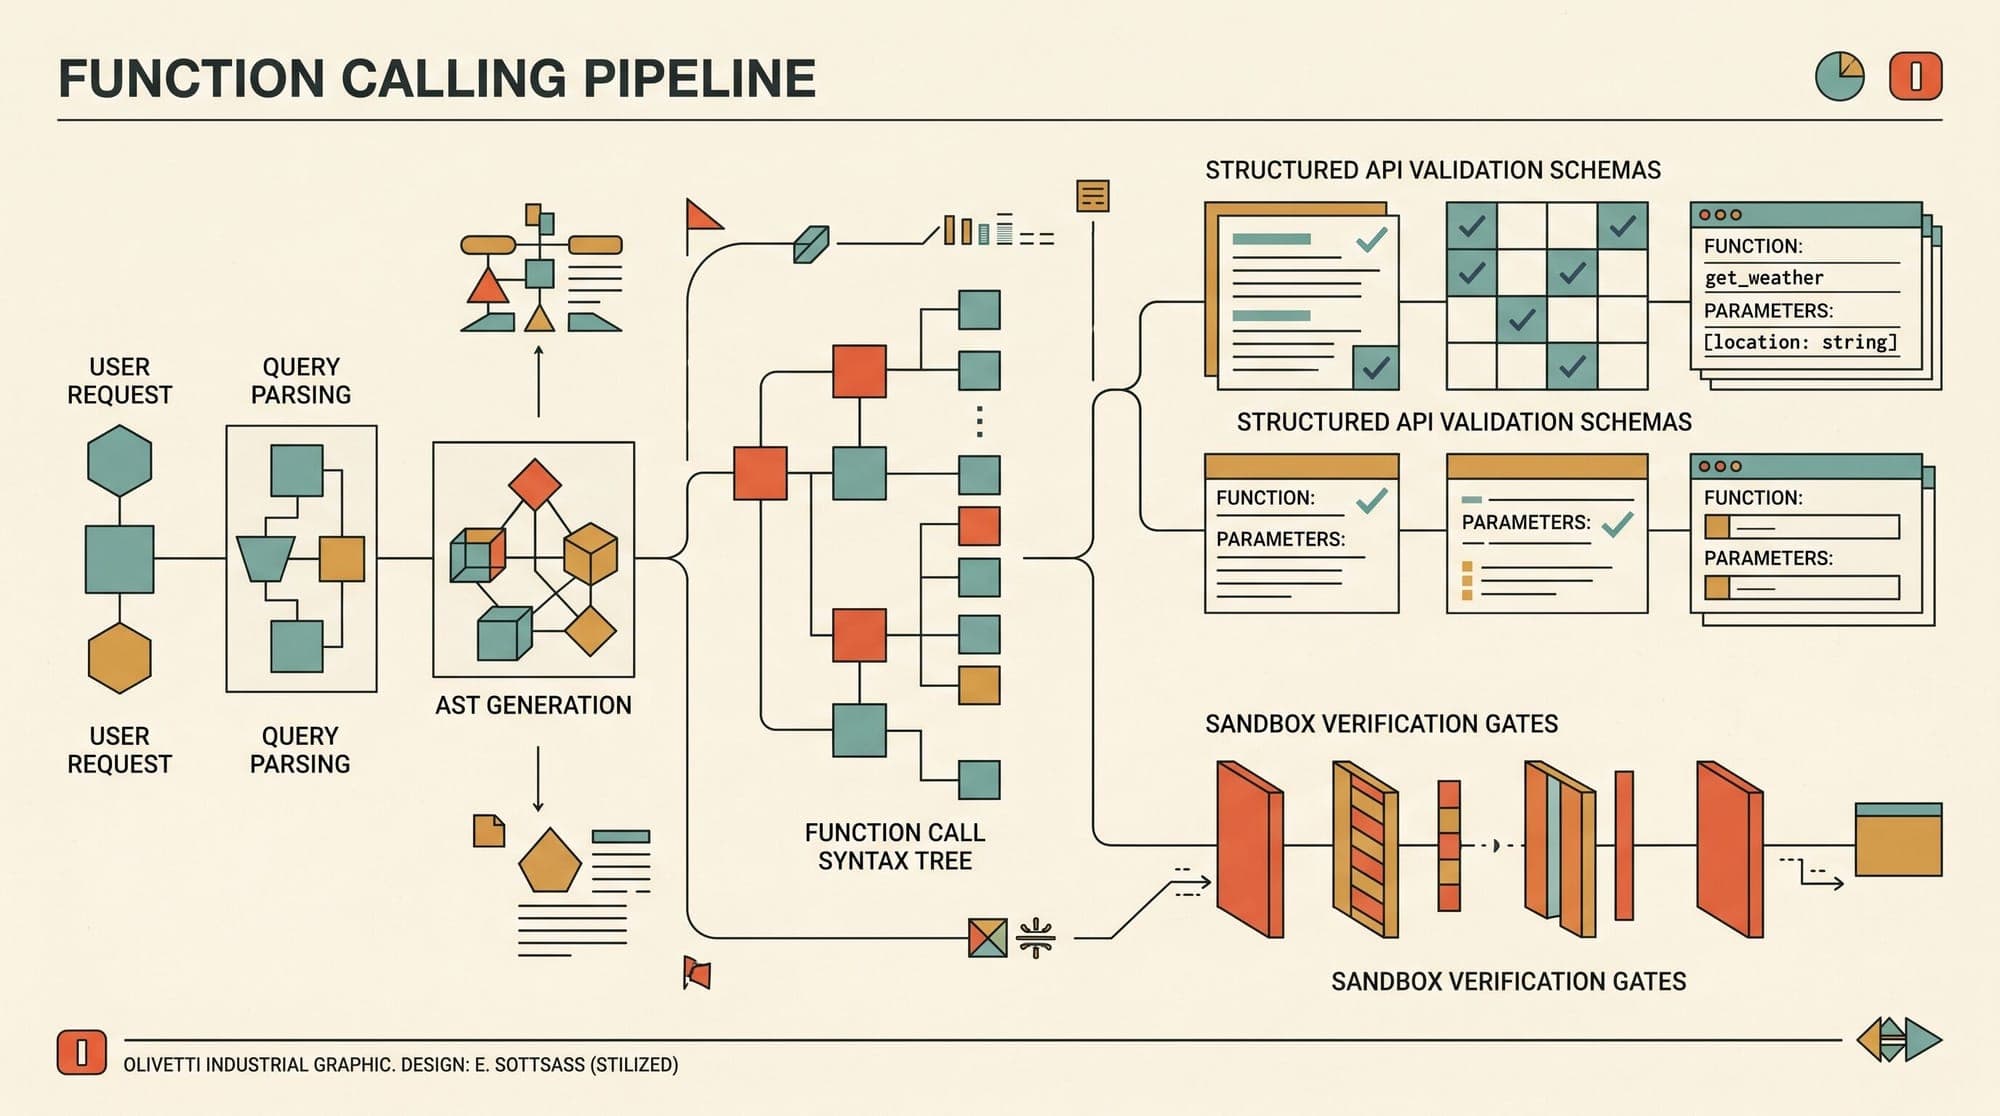
  13. Function Calling Evaluation in Production: AST Matching, Executable Sandboxes, and Multi-Turn Benchmark Architecture

    Production AI systems increasingly rely on Large Language Models not merely as conversational generators, but as deterministic execution routers that select and invoke external software tools. While general-purpose LLM evaluations such as MMLU or Chatbot Arena measure semantic fluency and broad reasoning, they provide little insight into whether a model can reliably format API parameters, adhere to strict JSON schemas, or maintain consistency across multi-step execution graphs. In real-world ag

    AI
    6 min read
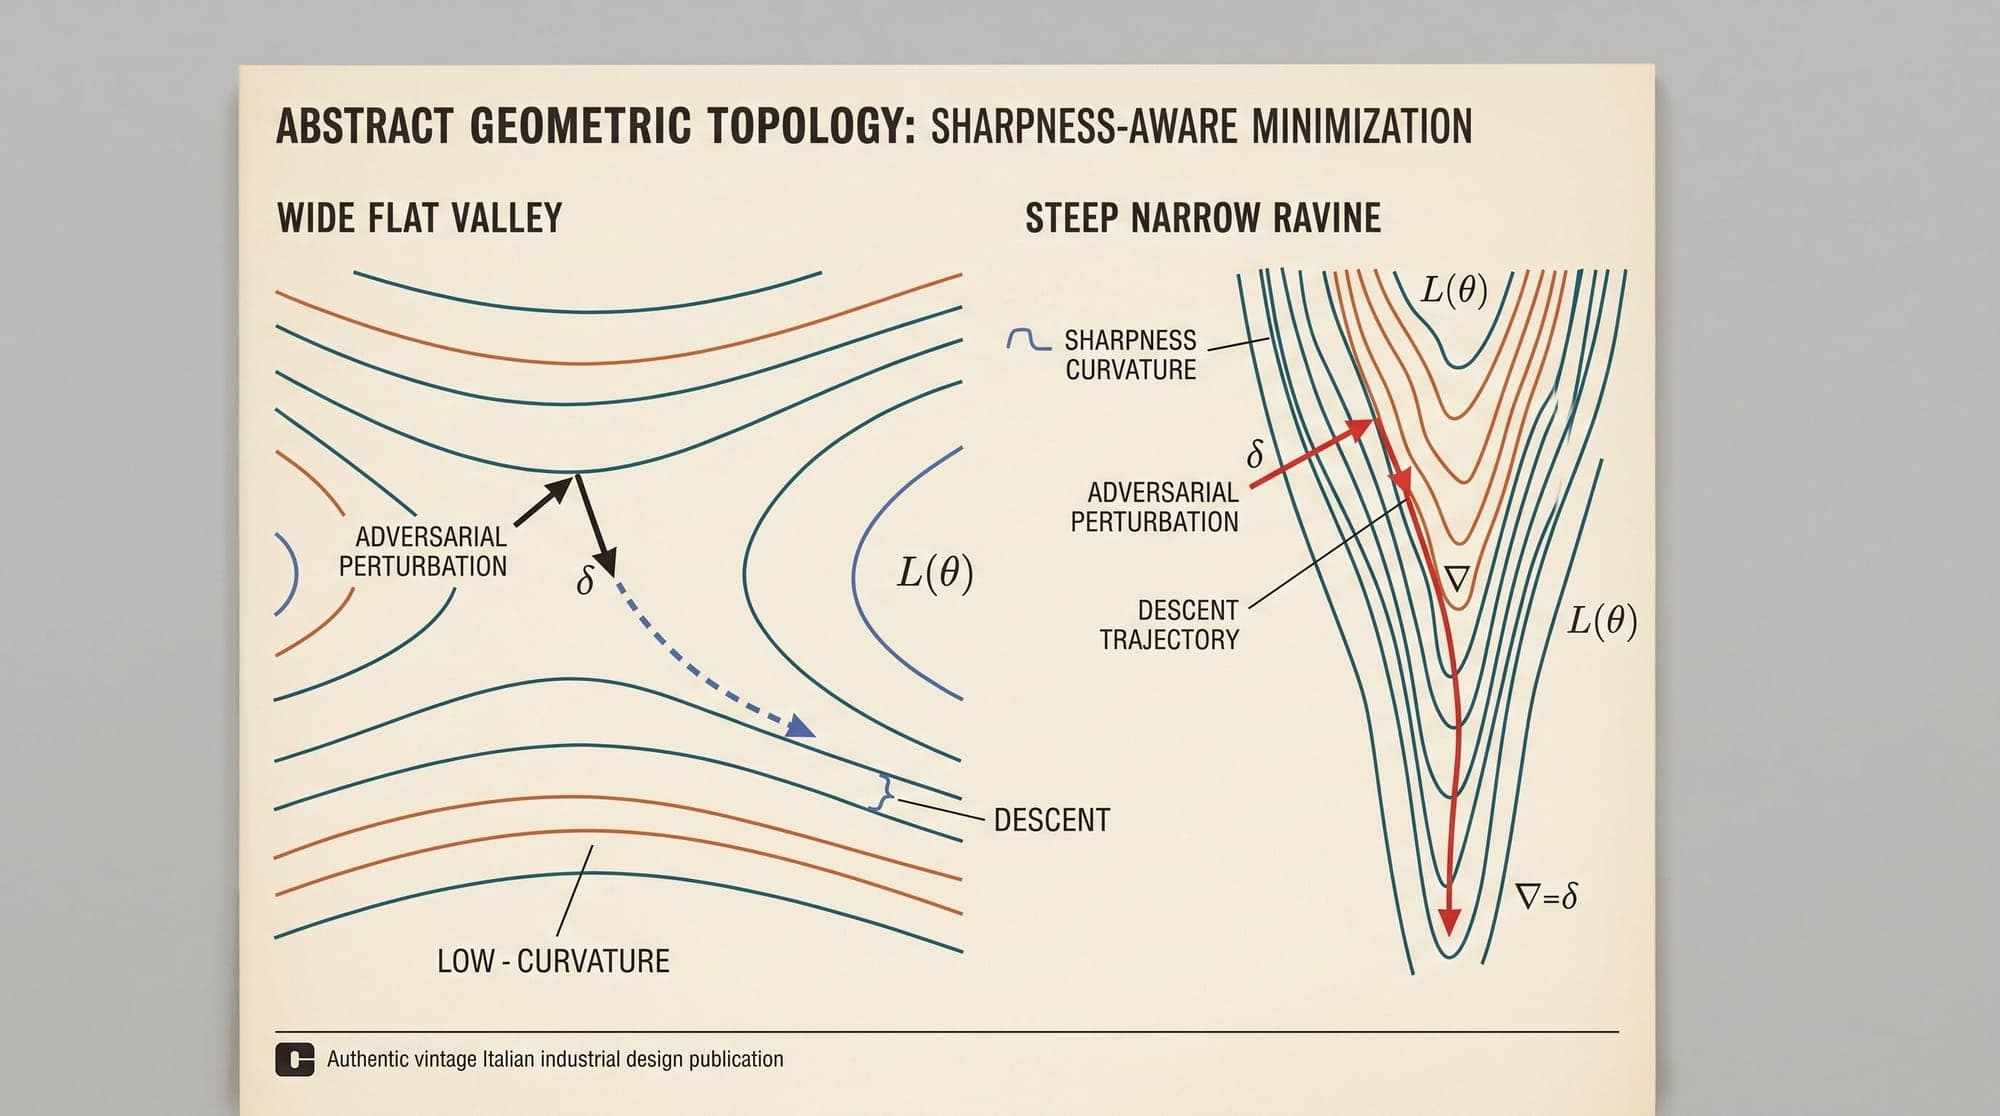
  14. Sharpness-Aware Minimization in Large Language Models: How Adversarial Weight Perturbations and Flat Minima Boost Generalization

    In overparameterized deep neural networks, minimizing empirical training loss is insufficient to guarantee optimal generalization on unseen distributions. Modern deep architectures, including vision models and autoregressive Large Language Models (LLMs), operate in regimes where parameter counts far exceed training token counts, producing highly non-convex loss surfaces populated by infinite global minima. Standard optimization via Stochastic Gradient Descent (SGD) or AdamW often converges to sh

    AI
    6 min read
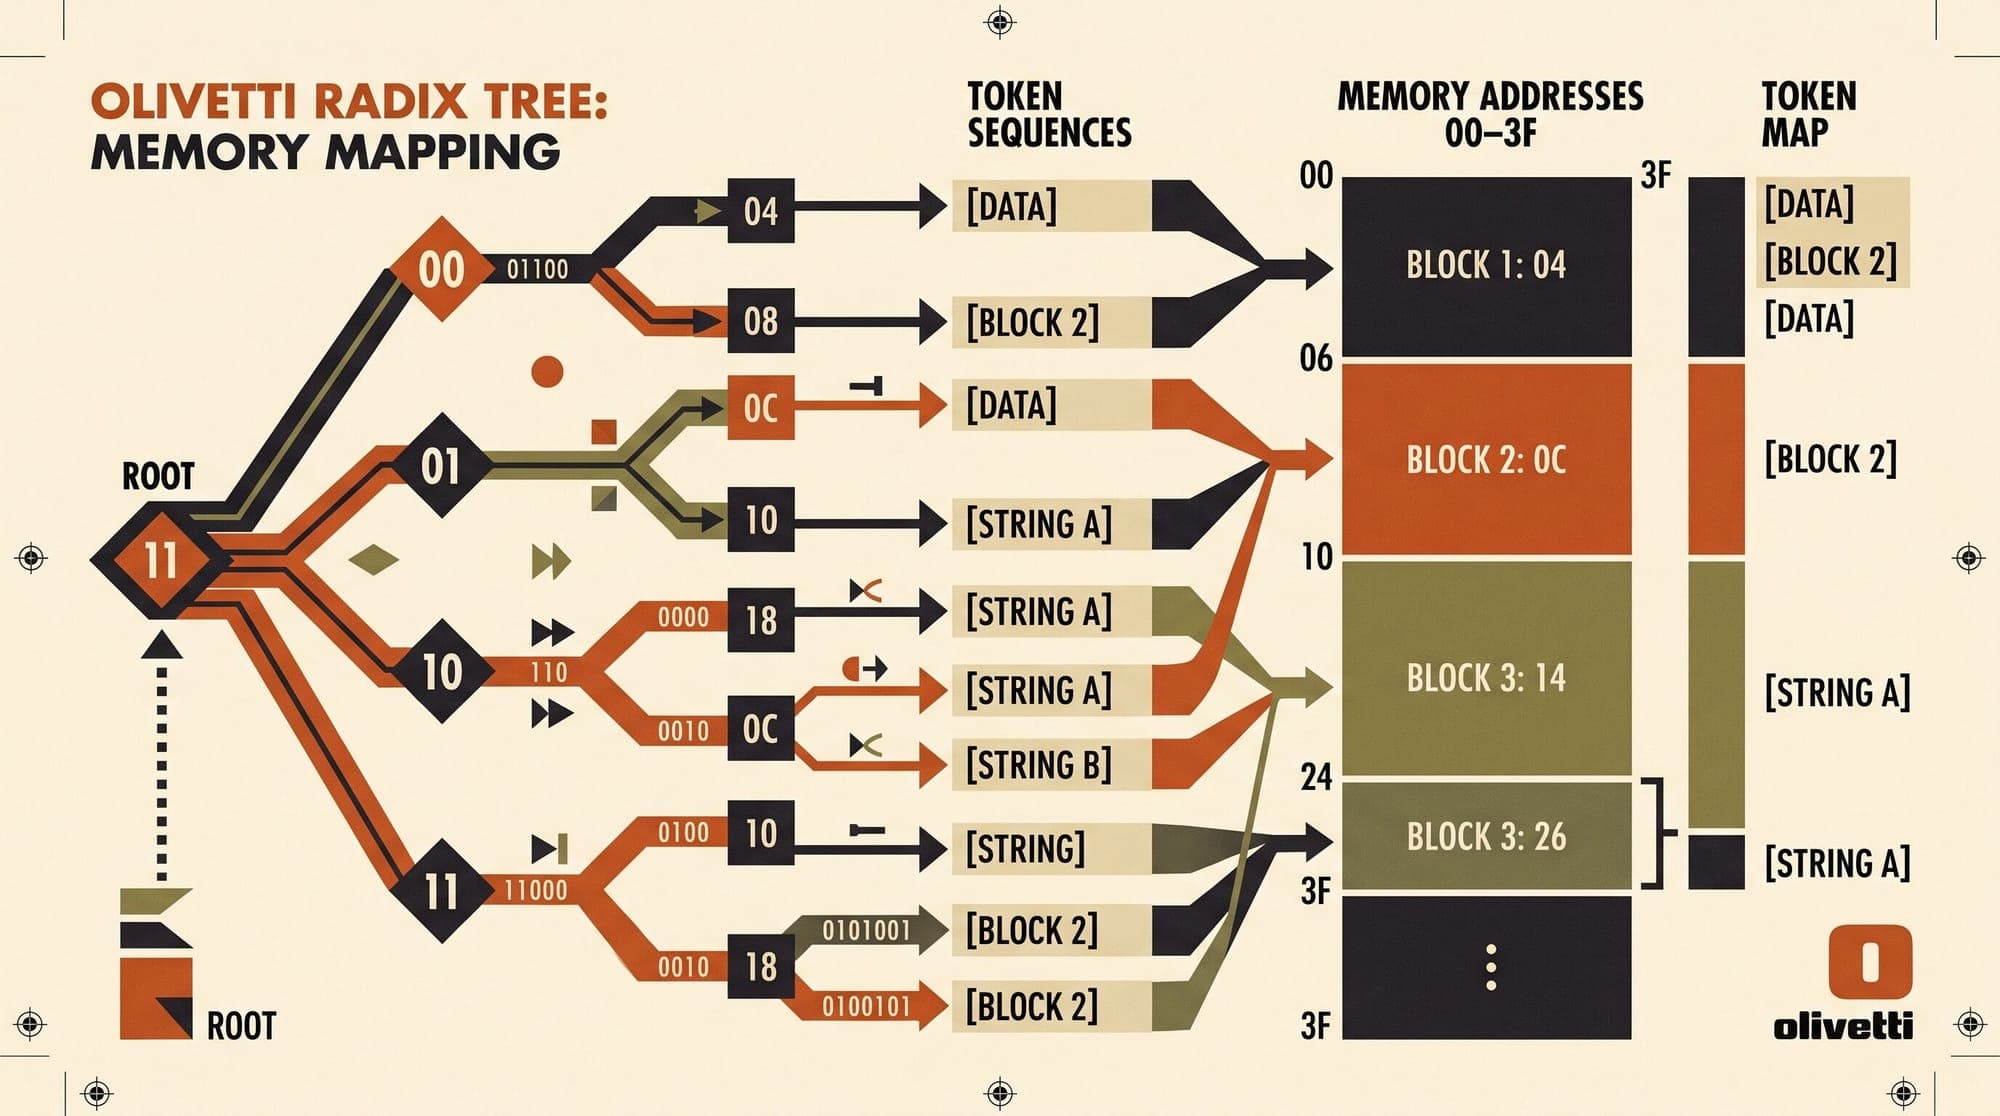
  15. Prefix-Tree KV Cache Management in Production: RadixAttention, Tree-Structured LRU Eviction, and Token-Level Sharing in SGLang and vLLM

    Prefix-Tree KV Cache Management in Production: RadixAttention, Tree-Structured LRU Eviction, and Token-Level Sharing in SGLang and vLLM Autoregressive large language model inference is heavily constrained by memory bandwidth and the computational overhead of the prefill phase. For workloads such as multi-turn conversations, autonomous agent tool loops, few-shot prompt evaluations, and tree-search decoding, consecutive requests often share substantial token prefixes. In a standard multi-turn ses

    AI
    7 min read
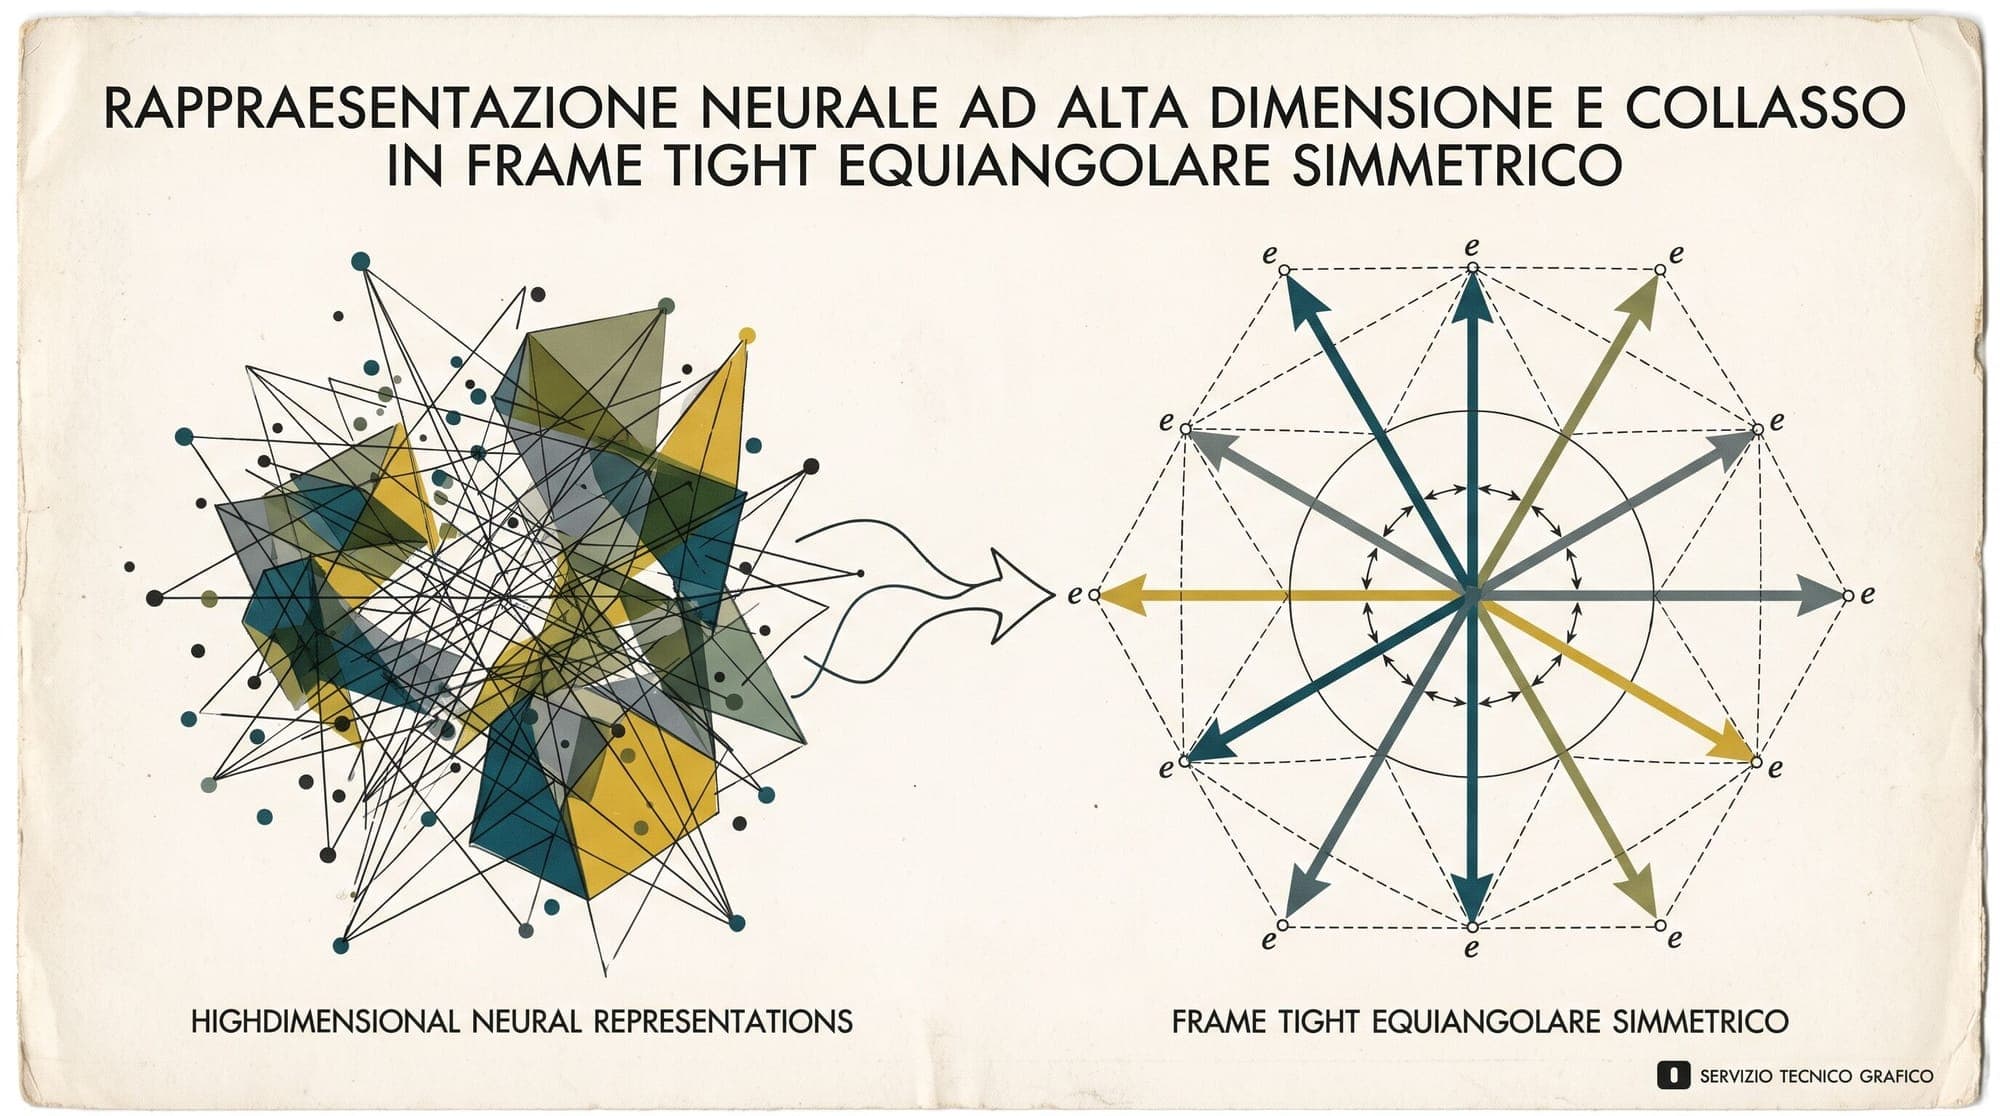
  16. Neural Collapse: How Simplex Equiangular Tight Frames Emerge at the Terminal Phase of Training

    In classification tasks, deep neural networks exhibit an unexpected geometric simplicity during late-stage optimization. While the internal activations of early training appear high-dimensional and complex, the penultimate layer representations and linear classifiers converge toward an exact, symmetrical geometric structure known as Neural Collapse (NC). First identified empirically by Papyan, Han, and Donoho (2020), Neural Collapse emerges during the Terminal Phase of Training (TPT). This regi

    edu
    6 min read
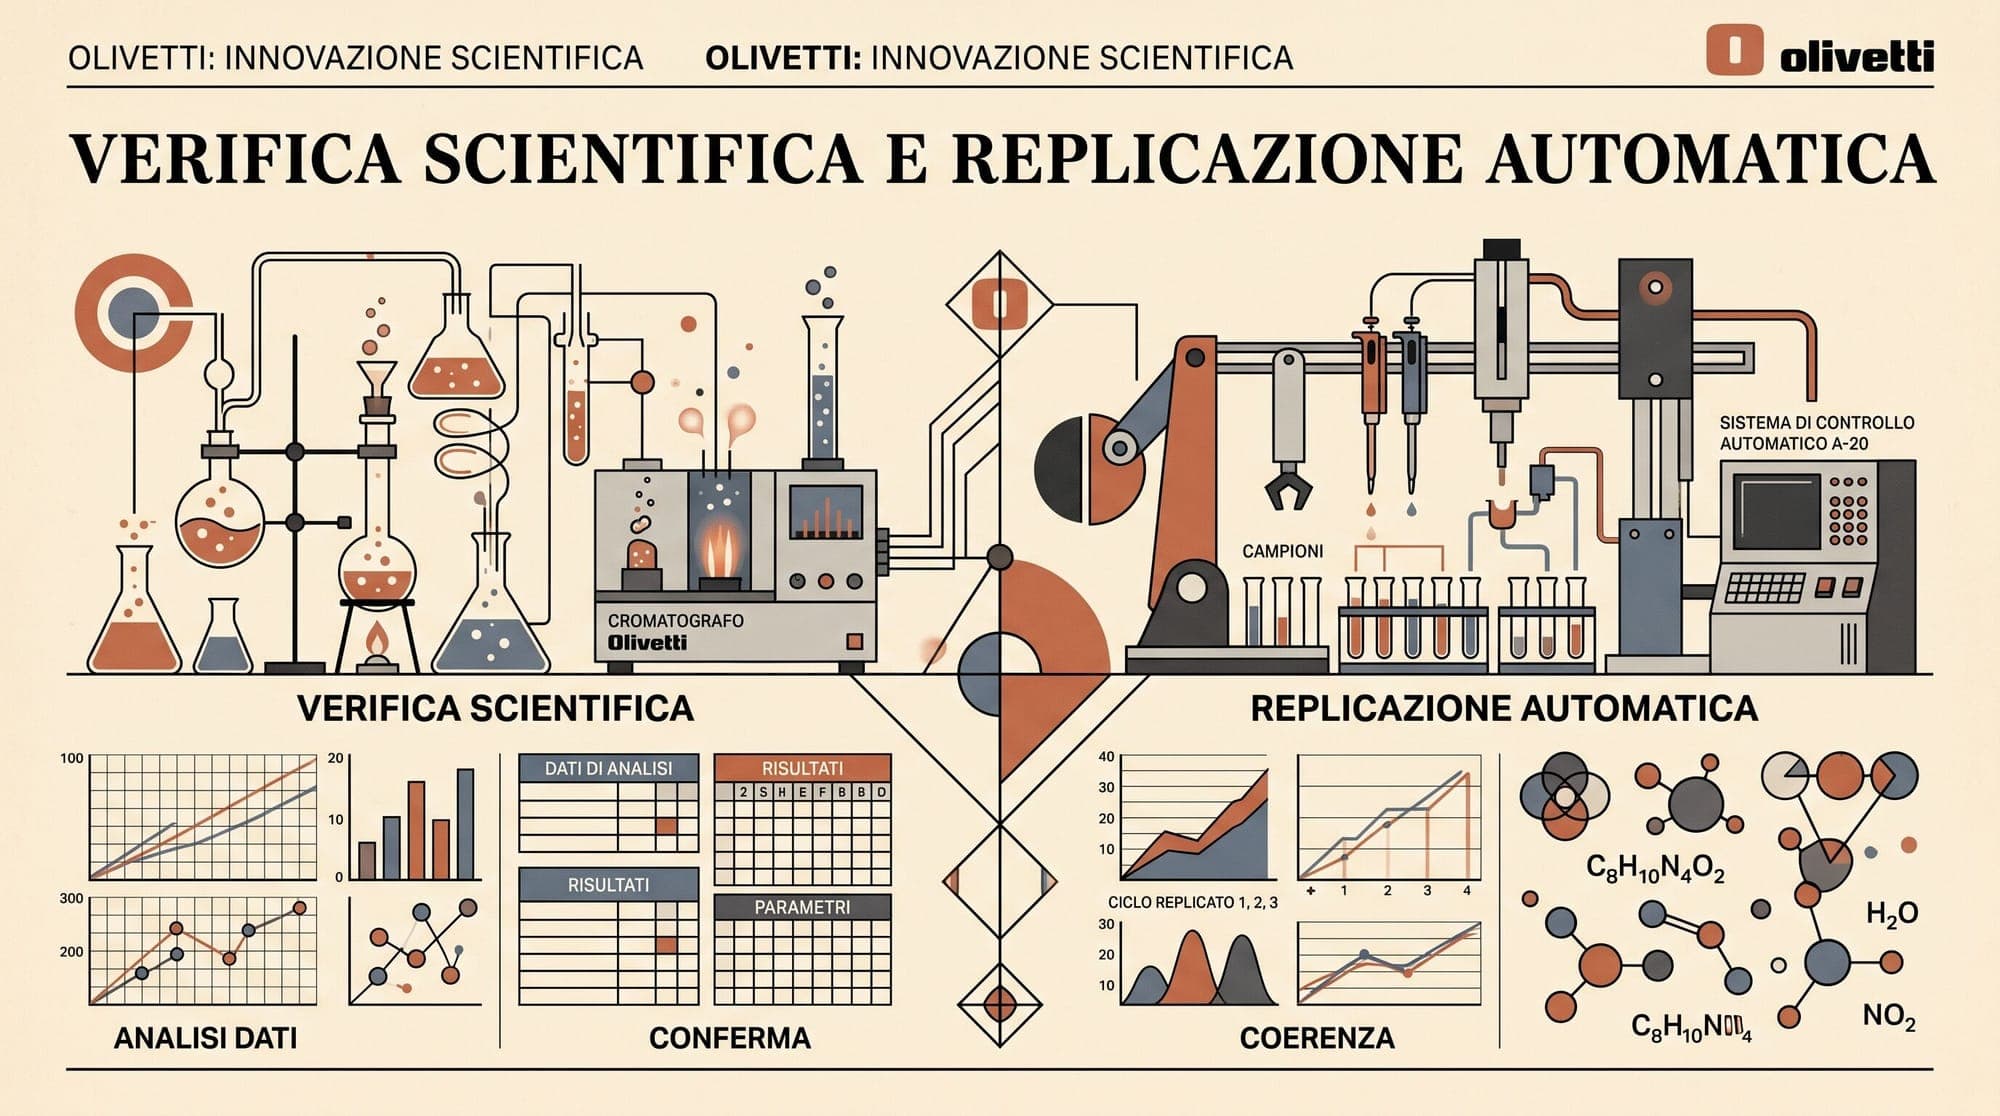
  17. Inherent Releases Faraday: 27B Scientific Agent Outperforms Frontier Models on Paper Replication

    London-based AI research startup Inherent has released Faraday, an autonomous AI agent engineered to independently reproduce published scientific research without prior exposure to target solutions. Founded by former Google DeepMind researchers Louis Kirsch, Kaloyan Aleksiev, Tantum Collins, and Edward Hughes, the lab launched Faraday weeks after securing a $50 million seed round. According to benchmark results published by the lab, Faraday outperformed significantly larger frontier systems, in

    AI
    2 min read
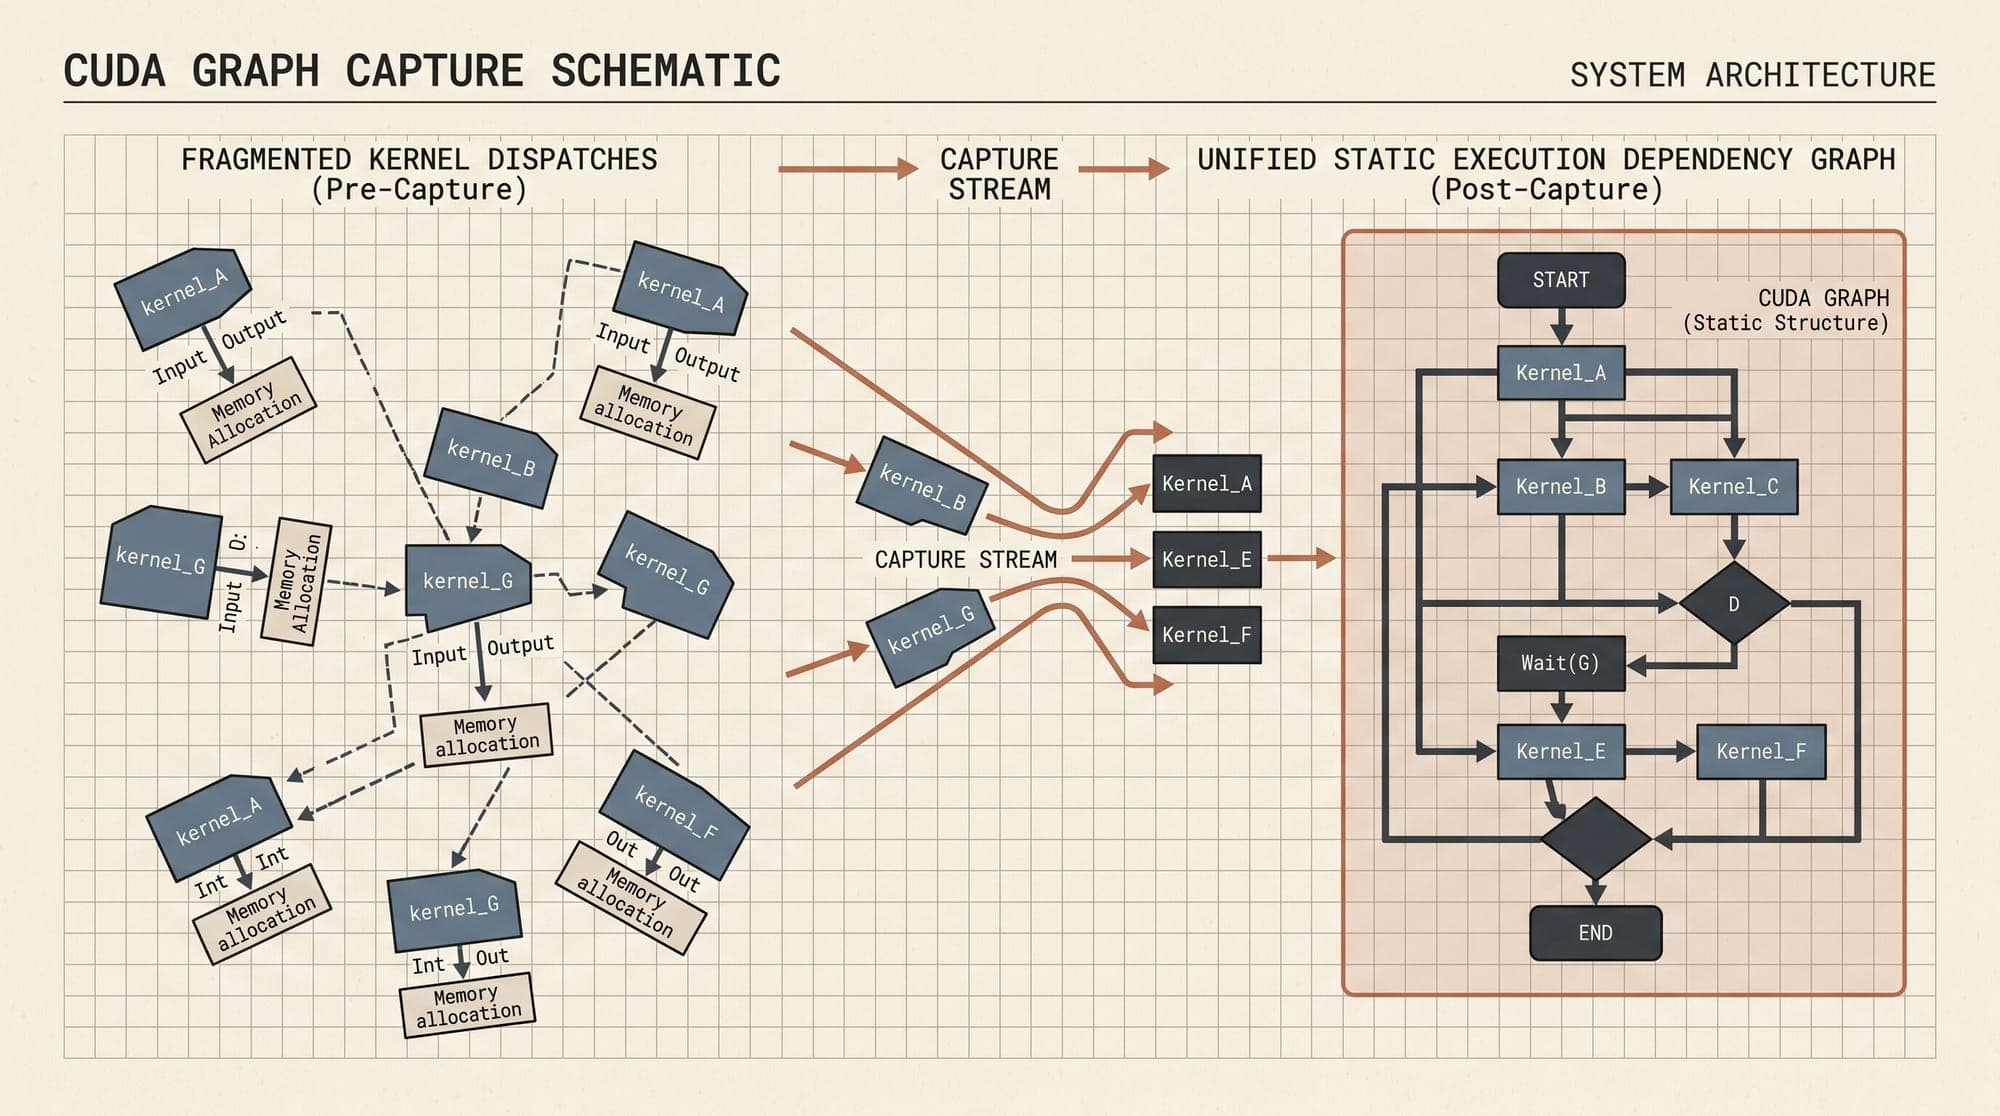
  18. CUDA Graph Capture in Production LLM Serving: Dynamic Batch Bucketing, Static Memory Pooling, and Kernel Launch Elimination

    CUDA Graph Capture in Production LLM Serving: Dynamic Batch Bucketing, Static Memory Pooling, and Kernel Launch Elimination In high-throughput large language model serving, the autoregressive generation (decode) phase presents an operational bottleneck distinct from prefill processing. While prefill computation is dominated by compute-bound General Matrix Multiplications (GEMMs) operating across extended sequence lengths, autoregressive decoding processes a single token per sequence at each ite

    Inference
    8 min read
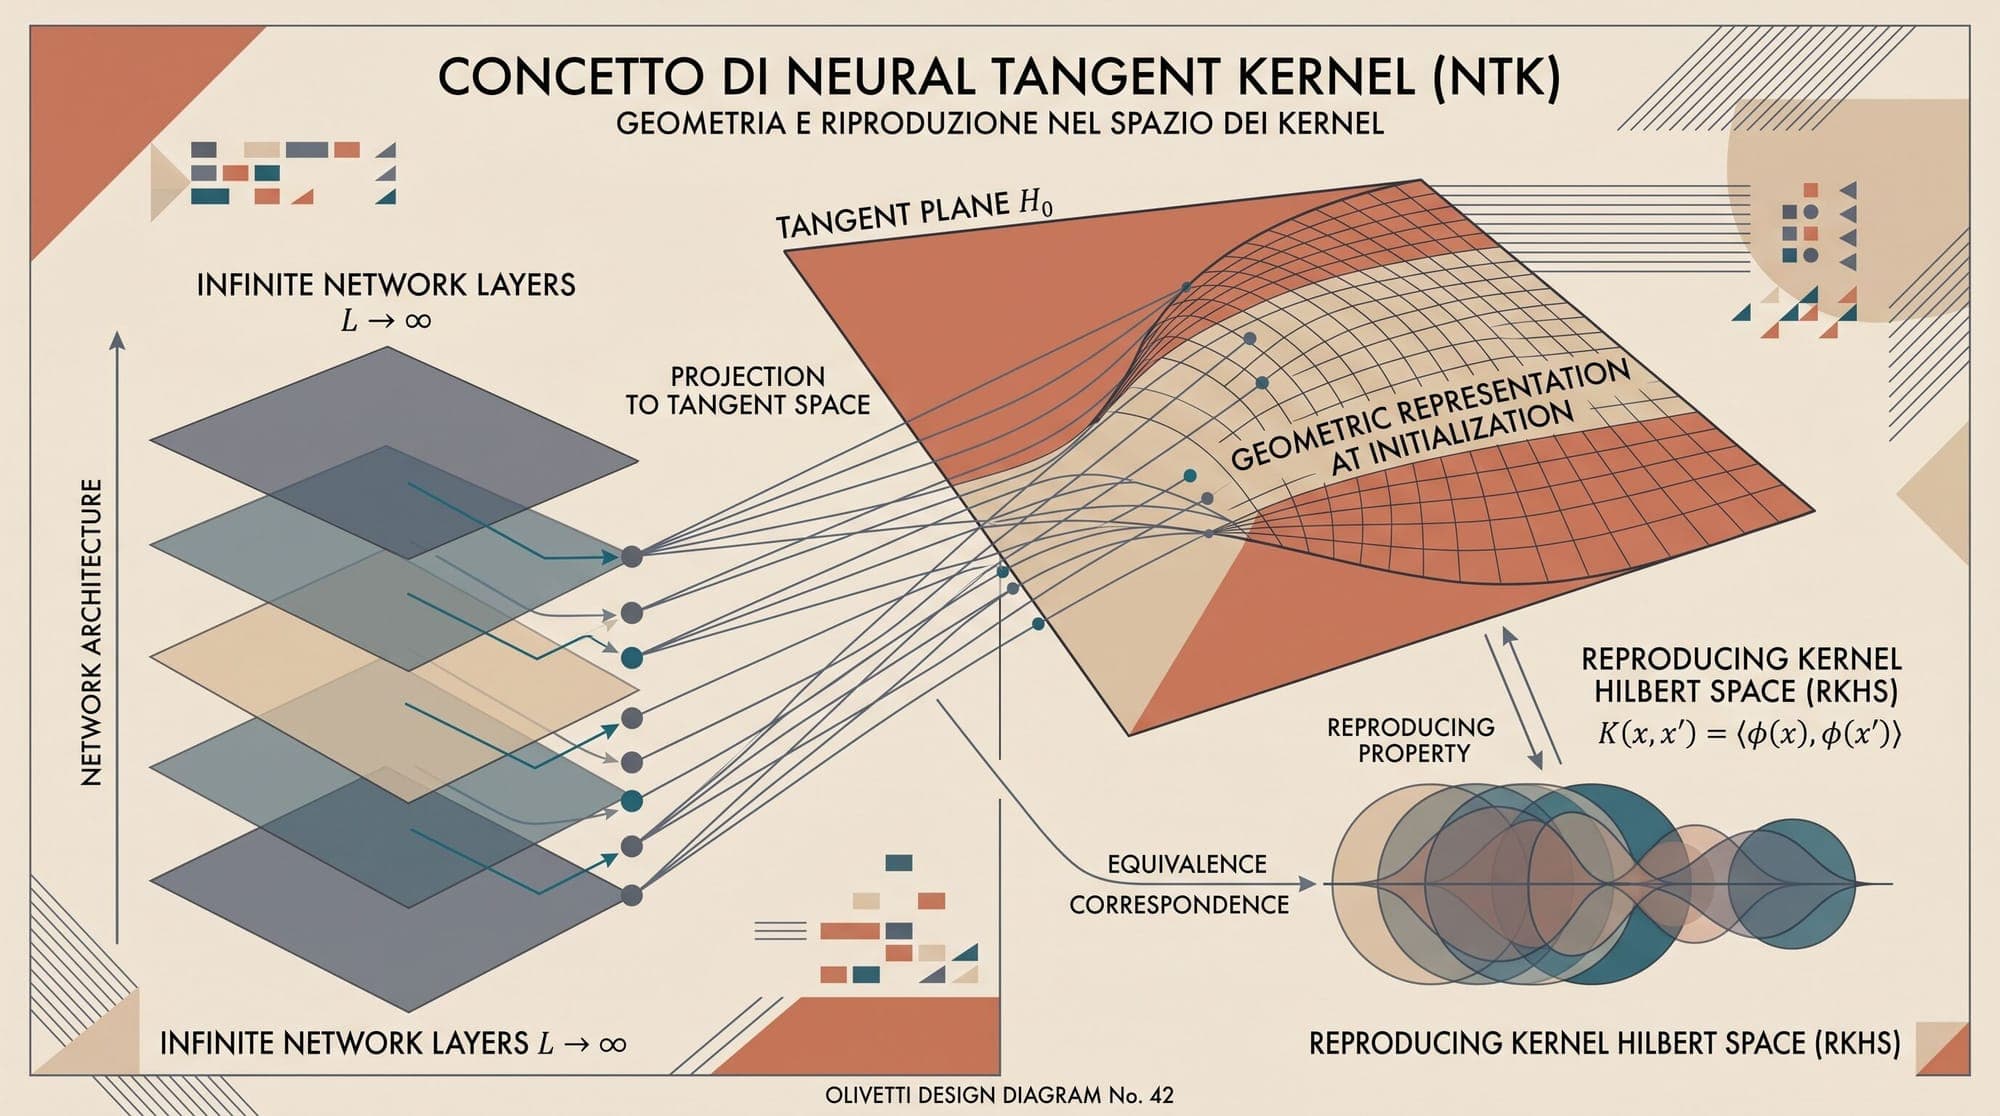
  19. Neural Tangent Kernel: How Infinite-Width Networks Linearize Gradient Descent

    The Neural Tangent Kernel (NTK) describes the behavior of infinitely wide neural networks during gradient descent. In the infinite-width limit, network training reduces to kernel regression with a fixed kernel — the NTK — that stays constant throughout training. This theoretical framework explains why wide networks converge to global minima, why they struggle to learn high-frequency functions early (spectral bias), and why they behave differently from finite-width networks that learn features.

    edu
    4 min read
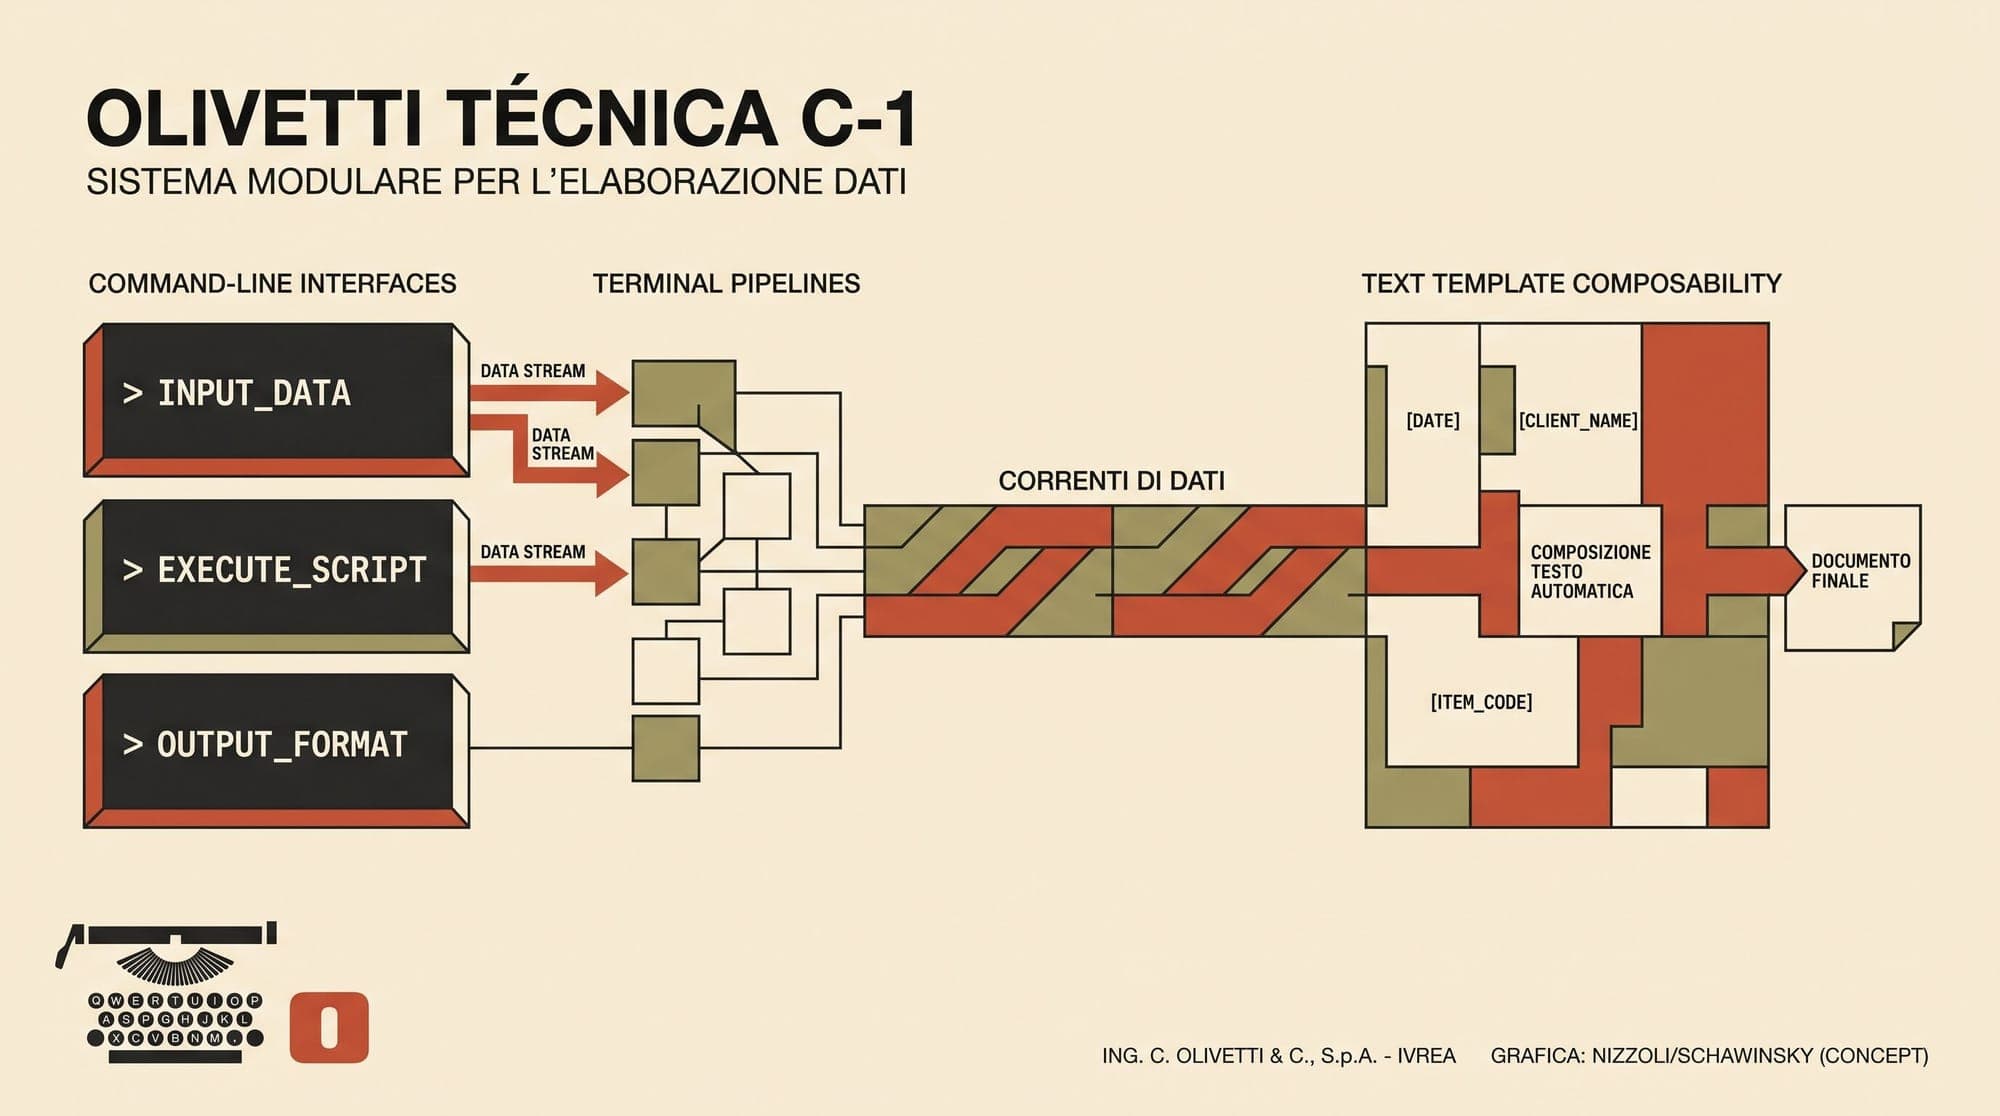
  20. LLM 0.33 Adds Template Chaining, Per-Call Embedding Keys, and Server Tool Logging

    Simon Willison has released llm 0.33, an update to the open-source command-line tool and Python library for interacting with large language models. The release introduces template composition, stateless per-call embedding credentials, and server-side tool execution visibility in logs, alongside an upgrade to the OpenAI Python 3.x client and httpx2. Template Composition and Parameter Decoupling The primary workflow enhancement in version 0.33 is the ability to repeat the -t or --template flag

    Tooling
    2 min read