GitHub Copilot Fusion: Multi-Model Routing Goes GA
GitHub Copilot Fusion is now generally available and routes each prompt across models. Artificial Analysis measured Fusion Max at $5.59 per task vs $11.42.
Model routing sends each request to the best model for the job. Posts compare routing and cascade approaches like RouteLLM and FrugalGPT, cover Snowflake's dynamic routing in its Cortex AI Gateway, and argue that model loyalty is over.
GitHub Copilot Fusion is now generally available and routes each prompt across models. Artificial Analysis measured Fusion Max at $5.59 per task vs $11.42.
Bito's Governor picks a model for each Claude Code, Cursor, Codex or Copilot request and answers code searches itself. Bito reports a 48% cost cut in one A/B test.
Vercel's switching data, Replit's new default, DeepSeek's silent upgrade, and OpenAI's shutdown calendar point the same way: the model is now a replaceable part, and the power sits with whoever controls which part gets used.
Model Routing and Cascades in Production: Comparing RouteLLM, FrugalGPT, Embedding Classifiers, and Verifier Cascades Enterprise LLM deployments face a persistent structural inefficiency: the uniform routing of all incoming queries to flagship frontier models. Commercial API pricing and self-hosted GPU infrastructure costs span two orders of magnitude between lightweight models (such as Llama 3.1 8B, GPT-4o-mini, and Claude 3.5 Haiku at $0.15 to $0.30 per million tokens) and frontier reasoning
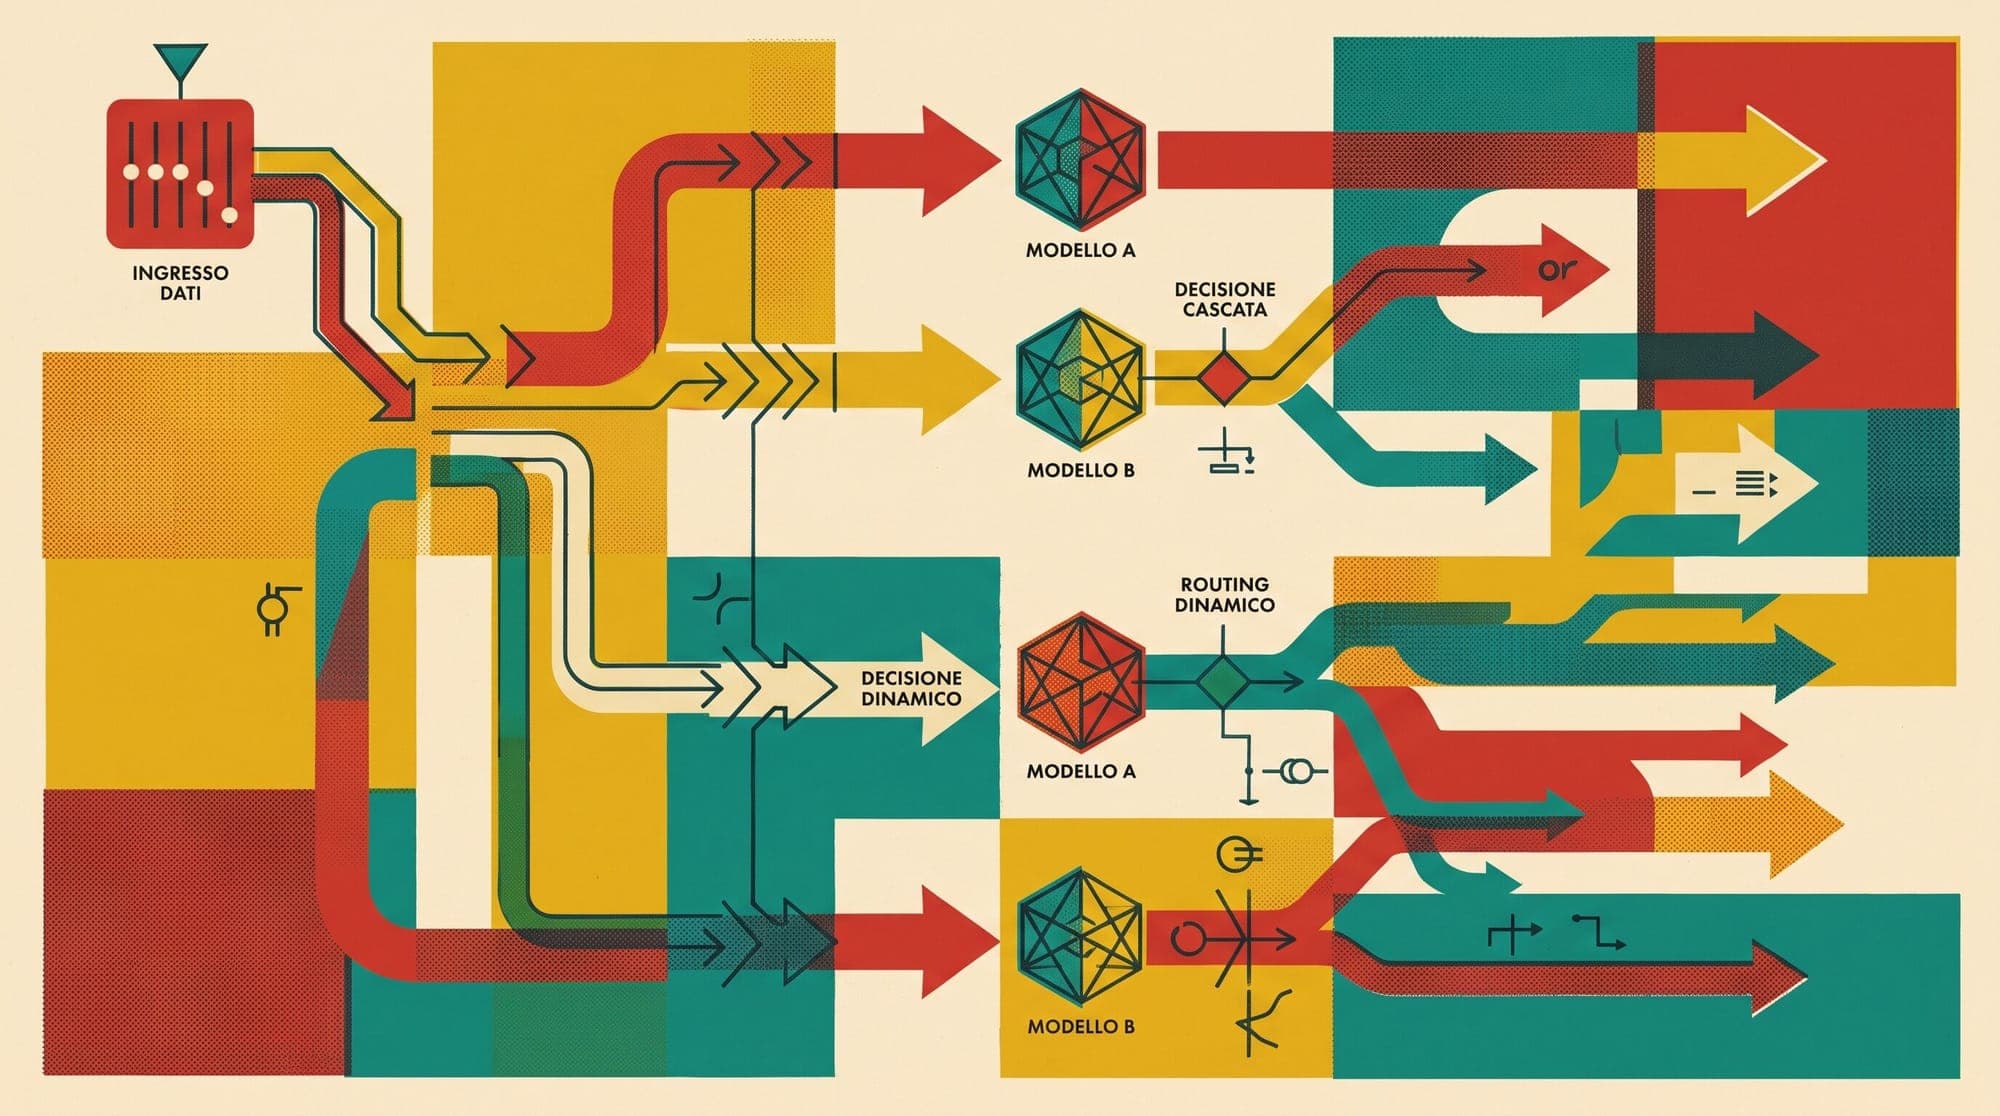
Snowflake has introduced dynamic model routing into its Cortex AI Gateway, allowing enterprise developers to automate large language model selection instead of binding agentic workloads to static endpoints. According to internal benchmarks reported by the company, automated routing can reduce token expenditure by up to 3x across mixed workloads by directing routine queries away from expensive frontier models toward lightweight architectures. The Inference Cost Bottleneck in Agentic Workflows