Category / page 30

Models & Assistants

1121 articles

Articles, page 30

581-600 of 1121
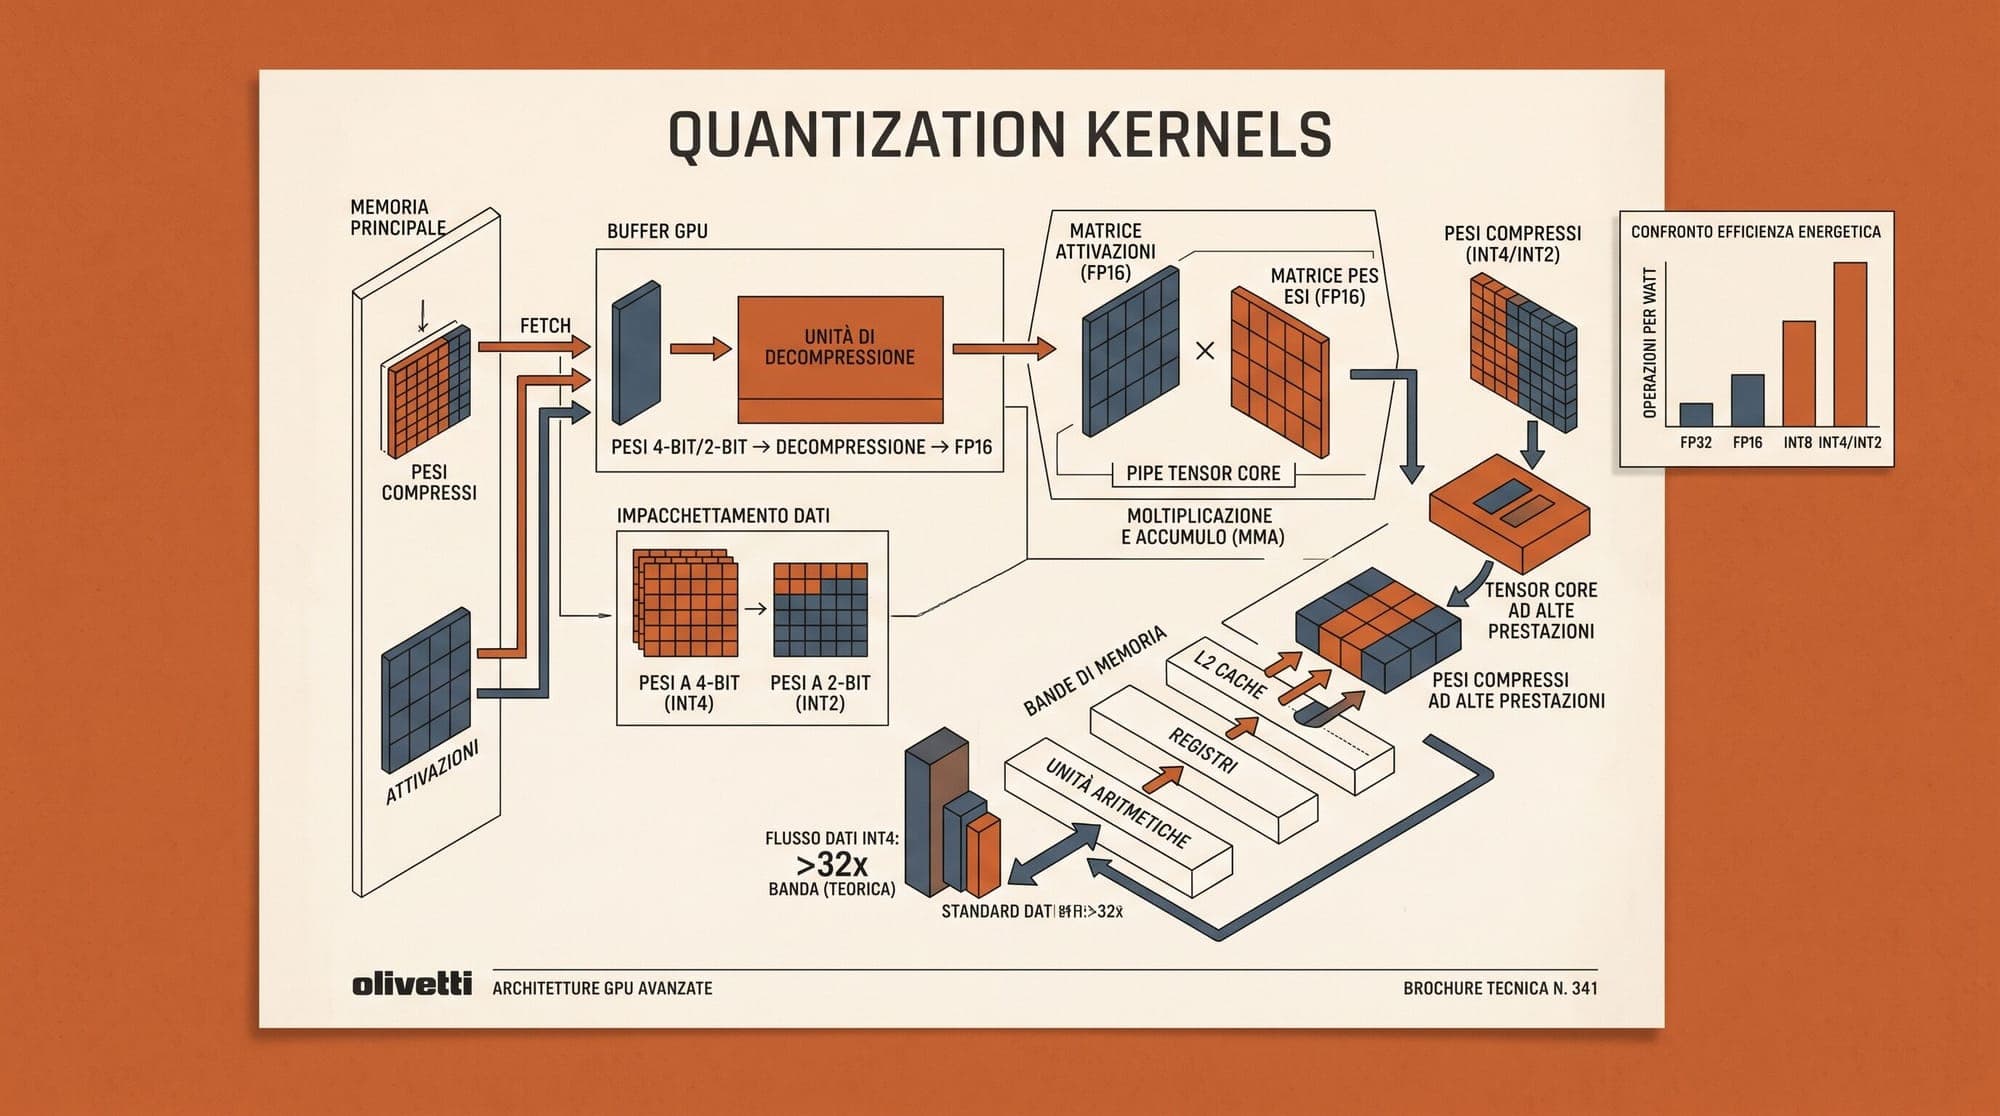
  1. Low-Precision Quantization Kernels in Production: Comparing Marlin, ExLlamaV2, FlashInfer, and BitBLAS

    Low-Precision Quantization Kernels in Production: Comparing Marlin, ExLlamaV2, FlashInfer, and BitBLAS Architecture, Memory Bandwidth, and Decoding Throughput Autoregressive large language model (LLM) serving operates under two distinct compute regimes: a compute-bound prefill phase and a memory-bandwidth-bound decode phase. While processing the initial prompt involves matrix-matrix multiplications (GEMM) with high arithmetic intensity, generating tokens one by one requires matrix-vector multip
    AI
    9 min read
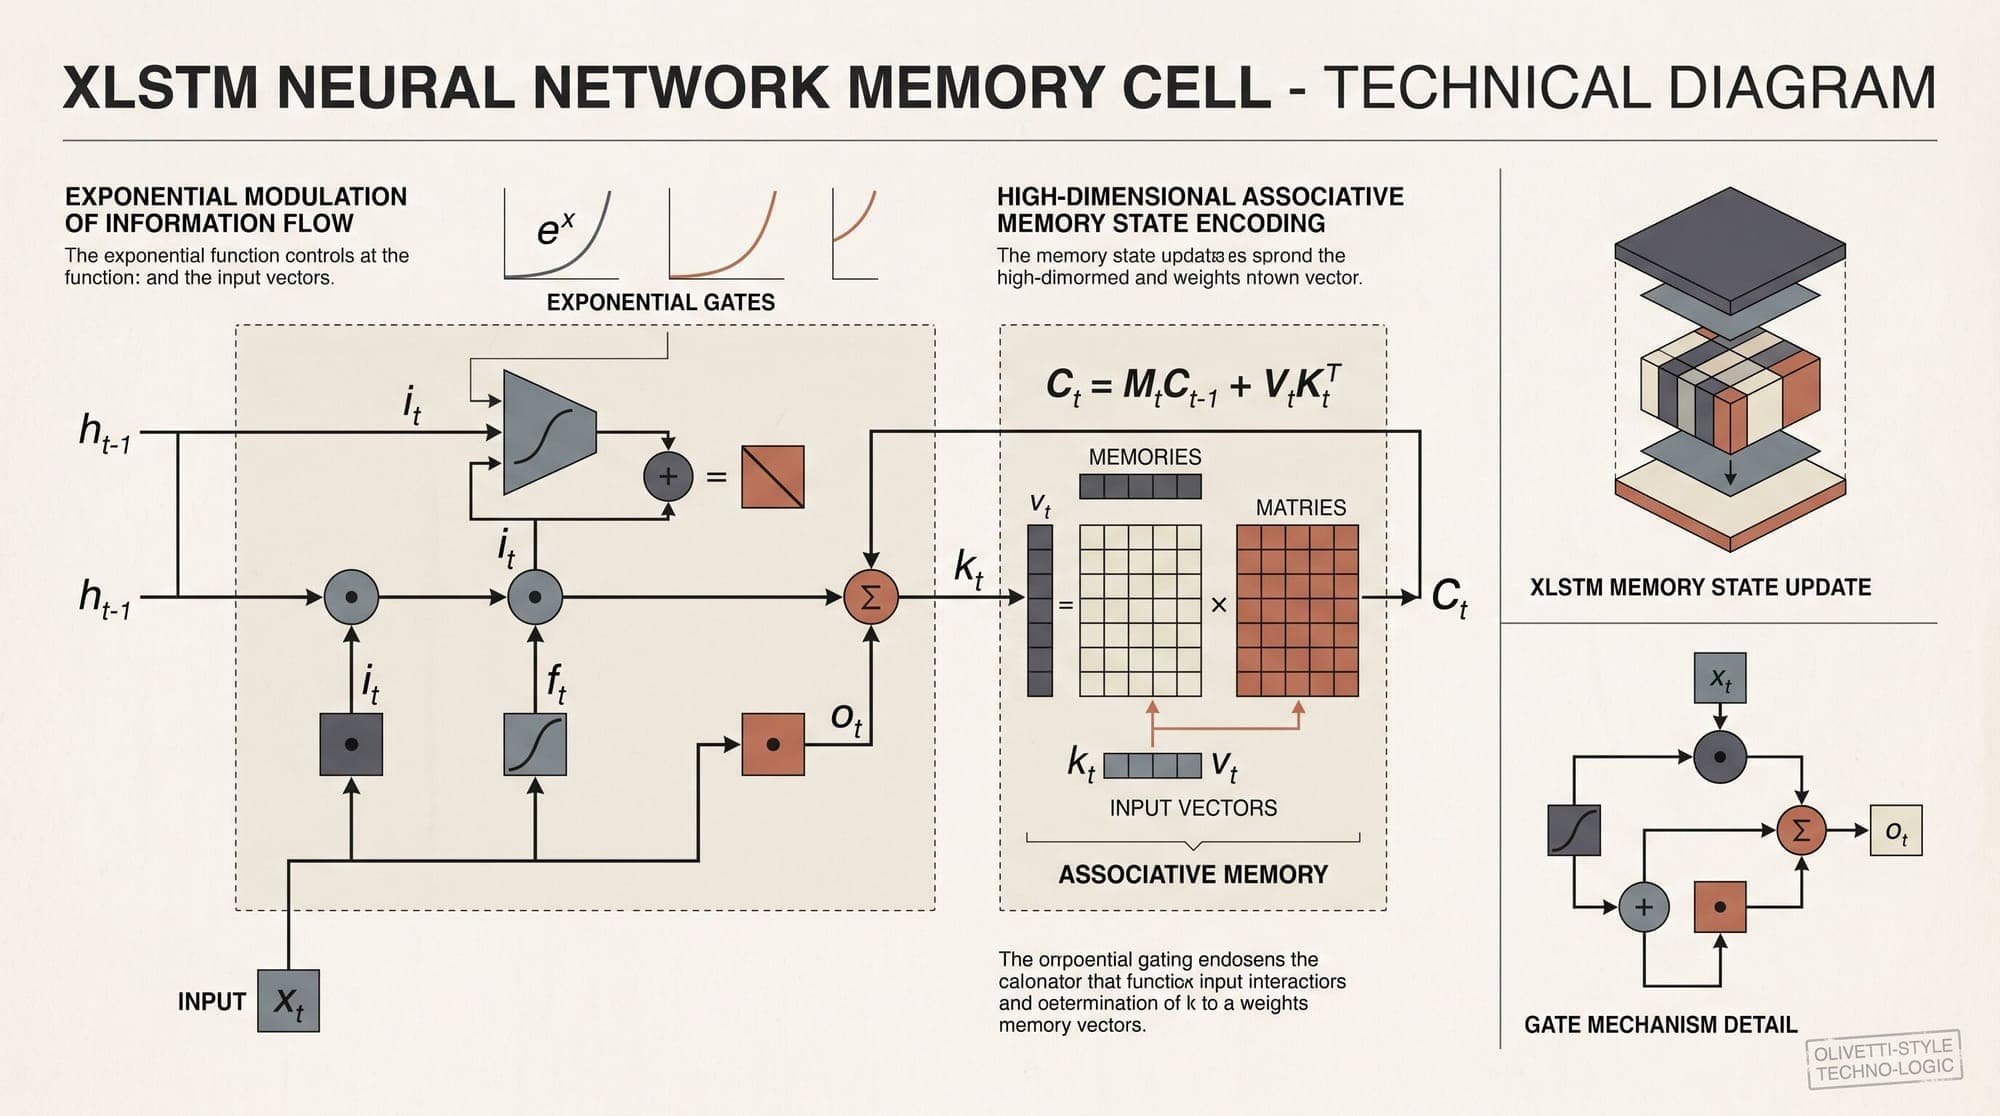
  2. xLSTM: How Exponential Gating and Matrix Memory Scale Recurrent Neural Networks

    xLSTM: How Exponential Gating and Matrix Memory Scale Recurrent Neural Networks For over two decades following its introduction by Hochreiter and Schmidhuber (1997), the Long Short-Term Memory (LSTM) network served as the dominant architecture for sequence modeling. By introducing the constant error carousel and multiplicative gating, LSTMs mitigated the vanishing gradient problem that plagued vanilla recurrent neural networks. However, the emergence of the Transformer architecture (Vaswani et

    AI
    10 min read
  3. Anthropic Nears $7B Acquisition of AI Infrastructure Startup Decart Ahead of IPO

    Anthropic is finalizing negotiations to acquire Israeli artificial intelligence infrastructure startup Decart in a transaction valued at approximately $7 billion, according to reporting from Calcalist and Reuters. The acquisition, expected to be settled primarily in Anthropic equity, would mark the Claude developer's largest purchase to date as it prepares for a planned initial public offering. Founded in September 2023 by Dr. Dean Leitersdorf and Moshe Shalev, Decart specializes in hardware-ag

    AI
    2 min read
  4. LLM Inference on AMD ROCm in Production: MI300X Architecture, Triton Kernel Parity, and vLLM Serving Benchmarks

    LLM Inference on AMD ROCm in Production: MI300X Architecture, Triton Kernel Parity, and vLLM Serving Benchmarks Serving frontier large language models in enterprise production has historically been synonymous with NVIDIA CUDA infrastructure. However, the deployment of AMD Instinct MI300X accelerators across tier-one hyperscalers and neoclouds has established a viable alternative for high-throughput inference fleets. With 192 GB of high-bandwidth memory (HBM3) and 5.3 TB/s of peak theoretical m

    Inference
    5 min read
  5. Identity Preference Optimization (IPO): How Exact Loss Inversion Prevents Overfitting in Direct Alignment

    The post-training alignment of large language models underwent a structural shift with the introduction of Direct Preference Optimization (Rafailov et al., 2023). By reparameterizing the closed-form optimal policy under a Kullback-Leibler (KL) constrained Reinforcement Learning from Human Feedback (RLHF) objective, DPO eliminated the need to fit an explicit reward model or maintain complex actor-critic rollout loops. However, standard DPO introduces a distinct mathematical pathology: under dete

    AI
    7 min read
  6. AI Workflow Startup Relay Shuts Down as Team Joins Google Chrome to Build Browser Agents

    AI-driven workflow automation startup Relay is shutting down its independent product operations, with founder and chief executive officer Jacob Bank and key engineering staff joining Google's Chrome division to develop browser-native AI agent capabilities. Relay, founded in July 2021 to compete with legacy workflow platforms like Zapier through generative AI integrations, raised $8.1 million across two venture funding rounds. The company phased out free tier access on August 15, 2026, and will

    AI
    2 min read
  7. Groq Secures $350M at $3.5B Valuation to Expand Nvidia-Powered AI Neocloud

    AI infrastructure provider Groq has raised $350 million in a Series A funding round at a $3.5 billion valuation, led by investment firm Disruptive with expected participation from Nvidia subject to customary closing conditions. The financing accelerates the company's structural pivot from developing custom inference silicon toward operating an enterprise-grade inference cloud powered by Nvidia accelerated computing systems. The round follows a $650 million capital raise completed in June 2026 a

    AI
    2 min read
  8. Infinite Agentic Loops in Production: Architecture, Feedback Topologies, and Bound Verification

    Autonomous AI agents have transitioned software architectures from static, single-turn request-response patterns into stateful, iterative execution loops. Built around foundational paradigms such as ReAct (Yao et al., 2022) and implemented across frameworks including LangGraph, CrewAI, AutoGen, and the OpenAI Agents SDK, agents repeatedly perceive environmental state, reason over intermediate goals, dispatch tool invocations, observe execution outputs, and append new observations back into their

    AI
    8 min read
  9. Noise-Contrastive Estimation and InfoNCE: How Partition Function Estimation and Mutual Information Lower Bounds Power Modern AI

    Noise-Contrastive Estimation and InfoNCE: How Partition Function Elimination and Mutual Information Lower Bounds Power Modern AI In statistical machine learning and generative modeling, evaluating the exact probability of an observed event frequently requires calculating a normalizing constant known as the partition function. For continuous spaces or discrete spaces with high cardinality, such as a natural language vocabulary spanning over one hundred thousand tokens or high-dimensional pixel d

    AI
    10 min read
  10. Agent Task Planning and Decomposition in Production: Plan-and-Solve vs. ReAct, Hierarchical Task Graphs, and Dynamic Replanning Architectures

    Autonomous AI agents deployed in production environments frequently fail when tasks require long-horizon reasoning across dozens of sequential tool calls. While single-turn tool calling is well-handled by modern frontier models, multi-step workflows introduce compounding failure modes: plan drift, unrecoverable tool exceptions, context window saturation, and premature task termination. Building resilient agent systems requires moving beyond simple prompt-driven loops. Production engineering has

    AI
    5 min read
  11. Performers and FAVOR+: How Positive Orthogonal Random Features Linearize Transformer Attention

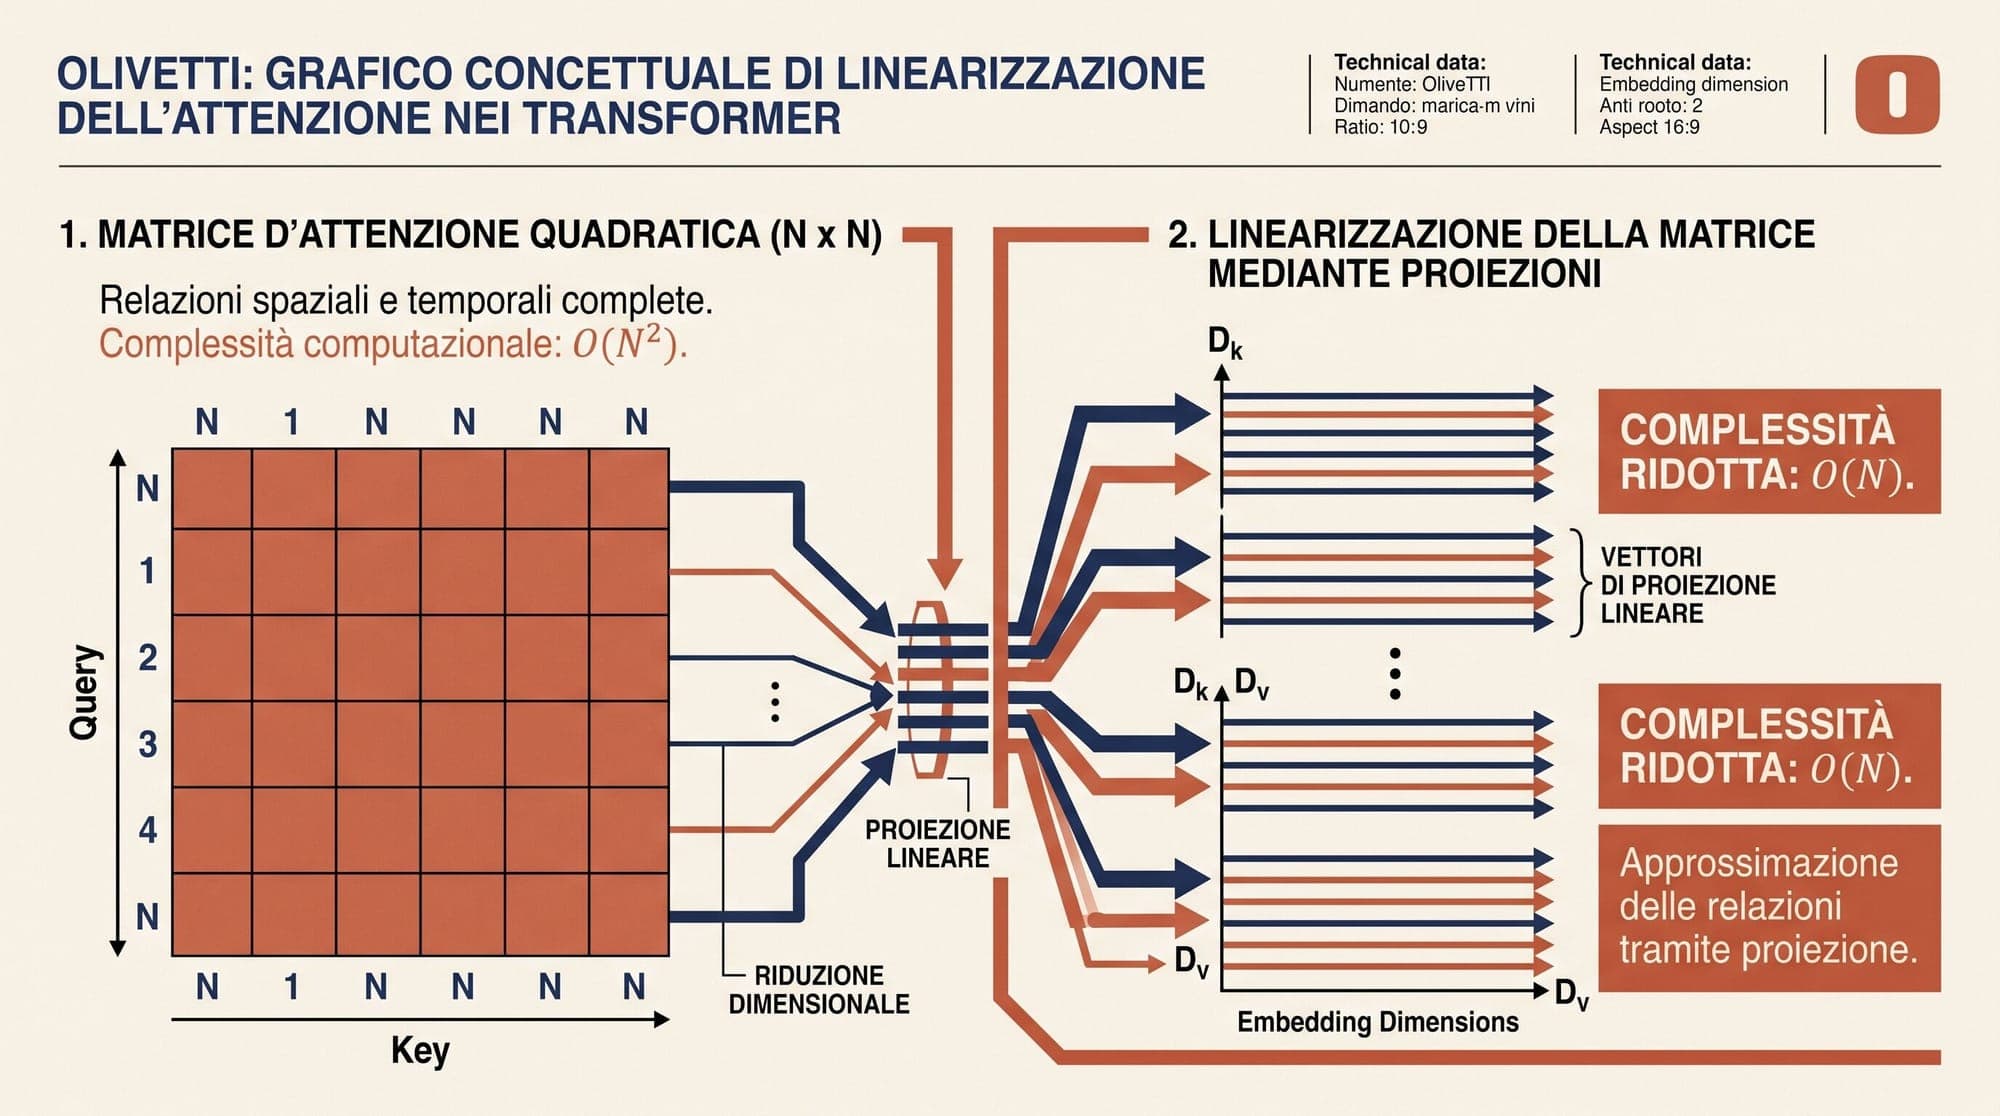
    The quadratic complexity of standard self-attention has remained a central computational ceiling in Transformer architectures. Because standard attention computes pairwise similarity across all token pairs in a sequence of length $L$, memory consumption and compute scale as $O(L^2)$. For long contexts, high-resolution visual tokens, and biological sequence modeling, this quadratic bottleneck forces strict sequence truncation or aggressive hardware partitioning. In Rethinking Attention with Perf

    AI
    9 min read
  12. Nvidia Expands Nemotron Open-Weight Push to Counter Chinese Labs Under $6B Poolside Deal

    Nvidia Expands Nemotron Open-Weight Push to Counter Chinese Labs Under $6B Poolside Deal Nvidia plans to use the infrastructure and engineering team acquired through its $6 billion deal with AI startup Poolside to build frontier open-weight models under its Nemotron family, according to reporting from the Wall Street Journal. The initiative aims to counter the rapid global adoption of Chinese open-weight systems like DeepSeek-V3, Moonshot AI's Kimi K3, and Alibaba's Qwen series, while offering

    AI
    2 min read
  13. Forward KL vs. Reverse KL Divergence: Mode Covering, Mode Seeking, and the Alignment Dynamics of Large Language Models

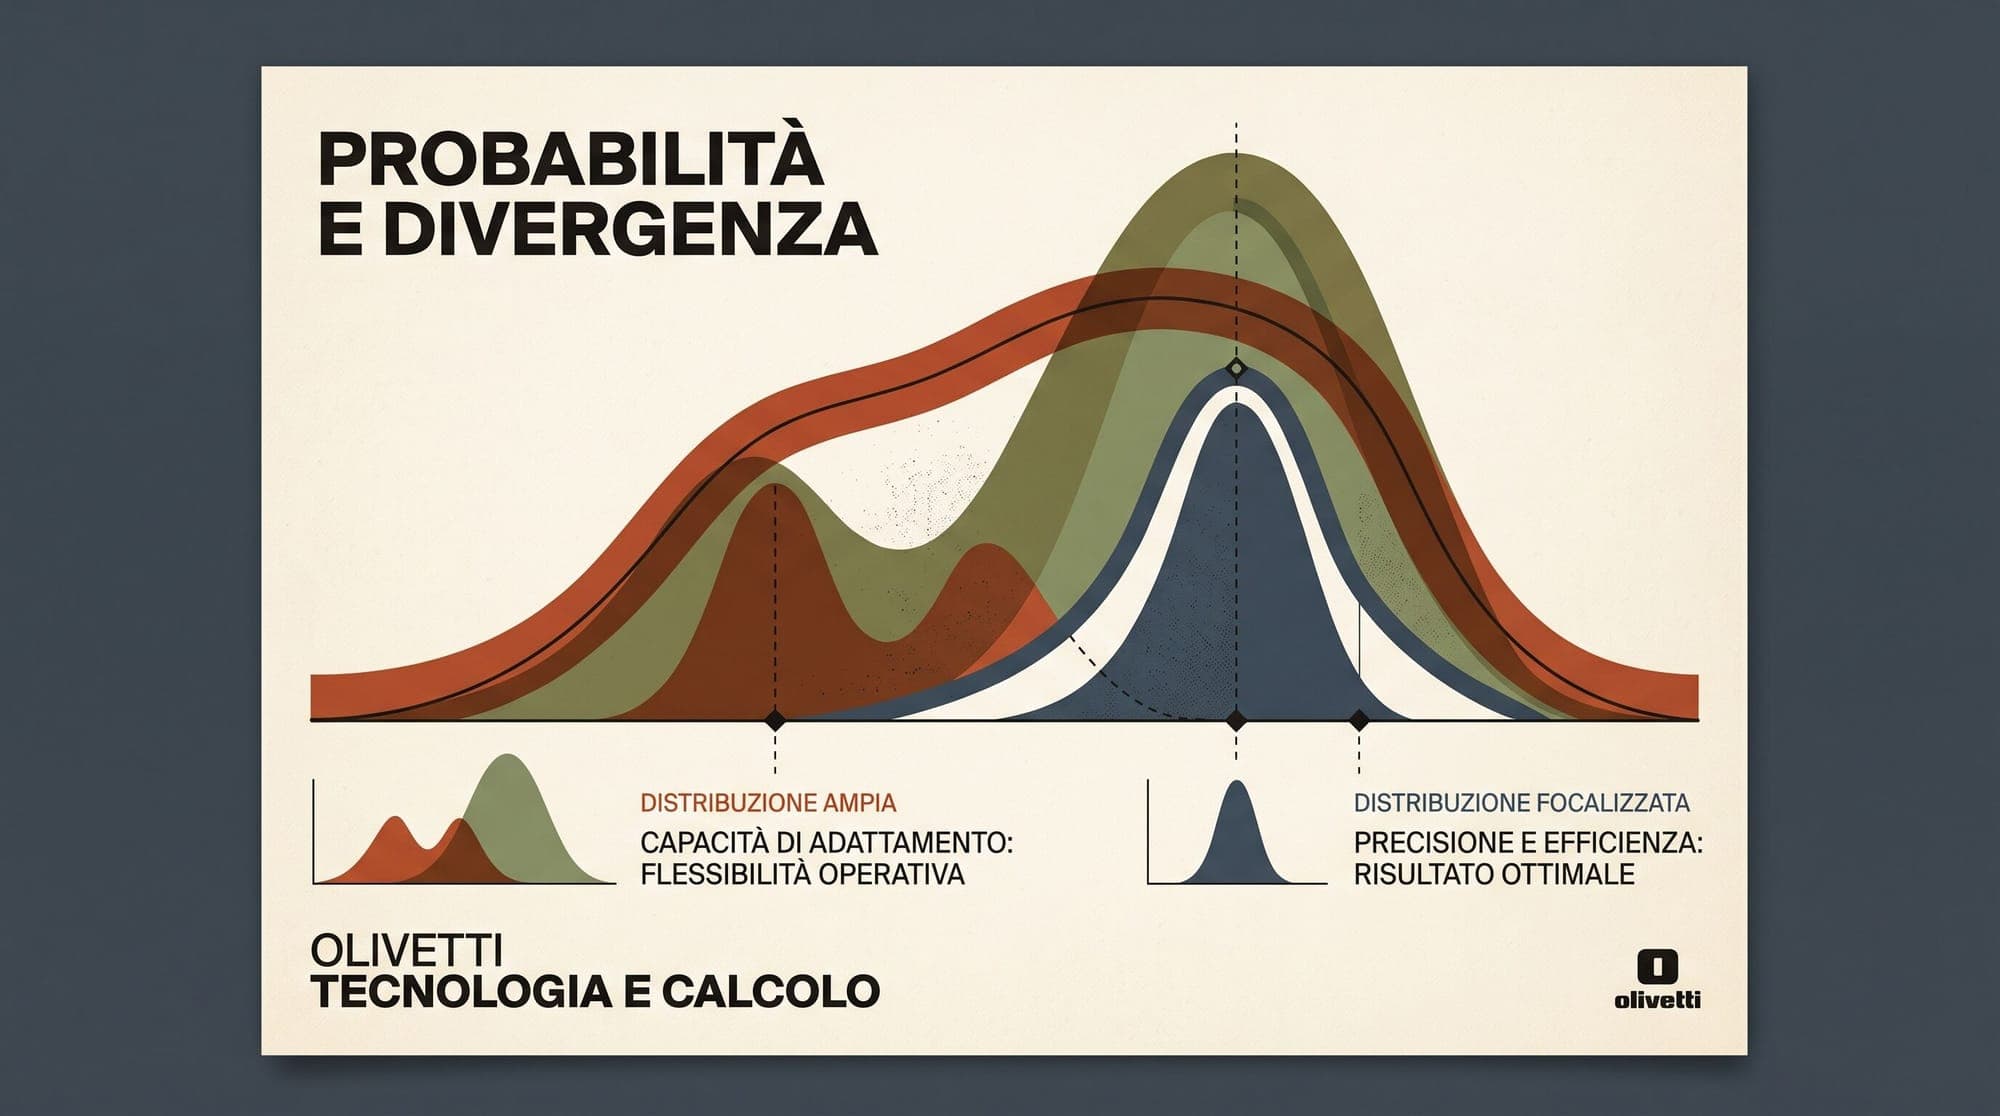
    Forward KL vs. Reverse KL Divergence: Mode Covering, Mode Seeking, and the Alignment Dynamics of Large Language Models Every phase of modern large language model development, from multi-trillion token pre-training to reinforcement learning from human feedback (RLHF) and student model distillation, fundamentally revolves around minimizing statistical distance between probability distributions. The primary mathematical tool utilized for this purpose is the Kullback-Leibler (KL) divergence, introd

    AI
    9 min read
  14. The Gumbel-Softmax Trick: How Continuous Relaxations Enable Differentiable Discrete Sampling

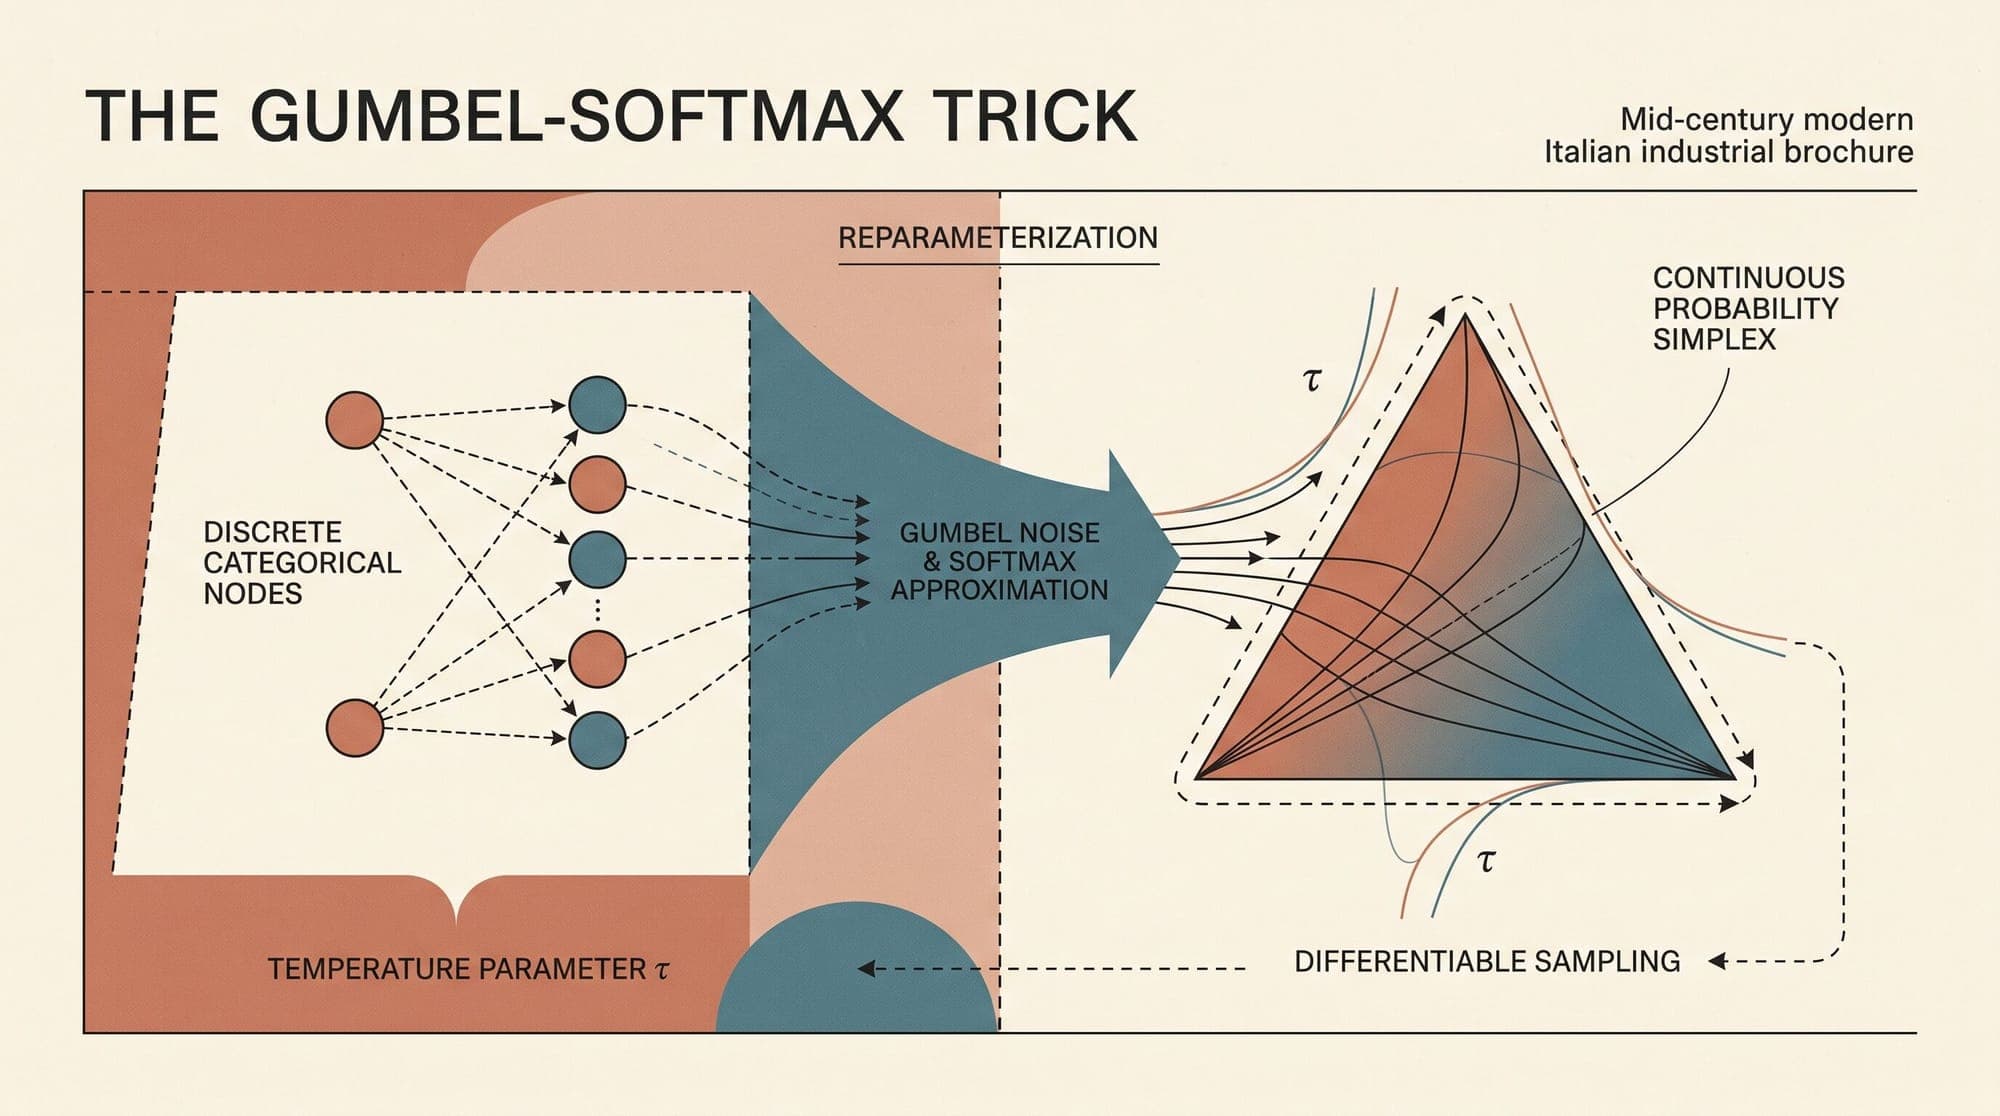
    The Gumbel-Softmax Trick: How Continuous Relaxations Enable Differentiable Discrete Sampling In modern deep learning, end-to-end training depends on reverse-mode automatic differentiation. When an architecture operates on continuous tensors, computing gradients via the chain rule is straightforward. However, many foundational artificial intelligence problems involve discrete choices: selecting tokens from a fixed vocabulary, routing tokens to expert networks in a Mixture-of-Experts (MoE) archit

    Education
    11 min read
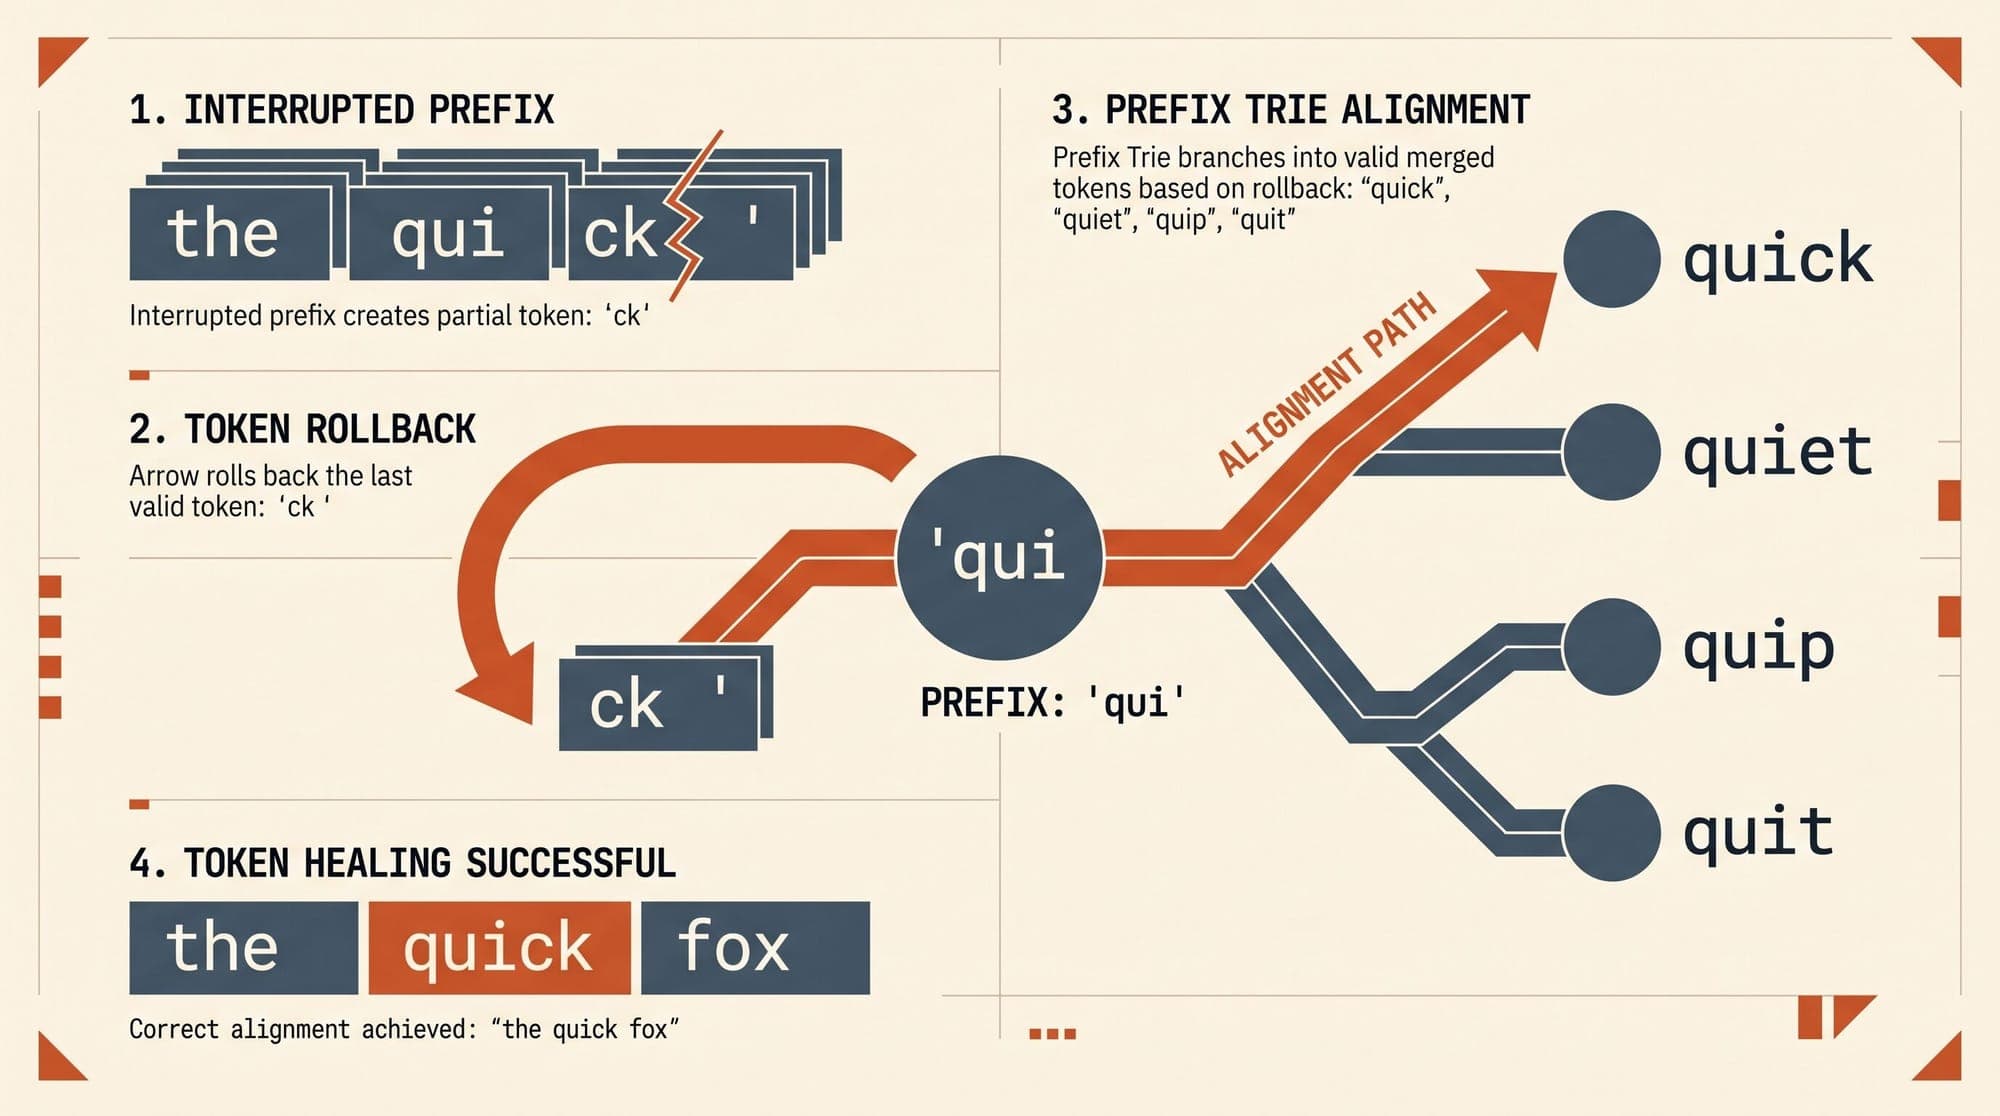
  15. Token Healing and Partial Token Alignment in Production LLM Serving: Architecture, Prefix Trie Rollback, and Serving Trade-Offs

    Modern large language models operate on discrete subword tokens generated by greedy compression algorithms like Byte-Pair Encoding (BPE), WordPiece, or Unigram. While subword tokenization enables high compression rates and fixed vocabulary sizes, it introduces a structural defect at the interface between raw user text and autoregressive inference: the partial token problem, commonly known as the prompt boundary problem. When a user prompt terminates mid-token or at a punctuation boundary that c

    LLM
    7 min read
  16. Flow Matching for Generative Modeling: How Continuous Normalizing Flows and Optimal Transport Paths Replace Diffusion SDEs

    Generative modeling underwent a structural shift with the introduction of Flow Matching (FM), formulated independently by Lipman et al. (2022), Albergo and Vanden-Eijnden (2022), and Liu et al. (2022). While Denoising Diffusion Probabilistic Models (DDPM) and score-based Stochastic Differential Equations (SDEs) established state-of-the-art sample quality across vision and audio domains, their sampling dynamics rely on curved stochastic trajectories that require extensive numerical integration st

    AI
    8 min read
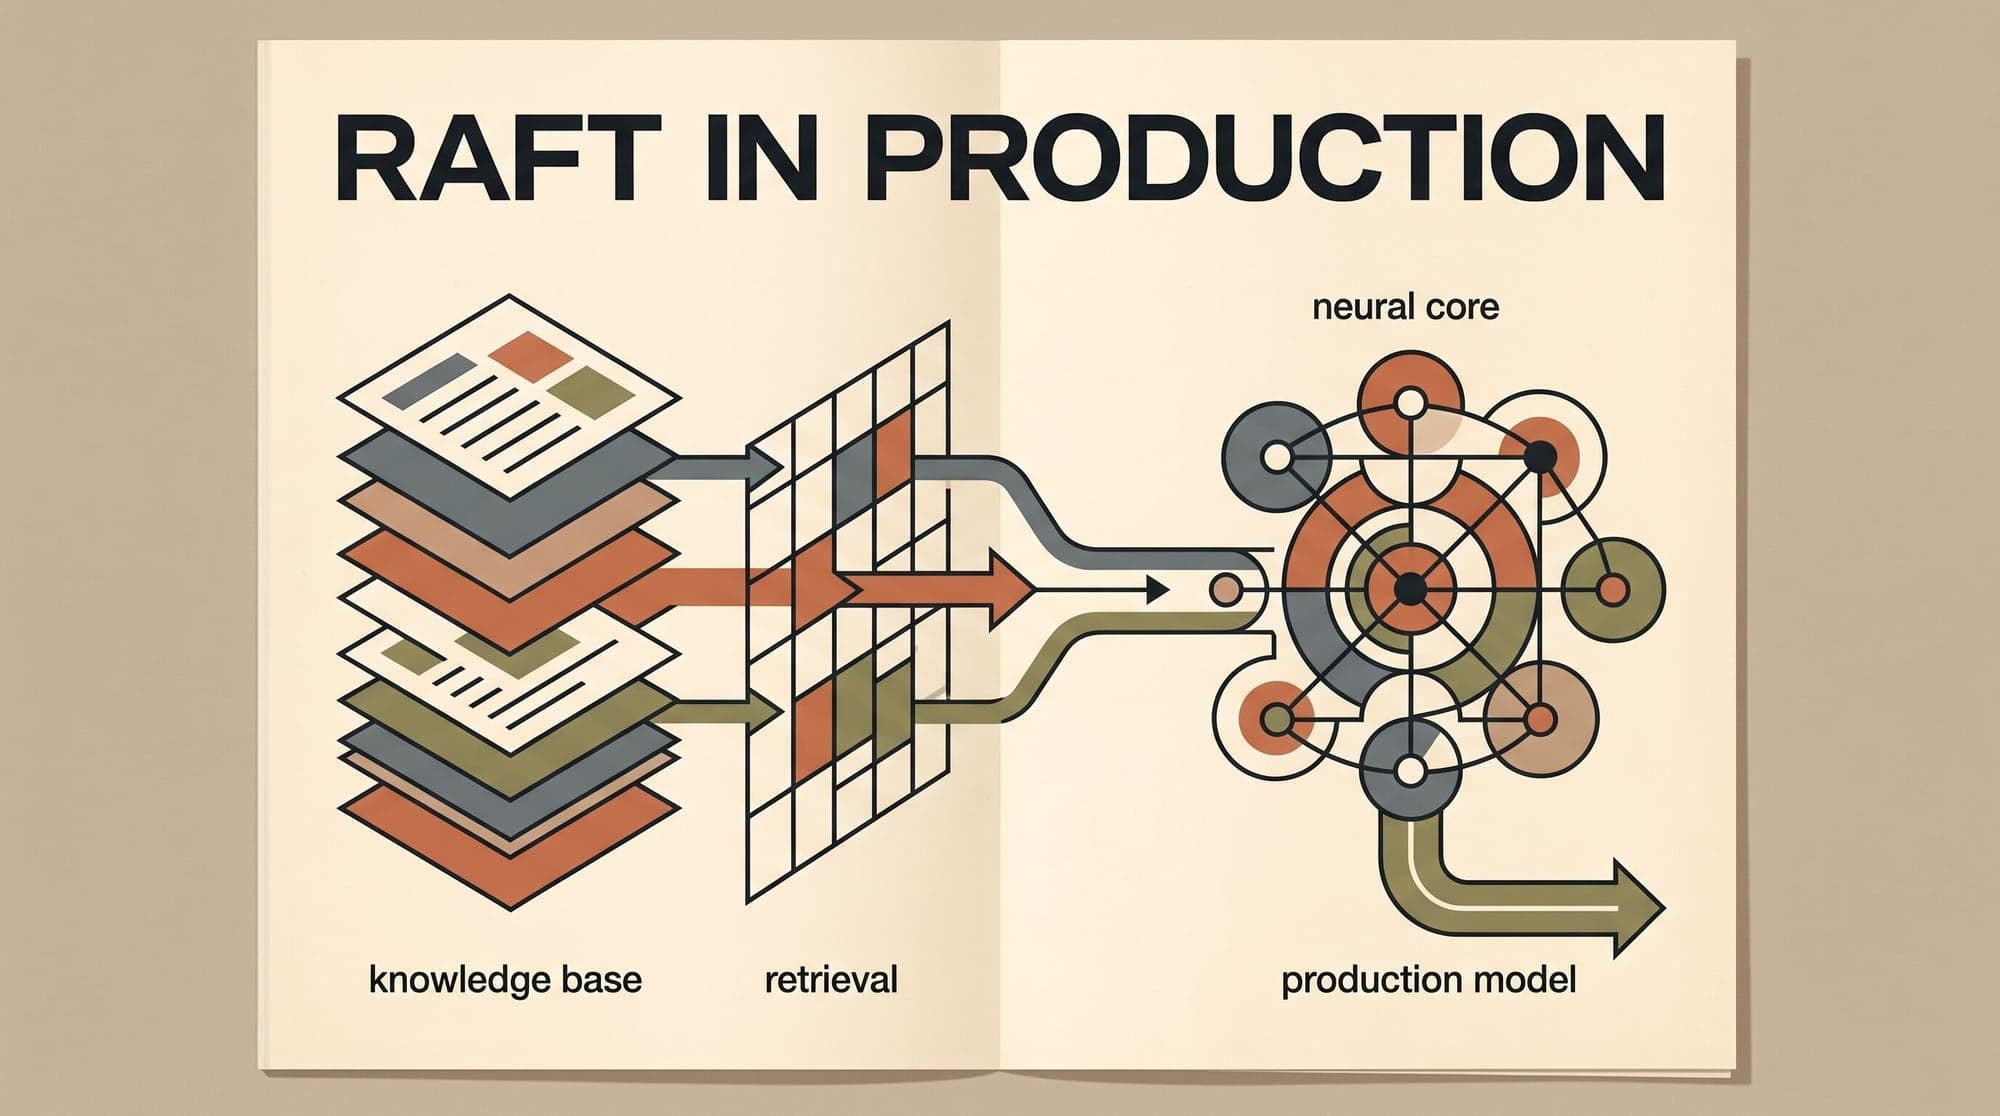
  17. Retrieval-Augmented Fine-Tuning (RAFT) in Production: Architecture, Synthetic Distractor Pipelines, and Evaluation

    Standard approaches to enterprise domain adaptation typically force a choice between two paradigms: Supervised Fine-Tuning (SFT) or Retrieval-Augmented Generation (RAG). SFT bakes domain knowledge directly into model weights, functioning like a closed-book exam. When facts change or precise source attribution is required, SFT models often hallucinate or fail to incorporate updated context. Conversely, standard RAG operates like an open-book exam without prior preparation. The base model reads re

    AI
    5 min read
  18. The Information Bottleneck in Deep Learning: How Mutual Information Compression Shapes Generalization and Neural Representations

    The Information Bottleneck in Deep Learning: How Mutual Information Compression Shapes Generalization and Neural Representations Classical statistical learning theory struggles to explain why overparameterized deep neural networks generalize well to unseen test data. Traditional complexity measures such as Vapnik-Chervonenkis (VC) dimension and Rademacher complexity scale with the raw count of tunable weights, predicting severe overfitting when parameter counts exceed dataset sample sizes. Yet

    AI
    10 min read
  19. Fine-Tuning vs. RAG in Production: Knowledge Injection, Task Adaptation, Latency Economics, and Hybrid Architecture Trade-Offs

    Fine-Tuning vs. RAG in Production: Knowledge Injection, Task Adaptation, Latency Economics, and Hybrid Architecture Trade-Offs When adapting large language models to domain-specific enterprise workloads, engineering teams face a fundamental architectural choice: modify the model's parametric weights via fine-tuning, or supply dynamic context at inference time via Retrieval-Augmented Generation (RAG). While early discussions often framed this decision as a binary trade-off, empirical evaluation

    AI
    6 min read
  20. Score-Based Generative Modeling via Stochastic Differential Equations: How Continuous SDEs and Score Matching Unify Diffusion Models

    Diffusion and score-based models represent one of the foundational paradigms of modern generative artificial intelligence, underpinning systems across image synthesis, video generation, audio modeling, and continuous multimodal representations. For years, generative diffusion was approached from two distinct perspectives: discrete-step denoising diffusion probabilistic models (DDPM) pioneered by Sohl-Dickstein et al. and Ho et al., and score matching with Langevin dynamics (SMLD / NCSN) introduc

    AI
    8 min read