Subscribe
Topic / page 7

Inference

Articles, page 7

121-131
  1. LLM Serving Frameworks in Production: SGLang vs. vLLM vs. TensorRT-LLM Architecture, Memory Management, and Throughput Trade-Offs

    Serving large language models in production has moved beyond simple iteration-level scheduling. While basic continuous batching solved the fundamental problem of GPU starvation during autoregressive decoding, modern production demands have shifted the engineering bottleneck toward KV cache memory reuse, compilation overhead, and structured generation efficiency. Three dominant serving runtimes currently lead high-throughput deployments: vLLM, SGLang, and NVIDIA TensorRT-LLM. Each framework appr
    Inference
    4 min read
  2. Etched in Talks to Raise $700M Led by Jane Street at $21B Valuation

    AI inference chip startup Etched is in negotiations to raise $700 million in a new financing round led by existing investor Jane Street, according to reporting from The Wall Street Journal. The proposed financing would value the San Jose-based semiconductor company at approximately $21 billion. The planned round follows a $300 million Series C led by Sequoia Capital that valued the startup at $10.3 billion, effectively doubling its valuation within weeks amid intensifying enterprise demand for

    Hardware
    2 min read
  3. Continuous Batching in Production LLM Serving: Iteration-Level Scheduling, Chunked Prefills, and Throughput Trade-Offs

    Static batching served as the standard execution paradigm for deep learning inference across computer vision and traditional natural language processing for years. In those domains, incoming requests typically feature fixed input dimensions and deterministic execution graphs. Autoregressive large language model serving breaks every assumption underlying static batching. Input prompts vary widely in token length, output generations terminate nondeterministically upon emitting an end-of-sequence t

    LLM
    6 min read
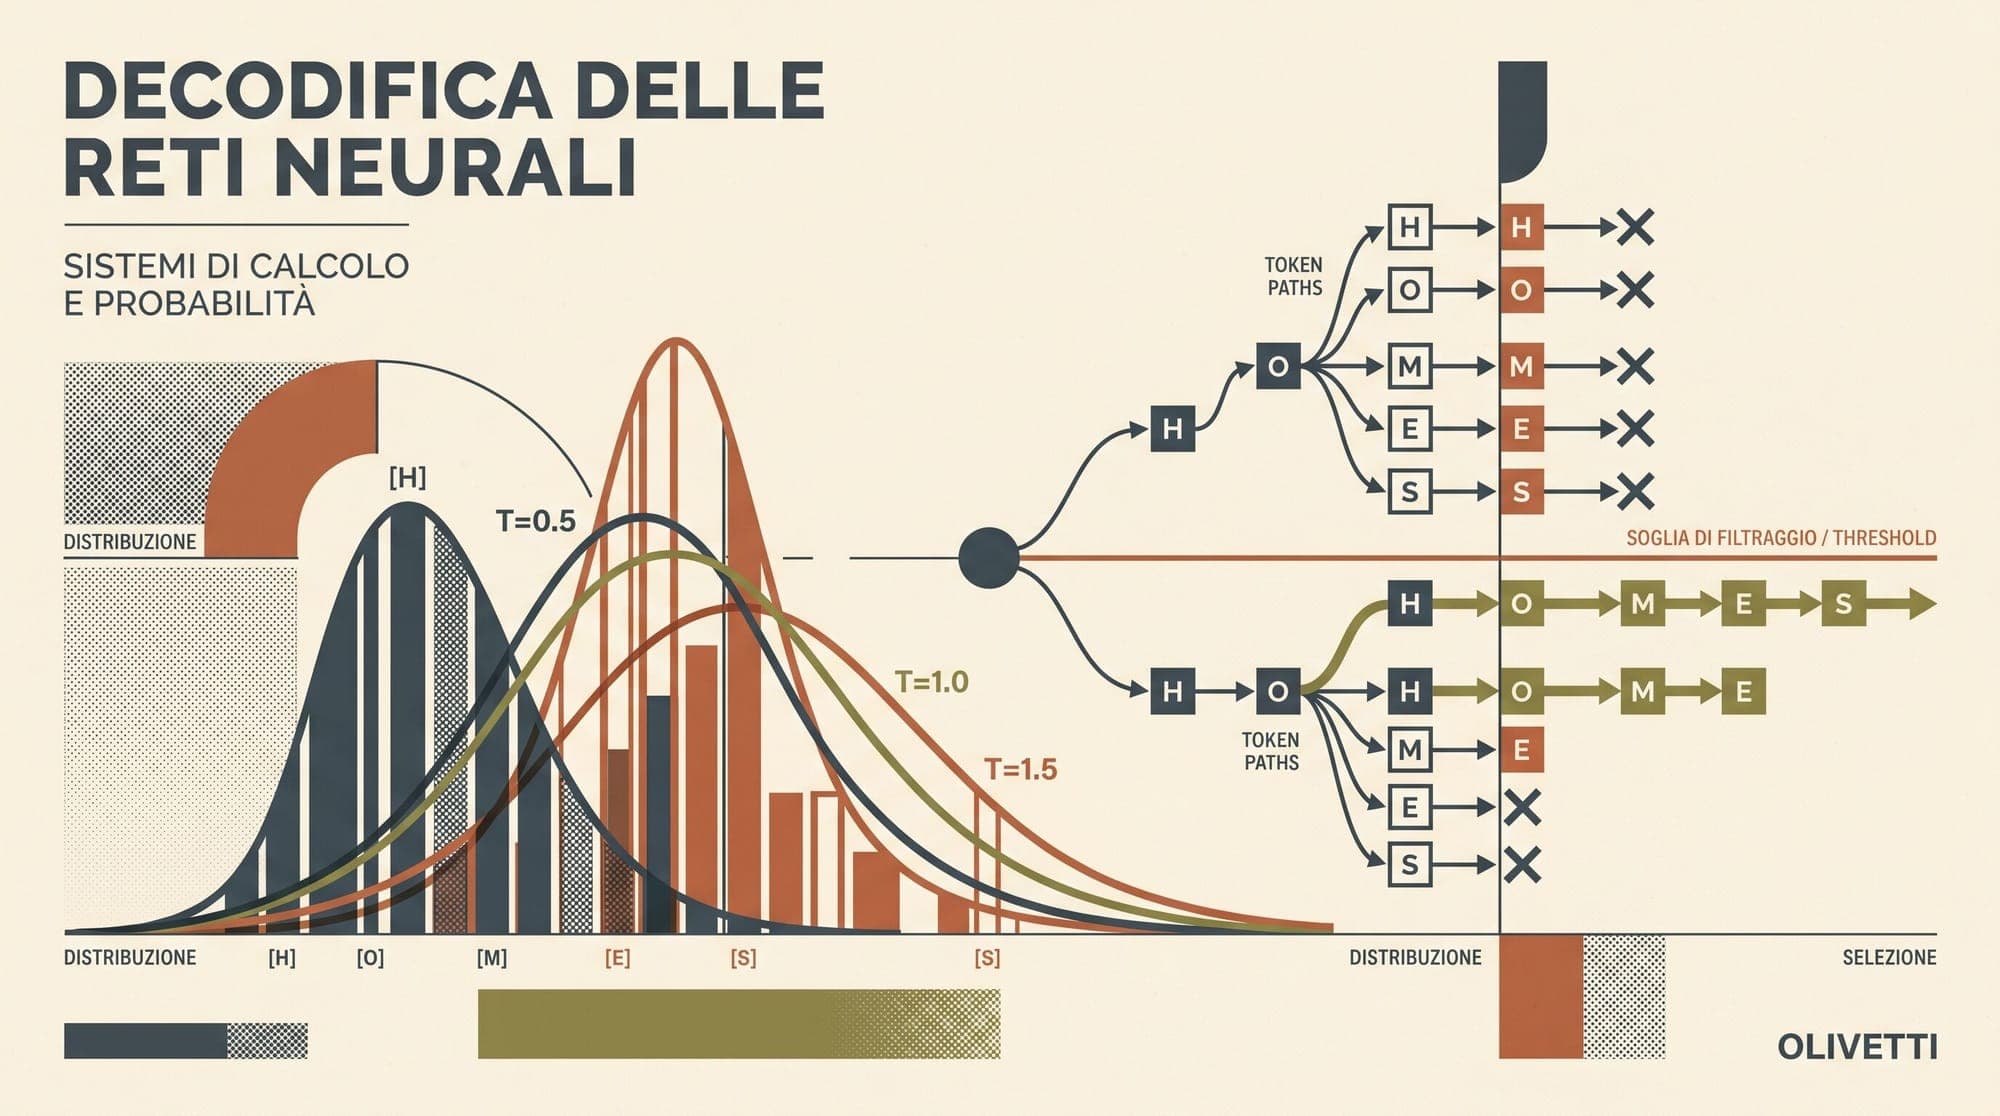
  4. Token Sampling in Large Language Models: How Temperature, Top-k, Top-p, and Min-p Govern Generative Decoding

    Large language models are autoregressive next-token predictors. During inference, the neural network processes an input context and outputs a vector of unnormalized scores, known as logits, across every token in its vocabulary. The mathematical pipeline that converts those raw logits into a single chosen token is the sampling and decoding stage. While model architecture and pre-training weights determine what a model knows, sampling algorithms govern how that knowledge is extracted. Small chang

    AI
    7 min read
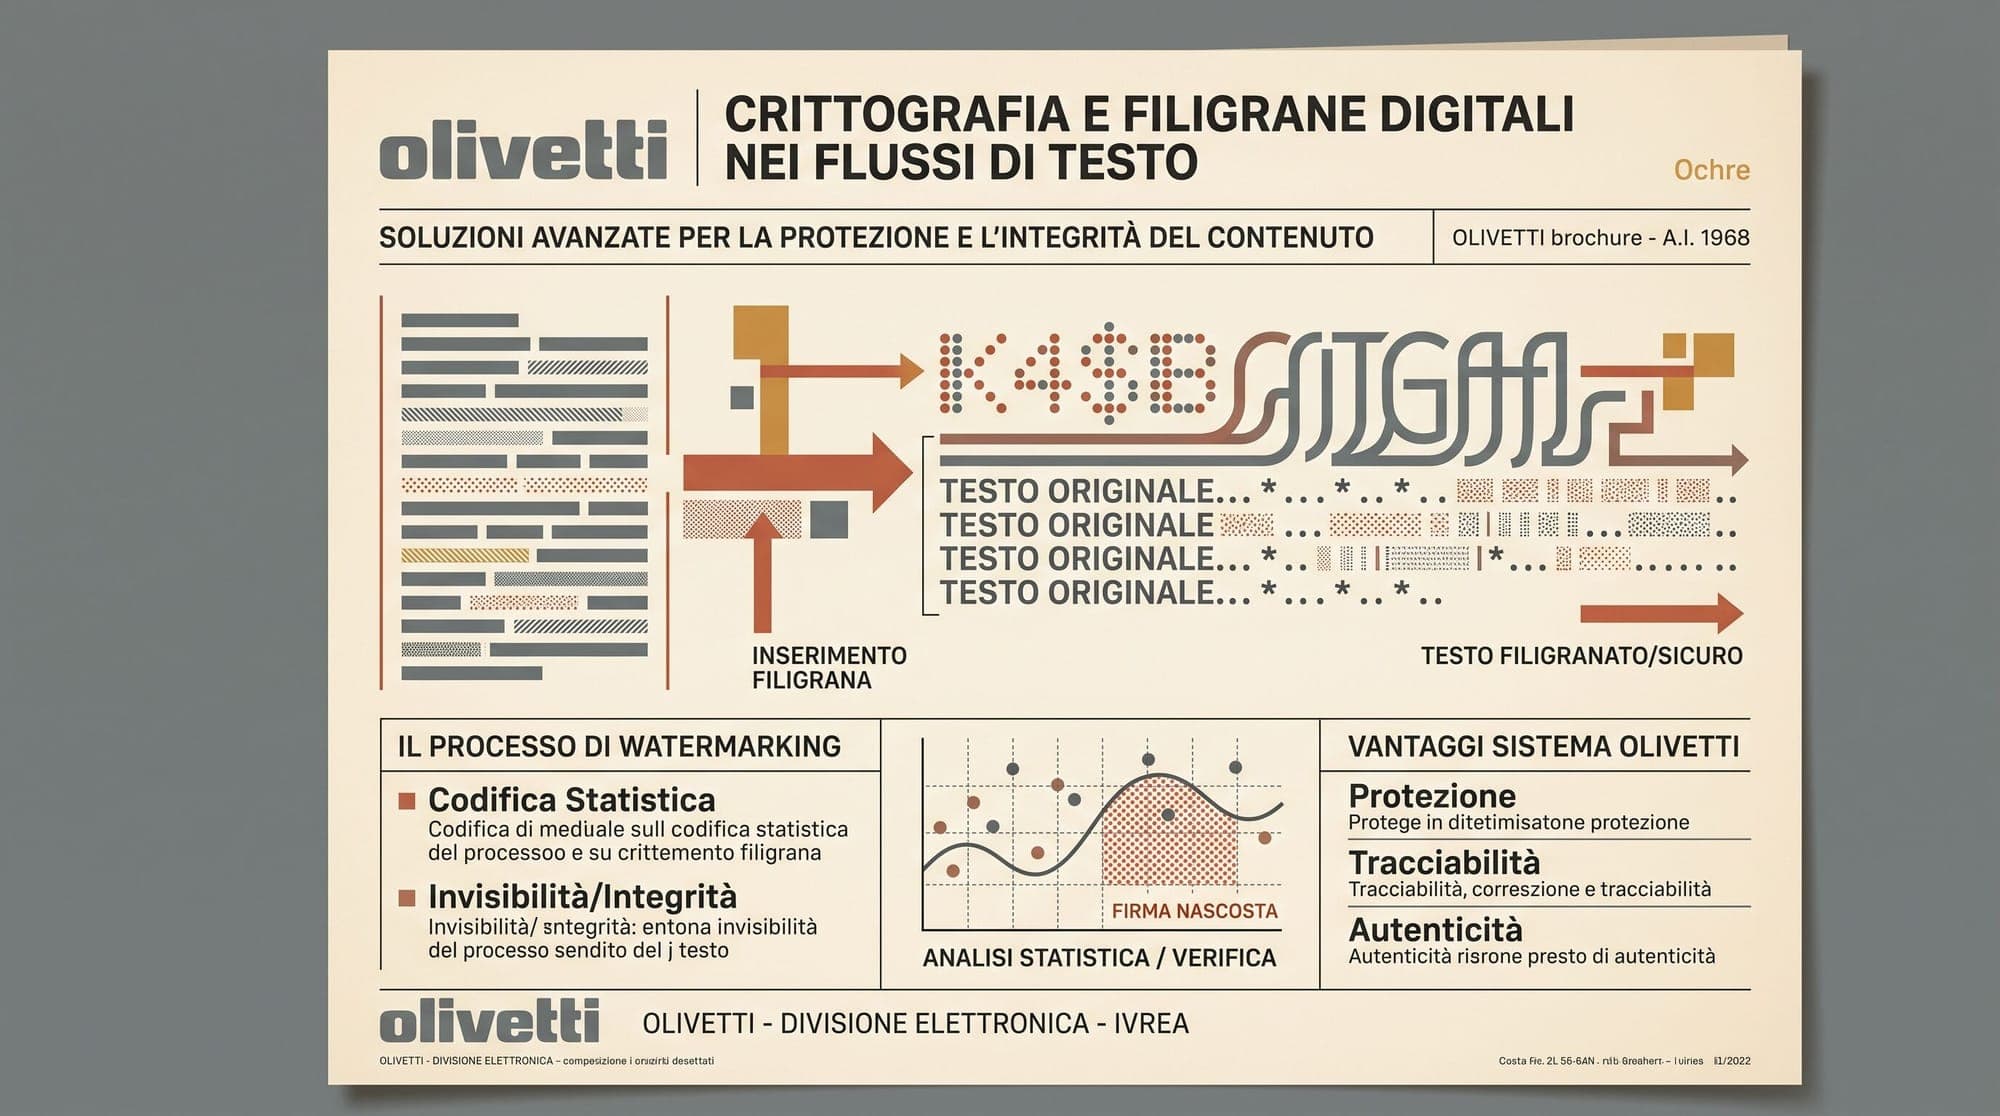
  5. Anthropic Rolls Out Global AI Text Watermarking for Claude to Comply with EU AI Act

    Anthropic has started deploying model-level text watermarking across Claude to meet the regulatory requirements of the European Union AI Act. The company confirmed that because it currently lacks infrastructure to reliably partition model inference behavior by geographic jurisdiction, watermarking is being applied globally across all Claude web products and API endpoints. The update follows the formalization of the EU Code of Practice on Transparency of AI-Generated Content, signed in July 2026

    Anthropic
    2 min read
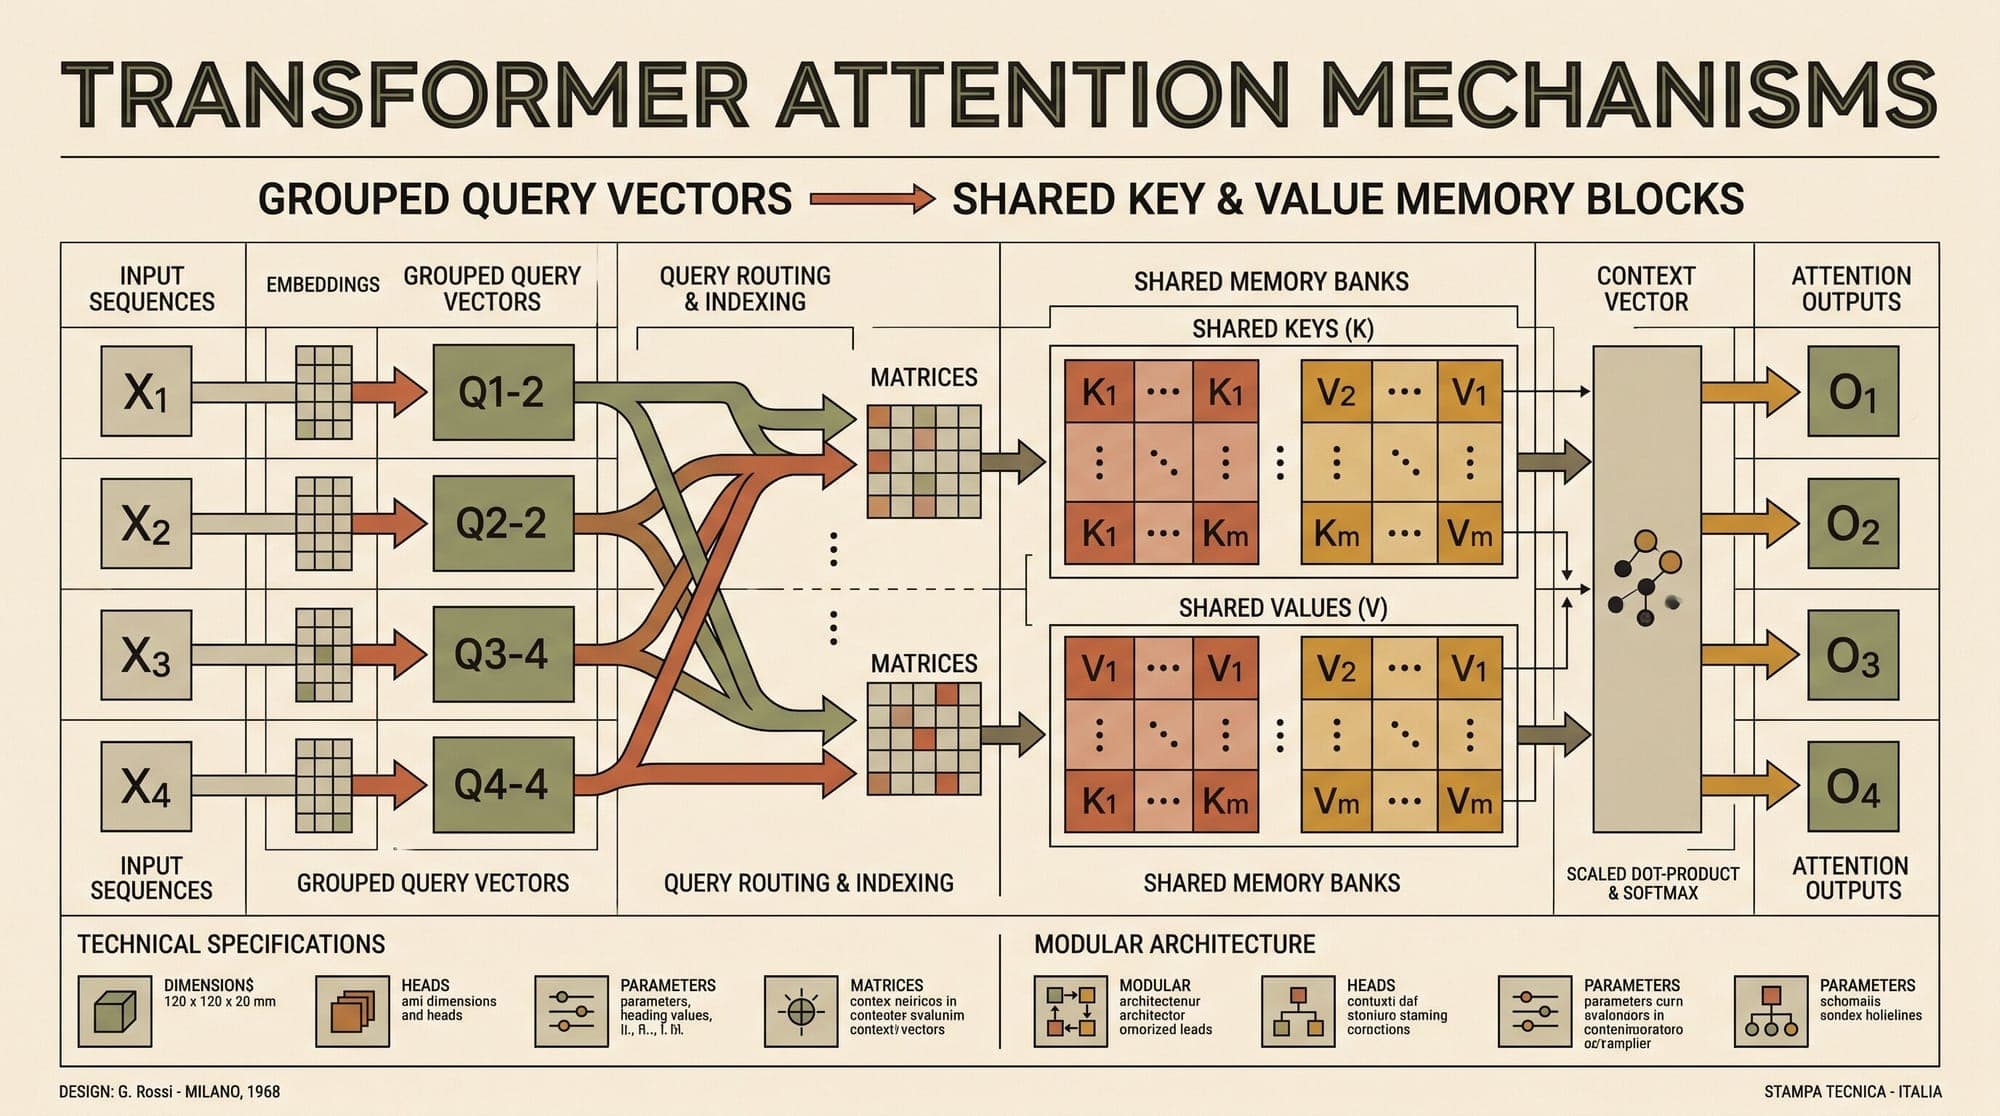
  6. Grouped-Query Attention: How Head Sharing Slashed KV Cache Memory and Scaled LLM Serving

    Serving large language models at scale presents a fundamental hardware bottleneck: autoregressive decoding is bound by memory bandwidth rather than compute. While the initial prompt processing phase (prefill) operates as compute-bound matrix multiplications, token-by-token generation requires loading billions of cached attention states from GPU High-Bandwidth Memory (HBM) to on-chip SRAM for every single generated token. Multi-Head Attention (MHA), introduced in the foundational Vaswani et al.

    AI
    6 min read
  7. LLM Model Routing and Cascades: Architecture, Economics, and Quality Trade-Offs

    In modern enterprise AI systems, uniform model dispatch, sending all incoming user traffic to a single frontier large language model, is one of the most common architectural inefficiencies. Frontier models like GPT-4o and Claude 3.5 Sonnet provide industry-leading reasoning and code generation capabilities, but their inference costs range between $2.50 and $15.00 per million tokens. Conversely, smaller open-weights or distilled models, such as Llama 3.1 8B or GPT-4o-mini, execute at a fraction o

    AI
    6 min read
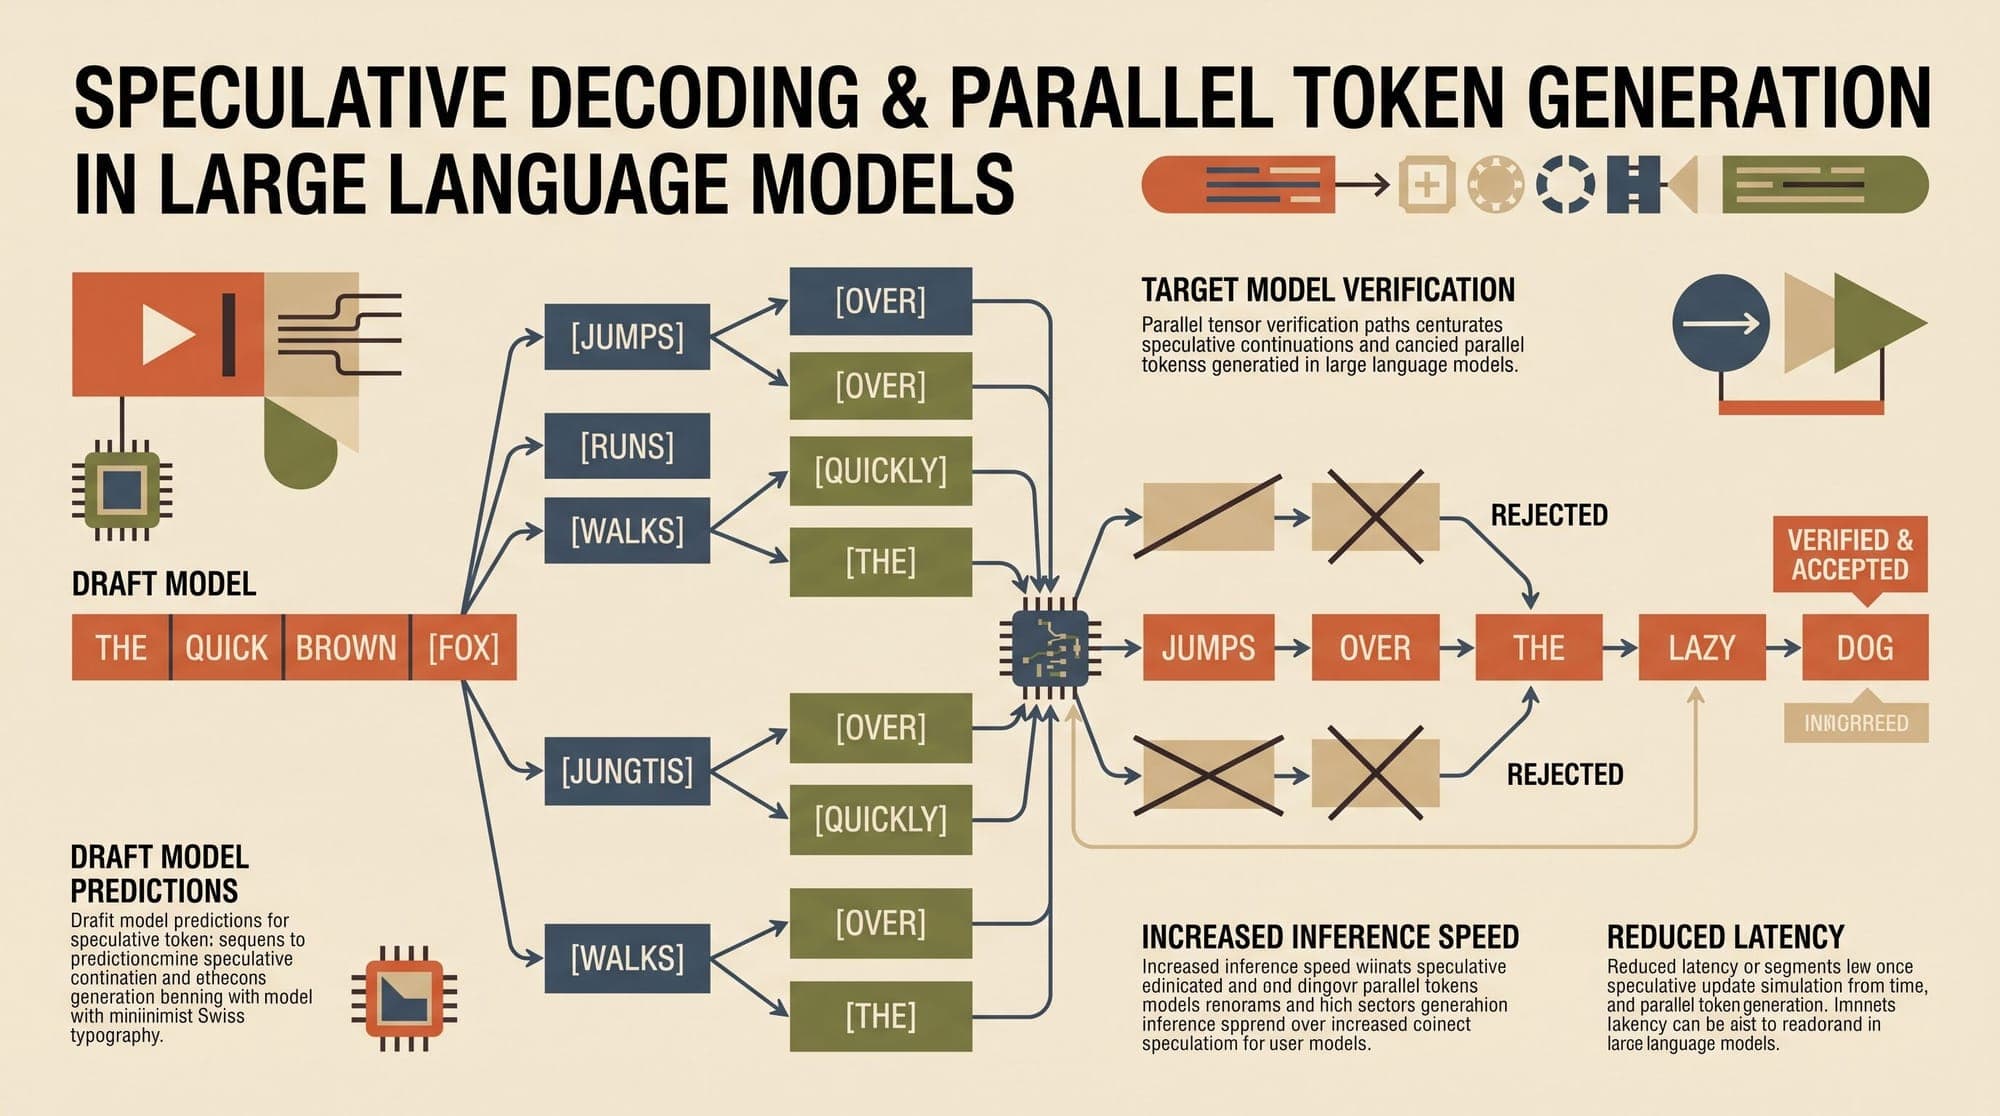
  8. Speculative Decoding in Production: Architecture, Economics, and Serving Trade-Offs

    Standard autoregressive large language model (LLM) generation produces one token per forward pass. Because modern inference architectures must read tens of gigabytes of model weights from high-bandwidth memory (HBM) into SRAM to process each solitary token at low batch sizes, generation is strictly memory-bandwidth bound rather than compute bound. Speculative decoding alters this hardware equation. By pairing a fast draft mechanism with parallel verification by the primary target model, inferen

    LLM
    6 min read
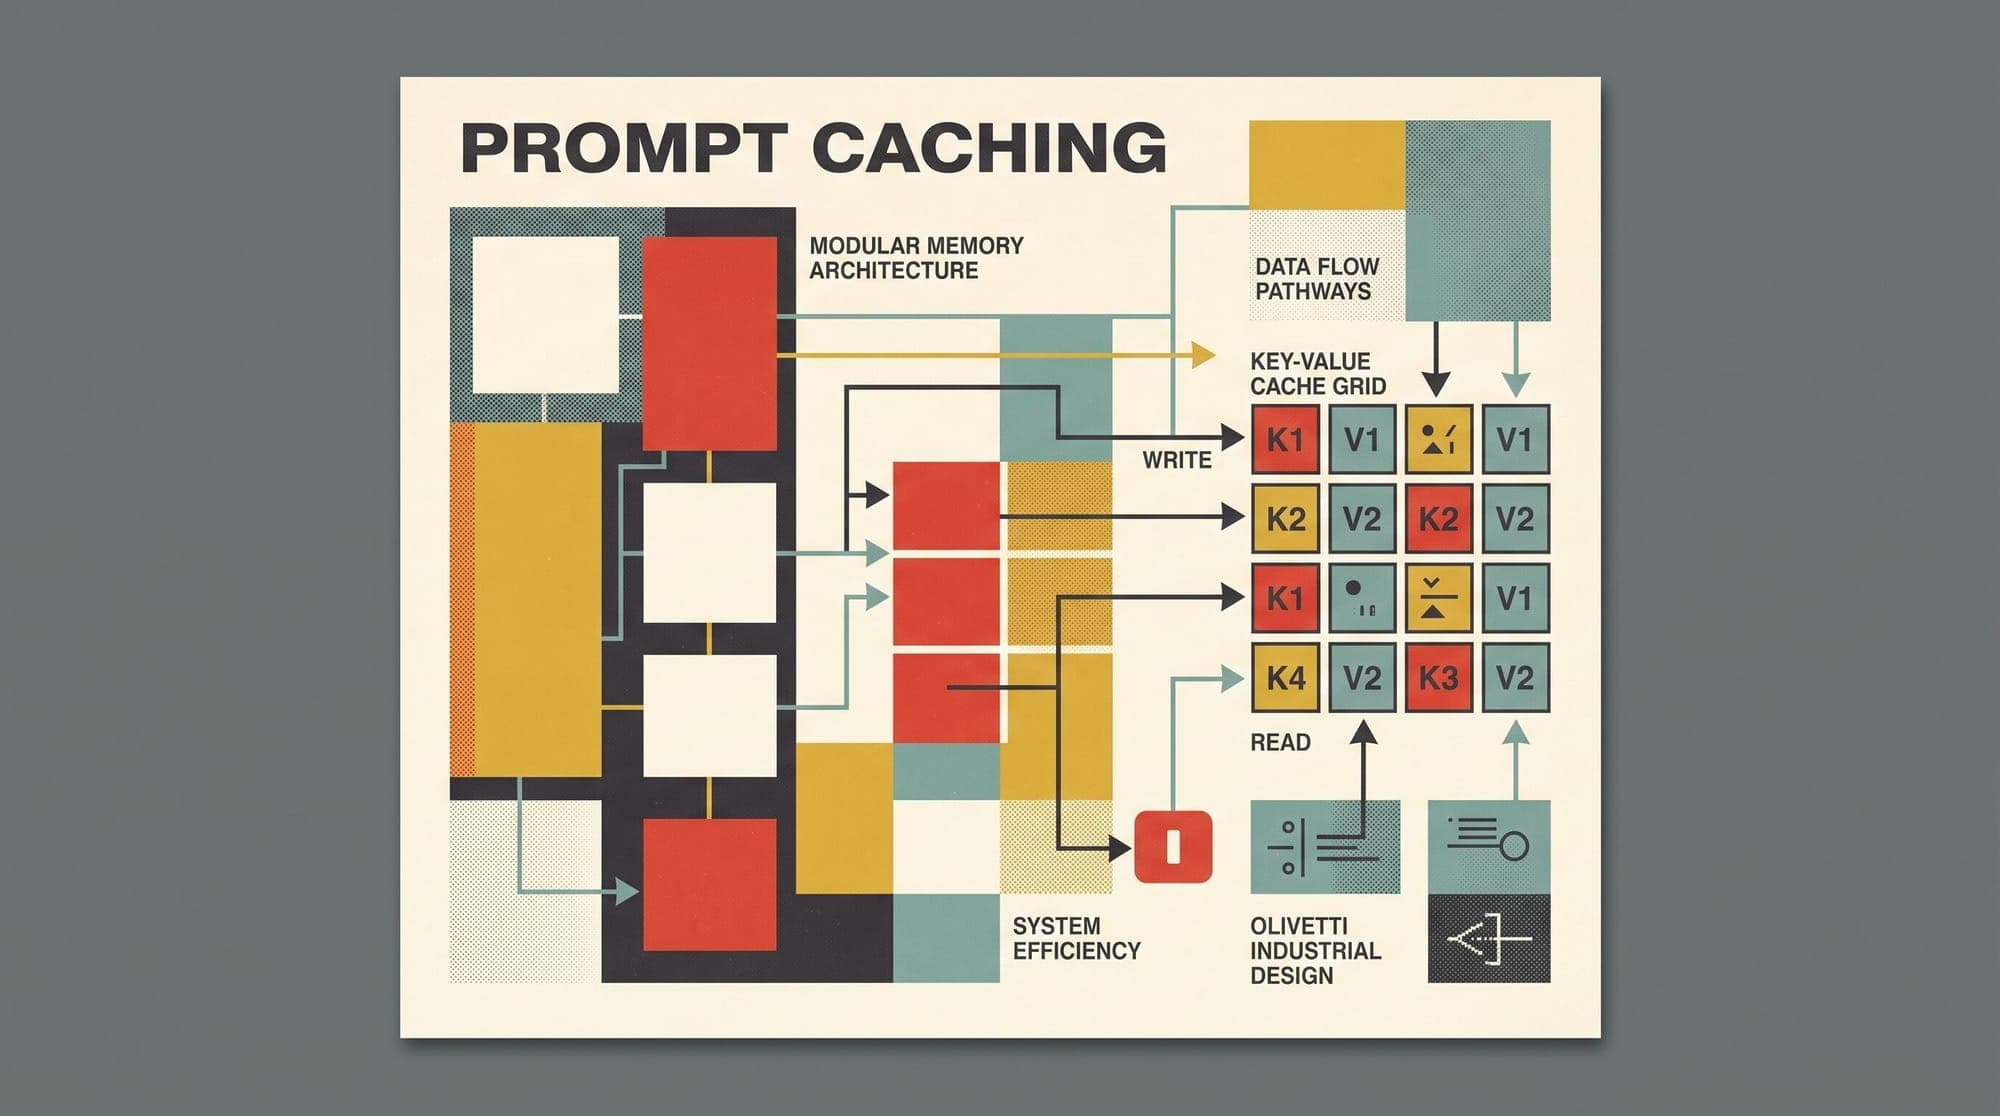
  9. Prompt Caching in Production: Architecture, Economics, and Invalidation Pitfalls

    As multi-turn AI agents, code generation assistants, and retrieval-augmented generation (RAG) pipelines expand in production, prompt sizes routinely exceed tens of thousands of tokens per request. In these architectures, the vast majority of tokens across consecutive API calls are static: system prompts, OpenAPI tool specifications, reference documents, and accumulated conversation history. Without optimization, inference engines must re-evaluate the full attention matrix for every token on eac

    AI
    5 min read
  10. French startup Kog says smarter software can pull 30x faster inference out of stock GPUs

    The race for faster AI inference has pushed labs toward custom silicon, but a French startup argues the cheapest speedup is already sitting in servers companies bought. Kog says it can reach roughly thirty times faster LLM inference on standard data-center GPUs using software alone. Kog demonstrated three thousand tokens per second per request on AMD MI300X and NVIDIA H200 GPUs in May, running a small two-billion-parameter model it has since open-sourced as Laneformer 2B. Chief executive Gael D

    AI
    2 min read