Reasoning Model Distillation in Production: Trajectory Curation, Thinking-Token Formatting, Over-Thinking Mitigation, and Student RL Alignment
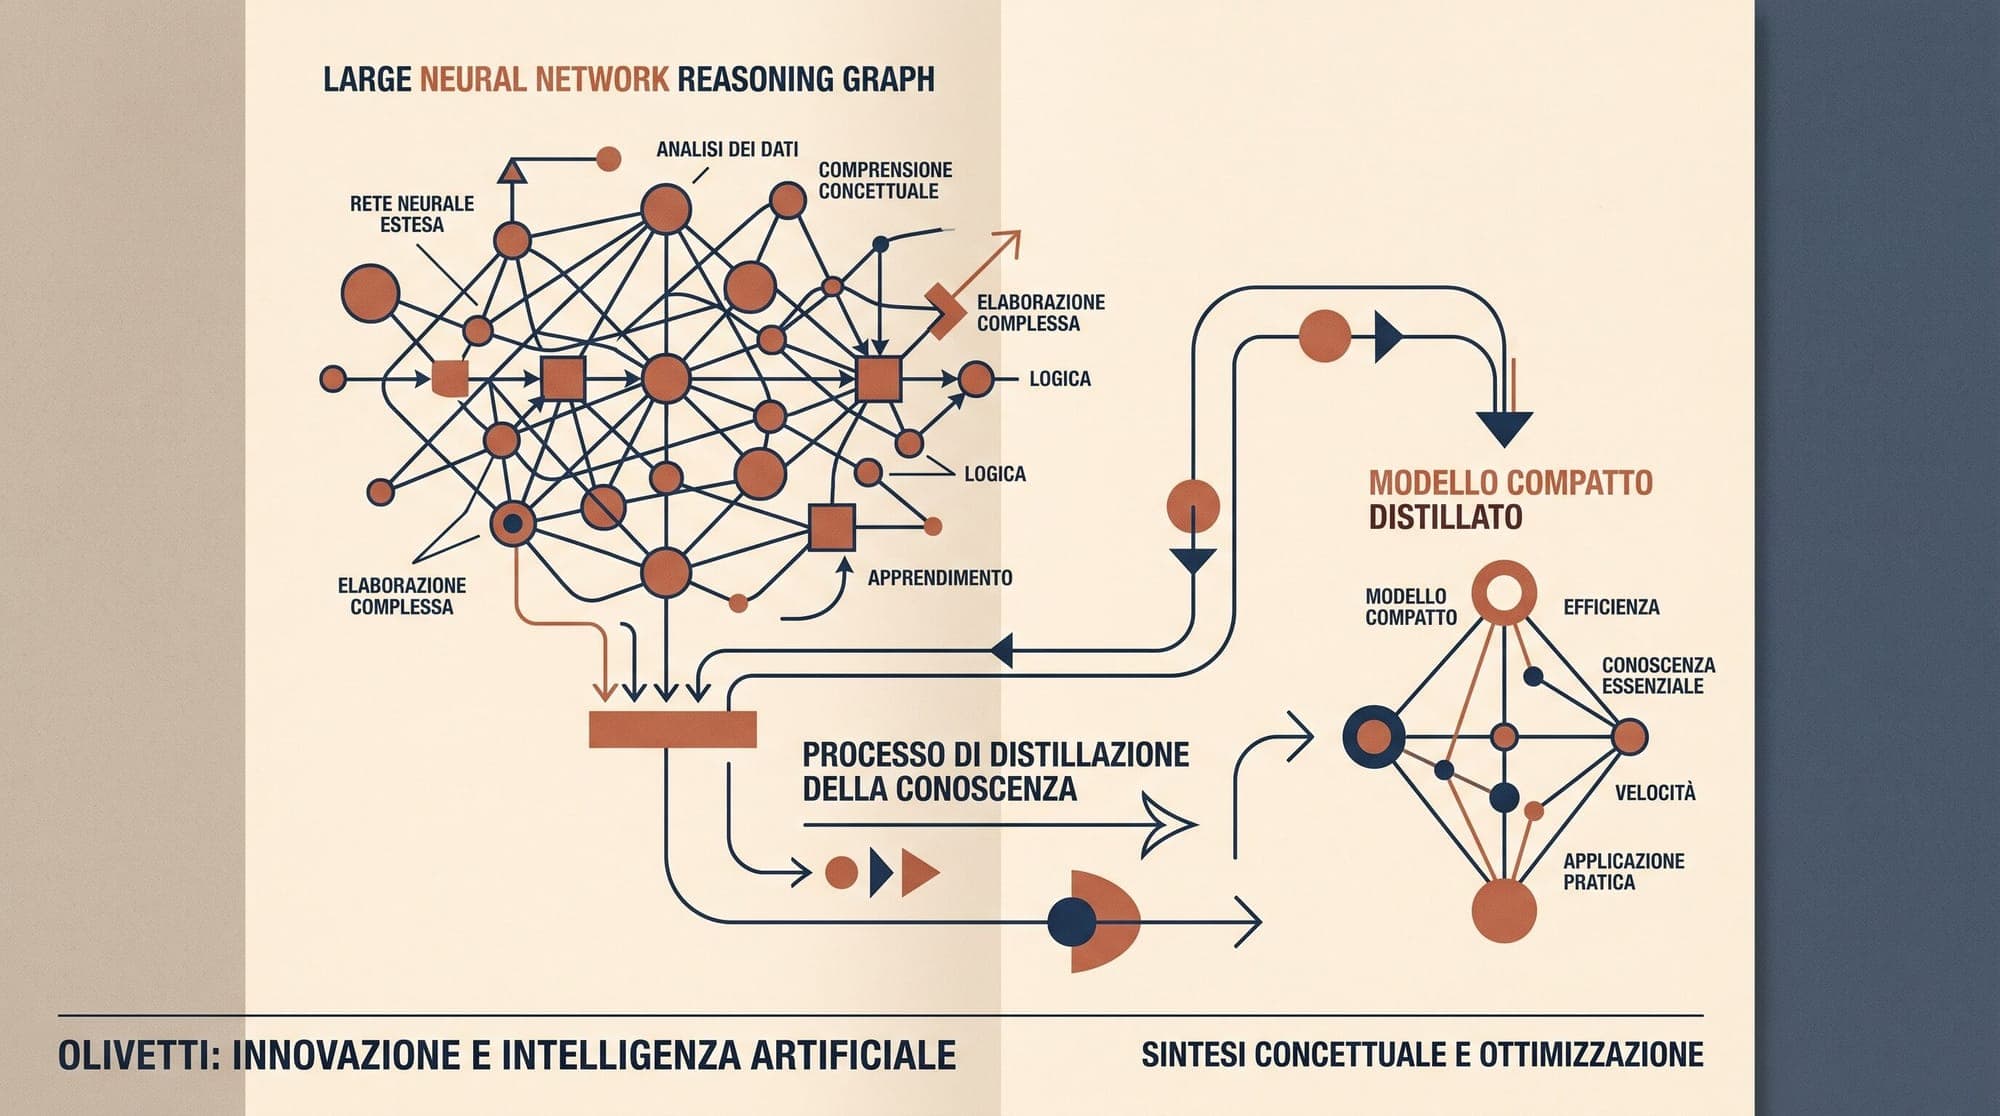
Reasoning Model Distillation in Production: Trajectory Curation, Thinking-Token Formatting, Over-Thinking Mitigation, and Student RL Alignment Distilling frontier reasoning models into compact language models has emerged as one of the most effective strategies for deploying low-latency, cost-efficient inference pipelines. Rather than training small models purely on input-output answer pairs, reasoning distillation transfers the intermediate exploration, backtracking, and verification trajectori
1 min