
Gradient clipping stabilizes Large Language Model (LLM) pretraining by capping the norm of the gradient vector when it exceeds a specific threshold, typically 1.0. This technique prevents exploding gradients caused by multiplying derivatives through long chains of layers, ensuring that large updates do not poison optimizer statistics or produce NaN values. It preserves the direction of the update while reducing its length, acting as a critical safety mechanism during optimization steps.
Every published recipe for pretraining a large language model contains the same quiet line: clip the gradient norm to 1.0. GPT-3 does it (Appendix B of the paper). So does DeepSpeed, where gradient_clipping: 1.0 is the factory default, and so do most recent training papers. One line of configuration, run on every optimizer step, on every parameter, for trillions of tokens. It is the cheapest stability device in deep learning, and almost nobody explains what it is protecting against. This post is that explanation.
The failure mode: one bad update
Gradient descent is a first-order method. At each step the model computes one vector, the gradient, and moves downhill along it. The scheme assumes the gradient is a reasonable local description of the loss surface. Sometimes it is not.
This was formalized in 1994, by Yoshua Bengio, Patrice Simard and Paolo Frasconi, in the paper that named the vanishing and exploding gradient problems. Training signal travels through a network the way an echo travels through a corridor: each layer it passes through multiplies it by that layer's local derivative. Stack enough layers or time steps and the multiplication compounds. If those factors average above one, the gradient grows exponentially and the update becomes enormous. If they average below one, the signal decays to nothing and early layers never learn. The paper's conclusion was blunt: with standard gradient descent, learning long-range structure is structurally hard, not merely badly tuned.
Vanishing gradients have architectural fixes: residual connections, gated units, careful initialization. Exploding gradients have no architectural cure, because a genuinely pathological batch can produce an enormous gradient in any network, at any depth. A single bad step can throw the loss upward, poison the optimizer's running statistics, and in the worst case produce NaNs that end the run. In a frontier-scale job, an uncontrolled spike is not a warning, it is days of wasted compute.
The rule, in one line
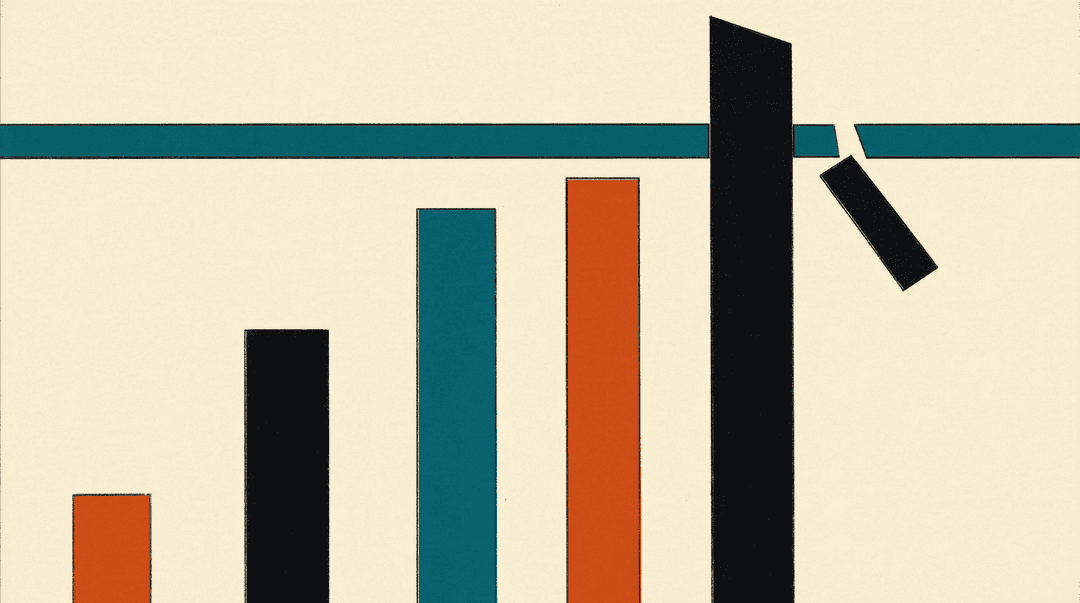
The standard remedy appeared in 2013, in On the difficulty of training Recurrent Neural Networks by Razvan Pascanu, Tomas Mikolov and Yoshua Bengio. The paper analyzed both gradient pathologies and proposed the rule that is now one line of Python:
if ||g|| > c:
    g = c * g / ||g||
Compute the norm of the gradient vector. If it exceeds a threshold c, scale the whole vector down so its norm equals c. If it does not, change nothing. The operation preserves the direction of the update exactly and caps only its length. A gradient of norm 4.2 against a threshold of 1.0 is multiplied by 1/4.2, roughly 0.24. Every component shrinks by the same factor, so the model still steps in the direction it believed in, it just takes a shorter step. Pascanu et al. described the effect as adapting the learning rate to the instantaneous gradient norm.
The idea was not invented from nothing. Mikolov had already been clipping recurrent gradients element-wise in his earlier language modeling work, capping each component at a fixed absolute value. The 2013 paper's contribution was the norm version, and the argument for it: element-wise clipping bends the gradient toward the coordinate axes and changes its direction, while norm clipping keeps the direction intact. The paper also noted two practical properties that still hold. Clipping adds exactly one hyperparameter, and training is not very sensitive to it, behaving well even at aggressive thresholds. A reasonable way to set it, the authors suggested, is to look at the typical gradient norm over many updates and clip above that.
What modern frameworks actually compute
In current practice the norm being clipped is usually the global norm across all parameters. PyTorch's clip_grad_norm_ treats the gradients of every parameter tensor "as if the norms of the individual gradients were concatenated into a single vector", computes one number, and rescales everything in place if that number exceeds the cap. The call sits between loss.backward() and optimizer.step().
That choice has a consequence worth understanding. Because the cap applies to the concatenated vector, one layer producing a runaway gradient drags the update of every other layer down with it. A spike in layer 40 shrinks the steps taken by layers 1 through 39, even though their gradients were fine. Alternatives exist, including per-layer and per-parameter clipping, and recent research proposals such as AdaGC, which sets per-layer thresholds adaptively, and GradientStabilizer, which fixes the norm of the update while leaving the gradient's shape alone. These papers benchmark against the standard global-norm baseline, value clipping and attention-entropy-derived schemes, and their consistent finding is that clipping variants help relative to no clipping while disagreeing about which variant wins. Global norm 1.0 remains the default not because it is optimal but because it is good enough, cheap, and battle-tested across hundreds of runs.
The number 1.0 itself is a convention rather than a law. Pascanu et al. used thresholds in single digits in their RNN experiments, with 6 for one task. GPT-3 chose 1.0 with Adam (beta1 0.9, beta2 0.95) and kept it at every optimizer update. By the time DeepSpeed and Megatron-style stacks standardized the recipe, 1.0 had become the setting nobody argued with. Note the scale mismatch this implies: a frontier model's gradient vector has hundreds of billions of components, so a global norm of 1.0 means the average component is minuscule. The threshold only bites when something is wrong, which is exactly when it should bite.
What clipping is not
Three confusions are worth defusing.
Clipping is not a fix for the cause of instability. The 2025 AdaGC paper surveyed loss-spike incidents in large runs and traced them to data quality (one poisoned batch, mitigated by resuming and skipping it), hardware faults, numerical precision edges, and optimizer hyperparameters. Clipping bounds the damage a spike can do to the weights. It does not tell you that your data loader handed you one poisoned batch, and teams fighting chronic instability treat frequent clipping events as a symptom to be diagnosed, not a feature to lean on.
Clipping gradients is not the same thing as PPO's clipping. In RLHF post-training, Proximal Policy Optimization clips the probability ratio between the new and old policy inside its objective, which constrains how far one update can move the model's outputs. The two mechanisms share a verb and guard different quantities. A PPO training loop can, and usually does, apply gradient clipping on top.
Finally, clipping is a training-time mechanism. It has no effect at inference: an LLM serving your prompt is running no backward pass and clipping no gradients. If a model ships with unusual numerical behavior, gradient clipping is not in the causal chain.
The takeaway
Gradient clipping is the seatbelt of LLM training: one comparison and, rarely, one division, executed every step for the entire run, invisible until the accident. It exists because of a 1994 observation that multiplying derivatives through long chains either amplifies noise exponentially or kills it, and because of a 2013 decision to stop asking which and just cap the product. The next time a training log shows the gradient norm jumping and the loss holding steady anyway, you will know what saved it.
Sources
- Bengio, Simard, Frasconi (1994). Learning long-term dependencies with gradient descent is difficult. IEEE Transactions on Neural Networks 5(2): https://ieeexplore.ieee.org/document/279181
- Pascanu, Mikolov, Bengio (2013). On the difficulty of training Recurrent Neural Networks: https://arxiv.org/abs/1211.5063
- Brown et al. (2020). Language Models are Few-Shot Learners (GPT-3), Appendix B: https://arxiv.org/abs/2005.14165
- PyTorch documentation, torch.nn.utils.clip_grad_norm_: https://pytorch.org/docs/stable/generated/torch.nn.utils.clip_grad_norm_.html
- DeepSpeed Configuration JSON, gradient_clipping: https://www.deepspeed.ai/docs/config-json/
- Xiao et al. (2025). AdaGC: Enhancing LLM Pretraining Stability via Adaptive Gradient Clipping: https://arxiv.org/abs/2502.11034
- GradientStabilizer: Fix the Norm, Not the Gradient (2025): https://arxiv.org/abs/2502.17055
- Schulman et al. (2017). Proximal Policy Optimization Algorithms: https://arxiv.org/abs/1707.06347
- Conda: Column-Normalized Adam for Training Large Language Models Faster (2025), standard 1.0 clipping recipe: https://arxiv.org/abs/2509.24218
Frequently asked questions
Why is a gradient norm of 1.0 used as the default threshold?
The threshold of 1.0 is a convention rather than a law, adopted by GPT-3, DeepSpeed, and most recent training papers because it is cheap, good enough, and battle-reviewed across hundreds of runs.
Does gradient clipping fix the root cause of instability?
No, gradient clipping bounds the damage an instability spike causes but does not address the underlying causes, which may include data quality issues, hardware faults, or numerical precision edges.
Is gradient clipping the same as PPO clipping?
No, they are different mechanisms; gradient clipping scales the gradient vector's norm during backpropagation, while PPO clipping constrains the probability ratio between new and old policies during reinforcement learning.
How does global norm clipping affect other layers during training?
Global norm clipping rescales all parameters if any single layer produces a runaway gradient, meaning a spike in one layer shrinks the update steps for all other layers even if their gradients were fine.
When was the concept of vanishing and exploding gradients formalized?
The failure mode of vanishing and exploding gradients was formally described in 1994 by Yoshua Bengio, Patrice Simard, and Paolo Frasconi in their paper on learning long-term dependencies.
