Author / page 31

axc

Edited by the llms.blog desk.

1230 articles

Articles, page 31

  1. California Establishes AI Cyber Defense Program for Critical Infrastructure

    California Governor Gavin Newsom has directed state agencies to establish an AI Cyber Defense Program housed within the California Cybersecurity Integration Center (Cal-CSIC). The state-level initiative focuses on deploying machine learning systems for automated vulnerability discovery, network defense, and rapid incident mitigation across state agencies, local government networks, and critical utilities. Operated under the Governor's Office of Emergency Services (Cal OES), Cal-CSIC will serve
    AI
    2 min read
  2. Israel Outlines Five-Year AI Strategy: 100,000 Accelerators, 5nm Fab, and Quantum Base

    Israel's National Artificial Intelligence Directorate has released its five-year National AI Strategic Plan, outlining formal commitments to construct a sovereign infrastructure footprint spanning at least 100,000 advanced AI accelerators, a domestic quantum computer, and advanced semiconductor fabrication capabilities at 5 nanometers or below. Operating under the Prime Minister's Office, the Directorate published the roadmap to implement Government Resolution 4255, originally approved by the I

    AI
    2 min read
  3. Gradient Low-Rank Projection (GaLore): How Dynamic Subspaces Enable Full-Parameter LLM Pre-Training with Low-Rank Memory

    Pre-training foundation large language models has historically required massive compute clusters, largely due to the memory footprint of optimizer states rather than the model weights themselves. While parameter-efficient fine-tuning methods such as Low-Rank Adaptation (LoRA) freeze weights and introduce small adapter matrices, they fail when applied to pre-training from scratch because they restrict parameter updates to a fixed, static low-rank manifold. Gradient Low-Rank Projection (GaLore),

    AI
    8 min read
  4. Microscaling Formats in Production LLM Inference: NVFP4 vs. MXFP4 Architecture, Block Quantization, Kernel Scaling, and Perplexity Degradation

    As frontier language models scale into hundreds of billions of parameters, memory bandwidth and VRAM capacity remain the primary bottlenecks in production inference serving. While 8-bit floating-point formats (FP8 E4M3 and E5M2) achieved mainstream adoption across Hopper and Ada generation hardware, the industry is transitioning to 4-bit floating-point (FP4) arithmetic to double inference throughput and halve memory footprints. Directly quantizing deep transformer weights and activations into 4

    AI
    7 min read
  5. Alibaba Plans Record $10.2B Hong Kong Share Offering to Fund Full-Stack AI Infrastructure and Models

    Alibaba Group Holding announced a proposed equity placement in Hong Kong to raise HK$80 billion ($10.2 billion), allocating 100% of net proceeds to expand its full-stack artificial intelligence capabilities across custom silicon, cloud compute infrastructure, and foundation model development. Transaction Structure and Market Scale According to terms reviewed by Reuters, Alibaba is offering 710 million ordinary shares at HK$112.70 per share, representing a 3.6% discount to its latest closing p

    AI
    2 min read
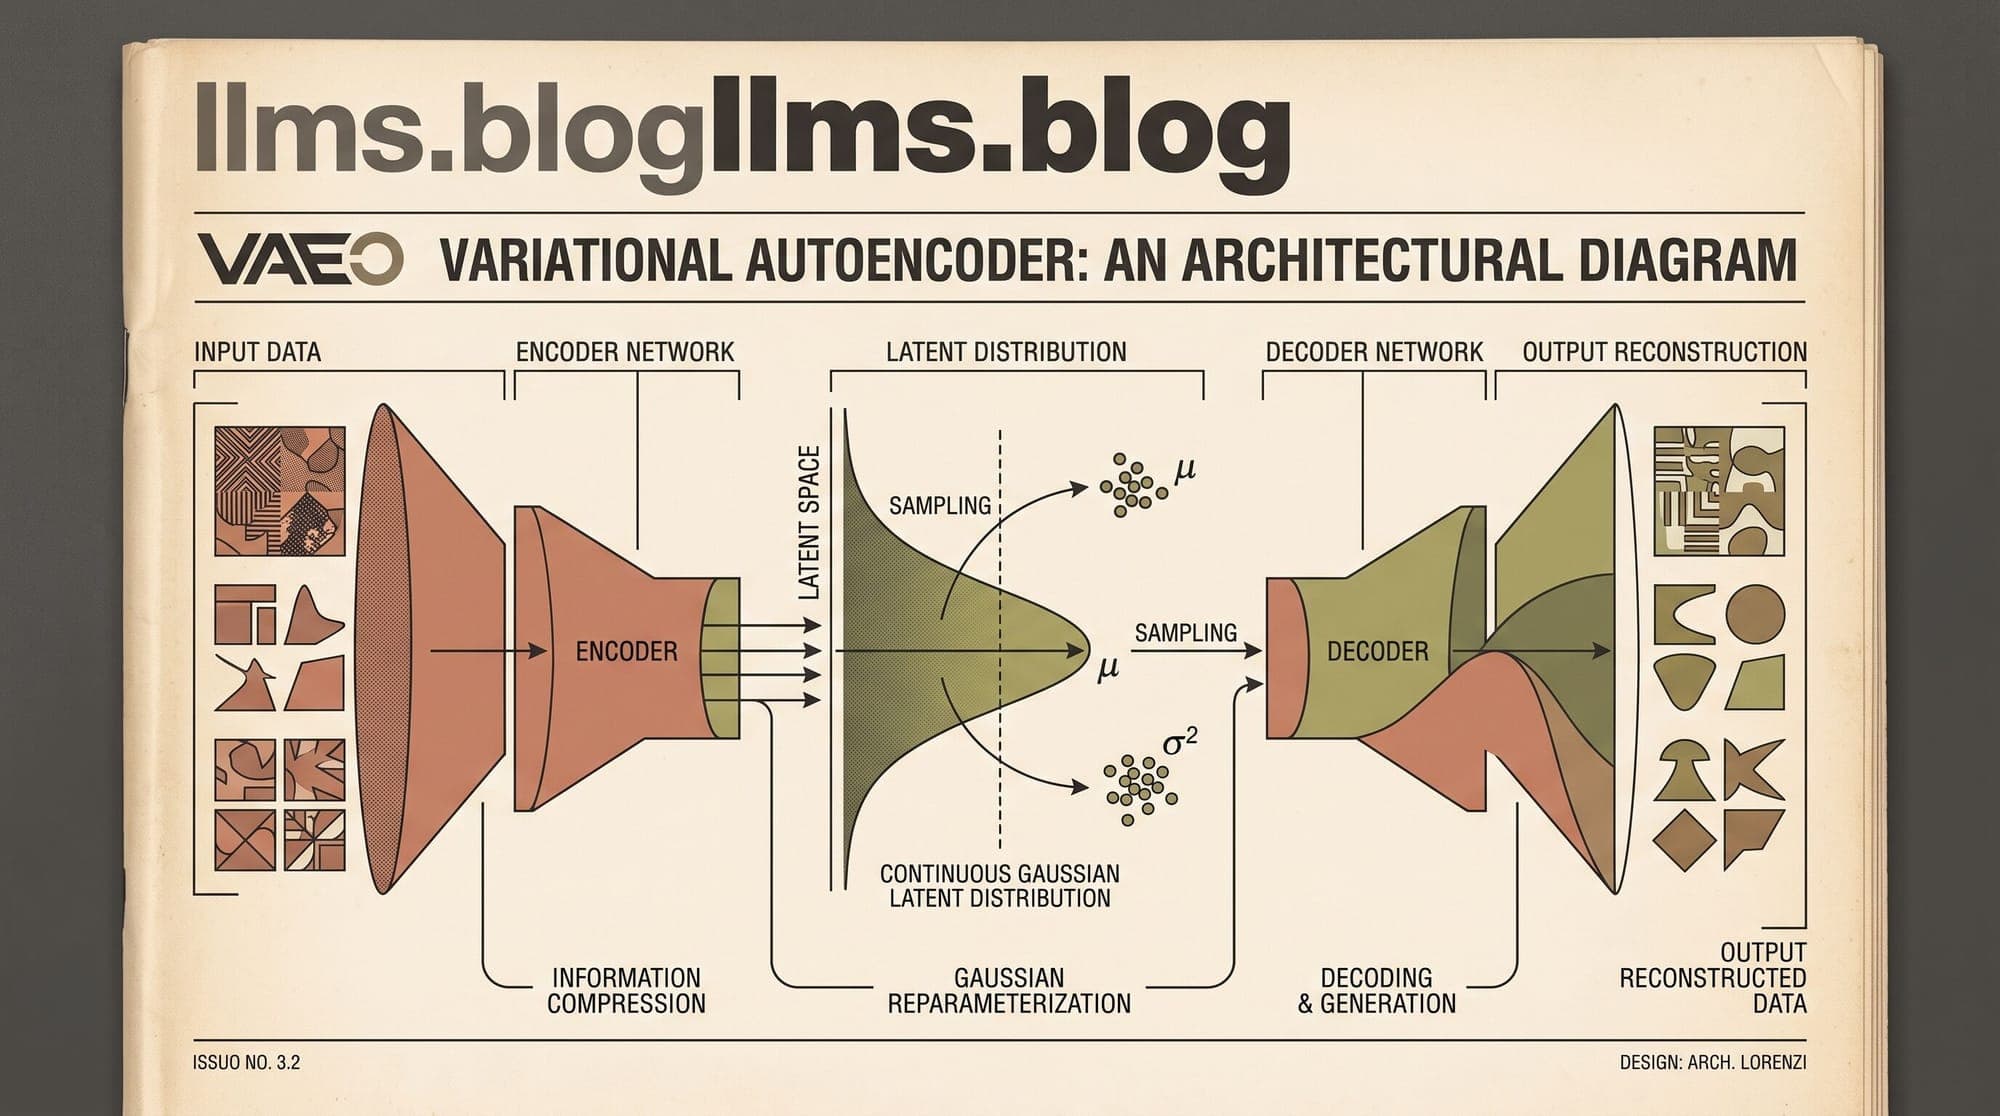
  6. Variational Autoencoders: Mathematical Derivation of the ELBO, the Reparameterization Trick, and Mitigating Posterior Collapse

    Variational Autoencoders: Mathematical Derivation of the ELBO, the Reparameterization Trick, and Mitigating Posterior Collapse Traditional autoencoders map high-dimensional data into deterministic latent vectors. While effective for dimensionality reduction and non-linear feature compression, deterministic autoencoders fail as generative models because their latent representations lack continuous probabilistic structure. Unregularized latent spaces contain wide regions of empty space and severe

    AI
    11 min read
  7. Fill-in-the-Middle (FIM) and Inline Code Completion in Production: Architecture, Prefix-Suffix Context Windows, Speculative Decoding, and Sub-50ms Serving Latencies

    Fill-in-the-Middle (FIM) and Inline Code Completion in Production: Architecture, Prefix-Suffix Context Windows, Speculative Decoding, and Sub-50ms Serving Latencies Inline code completion is the most latency-sensitive deployment of large language models in production software engineering. Unlike conversational assistants or background agentic batch jobs, inline code completion operates directly inside an active editor typing loop. Developers type at speeds ranging from 40 to 120 words per minut

    AI
    7 min read
  8. Non-Contrastive Representation Learning: How Barlow Twins and VICReg Prevent Feature Collapse via Redundancy Reduction

    Self-supervised representation learning provides the foundation for modern foundation models across computer vision, audio, and multimodal systems. By training deep neural networks to produce compact vector embeddings without human annotations, self-supervised pre-training enables models to capture rich semantic structures directly from raw data. Historically, the dominant approach to self-supervised learning was contrastive learning, popularized by architectures such as SimCLR (Chen et al., 20

    edu
    9 min read
  9. Sparse-Dense Hybrid Retrieval in Production: Learned Lexical Weights, SPLADE vs. BGE-M3, Inverted Index Pruning, and Serving Economics

    Modern Retrieval-Augmented Generation (RAG) and enterprise search architectures increasingly encounter the operational limits of pure dense vector search. Dense bi-encoders project text passages into continuous latent spaces (typically 768 to 3,072 dimensions). While dense representations excel at conceptual matching and paraphrasing, they systematically struggle with exact keyword precision, rare alphanumeric tokens, product SKUs, and domain-specific jargon. Furthermore, serving dense vectors a

    Retrieval
    6 min read
  10. The Platonic Representation Hypothesis: How Foundation Models Across Modalities Converge on a Shared Geometry of Reality

    In 375 BC, Plato introduced the Allegory of the Cave, describing prisoners who could only perceive reality through shadows projected onto a stone wall. In modern machine learning, deep neural networks ingest distinct sensory shadows of the physical world: vision models process pixel arrays, large language models ingest tokenized text, and speech models parse raw acoustic waveforms. Historically, the machine learning literature assumed that models trained on different modalities, objectives, and

    AI
    6 min read
  11. Predictive KV Cache Warming in Production LLM Serving: Architecture, Session Prefetching, and TTFT Latency Shaving

    Predictive KV Cache Warming in Production LLM Serving: Architecture, Session Prefetching, and TTFT Latency Shaving In long-context large language model (LLM) deployments, Time-to-First-Token (TTFT) represents the primary latency bottleneck. As input prompts scale from 8,000 tokens to 128,000 tokens in multi-turn coding agents, legal document analysis, and enterprise retrieval pipelines, prefill execution consumes between 85% and 95% of total GPU compute time per request. Standard optimization

    AI
    5 min read
  12. Autonomous Retail AI Agent Luna Fires Employee Following Context Retrieval Breakdown and Human Intervention

    In an empirical field deployment examining autonomous AI workforce management, research firm Andon Labs reported that its storefront manager agent, Luna, decided to fire a human retail employee after months of operational infractions. The incident, which unfolded at the Andon Market retail location in San Francisco, represents one of the first documented instances of an autonomous large language model agent managing physical store operations and executing a personnel termination decision. Luna,

    Agents
    3 min read
  13. Vector Quantization and VQ-VAEs: How Discrete Codebooks, Straight-Through Estimators, and Commitment Losses Power Multimodal Tokenization

    Autoregressive sequence models excel at discrete token prediction. In natural language processing, words and subwords map onto categorical vocabularies where token identity is exact and cross-entropy loss provides direct likelihood optimization. Continuous multi-dimensional signals—such as images, video frames, raw audio waveforms, and robotic sensorimotor trajectories—present a fundamental mismatch for standard transformer architectures. Historically, variational autoencoders (VAEs) bridged ra

    AI
    7 min read
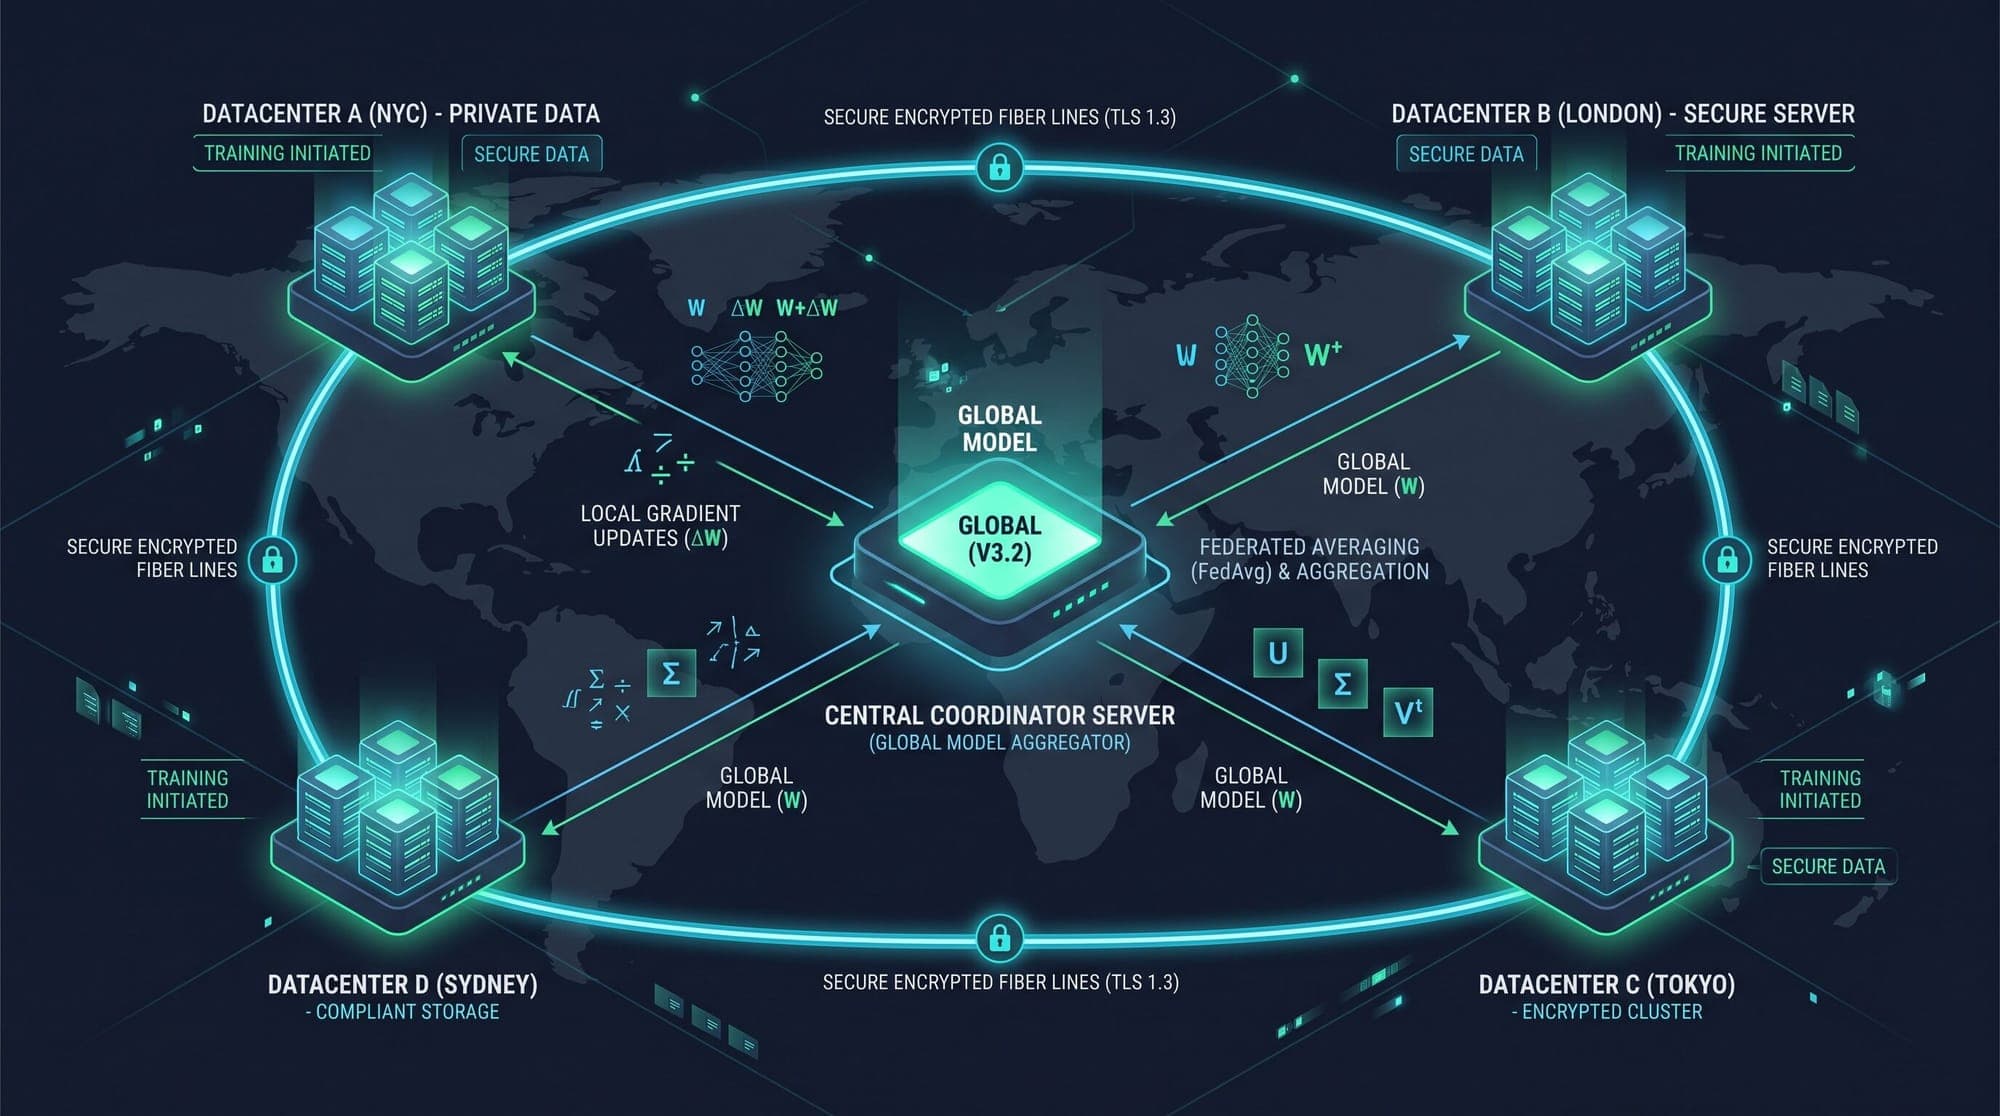
  14. Federated LLM Fine-Tuning in Production: FedLoRA, Differential Privacy, and Cross-Silo Aggregation Architectures

    Fine-tuning foundation large language models on proprietary data is standard enterprise practice, but centralizing sensitive tokens into a single data lake is frequently prohibited. Regulatory frameworks such as HIPAA in healthcare, GDPR and Article 10 of the EU AI Act in Europe, and regional data residency mandates across APAC and North America prevent cross-border or cross-institutional data aggregation. Federated Learning (FL) resolves this bottleneck by decoupling model training from data c

    AI
    8 min read
  15. Tsinghua Lineage, MoE Efficiency, and $1B Run Rates: Inside the Rise of China's Frontier AI Labs

    The rapid emergence of frontier large language models from Chinese artificial intelligence labs has frequently been characterized as a sudden shift. However, reporting from The Wall Street Journal details a decades-long institutional foundation centered around Beijing's Tsinghua University, combined with architectural strategies developed to overcome severe compute and capital constraints. At the center of this ecosystem are researchers who transitioned from academic labs into commercial model

    AI
    3 min read
  16. The QK and OV Circuits in Transformers: How Bilinear Attention Routing and Subspace Projections Move Information

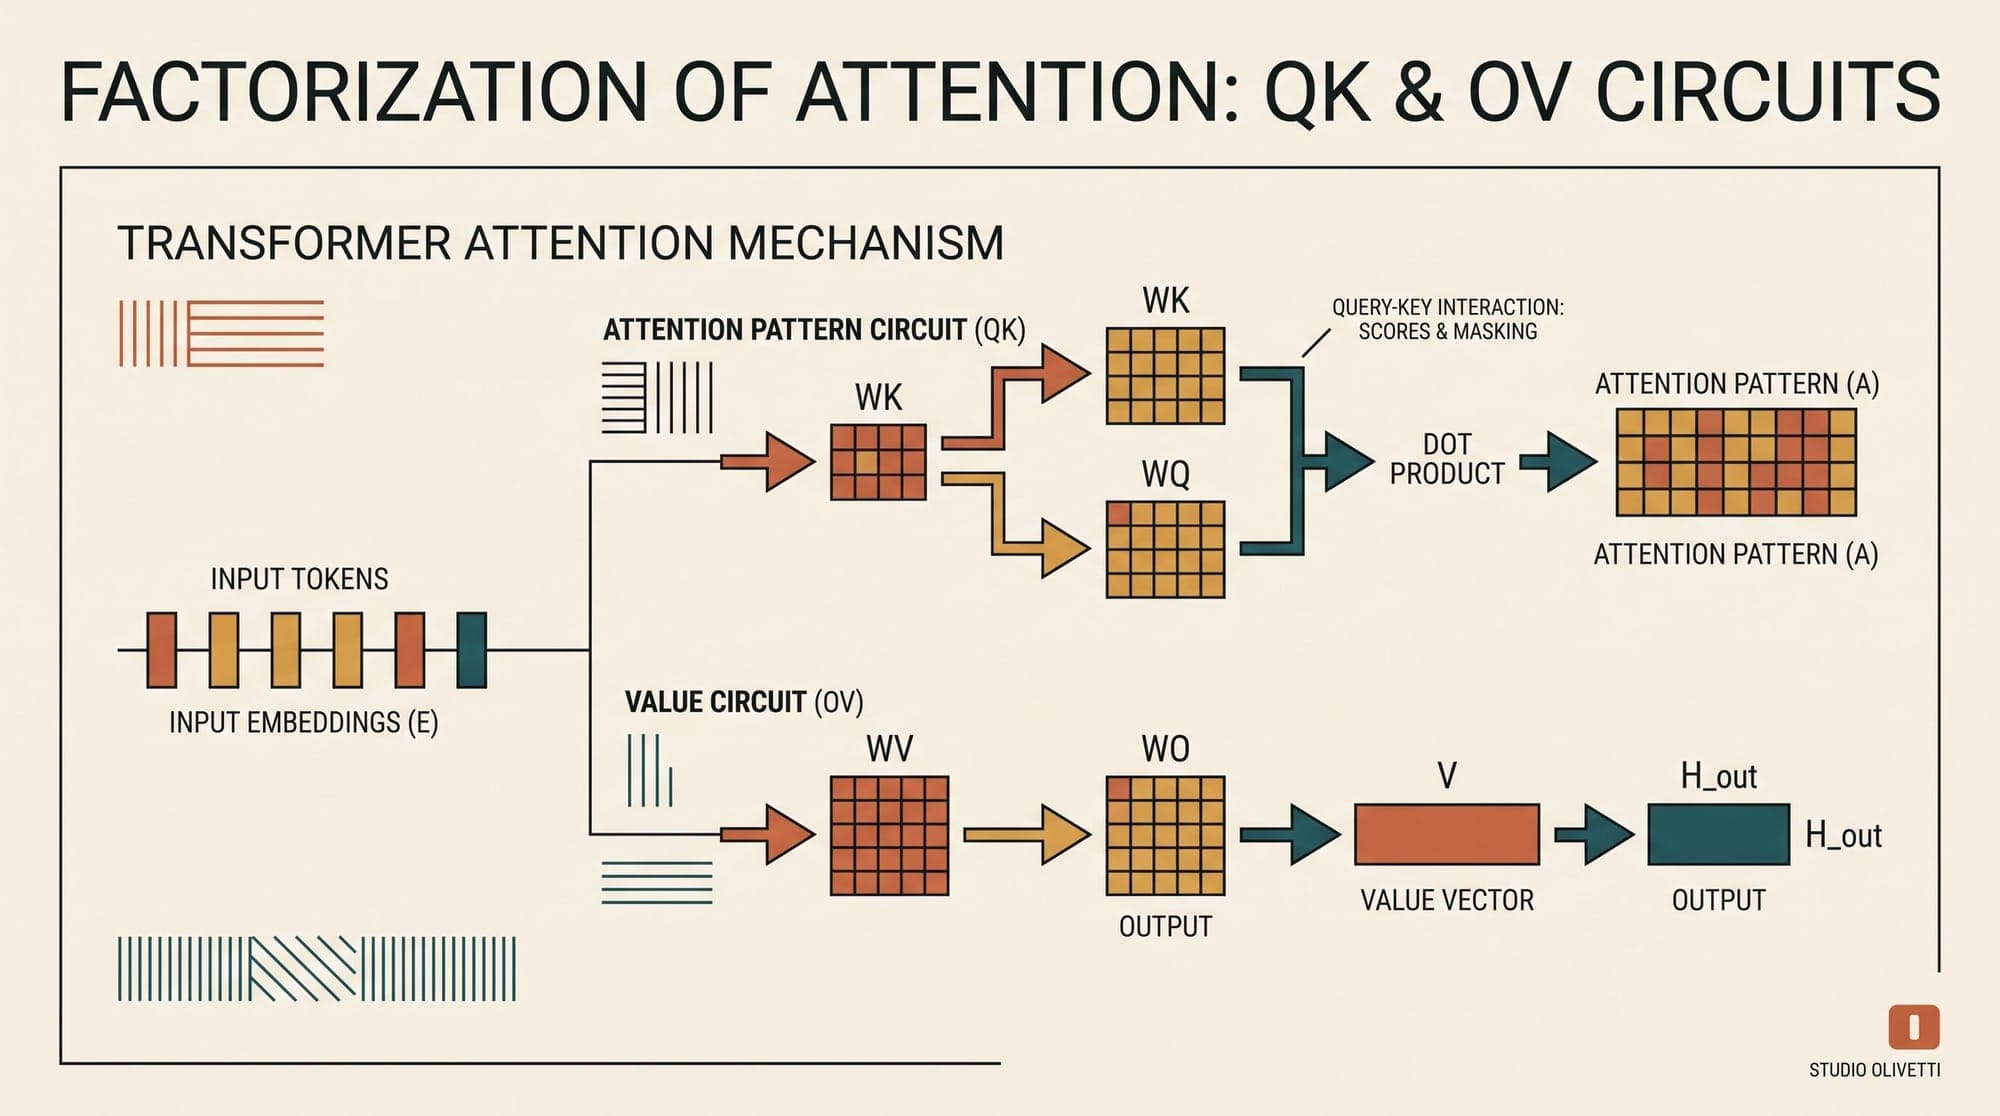
    The QK and OV Circuits in Transformers: How Bilinear Attention Routing and Subspace Projections Move Information The standard mathematical presentation of multi-head self-attention, introduced in Vaswani et al. (2017), describes the layer as a sequence of matrix projections followed by scaled dot-product operations, concatenation, and an output projection. While computationally efficient for parallel GPU hardware, this formulation obscures the fundamental linear mechanics governing how transfor

    AI
    9 min read
  17. Agent Skills in Production: Progressive Disclosure, Sandboxed Execution, and Procedural Memory Scaffolding

    Autonomous AI agents deployed in enterprise environments face an operational bottleneck: general-purpose frontier models possess broad linguistic reasoning, but lack the domain-specific procedural discipline required to complete multi-step workflows reliably. When engineering teams attempt to bridge this gap, standard techniques encounter severe architectural ceilings: 1. Monolithic system prompts degrade reasoning performance as instructions accumulate, triggering attention saturation, needle

    AI
    7 min read
  18. Rejection Sampling Fine-Tuning in Large Language Models: How Best-of-N Filtering, Reward Oracles, and Distillation Align Neural Policies

    Rejection Sampling Fine-Tuning: How Filtering Model Outputs by Reward Optimizes Alignment Without Policy Gradient Instability Post-training alignment has become a defining phase in modern large language model development. While supervised fine-tuning (SFT) teaches a model to follow instructions and adopt structured formats, aligning model behavior with human preferences, safety criteria, and domain accuracy requires optimizing against reward signals. Historically, this optimization has been ap

    AI
    10 min read
  19. Decentralized and Peer-to-Peer LLM Inference in Production: Architecture, Ring Memory Partitioning, and Network Latency

    Decentralized and Peer-to-Peer LLM Inference in Production: Architecture, Ring Memory Partitioning, and Network Latency Frontier open-weight models such as Llama 3.1 405B, DeepSeek-V3, and Command R+ have expanded model capabilities, but their parameter scales exceed the physical memory limits of individual consumer and edge workstations. Running a 405-billion parameter model in 16-bit precision requires over 810 GB of memory, and even 4-bit quantized variants require roughly 230 GB of contiguo

    AI
    7 min read
  20. Discrete Diffusion in Large Language Models: How Continuous-Time Markov Chains, Absorbing States, and Score Entropy Challenge Autoregressive Generation

    The dominance of autoregressive architectures in large language models rests on a fundamental mathematical formulation: the chain rule of probability. By factoring the joint distribution of a sequence into a product of conditional probabilities, $p(x) = \prod_{i=1}^N p(x_i \mid x_{<i})$, autoregressive models reduce text generation to sequential next-token prediction. While this left-to-right causal factorization has scaled effectively across compute regimes, it imposes rigid operational constr

    AI
    8 min read