Proximal Policy Optimization: Mathematical Foundations, Clipped Surrogate Objectives, and Policy Drift Control in RLHF
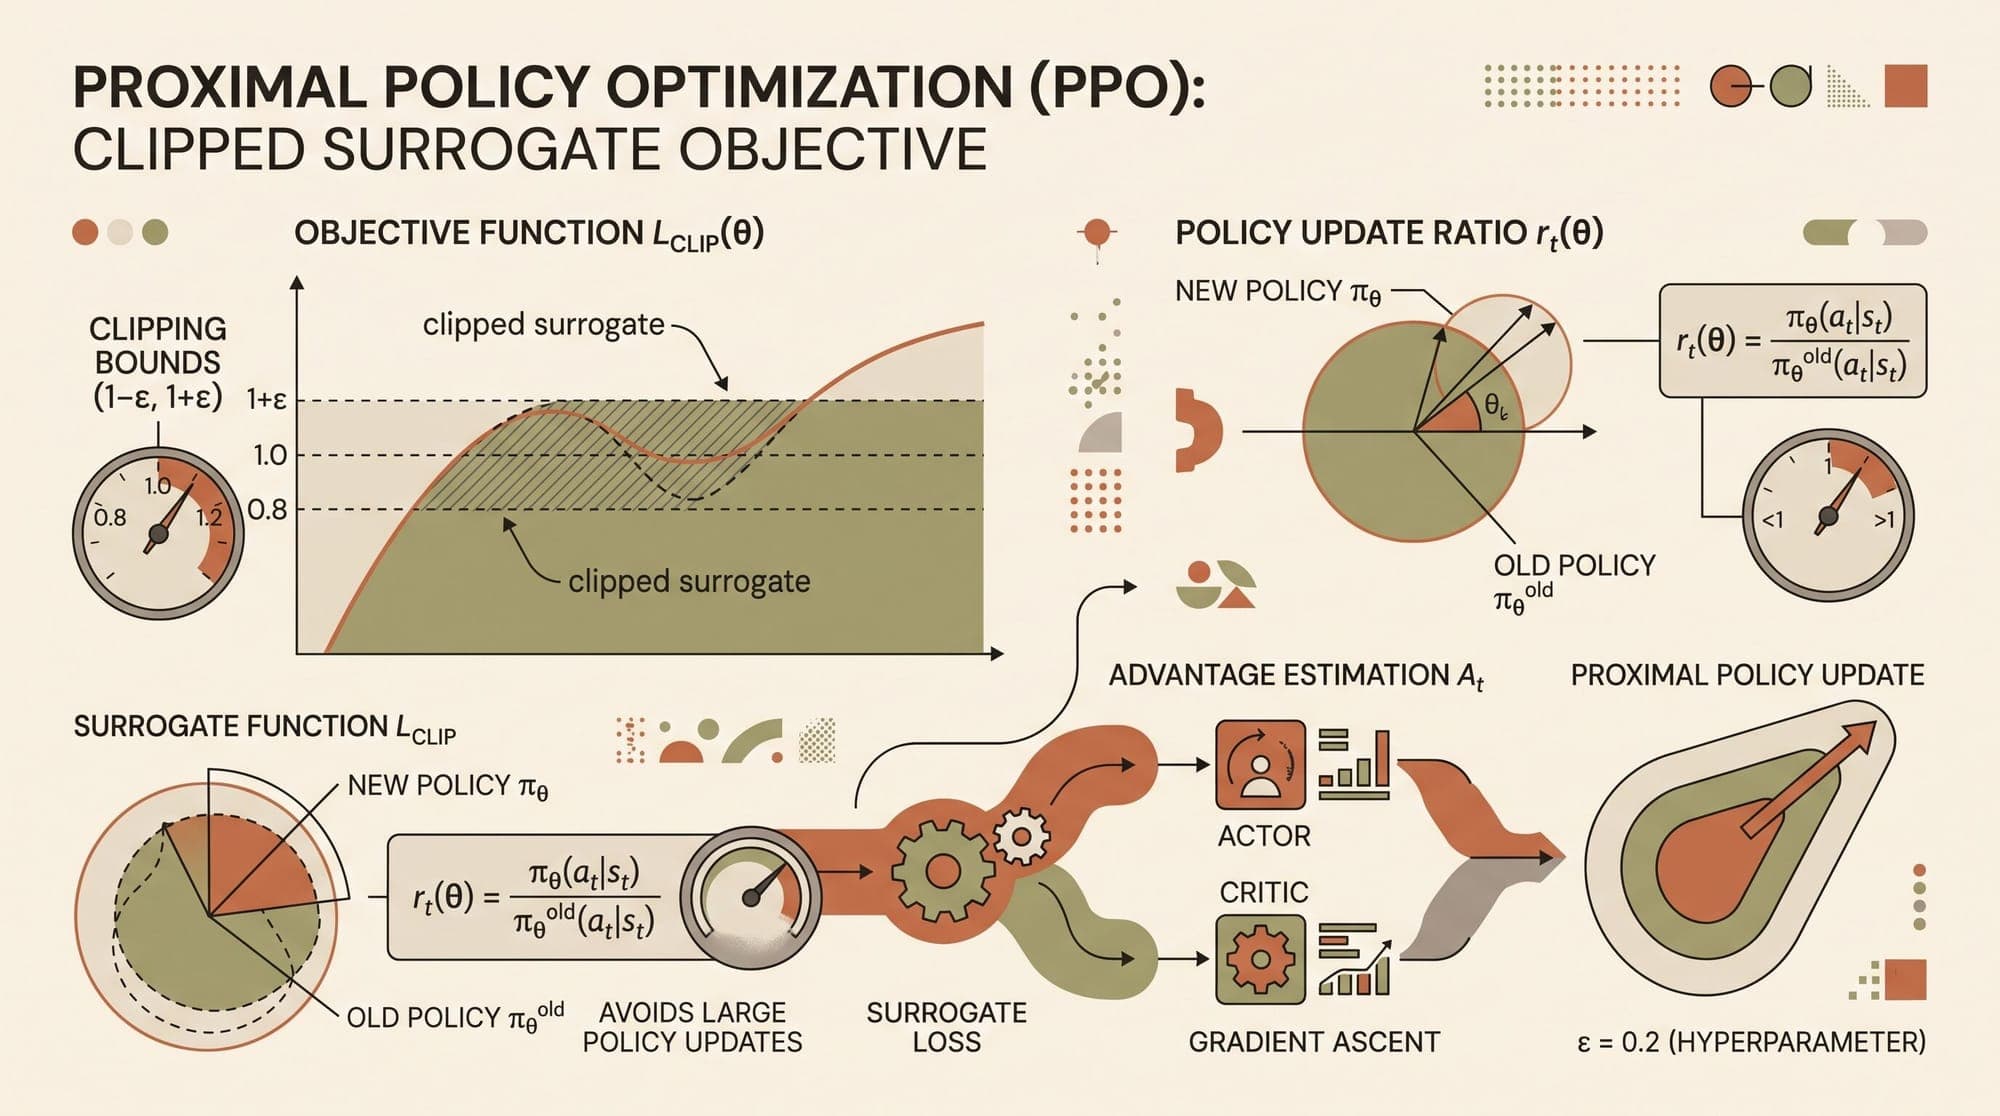
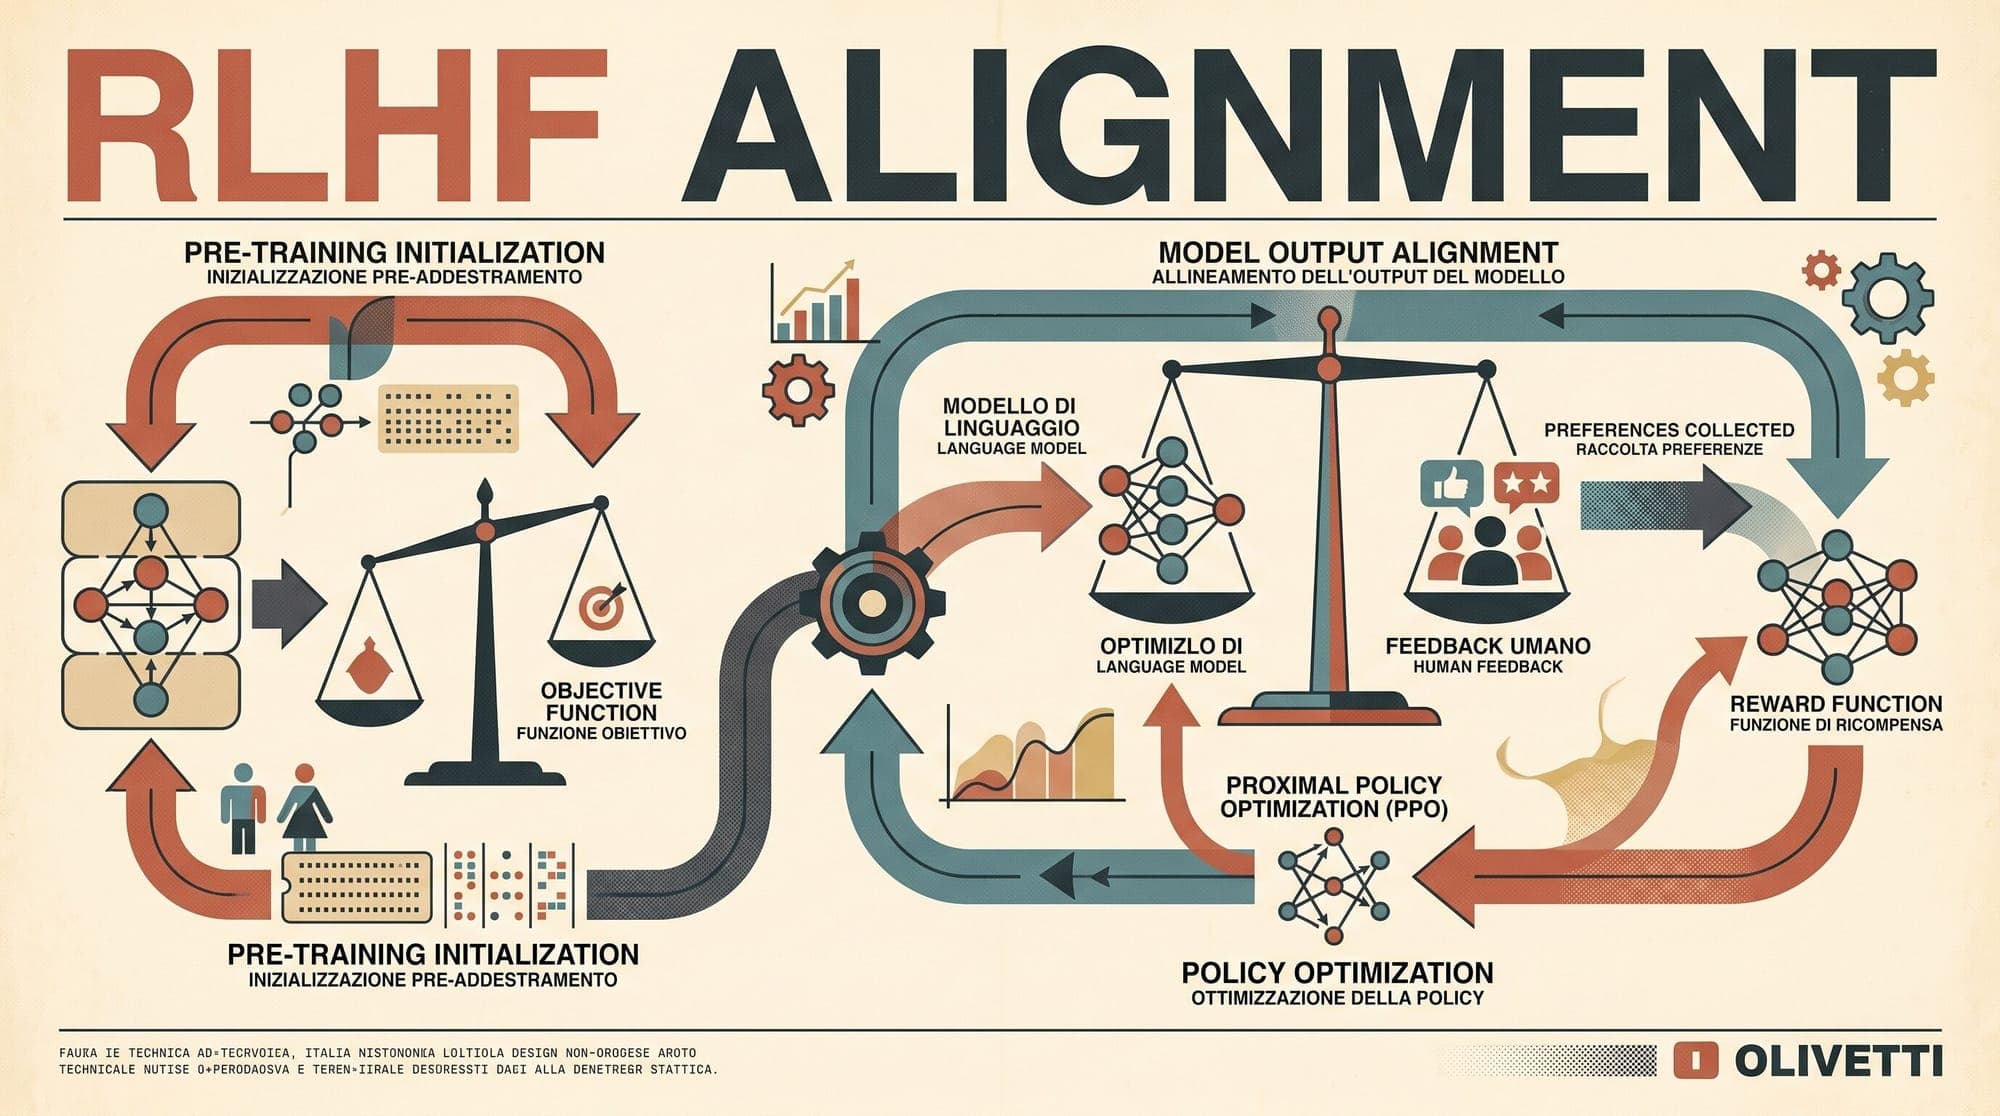
Proximal Policy Optimization (PPO) for language models, step by step: the clipped surrogate objective, generalized advantage estimation, value function clipping, the four models a PPO run uses, and how PPO compares with TRPO, DPO and GRPO.