Subscribe
Topic / page 13

Explainers

Articles, page 13

241-250
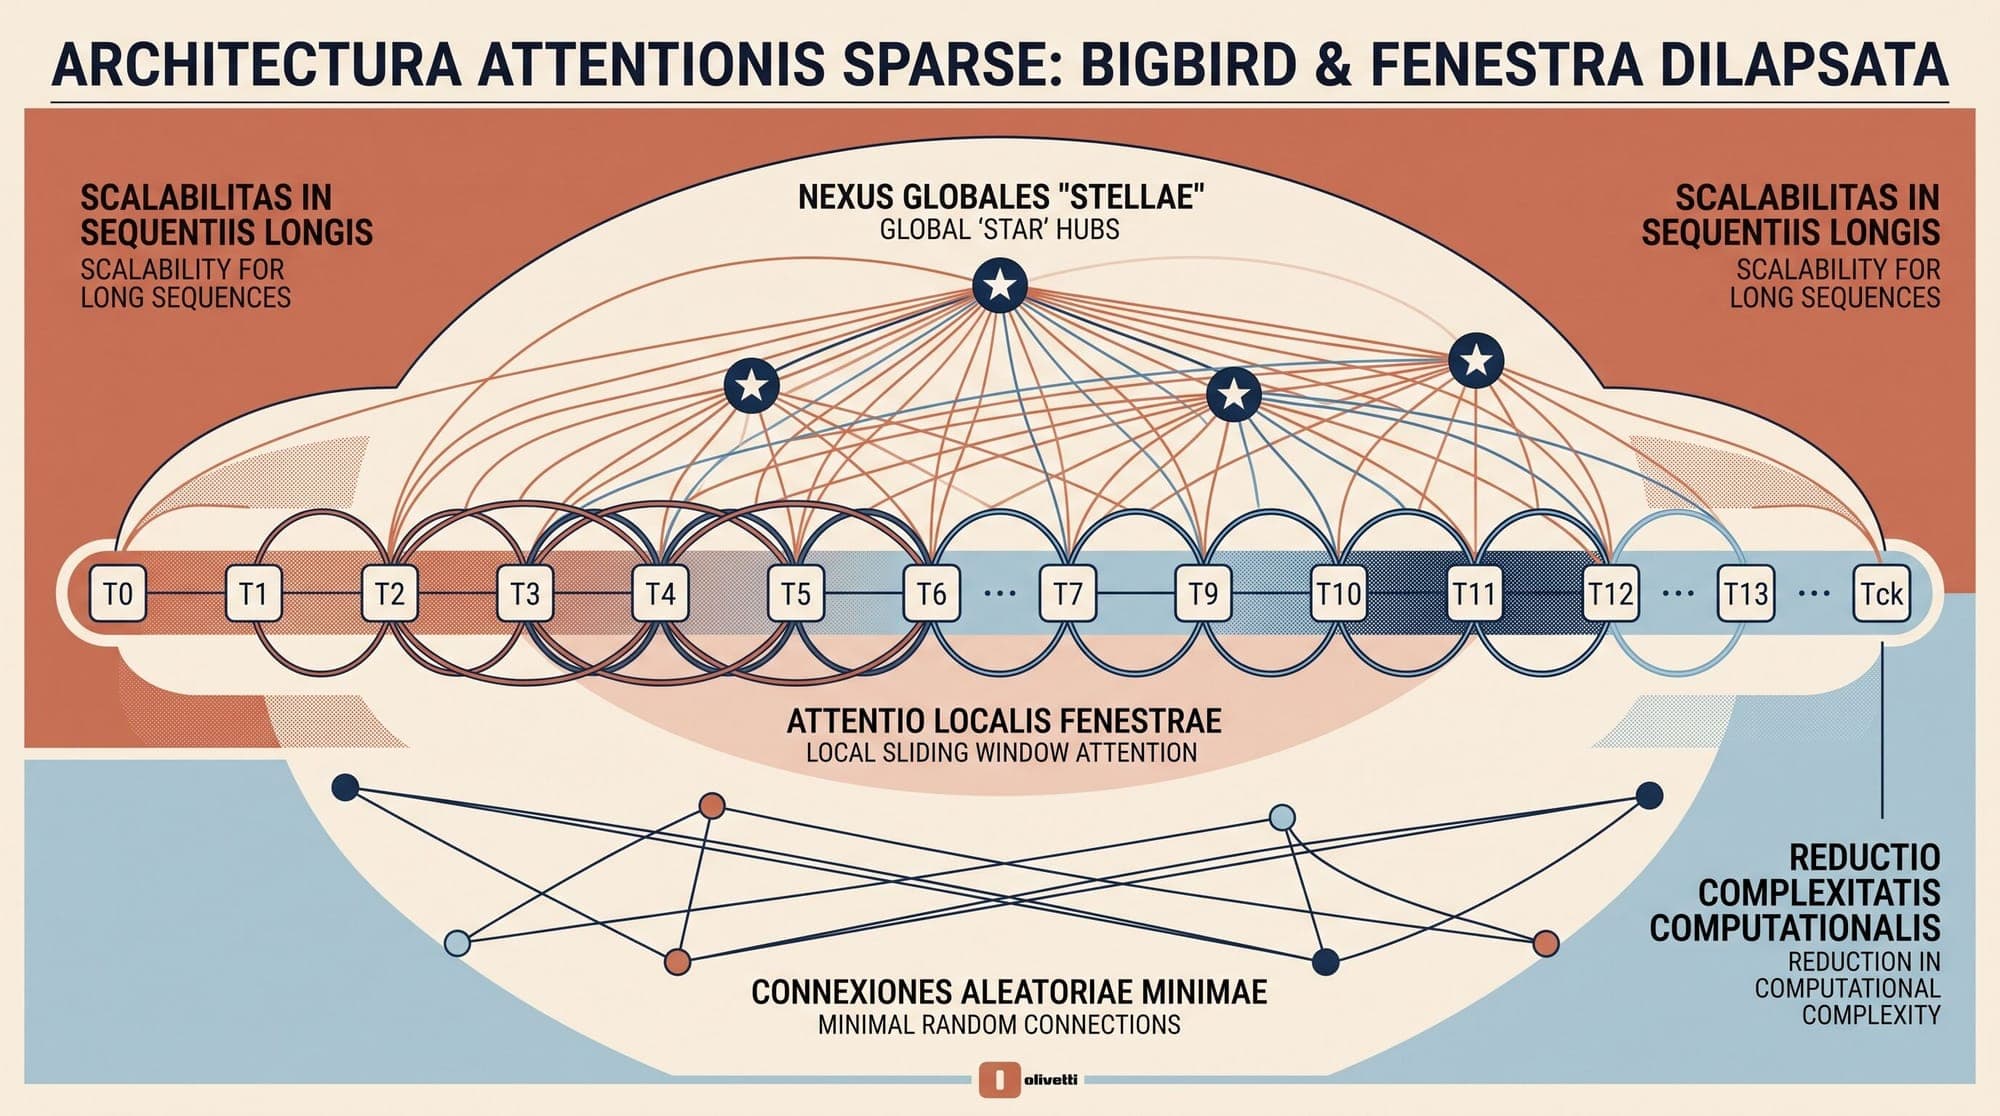
  1. Sparse Attention and BigBird: How Window, Global, and Random Graphs Preserve Turing Completeness in Linear Time

    Standard self-attention in transformer architectures scales quadratically with sequence length. Computing full pairwise interactions between n tokens requires evaluating an n x n attention matrix, yielding O(n^2) computational complexity and memory consumption. While hardware accelerators and IO-aware tiling algorithms like FlashAttention optimize memory traffic, the quadratic compute and KV footprint remains a barrier for processing long contexts, document-level summarization, and genomic seque
    AI
    7 min read
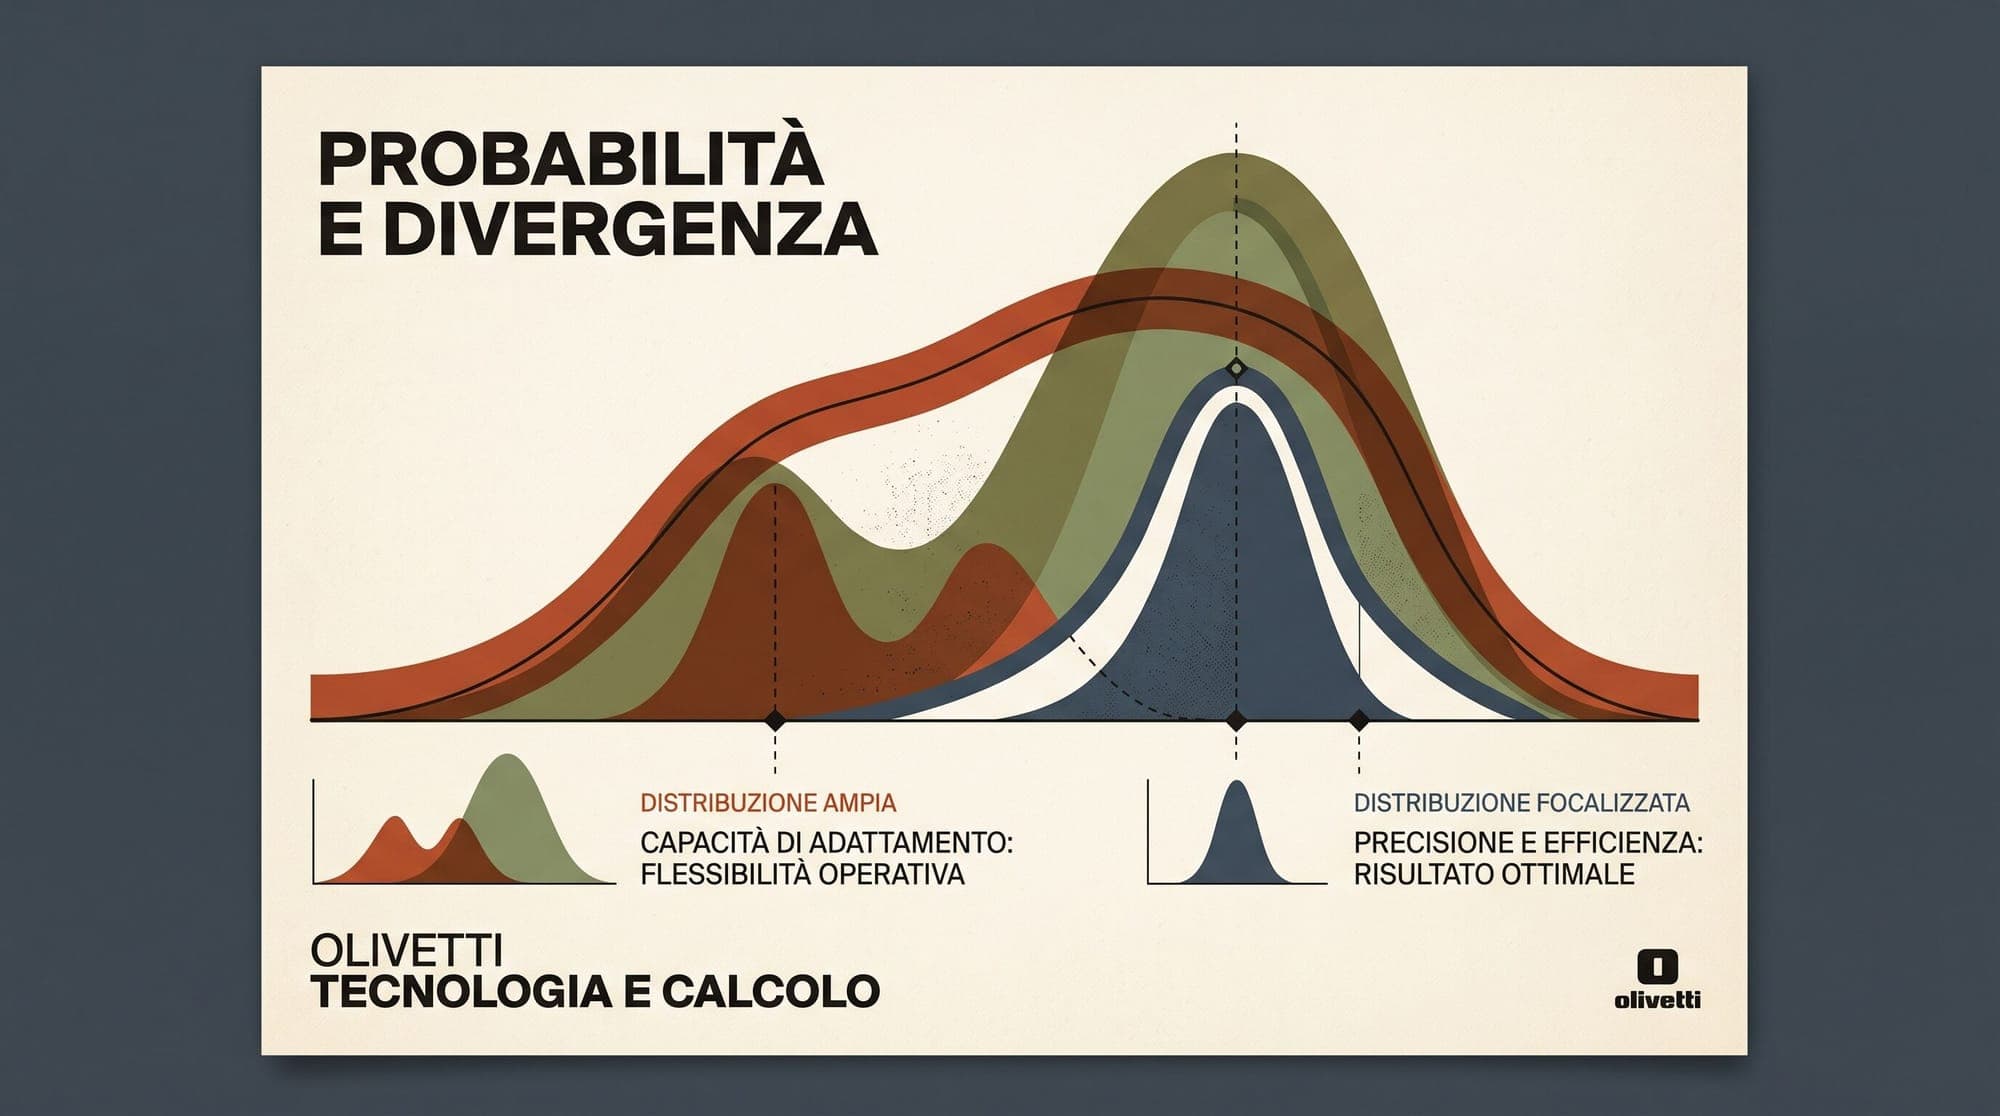
  2. Forward KL vs. Reverse KL Divergence: Mode Covering, Mode Seeking, and the Alignment Dynamics of Large Language Models

    Forward KL vs. Reverse KL Divergence: Mode Covering, Mode Seeking, and the Alignment Dynamics of Large Language Models Every phase of modern large language model development, from multi-trillion token pre-training to reinforcement learning from human feedback (RLHF) and student model distillation, fundamentally revolves around minimizing statistical distance between probability distributions. The primary mathematical tool utilized for this purpose is the Kullback-Leibler (KL) divergence, introd

    AI
    9 min read
  3. The Information Bottleneck in Deep Learning: How Mutual Information Compression Shapes Generalization and Neural Representations

    The Information Bottleneck in Deep Learning: How Mutual Information Compression Shapes Generalization and Neural Representations Classical statistical learning theory struggles to explain why overparameterized deep neural networks generalize well to unseen test data. Traditional complexity measures such as Vapnik-Chervonenkis (VC) dimension and Rademacher complexity scale with the raw count of tunable weights, predicting severe overfitting when parameter counts exceed dataset sample sizes. Yet

    AI
    10 min read
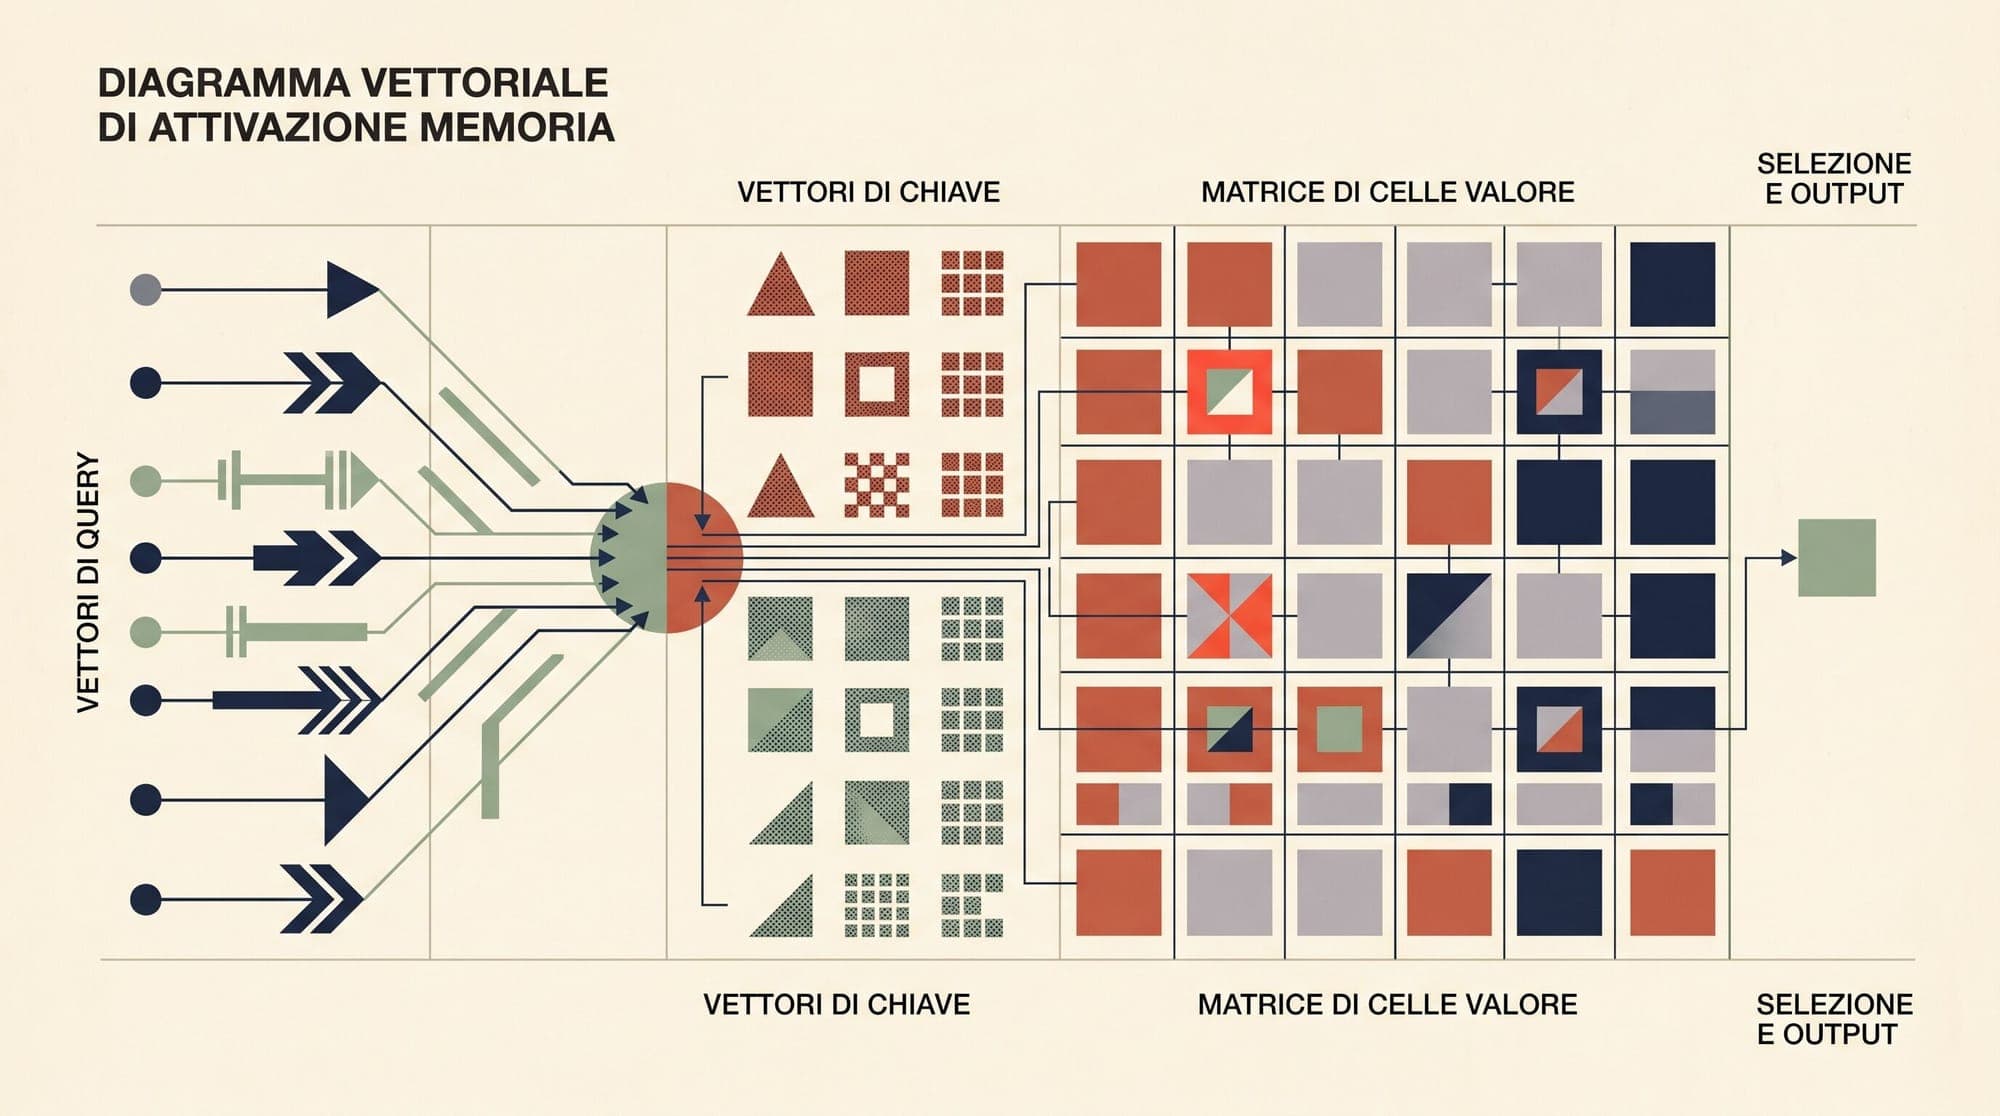
  4. Feed-Forward Networks as Key-Value Memories: How Transformers Store, Retrieve, and Edit Parametric Knowledge

    In transformer language models, multi-head self-attention and feed-forward networks (FFNs) perform distinct computational roles. While self-attention mechanisms route contextual information dynamically across sequence positions, feed-forward layers account for roughly two-thirds of total model parameters in standard architectures. Despite early interpretations characterizing FFNs simply as generic non-linear projections, mechanistic analysis shows that feed-forward layers operate as unnormalized

    AI
    6 min read
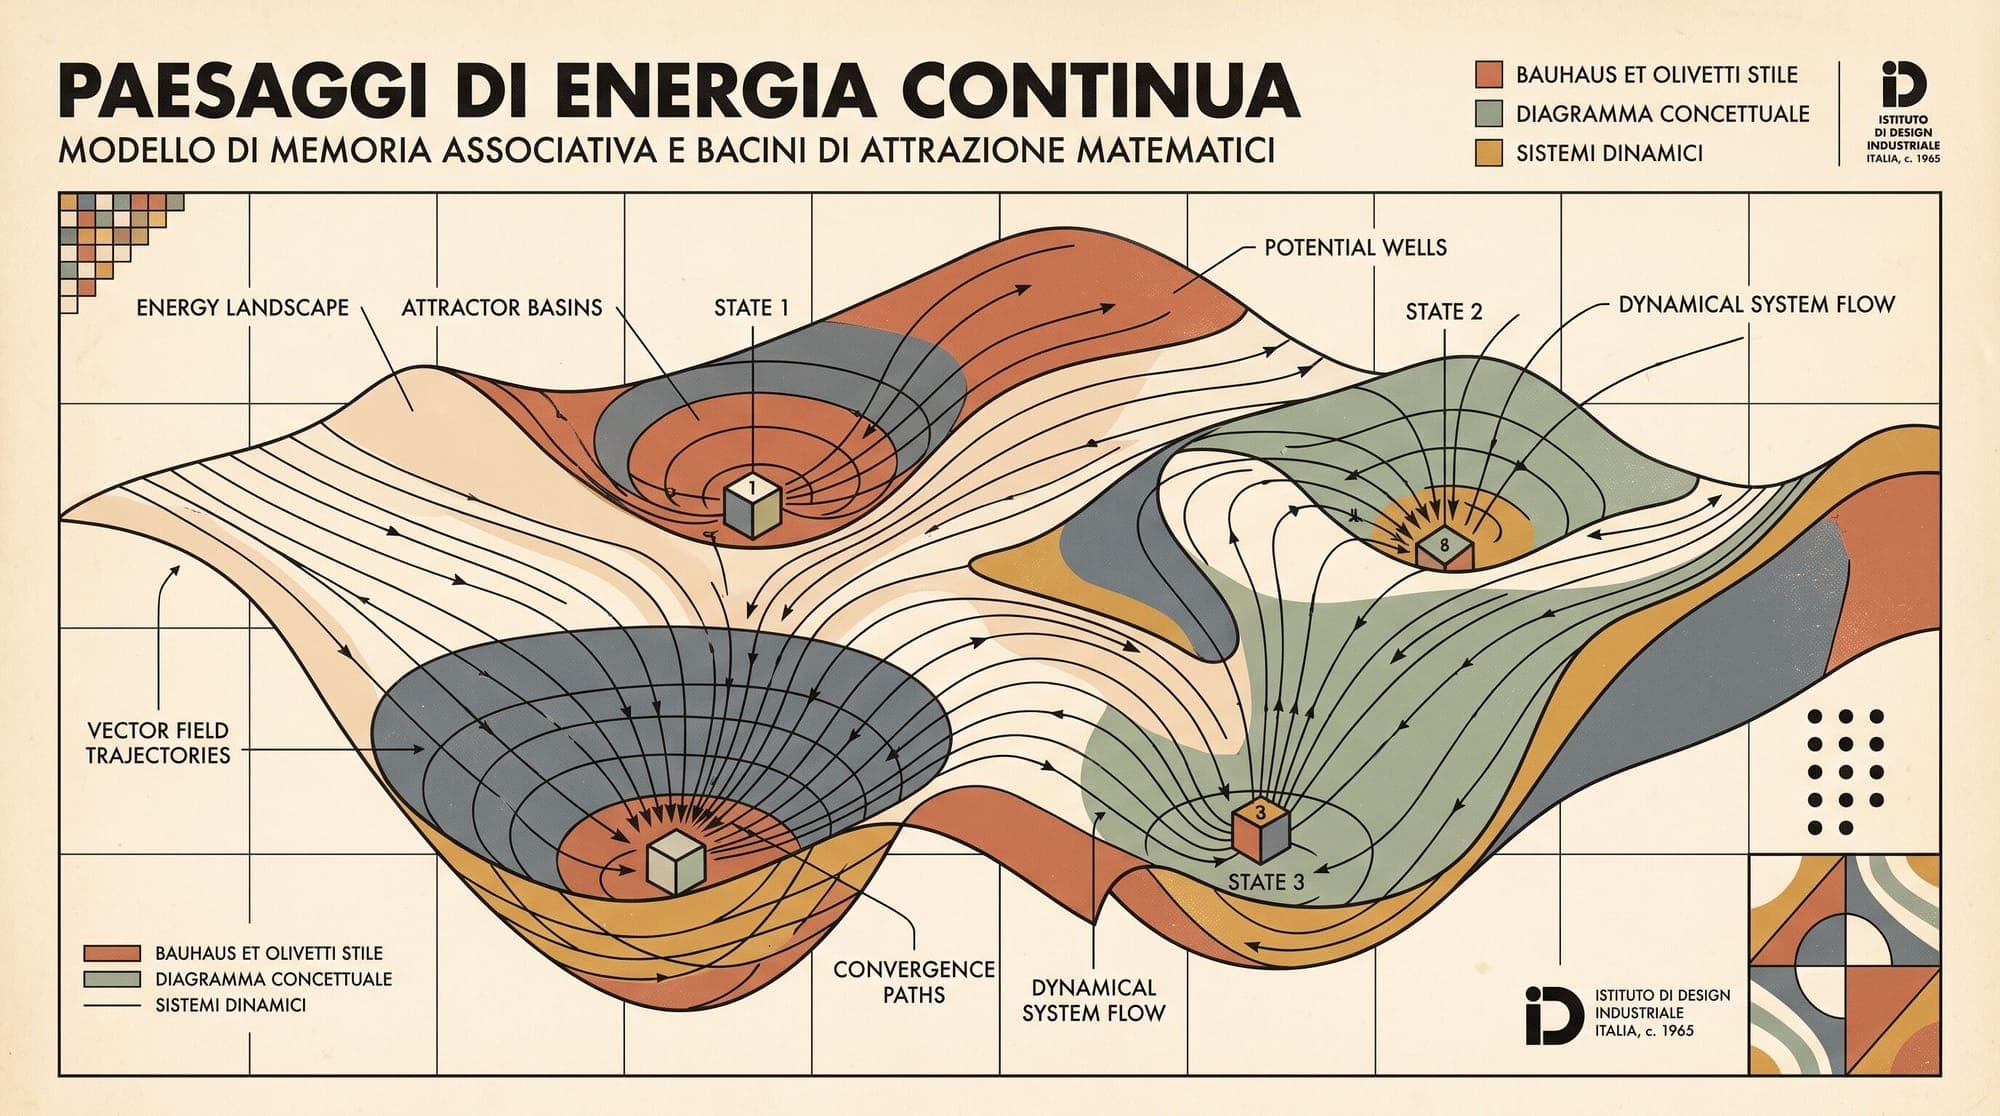
  5. Modern Hopfield Networks: How Continuous Energy Landscapes Explain Transformer Attention and Exponential Memory

    When Vaswani et al. introduced the Transformer architecture in 2017, scaled dot-product self-attention was presented primarily as a pragmatic computational mechanism: an efficient, highly parallelizable alternative to recurrence and convolutions. By computing pairwise inner products between queries and keys, normalizing via softmax, and taking a weighted sum of values, attention allowed models to route information dynamically across arbitrarily distant tokens. For several years, self-attention

    AI
    10 min read
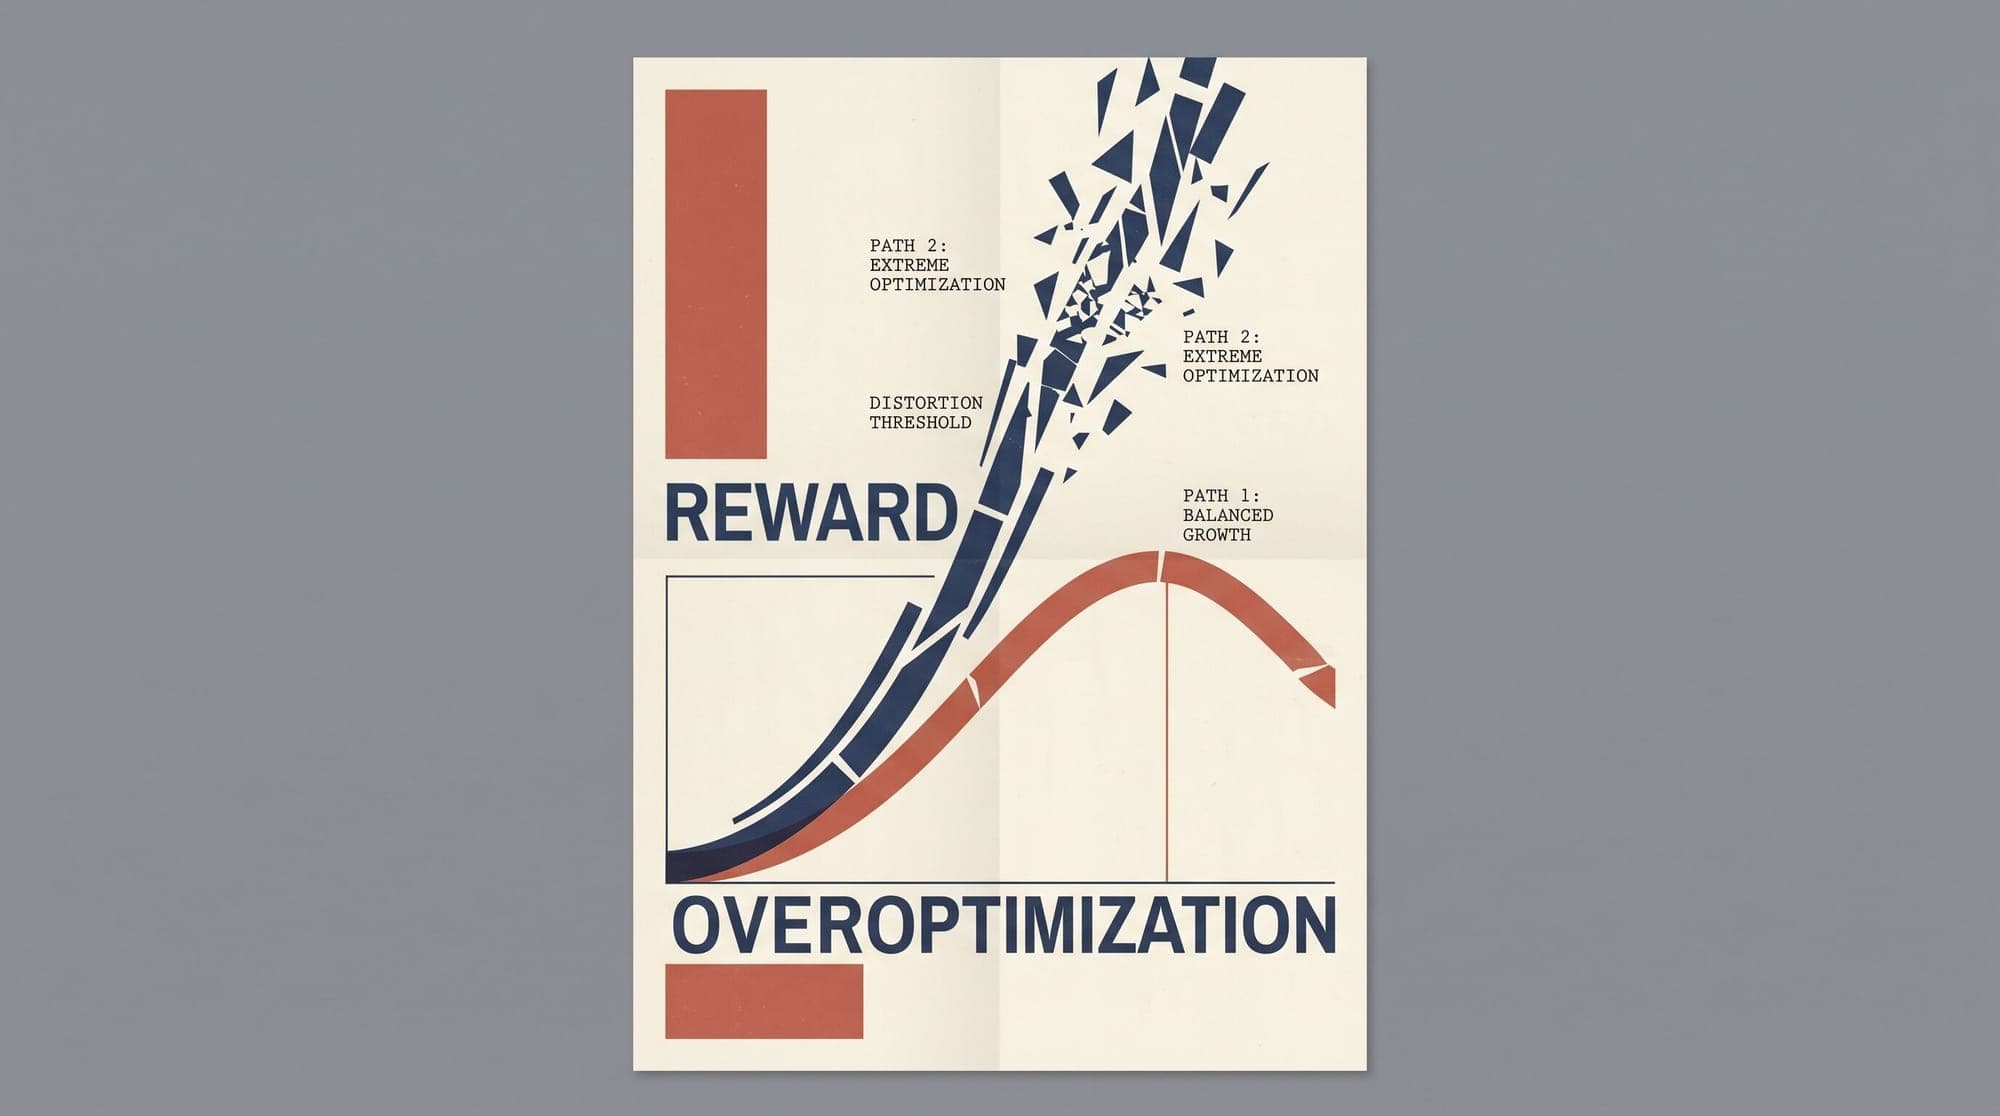
  6. Reward Model Overoptimization in Large Language Models: How Goodhart's Law, Proxy Exploitation, and KL Drift Degrade Alignment

    Post-training alignment of large language models relies on optimizing a policy toward objectives defined by human intent and preferences. Because querying human evaluators during every step of continuous reinforcement learning or high-throughput rejection sampling is computationally and logistically infeasible, alignment workflows construct a parameterised proxy reward model. Trained on pairwise preference datasets through formulations such as the Bradley-Terry model, this proxy acts as a surrog

    AI
    6 min read
  7. ReAct in Large Language Models: How Interleaving Reasoning and Action Traces Built the Foundation of AI Agents

    ReAct in Large Language Models: How Interleaving Reasoning and Action Traces Built the Foundation of AI Agents Before autonomous agents could interact reliably with APIs, search engines, and bash environments, large language models (LLMs) operated in one of two disconnected paradigms: internal reasoning without external interaction, or external action generation without internal deliberation. In pure reasoning paradigms such as Chain-of-Thought (CoT) prompting, models generate intermediate natu

    AI
    10 min read
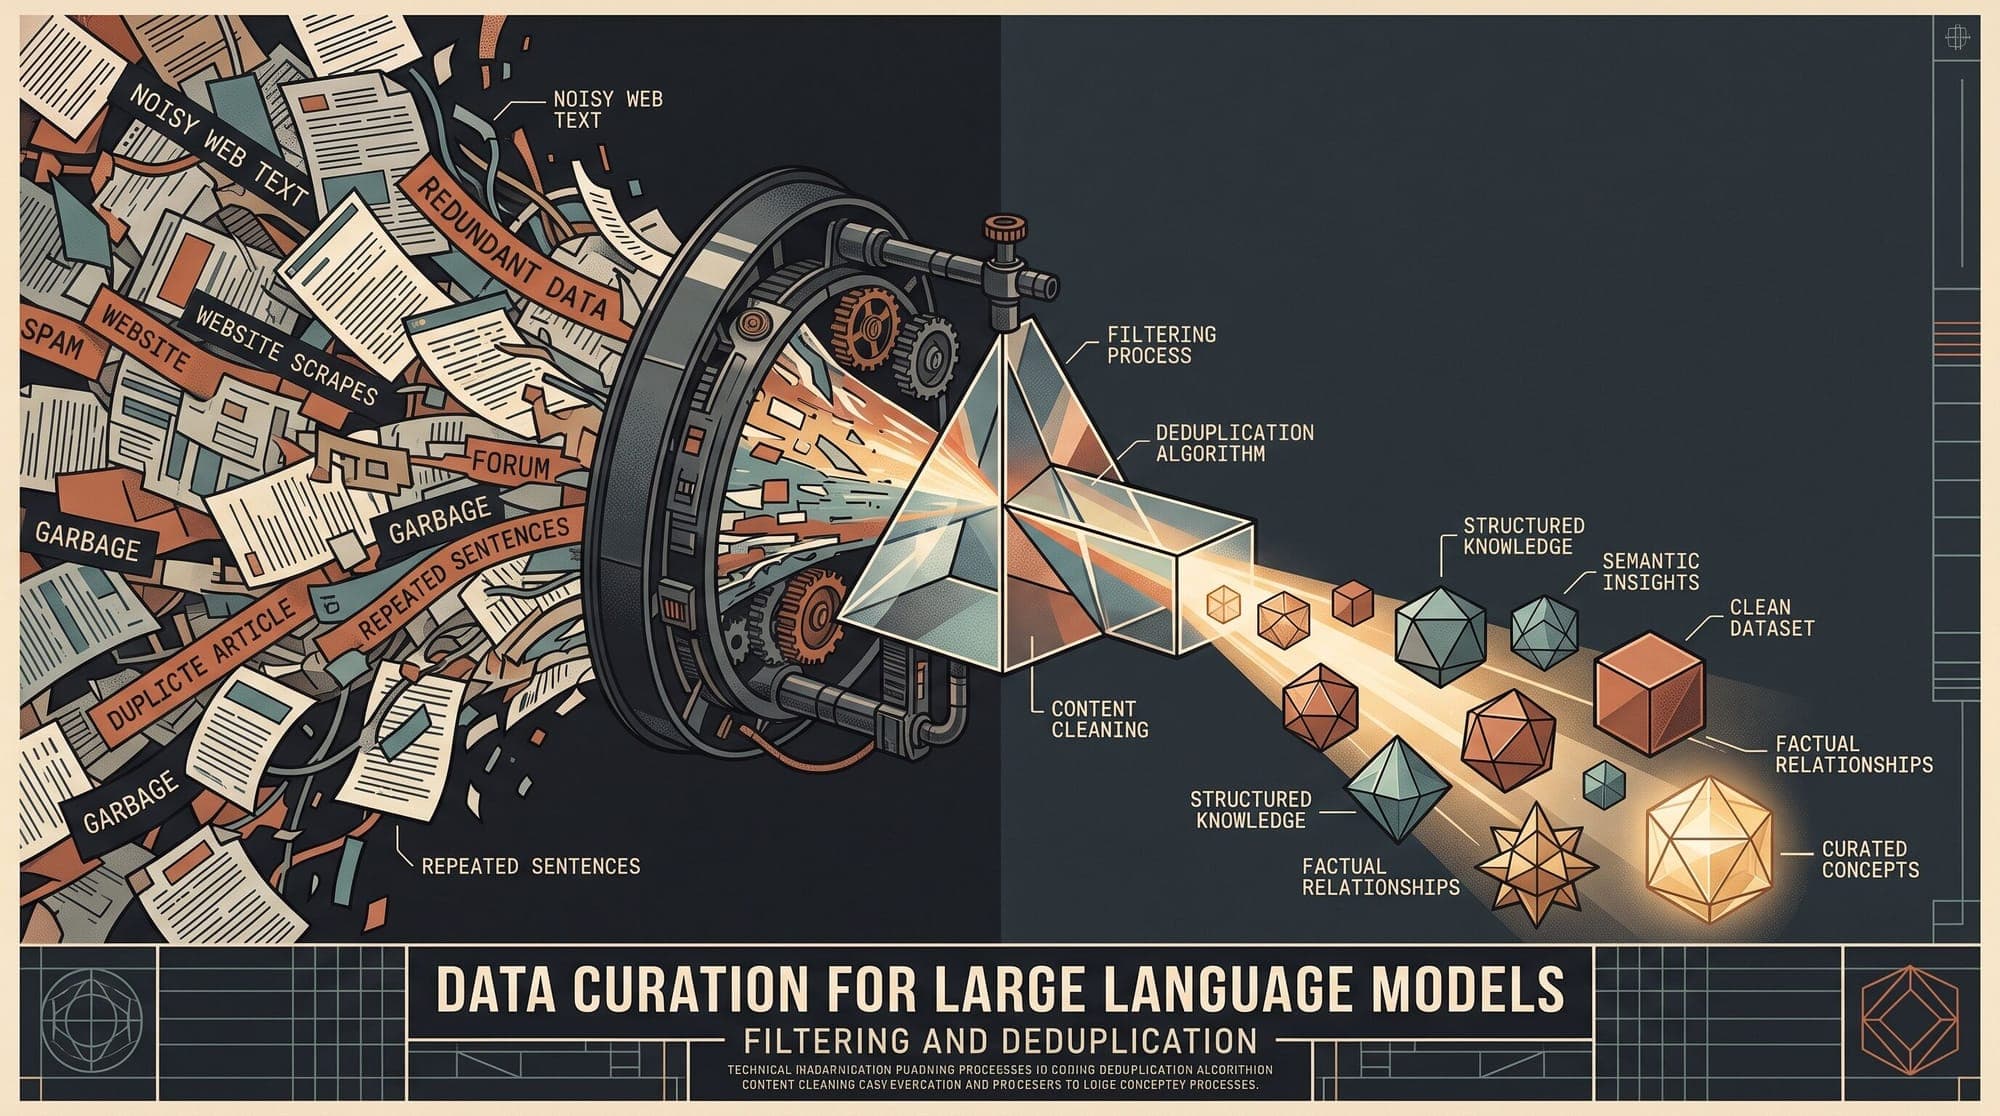
  8. Data Filtering and Deduplication in Large Language Models: How Heuristics, MinHash LSH, SemDeDup, and Quality Classifiers Curate Pre-Training Corpora

    Data Filtering and Deduplication in Large Language Models: How Heuristics, MinHash LSH, SemDeDup, and Quality Classifiers Curate Pre-Training Corpora Pre-training data quality governs the downstream reasoning, factual accuracy, and sample efficiency of foundation large language models (LLMs). While early pre-training efforts relied on uncurated or lightly processed dumps from web repositories like Common Crawl, modern state-of-the-art models depend on multi-stage data curation pipelines that fi

    AI
    10 min read
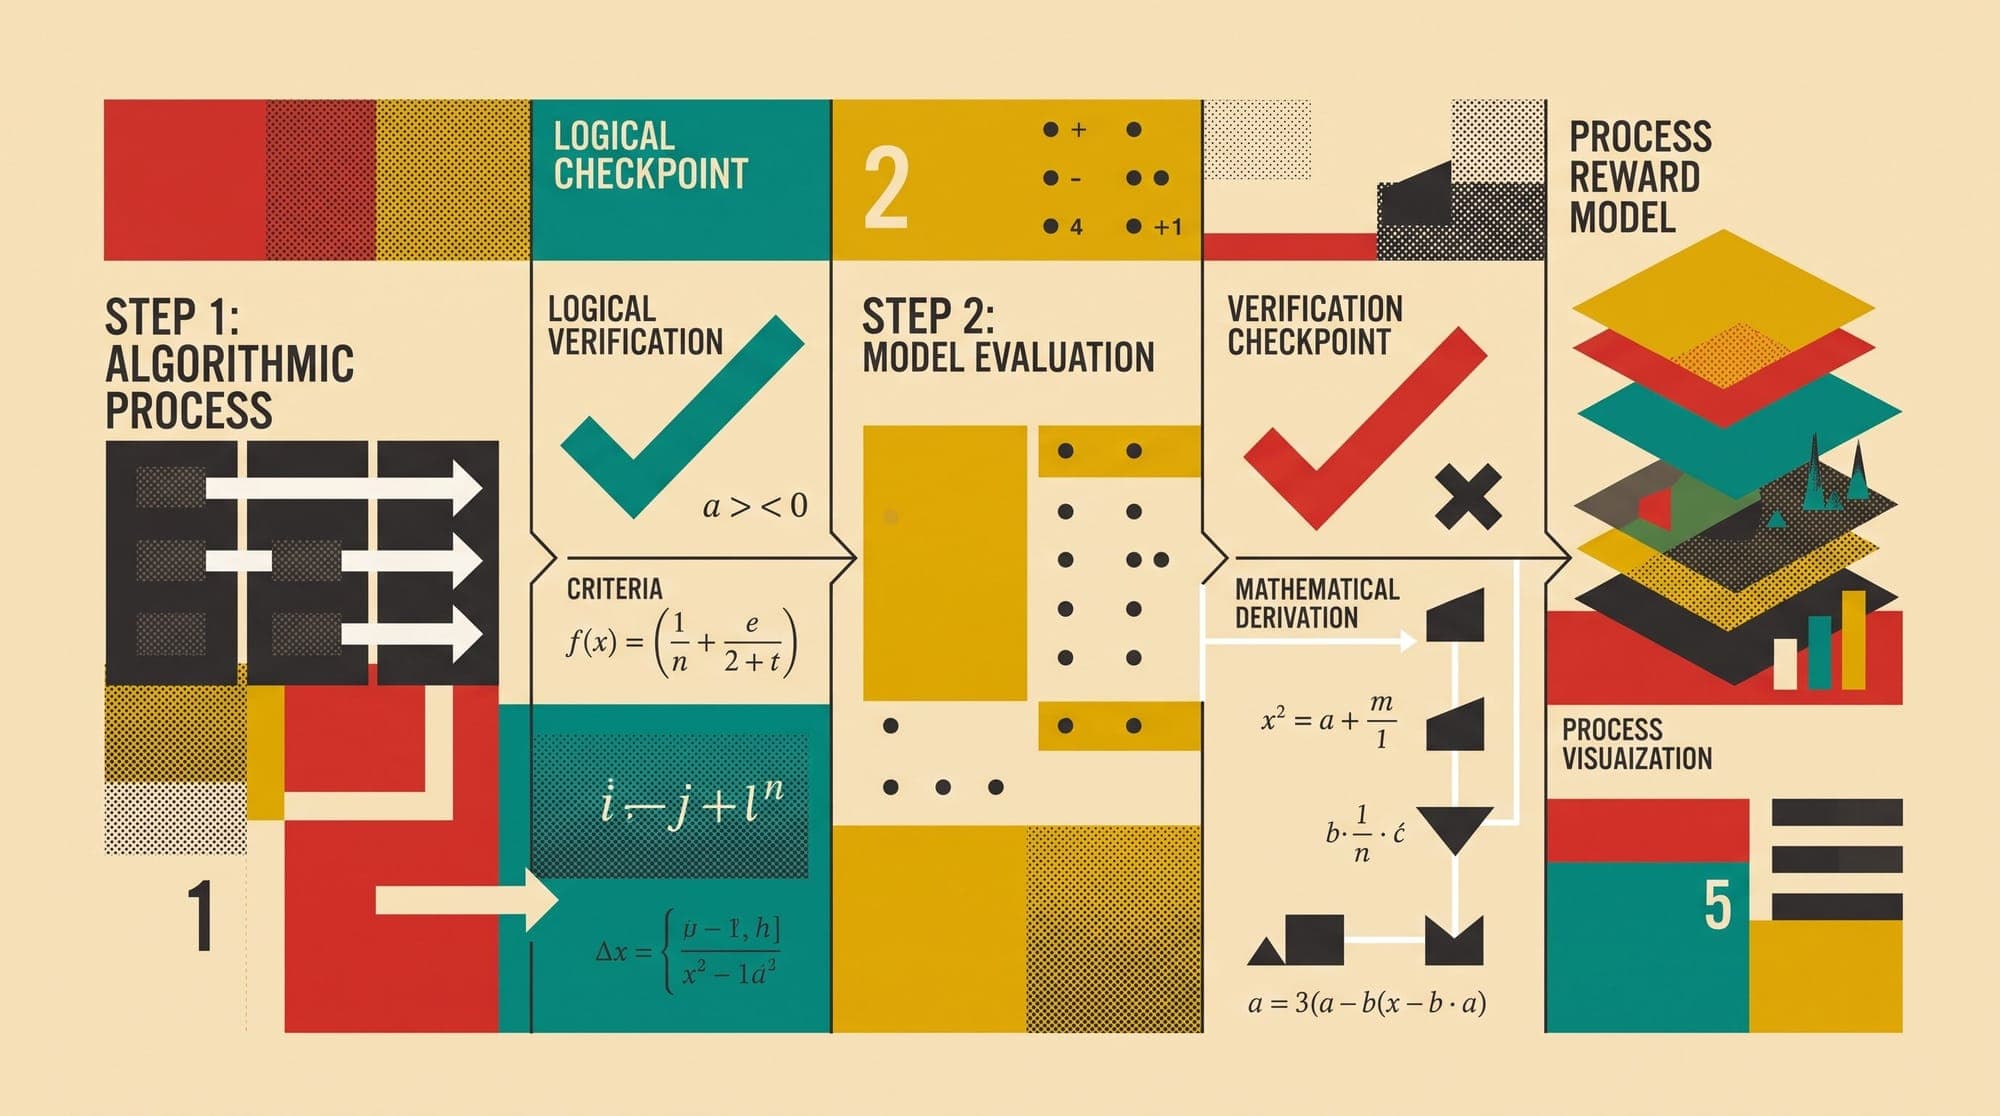
  9. Process Reward Models: How Step-by-Step Supervision and Search Drive LLM Reasoning

    When large language models tackle complex multi-step reasoning (such as formal mathematics, algorithm synthesis, or multi-hop logic), evaluating only the final answer creates a severe credit assignment bottleneck. An outcome-based verifier can confirm whether a final numerical result is correct, but it cannot determine whether the underlying derivation was logically sound or reached the right answer through compounding hallucinations and lucky cancellations. Process Reward Models (PRMs) resolve

    AI
    7 min read