
Every headline number in the AI industry traces back to the same piece of silicon. Datacenter buildouts are measured in "GPU equivalents." Nvidia became one of the most valuable companies on earth selling a chip whose original purpose was rendering video game graphics. If you want to understand why the industry is shaped this way, the answer is not software. It is arithmetic.
This entry in our "What Is" explainer series is the most mechanical one yet: what a GPU is, why matrix multiplication rules this field, and why the spec sheet number everyone quotes (FLOPS) is often the least important one.
A language model is mostly matrix multiplication
Strip away the marketing and a transformer does one thing over and over: it multiplies big matrices by other big matrices. Every layer of every forward pass is a sequence of generalized matrix multiplications (GEMMs): projecting tokens into query, key and value matrices, attention as two chained matrix products, and the feed-forward layers as two more. Nvidia's own performance guide frames the entire workload of deep learning around how efficiently a GPU partitions these matrix products into tiles and assigns them to thread blocks (NVIDIA documentation).
The same is true of the old convolutional networks that came before transformers. Convolutions are little more than many small matrix multiplications sliding across an image. So when researchers say "AI is matrix multiplication," they are being almost literally accurate: the dominant cost of both training and inference is multiplying arrays of numbers, billions of times.
Why a CPU struggles with this and a GPU does not
A central processing unit is built for latency. It has a handful of powerful cores wrapped in sophisticated machinery (caches, branch prediction, out-of-order execution) whose job is to finish one complicated, sequential task as fast as possible (arXiv survey of CPU vs GPU matrix multiplication).
A graphics processing unit is built for the opposite trade. It packs thousands of simpler cores onto the die and optimizes for throughput: the same operation applied to a mountain of data at once. That design was born from graphics. A frame of 3D video means transforming millions of vertices and shading millions of pixels, and no pixel's color depends on its neighbor's. The work is regular, predictable, and embarrassingly parallel.
Matrix multiplication shares exactly those properties. Each entry of the output matrix is an independent dot product. Nothing has to wait for anything else. A workload a CPU sequences through a few cores becomes a workload a GPU spreads across thousands. For large matrices in the study above, a mobile GPU beat a parallel CPU by more than 45 times, and the gap widens with problem size.
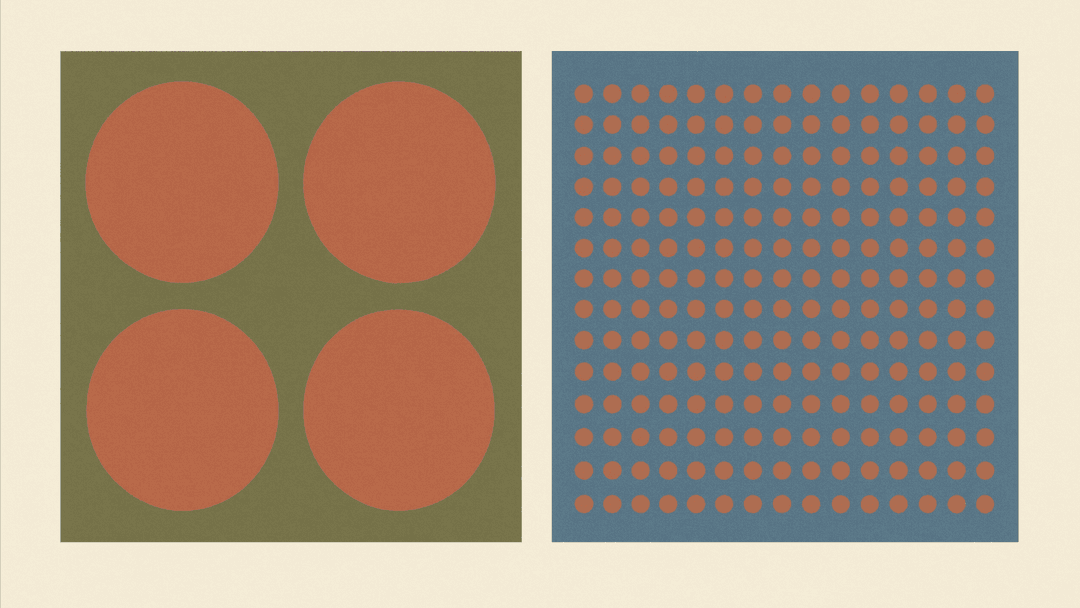
The CPU/GPU split in one picture: a few big units versus many small ones, doing the same work.
How graphics cards became AI machines
The pivot point was software. In 2007 Nvidia released CUDA, an API that let ordinary programs run calculations on the graphics card instead of only drawing with it (Wikipedia: CUDA). Suddenly the parallel hardware built for pixels was general-purpose arithmetic.
The demonstration everyone cites is AlexNet. In 2012, a Toronto team (Krizhevsky, Sutskever, Hinton) won the ImageNet vision competition by a wide margin, with 15.3% top-5 error against 26.2% for the runner-up. Their network had 60 million parameters, trained over five to six days on two GeForce GTX 580 cards, 3GB of memory each (NeurIPS 2012 paper, PDF). The GTX 580 launched at $500 and did about 1.6 trillion floating-point operations per second in 32-bit math (Wikipedia: AlexNet).
The lesson the field took was not "deep learning works." It was "the next GPU generation is the next breakthrough." The authors wrote that results "can be improved simply by waiting for faster GPUs and bigger datasets." The industry obliged, and the chip roadmap bent toward matrix math: dedicated Tensor Cores that execute a mixed-precision matrix multiply-accumulate in a single clock cycle are now a standard fixture on Nvidia datacenter GPUs (NVIDIA documentation).
The number that actually limits your model
Here is where the naive mental model breaks. You would think a faster chip makes token generation proportionally faster. It often does not, because a GPU is constrained by two different hardware ceilings at once.
The first is arithmetic: how many floating-point operations the cores can perform per second. The second is bandwidth: how many bytes the memory chips can hand to the cores per second. The classic framework for reasoning about this is the roofline model, introduced by Williams, Waterman and Patterson in 2009 (ACM/IEEE Supercomputing).
The tool it gives you is called arithmetic intensity: the number of math operations performed per byte moved from memory. Below a hardware-specific crossover point, the chip is memory-bound: the Tensor Cores sit partly idle waiting for data, and adding more FLOPS would accomplish nothing. Above it, you are compute-bound and the math units are the limit (Spheron roofline explainer).
Run the numbers on a flagship. An H100 advertises up to 1,979 trillion operations per second in 16-bit math (counting sparsity) and 3.35 terabytes per second of high-bandwidth memory (Nvidia H100 page; d-Matrix analysis). Divide one by the other and the ridge point is roughly 590 FLOPs per byte. A workload must do about 590 calculations on every byte it loads just to keep the chip busy.
Why generating one token is a memory problem
Training and prefilling a long prompt process thousands of tokens at once. The same weights get reused for all of them, so the arithmetic intensity is high and the chip runs near its compute ceiling.
Plain generation is the opposite. To emit a single token, the model must read every parameter in the network from memory, plus re-read the key-value cache, the attention state for every previous token in the conversation, which grows with context length (d-Matrix analysis). That is roughly two FLOPs per byte touched, one or two orders of magnitude below the ridge point. In measurements of small-batch decode, the compute-to-memory ratio sits between 0.5 and 1 operation per byte, firmly memory-bound (arXiv 2503.08311).
This is why much of an H100's headline speed "evaporates" during single-stream chat (rooftop analysis), and why serving companies batch many requests together: batching reuses each weight read across dozens of conversations, pulling the workload back toward the compute-bound side. It is also why quantization, which shrinks each parameter to fewer bytes, speeds up generation: it reduces exactly what the bottleneck measures. And it is why memory, not logic, sets the price: high-bandwidth memory stacks and the packaging that attaches them to the chip are among the scarcest inputs in the AI buildout.
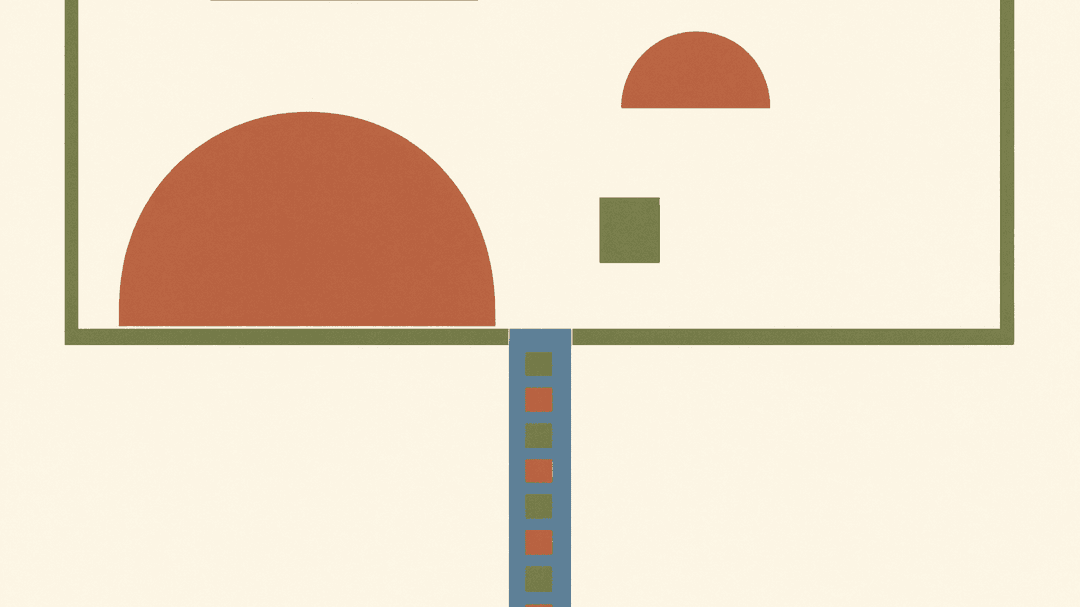
Generation is a funnel: bytes squeeze through a narrow memory channel while the math units wait.
The challengers, and why the GPU still wins
Google made the sharpest counterargument. Its Tensor Processing Unit, first deployed in datacenters in 2015, strips out everything a general-purpose chip needs and keeps only the matrix engine: a 65,536-cell 8-bit multiply unit peaking at 92 trillion operations per second, with a large software-managed on-chip memory instead of caches. In Google's 2017 measurements the TPU ran production neural network inference 15 to 30 times faster than a contemporary CPU or GPU at 30 to 80 times better performance per watt (Jouppi et al., arXiv 1704.04760; Google Cloud blog).
The TPU paper makes the trade-off explicit: domain-specific silicon wins on efficiency, but graphics cards won the field because workloads kept moving. A GPU trained AlexNet in 2012, a GPT in 2018, and a reasoning model today, without new hardware. Custom chips need their own compilers, libraries and supply chains, and the software stack Nvidia accumulated (CUDA, cuDNN, cuBLAS, and the frameworks that call them) is the reason "buy more GPUs" remains the default answer. That is changing at the edges (every major lab now runs some alternative silicon), but the center of gravity holds.
Why this matters
Three practical takeaways. First, when you read "the model was trained on 100,000 GPUs," the relevant question is memory bandwidth and interconnect, not just FLOPS. Second, the latency you feel in a chat interface is mostly the memory bottleneck of generation, which is why long outputs slow down and batching discounts exist. Third, the entire economics of open-weights models, quantized downloads and subscription tiers trace to one hardware fact: this workload spends most of its time waiting for bytes.
Sources
- NVIDIA, Matrix Multiplication Background User's Guide: https://docs.nvidia.com/deeplearning/performance/dl-performance-matrix-multiplication/index.html
- "Accelerating Matrix Multiplication: A Performance Comparison Between Multi-Core CPU and GPU": https://arxiv.org/abs/2507.19723
- Krizhevsky, Sutskever, Hinton, ImageNet Classification with Deep Convolutional Neural Networks (NeurIPS 2012): https://proceedings.neurips.cc/paper/4824-imagenet-classification-with-deep-convolutional-neural-networks.pdf
- Wikipedia, AlexNet: https://en.wikipedia.org/wiki/AlexNet
- Wikipedia, CUDA: https://en.wikipedia.org/wiki/CUDA
- Williams, Waterman, Patterson, Roofline: An Insight-Based Performance Model (2009): https://dl.acm.org/doi/10.1145/1654009.1654015
- Spheron, "The Roofline Model for LLM Inference": https://www.spheron.network/blog/the-roofline-model-for-llm-inference-are-you-compute-bound-o
- d-Matrix, "AI Inference Bottleneck: Why It's Memory, Not Compute": https://www.d-matrix.ai/ai-inference-bottleneck
- "What Does 'LLMs Are Memory Bandwidth Bound' Really Mean?": https://medium.com/@jiminlee-ai/what-does-llms-are-memory-bandwidth-bound-really-mean-4a1a57161b53
- "Mind the Memory Gap: Unveiling GPU Bottlenecks in Large-Batch LLM Inference": https://arxiv.org/abs/2503.08311
- Nvidia H100 product page: https://www.nvidia.com/en-us/data-center/h100/
- Jouppi et al., In-Datacenter Performance Analysis of a Tensor Processing Unit: https://arxiv.org/abs/1704.04760
- Google Cloud, "An in-depth look at Google's first Tensor Processing Unit (TPU)": https://cloud.google.com/blog/products/ai-machine-learning/an-in-depth-look-at-googles-first-tensor-processing-unit-tpu
