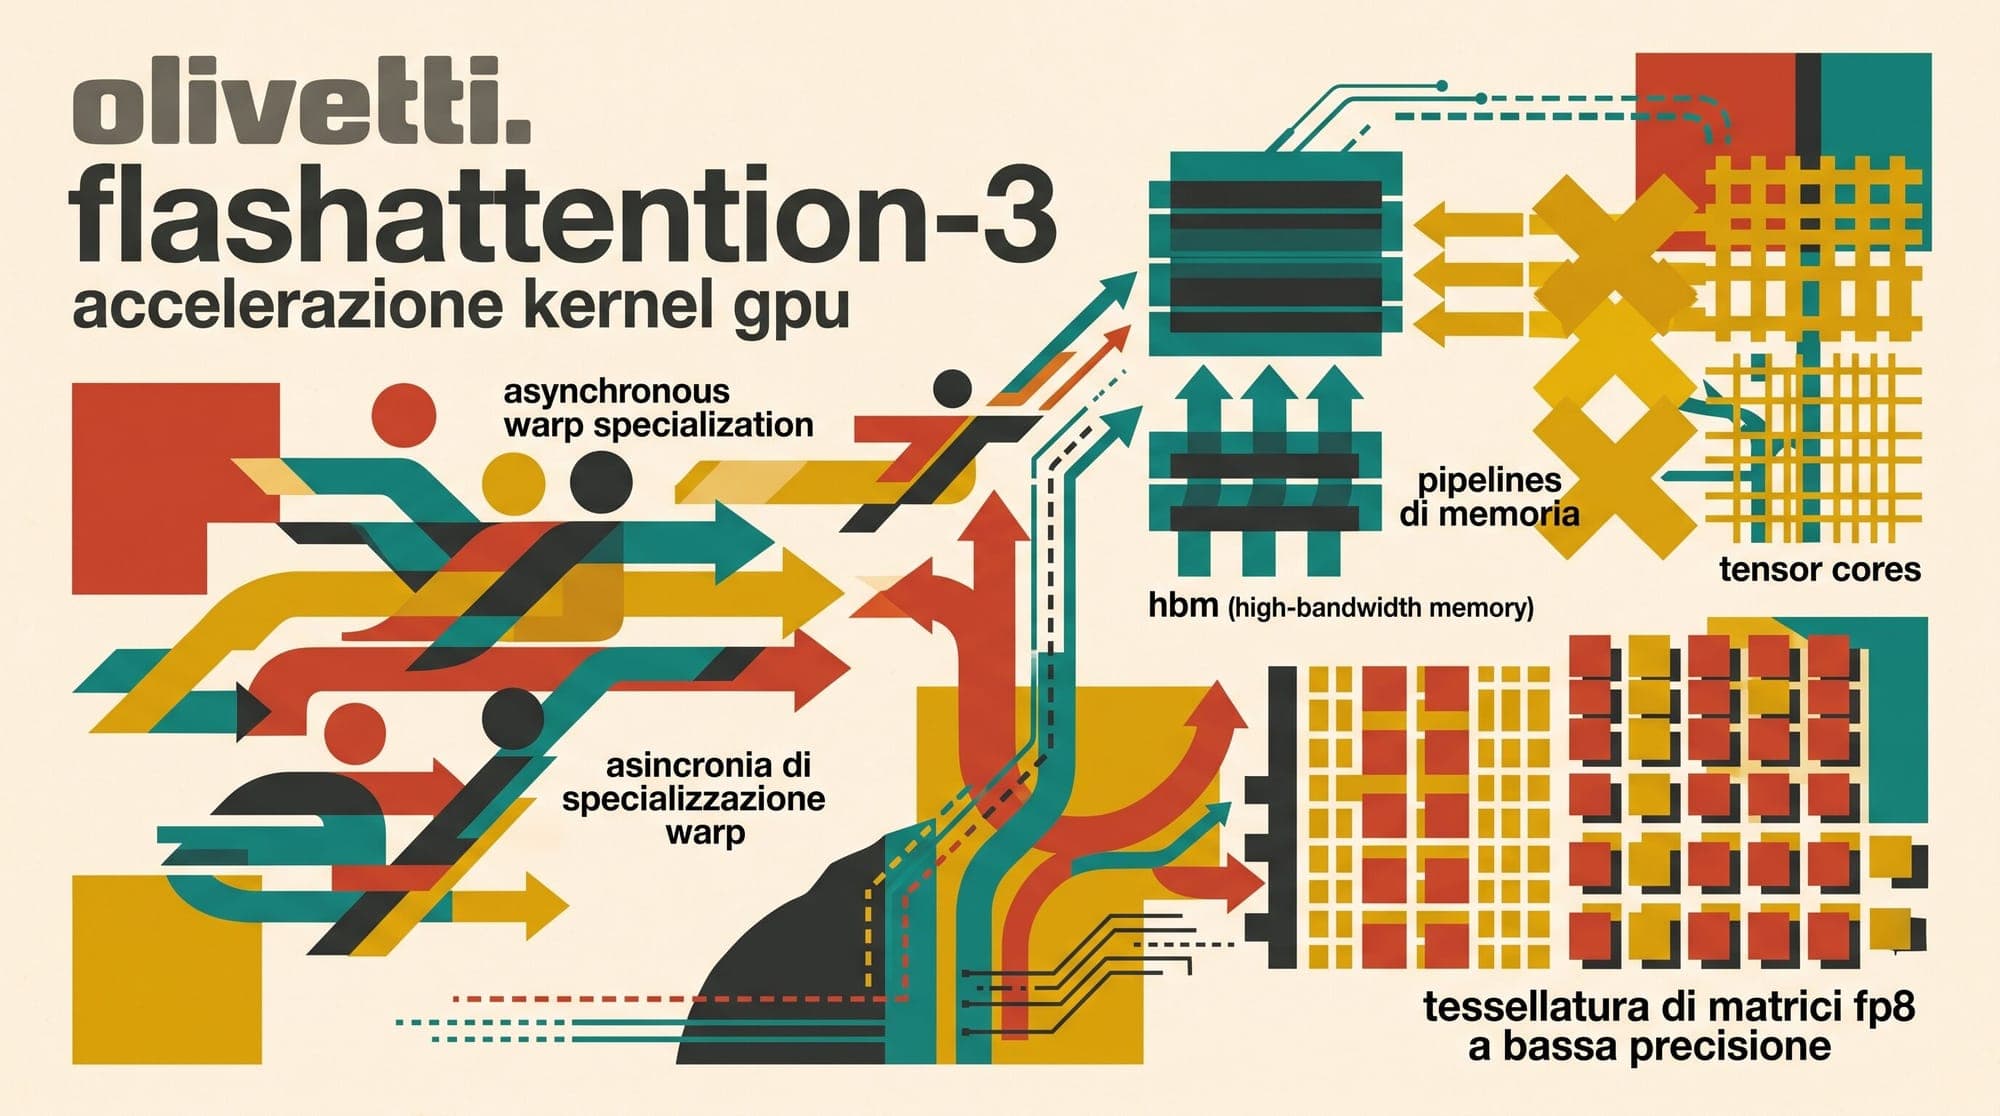
FlashAttention-3: How Warp Specialization, Asynchronous TMA Tiling, and FP8 Hardware Acceleration Scale Attention on Hopper GPUs
FlashAttention-3: How Warp Specialization, Asynchronous TMA Tiling, and FP8 Hardware Acceleration Scale Attention on Hopper GPUs The emergence of Transformer architectures scaled deep learning across language, vision, and multimodal domains, but standard exact attention has historically imposed severe compute and memory bandwidth bottlenecks. The standard multi-head self-attention operation computes: $$\text{Attention}(Q, K, V) = \text{softmax}\left(\frac{QK^T}{\sqrt{d}}\right)V$$ For a seque