Generalized Advantage Estimation: How Exponential Weighting Balances Bias and Variance in Policy Optimization
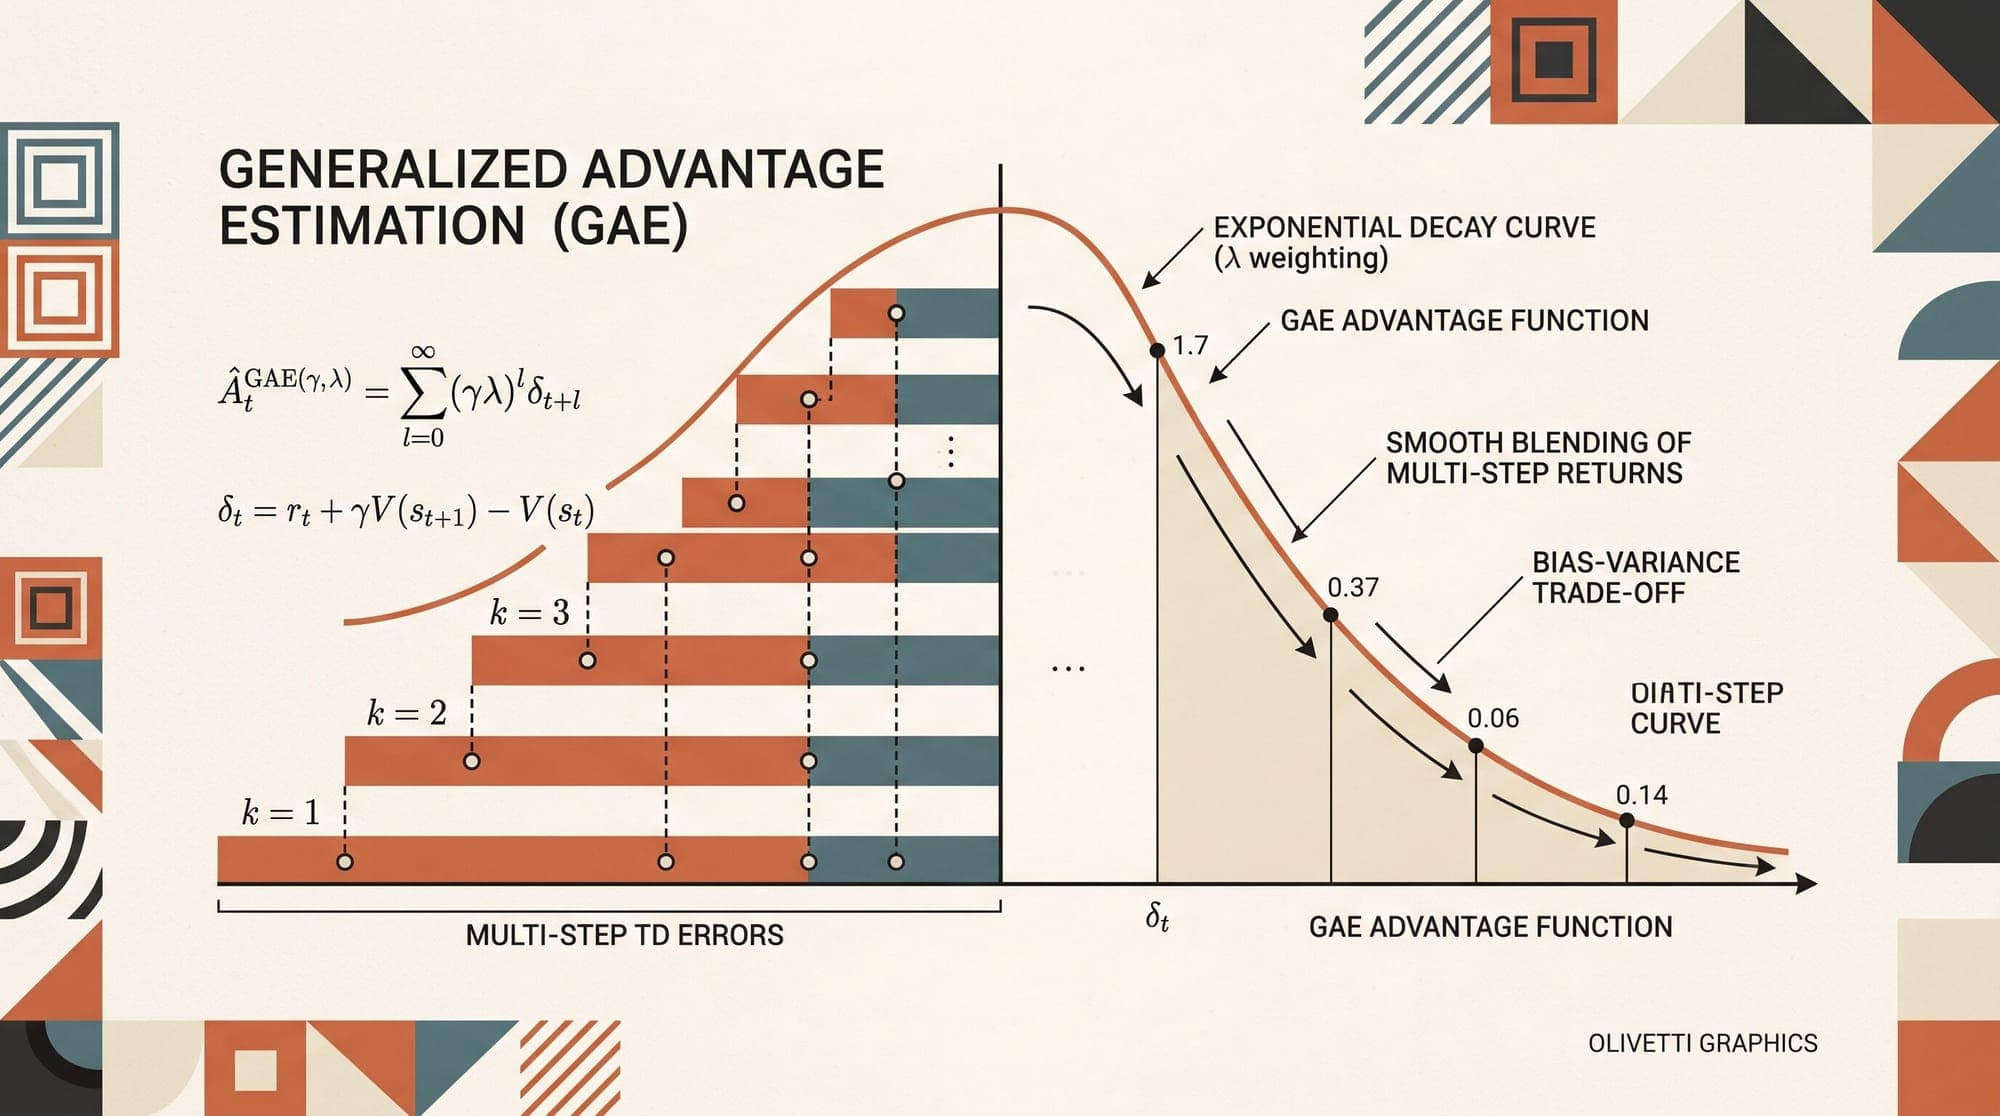
Policy gradient algorithms form the theoretical backbone of modern policy optimization, ranging from continuous robotic control to reinforcement learning from human feedback (RLHF) in frontier large language models. A persistent challenge in policy optimization is variance: estimating the gradient of expected cumulative reward over stochastic trajectories generates high-variance Monte Carlo signals that require massive sample sizes and risk destabilizing gradient updates. Generalized Advantage