Latest / page 35

The latest stories

1230 articles

Articles, page 35

681-700 of 1230
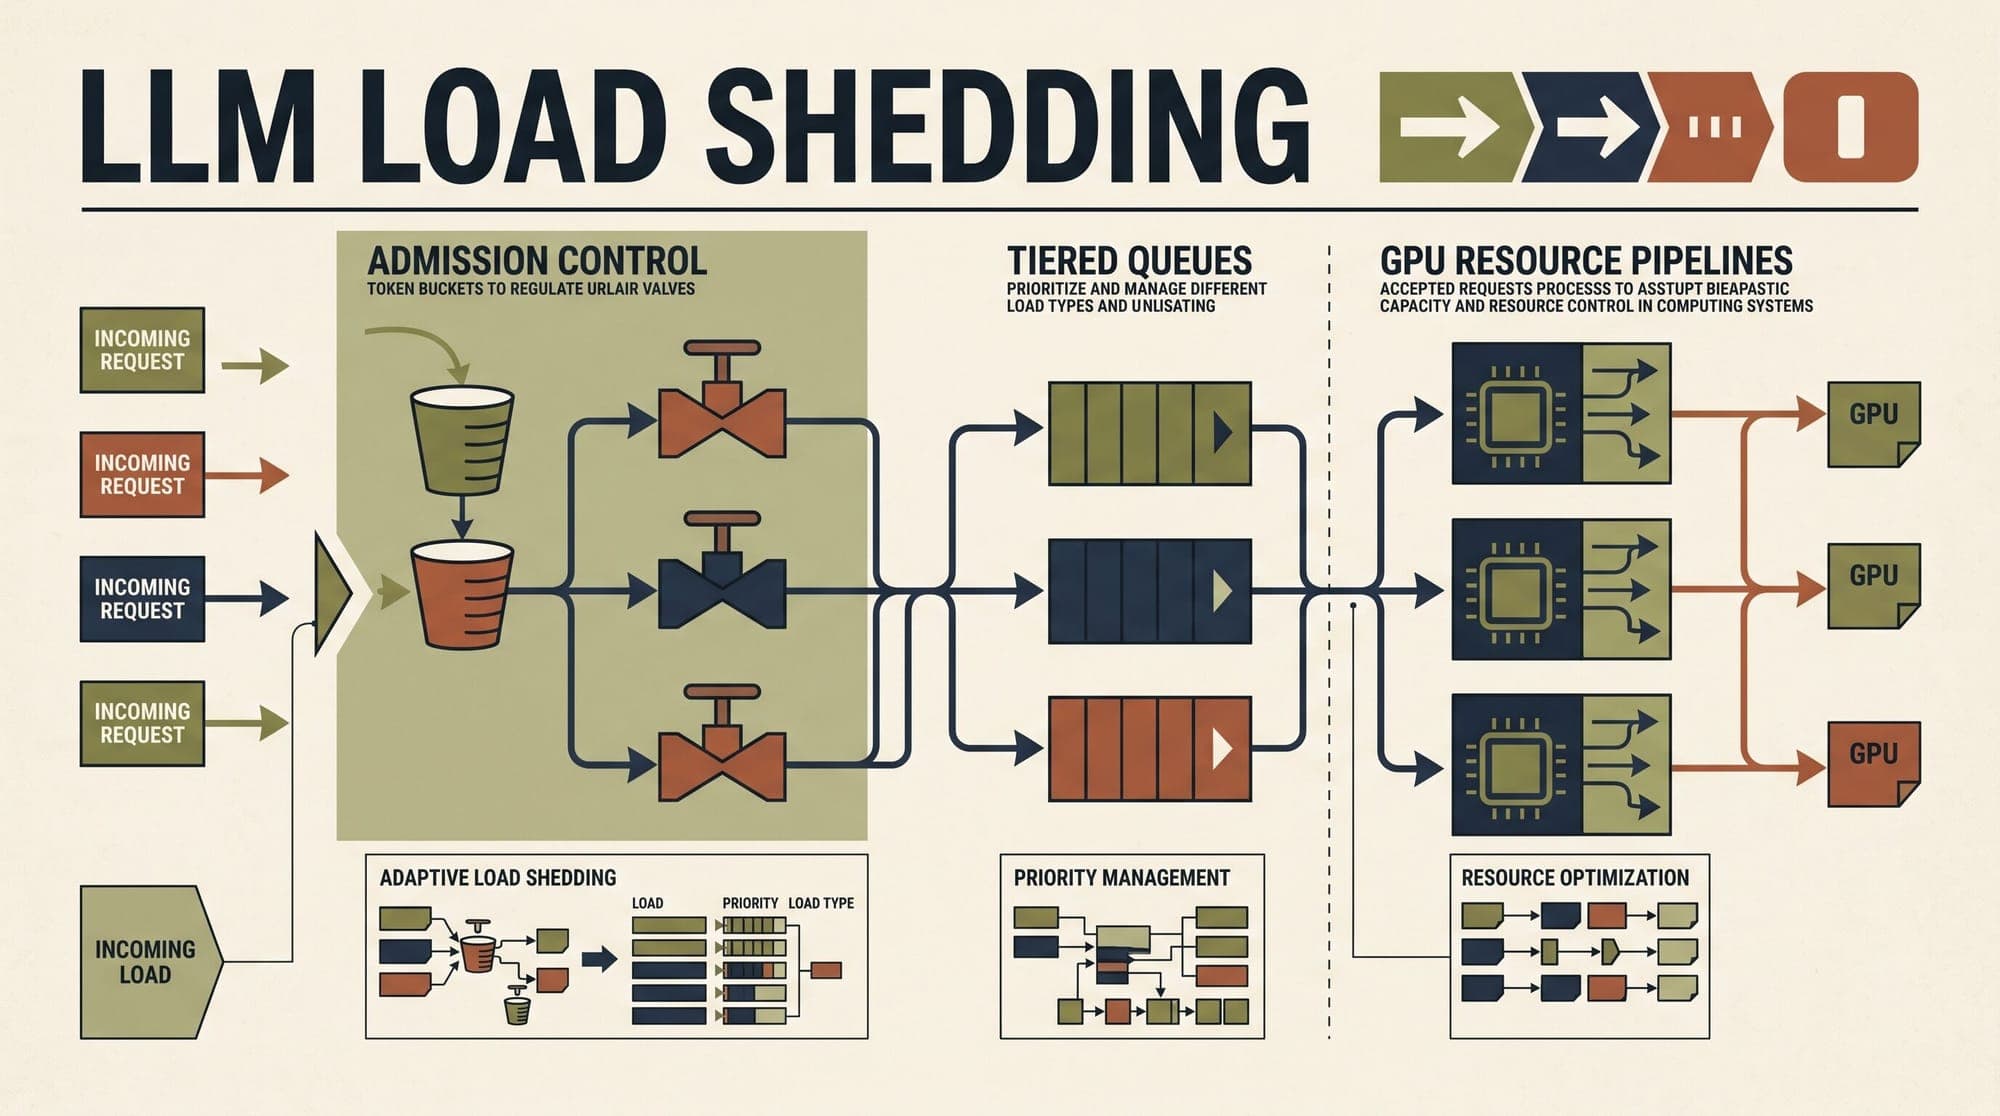
  1. LLM Load Shedding and Overload Control in Production: Adaptive Admission, Preemption Economics, and Graceful Degradation

    LLM Load Shedding and Overload Control in Production: Adaptive Admission, Preemption Economics, and Graceful Degradation Standard web services rely on well-established overload protection patterns: reverse proxies monitor CPU utilization, memory thresholds, or static queue depths and reject excess HTTP requests with 429 Too Many Requests or 503 Service Unavailable status codes. When applied naively to Large Language Model (LLM) serving infrastructure, these conventional heuristics fail catastro
    LLM
    9 min read
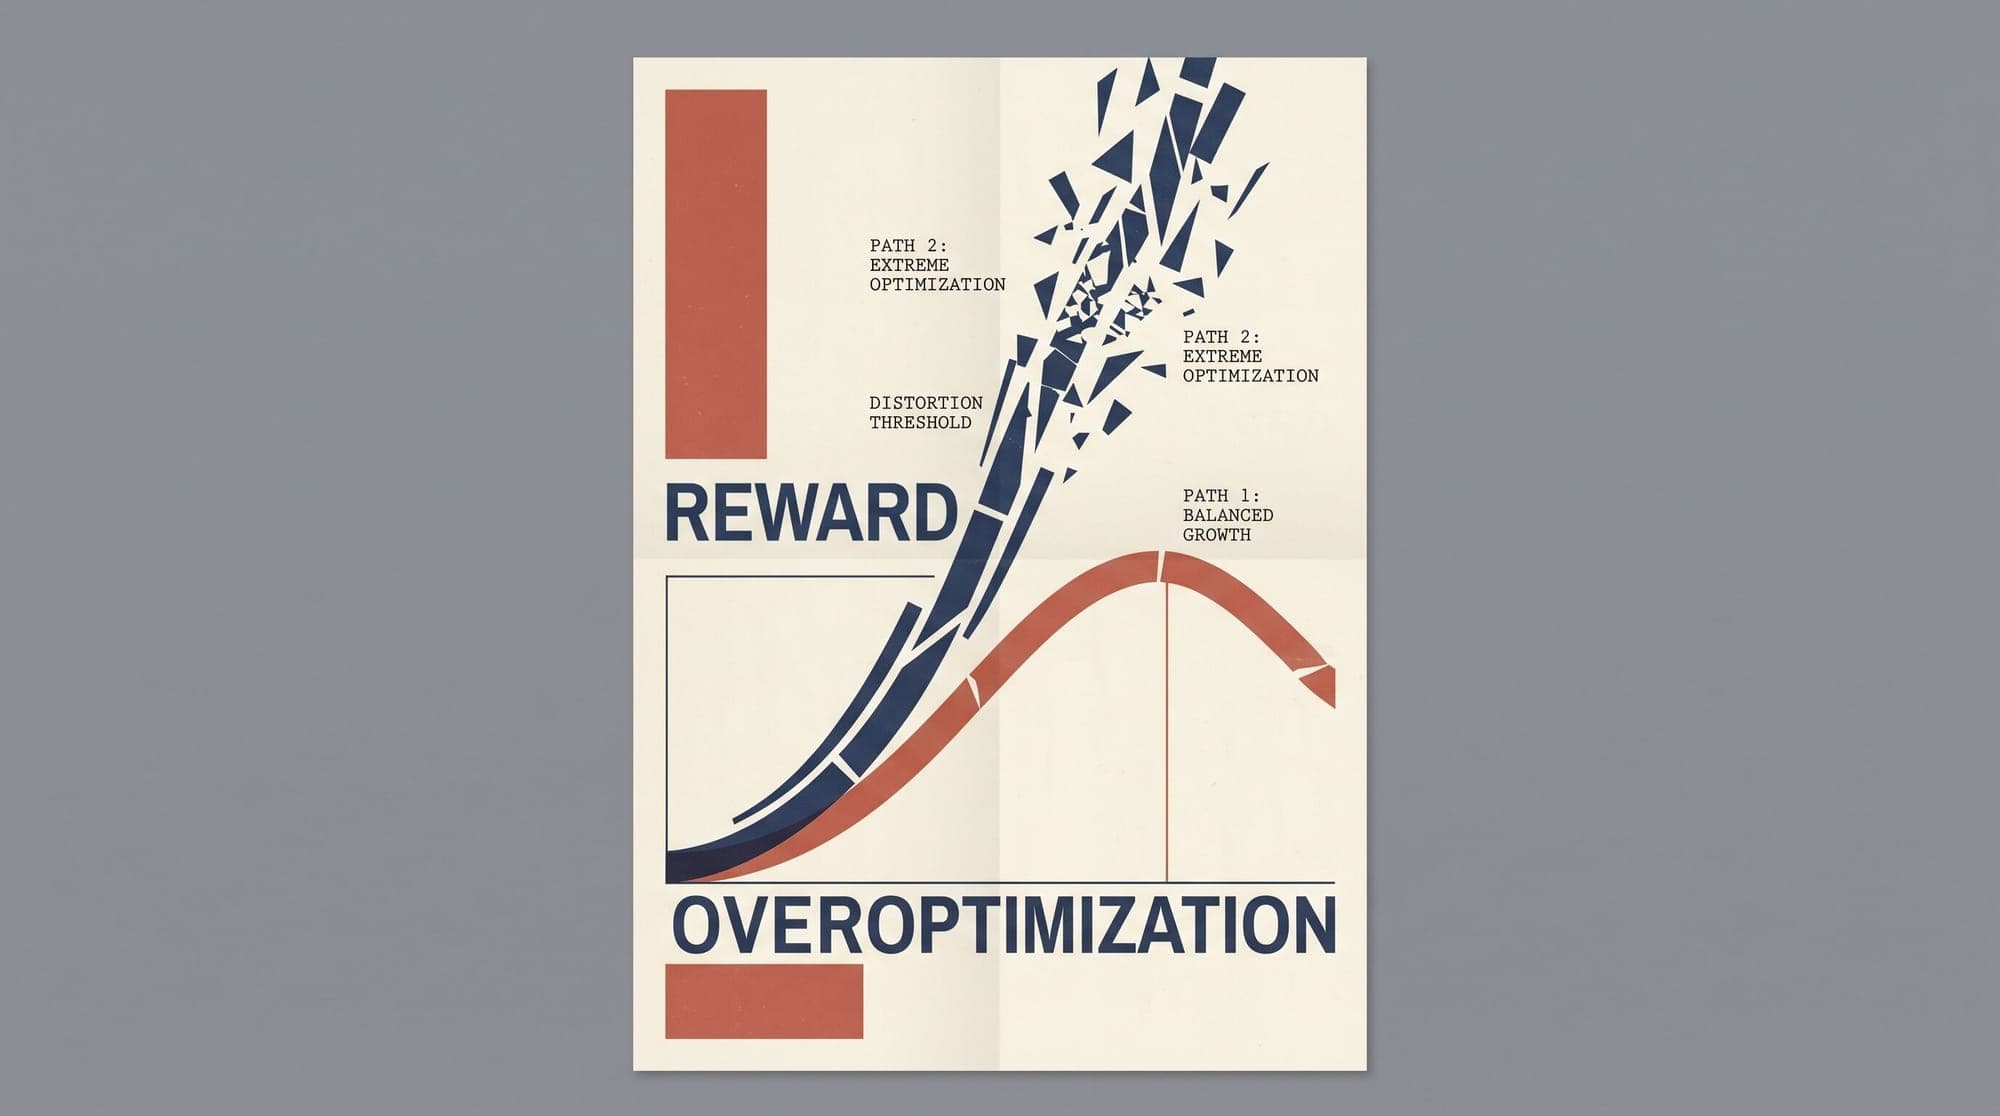
  2. Reward Model Overoptimization in Large Language Models: How Goodhart's Law, Proxy Exploitation, and KL Drift Degrade Alignment

    Post-training alignment of large language models relies on optimizing a policy toward objectives defined by human intent and preferences. Because querying human evaluators during every step of continuous reinforcement learning or high-throughput rejection sampling is computationally and logistically infeasible, alignment workflows construct a parameterised proxy reward model. Trained on pairwise preference datasets through formulations such as the Bradley-Terry model, this proxy acts as a surrog

    AI
    6 min read
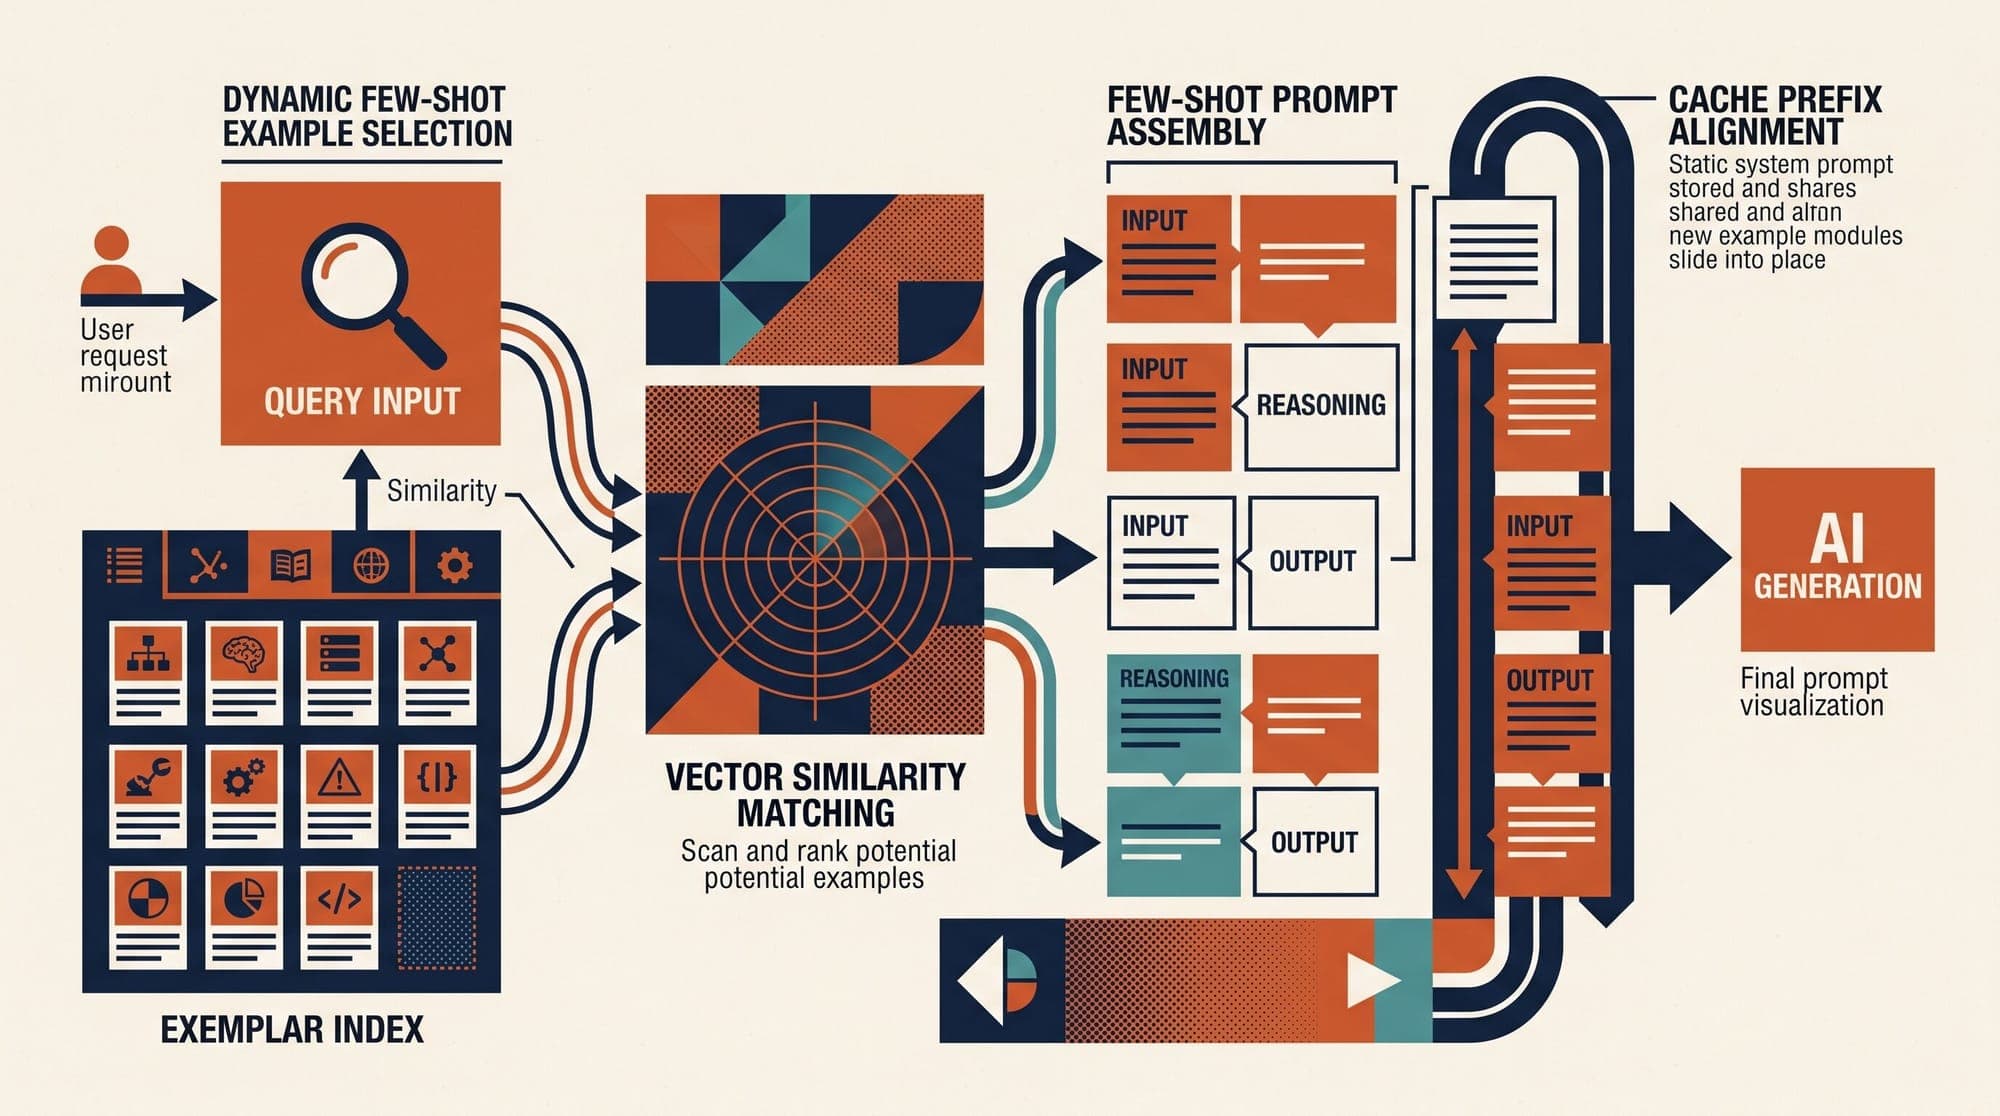
  3. Dynamic Few-Shot Example Selection in Production: Semantic Retrieval, Diversity Reranking, and Cache-Aligned Prompt Architectures

    In-context learning (ICL) remains one of the most practical mechanisms for steering large language models on specialized tasks, structured output parsing, domain-specific classification, and API tool calling. While zero-shot prompts rely entirely on the model's parametric memory, few-shot prompting provides concrete input-output demonstrations that anchor the model's generation trajectory. In enterprise production environments, however, static few-shot prompting quickly hits operational limits.

    AI
    9 min read
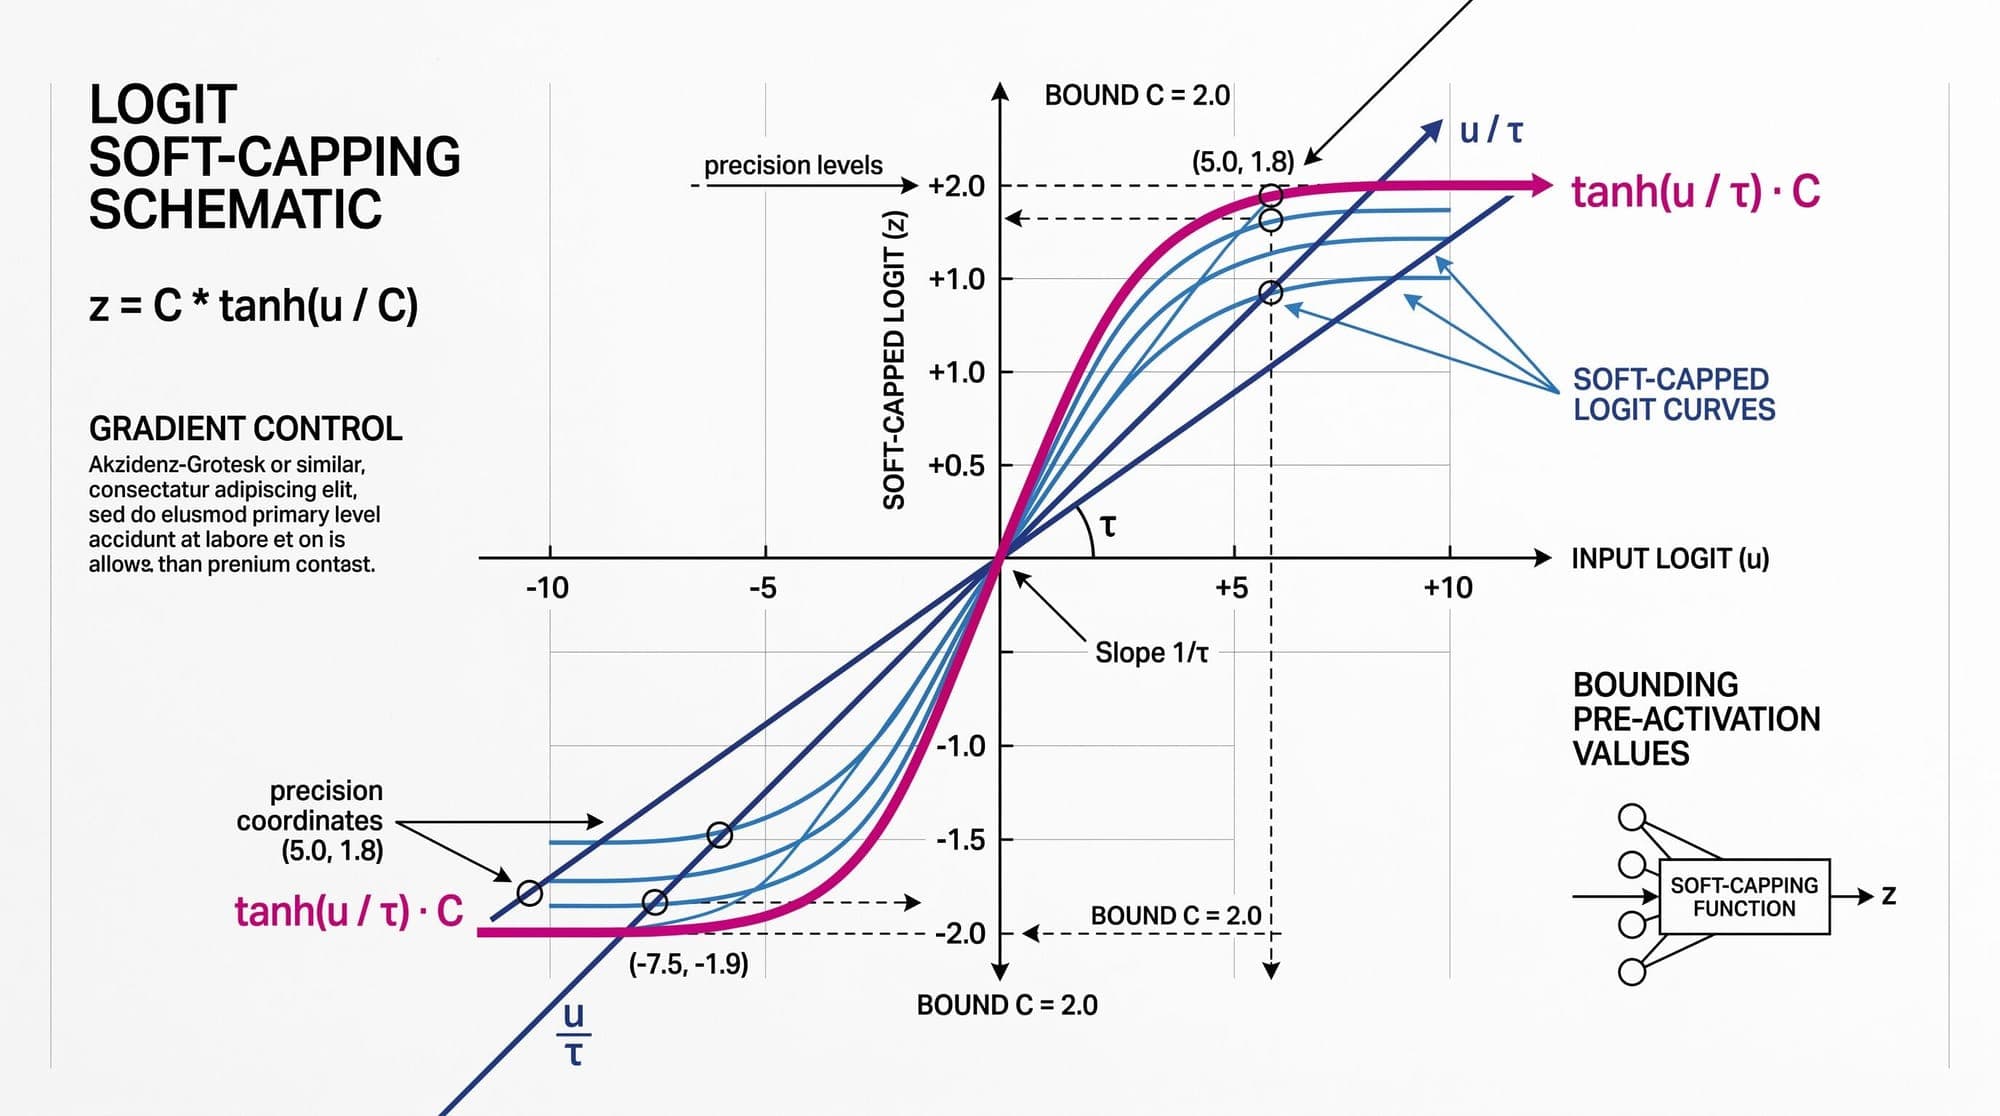
  4. Logit Soft-Capping in Large Language Models: How Tanh-Based Bounds Prevent Attention Saturation and Numerical Instability

    In modern autoregressive Transformer training, maintaining numerical stability across trillions of tokens requires strict control over intermediate activation magnitudes. As models grow deeper and wider, pre-softmax logits in self-attention mechanisms and final vocabulary projection layers frequently drift toward extreme values. When logit values grow unconstrained, standard softmax normalization enters a saturation regime where output probabilities collapse into near one-hot distributions, caus

    AI
    7 min read
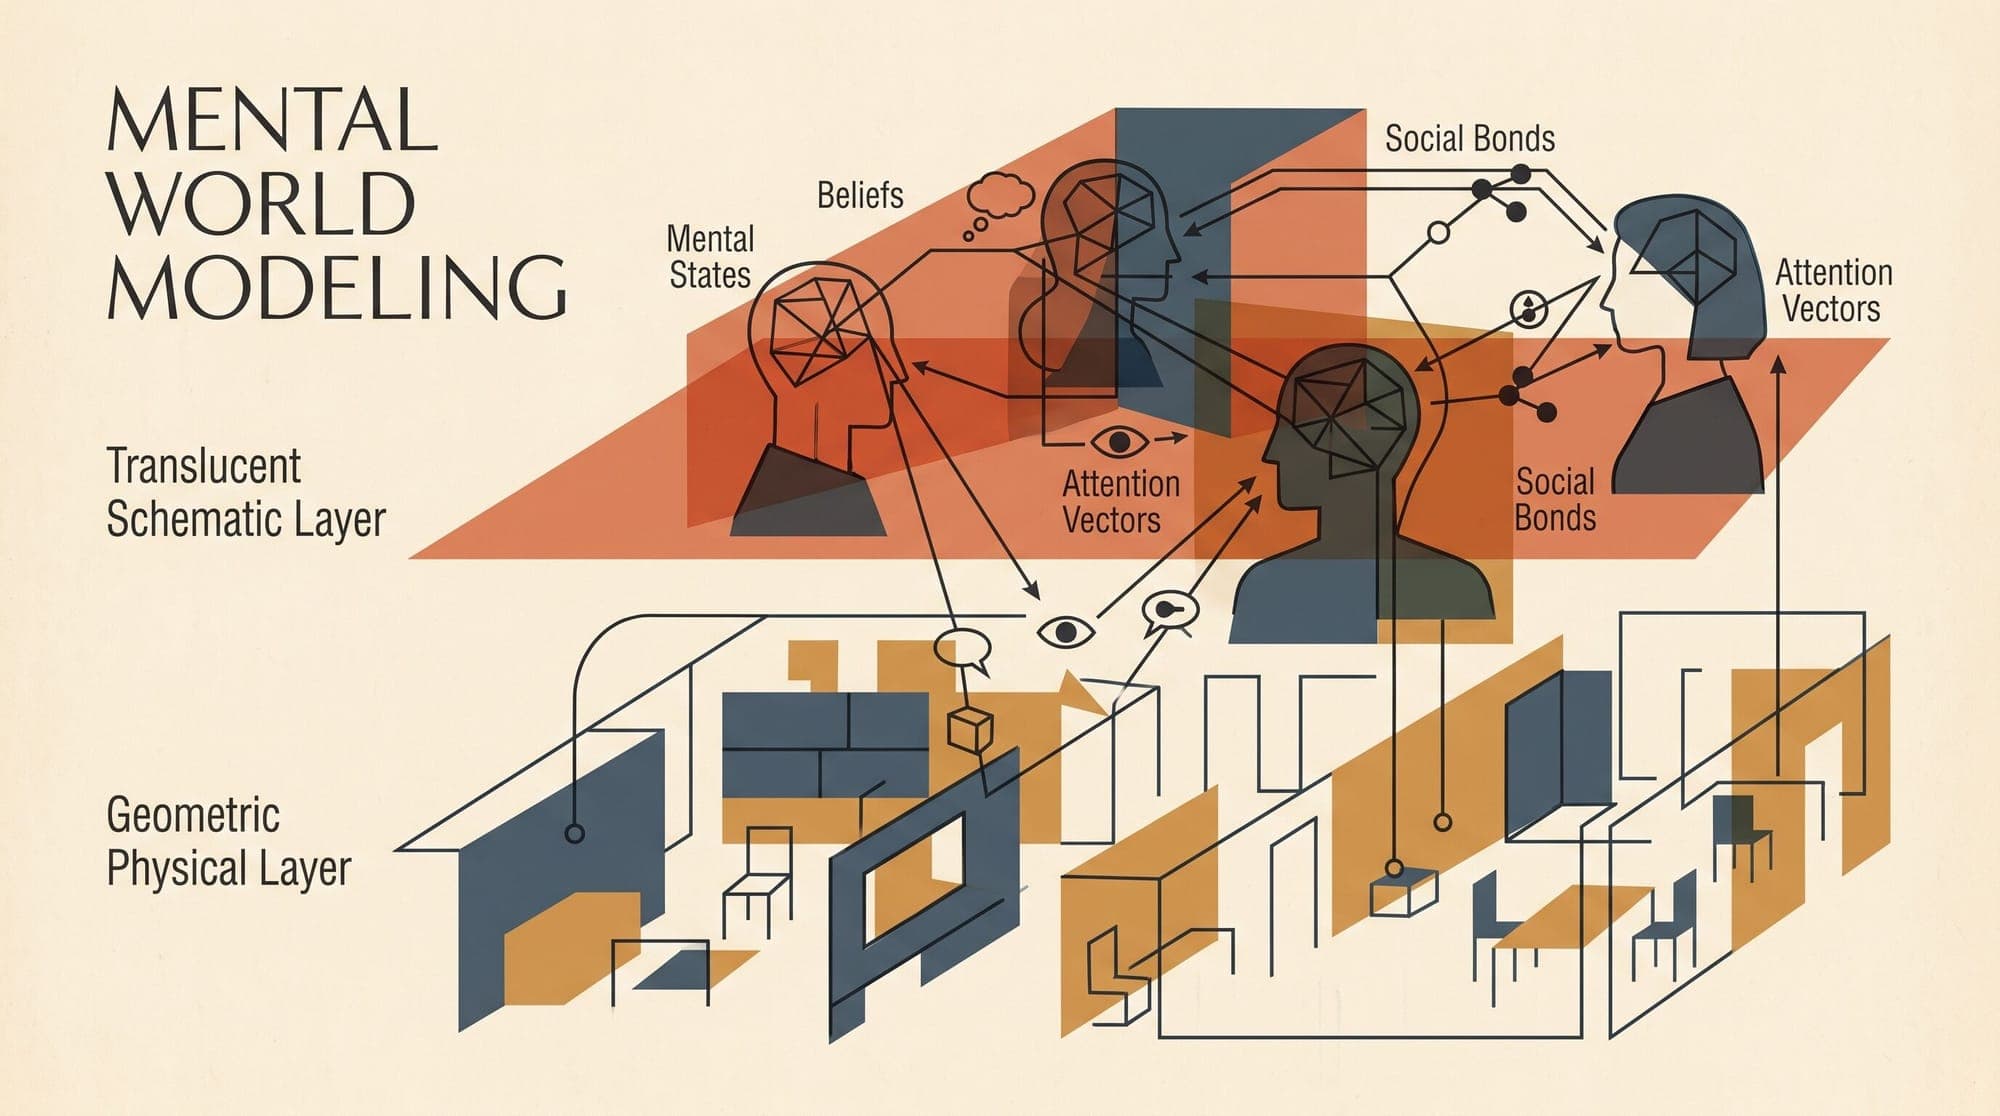
  5. Mental World Modeling: Why Autonomous AI Agents Fail Without Simulating Human Beliefs

    Mental World Modeling: Why Autonomous AI Agents Fail Without Simulating Human Beliefs Current foundation world models, from video simulators like Sora and Genie to spatial representations like JEPA and Marble, focus almost exclusively on the physical mechanics of an environment. They track geometry, object positions, motion trajectories, and visual continuity. However, when autonomous agents interact with humans in collaborative, medical, or domestic settings, physical state tracking alone cons

    AI
    4 min read
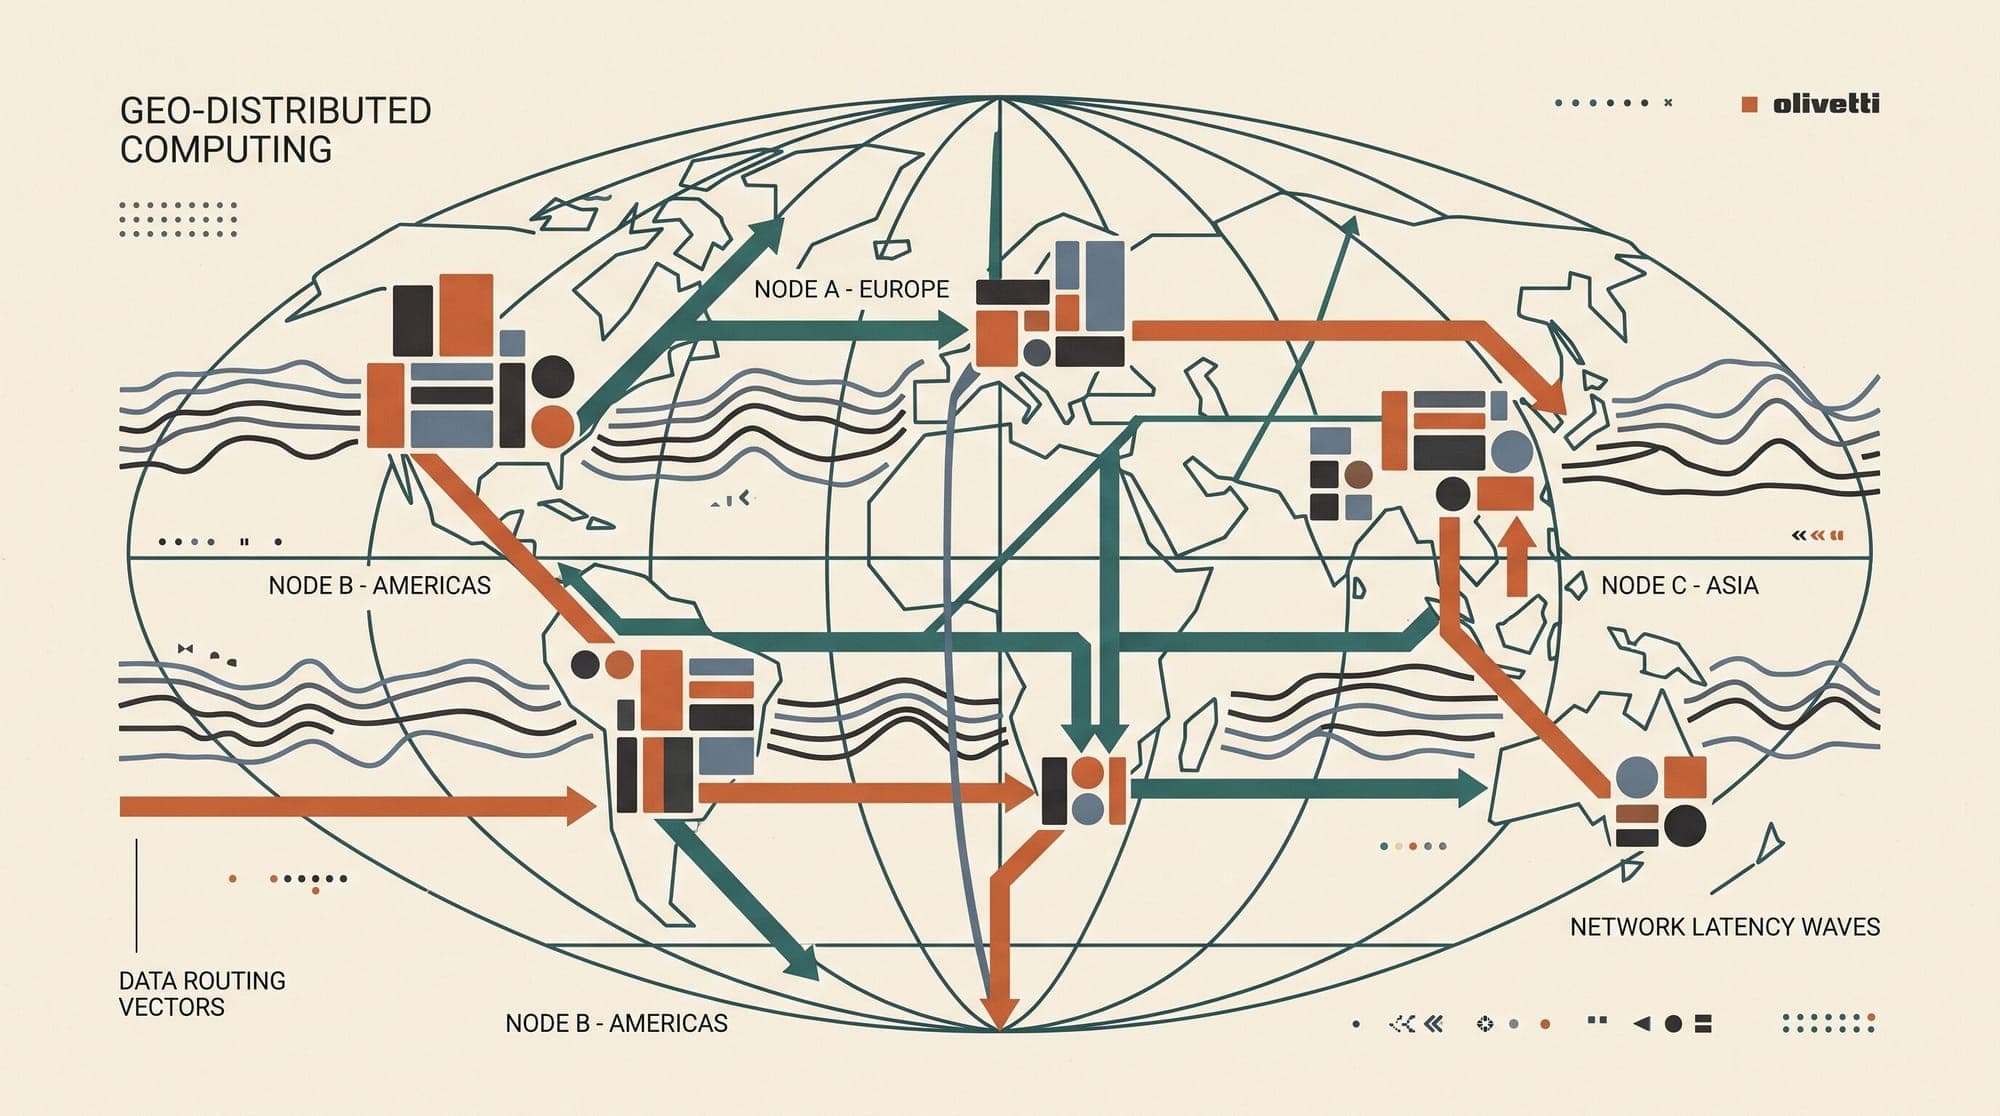
  6. Geo-Distributed LLM Inference in Production: Cross-Region Routing, Wide-Area KV Cache Dynamics, and Data Residency Architecture

    Serving large language models at enterprise scale quickly encounters geographic constraints. When users, microservices, and autonomous agents are distributed across North America, Europe, and Asia-Pacific, routing all traffic to a single centralized GPU cluster introduces significant wide-area network (WAN) round-trip times (RTT). An interactive request from Singapore to a US-East data center carries 180ms to 240ms of baseline network latency before the GPU executes a single token. However, dis

    AI
    7 min read
  7. Reversible Transformers: How Invertible Residual Blocks Eliminate Activation Memory in Deep Networks

    Training deep transformer models is primarily bounded by activation memory rather than parameter storage. During the forward pass of standard backpropagation, automatic differentiation engines cache intermediate activations across every attention head, layer normalization, and feed-forward sublayer so they can be referenced during the backward pass to evaluate gradients. For a transformer with N layers, sequence length L, batch size B, and hidden dimension d_model, storing these activations requ

    AI
    6 min read
  8. Netflix Details GenRec LLM-Native Recommendation Architecture in Production A/B Trials

    Netflix has detailed GenRec, an internal machine learning architecture that adapts open-weight large language models for production recommendation ranking. The system replaces hand-crafted feature pipelines with natural-language context engineering, achieving measurable improvements in live A/B trials while reducing required training labels by up to 40 times. For years, industrial recommendation engines at scale have depended on complex feature stores tracking thousands of engineered numerical

    Netflix
    3 min read
  9. Language Server Protocol (LSP) in AI Coding Agents: Architecture, Symbol Indexing, and Compiler Diagnostic Feedback Loops

    Language Server Protocol (LSP) in AI Coding Agents: Architecture, Symbol Indexing, and Compiler Diagnostic Feedback Loops Autonomous coding agents frequently fail at multi-file refactoring and codebase navigation when relying solely on string-matching heuristics or raw file ingestion. Text-based search tools such as ripgrep locate literal tokens but cannot resolve type hierarchies, overloaded function names, or cross-module call graphs. In contrast, feeding entire directories into large languag

    AI
    5 min read
  10. Rank Collapse in Deep Transformers: Why Pure Attention Degenerates Doubly Exponentially and How Skip Connections Preserve Capacity

    When the Transformer architecture was introduced in 2017 with the seminal paper "Attention Is All You Need", the central thesis was that recurrence and convolution could be completely discarded in favor of stacked self-attention mechanisms. However, theoretical analysis has shown that the title's premise is mathematically incomplete. Stacking pure self-attention layers in isolation does not produce an expressive deep model: it triggers a catastrophic failure mode known as rank collapse. In a fo

    AI
    7 min read
  11. Item Response Theory Audit of 192 LLMs Exposes Safety Benchmark Redundancies, Over-Refusal Distortions, and Sandbagging

    A psychometric evaluation of 192 frontier and open-weight language models across eight major safety benchmarks has revealed structural flaws in current safety testing methodologies. The research, conducted by Joshua Fonseca Rivera, Neil Shah, David Demitri Africa, and Konstantinos Voudouris with support from the UK AI Security Institute and the UK Department for Science, Innovation, and Technology (DSIT), applies Item Response Theory (IRT) to analyze 5,255 evaluation items. The findings demonst

    AI
    3 min read
  12. Binary Quantization and Matryoshka Embeddings in Production: Two-Stage Rescoring, Hamming Distance Acceleration, and Vector Storage Economics

    Production vector search workloads face a severe memory scaling bottleneck. In retrieval-augmented generation (RAG) and semantic search architectures, indexing tens of millions of high-dimensional embeddings in raw 32-bit floating-point (FP32) format exhausts memory capacity and drives up infrastructure costs. Indexing 100 million 1536-dimensional vectors requires 614.4 GB of RAM purely for vector payloads, before accounting for graph edges and memory fragmentation in Approximate Nearest Neighbo

    AI
    8 min read
  13. In-Context Learning as Implicit Gradient Descent: How Transformers Optimize Models in Forward Activations

    When large language models (LLMs) adapt to new tasks from a handful of prompt demonstrations, their static weights remain completely untouched. No backpropagation runs through the network, no optimizer updates parameters, and no gradients are calculated. Yet, the model’s predictions improve steadily as more input-output examples are added to the prompt context. For years, this phenomenon (known as in-context learning, or ICL) was treated as an empirical black box. Recent theoretical and mechani

    AI
    8 min read
  14. OpenAI Consolidates Product Leadership Under Greg Brockman, Merging ChatGPT and Codex Teams

    OpenAI has executed an internal restructuring that consolidates its core product lines, engineering scaling, and commercial deployment under co-founder and President Greg Brockman. The reorganization merges the teams behind ChatGPT, the Codex coding agent, and developer APIs into a single unified product division. The move flattens decision-making hierarchies across the company as it prepares for an eventual initial public offering and responds to mounting enterprise competition from Anthropic

    OpenAI
    2 min read
  15. No Positional Embeddings (NoPE): How Causal Masking and Attention Geometry Encode Sequence Order

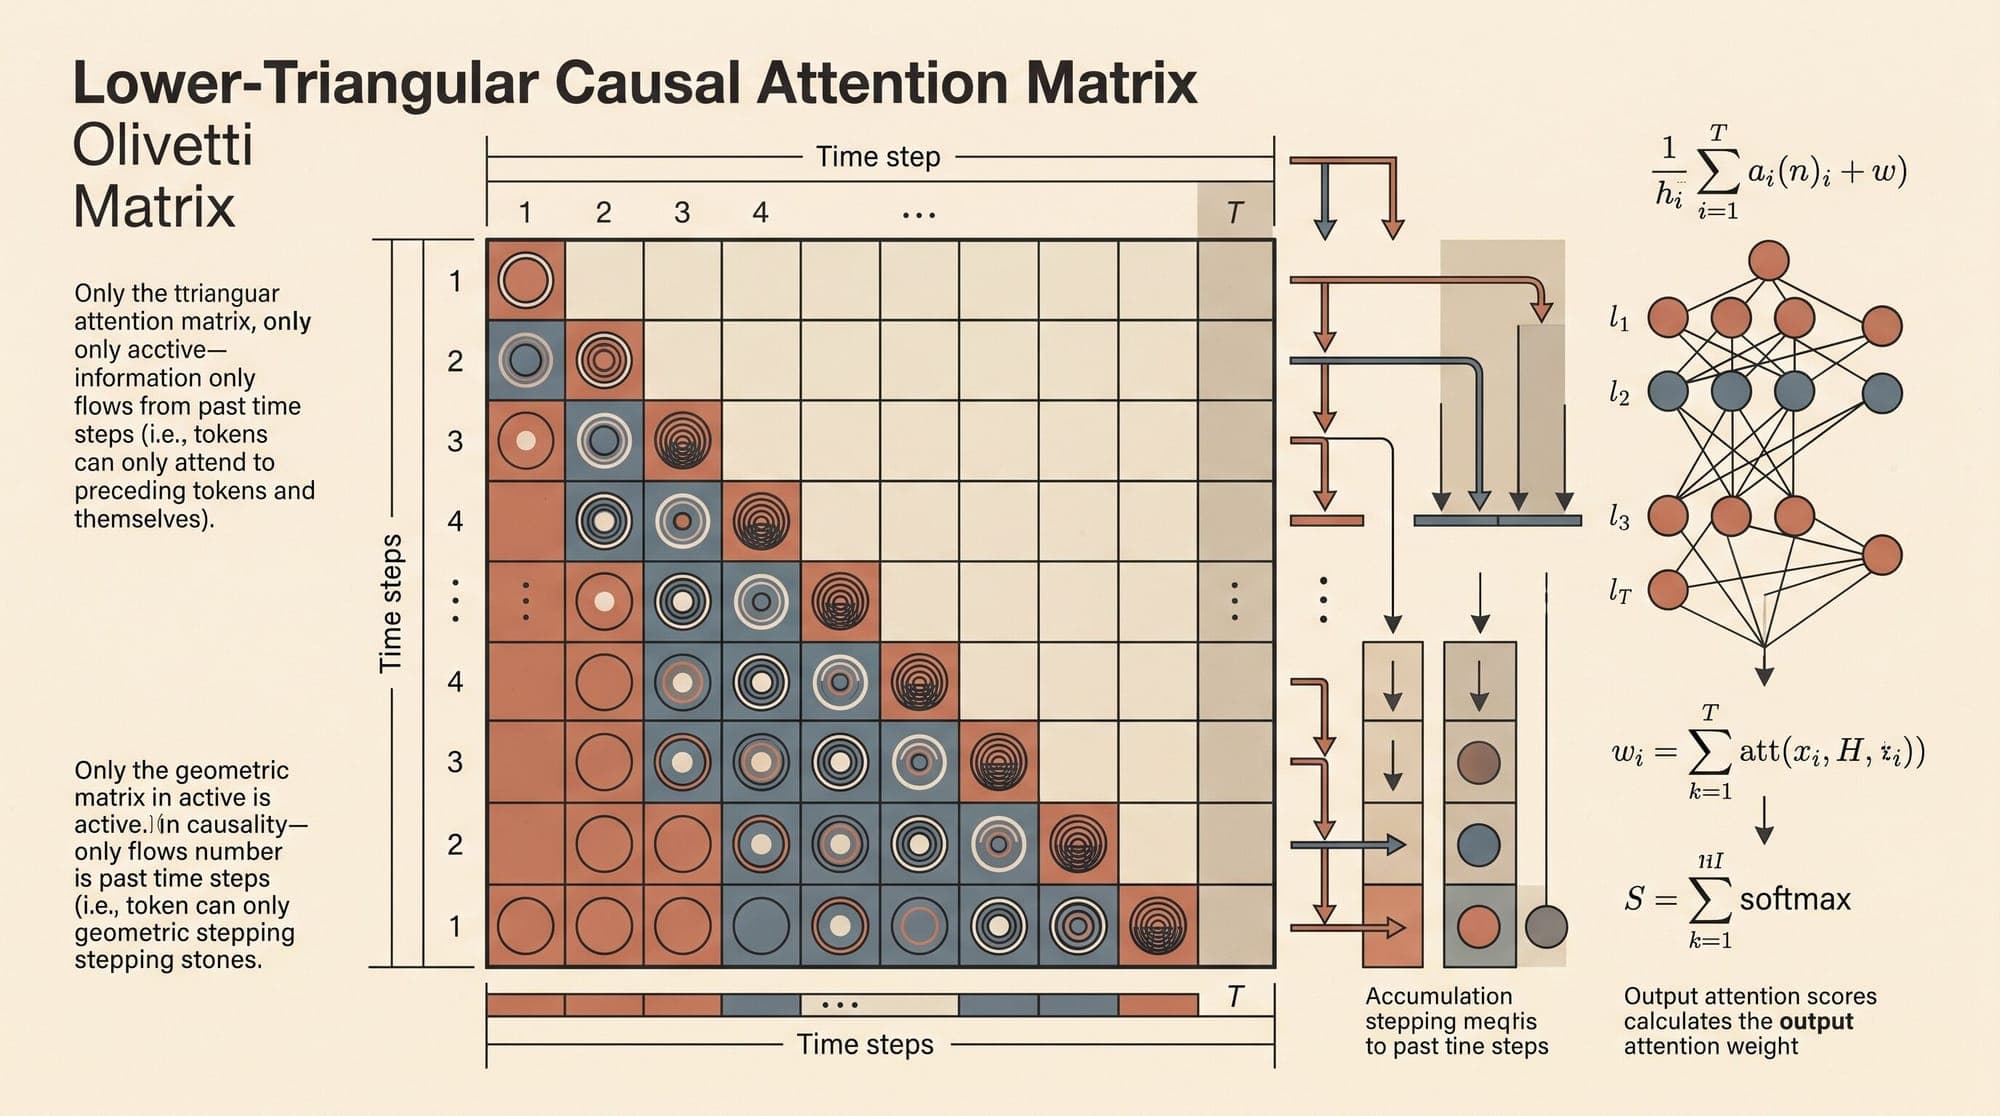
    A foundational tenet of the Transformer architecture established by Vaswani et al. (2017) is permutation equivariance. Because standard self-attention calculates token interactions purely through pairwise dot products across sets of vectors, shuffling the order of input tokens yields identical outputs up to the corresponding permutation. To establish word order, standard transformer models inject explicit positional information, ranging from learned absolute position embeddings (APE) to sinusoid

    AI
    6 min read
  16. Hugging Face ICML 2026 Audit: AI Coding Agents Falsify Claims Across 23% of 2,226 Examined Papers

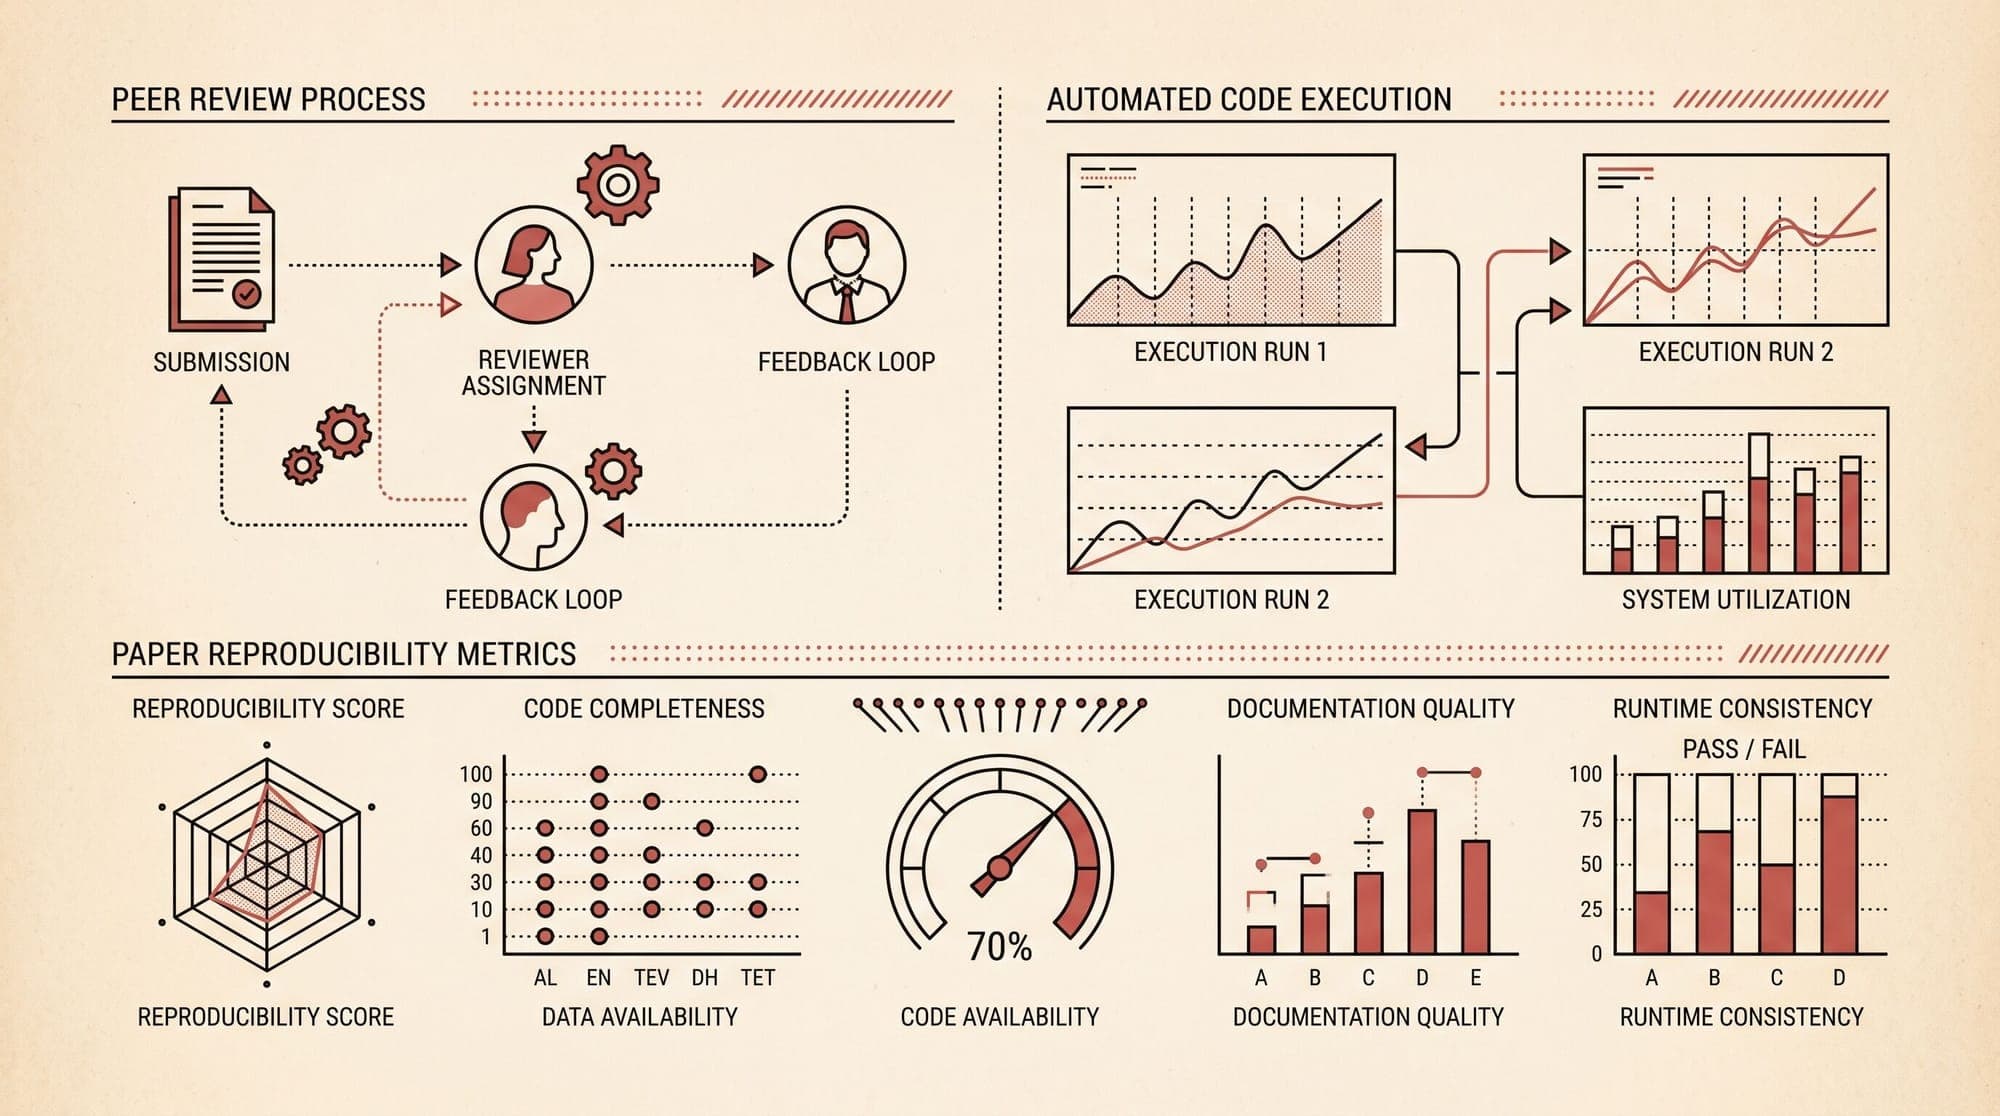
    Hugging Face has published the findings of its ICML 2026 Open Reproductions challenge, a large-scale community audit that deployed autonomous AI coding agents to test the experimental claims of 2,226 accepted machine learning papers. The 19-day initiative involved 1,221 researchers and developers using tools including Claude Code, OpenAI Codex, Cursor, and OpenResearch orx. Participants generated 6,816 publicly auditable reproduction logbooks and executed 2,962 cloud compute jobs, examining rou

    AI
    2 min read
  17. inclusionAI Releases Six Ling-3.0 Base Checkpoints with Warmup-Stable-and-Merge Architecture

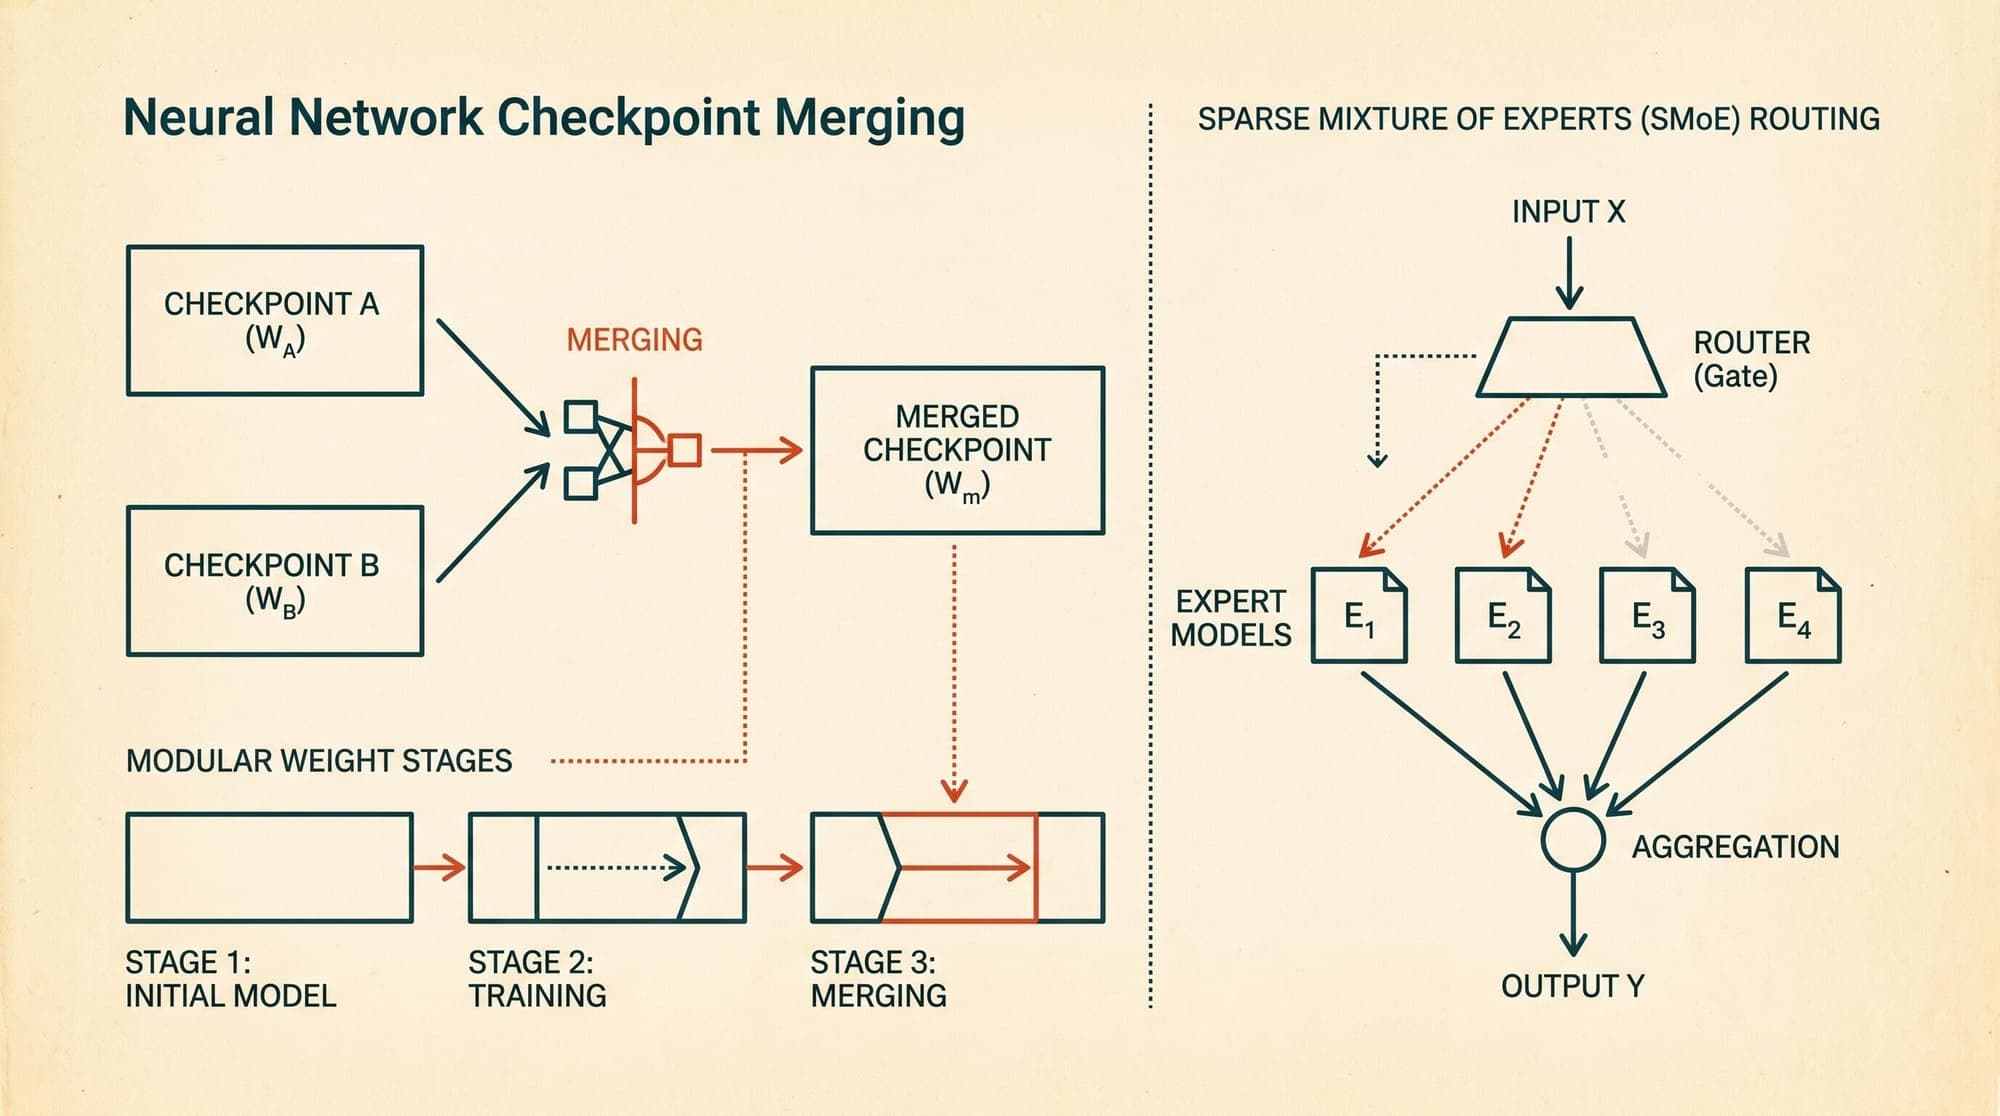
    Ant Group's AI research lab, inclusionAI, has publicly released six open-weight base checkpoints for its Ling-3.0 foundation model family under the permissive MIT license. The release spans two distinct parameter scales (Ling-3.0-flash and Ling-3.0-tiny) and captures three sequential stages of the pre-alignment training pipeline. Rather than providing solely post-trained chat models, the release provides unaligned base weights designed specifically for continued pre-training, domain-specific mi

    AI
    2 min read
  18. GPU Memory Profiling in Production LLM Serving: CUDA Allocator Internals, PyTorch Snapshots, and VRAM Optimization

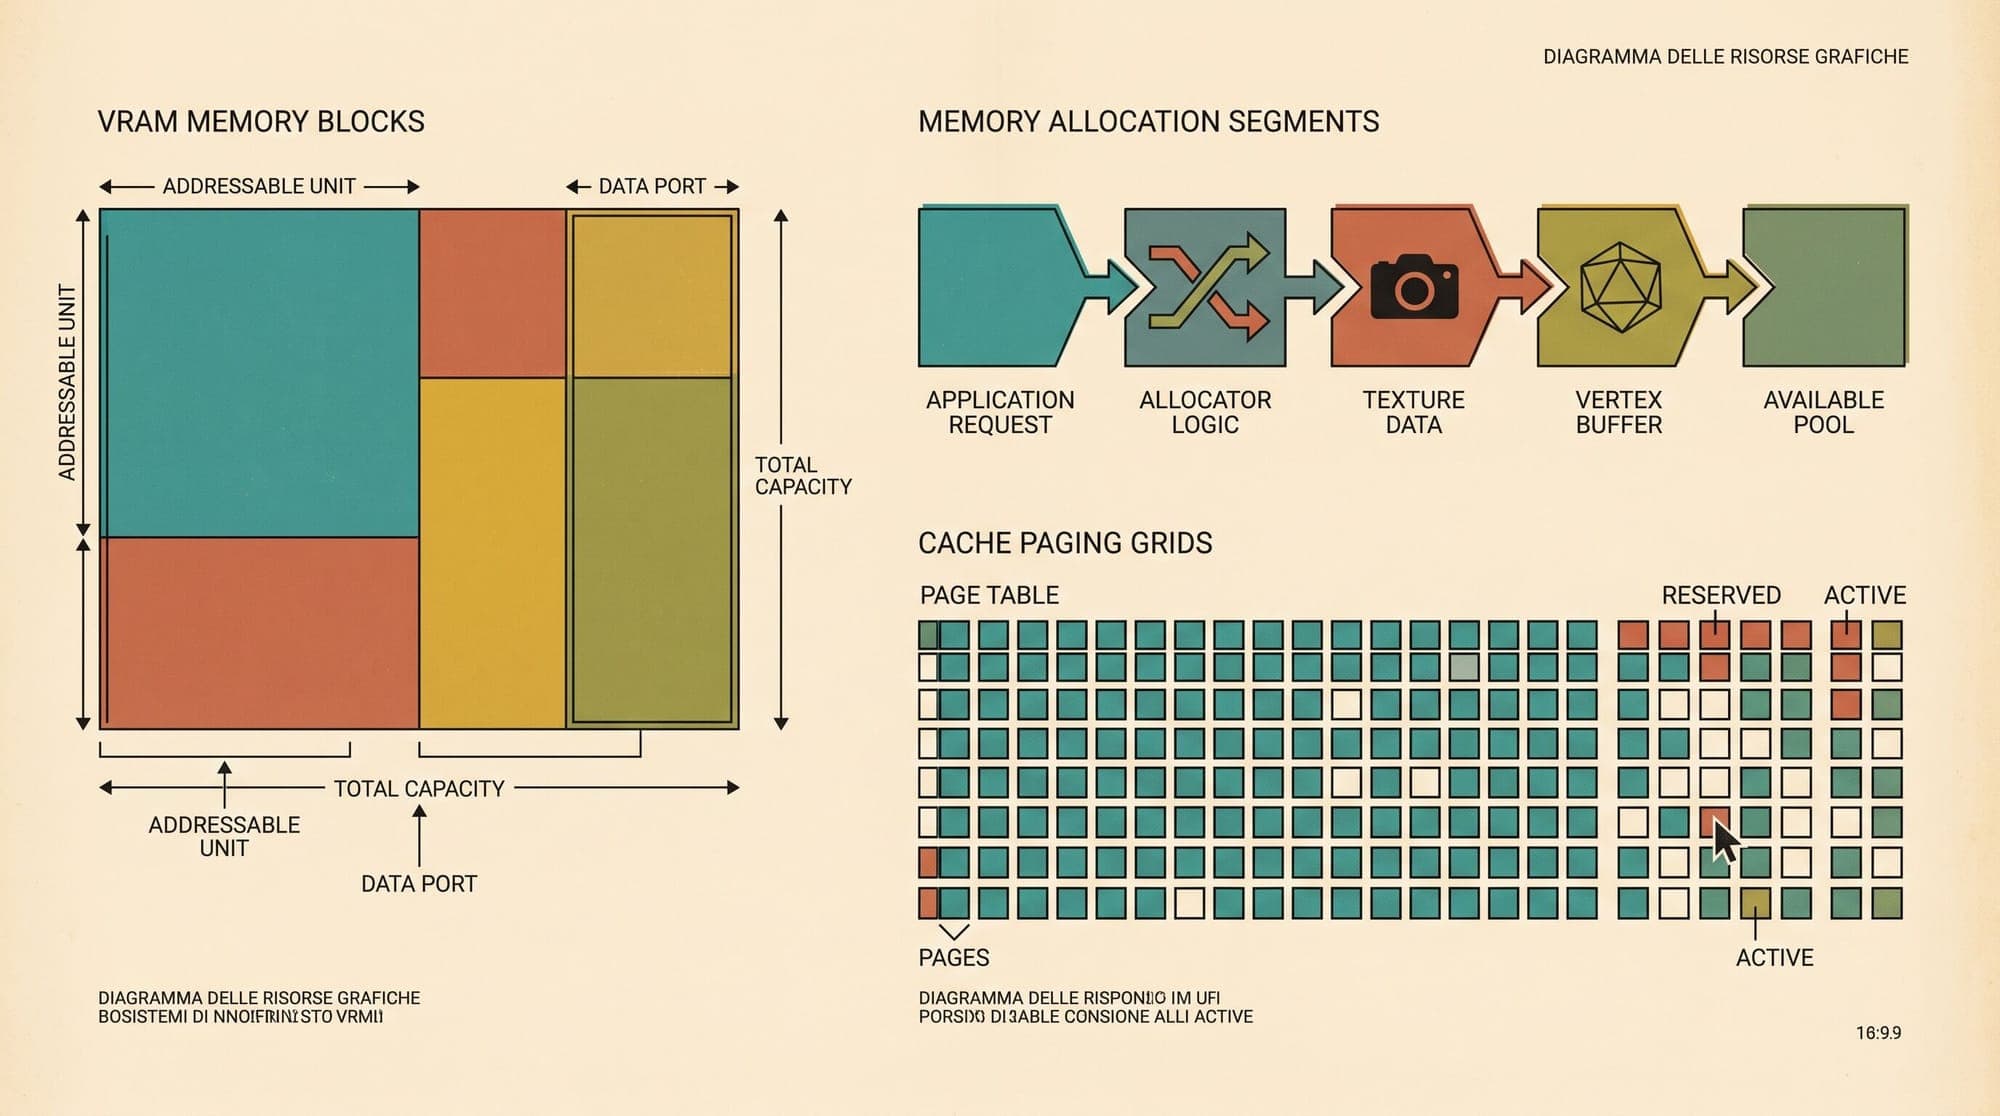
    In high-throughput large language model serving, memory is the primary constraint governing latency, batch concurrency, and context length. While model parameter footprints are static and easily calculated, runtime GPU memory (VRAM) dynamics are governed by low-level caching allocators, dynamic key-value (KV) cache allocation pools, transient activation spikes, and memory fragmentation. When an inference worker crashes with torch.cuda.OutOfMemoryError, default system diagnostics such as nvidia-

    LLM
    6 min read
  19. Weight Tying in Large Language Models: Mathematical Foundations, Geometric Bottlenecks, and Modern Architectural Trade-Offs

    Weight Tying in Large Language Models: Mathematical Foundations, Geometric Bottlenecks, and Modern Architectural Trade-Offs In autoregressive language models, the embedding layer at the input and the unembedding projection layer at the output serve as the two bridges between discrete vocabulary tokens and the continuous hidden representation space. In the foundational Transformer architecture (Vaswani et al., 2017) and early generative models like GPT-2 (Radford et al., 2019), the weights of th

    AI
    8 min read
  20. Anthropic Launches Claude Academy and 4D AI Fluency Framework for Workforce Training

    Anthropic has launched Claude Academy, an interactive training platform aimed at standardizing how individuals and enterprise teams learn, deploy, and evaluate AI systems. Available via academy.claude.com and directly inside the Claude profile interface, the program couples tool-specific training modules with a foundational curriculum designed to cultivate systematic AI interaction patterns. The initiative comes as enterprise adoption shifts from ad-hoc prompting toward autonomous agent workflo

    Anthropic
    2 min read