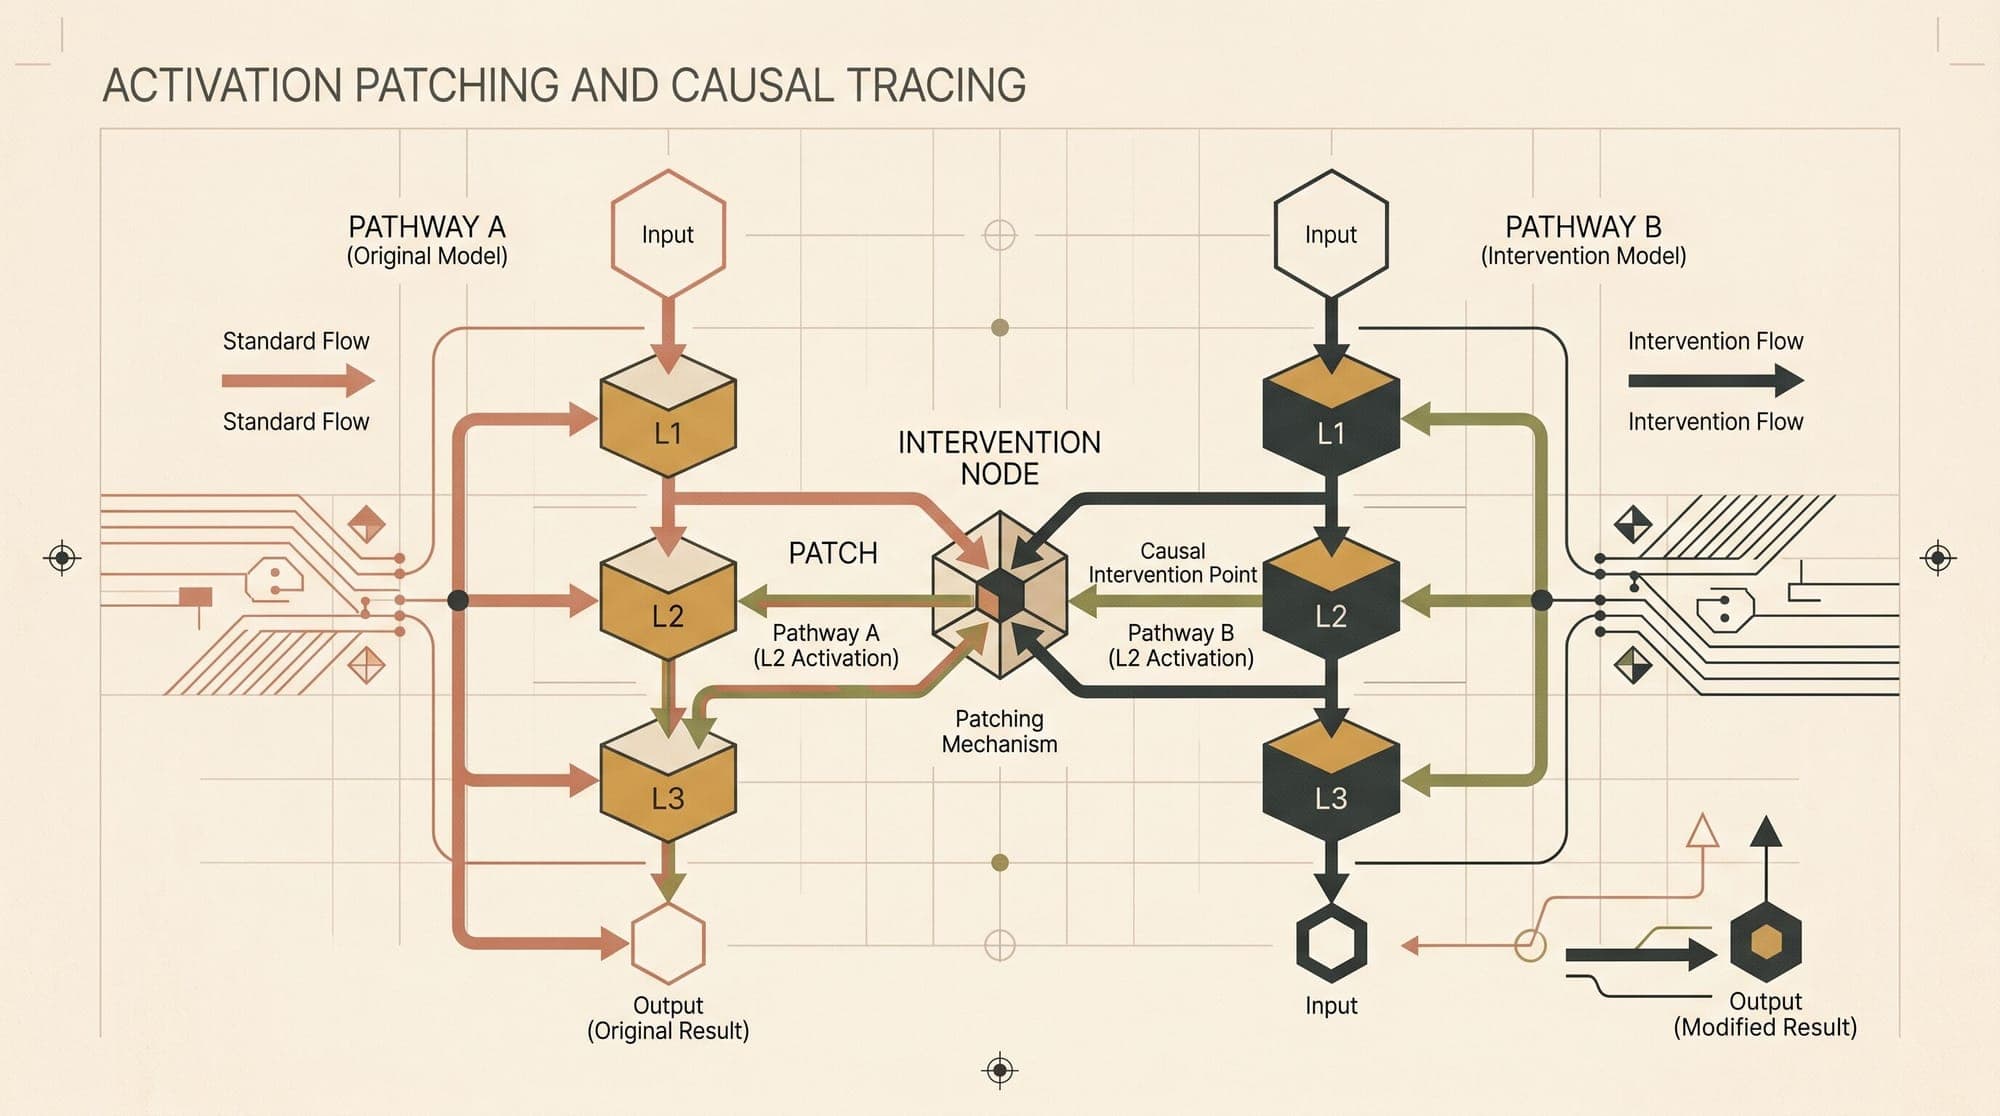
Activation Patching and Causal Tracing: Mathematical Foundations, Counterfactual Interventions, and Circuit Discovery in Large Language Models
Activation Patching and Causal Tracing: Mathematical Foundations, Counterfactual Interventions, and Circuit Discovery in Large Language Models Mechanistic interpretability aims to reverse-engineer the computational graphs implemented by trained neural networks into human-understandable algorithms. In autoregressive Transformer models, standard observational tools such as attention map visualization and linear probing often fail to distinguish between active computational paths and passive corre