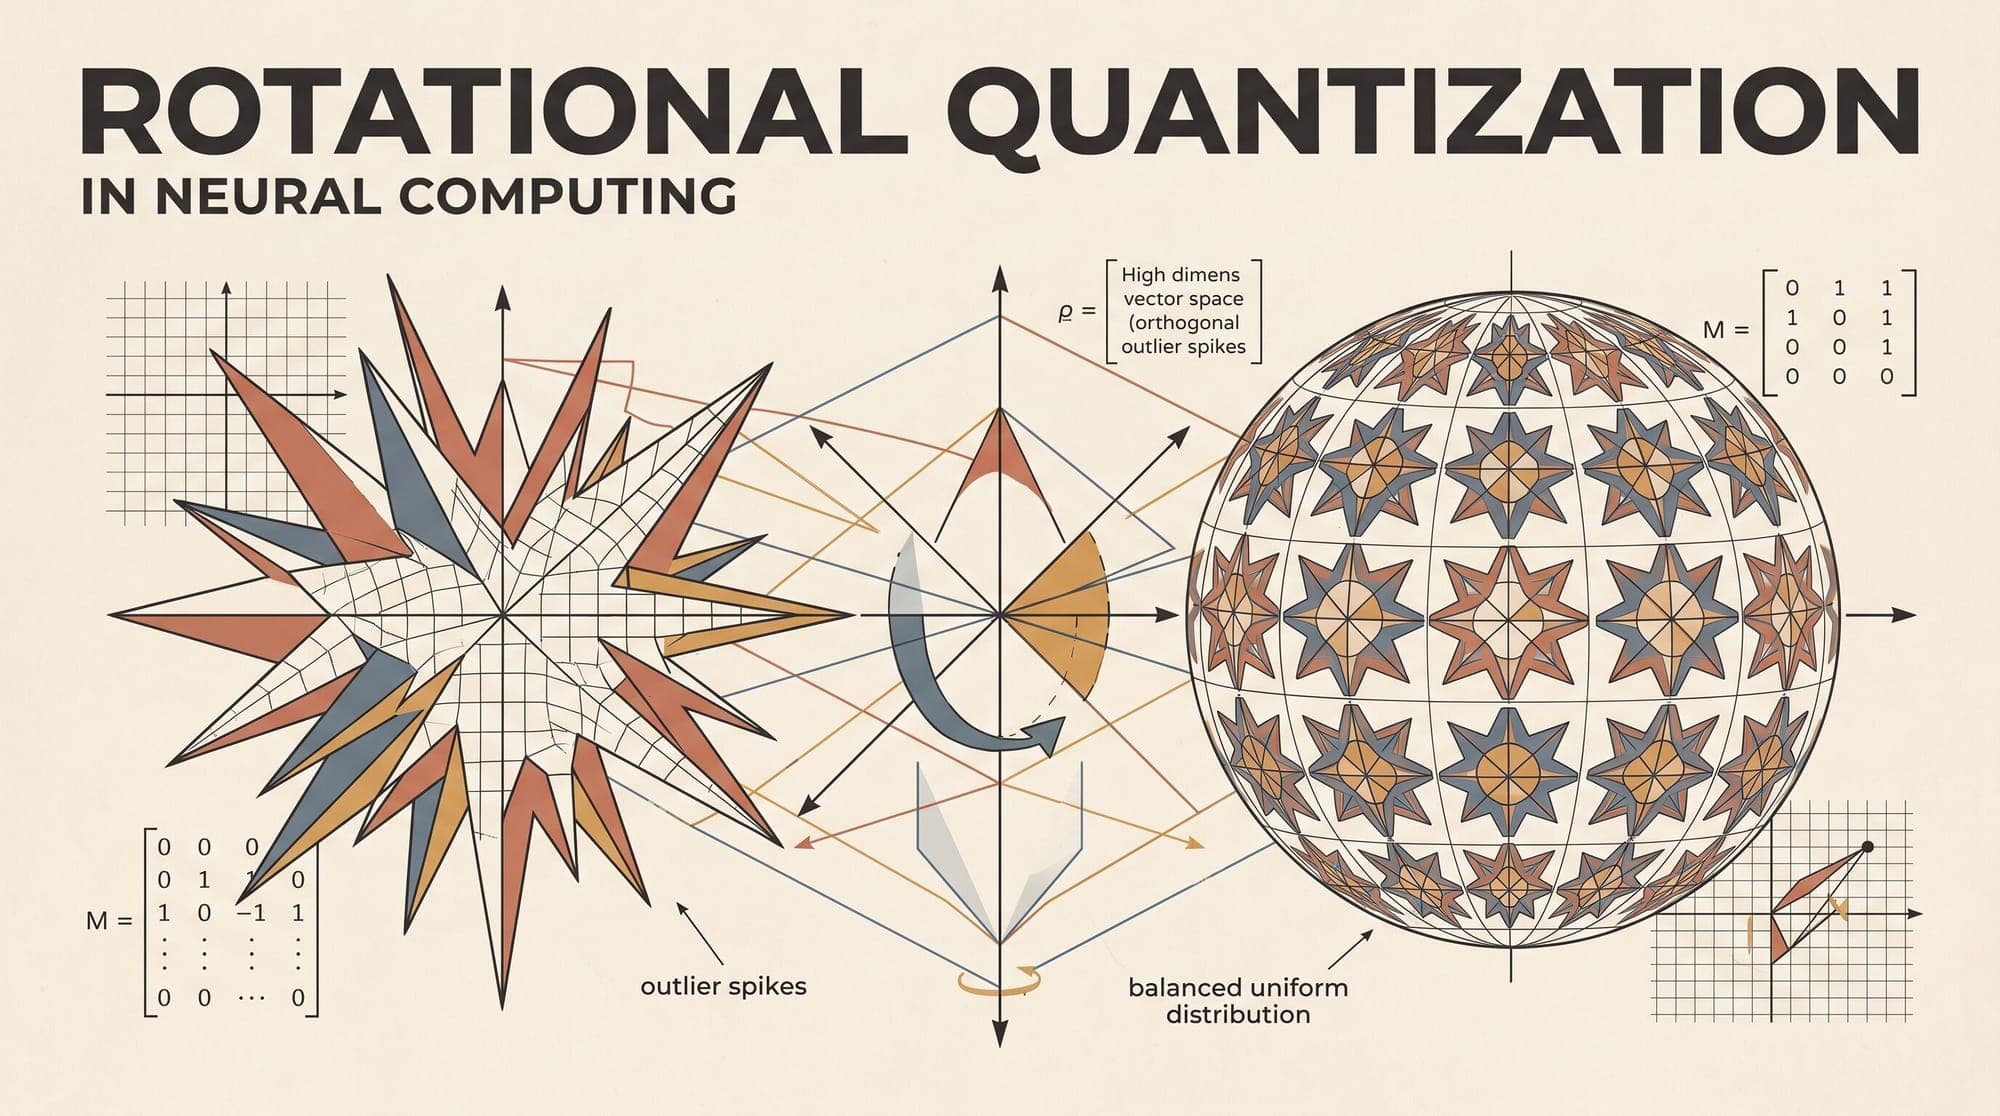
Rotational Quantization: How Orthogonal Transforms and Hadamard Incoherence Enable Outlier-Free Low-Bit Inference
Large language model serving is governed by two physical bottlenecks: memory bandwidth during autoregressive decoding and compute throughput during prompt prefill. While weight-only post-training quantization (such as GPTQ or AWQ) reduces parameter footprint to 4 bits, it leaves activations in 16-bit floating-point formats. As a result, inference engines cannot utilize high-throughput INT4 tensor cores, and the key-value (KV) cache continues to consume massive memory pools. Attempting to quanti