Subscribe
Topic

ColBERT

ColBERT is a late-interaction retrieval model that compares queries and documents token by token. Posts explain multi-vector embeddings and the MaxSim operator, and cover Sentence Transformers 6.0 adding ColBERT training support.

Articles

1-2
  1. Sentence Transformers 6.0 Adds MultiVectorEncoder for ColBERT Late-Interaction Training

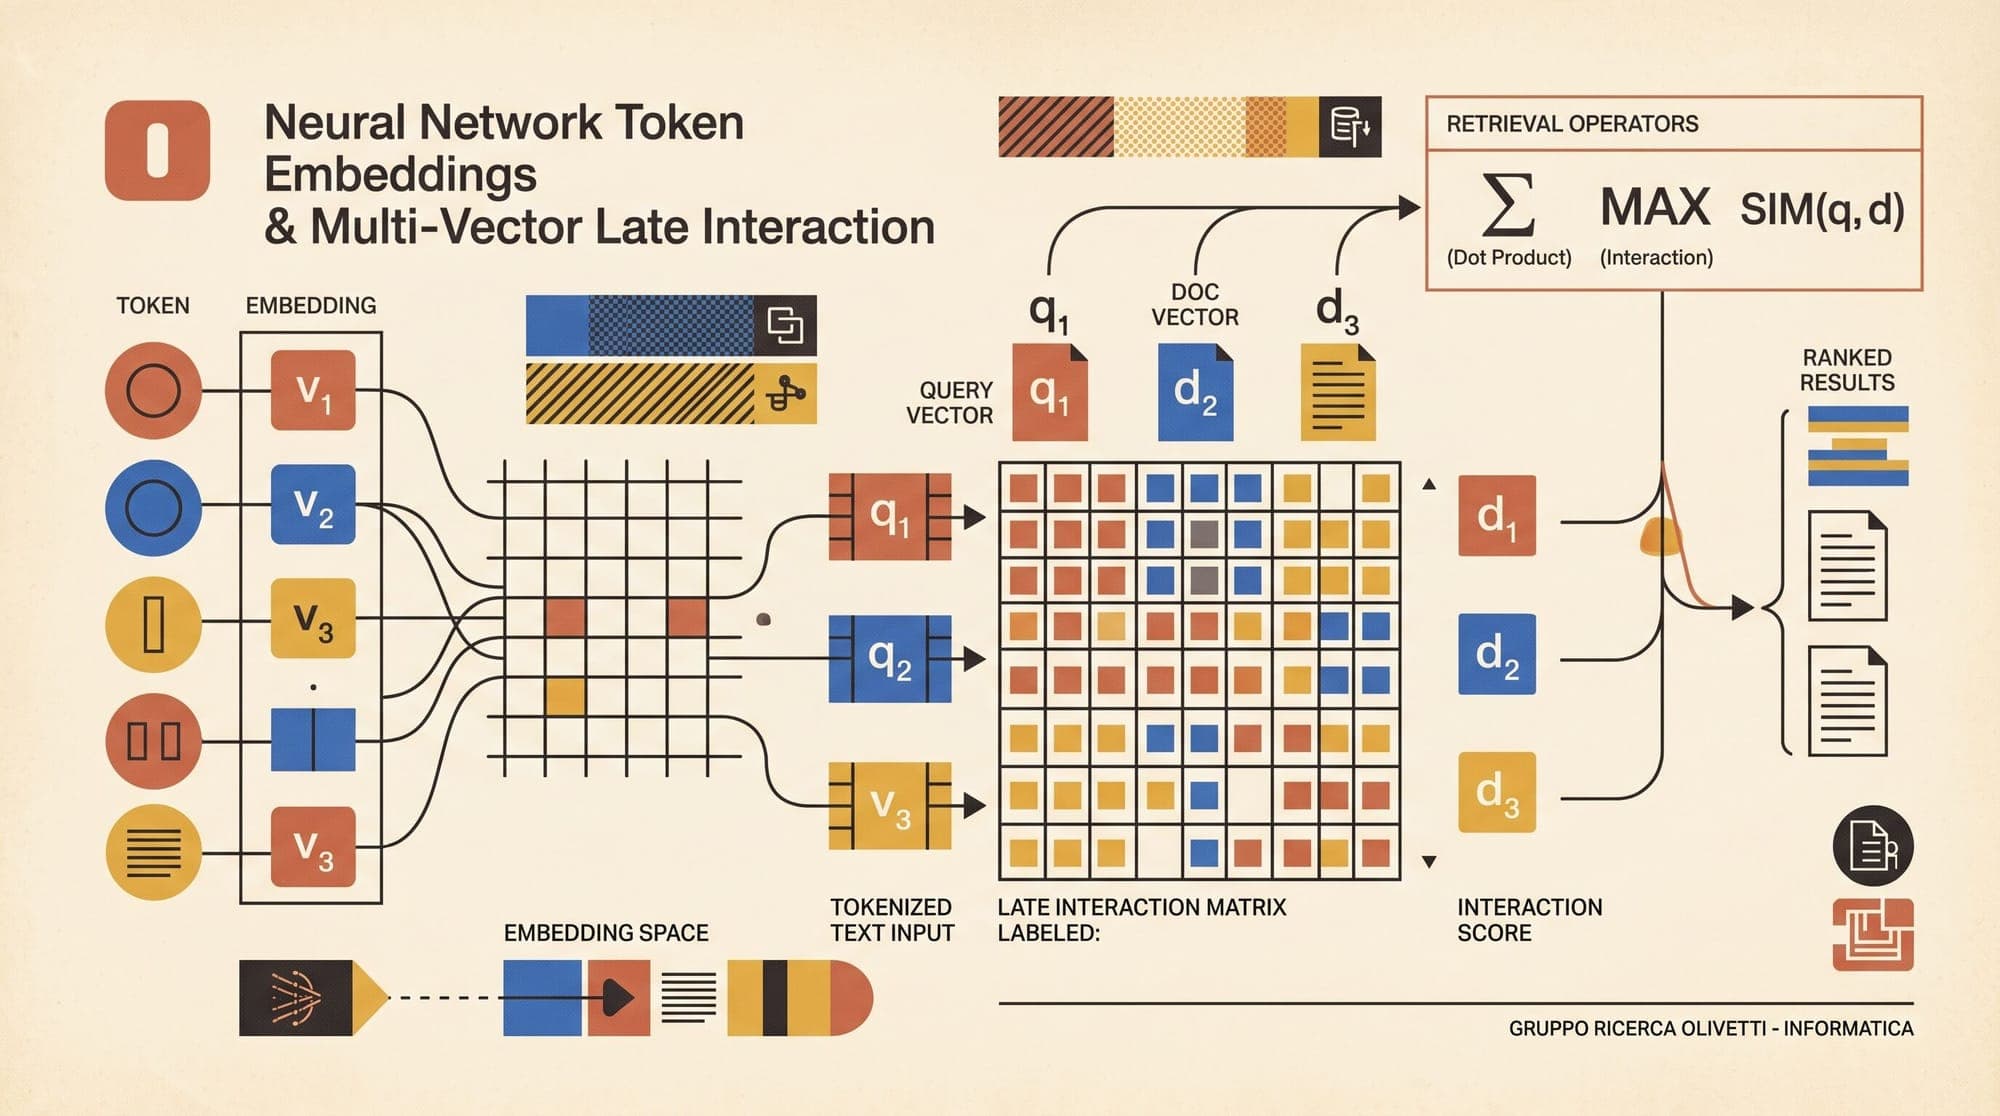
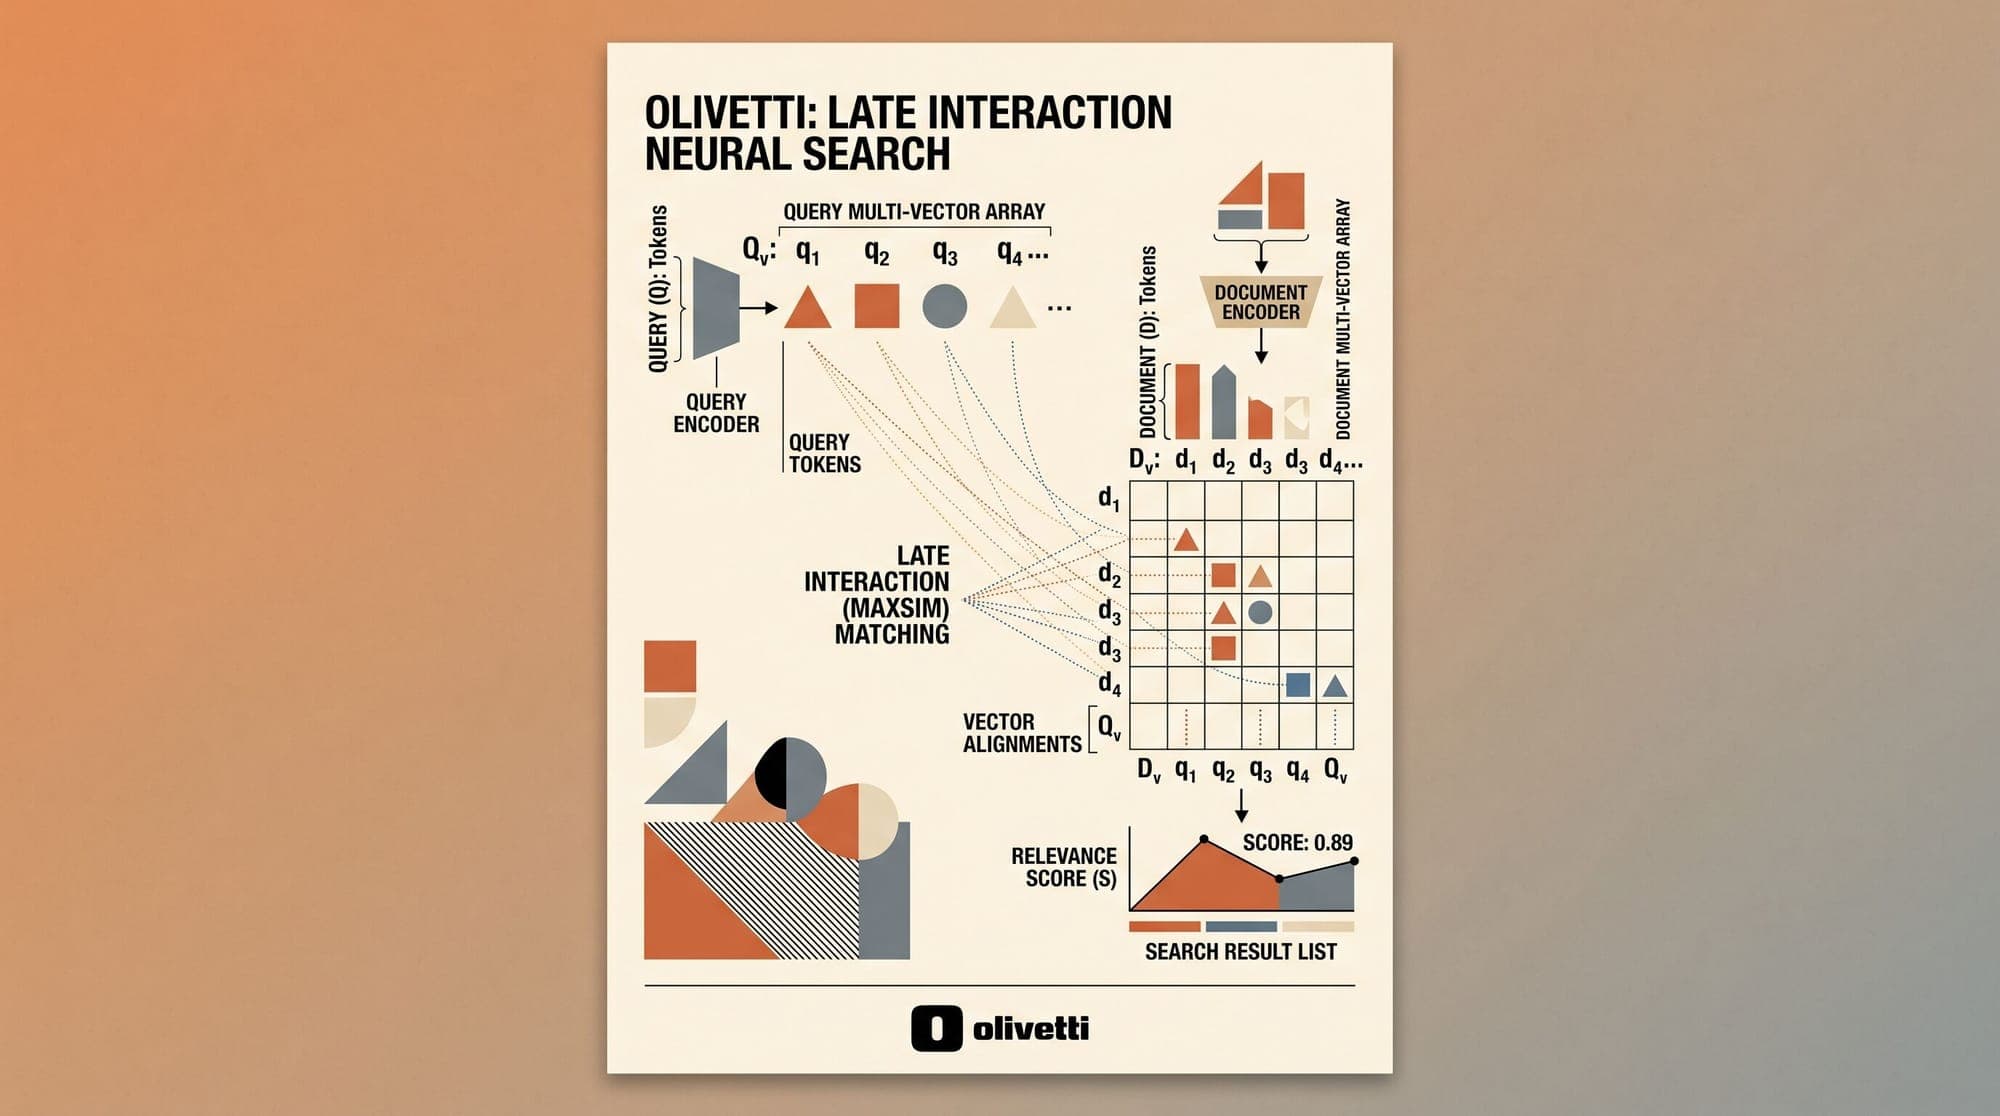
    Hugging Face has released Sentence Transformers v6.0, adding native architecture and training workflows for multi-vector late-interaction retrieval models. The update introduces MultiVectorEncoder, bringing ColBERT-style token-level representations directly into the library alongside existing dense embedding, sparse embedding, and cross-encoder reranker classes. While traditional dense retrieval compresses an entire document into a single fixed-dimension vector, multi-vector models preserve ind
    AI
    2 min read
  2. Late Interaction and ColBERT: How Multi-Vector Embeddings and the MaxSim Operator Transform Neural Retrieval

    Information retrieval systems have long wrestled with a fundamental tension between computational efficiency and semantic expressiveness. Traditional dense bi-encoders like DPR compress an entire passage into a single dense vector, allowing sub-linear approximate nearest neighbor (ANN) search over millions of documents. However, forcing multi-sentence passages into a single vector representation creates an information bottleneck that discards fine-grained token-level nuances, entities, and keywo

    AI
    6 min read