State Space Models in Large Language Models: How Mamba, S4, and Selective Recurrence Challenge Transformer Attention
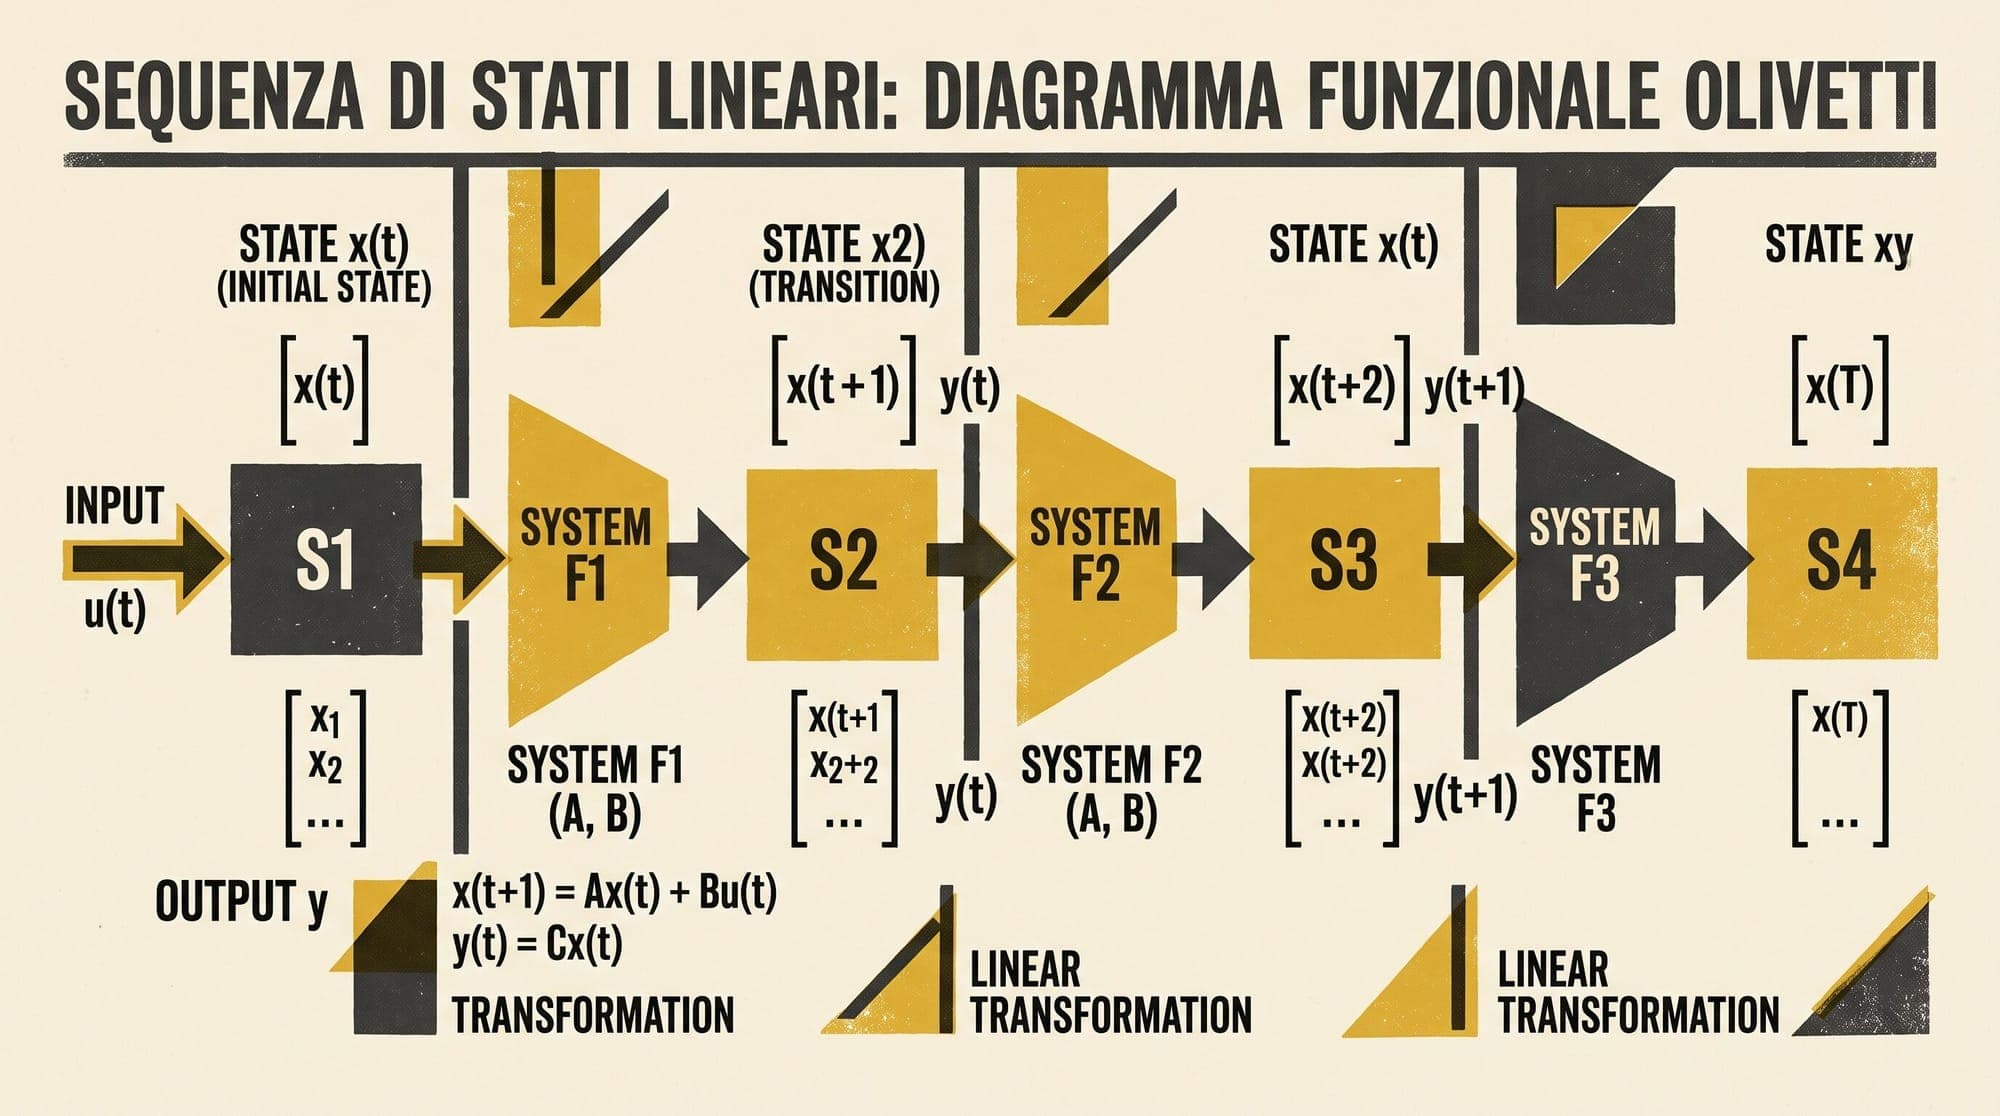
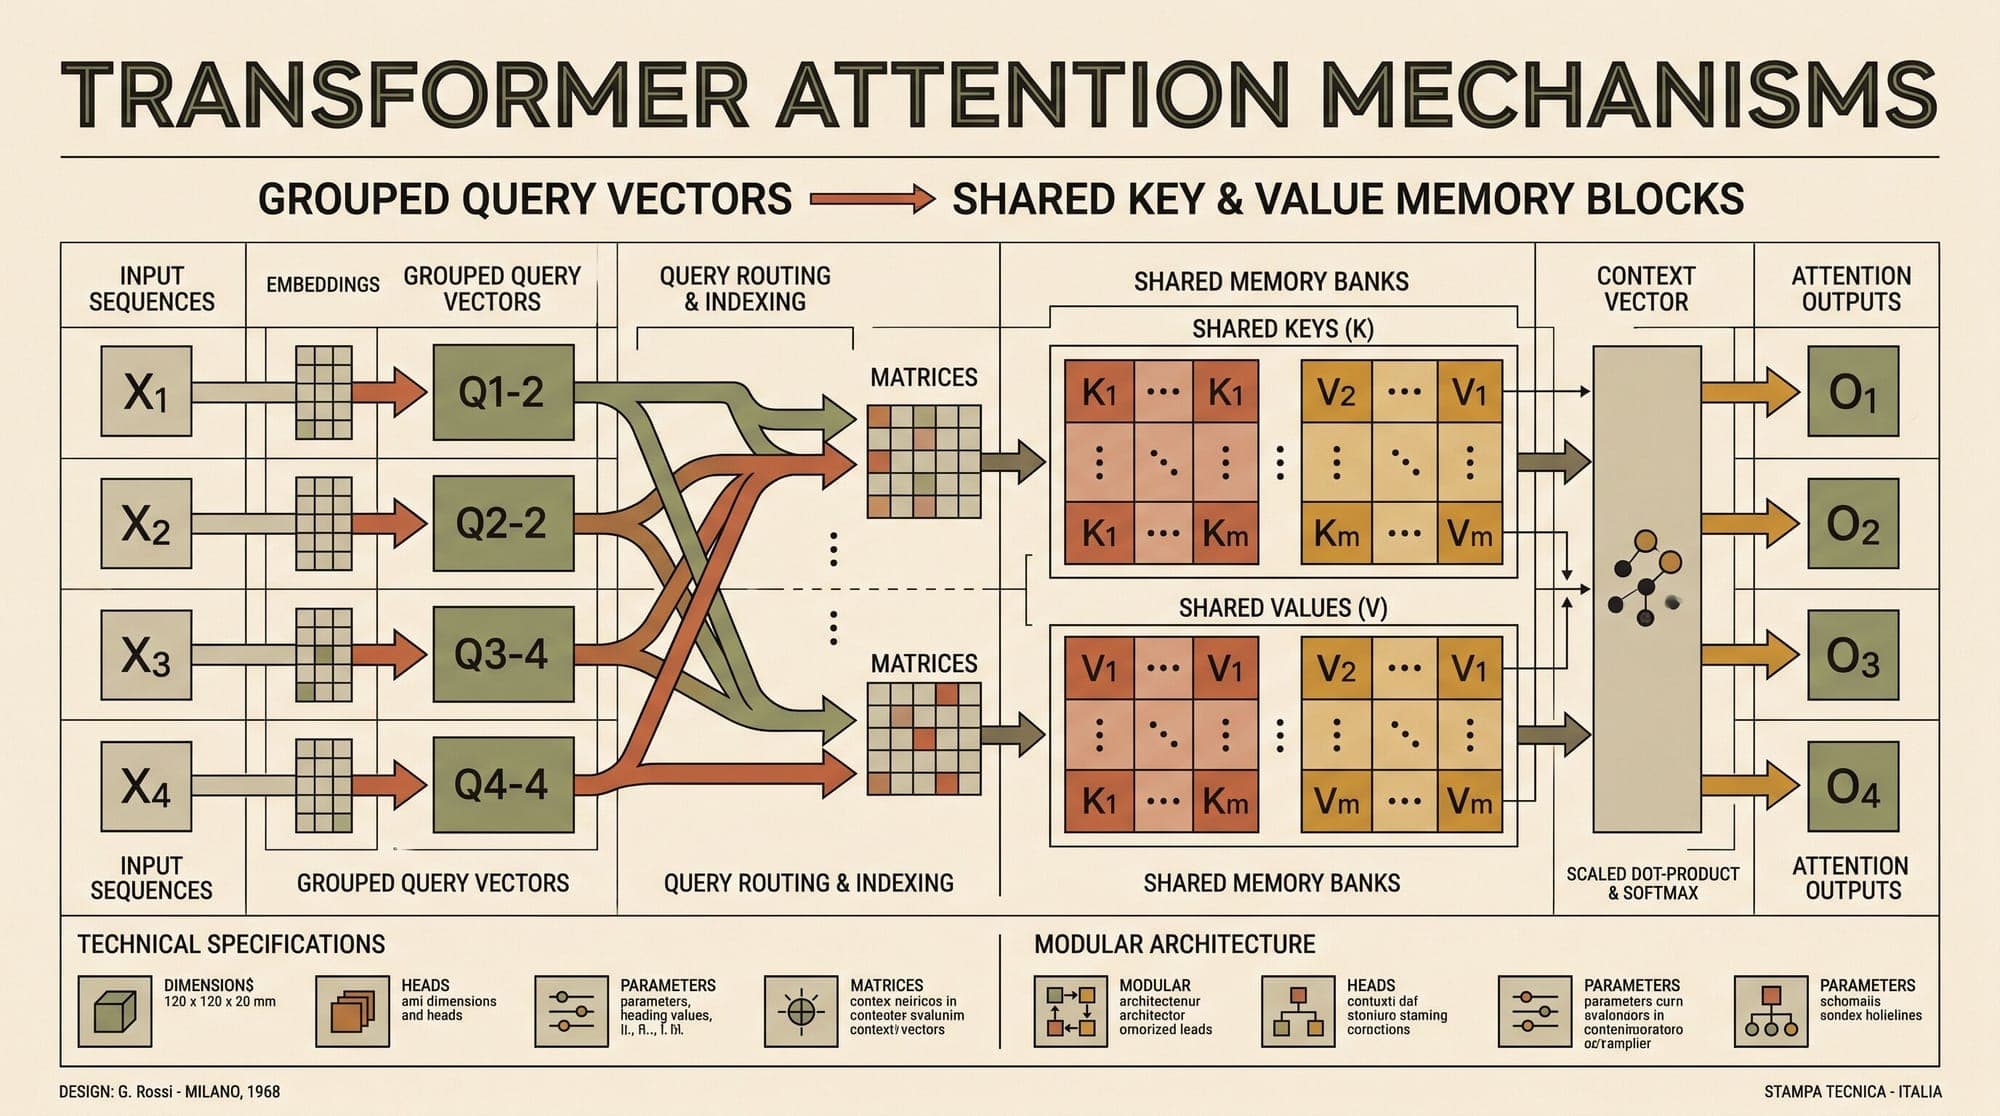
Modern large language models rely almost universally on the Transformer architecture. However, the core mechanism powering Transformers, softmax multi-head self-attention, exhibits fundamental scaling limitations. Specifically, standard self-attention requires quadratic time and memory complexity relative to sequence length during prefilling, alongside a linear memory expansion for the key-value (KV) cache during autoregressive token generation. To circumvent these computational bottlenecks, re