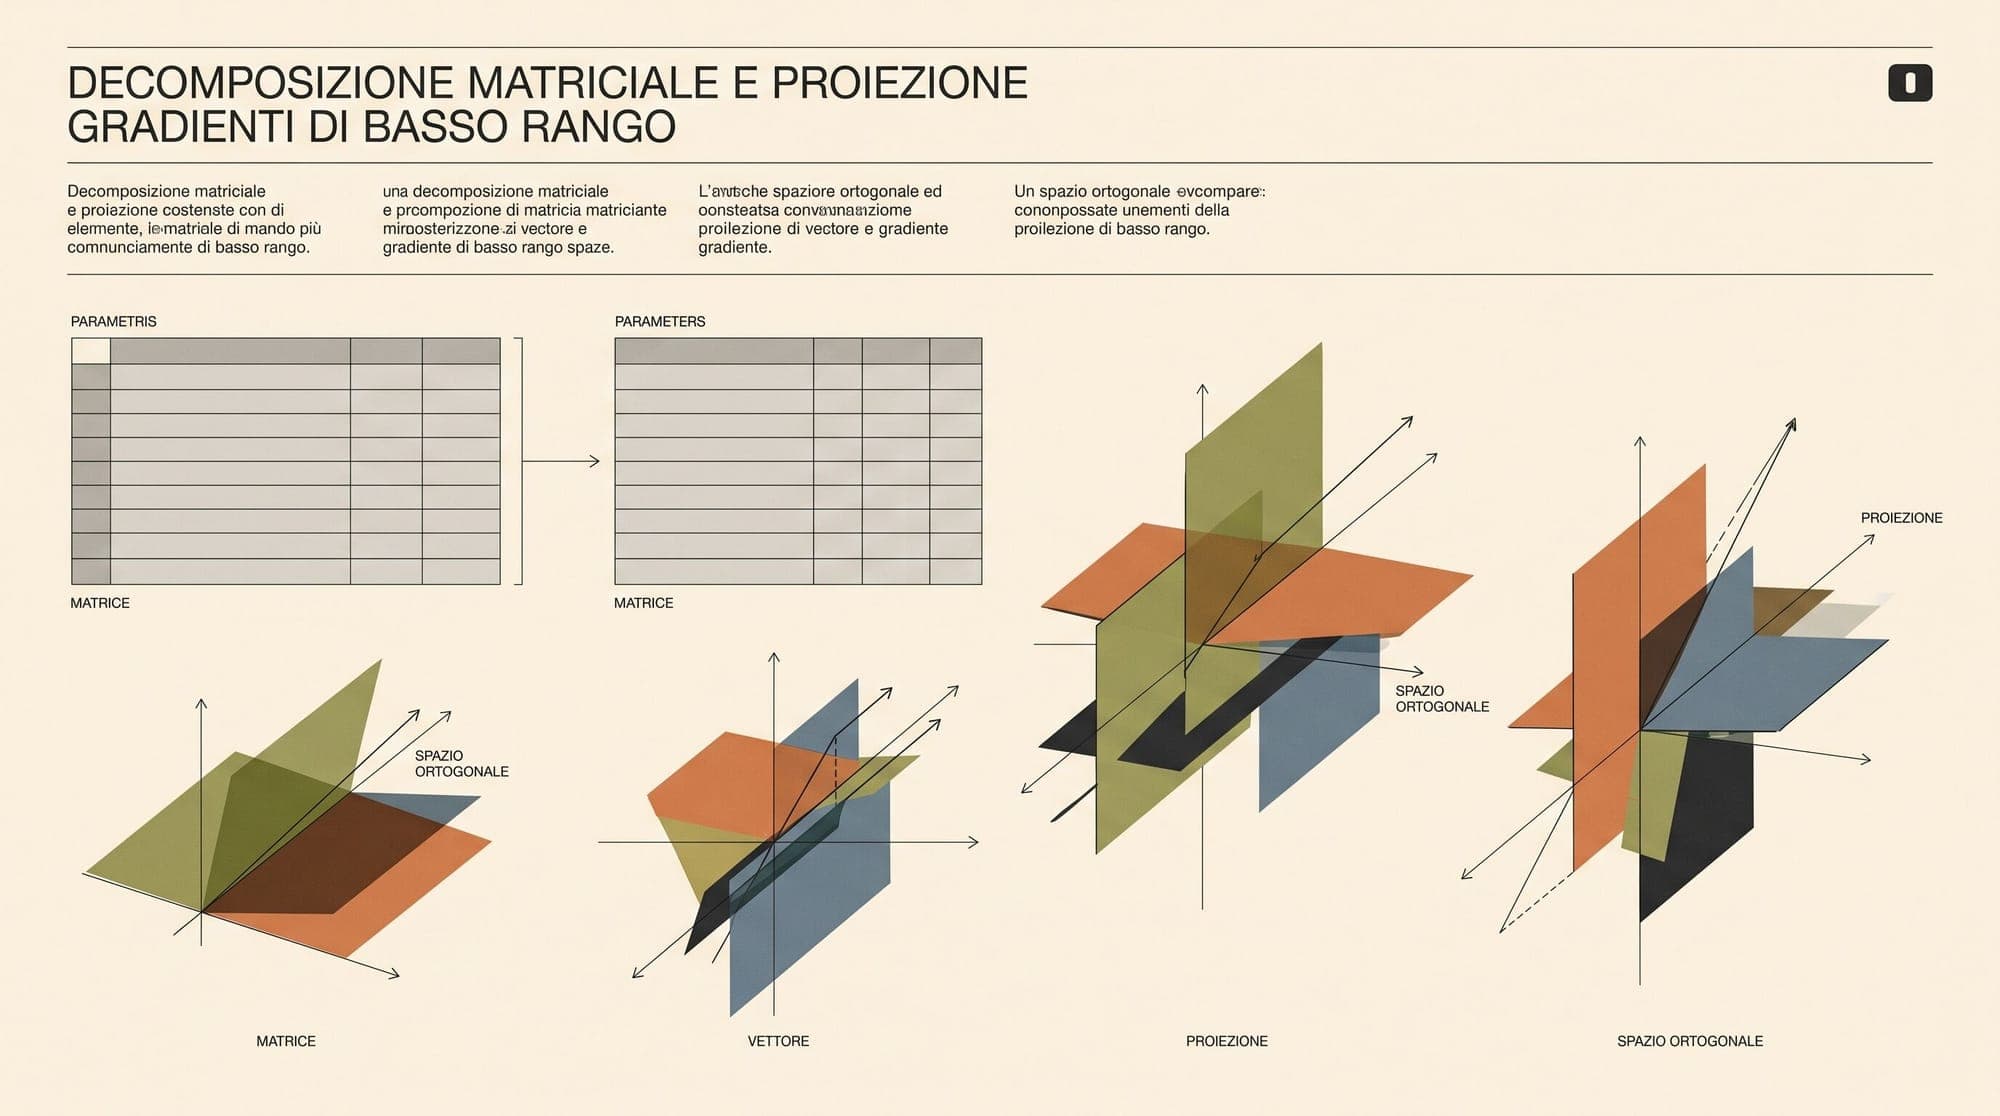
Gradient Low-Rank Projection (GaLore): How Dynamic Subspaces Enable Full-Parameter LLM Pre-Training with Low-Rank Memory
Pre-training foundation large language models has historically required massive compute clusters, largely due to the memory footprint of optimizer states rather than the model weights themselves. While parameter-efficient fine-tuning methods such as Low-Rank Adaptation (LoRA) freeze weights and introduce small adapter matrices, they fail when applied to pre-training from scratch because they restrict parameter updates to a fixed, static low-rank manifold. Gradient Low-Rank Projection (GaLore),