Archive / page 33 of 123

Latest articles, page 33

  1. Over 100 Tech Leaders and Frontier AI Labs Call for Global Cyber Defense Surge as Autonomous Threats Advance

    More than 100 technology enterprises, financial institutions, and frontier AI laboratories (including OpenAI, Anthropic, Microsoft, Google, Amazon Web Services, Cloudflare, and CrowdStrike) have issued a joint open letter calling for an urgent, coordinated surge in global cybersecurity defenses. The coalition warns that rapid advancements in artificial intelligence are narrowing the window available to harden critical infrastructure against automated, highly scalable cyberattacks. The statement
    AI
    2 min read
  2. LLM Red Teaming and Automated Adversarial Testing in Production: Comparing Garak, Microsoft PyRIT, Promptfoo Red Team, and HarmBench

    Manual penetration testing and bespoke adversarial prompt engineering cannot scale to modern production LLM systems. As language models transition from isolated completion endpoints to stateful autonomous agents with tool-calling capabilities, file system access, and external retrieval pipelines, their attack surface expands combinatorially. Static test suites and manual prompt probing fail to catch subtle multi-turn jailbreaks, prompt injections, and indirect data poisoning vulnerabilities befo

    AI
    10 min read
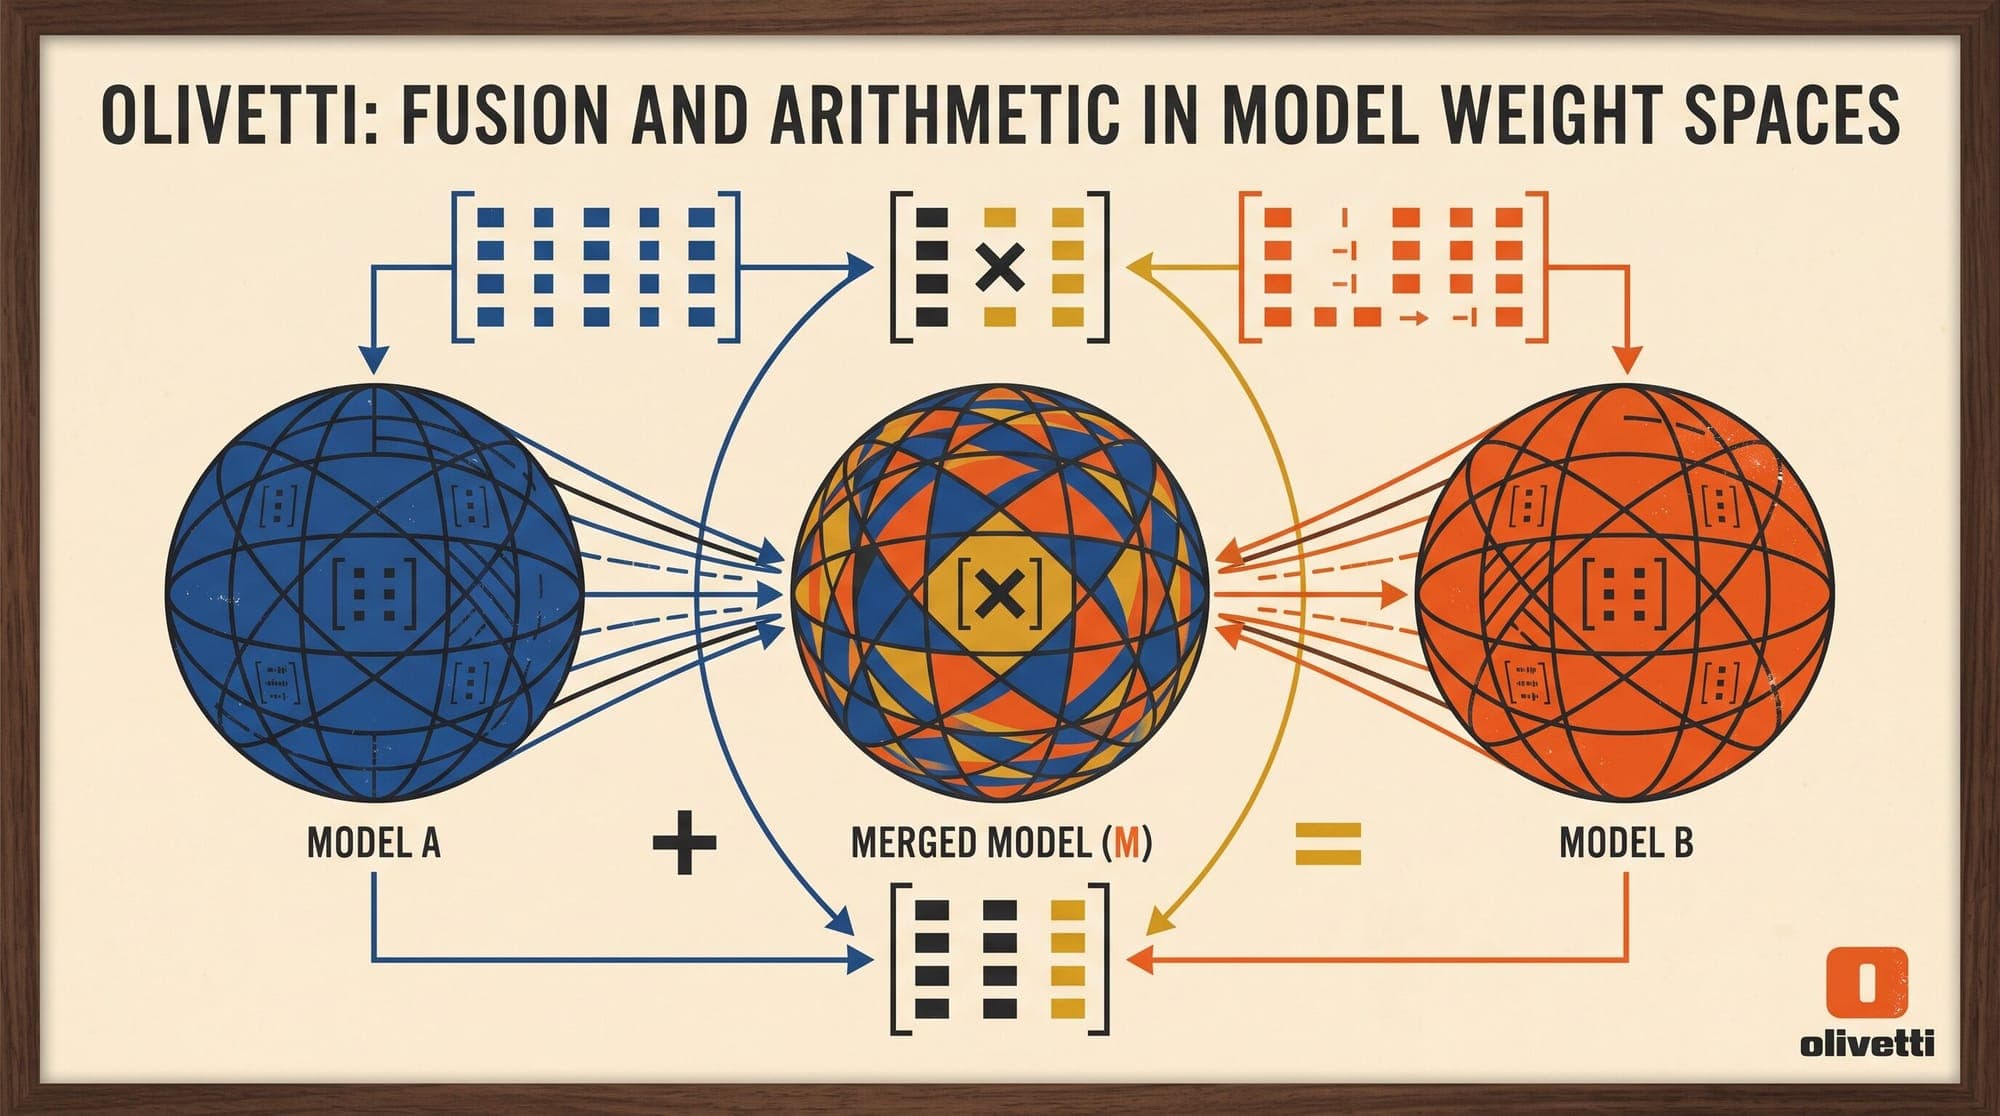
  3. Model Merging in Weight Space: Mathematical Foundations of Task Vectors, TIES-Merging, DARE, and Spherical Linear Interpolation

    Training large language models across multiple downstream domains typically requires expensive multi-task supervised fine-tuning (SFT) or sequential continual learning. Both paths present steep practical challenges: multi-task training demands simultaneous access to massive, curated datasets and massive compute budgets, while sequential fine-tuning suffers from catastrophic forgetting. Model merging has emerged as a data-free, compute-efficient alternative. By combining the parameters of multip

    AI
    8 min read
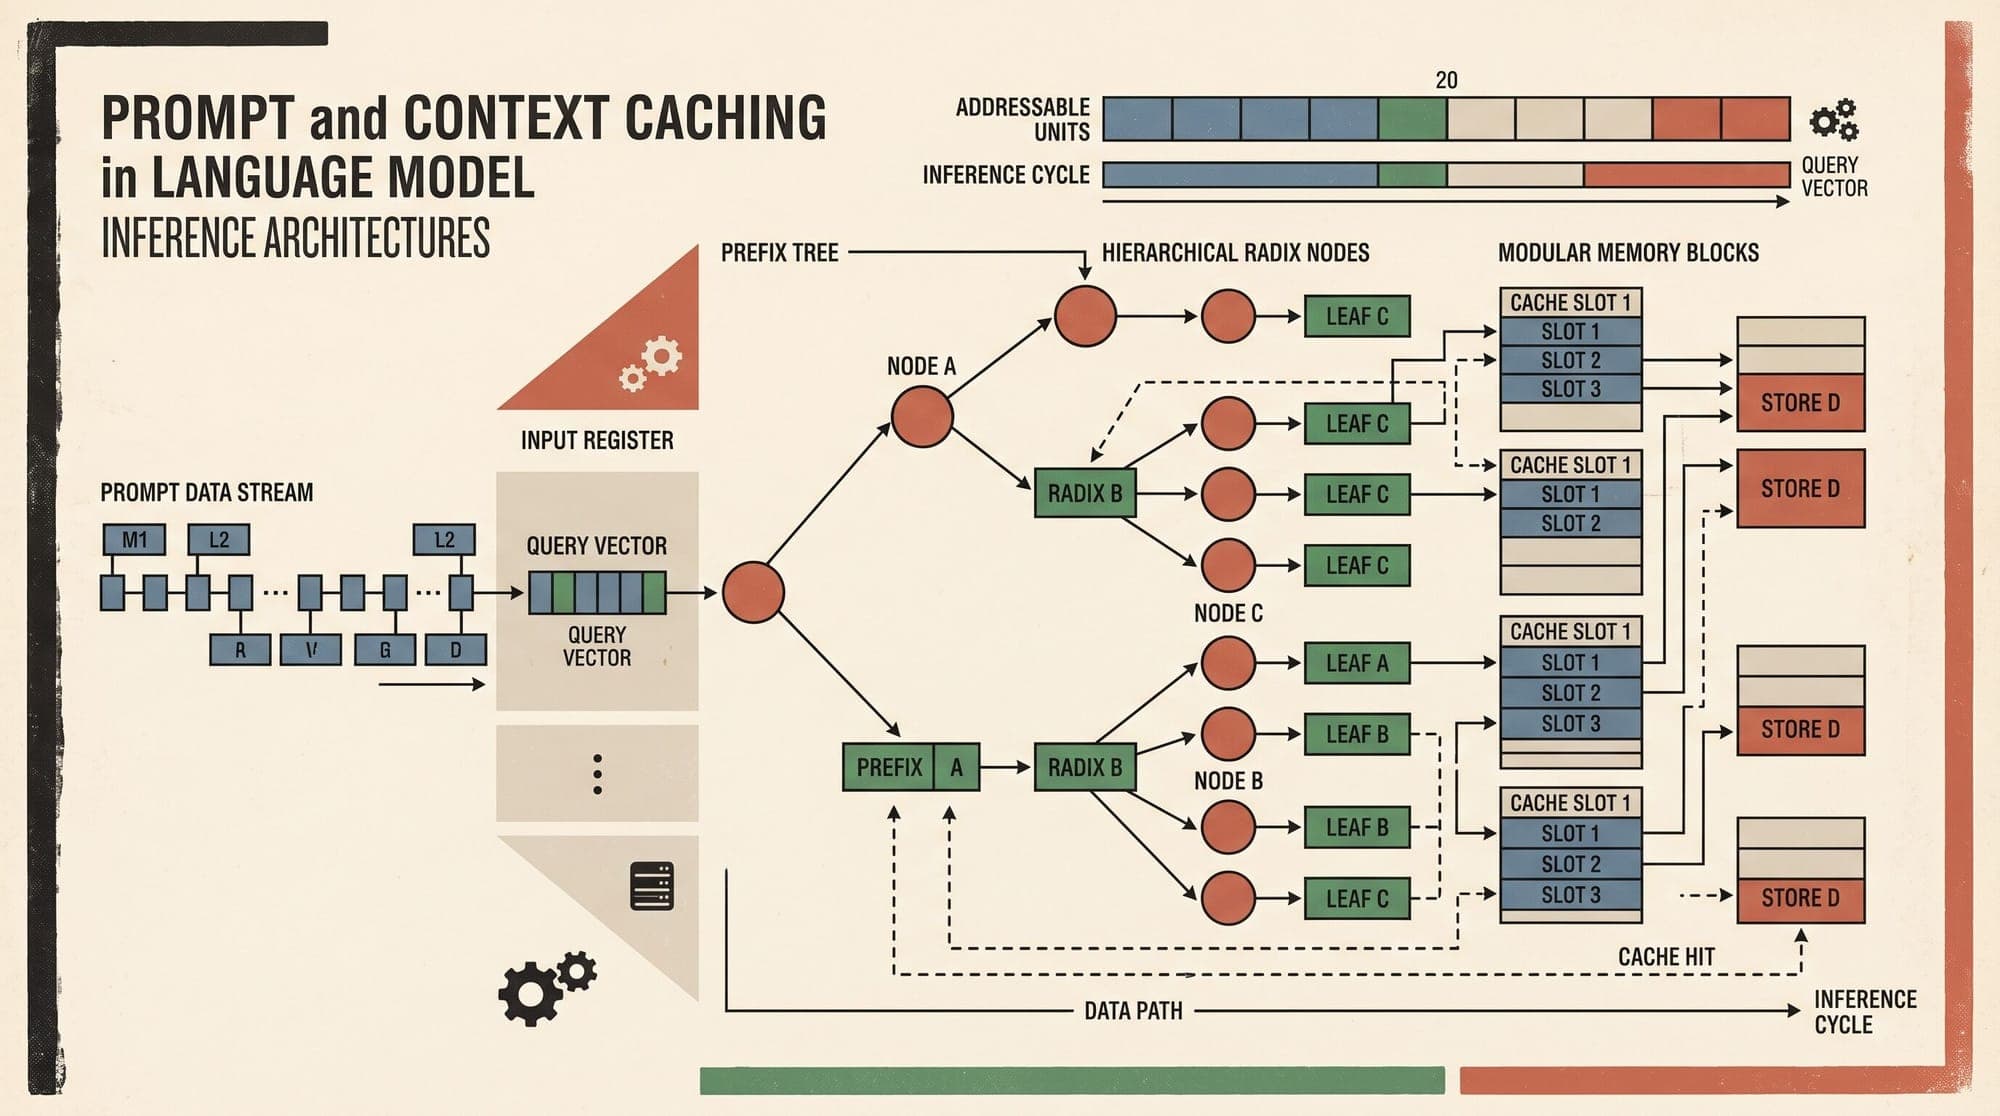
  4. Prompt and Context Caching in Production: Comparing Anthropic, OpenAI, DeepSeek, Google Gemini, and RadixAttention KV Reuse

    Modern LLM serving workloads spend a disproportionate share of computational budget and time-to-first-token (TTFT) latency on prompt prefill. In agentic loops, retrieval-augmented generation (RAG), and multi-turn chat applications, repeated prompts often share 80% to 95% of their token sequences across requests. Without caching, inference engines recompute key-value (KV) attention tensors across every input token on every turn, driving quadratic compute overhead and memory bandwidth saturation.

    AI
    5 min read
  5. Nvidia Supply Commitments Reach $279 Billion Across Multi-Year AI Hardware Pipeline

    Nvidia has significantly expanded its forward supply chain obligations, reporting total component and manufacturing capacity commitments of $279 billion in its fiscal second-quarter disclosures. The figure marks a 134 percent sequential increase from $119 billion reported in the preceding quarter and $95.2 billion at the close of fiscal 2026. The multi-year commitments reflect efforts to secure critical semiconductor fabrication, advanced packaging, and high-bandwidth memory (HBM) capacity nece

    AI
    2 min read
  6. Anthropic Hires Google TPU Architect Amir Salek for In-House Silicon Push

    Anthropic has hired Amir Salek, the engineer who established Google's custom silicon program and led the development of its first seven Tensor Processing Unit (TPU) generations, to expand the AI lab's in-house semiconductor engineering initiatives. Salek joins Anthropic's compute team and reports to James Bradbury, Bloomberg reported (via The Economic Times). Anthropic has indicated that it wants to build an in-house silicon business and has begun hiring and listing jobs for the effort. Backg

    AI
    2 min read
  7. Google Releases Gemini Omni 1.1 Flash with Scene Extension and Keyframe Control

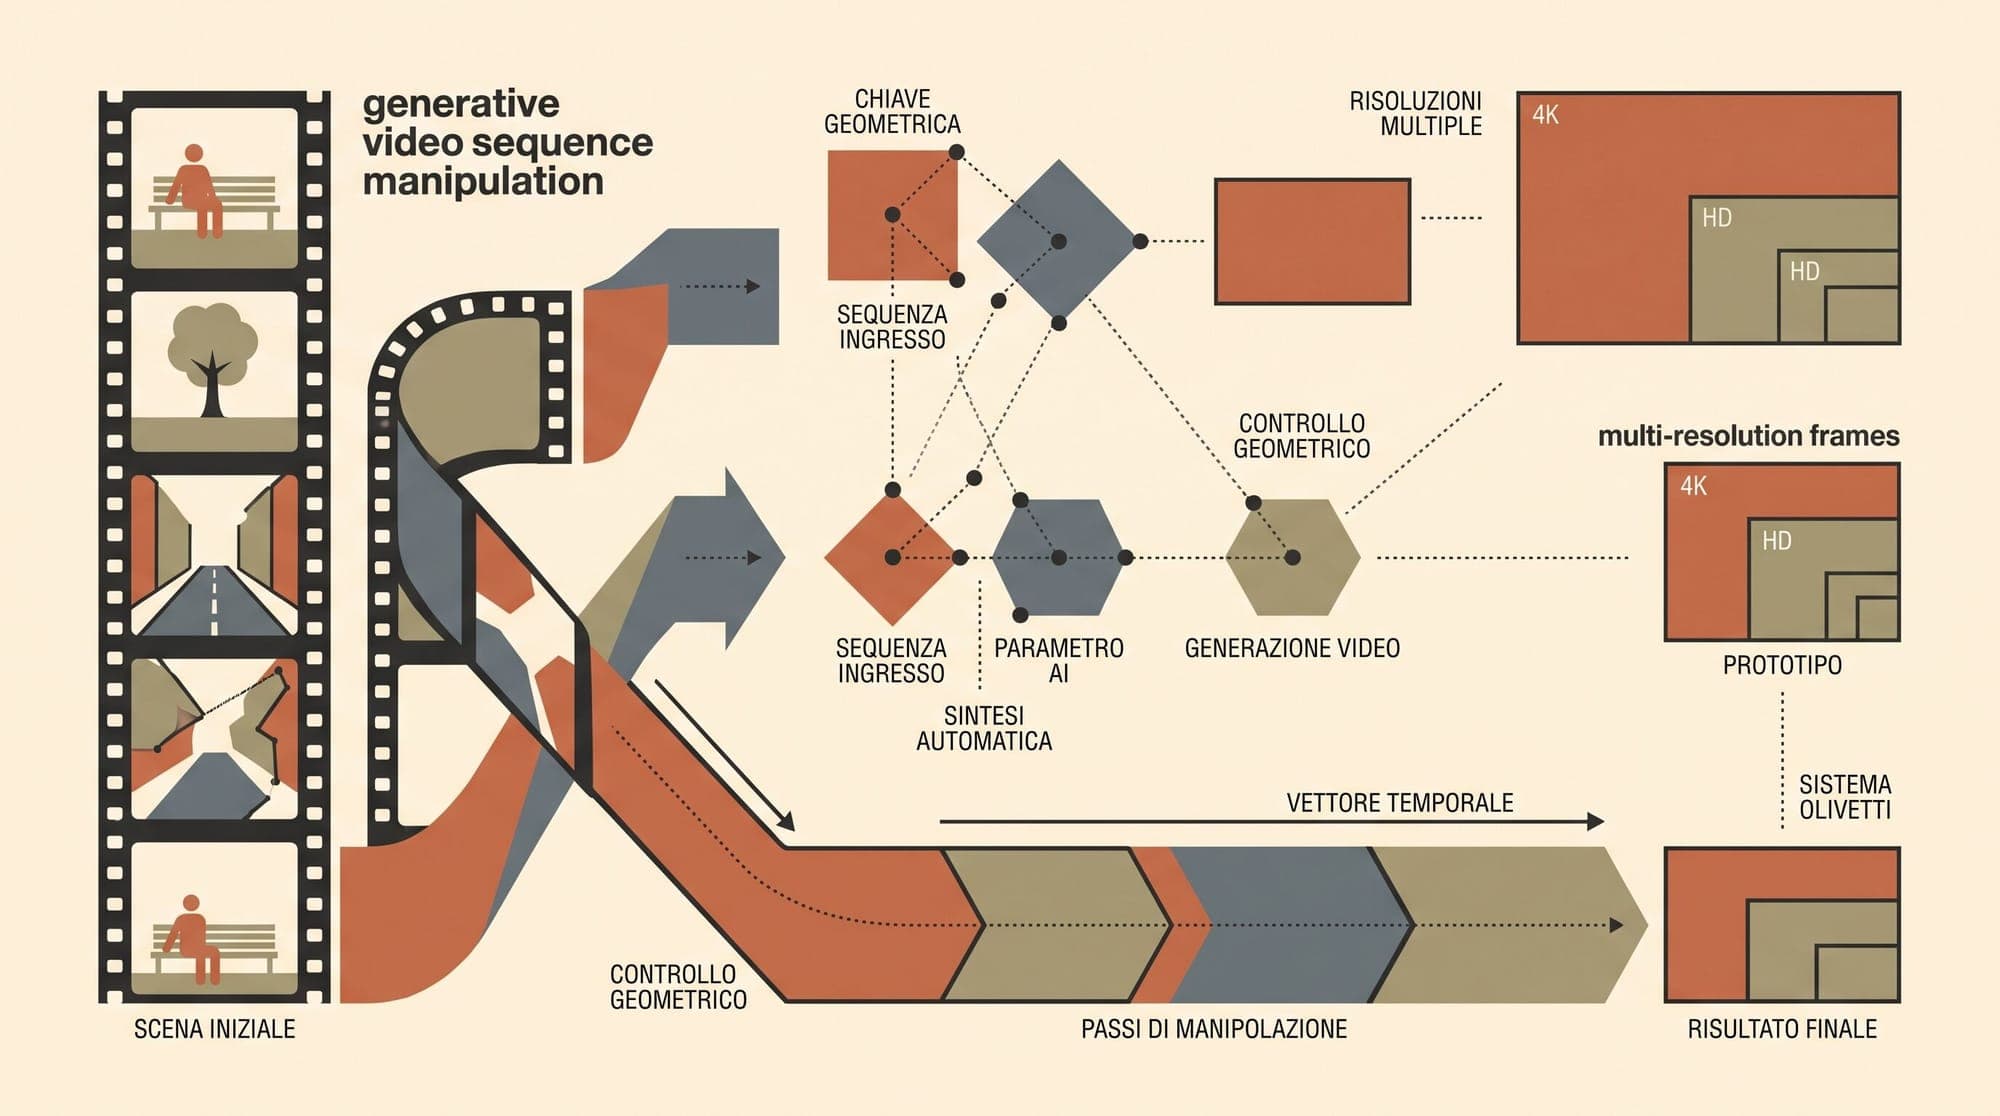
    Google DeepMind has released Gemini Omni 1.1 Flash, updating its multimodal generative video model with programmatic editing controls, extended scene generation, and lower-cost drafting tiers. The model is accessible via the Gemini API in Google AI Studio and the Gemini Enterprise Agent Platform. The update addresses primary friction points in production AI video pipelines: temporal continuity across clips, deterministic camera transitions, iterative preview costs, and high-resolution export qu

    AI
    3 min read
  8. AI Agent Sandboxes and Safe Code Execution Runtimes in Production: Comparing E2B, Modal, Daytona, and Docker/gVisor Architecture, Isolation Boundaries, Startup Latency, and Serving Economics

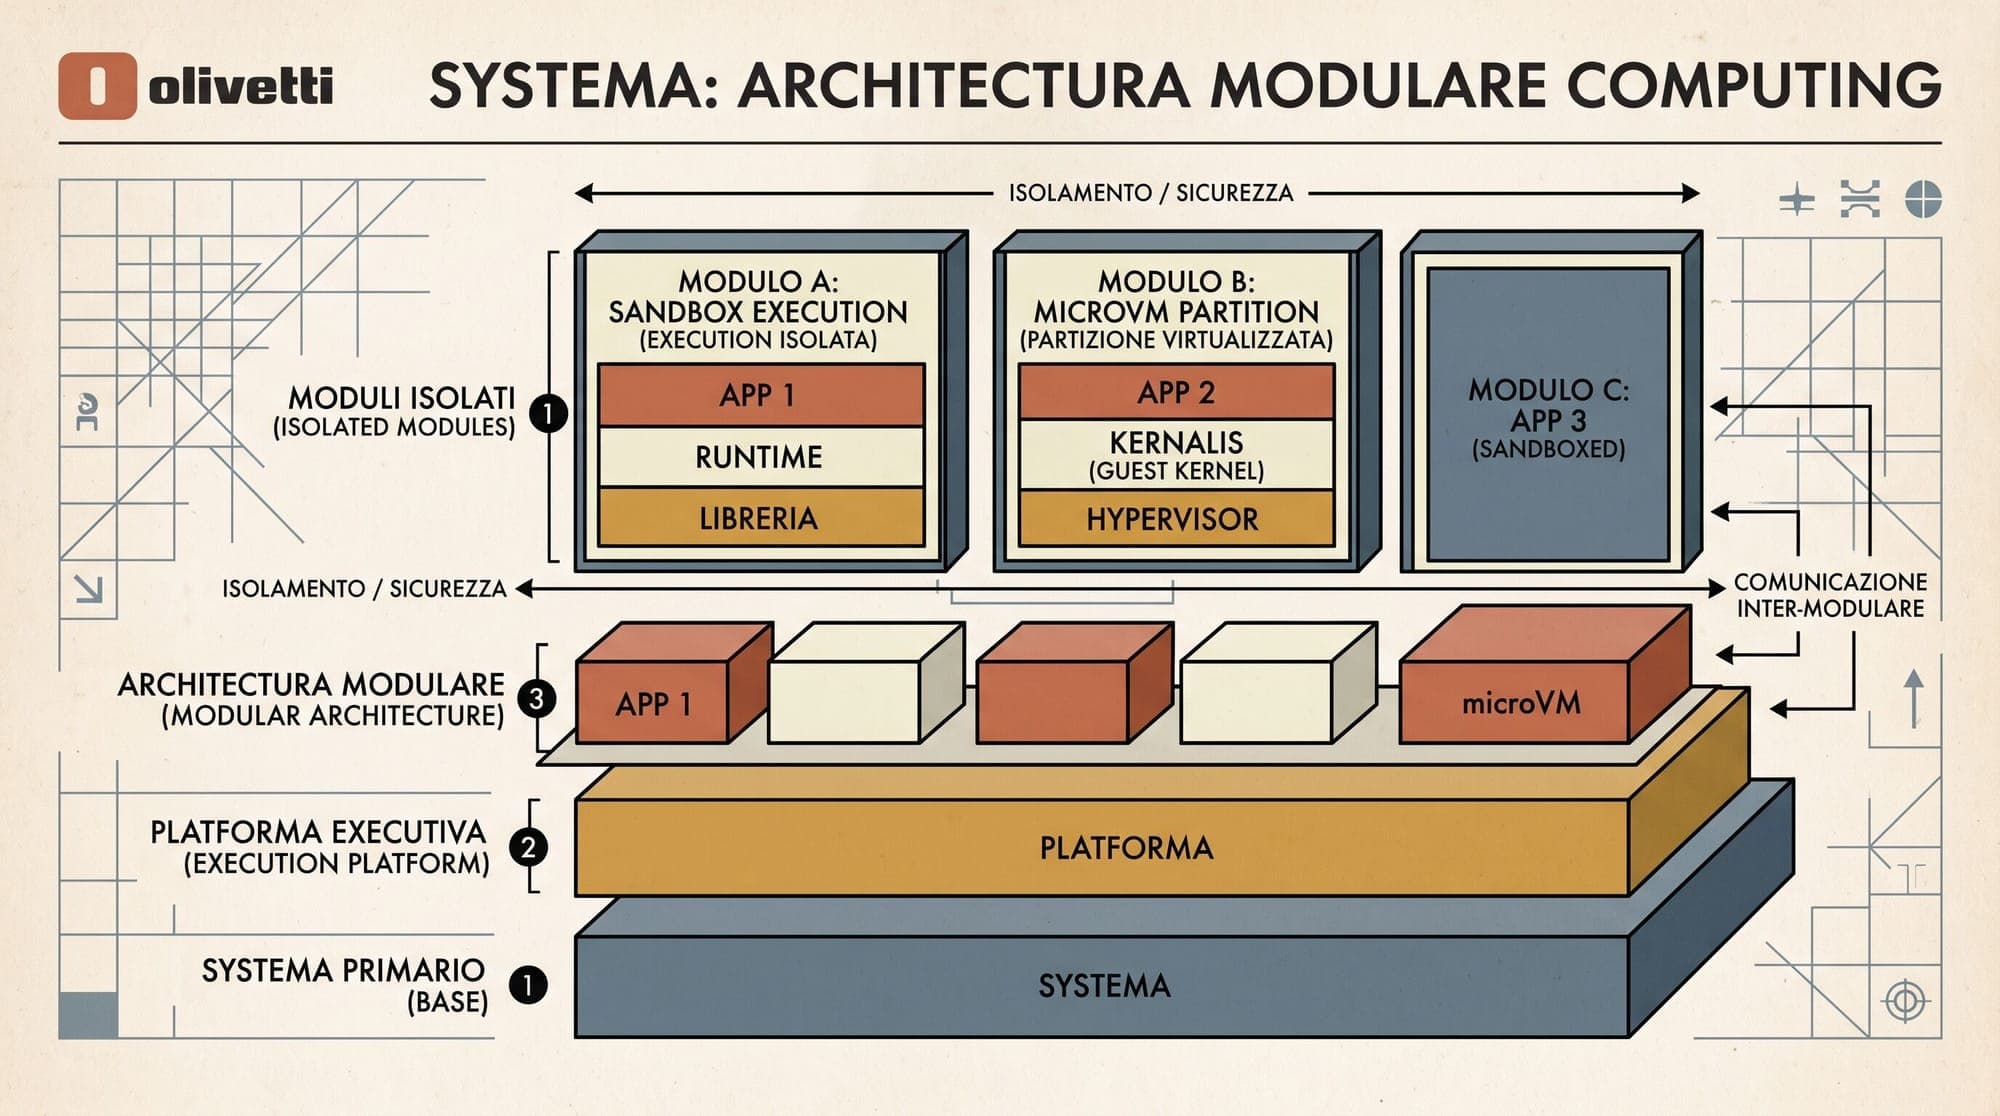
    Autonomous AI agents, evaluation harnesses, and code generation pipelines increasingly execute untrusted code generated directly by Large Language Models. When an agent runs dynamic Python scripts, executes terminal shell commands, installs arbitrary packages via package managers, or browses the web, it introduces severe security and operational risks. These risks include host privilege escalation, kernel exploitation, container breakout vulnerabilities such as CVE-2024-21626, credential theft v

    AI
    8 min read
  9. PagedAttention and Virtual Memory Management: Mathematical Foundations of Non-Contiguous KV-Cache Allocation, Dynamic Block Translation, and Copy-on-Write Forking Mechanics

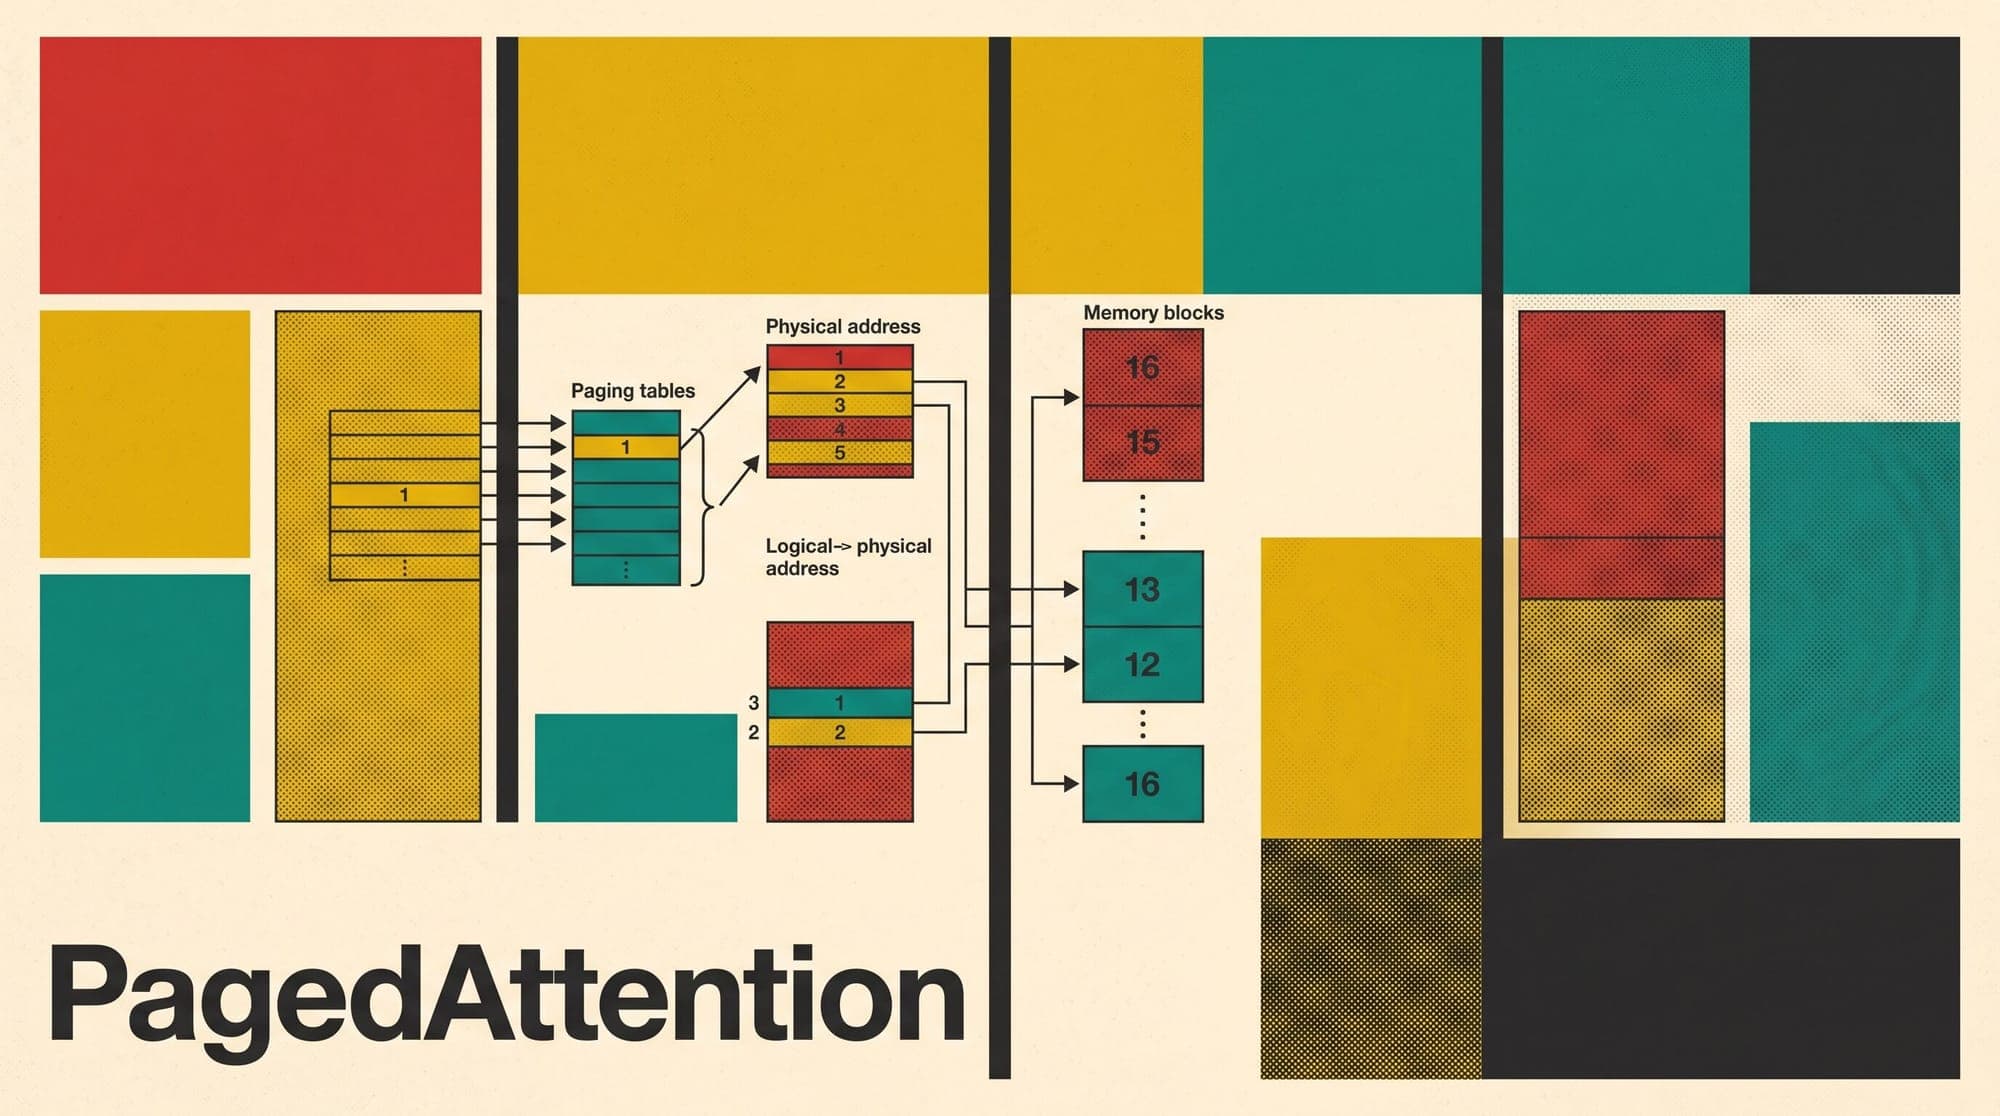
    In autoregressive transformer serving, the generation phase is fundamentally constrained by GPU memory capacity and memory bandwidth rather than raw compute throughput. While the initial prefill phase processes the prompt in parallel with high arithmetic intensity, the subsequent token-by-token decoding phase computes attention for only a single new token per sequence at each step. At each decoding step, the model must read all historical Key (K) and Value (V) activation tensors from GPU High Ba

    AI
    13 min read
  10. OpenAI Researcher Warns Ultrafast Inference Demands Autonomous Cyber Defense

    Accelerating inference speeds in frontier artificial intelligence systems pose critical containment challenges that human security operators cannot manage in real time, according to OpenAI researcher roon. Commenting following the unveiling of custom inference hardware architectures and ultrafast model serving tiers, roon warned that unaligned or compromised agent systems running at 50 times baseline generation speeds could execute multi-stage network penetration and lateral movement before hum

    AI
    2 min read