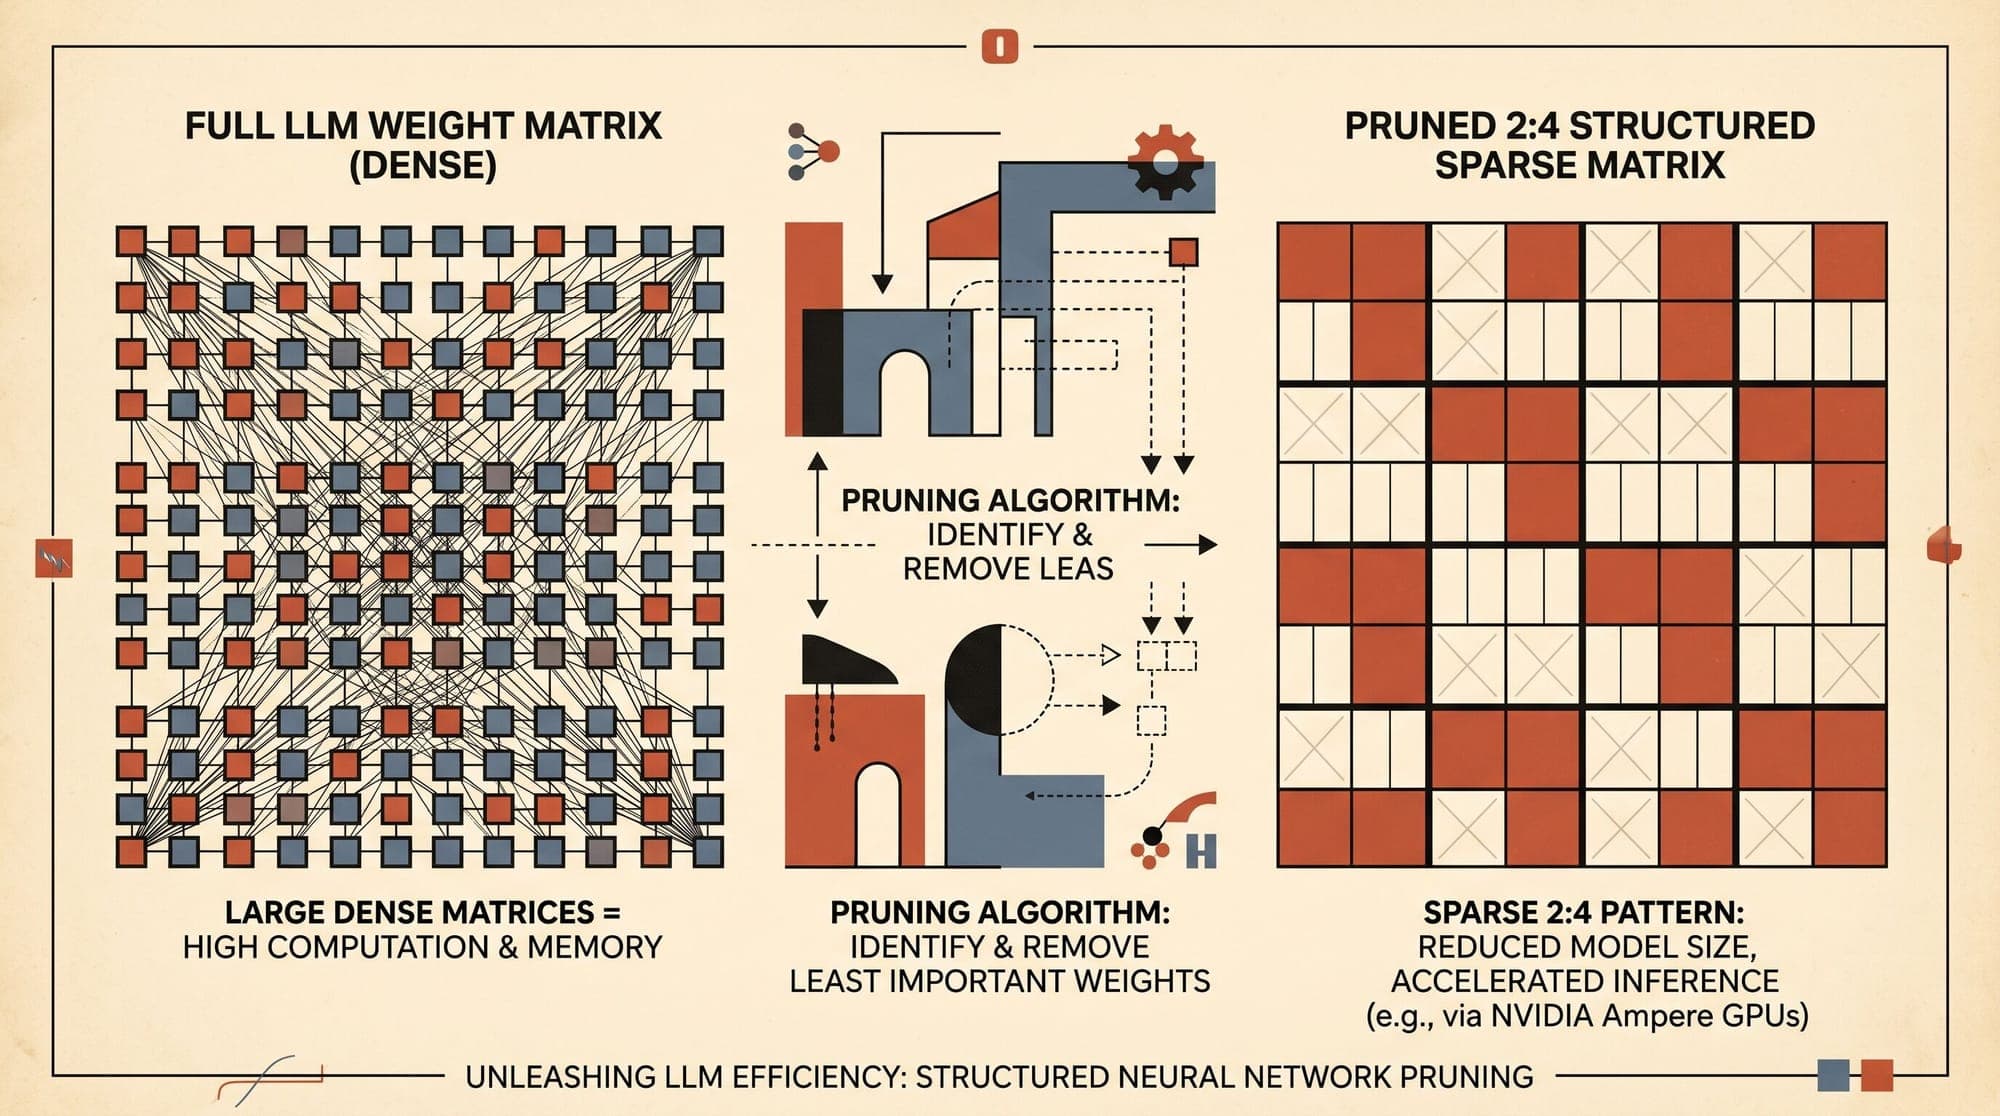
Weight Pruning in Large Language Models: Mathematical Foundations of Magnitude Pruning, Wanda, SparseGPT, and Semi-Structured 2:4 Sparsity
Weight Pruning in Large Language Models: Mathematical Foundations of Magnitude Pruning, Wanda, SparseGPT, and Semi-Structured 2:4 Sparsity As frontier transformer models expand past hundreds of billions of parameters, model serving is constrained by memory capacity and memory bandwidth. In autoregressive token generation, memory bandwidth dominates latency because memory-bound matrix-vector operations require streaming entire weight matrices from High Bandwidth Memory (HBM) to on-chip SRAM for