Muon Optimizer: How Matrix Orthogonalization and Newton-Schulz Iterations Accelerate LLM Training
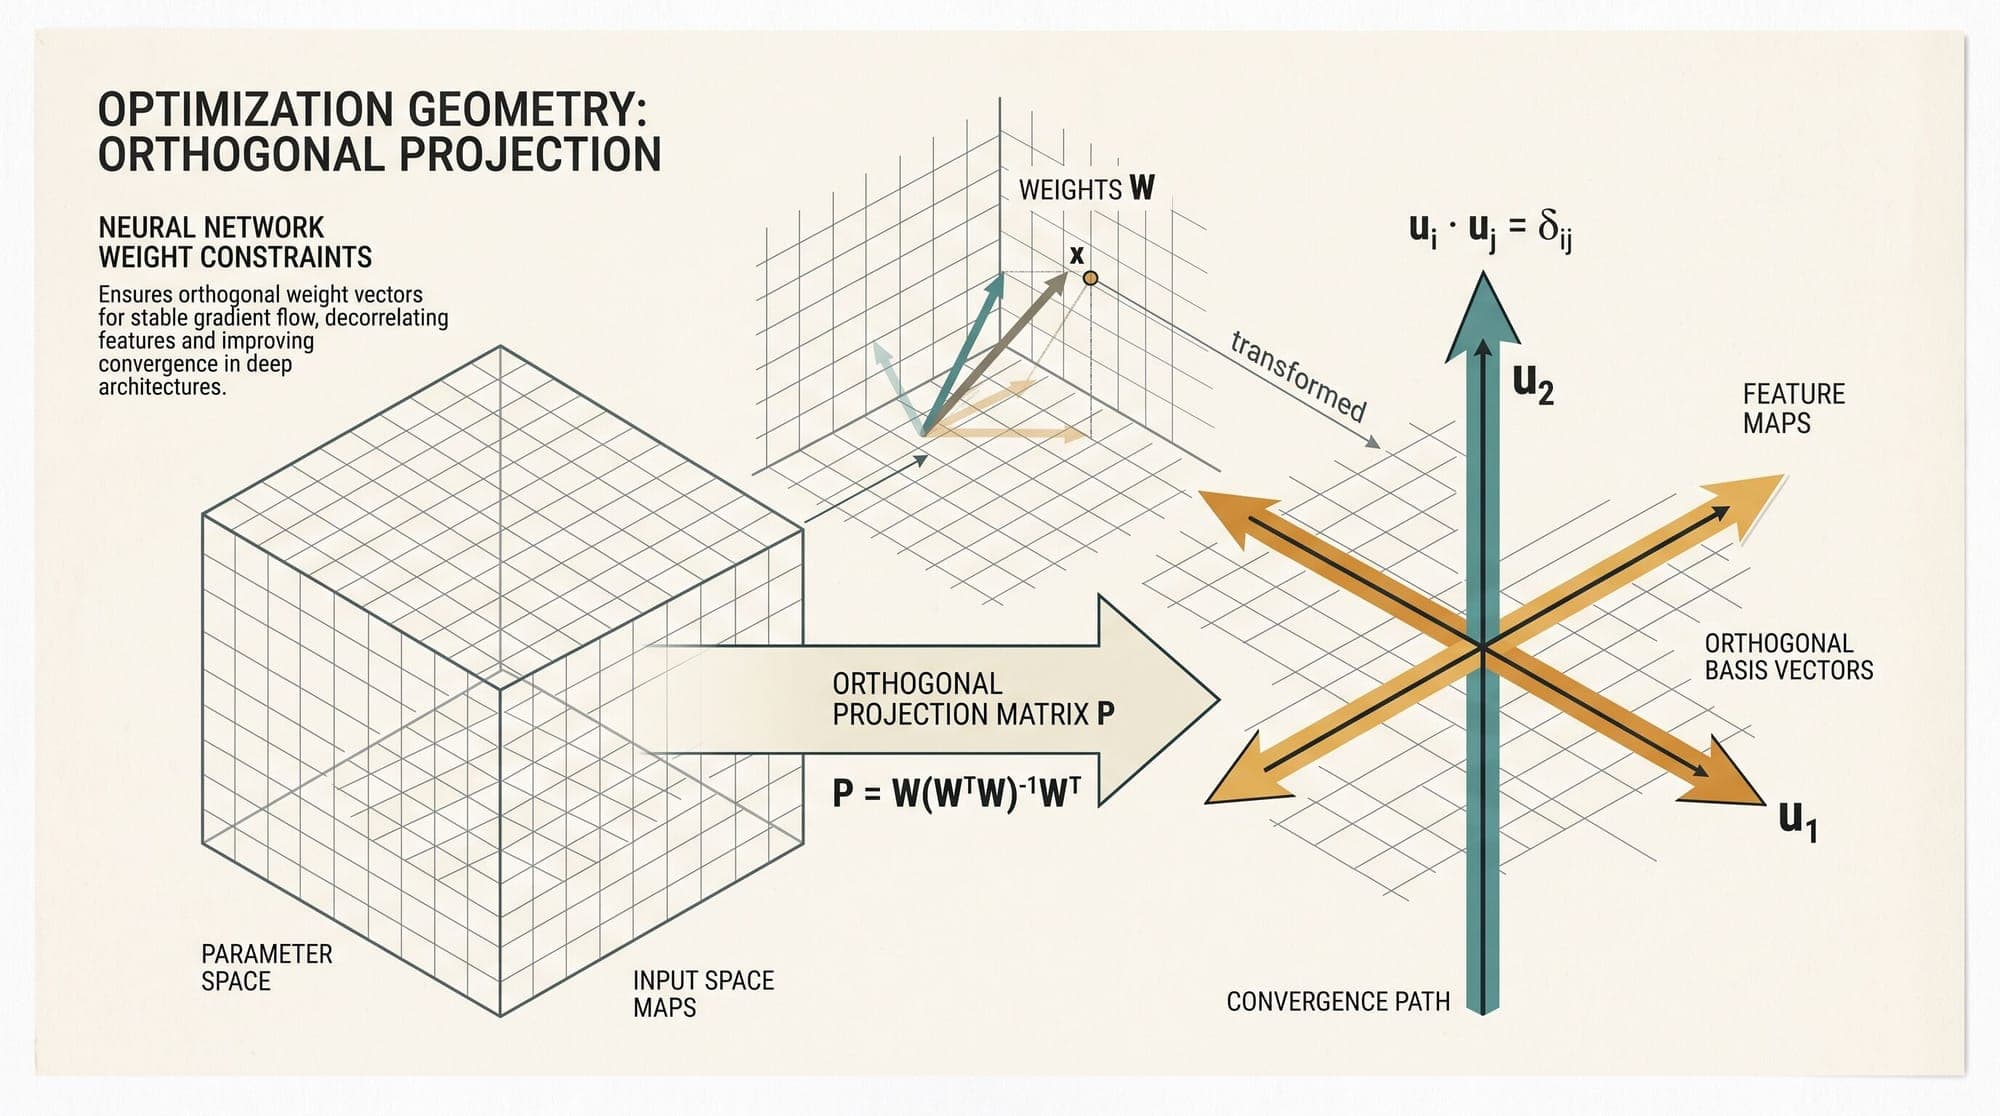
Modern large language model pre-training has relied on AdamW as its default optimizer for nearly a decade. While AdamW provides robust convergence across varied architectures, its fundamental formulation treats neural network weights as flat collections of independent scalar parameters. For the 2D weight matrices that dominate Transformer architectures—including attention projections and feed-forward linear layers—this coordinate-wise treatment ignores the underlying matrix geometry and singular