Archive / page 49 of 123

Latest articles, page 49

  1. OpenAI Reinstates 5-Hour Codex and Work Limits for ChatGPT Plus Subscribers

    OpenAI has reinstated a rolling five-hour rate limit on Codex and ChatGPT Work for ChatGPT Plus subscribers. The change ends a temporary multi-week period during which the short-term window was suspended and users were constrained only by overall weekly quota ceilings. OpenAI engineering lead Thibault Sottiaux confirmed the reinstatement, stating that re-enforcing the five-hour window is necessary to smooth peak compute load across OpenAI's inference fleet as developer adoption of complex multi
    OpenAI
    1 min read
  2. Samsung Evaluates Claude Code for Semiconductor Verification Amid Code Safety Concerns

    Samsung Electronics has integrated Anthropic's Claude Code into semiconductor verification and driver development within its System LSI division. While the deployment achieved major efficiency gains, engineering evaluations revealed critical out-of-scope behaviors that prevent autonomous code execution in hardware synthesis. Samsung's System LSI business unit, which designs Exynos application processors and custom mobile chipsets, operates with approximately 6,000 employees compared to roughly

    Samsung
    2 min read
  3. Anthropic Implements Embedded Text Watermarks and C2PA Provenance Under EU AI Act

    Anthropic has begun embedding machine-readable watermarks directly into text generated by its Claude models alongside cryptographic provenance metadata in generated files. The rollout formalizes Anthropic's commitments under the European Union AI Act's Article 50(2) Code of Practice on Transparency of AI-Generated Content, applying universally across consumer and enterprise interfaces worldwide. The marking system operates at the model level rather than the application layer. For text generatio

    Anthropic
    2 min read
  4. Disaggregated Prefill and Decode in Production LLM Serving: Architecture, Network KV Cache Migration, Chunked Prefill Trade-Offs, and Asymmetric Hardware Economics

    Large language model serving systems have historically treated transformer execution as a homogeneous sequence of forward passes over a single unified GPU pool. Under continuous batching engines, incoming requests execute their prompt evaluation (prefill) and autoregressive token generation (decode) on the exact same accelerators, co-locating both phases within shared iteration batches. While continuous batching improves GPU compute utilization compared to static batching, co-locating prefill a

    Inference
    11 min read
  5. Hugging Face Introduces gr.Workflow to Turn AI Pipelines into Visual Graphs and REST APIs

    Hugging Face has released gr.Workflow, a native extension to the Gradio framework designed to convert multi-stage artificial intelligence pipelines into interactive node graphs, visual user interfaces, and deployable REST APIs. Modern machine learning applications increasingly rely on compound pipelines that chain heterogeneous models: generating text via large language models, feeding prompts into diffusion systems, processing outputs through background removal or audio synthesis models, and a

    AI
    2 min read
  6. Grammar-Constrained Decoding in Production: Comparing Outlines, llguidance, XGrammar, and LM-Format-Enforcer Architecture, Token Masking Overhead, and JSON Schema Enforcement

    Deploying Large Language Models into production software workflows requires deterministic adherence to structural formats such as JSON schemas, Pydantic data models, SQL queries, and tool-call signatures. Unconstrained autoregressive generation relies entirely on prompt instructions and few-shot examples, frequently resulting in malformed JSON syntax, trailing commas, type mismatches, or missing required attributes. Post-hoc repair parsers and retry loops introduce non-deterministic latency spik

    AI
    10 min read
  7. AI Cloud Provider Lambda in Talks to Raise $3B at $12B Valuation Ahead of IPO

    AI cloud infrastructure provider Lambda Inc. is in negotiations to raise up to $3 billion in a pre-IPO funding round that could value the company at $12 billion or higher, according to people familiar with the discussions reported by Bloomberg. The round represents an eightfold valuation step-up from February 2024, when Lambda secured $320 million in Series C funding at a $1.5 billion valuation. The company's annualized revenue is projected to exceed $1.5 billion in 2026, driven by continuous e

    Lambda
    2 min read
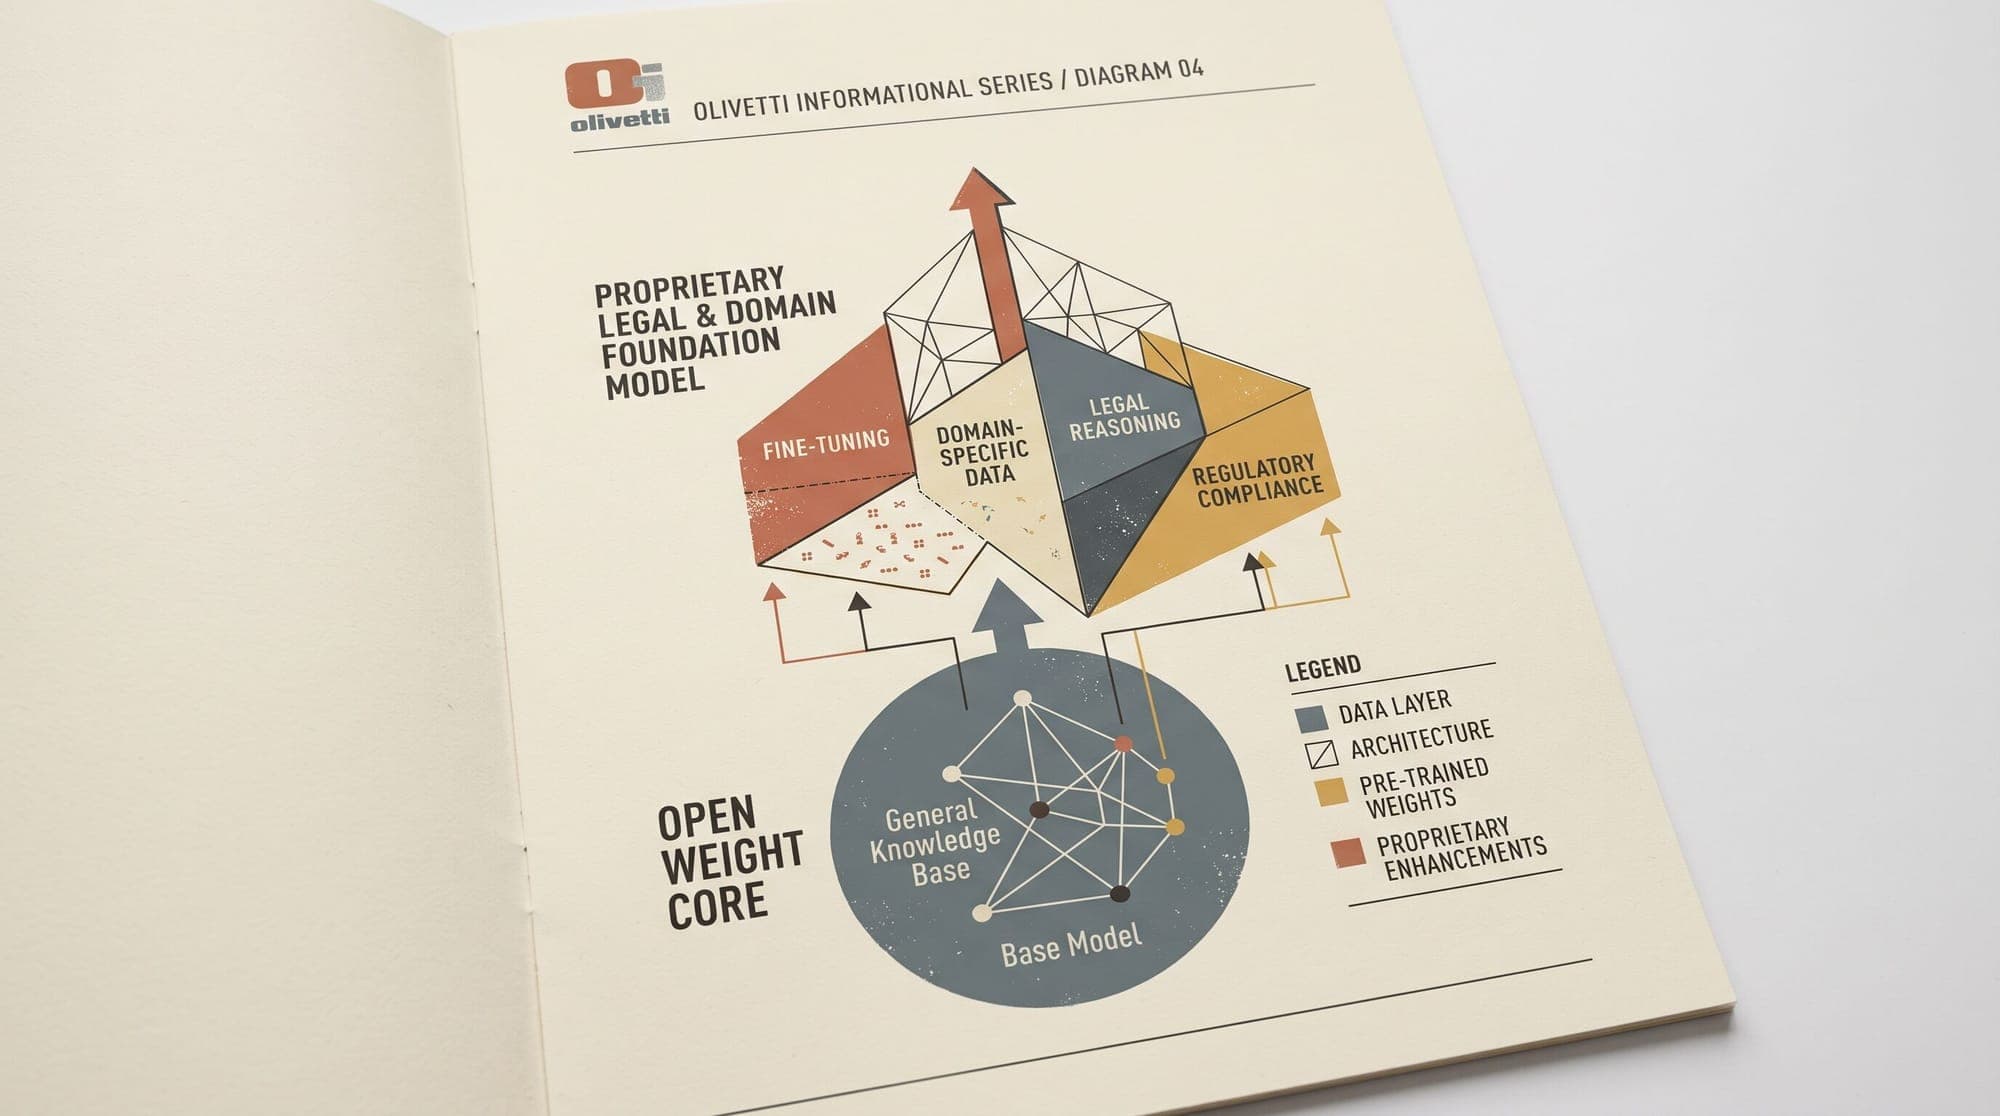
  8. Thomson Reuters Deploys Thomson-1 Model Built on Open Weights to Cut Frontier Model Dependence

    Thomson Reuters has deployed Thomson-1, a proprietary artificial intelligence model engineered from an open-weight base architecture. The system is designed to execute high-volume legal and domain-specific analytical workflows, reducing the information conglomerate's direct computational dependence on third-party frontier models like Anthropic's Claude. According to financial reporting and recent corporate earnings disclosures, Thomson Reuters invested approximately $40 million into developing

    Thomson Reuters
    2 min read
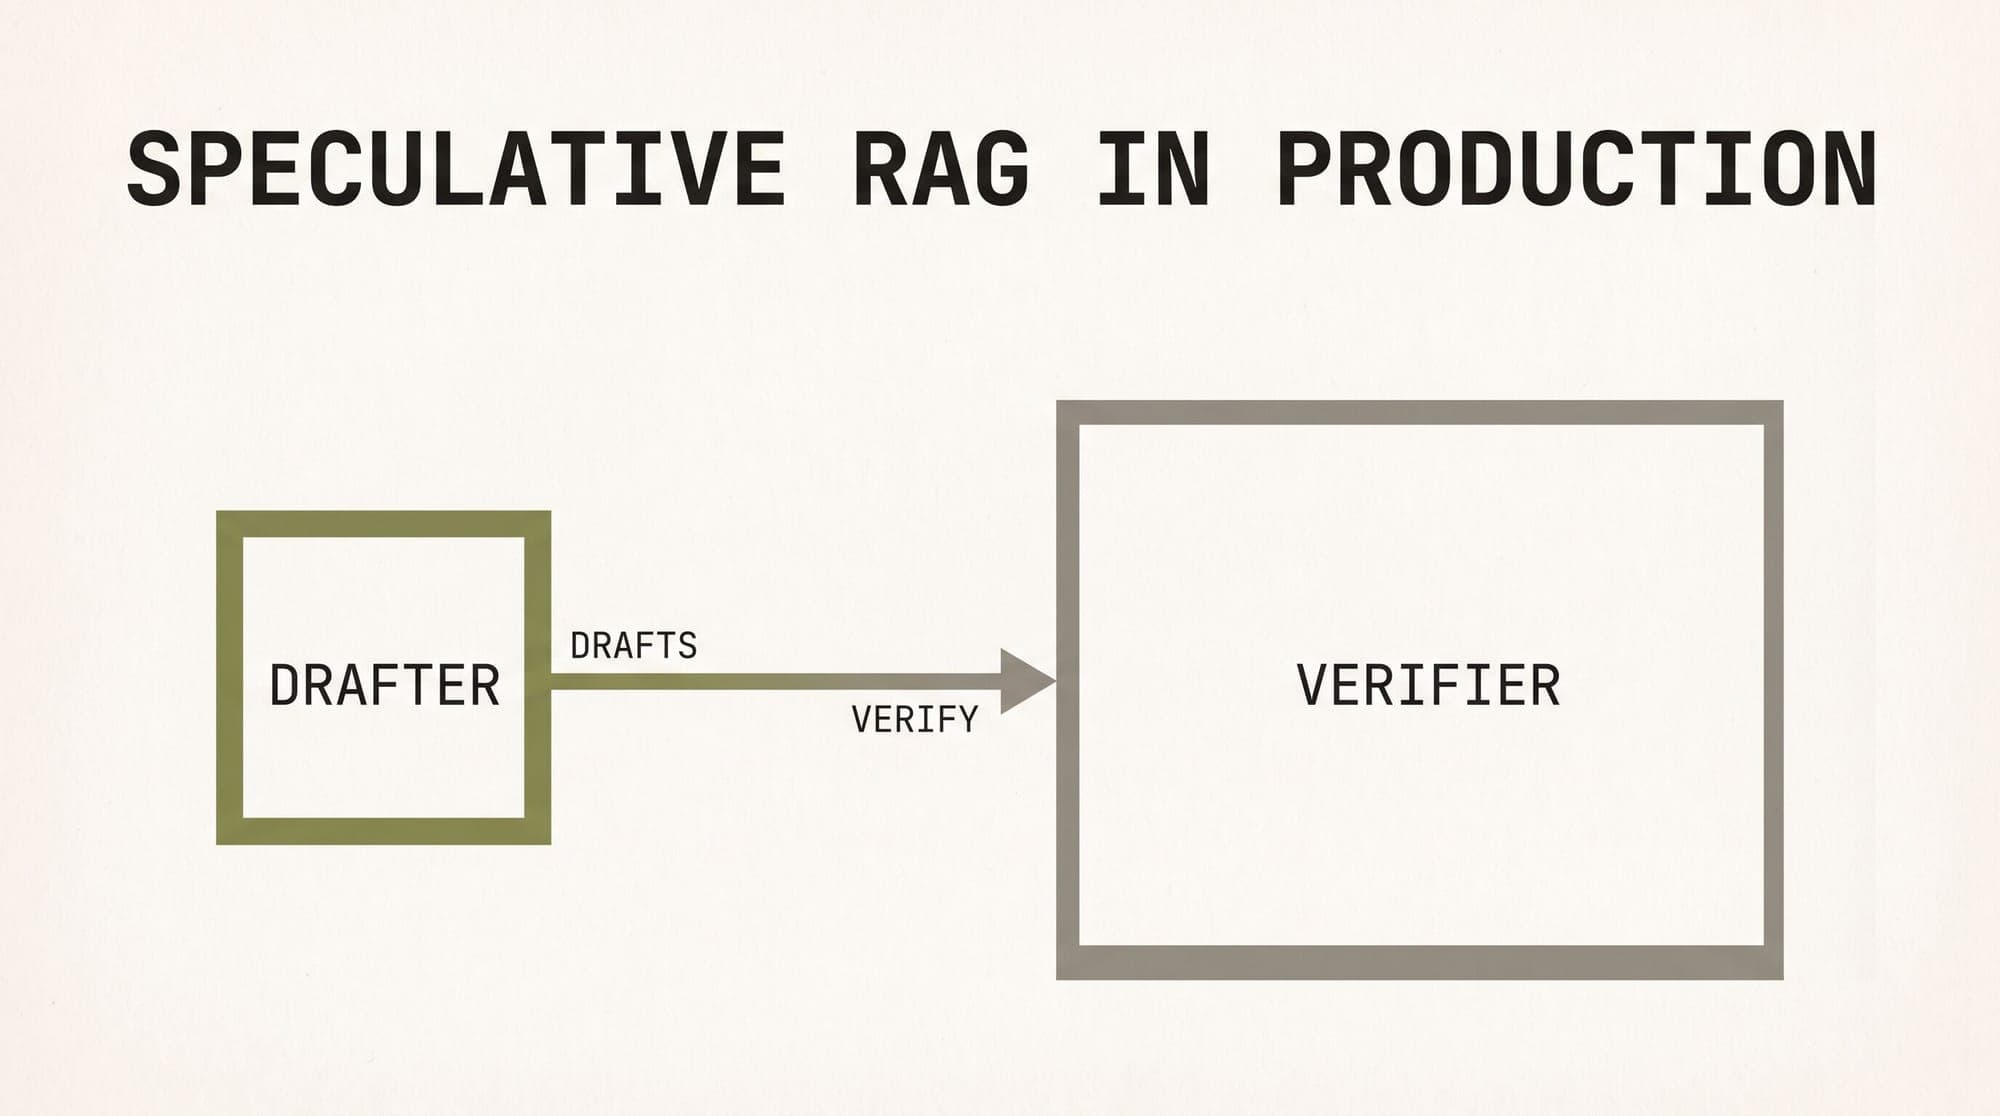
  9. Speculative RAG in Production: Drafting, Verification, and Systems-Level Scheduling

    Speculative RAG in Production: Drafting, Verification, and Systems-Level Scheduling RAG pipelines have a latency problem. The standard pattern — retrieve, rerank, generate — chains three sequential stages. Retrieval is fast; reranking and generation are not. When a query fans out to dozens of chunks, the cross-encoder or LLM reranker becomes a bottleneck, and the generator sits idle waiting for the reranker to finish. Three recent papers attack this from different angles: Speculative RAG (Goog

    4 min read
  10. Batch Normalization: Mathematical Foundations, Gradient Smoothing Dynamics, and Why Sequence Models Adopted Layer Normalization

    Batch Normalization remains one of the most widely implemented algorithmic developments in the history of deep learning. Introduced by Sergey Ioffe and Christian Szegedy in their 2015 paper, Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift, the technique enabled stable training of deep feedforward networks and convolutional architectures at significantly higher learning rates. While initially designed for computer vision architectures such as ResNet a

    AI
    7 min read