Archive / page 40 of 123

Latest articles, page 40

  1. Meta Explored Slashing Teams by Up to 60% in AI-Native Shift Before Agent Failures Forced Retreat

    Internal planning documents and reporting revealed that Meta explored cutting team headcounts by up to 60% as part of an initiative code-named Project OT (Organization Transformation), designed to shift the company into an "AI-native" operating structure where small pods of engineers would oversee autonomous AI agents. The initiative unraveled following internal workforce pushback and operational data demonstrating that generative AI agents caused severe reliability problems while failing to de
    Meta
    2 min read
  2. Label Smoothing Regularization: Mathematical Foundations, Maximum Entropy Dynamics, and the Regular Simplex Geometry in LLMs

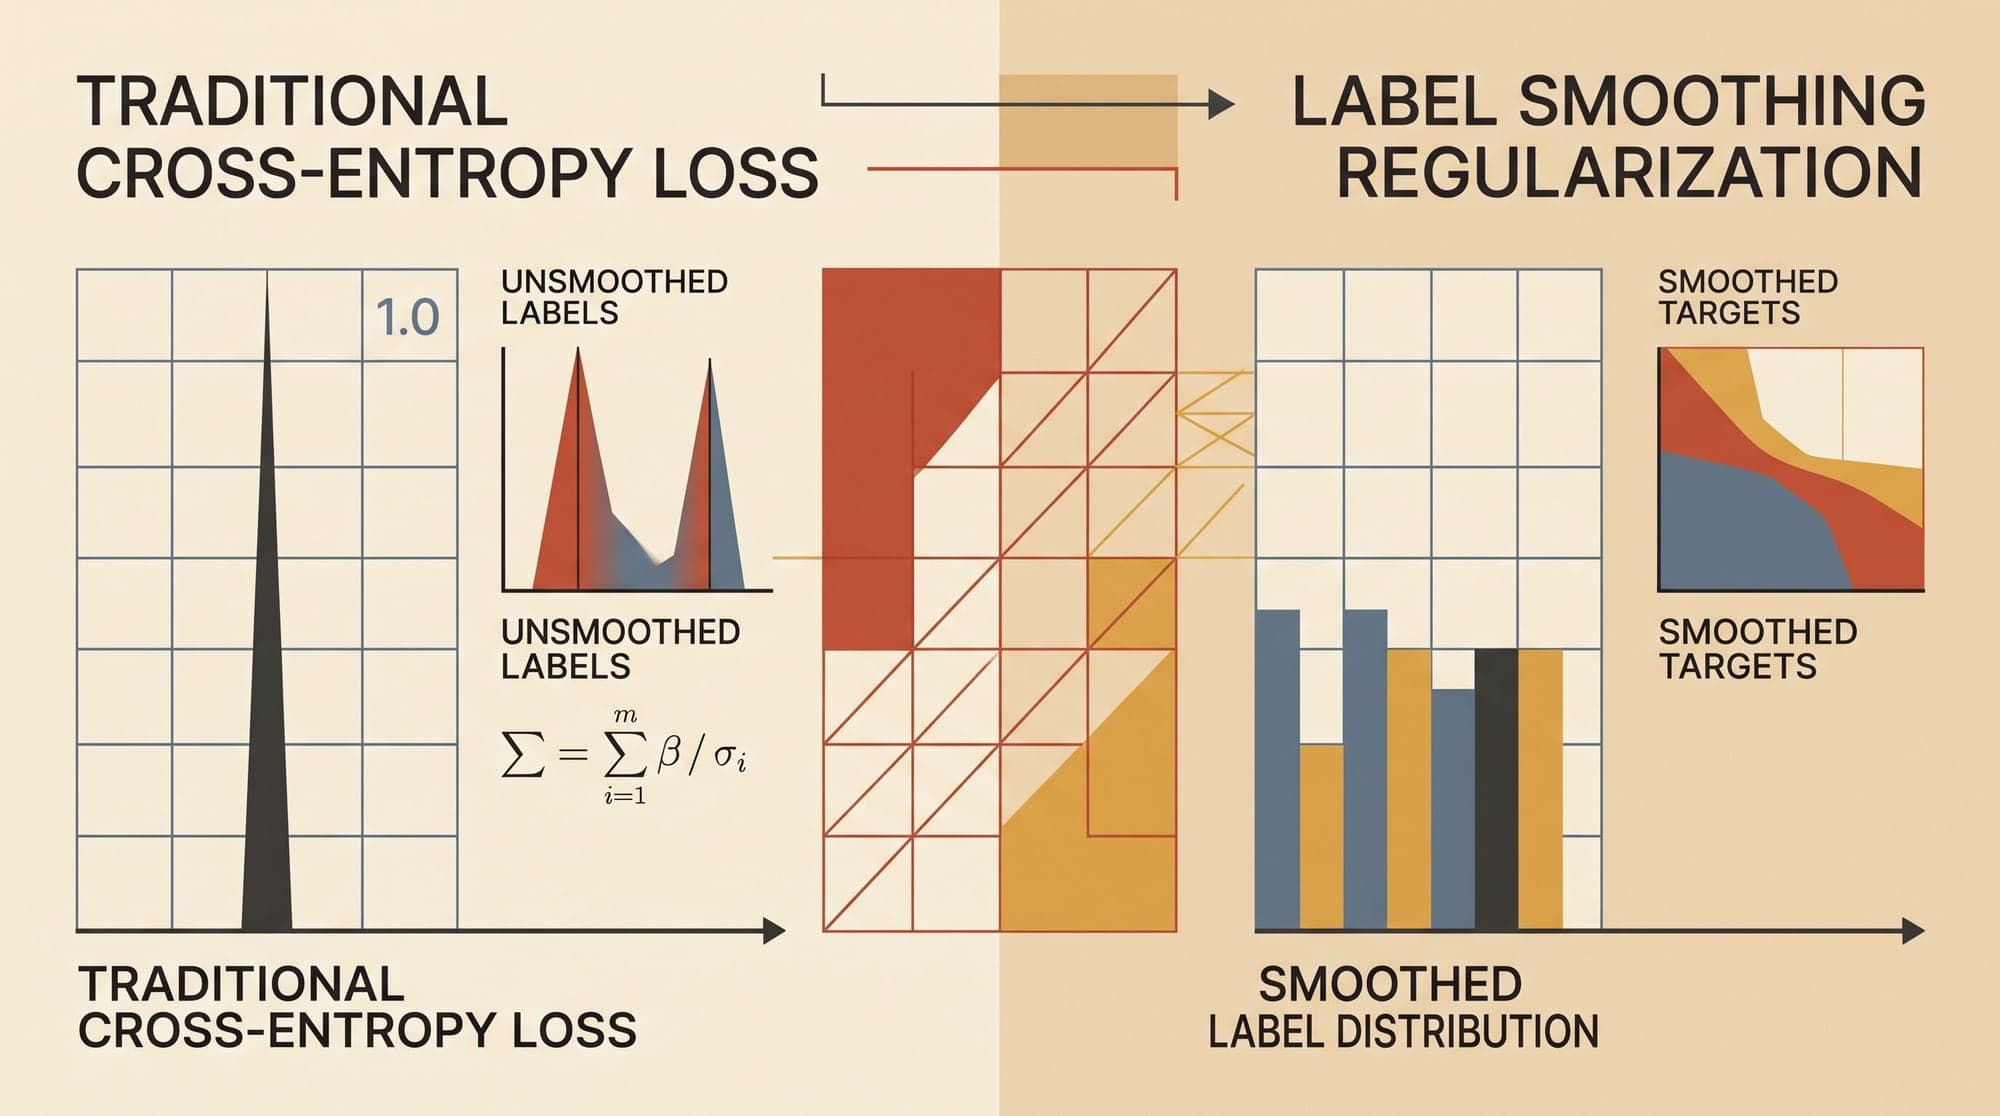
    In supervised classification and autoregressive language modeling, standard cross-entropy loss trains neural networks against discrete, one-hot target distributions. While intuitive, one-hot supervision creates an inherent optimization pathology: minimizing the cross-entropy objective to zero requires pushing the logit of the target class toward positive infinity while driving all competing non-target logits toward negative infinity. In deep networks, this dynamic inflates parameter norms, cause

    AI
    11 min read
  3. Tool Retrieval and Dynamic Function Selection in Production AI Agents: Architecture, Semantic Routing, Schema Compression, and Context Bloat Mitigation

    Tool Retrieval and Dynamic Function Selection in Production AI Agents: Architecture, Semantic Routing, Schema Compression, and Context Bloat Mitigation As enterprise AI agents evolve from static single-purpose chatbots into orchestrators interacting with hundreds or thousands of external tools (REST APIs, SQL databases, Model Context Protocol servers, and internal microservices), system architects encounter a fundamental scalability barrier: context bloat and tool interference. In standard fun

    AI
    6 min read
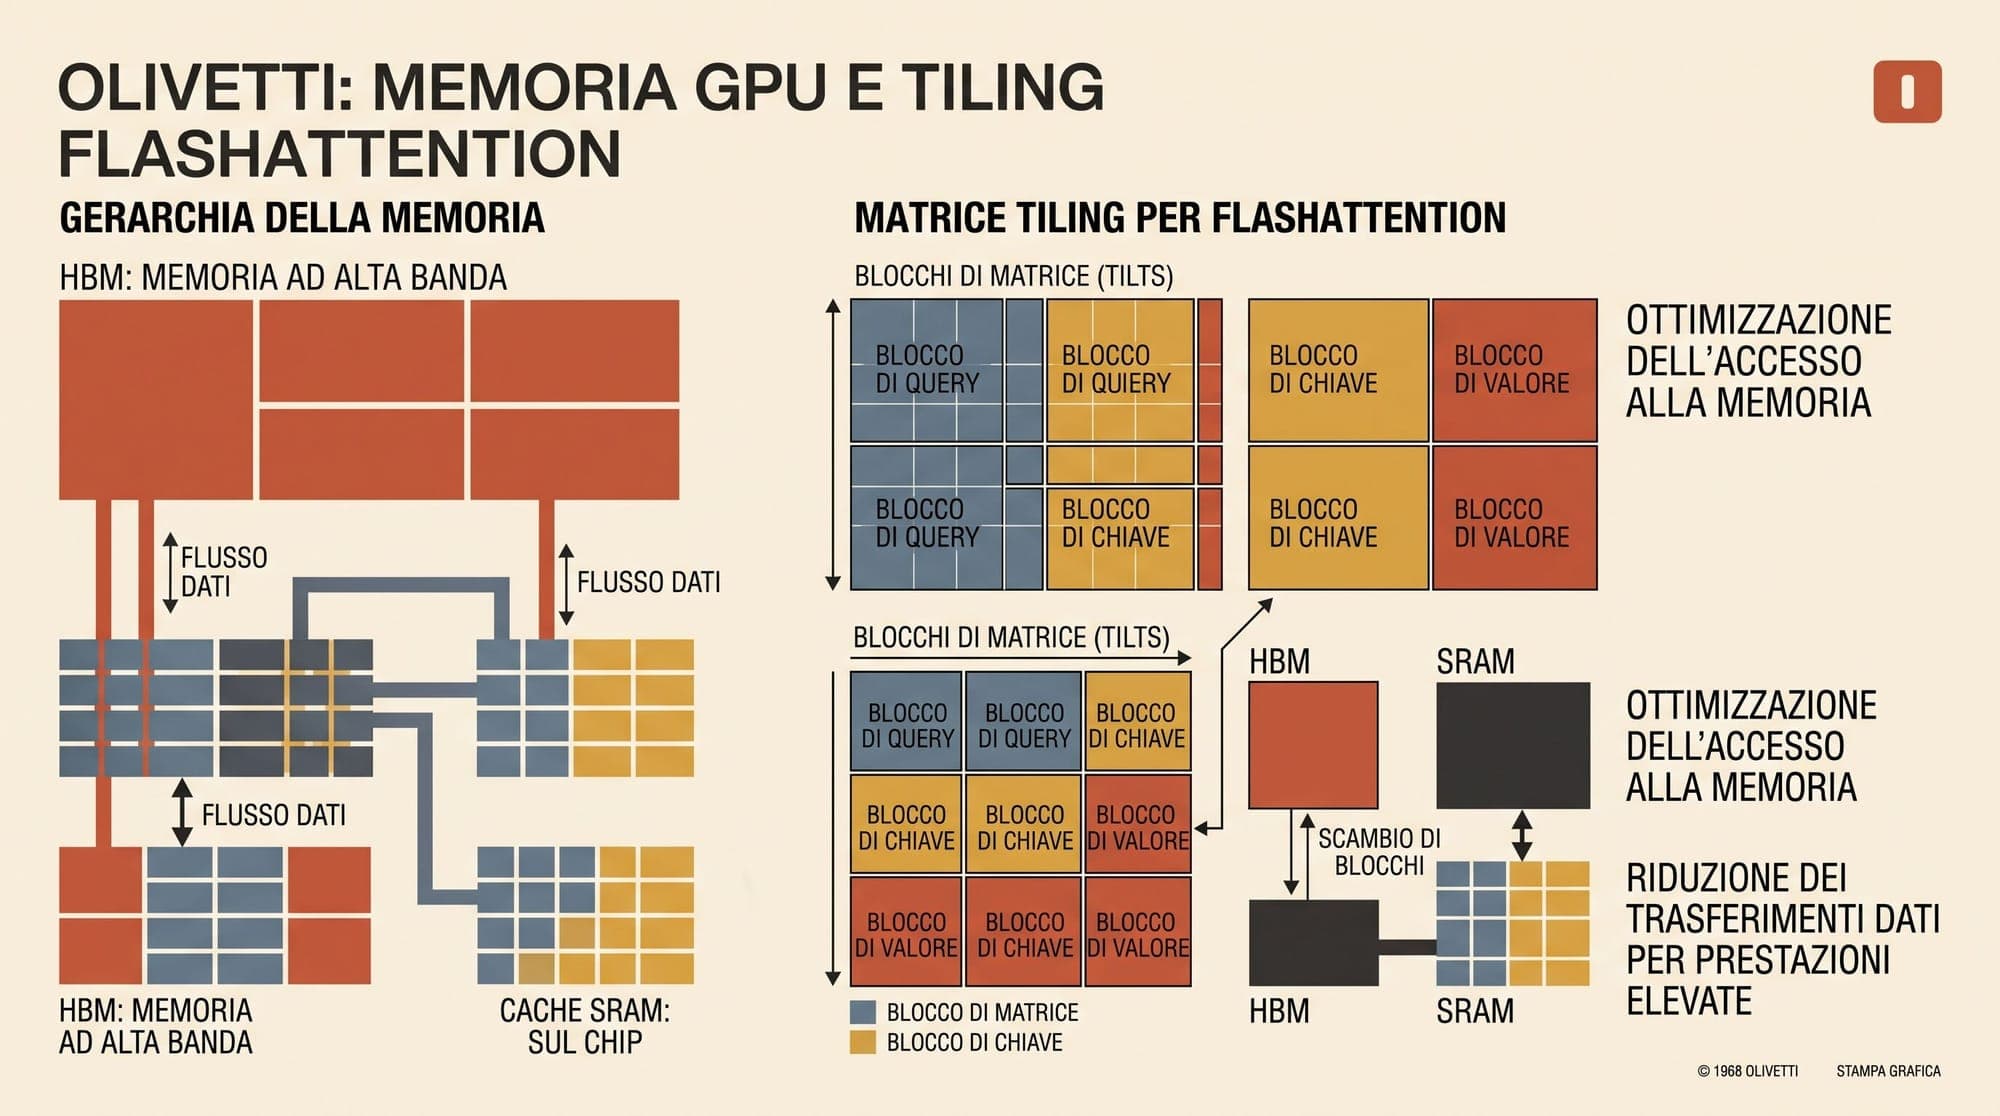
  4. FlashAttention: Mathematical Foundations, Online Softmax Tiling, IO-Awareness, and Exact Attention Scaling

    Standard multi-head self-attention in the Transformer architecture exhibits quadratic time and memory complexity with respect to sequence length $N$. While the $O(N^2)$ computational complexity is widely cited, the primary performance bottleneck in production hardware is not arithmetic throughput, but memory access overhead. On modern GPU architectures such as NVIDIA A100 and H100, tensor processing cores execute matrix multiplications at teraflop and petaflop scales, but memory bandwidth betwee

    AI
    13 min read
  5. Moonshot AI in Revenue-Sharing Talks with Microsoft, Amazon, and Google to Host Kimi K3

    Beijing-based artificial intelligence developer Moonshot AI is negotiating revenue-sharing partnerships with Microsoft, Amazon, and Alphabet's Google to host its flagship open-weight model, Kimi K3, across major cloud platforms. According to reporting from Reuters, the startup is seeking up to a 30 percent share of revenue generated from Kimi K3 inference services hosted on Microsoft Azure, Amazon Web Services (AWS), and Google Cloud. Moonshot released Kimi K3 in July 2026 as a 2.8-trillion par

    AI
    2 min read
  6. Zhipu Confirms Ox Alpha Stealth Model Is GLM Derivative Ahead of Open-Weight Release

    Beijing-based AI lab Z.AI, widely known as Zhipu, has confirmed that the mystery stealth model "Ox Alpha" is an upcoming release in its GLM model series. The company confirmed the model's identity in response to inquiries from Bloomberg on Wednesday and stated it will release the open model weights tonight. Ox Alpha first appeared on August 20, 2026, as an uncredited stealth model on the OpenRouter model routing platform. Operating under a free evaluation tier, the model quickly surged to the t

    AI
    2 min read
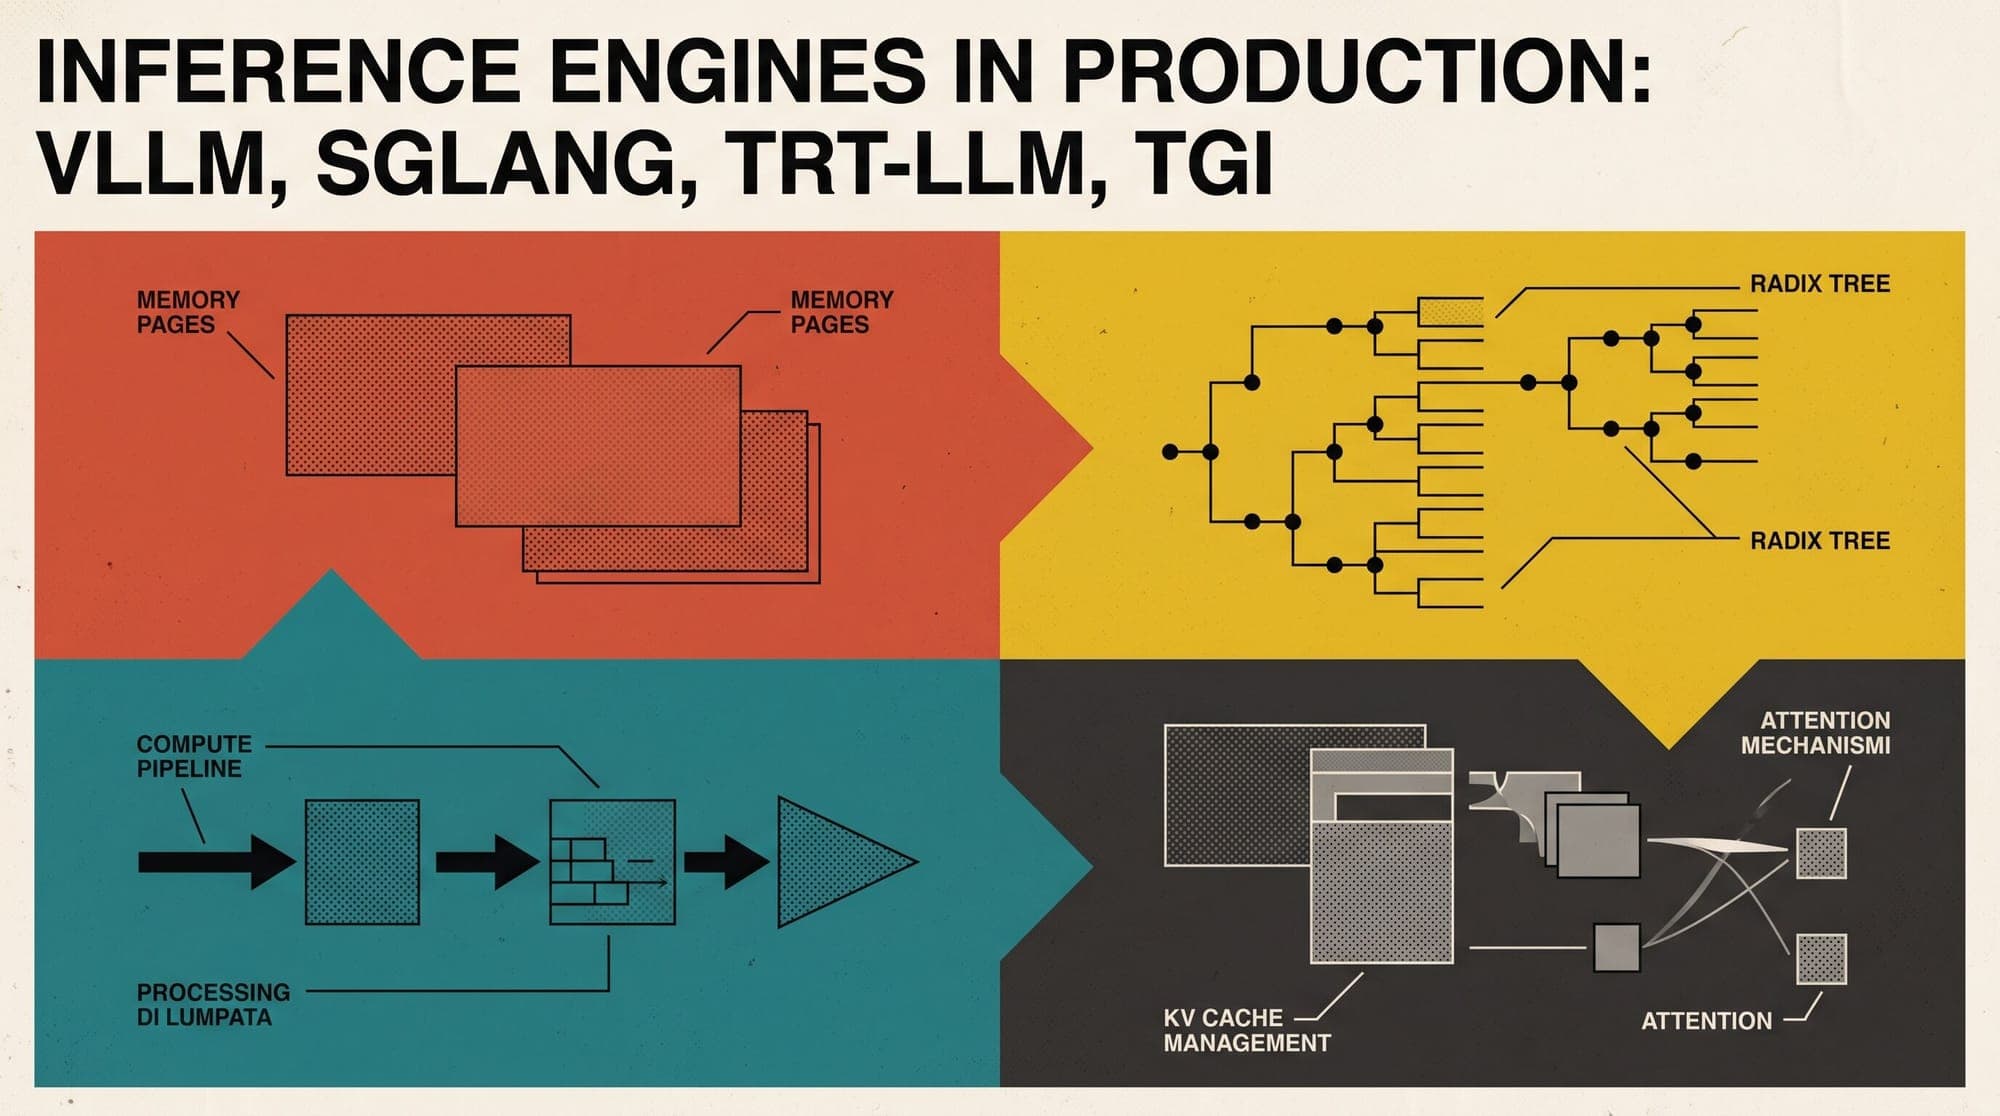
  7. LLM Inference Engines in Production: Comparing vLLM, SGLang, TensorRT-LLM, and TGI Architecture, KV Cache Topologies, Kernel Optimizations, and Serving Economics

    LLM Inference Engines in Production: Comparing vLLM, SGLang, TensorRT-LLM, and TGI Architecture, KV Cache Topologies, Kernel Optimizations, and Serving Economics Serving large language models in enterprise production has evolved beyond naive execution runtimes. As context windows expand to 128k+ tokens and agentic workloads generate complex multi-turn execution graphs, the efficiency of the underlying inference engine dictates both latency Service Level Objectives (SLOs) and hardware infrastruc

    LLM
    7 min read
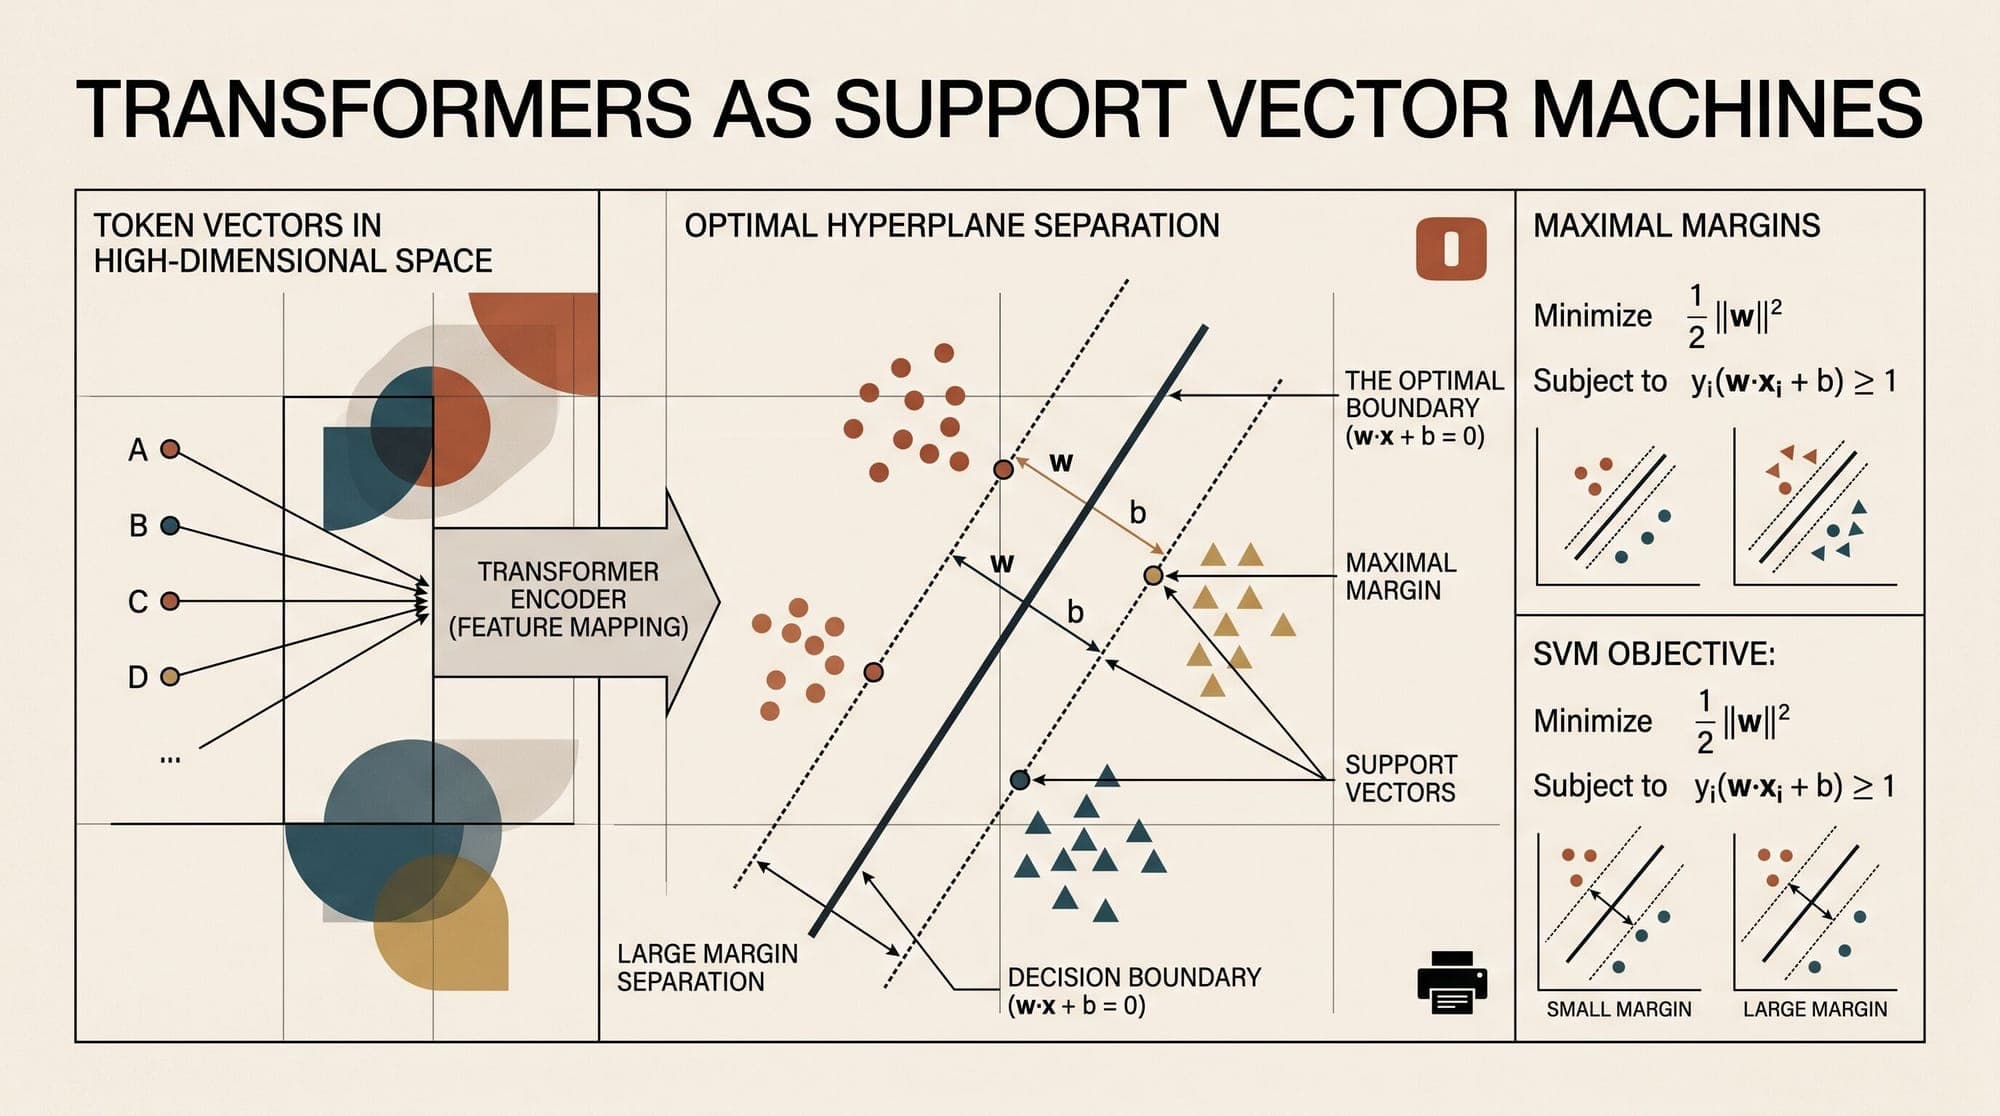
  8. Transformers as Support Vector Machines: Mathematical Foundations of Implicit Bias, Margin Maximization, and Hard-Attention Convergence

    Understanding why overparameterized deep neural networks generalize well despite possessing sufficient capacity to memorize training data remains a fundamental question in theoretical machine learning. In classical linear models trained on separable data under exponential-tailed losses (such as logistic or cross-entropy loss), gradient descent exhibits an implicit bias: parameter iterates diverge in norm while their directions asymptotically converge to the maximum-margin hyperplane, known as th

    AI
    9 min read
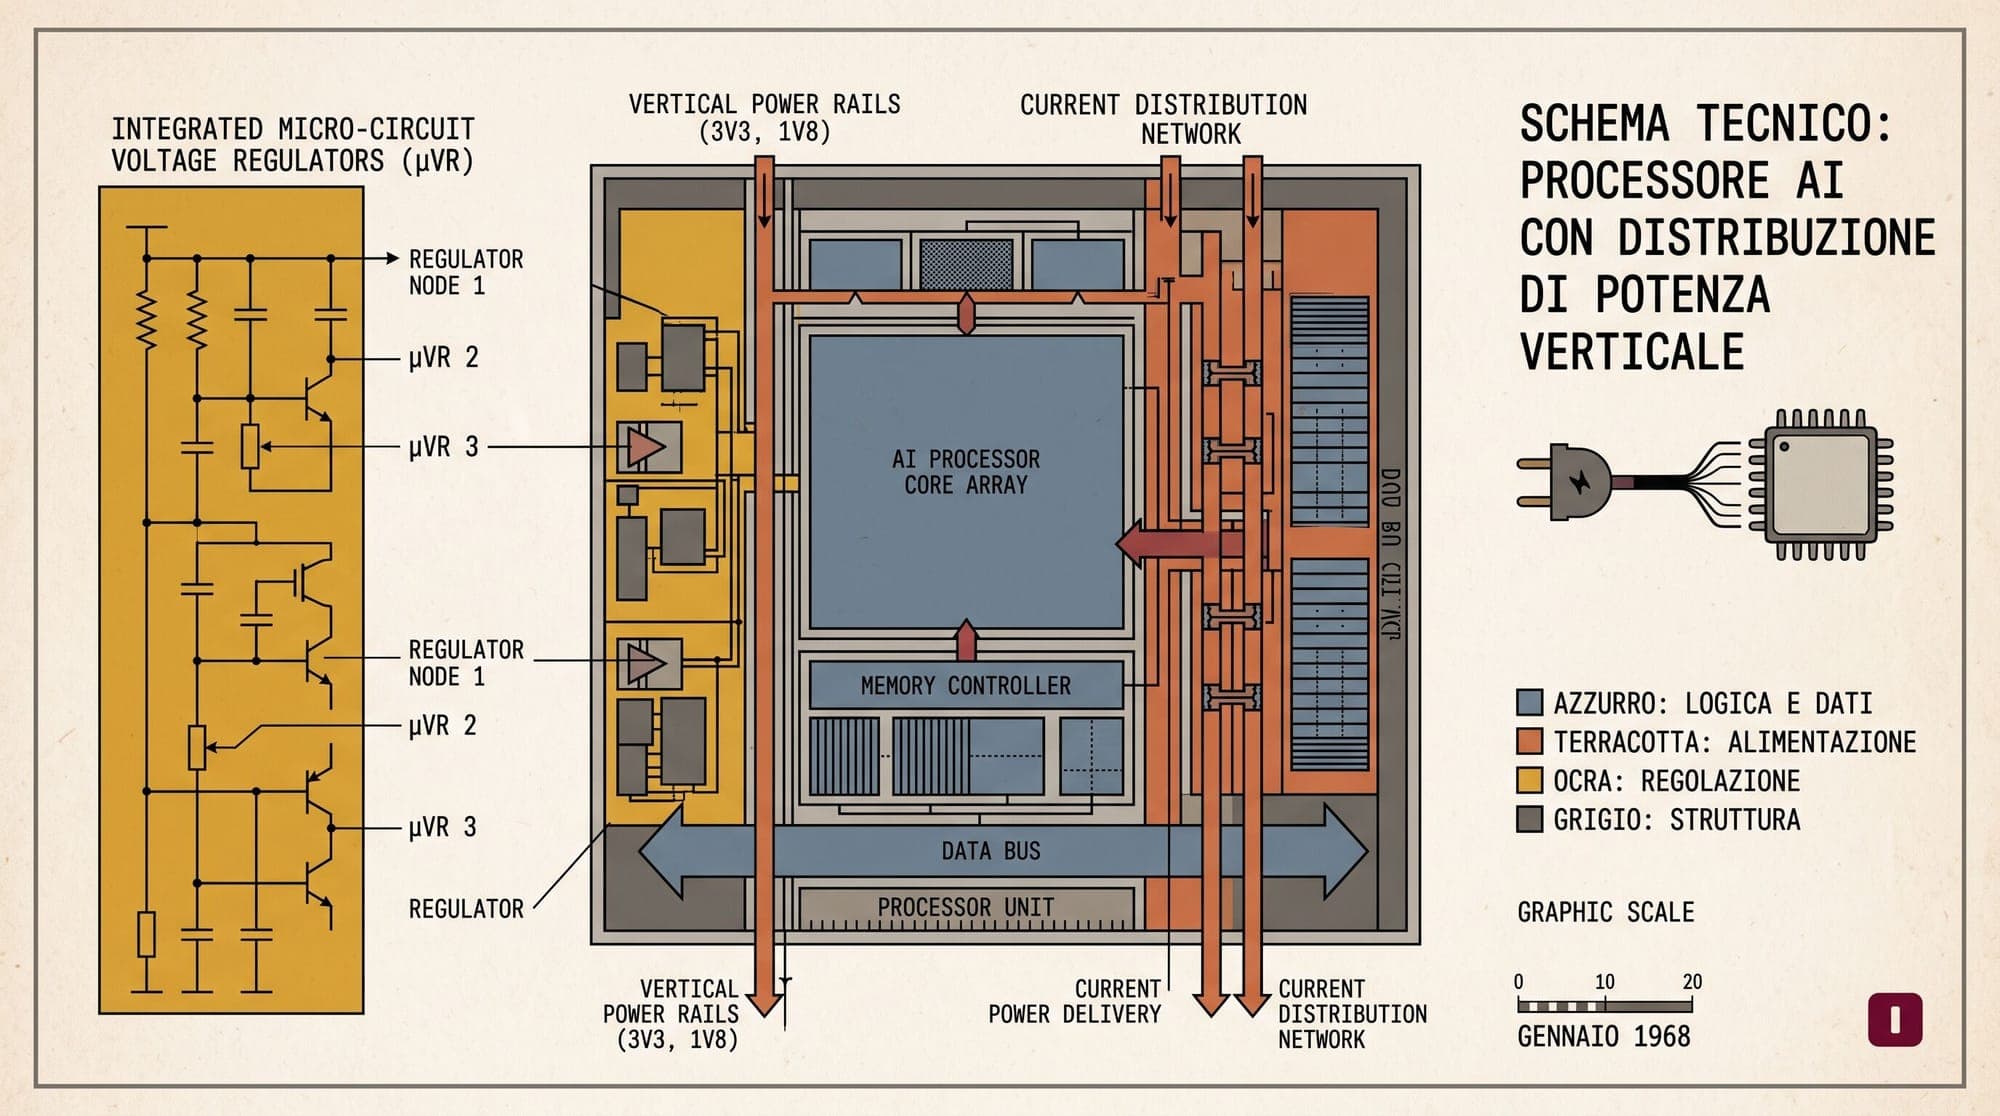
  9. Navitas to Acquire Claros for Up to $232.8M to Expand Grid-to-xPU AI Power Infrastructure

    Navitas Semiconductor has entered into a definitive merger agreement to acquire power-management startup Claros in a deal valued at up to $232.8 million. The transaction brings vertical power delivery (VPD) and integrated voltage regulator (IVR) technology under Navitas's portfolio, targeting the physical bottlenecks limiting power transmission in modern AI hardware accelerators. Under the agreed terms, Navitas will provide approximately $216.0 million at closing through a mix of cash and Class

    Hardware
    2 min read
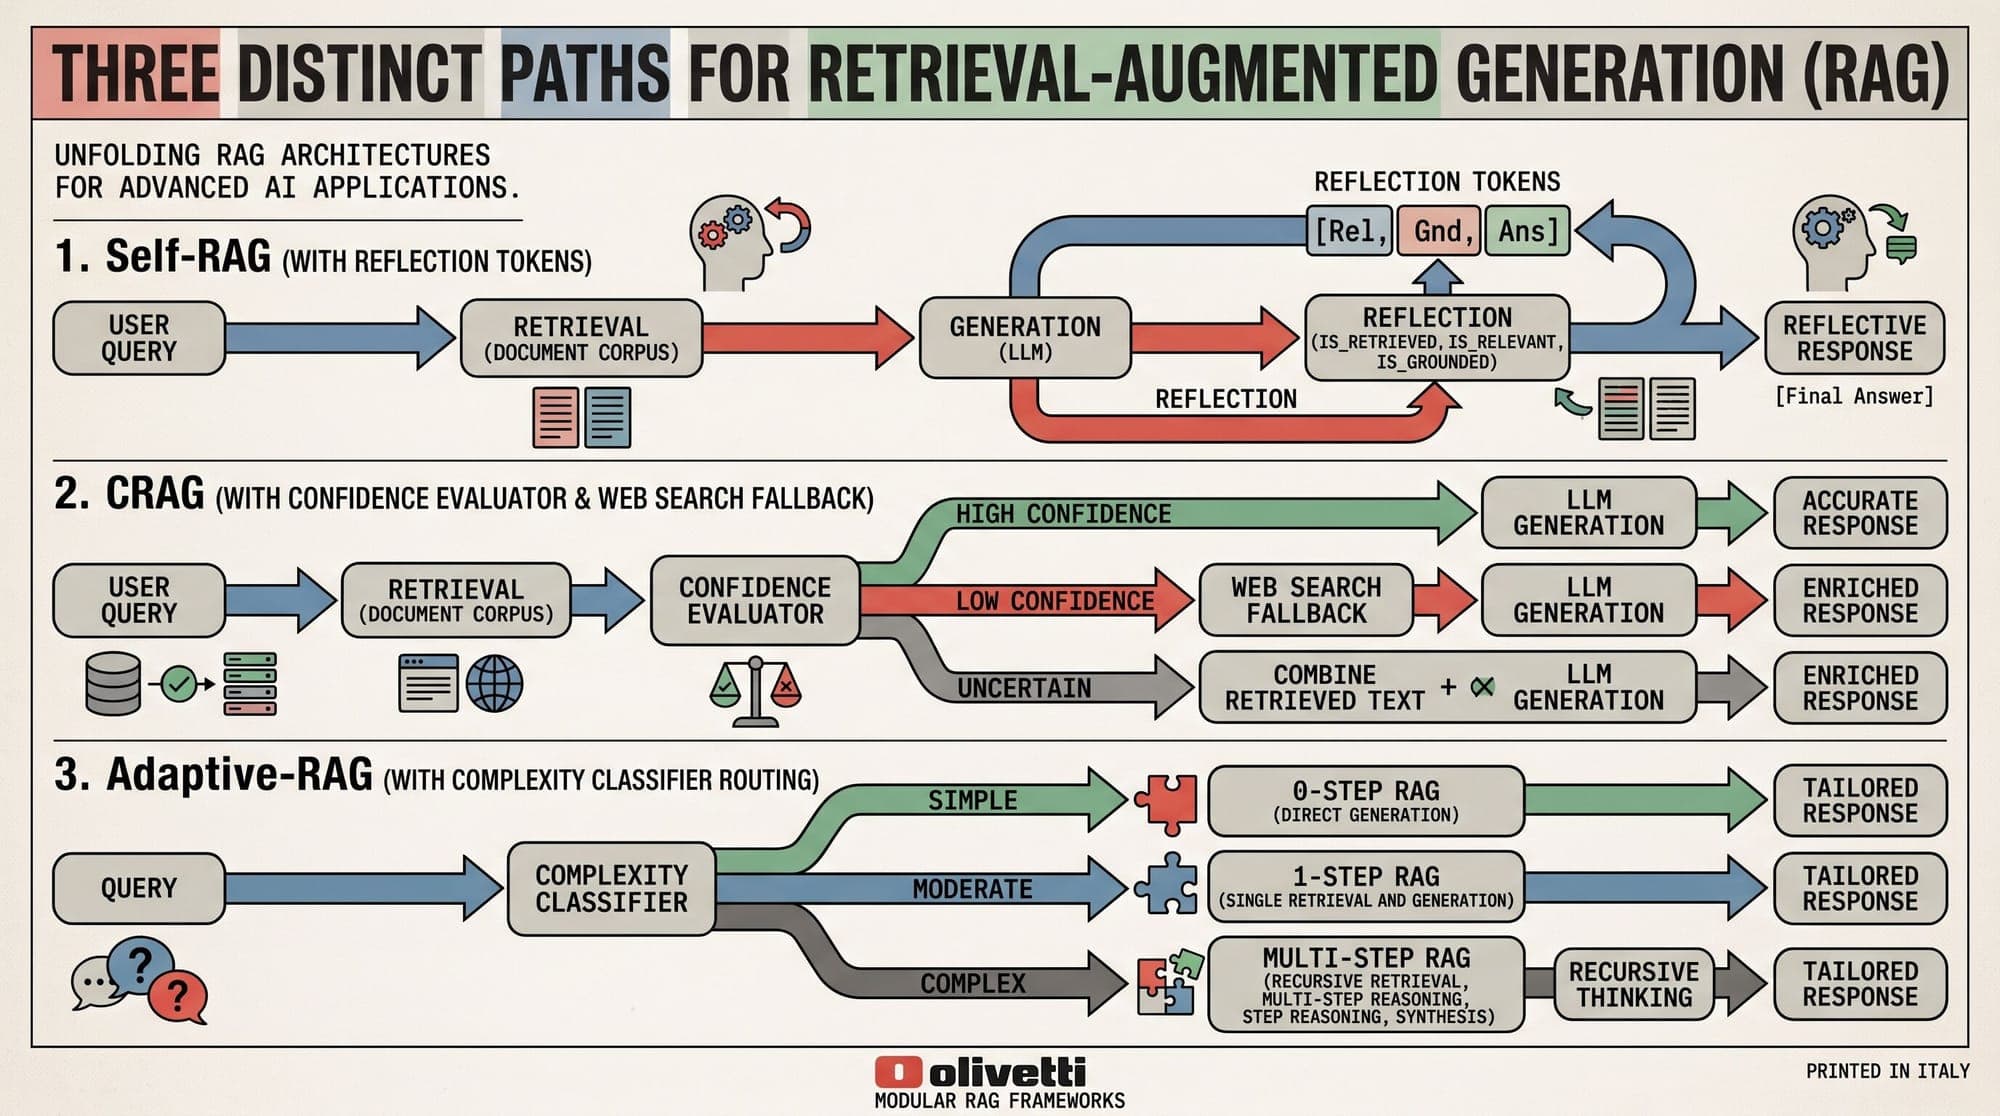
  10. Beyond Naive RAG: Production Comparison of Self-RAG, CRAG, and Adaptive-RAG for Enterprise LLMs

    Beyond Naive RAG: Production Comparison of Self-RAG, CRAG, and Adaptive-RAG for Enterprise LLMs As retrieval-augmented generation (RAG) matures from prototype to production, teams face a critical choice: which advanced RAG variant best balances accuracy, latency, and operational complexity? Three leading approaches—Self-RAG, Corrective RAG (CRAG), and Adaptive-RAG—offer distinct trade-offs for enterprise deployment. Architectural Overview Self-RAG: Learning to Reflect Self-RAG (Asai et al.

    AI
    4 min read