Archive / page 44 of 123

Latest articles, page 44

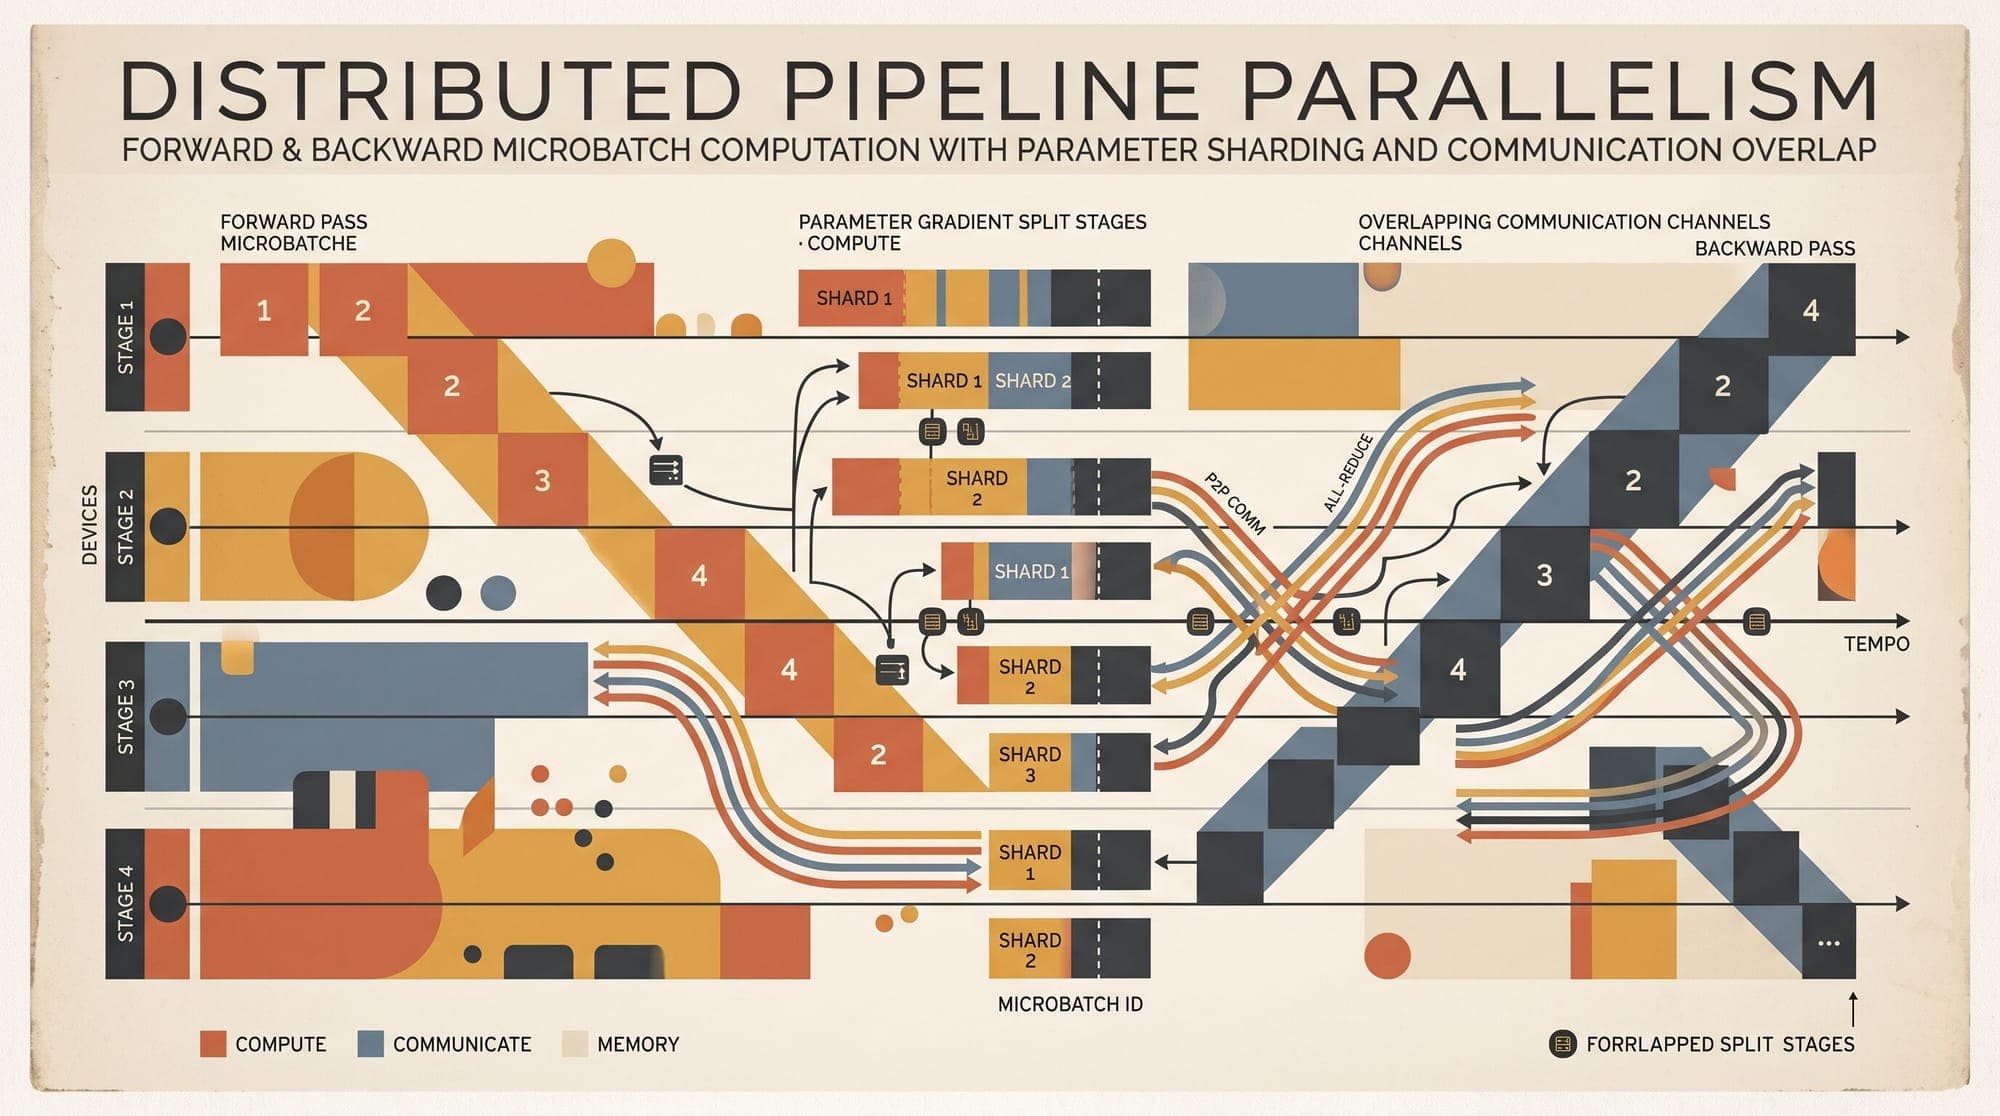
  1. Pipeline Parallelism in Production LLM Training: Comparing 1F1B, Interleaved 1F1B, Zero-Bubble, and DualPipe Schedules

    Pipeline Parallelism in Production LLM Training: Comparing 1F1B, Interleaved 1F1B, Zero-Bubble, and DualPipe Schedules Training modern large language models spanning hundreds of billions of parameters requires distributing model layers across multiple compute nodes. While Tensor Parallelism (TP) partitions individual matrix multiplications across GPUs within a single node, its reliance on high-frequency, all-reduce communications limits its practical scaling to the high-bandwidth domain of NVLi
    AI
    8 min read
  2. Anthropic Launches $5M Grant Program to Fund AI Wellbeing Evaluations and Benchmarks

    Anthropic has launched a $5 million grant initiative to support independent development of open-source benchmarks and evaluation harnesses measuring the impact of artificial intelligence systems on user wellbeing. The program will supply research teams with direct financial grants, subsidized API access to Claude models, and technical support from Anthropic's Safeguards team. All evaluation frameworks, datasets, and grading methodology developed under the grant program will be released publicly

    Anthropic
    2 min read
  3. OpenAI Introduces Admin Plugin for ChatGPT Work and Codex to Automate Workspace Governance

    OpenAI has released the Admin plugin for ChatGPT Work and Codex, embedding enterprise workspace management, user provisioning, permission audits, and spending controls directly into chat conversations. The plugin exposes Admin Console functionality through permission-scoped tools, allowing administrators to execute diagnostic queries and administrative actions without toggling across external consoles or building bespoke scripting pipelines. Conversational Workspace Administration Managing en

    OpenAI
    2 min read
  4. BitNet b1.58: Mathematical Foundations of 1.58-Bit Ternary Quantization, Absmean Scaling, and Multiplication-Free LLM Architectures

    Standard Large Language Models (LLMs) rely on 16-bit floating-point (FP16 or BF16) matrix multiplications for both pre-training and autoregressive inference. While post-training quantization techniques (such as GPTQ, AWQ, and dynamic FP8/INT4 scaling) compress weights after training, they often introduce perplexity degradation at ultra-low bitwidths ($<4$ bits) or still require floating-point dequantization at runtime. Quantization-aware pre-training architectures directly tackle this computati

    AI
    6 min read
  5. Test-Time Compute and Inference Search in Production: Comparing Best-of-N, Monte Carlo Tree Search, PRM-Guided Beam Search, and Dynamic Budget Allocation Architecture, Token Economics, and Serving Latency

    In standard production Large Language Model (LLM) deployments, generation compute is fixed: a prompt is processed during prefill, and the model generates an answer via greedy autoregressive decoding or low-temperature sampling. Under this paradigm, accuracy on complex reasoning, mathematical derivation, theorem proving, and code synthesis is bounded by the model parameter count and training data distributions. Recent empirical work demonstrates that scaling inference-time compute can achieve pe

    AI
    11 min read
  6. Gatik Raises $200M Series D to Scale Autonomous Middle-Mile Trucking Fleet

    Autonomous middle-mile logistics startup Gatik has raised $200 million in a Series D funding round to accelerate the deployment of its driverless commercial freight fleet. The capital brings Gatik's total institutional funding to approximately $500 million since its founding in 2019. The funding round was co-led by Qatar Investment Authority (QIA) and Koch Disruptive Technologies (KDT), with participation from Millennium Management, ARK Invest, and Intact Private Capital. Gatik did not disclose

    Autonomous Vehicles
    2 min read
  7. Gamma Acquires AI Design Startup Lica to Establish Multimodal Research Lab

    AI presentation platform Gamma has acquired design startup Lica to establish an internal research division focused on multimodal communication and automated layout models. The deal brings Lica co-founders Priyaa Kalyanaraman and Purvanshi Mehta to Gamma to head the new research laboratory. Gamma reached a $2.1 billion valuation in November 2025 following a $68 million funding round, scaling its user base to more than 100 million accounts. The platform allows users to generate presentations, doc

    AI
    1 min read
  8. Context Parallelism in Production: Comparing DeepSpeed Ulysses, Megatron Sequence Parallelism, Ring Attention, and Unified Sequence Parallelism (USP) Architecture, Communication Overhead, and Scale-Out Economics

    Scaling context windows in Large Language Models (LLMs) from 8,192 tokens to 128k, 256k, and 1M tokens introduces severe memory and compute constraints. Standard Data Parallelism (DP) duplicates entire model activations per sequence, failing when a single sequence exceeds GPU VRAM. Tensor Parallelism (TP) splits weight matrices across GPUs, but scaling TP beyond a single 8-GPU node degrades throughput due to high-frequency, low-latency cross-GPU collective communications. Pipeline Parallelism (P

    AI
    10 min read
  9. Anthropic Unifies Memory Across Claude Chat and Cowork Sessions

    Anthropic has updated its architecture to unify the memory systems powering Claude chat and Claude Cowork, allowing context and user preferences established during conversational sessions to persist directly into workspace tasks. The update addresses a common friction point in AI workflow orchestration, where users previously had to manually rebrief agentic workspaces on project context already established in conversational threads. Real-Time In-Session Memory Extraction Prior iterations of C

    AI
    2 min read
  10. LLM Observability in Production: OpenTelemetry GenAI Semantic Conventions vs. OpenInference, Distributed Trace Propagation Across Multi-Agent Graphs, and High-Throughput Sampling Economics

    Production large language model (LLM) architectures have transitioned from isolated completion endpoints to complex, distributed directed acyclic graphs (DAGs). Modern AI systems incorporate multi-agent orchestration, iterative tool execution, vector retrieval pipelines, and speculative decoding loops. Operating these workloads at enterprise scale exposes critical observability gaps that traditional application performance monitoring (APM) tools cannot address. Standard request-response APM metr

    AI
    7 min read