Subscribe
Topic

Vision Transformers

Self-supervised training methods for vision transformers. Posts explain DINO, which learns from momentum teachers with centering and sharpening, and Masked Autoencoders, which learn by reconstructing heavily masked images.

Articles

1-2
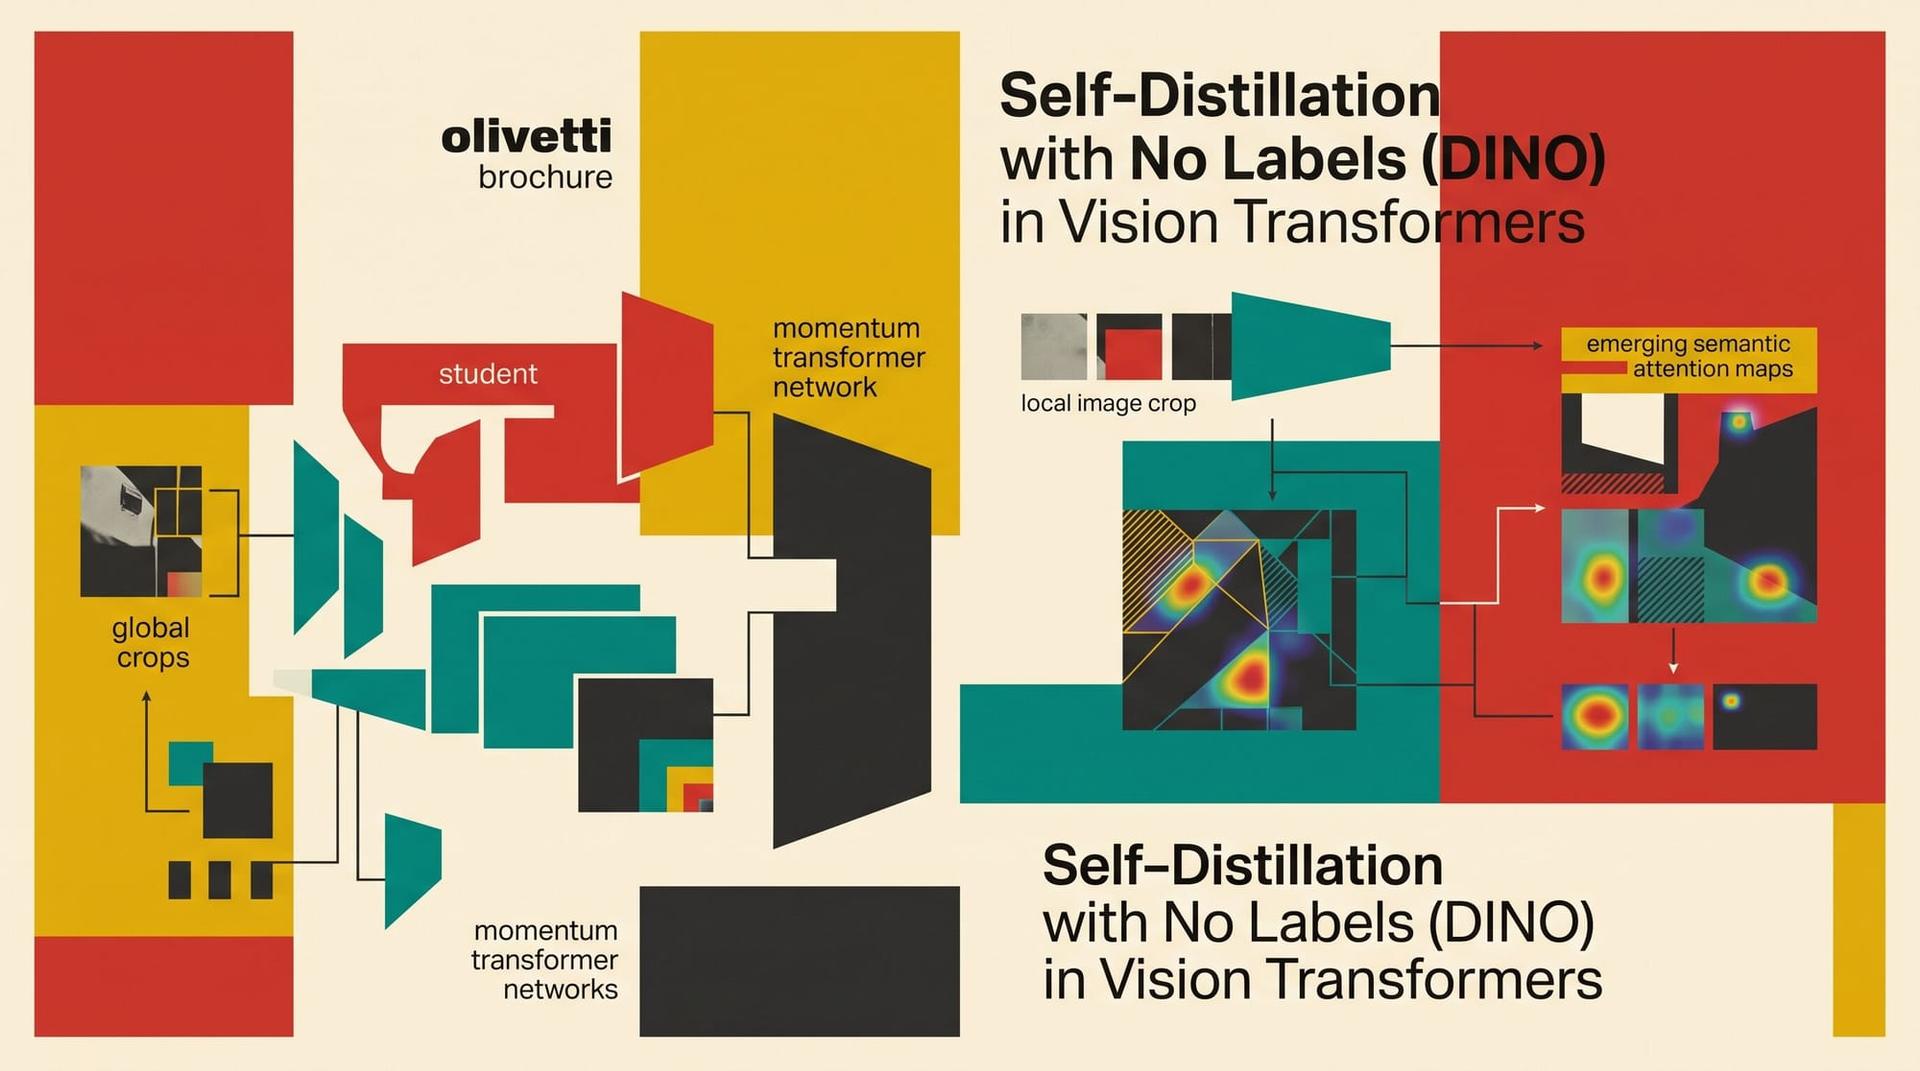
  1. Self-Distillation with No Labels (DINO): How Momentum Teachers, Centering, and Sharpening Emerge Semantic Attention in Vision Transformers

    Self-Distillation with No Labels (DINO): How Momentum Teachers, Centering, and Sharpening Emerge Semantic Attention in Vision Transformers When the Vision Transformer (ViT) was introduced by Dosovitskiy et al. in 2020, standard wisdom suggested that transformers required massive supervised corpora (such as JFT-300M) to overcome their lack of convolutional inductive biases. Unlike Convolutional Neural Networks (CNNs), which bake translation equivariance and local receptive fields directly into t
    AI
    8 min read
  2. Masked Autoencoders: How Asymmetric Encoders, High Masking Ratios, and Pixel Reconstruction Scaled Vision Transformers

    Masked Autoencoders: How Asymmetric Encoders, High Masking Ratios, and Pixel Reconstruction Scaled Vision Transformers Self-supervised pre-training transformed natural language processing through masked language modeling, popularized by BERT (Devlin et al., 2018). By hiding a subset of input tokens and training a bidirectional Transformer to predict the missing words from context, models learned rich, generalizable linguistic representations without manual annotations. Adapting this masked pre

    AI
    11 min read