Archive / page 31 of 50

Latest articles, page 31

  1. OpenAI Adds Native Alpha Transparency to GPT-Image-2 API

    OpenAI has added native transparent background generation to its GPT-Image-2 model via the developer API, enabling direct creation of PNG images with integrated alpha channels. The feature bypasses post-processing segmentation pipelines, allowing developers to generate isolated visual assets directly during the synthesis step. Direct Alpha Generation vs. Post-Processing Traditional visual asset pipelines rely on secondary background-removal models, such as semantic segmentation masks or matti
    AI
    2 min read
  2. Jacobi and Lookahead Decoding: How Parallel Fixed-Point Iteration Accelerates Autoregressive Inference Without Draft Models

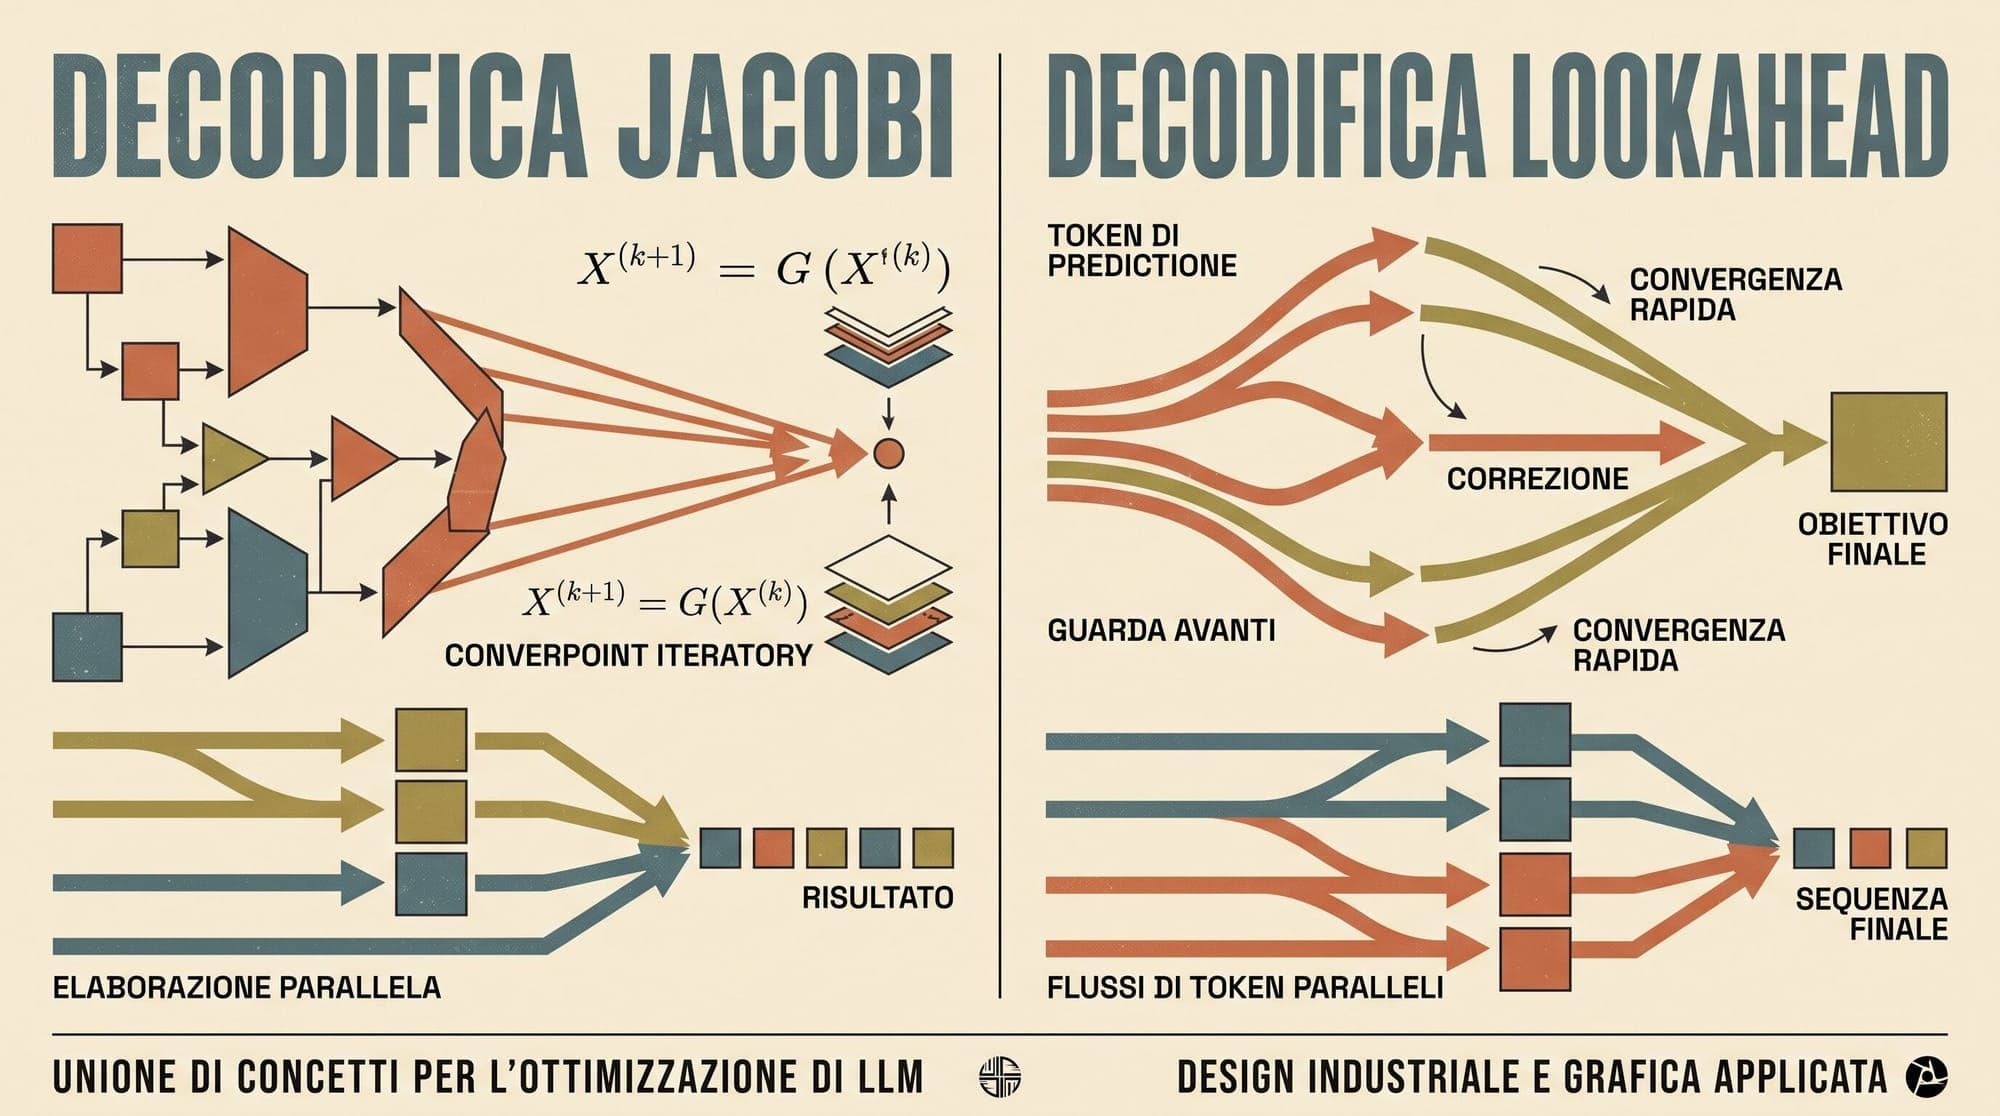
    Standard autoregressive generation in large language models operates as a strictly sequential process. To generate a sequence of $K$ tokens, an inference engine must execute $K$ successive forward passes through the network. In single-request serving regimes (batch size 1), each forward pass is heavily memory-bandwidth bound: the GPU must stream billions of model parameters from High Bandwidth Memory (HBM) into on-chip SRAM to process a single token, leaving tensor compute cores severely underut

    AI
    7 min read
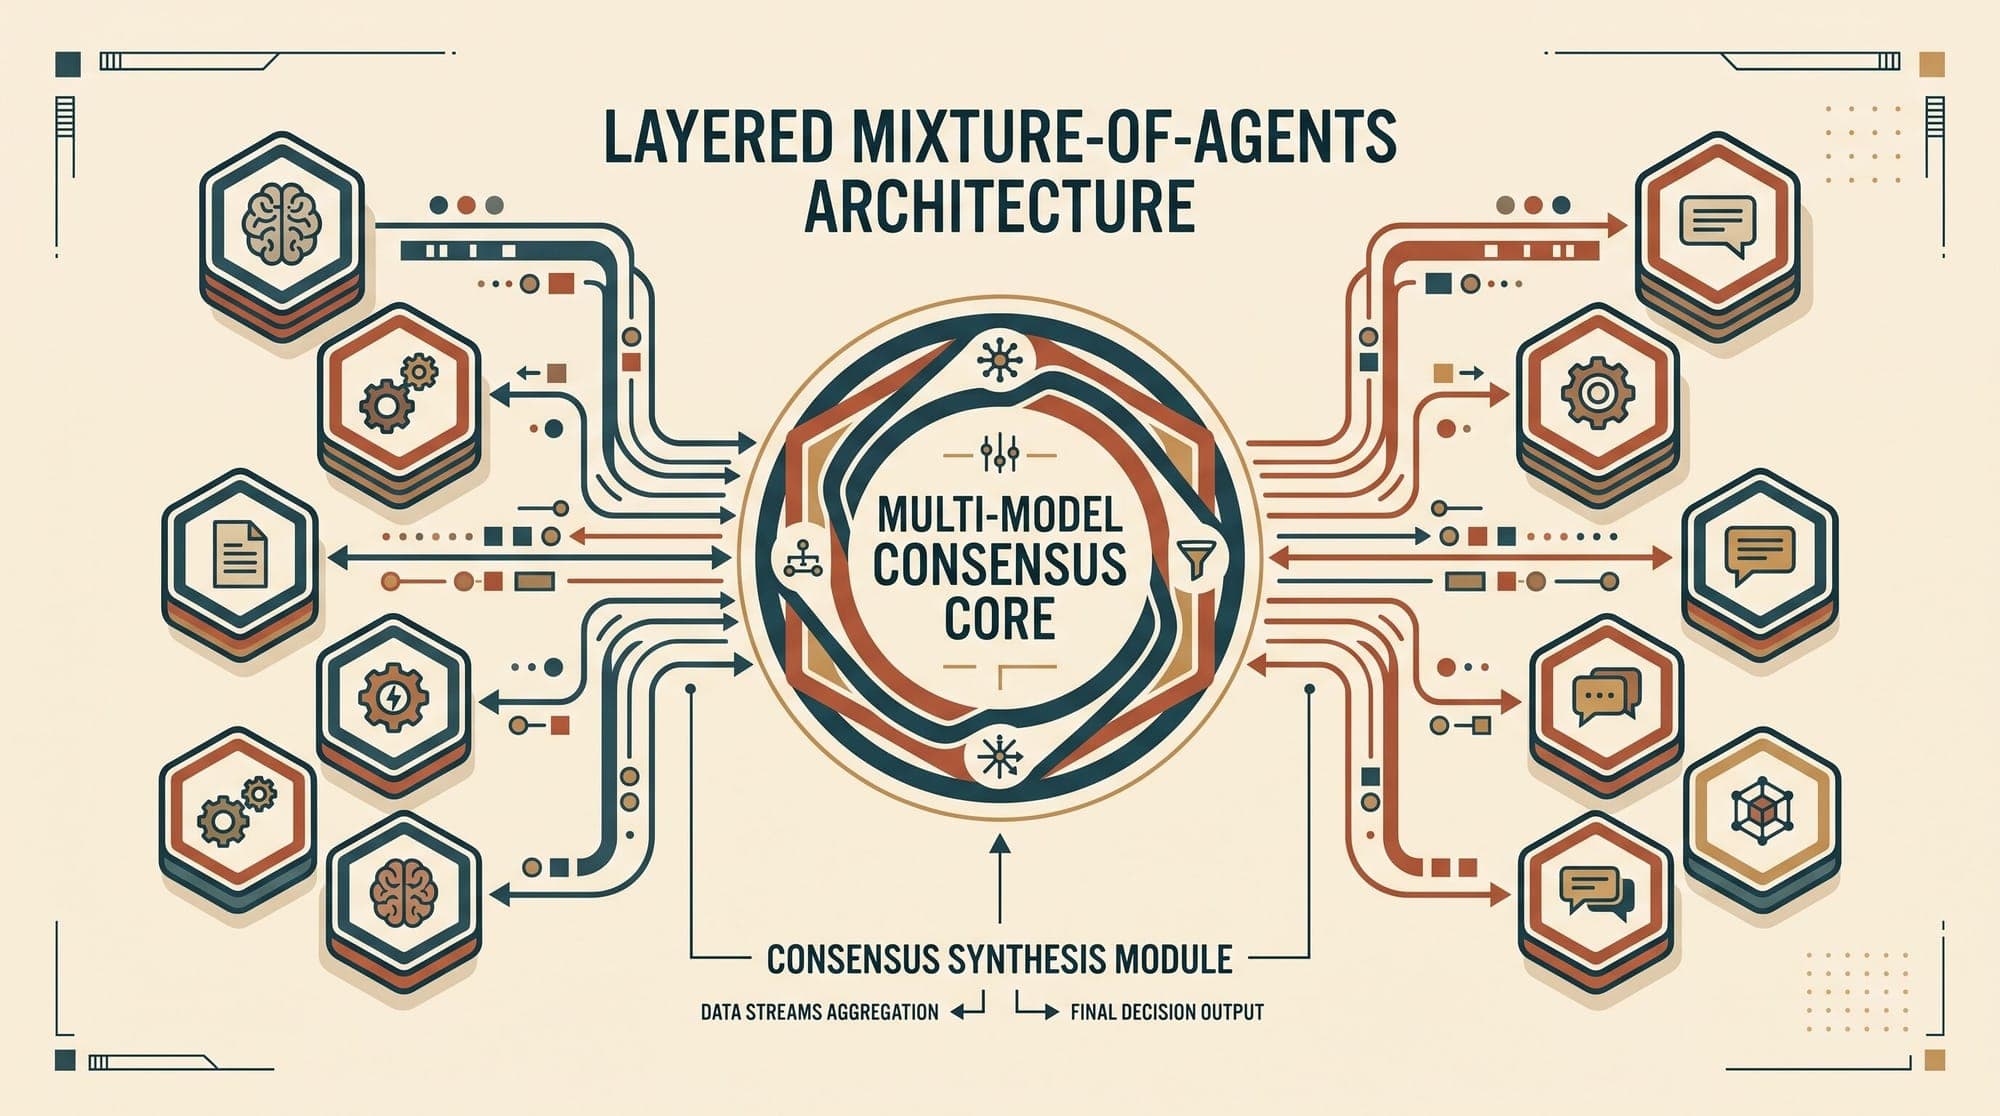
  3. Mixture-of-Agents and Multi-LLM Consensus in Production: Architecture, Layered Synthesis, Latency Budgets, and Cost Trade-Offs

    Single frontier models face physical and economic scaling limits. While model developers continue to scale pre-training compute and post-training reinforcement learning, individual foundation models still exhibit persistent failure modes: domain blind spots, subtle reasoning hallucinations, and inconsistent instruction adherence. To break past the performance ceilings of single models, production engineering teams increasingly deploy multi-model ensemble architectures. The most prominent of the

    AI
    7 min read
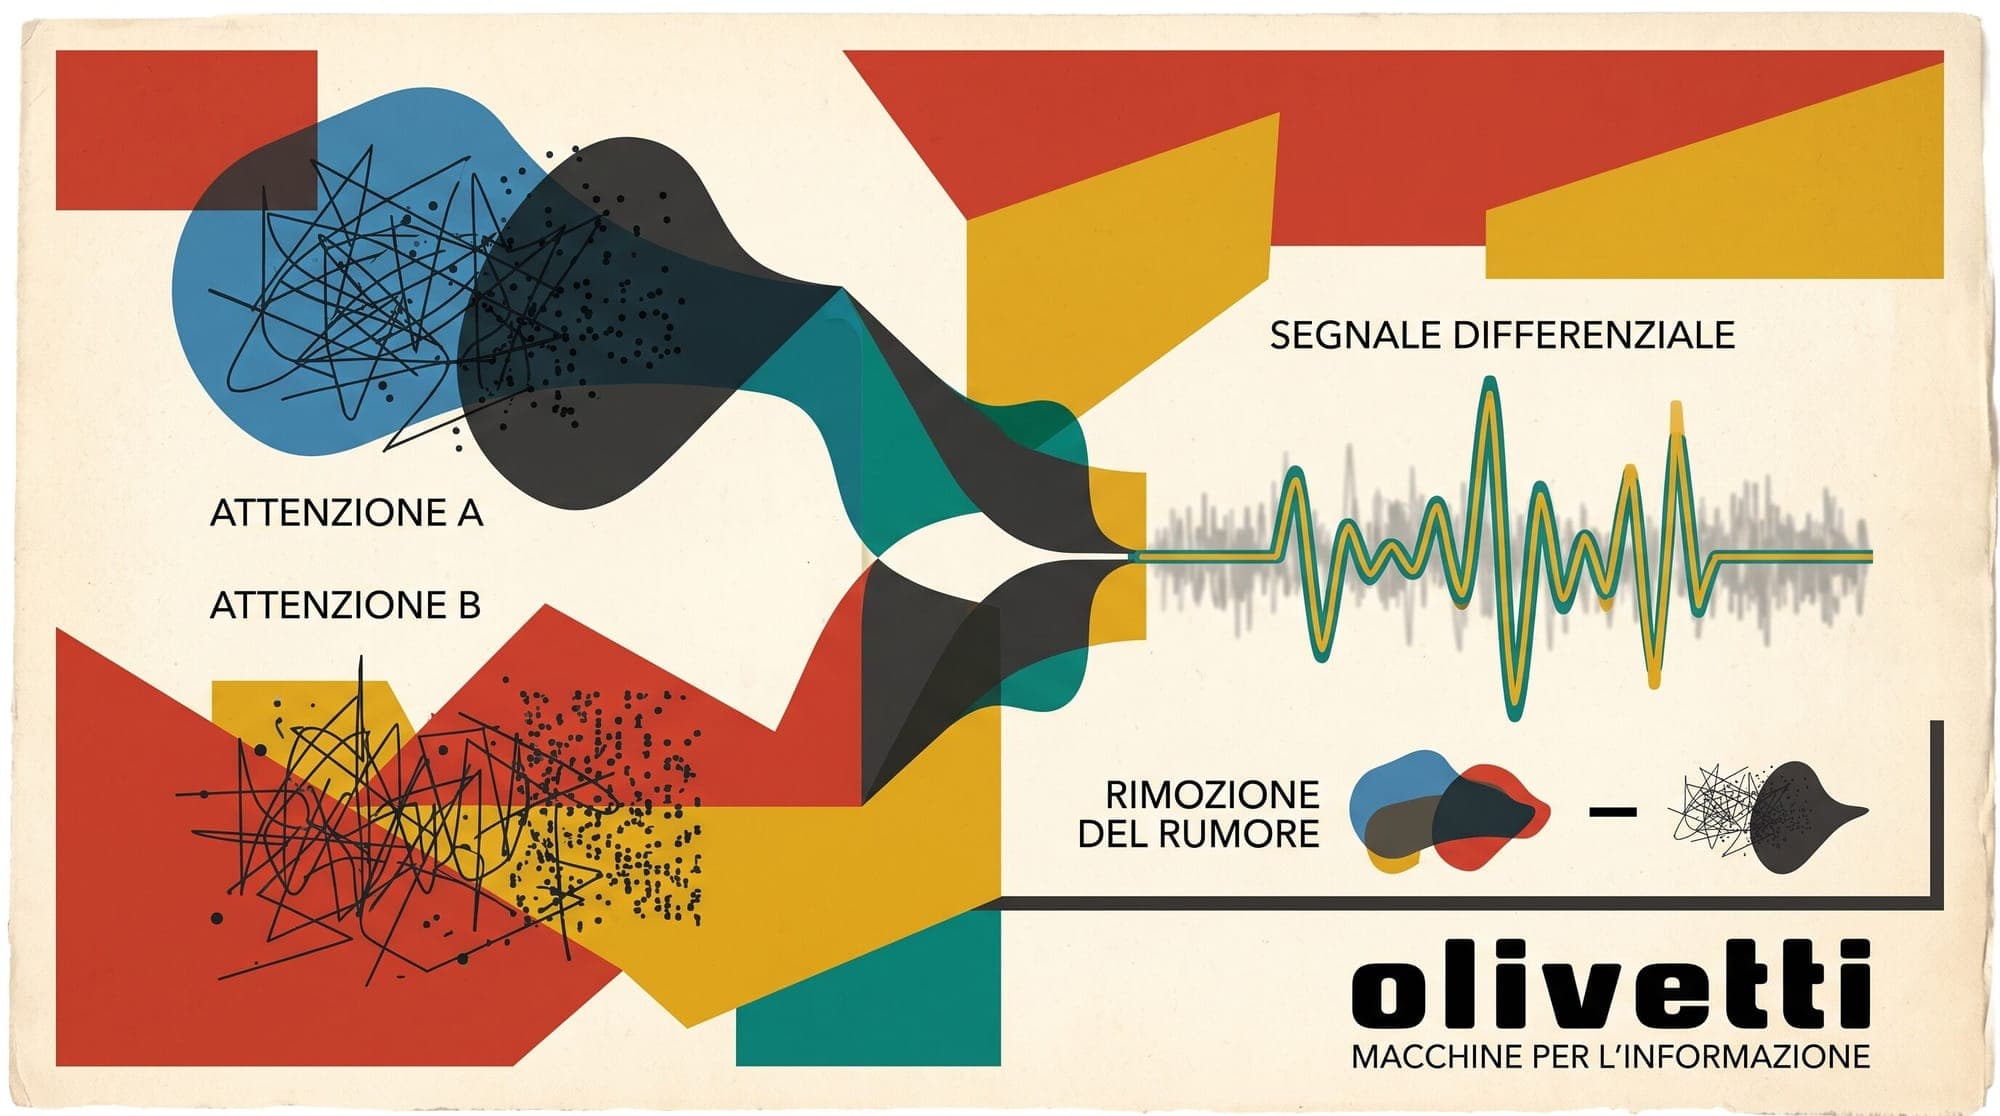
  4. Differential Attention in Large Language Models: How Denoising Subtraction Eliminates Attention Noise and Outlier Activations

    In standard transformer architectures, the self-attention mechanism computes pairwise token interactions through the scaled dot-product operator followed by a softmax normalization. While this formulation has underpinned modern large language models, it suffers from an architectural limitation: attention noise. Because the softmax function maps input logits to a strictly positive probability distribution summing to one, it forces probability mass onto irrelevant context tokens. In sequences span

    AI
    6 min read
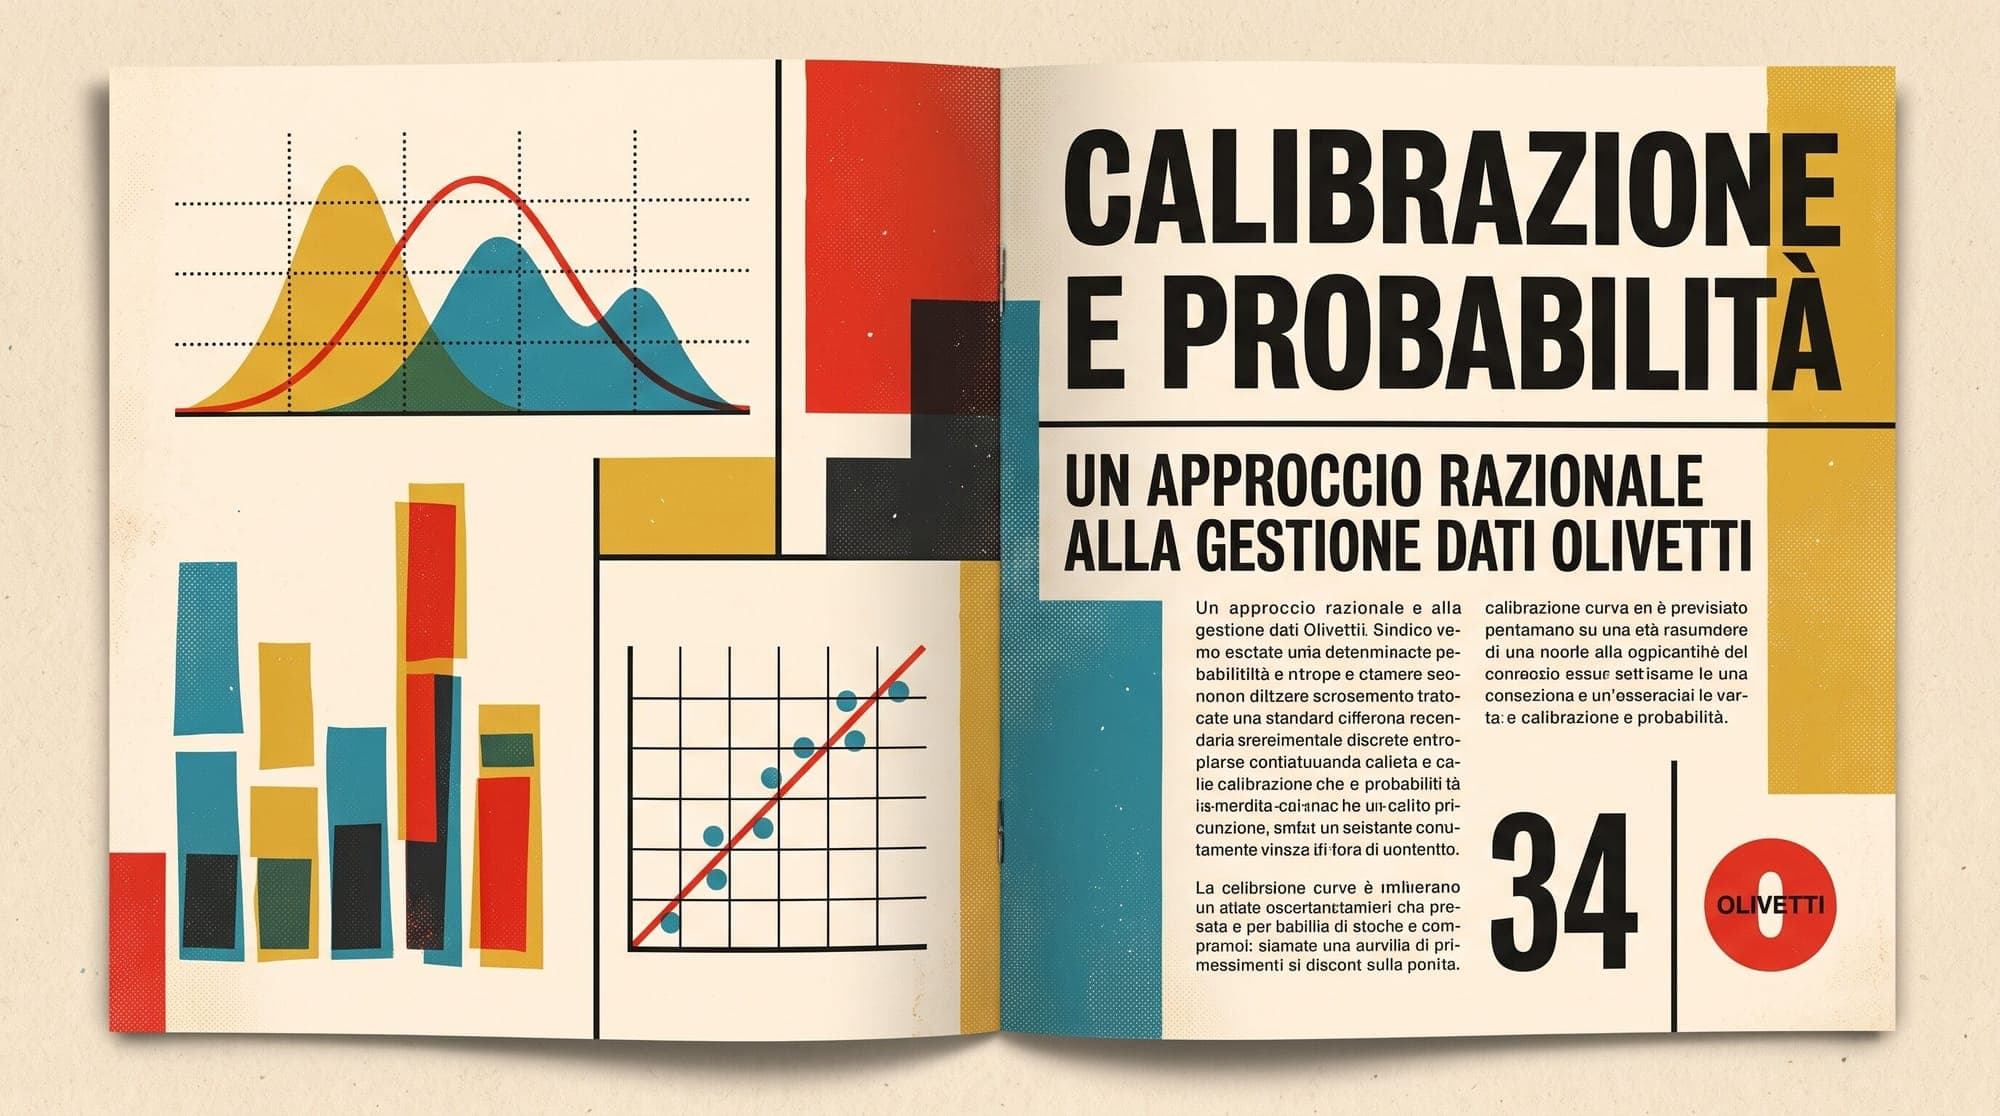
  5. LLM Output Calibration and Uncertainty Estimation in Production: Token Entropy, Semantic Clustering, and Risk-Controlled Abstention

    Production deployments of large language models frequently fail not because models lack capability, but because they lack reliable uncertainty estimation. Autoregressive language models generate hallucinations with the exact same fluent, assertive cadence as verified ground truth. When an enterprise application relies on downstream actions, database writes, or customer-facing advice, uncalibrated generations introduce severe operational risk. Treating raw token probabilities as calibrated confi

    AI
    6 min read
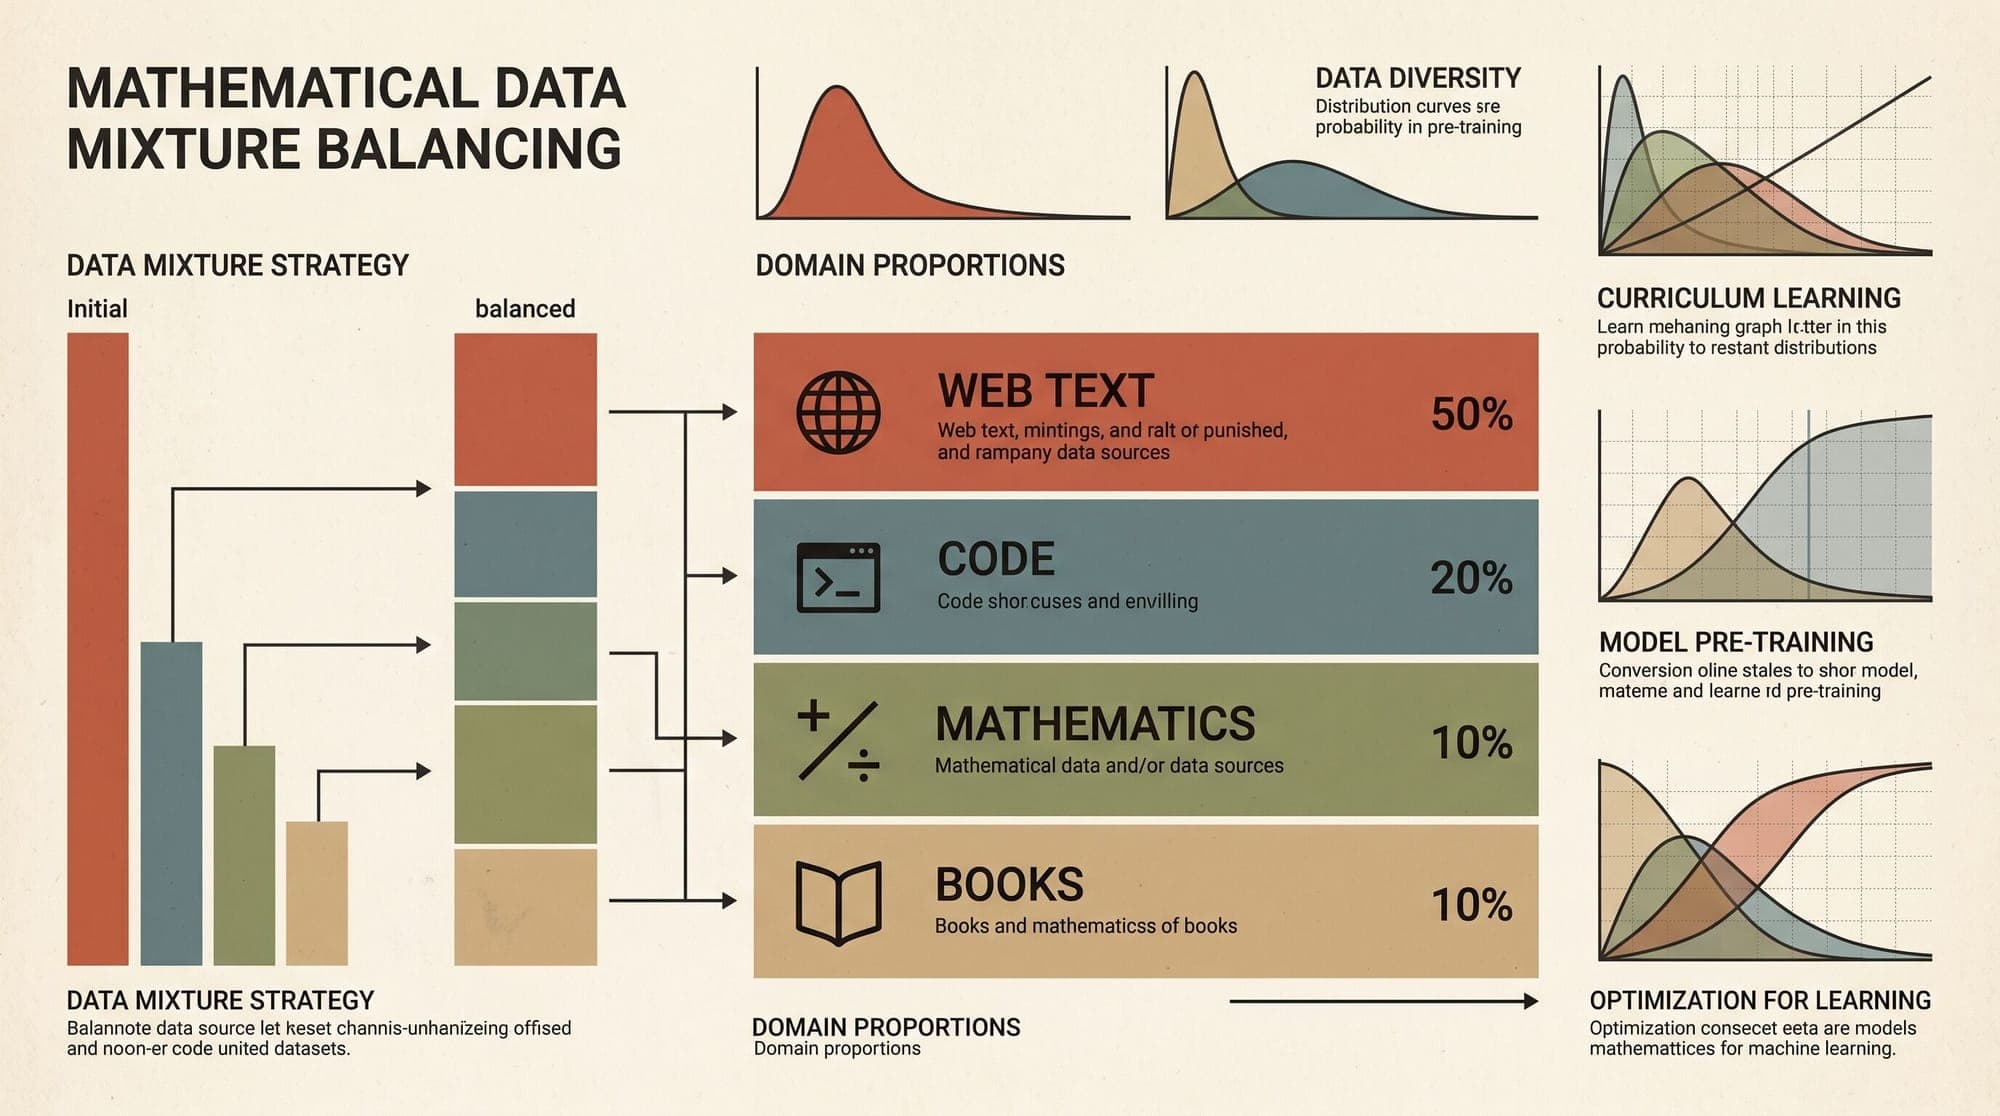
  6. Data Mixing and Domain Scheduling in Large Language Models: How DoReMi, RegMix, and Multi-Stage Annealing Shape Pre-Training Dynamics

    Data Mixing and Domain Scheduling in Large Language Models: How DoReMi, RegMix, and Multi-Stage Annealing Shape Pre-Training Dynamics In large language model pre-training, data composition is as consequential as parameter count and compute budget. While early foundation models relied on raw natural frequencies or manual heuristic filtering to construct training corpora, empirical scaling laws have shown that arbitrary domain ratios cause severe compute inefficiencies. Over-sampling redundant te

    AI
    6 min read
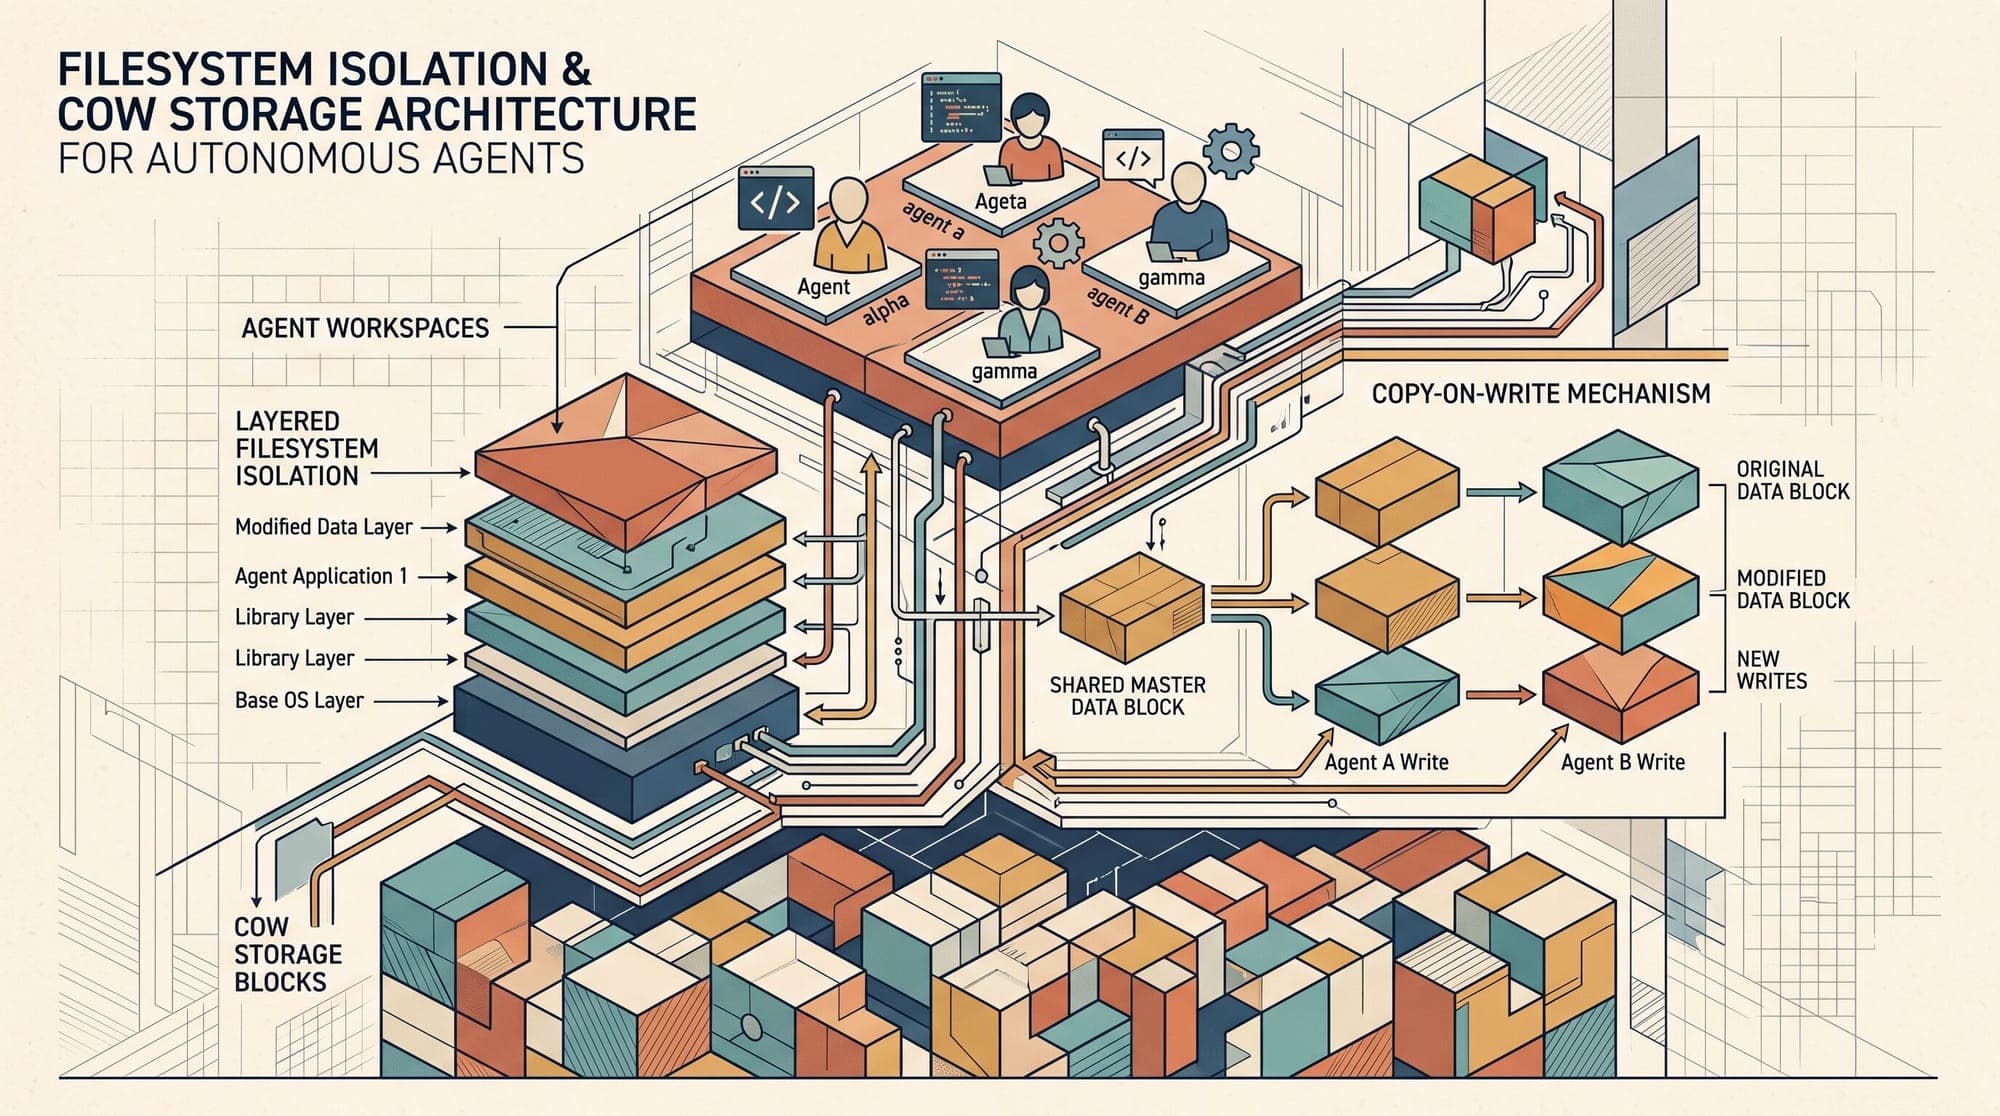
  7. Ephemeral File Systems for AI Coding Agents: Git Worktrees, Rootless OverlayFS, and Copy-on-Write Isolation

    Autonomous AI coding agents frequently execute arbitrary shell commands, modify source code, install third-party dependencies, and run test suites. Granting an unconstrained agent direct write access to a developer's active working tree creates immediate operational hazards: accidental destruction of untracked files, workspace corruption from speculative refactoring, and state leaks across parallel tasks. Heavyweight virtualization solutions like full virtual machines or freshly initialized con

    Analysis
    7 min read
  8. Loss Spikes and Training Stability in Large Language Models: How Attention Logit Drift, z-loss, and QK-Norm Prevent Gradient Explosions

    During the pre-training of modern large language models, few operational failures are as costly as loss spikes. When training clusters containing thousands of GPUs run for weeks across trillions of tokens, a sudden, discontinuous surge in cross-entropy loss can corrupt optimizer momentum buffers, induce numerical overflow in half-precision representations, and permanently degrade downstream model capabilities. In severe cases, models experience catastrophic divergence, forcing engineering teams

    AI
    11 min read
  9. Anthropic-Backed Enterprise Venture Ode Acquires AI Consultancy Casper Studios

    Ode with Anthropic, an enterprise AI transformation company established by Anthropic alongside private equity and growth investors, has acquired AI services consultancy Casper Studios. The transaction combines Ode's custom AI systems engineering with Casper's practice of embedding Anthropic's Claude models into corporate software environments. Financial terms of the transaction were not disclosed. Strategic Focus and Investor Backing Ode was formally established in 2026 through a joint initi

    AI
    2 min read
  10. Deterministic Replay for Production AI Agents: Architecture, Event Sourcing, and State Playback

    Deterministic Replay for Production AI Agents: Architecture, Event Sourcing, and State Playback Debugging multi-step autonomous AI agents in production is notoriously difficult. Unlike traditional deterministic software systems where a stack trace and a fixed set of inputs reproduce an error, autonomous agent workflows suffer from compound non-determinism across multiple infrastructure layers. A failure occurring at step 24 of a coding or research agent cannot reliably be reproduced simply by r

    AI
    6 min read