Low-Rank Adaptation (LoRA) and DoRA: Mathematical Foundations, Intrinsic Dimensionality, and Directional Weight Decomposition
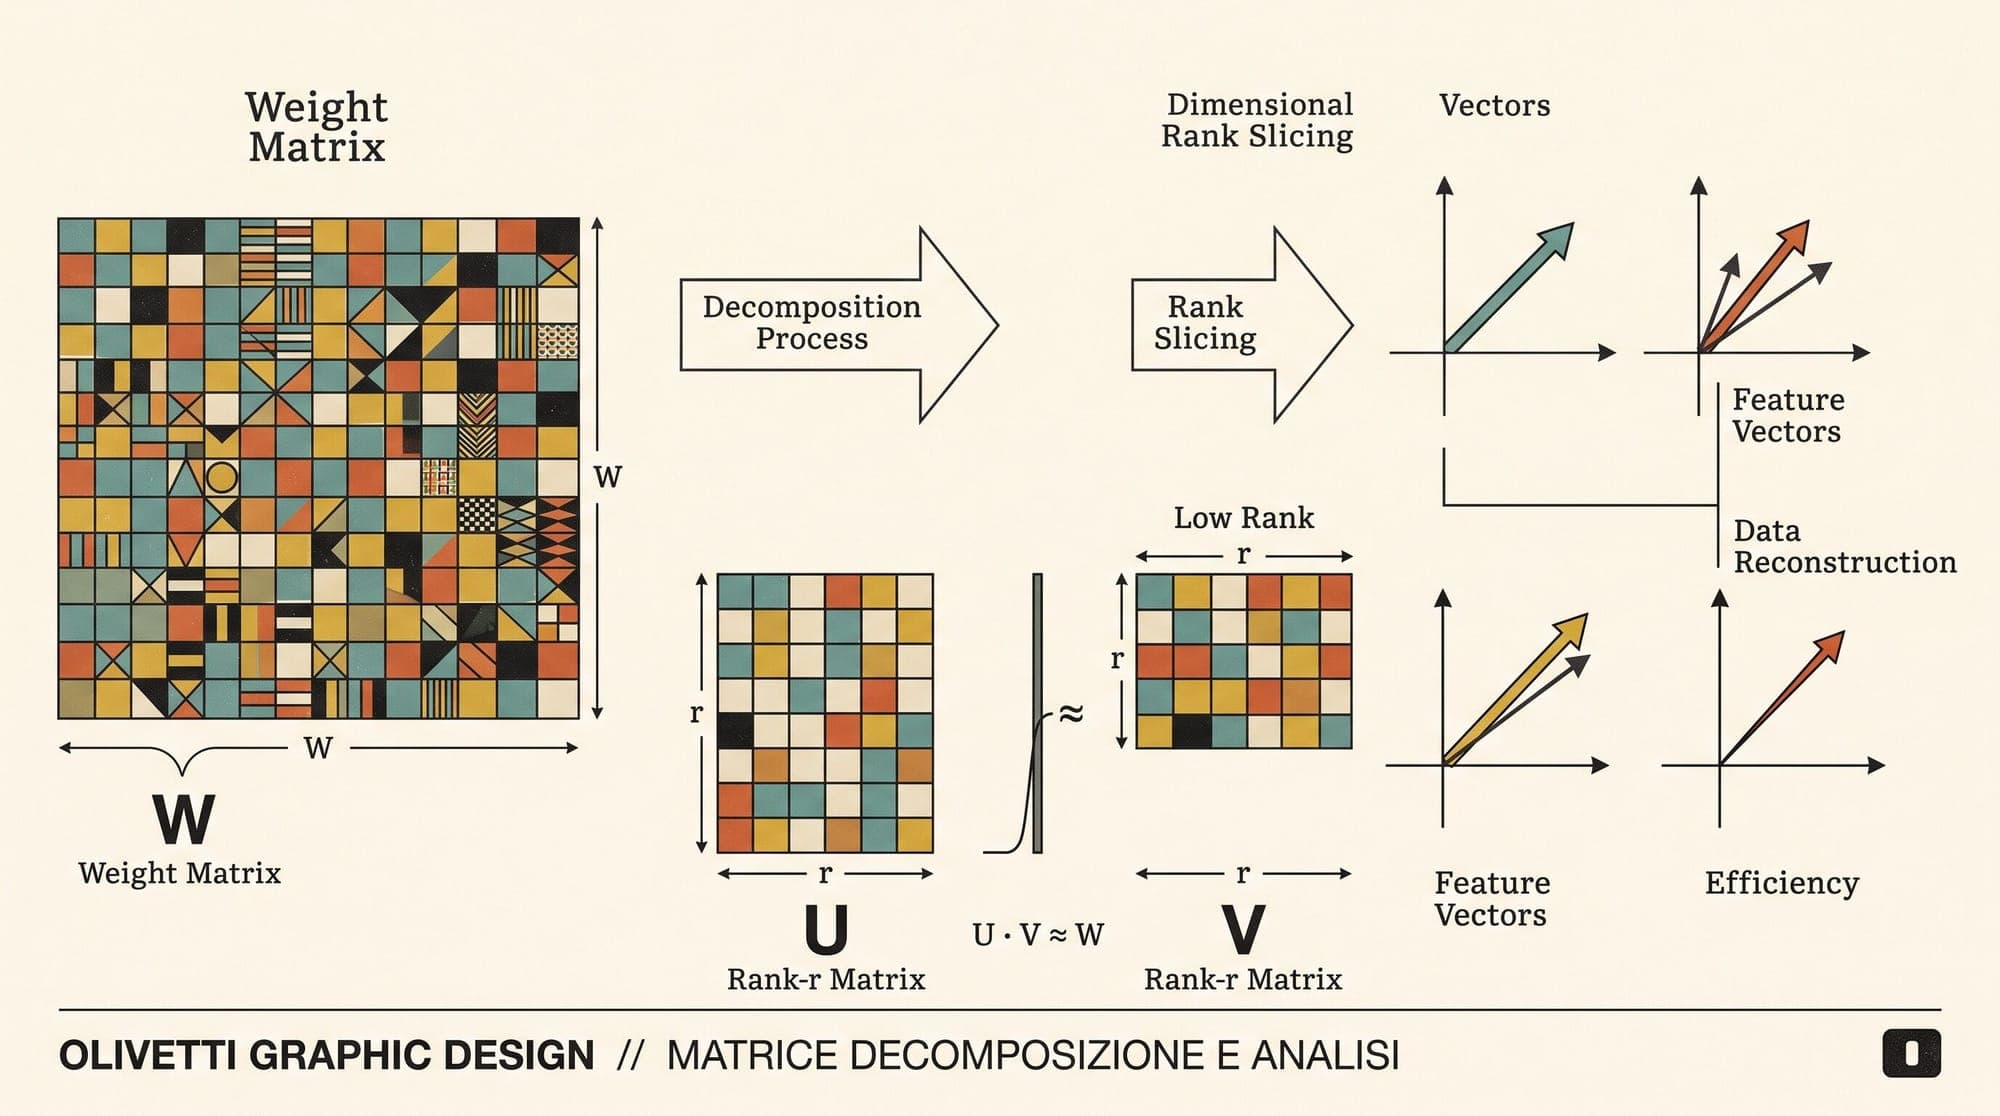
Low-Rank Adaptation (LoRA) and DoRA: Mathematical Foundations, Intrinsic Dimensionality, and Directional Weight Decomposition Full-parameter fine-tuning of large language models presents prohibitive memory requirements during training. Standard full fine-tuning requires updating every weight matrix in a model, demanding storage not only for the model parameters themselves, but also for activation tensors, backward gradients, and first- and second-moment optimizer states. For a 70-billion-parame