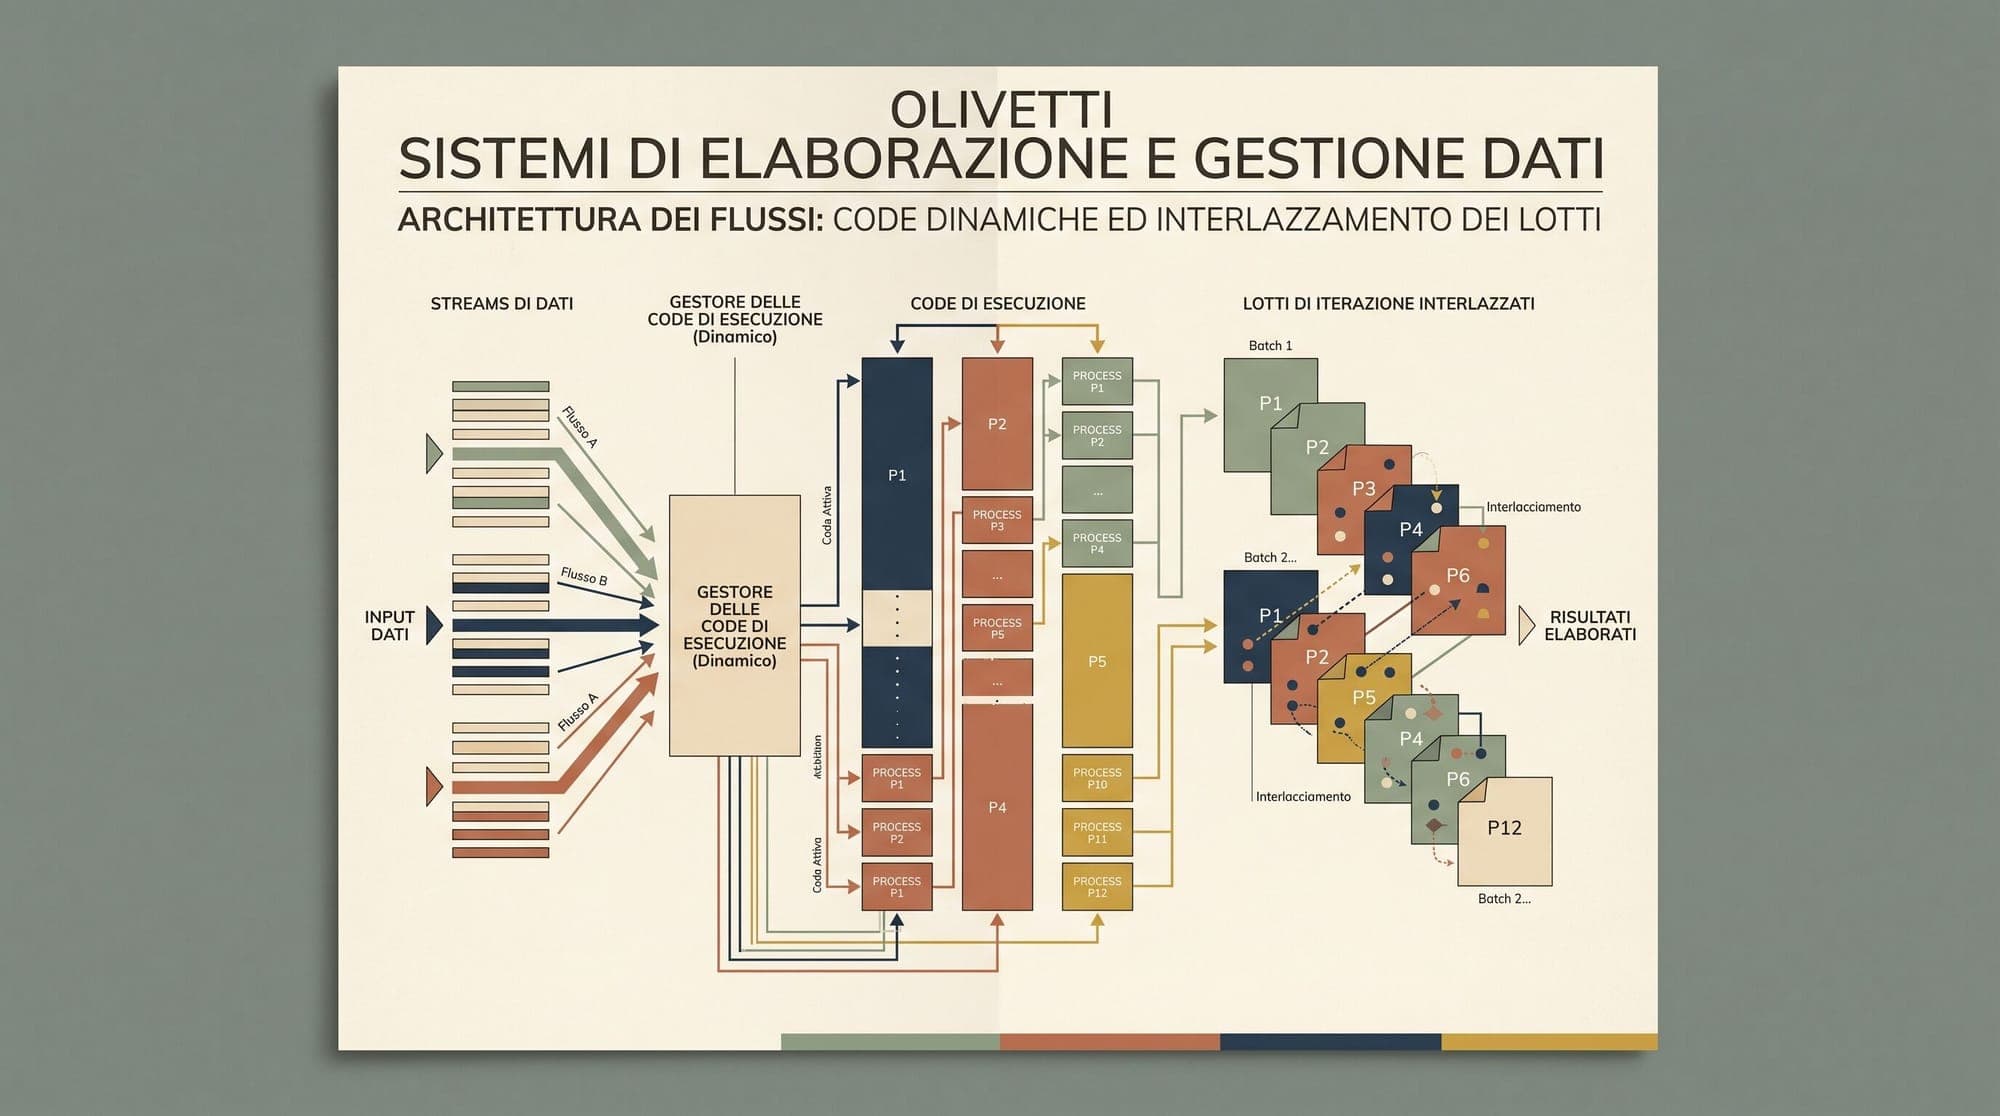
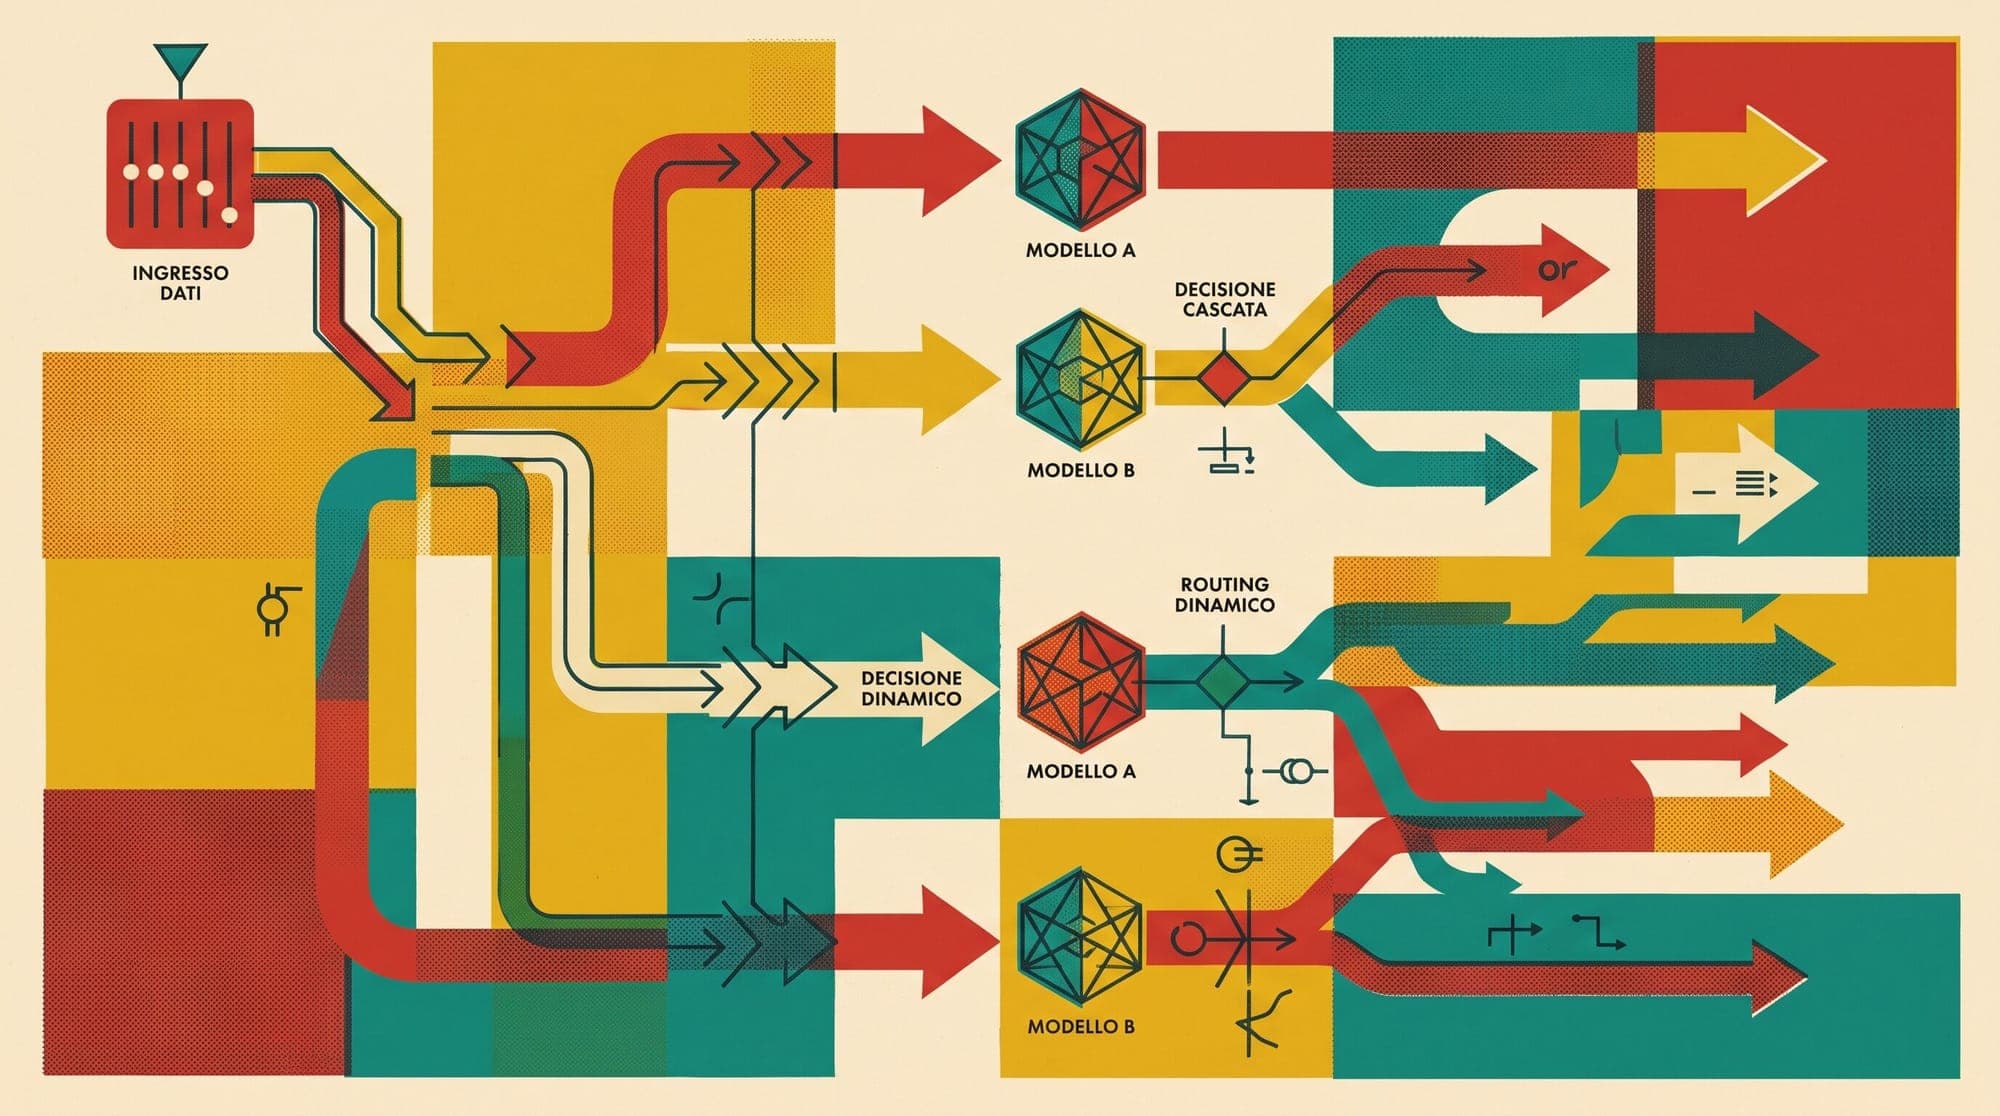
Continuous Batching and Request Scheduling in Production LLM Serving: Comparing Orca, FastServe, Sarathi-Serve, and vLLM Architecture, Preemption Policies, Chunked Prefill Interleaving, and TTFT-TBT Trade-Offs
Autoregressive large language model serving exhibits a fundamental architectural tension between compute utilization and latency guarantees. Standard deep learning inference pipelines rely on static request-level batching, where incoming queries are grouped into a fixed tensor, executed across forward passes until all sequences finish, and evicted simultaneously. In transformer-based text generation, static batching collapses serving efficiency. Because sequence lengths vary widely and token gen