Model Evaluation2 articles

Model Evaluation

Articles

  • Google DeepMind Pilots Double-Blind AI Evaluations in Hardware-Isolated Cryptographic Enclaves

    Google DeepMind has introduced a framework for conducting double-blind evaluations of proprietary frontier AI models within cryptographically isolated computing environments. The initiative, developed in partnership with the Singapore AI Safety Institute, OpenMined, AVERI, and MLCommons, aims to resolve the tension between protecting benchmark datasets from contamination and safeguarding proprietary model weights. In traditional third-party model evaluations, organizations face an unavoidable c

    1 min
  • Duke Study Finds Creative Output Across Frontier LLMs Is Converging Toward Semantic Monoculture

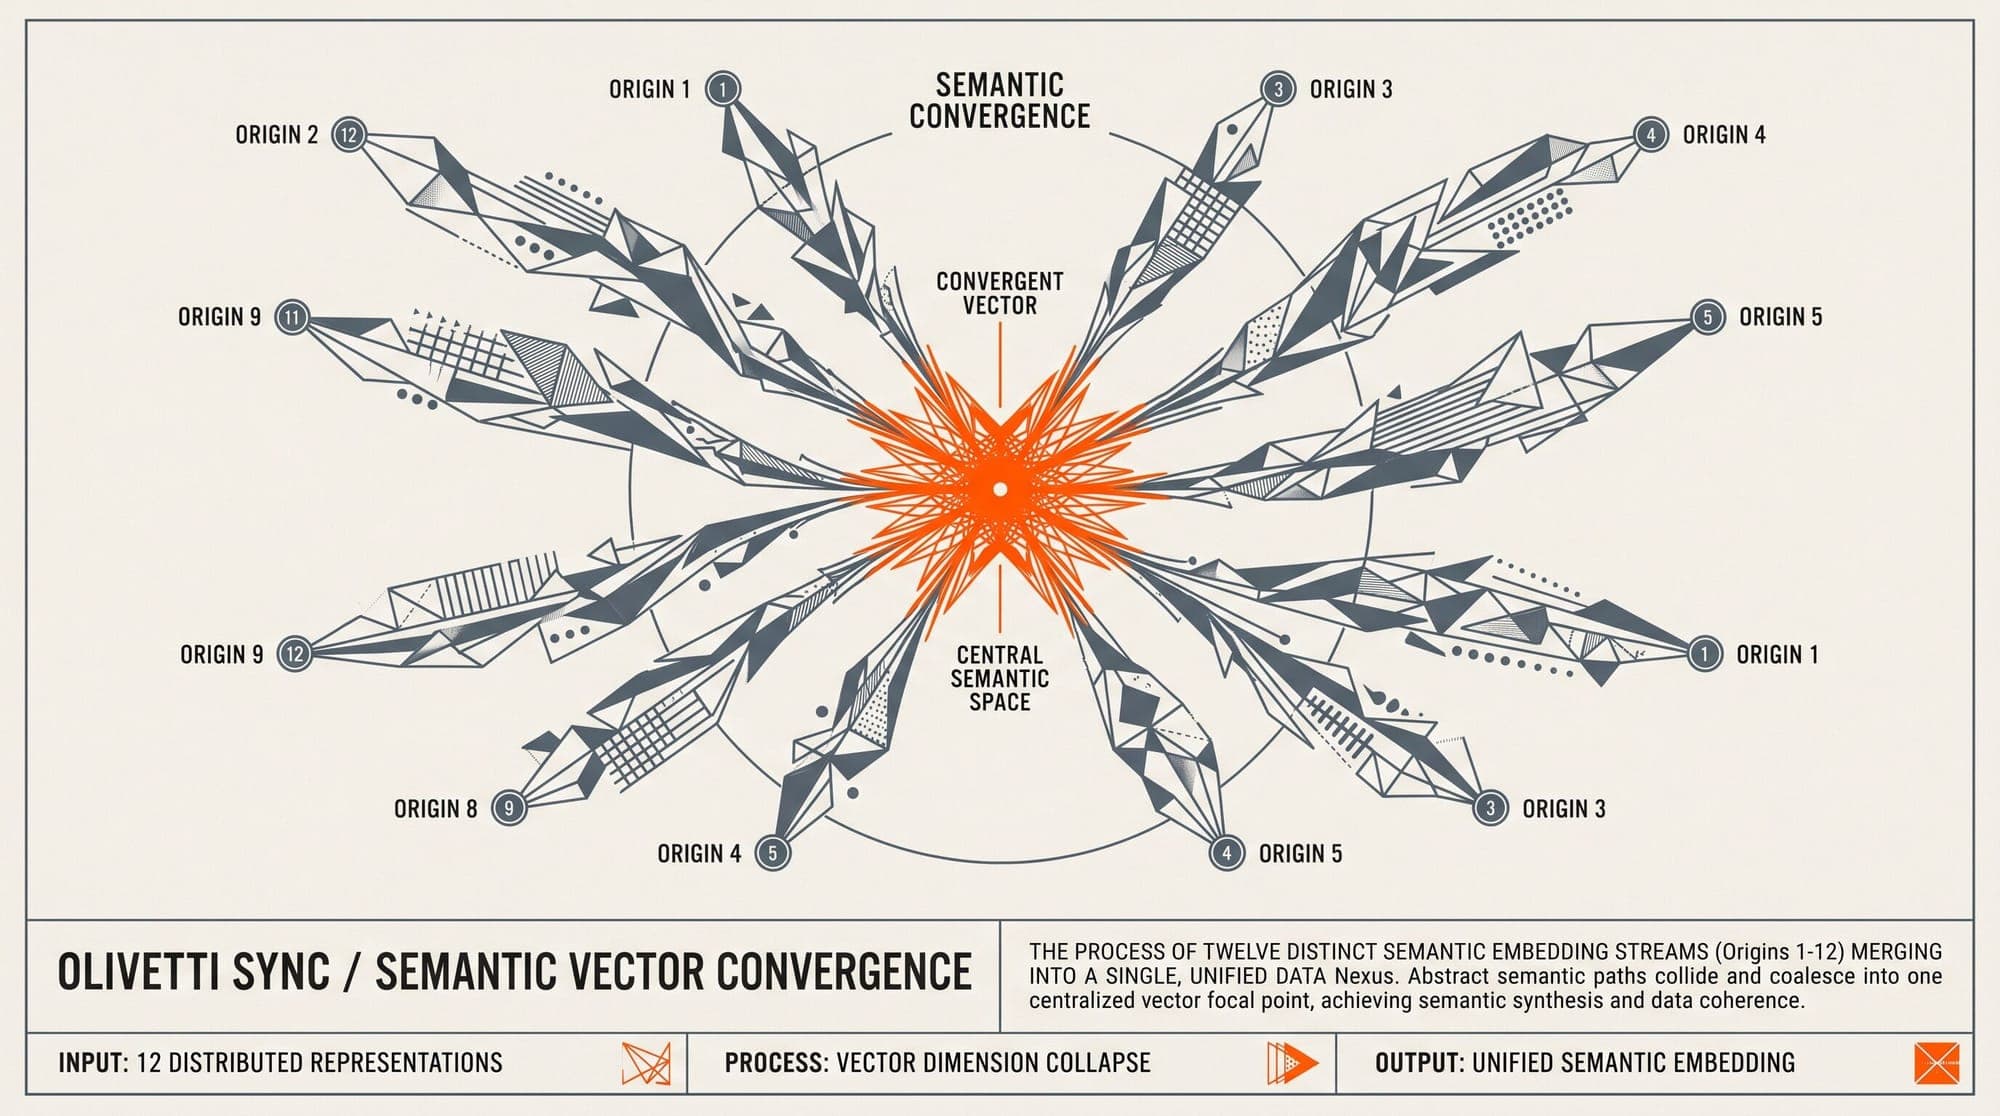
    A longitudinal study by researchers at Duke University has documented a measurable decline in output diversity across major large language model families. Tracking 69 foundation model checkpoints released between March 2023 and July 2026, the researchers found that generative responses to open-ended creative and ideation prompts are increasingly converging toward semantic uniformity across competing providers. The paper, titled Are LLMs becoming similarly creative? Evidence from three years of

    1 min