Speculative Decoding: Mathematical Foundations, Exact Distribution Preservation via Rejection Sampling, and Tree-Structured Verification
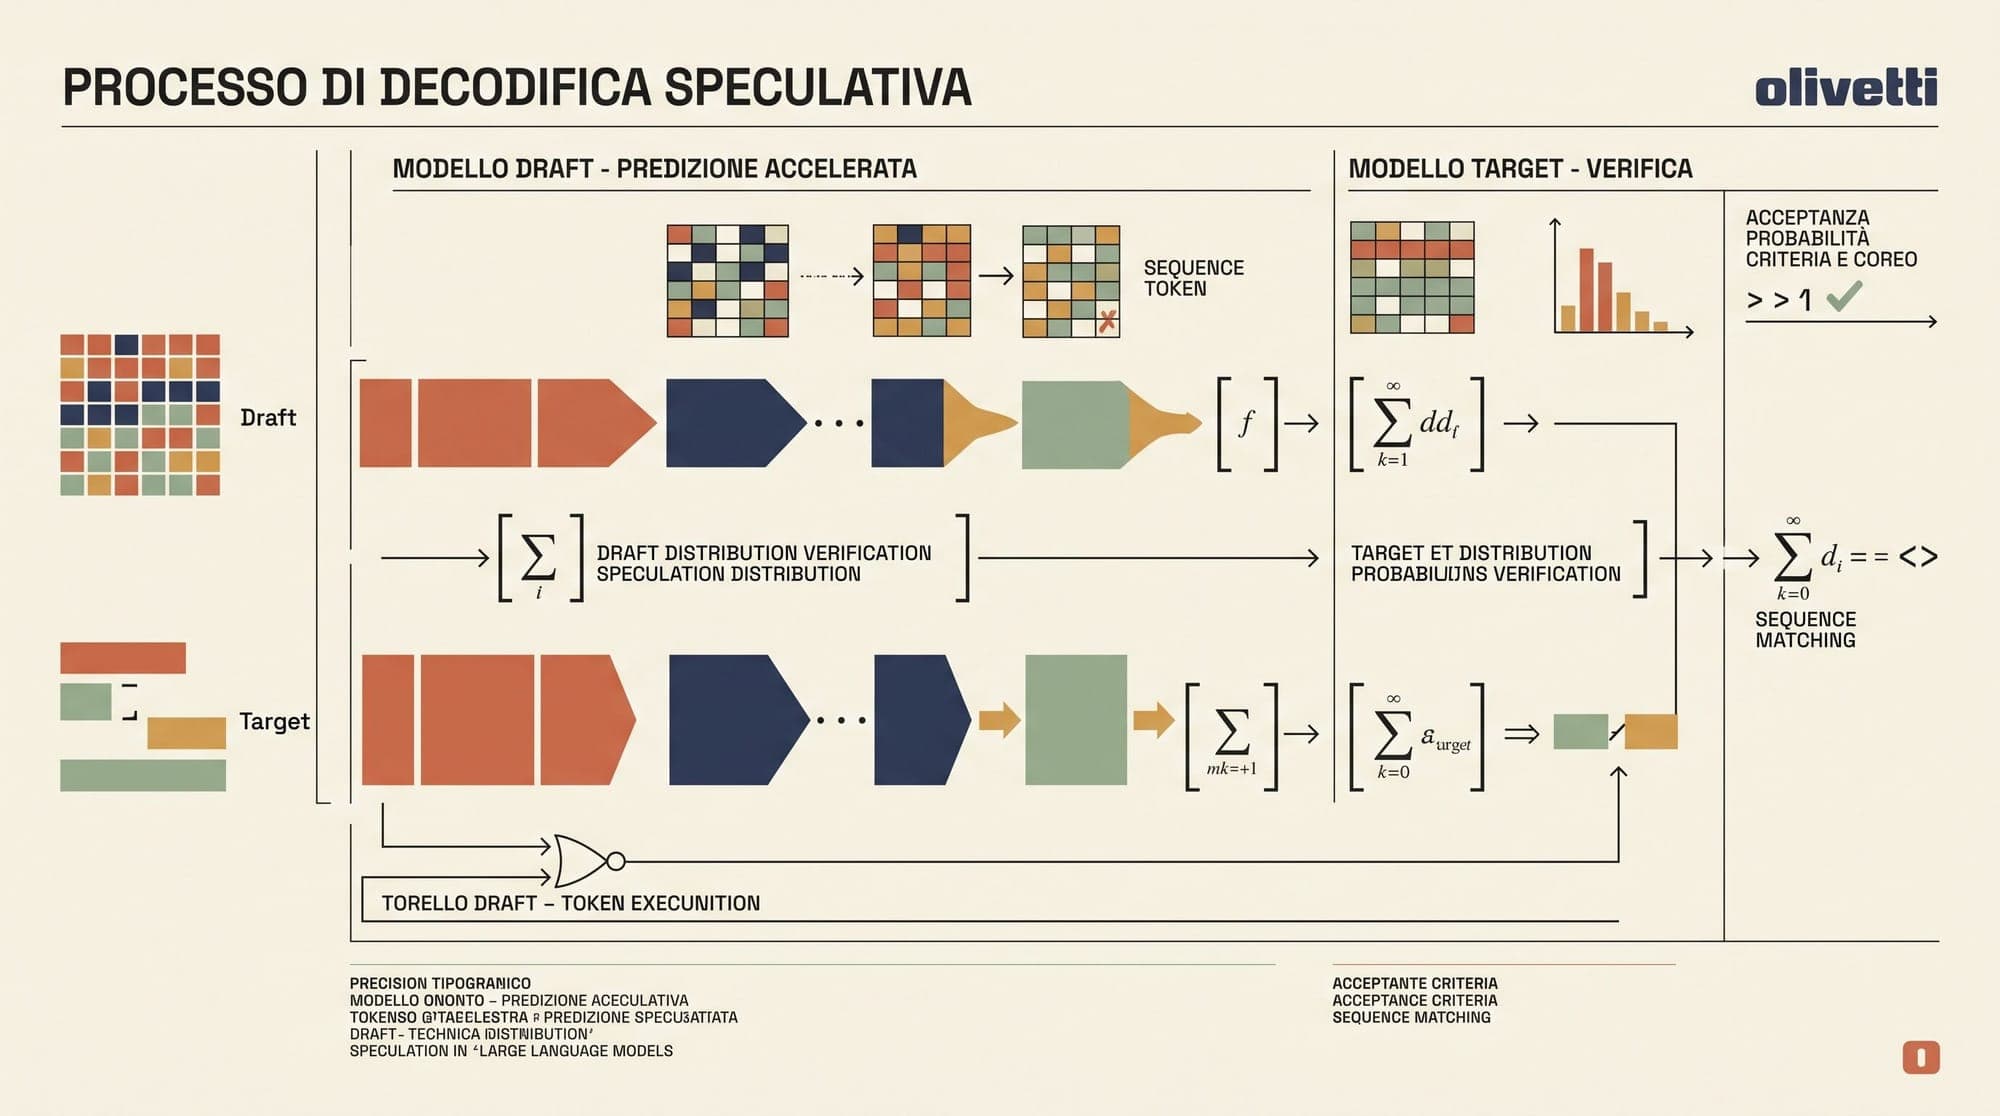
Autoregressive decoding in large language models exhibits a severe computational asymmetry. Generating text token by token requires loading every parameter of a multi-billion-parameter network into high-bandwidth memory (HBM) for every forward pass. In low-batch or single-stream inference regimes, the compute units spend the majority of execution cycles waiting for memory transfers, yielding an arithmetic intensity of order O(1) FLOP per byte. Speculative decoding resolves this bottleneck by de
1 min